
✨ A synthetic dataset generation framework that produces diverse coding questions and verifiable solutions - all in one framwork
See the codeREADME
🐱 KodCode: A Diverse, Challenging, and Verifiable Synthetic Dataset for Coding
KodCode is the largest fully-synthetic open-source dataset providing verifiable solutions and tests for coding tasks. It contains 12 distinct subsets spanning various domains (from algorithmic to package-specific knowledge) and difficulty levels (from basic coding exercises to interview and competitive programming challenges). KodCode is designed for both supervised fine-tuning (SFT) and RL tuning.
🏆 KodCode has been accepted to ACL 2025 and received the Best Paper Award at DataWorld @ ICML 2025!
- 🕸️ Project Website - To discover the reasoning for the name of KodCode 🤨
- 📄 Technical Report - Discover the methodology and technical details behind KodCode
- 💾 Github Repo - Access the complete pipeline used to produce KodCode V1
- 🤗 HF Datasets: KodCode-V1 (For RL); KodCode-V1-SFT-R1 (for SFT)
Overview
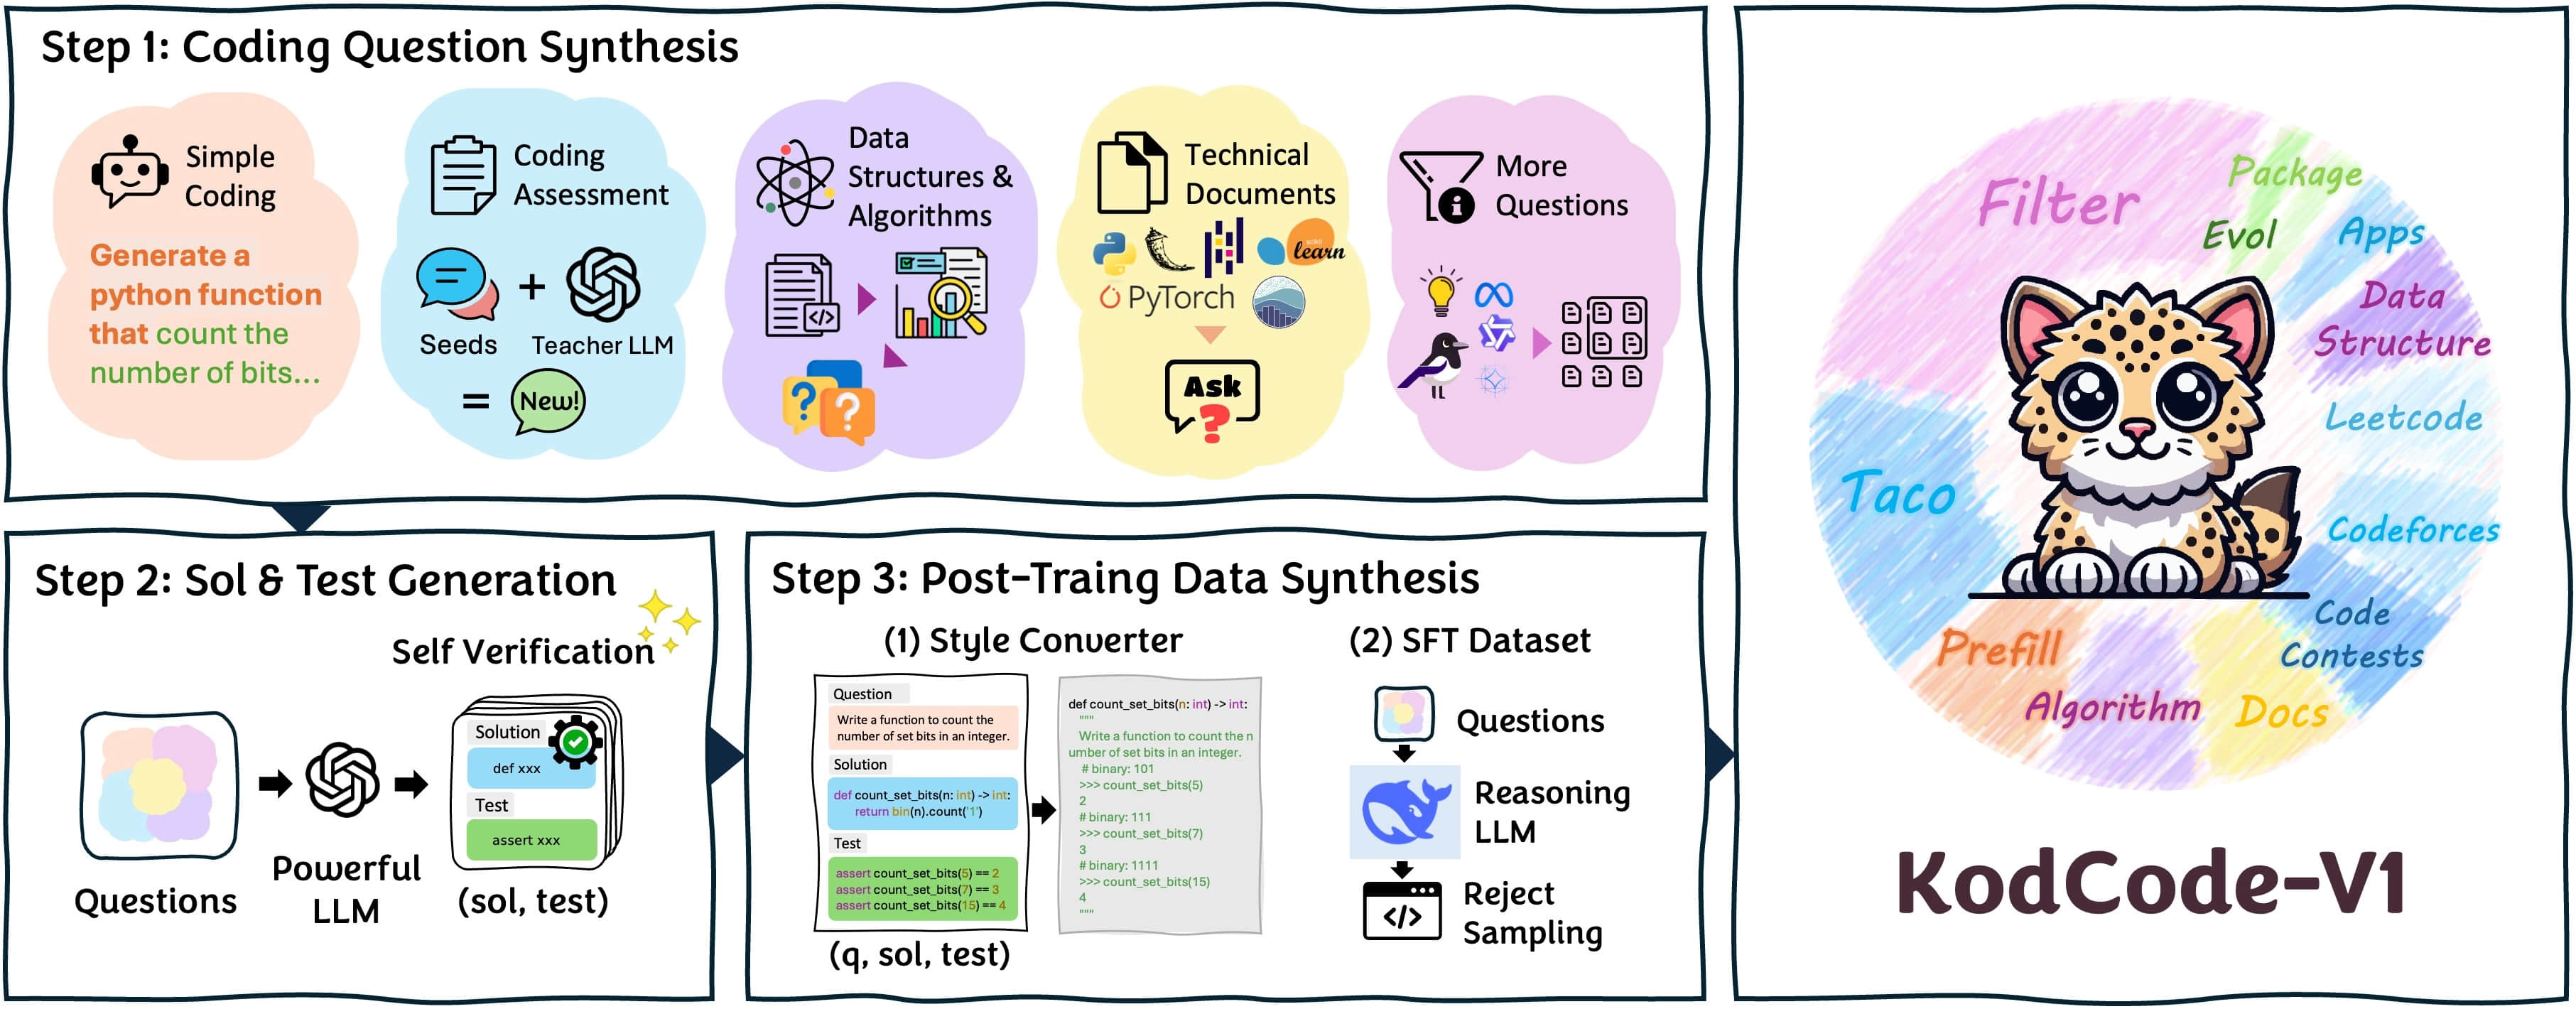
Features
KodCode is a comprehensive pipeline designed to generate diverse, challenging, and verifiable synthetic datasets for coding tasks. Key features include:
- Diverse Sources: Generate high-quality coding questions from multiple sources including zero-shot generation, human-written assessment questions, code snippets, and technical documentation - all unified in a single framework!
- Self-Verification: Generate verifiable solutions and tests for each coding question. Support pytest and parallel execution.
- Style Converter: Easy to convert between different styles of coding questions.
Installation
1. Build code generation environment
Option 1: conda
git clone https://github.com/KodCode-AI/kodcode.git
cd kodcode
conda create -n kodcode python=3.10 -y
conda activate kodcode
pip install -r requirements.txt
Option 2: uv
git clone https://github.com/KodCode-AI/kodcode.git
cd kodcode
uv venv
source .venv/bin/activate
uv pip install -r requirements.txt
2. Build code execution environment
Option 1: Local
To run unit tests in parallel, you also need to install parallel. For example, if you are using Ubuntu, you can install parallel by:
sudo apt-get install parallel
Option 2: Docker
Please install Nvidia container toolkit first to support GPU.
We provided a off-the-shelf docker image for running tests:
docker pull zcxu/kodcode-test-environment:python3.10-cuda12.4-v0.1
Generate KodCode
Please refer to the pipeline for details.
Training
SFT: We used Llama-Factory to train the SFT checkpoint.
RL: Please refer to code-r1 for RL training using KodCode datasets, which is based on verl.
TODO
Repo Update
- One-line command to generate KodCode
- Integrate the test pipeline (i.e.,
pytest) for RL training. -> Supported in forkedcode-r1with the latest verl! Thank you Jiawei @ganler!!! - Implement dockerized execution for unit tests
Data Update
-
KodCode-Litewith 10K samples for light-weight RL training -
KodCode-V1.1: Supportstdinformat with ~50K additional samples
🧐 Other Information
License: Please follow CC BY-NC 4.0.
Contact: For questions, suggestions, or feedback, please reach out to Zhangchen Xu, or raise an issue. We welcome your input and are committed to continuously improving KodCode to better serve the community.
📚 Citation
If you find the model, data, or code useful, please cite:
@article{xu2025kodcode,
      title={KodCode: A Diverse, Challenging, and Verifiable Synthetic Dataset for Coding},
      author={Zhangchen Xu and Yang Liu and Yueqin Yin and Mingyuan Zhou and Radha Poovendran},
      year={2025},
      eprint={2503.02951},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2503.02951},
}
Contributors


Similar repos




Languages
Python
91.3%
Shell
8.7%
✨ A synthetic dataset generation framework that produces diverse coding questions and verifiable solutions - all in one framwork
See the codeREADME
🐱 KodCode: A Diverse, Challenging, and Verifiable Synthetic Dataset for Coding
KodCode is the largest fully-synthetic open-source dataset providing verifiable solutions and tests for coding tasks. It contains 12 distinct subsets spanning various domains (from algorithmic to package-specific knowledge) and difficulty levels (from basic coding exercises to interview and competitive programming challenges). KodCode is designed for both supervised fine-tuning (SFT) and RL tuning.
🏆 KodCode has been accepted to ACL 2025 and received the Best Paper Award at DataWorld @ ICML 2025!
- 🕸️ Project Website - To discover the reasoning for the name of KodCode 🤨
- 📄 Technical Report - Discover the methodology and technical details behind KodCode
- 💾 Github Repo - Access the complete pipeline used to produce KodCode V1
- 🤗 HF Datasets: KodCode-V1 (For RL); KodCode-V1-SFT-R1 (for SFT)
Overview
Features
KodCode is a comprehensive pipeline designed to generate diverse, challenging, and verifiable synthetic datasets for coding tasks. Key features include:
- Diverse Sources: Generate high-quality coding questions from multiple sources including zero-shot generation, human-written assessment questions, code snippets, and technical documentation - all unified in a single framework!
- Self-Verification: Generate verifiable solutions and tests for each coding question. Support pytest and parallel execution.
- Style Converter: Easy to convert between different styles of coding questions.
Installation
1. Build code generation environment
Option 1: conda
git clone https://github.com/KodCode-AI/kodcode.git
cd kodcode
conda create -n kodcode python=3.10 -y
conda activate kodcode
pip install -r requirements.txt
Option 2: uv
git clone https://github.com/KodCode-AI/kodcode.git
cd kodcode
uv venv
source .venv/bin/activate
uv pip install -r requirements.txt
2. Build code execution environment
Option 1: Local
To run unit tests in parallel, you also need to install parallel. For example, if you are using Ubuntu, you can install parallel by:
sudo apt-get install parallel
Option 2: Docker
Please install Nvidia container toolkit first to support GPU.
We provided a off-the-shelf docker image for running tests:
docker pull zcxu/kodcode-test-environment:python3.10-cuda12.4-v0.1
Generate KodCode
Please refer to the pipeline for details.
Training
SFT: We used Llama-Factory to train the SFT checkpoint.
RL: Please refer to code-r1 for RL training using KodCode datasets, which is based on verl.
TODO
Repo Update
- One-line command to generate KodCode
- Integrate the test pipeline (i.e.,
pytest) for RL training. -> Supported in forkedcode-r1with the latest verl! Thank you Jiawei @ganler!!! - Implement dockerized execution for unit tests
Data Update
-
KodCode-Litewith 10K samples for light-weight RL training -
KodCode-V1.1: Supportstdinformat with ~50K additional samples
🧐 Other Information
License: Please follow CC BY-NC 4.0.
Contact: For questions, suggestions, or feedback, please reach out to Zhangchen Xu, or raise an issue. We welcome your input and are committed to continuously improving KodCode to better serve the community.
📚 Citation
If you find the model, data, or code useful, please cite:
@article{xu2025kodcode,
      title={KodCode: A Diverse, Challenging, and Verifiable Synthetic Dataset for Coding},
      author={Zhangchen Xu and Yang Liu and Yueqin Yin and Mingyuan Zhou and Radha Poovendran},
      year={2025},
      eprint={2503.02951},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2503.02951},
}
Similar repos
Contributors
Languages
Python
91.3%
Shell
8.7%