
A PyTorch implementation of Style Tokens: Unsupervised Style Modeling, Control and Transfer in End-to-End Speech Synthesis
Python
375
18 commits
updated Dec 8, 2022
README
GST-Tacotron-Pytorch
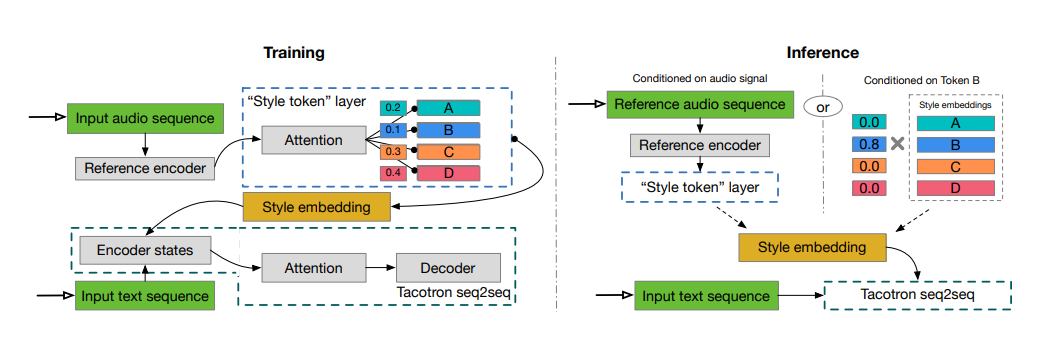
A PyTorch implementation of Style Tokens: Unsupervised Style Modeling, Control and Transfer in End-to-End Speech Synthesis
Update
Add support for blizzard dataset.
Requirements
pip3 install -r requirements.txt
File structure
Hyperparameters.py--- hyperparametersNetwork.py--- encoder and decoderModules.py--- some modules for tacotronLoss.py--- loss functionData.py--- dataset loaderutils.py--- some util functions for data I/OSynthesis.py--- speech generation
How to train
- Download a multispeaker dataset
- Preprocess your data and implement your
get_XX_datafunction inData.py - Set hyperparameters in
Hyperparameters.py - Make a directory named
logas follow:
--- log
|    |
|    --- log[log_number]
|
--- code
     |
     --- Tacotron
             |
             --- train.py
             |
             --- Network.py
             |
           ......
- Run train.py
python3 train.py [log_number] [dataset_size] [start_epoch]

[log_number]: the log directory number
[dataset_size]: int or all
[start_epoch]: which epoch start to train (0 if start from scratch )

for example:
python3 train.py 0 all 0
How to generate wav
Rungenerate.py. Replace the text in generate.py with any chinese sentences as you like before running
The pretained model provided is trained on Chinese dataset, so it only supports chinese now.
Star History
Contributors

15 commits

3 commits
Similar repos


Languages
Python
100.0%
A PyTorch implementation of Style Tokens: Unsupervised Style Modeling, Control and Transfer in End-to-End Speech Synthesis
Python
375
18 commits
updated Dec 8, 2022
README
GST-Tacotron-Pytorch
A PyTorch implementation of Style Tokens: Unsupervised Style Modeling, Control and Transfer in End-to-End Speech Synthesis
Update
Add support for blizzard dataset.
Requirements
pip3 install -r requirements.txt
File structure
Hyperparameters.py--- hyperparametersNetwork.py--- encoder and decoderModules.py--- some modules for tacotronLoss.py--- loss functionData.py--- dataset loaderutils.py--- some util functions for data I/OSynthesis.py--- speech generation
How to train
- Download a multispeaker dataset
- Preprocess your data and implement your
get_XX_datafunction inData.py - Set hyperparameters in
Hyperparameters.py - Make a directory named
logas follow:
--- log
|    |
|    --- log[log_number]
|
--- code
     |
     --- Tacotron
             |
             --- train.py
             |
             --- Network.py
             |
           ......
- Run train.py
python3 train.py [log_number] [dataset_size] [start_epoch]

[log_number]: the log directory number
[dataset_size]: int or all
[start_epoch]: which epoch start to train (0 if start from scratch )

for example:
python3 train.py 0 all 0
How to generate wav
Rungenerate.py. Replace the text in generate.py with any chinese sentences as you like before running
The pretained model provided is trained on Chinese dataset, so it only supports chinese now.
Star History
Similar repos
Contributors
15 commits
3 commits
Languages
Python
100.0%