KaiWU5/Awesome-AI4AI

AI4AI Survey: can AI reliably improve AI? 223 papers on long-horizon agents, benchmarks, harness design, and recursive self-improvement · updated weekly

Python

172

29 commits

updated Sep 21, 2026

See the code

README

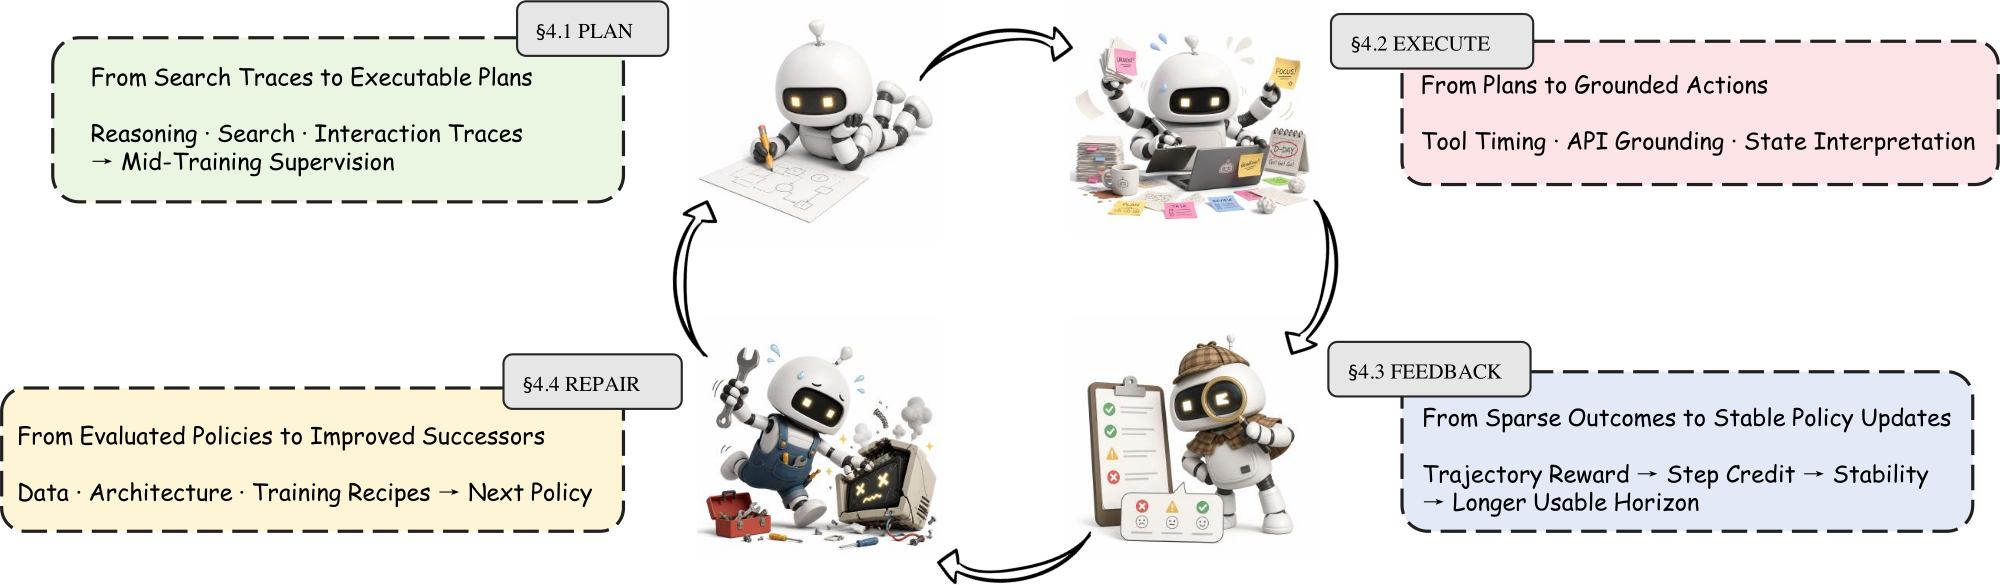
Towards AI that improves AI — the plan, execute, feedback, repair loop

🚀 Awesome AI4AI

AI4AI Survey: From Long-Horizon Agents to Recursive Self-Improvement
Definitions, Reliable Horizons, and Open Problems · 23 authors · 7 institutions

Updated weekly with the month's top AI-for-AI papers, news, and blogs. Stay tuned 🔥
Paper, nice layout Paper on Preprints.org Project Site RSIHub Harness Blog DOI


Why This Repo

🔄 Automatic rankings
Citations, GitHub stars, and rankings refresh every Monday.
🗞️ Weekly update
The month's top papers and releases, re-ranked every week against primary sources.
🧭 Survey-grounded map
From long-horizon agents to recursive self-improvement.

Star ⭐ to save the map · Watch 👀 for weekly updates · Share 🔁 with your lab

What's New

  • 📄 2026-08-30 — Companion survey now online. Read AI4AI Survey: From Long-Horizon Agents to Recursive Self-Improvement—Definitions, Reliable Horizons, and Open Problems.
  • 🔄 Every Monday — Automatic refresh. Citations, GitHub stars, and recent-paper/yearly rankings update automatically.
  • 🚀 2026-09-16 — Latest weekly edition published. The living catalog and source-verified news digest are up to date.
🗂️ Explore the full collection

📅 Weekly Update · Monthly Top 10

Updated 2026-09-16 · The month's top stories, refreshed every Monday alongside citation rankings.

How we select: The top stories from the trailing 30 days, scored on publisher authority, discussion volume, whether a concrete verifiable result is reported, whether it changes what agent builders do now, whether an artifact was released, and expected durability. Only primary sources are cited, and performance claims remain attributed to their publishers.

Date · TypeNewsWhy it matters
2026‑09‑11
Model release
Introducing Fugu Max and Fugu Ultra v2: Orchestrating the Pareto Frontier
Sakana AI
Sakana AI describes a model trained to route tasks across a fixed pool of open-weight and specialized models and to recursively call instances of itself. It reports 48.3 on Chartography against 27.3 for Opus 5, and says the scores are reached without Fable 5, Fable 5.1 or GPT-6 Astra in the agent pool.
2026‑09‑10
Open-weight release
DeepSeek-V4.1-Flash
DeepSeek
DeepSeek publishes weights on Hugging Face for a 552B mixture-of-experts model built on a new causal encoder-decoder architecture that activates roughly 8B parameters on input and 16B on output. It reports 90.6 on Terminal-Bench 2.1 and 74.2 on DeepSWE v1.1, and says the KV cache needs a quarter of the prior generation's HBM.
2026‑09‑10
Harness release
Introducing the Agents API
OpenAI
OpenAI ships the harness that runs Codex as a managed service in public beta, saying it handles session orchestration, context compaction, sub-agent coordination and recovery while developers supply tools and choose a sandbox. It offers versioned harness access alongside each model launch.
2026‑09‑10
Model release
Introducing SWE-2: Pushing the Pareto Frontier
Cognition
Cognition says it scaled reinforcement learning to a 2.8T-parameter Kimi K3 base for the first time, training every reasoning-effort level in a single run with a cost-penalized reward. It reports 50.0 on its own FrontierCode 1.1 Main at 64 percent lower cost than Fable 5.1, and 58 percent fewer turns than SWE-1.7.
2026‑09‑08
Paper
NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness
arXiv
The authors log predicted capability demand, chosen service tier and interaction outcome for each turn, then reuse those routing signals as a three-stage fine-tuning curriculum and an evaluation-selection-update loop. They report macro-average gains from 58.94 to 64.87 at 4B and 65.60 to 69.04 at 9B across eleven benchmarks, with weights and code released.
2026‑09‑03
Paper
EvoHarnessBench: Can Your Agents Keep Pace with an Evolving Harness?
arXiv
The authors hold tasks fixed and instead grow the harness across tools, skills and agents over 17 multi-stage streams covering 802 tasks, 520 tools, 42 skills and 62 agents. They report harness-induced forgetting of up to 34.7 percent backward transfer on the agents axis with model parameters unchanged.
2026‑09‑03
Model release
GPT-6 Astra: A new generation of intelligence
OpenAI
OpenAI reports 64.6 percent on Terminal-Bench Science 0.1 and 57.9 percent on Terminal-Bench 4.0, and introduces experimental Codex notes and searchable history across context windows for long-running work.
2026‑09‑02
Model update
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Google
Google reports 54.9 percent on HLE-Verified for Gemini 3.8 Flash while retaining the introductory token prices of 3.7 Flash. It says long-running agentic loops helped evaluate and refine the models, and releases Flash Cyber through trusted-defender access.
2026‑09‑01
Model release
Introducing Claude Fable 5.1 and Claude Mythos 5.1
Anthropic
Anthropic reports 52.6 percent on Terminal-Bench-Science 0.1 versus 24.7 percent for Fable 5, and estimates that lower cache-read pricing reduces highly agentic workload costs by up to roughly 45 percent.
2026‑08‑31
Paper
WHALE: A Simple Recipe for Joint Harness-Weight Optimization
arXiv
The authors alternate model-weight updates with executable harness search, reporting gains of 4.15 to 24.38 percentage points over the tested single-component and prompt-weight baselines across three domains with Qwen3.5-2B/4B agents. Code is released for reproducing the joint optimization recipe.

Want next month's news? Watch the repository. Citation counts, rankings, and the month's top stories refresh every Monday. Browse past editions →

📈 Live Rankings

Citation counts are current through 2026-09-21 from Semantic Scholar and OpenAlex. Rankings are discovery aids, not quality scores; audit evidence remains independent of popularity. GitHub stars are snapshots from 2026-09-21. For papers indexed as multiple versions, retain the largest title-verified count reported by the configured sources. All yearly rankings use first public appearance year; a later venue year never moves a paper into a newer cohort.

🔥 Recent Papers by Average Monthly Citations

PaperVenueDateCitationsAvg. cites/monthCode
AlphaEvolve: A coding agent for scientific and algorithmic discoveryarXiv2025-0686257.5
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line InterfacesarXiv2026-0142553.1GitHub · ★ 2,593
Towards End-to-End Automation of AI ResearchNature 20262026-0324941.5GitHub · ★ 7,194
Mem0: Building Production-Ready AI Agents with Scalable Long-Term MemoryEuropean Conference on Artificial Intelligence (ECAI)2025-0464037.6GitHub · ★ 65,741
Why Do Multi-Agent LLM Systems Fail?Advances in Neural Information Processing Systems2025-0361033.9GitHub · ★ 415
Meta-Harness: End-to-End Optimization of Model HarnessesarXiv2026-0318330.5GitHub · ★ 1,221
Memory in the Age of AI AgentsarXiv preprint arXiv:2512.135642025-1226929.9
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language modelsProceedings of the 42nd International Conference on Machine Learning202543529.0GitHub · ★ 13,037
Agentic Context Engineering: Evolving Contexts for Self-Improving Language ModelsarXiv2025-1031028.2GitHub · ★ 1,327
LLMs Get Lost In Multi-Turn ConversationInternational Conference on Learning Representations2025-0545028.1GitHub · ★ 297

🏆 Most-Cited Papers by Year

Top 12 of 2026 by citations
Top 12 of 2025 by citations
PaperDateCitationsCode
A-MEM: Agentic Memory for LLM Agents
Advances in Neural Information Processing Systems
2025-021010GitHub · ★ 974
AlphaEvolve: A coding agent for scientific and algorithmic discovery
arXiv
2025-06862
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
European Conference on Artificial Intelligence (ECAI)
2025-04640GitHub · ★ 65,741
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03610GitHub · ★ 415
LLMs Get Lost In Multi-Turn Conversation
International Conference on Learning Representations
2025-05450GitHub · ★ 297
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models
Proceedings of the 42nd International Conference on Machine Learning
2025435GitHub · ★ 13,037
Group-in-Group Policy Optimization for LLM Agent Training
Advances in Neural Information Processing Systems
2025-05414GitHub · ★ 2,324
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv
2025-10310GitHub · ★ 1,327
PaperBench: Evaluating AI's ability to replicate AI research
arXiv
2025-04280GitHub · ★ 1,300
Memory in the Age of AI Agents
arXiv preprint arXiv:2512.13564
2025-12269
Darwin Godel Machine: Open-ended evolution of self-improving agents
arXiv
2025-05239GitHub · ★ 2,354
DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents
arXiv preprint arXiv:2506.11763
2025-06234GitHub · ★ 832
Top 12 of 2024 by citations
PaperDateCitationsCode
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
arXiv
2024-061177GitHub · ★ 1,445
OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
NeurIPS 2024
2024-041172GitHub · ★ 3,152
Self-rewarding language models
arXiv
2024-01716
Demystifying LLM-Based Software Engineering Agents
Proceedings of the ACM on Software Engineering
2024-07500GitHub · ★ 2,112
TravelPlanner: A Benchmark for Real-World Planning with Language Agents
International Conference on Machine Learning
2024-02481GitHub · ★ 549
WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01452GitHub · ★ 1,125
AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents
International Conference on Learning Representations
2024-05434GitHub · ★ 924
MLE-bench: Evaluating machine learning agents on machine learning engineering
ICLR 2025
2024-10403GitHub · ★ 1,747
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Advances in Neural Information Processing Systems
2024-05360GitHub · ★ 4,017
When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs
Transactions of the Association for Computational Linguistics
2024-06352
WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks?
Proceedings of the 41st International Conference on Machine Learning
2024-03349GitHub · ★ 274
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
ACL 2024
2024-07327GitHub · ★ 518
Top 12 of 2023 by citations
PaperDateCitationsCode
Toolformer: Language Models Can Teach Themselves to Use Tools
Advances in Neural Information Processing Systems
2023-025659
Generative Agents: Interactive Simulacra of Human Behavior
Proceedings of the 36th annual acm symposium on user interface software and technology
2023-045576GitHub · ★ 22,130
Reflexion: language agents with verbal reinforcement learning
NeurIPS 2023
2023-035327GitHub · ★ 3,280
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Advances in Neural Information Processing Systems
2023-054909GitHub · ★ 6,068
Self-Refine: Iterative refinement with self-feedback
NeurIPS 2023
2023-034692GitHub · ★ 822
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
ICLR 2024
2023-103793GitHub · ★ 5,883
Voyager: An Open-Ended Embodied Agent with Large Language Models
Transactions on Machine Learning Research
2023-052314GitHub · ★ 7,221
ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs
International Conference on Learning Representations
2023-072266GitHub · ★ 5,745
WebArena: A Realistic Web Environment for Building Autonomous Agents
ICLR 2024
2023-072026GitHub · ★ 1,611
Gorilla: Large Language Model Connected with Massive APIs
Advances in Neural Information Processing Systems
2023-051642GitHub · ★ 13,037
Mind2Web: Towards a Generalist Agent for the Web
Advances in Neural Information Processing Systems
2023-061441GitHub · ★ 1,028
MemGPT: Towards LLMs as Operating Systems
arXiv preprint arXiv:2310.08560
2023-101336GitHub · ★ 24,819

🧪 Benchmarks

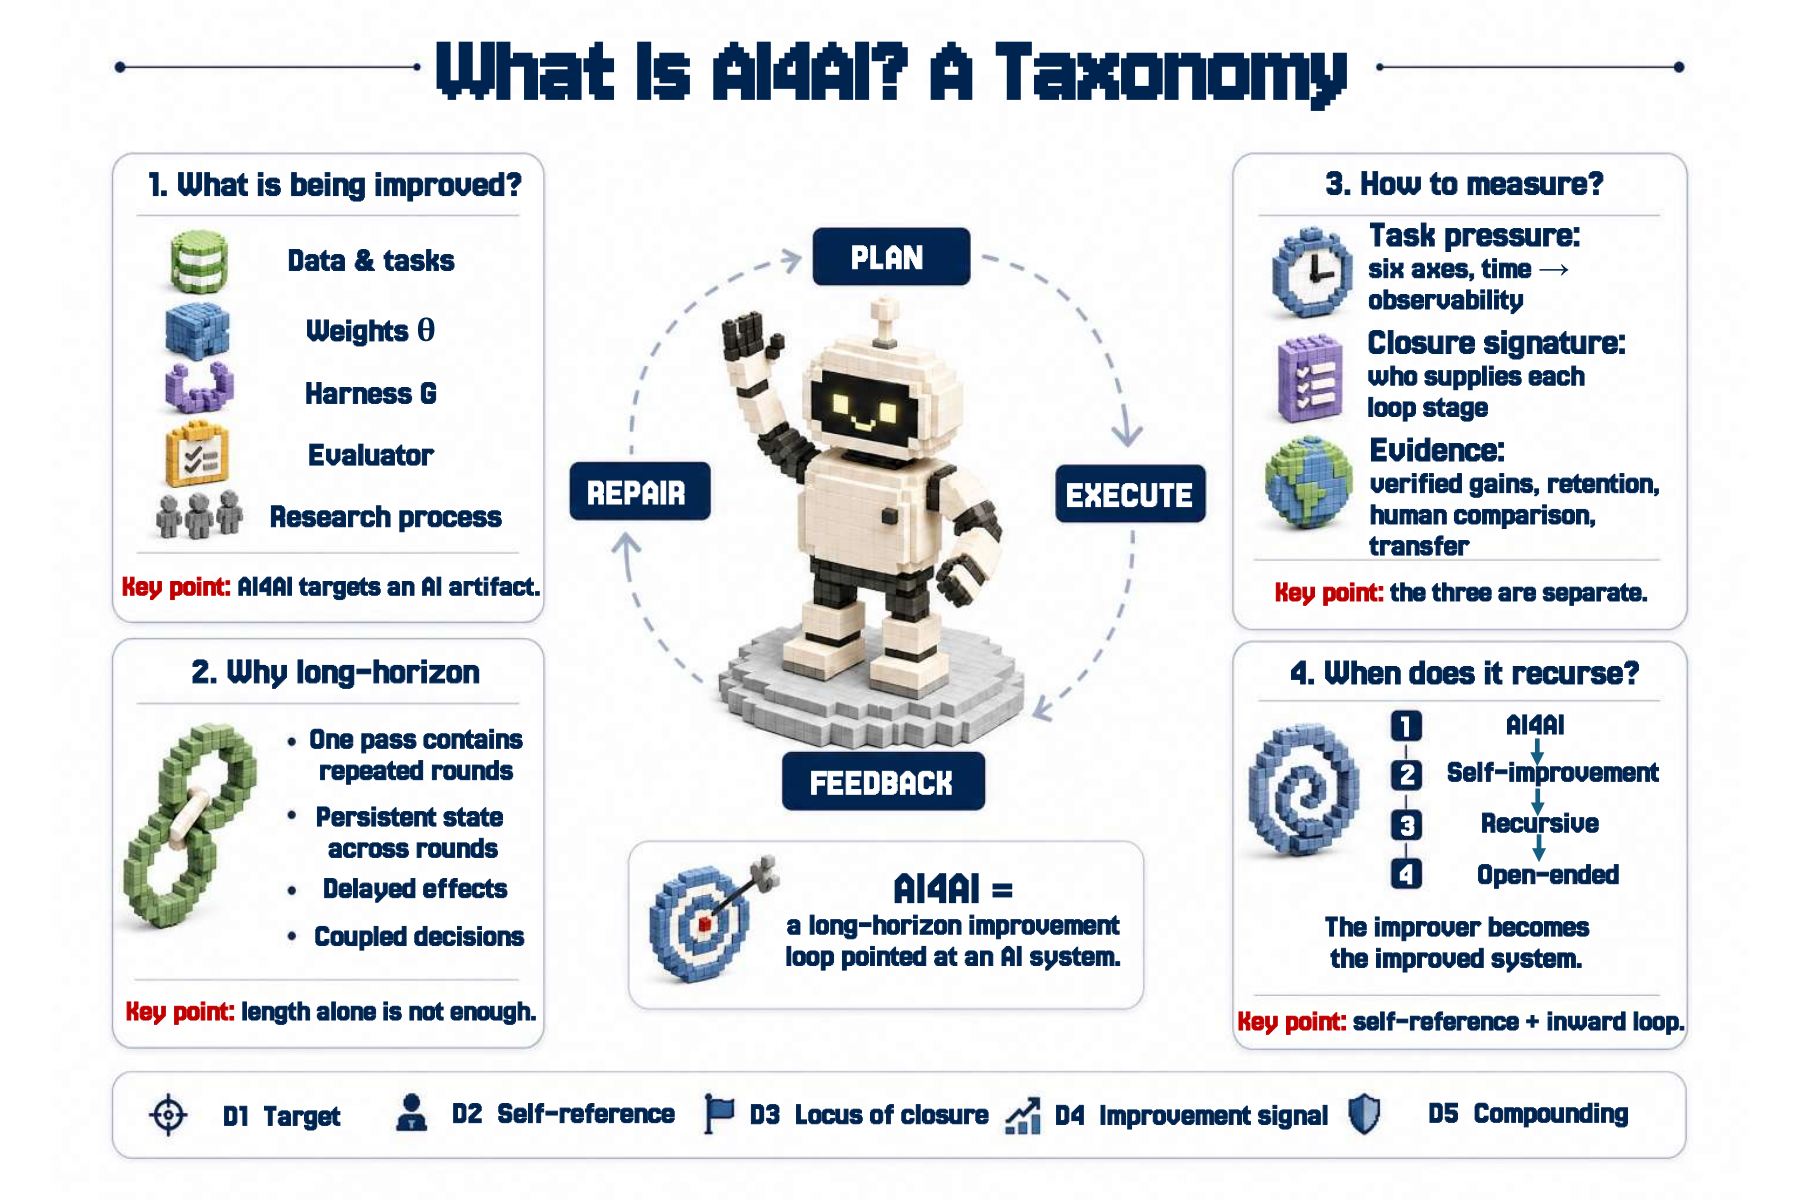
Figure 3 from the companion survey: What Is AI4AI? A Taxonomy

111 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

PaperDateCitationsCode
SWE-Bench ProMax: Benchmarking Agents on Large-Scale Multilingual Code Refactoring
arXiv
2026-085
HarnessOpt-Bench: Evaluating LLMs at Harness Optimization
arXiv preprint arXiv:2608.06301
2026-081
When History Lies: Evaluating and Improving Tool Use under Misleading Multi-Turn Histories
arXiv preprint arXiv:2608.06057
2026-080
DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks
arXiv preprint arXiv:2607.07946
2026-0722GitHub · ★ 1,709
ChainSWE: Benchmarking Coding Agents on Multi-Bug Software Maintenance
arXiv preprint arXiv:2607.02606
2026-071
Kimi K3: Open Frontier Intelligence
arXiv
2026-0733GitHub · ★ 8,832
Can AI Agents Conduct Open-Ended AI Research? Early Evidence from Two Case Studies
arXiv
2026-076
RSIBench-Data: Benchmarking Data-Centric Research for Recursive Self-Improvement
arXiv
2026-079GitHub · ★ 159
Do Agent Benchmarks Measure Capability? Protocol Validity in the Age of Agentic AI
arXiv preprint arXiv:2607.22368
2026-074
Do Agent Optimizers Compound? A Continual-Learning Evaluation on Terminal-Bench 2.0
arXiv preprint arXiv:2607.14004
2026-072GitHub · ★ 8
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-074GitHub · ★ 733
FrontierSWE
Proximal Blog
2026GitHub · ★ 230
WeaveBench: A Long-Horizon, Real-World Benchmark for Computer-Use Agents with Hybrid Interfaces
arXiv preprint arXiv:2606.09426
2026-065
Do LLMs Catch Their Own Mistakes? A Comprehensive Benchmark for Reflective Tool Use LLMs
Findings of the Association for Computational Linguistics: ACL 2026
20260
The Meta-Agent Challenge: Are Current Agents Capable of Autonomous Agent Development?
arXiv preprint arXiv:2606.04455
2026-064GitHub · ★ 24
SWE-Explore: Benchmarking How Coding Agents Explore Repositories
arXiv
2026-0615GitHub · ★ 42
SWE-InfraBench: Evaluating Language Models on Cloud Infrastructure Code
arXiv
2026-060
SWE-Marathon: Can Agents Autonomously Complete Ultra-Long-Horizon Software Work?
arXiv
2026-0610
FARS: A Fully Automated Research System Deployed at Scale
arXiv
2026-064
DeskCraft: Benchmarking Desktop Agents on Professional Workflows and Human-in-the-Loop Collaboration
arXiv preprint arXiv:2606.03103
2026-062GitHub · ★ 92
NatureBench: Can Coding Agents Match the Published SOTA of Nature-Family Papers?
arXiv
2026-062GitHub · ★ 125
OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks
arXiv
2026-0617GitHub · ★ 322
MLS-Bench: A Holistic and Rigorous Assessment of AI Systems on Building Better AI
arXiv preprint arXiv:2605.08678
2026-058GitHub · ★ 118
ProgramBench: Can Language Models Rebuild Programs From Scratch?
arXiv
2026-0526GitHub · ★ 928
RoadmapBench: Evaluating Long-Horizon Agentic Software Development Across Version Upgrades
arXiv
2026-052GitHub · ★ 16
SWE Atlas: Benchmarking Coding Agents Beyond Issue Resolution
arXiv
2026-054GitHub · ★ 72
SWE-Chain: Benchmarking Coding Agents on Chained Release-Level Package Upgrades
arXiv
2026-055GitHub · ★ 15
SWE-Cycle: Benchmarking Code Agents across the Complete Issue Resolution Cycle
arXiv
2026-052GitHub · ★ 0
Breaking, Stale, or Missing? Benchmarking Coding Agents on Project-Level Test Evolution
arXiv
2026-051GitHub · ★ 5
How Far Are We From True Auto-Research?
arXiv
2026-056
Agent^2 RL-Bench: Can LLM Agents Engineer Agentic RL Post-Training?
arXiv preprint arXiv:2604.10547
2026-044GitHub · ★ 14,701
Toward autonomous long-horizon engineering for ML research
arXiv
2026-0410GitHub · ★ 146
KnowU-Bench: Towards Interactive, Proactive, and Personalized Mobile Agent Evaluation
arXiv preprint arXiv:2604.08455
2026-0420GitHub · ★ 77
CI-Repair-Bench: A Repository-Aware Benchmark for Automated Patch Validation via CI Workflows
arXiv
2026-041GitHub · ★ 1
Evaluating LLM-Based 0-to-1 Software Generation in End-to-End CLI Tool Scenarios
arXiv
2026-041GitHub · ★ 2
AutoSOTA: An End-to-End Automated Research System for State-of-the-Art AI Model Discovery
arXiv
2026-0416GitHub · ★ 681
The Long-Horizon Task Mirage? Diagnosing Where and Why Agentic Systems Break
arXiv preprint arXiv:2604.11978
2026-0425
SWE-Milestone: Evaluating AI Agents on Continuous Software Evolution
International Conference on Machine Learning
2026-036GitHub · ★ 73
Beyond pass@1: A Reliability Science Framework for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.29231
2026-036
Towards End-to-End Automation of AI Research
Nature 2026
2026-03249GitHub · ★ 7,194
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-0334GitHub · ★ 566
ReCUBE: Evaluating Repository-Level Context Utilization in Code Generation
arXiv
2026-031GitHub · ★ 1
SWE-CI: Evaluating Agent Capabilities in Maintaining Codebases via Continuous Integration
arXiv
2026-0317GitHub · ★ 178
FeatureBench: Benchmarking Agentic Coding for Complex Feature Development
arXiv
2026-0227GitHub · ★ 94
LongCLI-Bench: A Preliminary Benchmark and Study for Long-horizon Agentic Programming in Command-Line Interfaces
arXiv
2026-0224GitHub · ★ 47
AIRS-Bench: A Suite of Tasks for Frontier AI Research Science Agents
arXiv
2026-0222GitHub · ★ 120
SWE-rebench V2: Language-Agnostic SWE Task Collection at Scale
arXiv preprint arXiv:2602.23866
2026-0214
LUMINA: Long-horizon Understanding for Multi-turn Interactive Agents
Findings of the Association for Computational Linguistics: ACL 2026
2026-011
RepoGenesis: Benchmarking End-to-End Microservice Generation from Readme to Repository
arXiv
2026-016GitHub · ★ 101
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces
arXiv
2026-01425GitHub · ★ 2,593
ARC: Active and Reflection-driven Context Management for Long-Horizon Information Seeking Agents
Findings of the Association for Computational Linguistics: ACL 2026
2026-015
DeepPlanning: Benchmarking Long-Horizon Agentic Planning with Verifiable Constraints
arXiv preprint arXiv:2601.18137
2026-0133
Toward ultra-long-horizon agentic science: Cognitive accumulation for machine learning engineering
arXiv
2026-0124
Towards a Science of Scaling Agent Systems
arXiv
2025-12127GitHub · ★ 53
DoVer: Intervention-Driven Auto Debugging for LLM Multi-Agent Systems
International Conference on Learning Representations
2025-1214GitHub · ★ 41
NL2Repo-Bench: Towards Long-Horizon Repository Generation Evaluation of Coding Agents
arXiv
2025-1247GitHub · ★ 176
SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios
arXiv
2025-1242GitHub · ★ 58
Holistic Agent Leaderboard: The Missing Infrastructure for AI Agent Evaluation
arXiv preprint arXiv:2510.11977
2025-1069GitHub · ★ 311
BuildBench: Benchmarking LLM Agents on Compiling Real-World Open-Source Software
arXiv
2025-091
SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
arXiv
2025-09232GitHub · ★ 527
HeroBench: A Benchmark for Long-Horizon Planning and Structured Reasoning in Virtual Worlds
arXiv preprint arXiv:2508.12782
2025-086GitHub · ★ 14
Hell or High Water: Evaluating Agentic Recovery from External Failures
Second Conference on Language Modeling
2025-086GitHub · ★ 5
OdysseyBench: Evaluating LLM Agents on Long-Horizon Complex Office Application Workflows
arXiv preprint arXiv:2508.09124
2025-0853GitHub · ★ 18
Evaluation and Benchmarking of LLM Agents: A Survey
Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.2
2025-07203GitHub · ★ 21
SWE-MERA: A Dynamic Benchmark for Agenticly Evaluating Large Language Models on Software Engineering Tasks
Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing: System Demonstrations
2025-077
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models
Proceedings of the 42nd International Conference on Machine Learning
2025435GitHub · ★ 13,037
DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents
arXiv preprint arXiv:2506.11763
2025-06234GitHub · ★ 832
Mind2Web 2: Evaluating Agentic Search with Agent-as-a-Judge
arXiv preprint arXiv:2506.21506
2025-0674GitHub · ★ 114
RoboCerebra: A Large-scale Benchmark for Long-horizon Robotic Manipulation Evaluation
Advances in Neural Information Processing Systems
2025-0634GitHub · ★ 78
ALE-Bench: A Benchmark for Long-Horizon Objective-Driven Algorithm Engineering
Advances in Neural Information Processing Systems
2025-0630GitHub · ★ 220
ML-Master: Towards AI-for-AI via integration of exploration and reasoning
arXiv
2025-0655GitHub · ★ 450
MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research
arXiv preprint arXiv:2505.19955
2025-0556GitHub · ★ 36
LLMs Get Lost In Multi-Turn Conversation
International Conference on Learning Representations
2025-05450GitHub · ★ 297
SWE-bench Goes Live!
Advances in Neural Information Processing Systems
2025-0562GitHub · ★ 241
PaperBench: Evaluating AI's ability to replicate AI research
arXiv
2025-04280GitHub · ★ 1,300
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03610GitHub · ★ 415
A Survey on Evaluation of LLM-based Agents
Findings of the Association for Computational Linguistics: ACL 2026
2025-03226
Robotouille: An Asynchronous Planning Benchmark for LLM Agents
International Conference on Learning Representations
2025-0238GitHub · ★ 49
DI-BENCH: Benchmarking Large Language Models on Dependency Inference with Testable Repositories at Scale
Findings of the Association for Computational Linguistics: ACL 2025
2025-018GitHub · ★ 7
TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks
Advances in Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track
2024-12308GitHub · ★ 781
RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts
arXiv
2024-11152GitHub · ★ 163
MLE-bench: Evaluating machine learning agents on machine learning engineering
ICLR 2025
2024-10403GitHub · ★ 1,747
Agent-as-a-Judge: Evaluate Agents with Agents
Forty-second International Conference on Machine Learning
2024-10223GitHub · ★ 828
Windows Agent Arena: Evaluating Multi-Modal OS Agents at Scale
International Conference on Machine Learning
2024-09208GitHub · ★ 901
ToolSandbox: A Stateful, Conversational, Interactive Evaluation Benchmark for LLM Tool Use Capabilities
Findings of the Association for Computational Linguistics: NAACL 2025
2024-08263GitHub · ★ 286
OfficeBench: Benchmarking Language Agents across Multiple Applications for Office Automation
arXiv preprint arXiv:2407.19056
2024-0754GitHub · ★ 46
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
ACL 2024
2024-07327GitHub · ★ 518
Introducing SWE-bench Verified
2024
WebCanvas: Benchmarking Web Agents in Online Environments
ICML 2024 Workshop on Agentic Markets
2024-06125GitHub · ★ 281
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
arXiv
2024-061177GitHub · ★ 1,445
NATURAL PLAN: Benchmarking LLMs on Natural Language Planning
arXiv preprint arXiv:2406.04520
2024-06141GitHub · ★ 59
AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents
International Conference on Learning Representations
2024-05434GitHub · ★ 924
Benchmarking Mobile Device Control Agents across Diverse Configurations
arXiv preprint arXiv:2404.16660
2024-0449GitHub · ★ 33
OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
NeurIPS 2024
2024-041172GitHub · ★ 3,152
WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks?
Proceedings of the 41st International Conference on Machine Learning
2024-03349GitHub · ★ 274
OmniACT: A Dataset and Benchmark for Enabling Multimodal Generalist Autonomous Agents for Desktop and Web
Computer Vision -- ECCV 2024
2024-02170
WebLINX: Real-World Website Navigation with Multi-Turn Dialogue
International Conference on Machine Learning
2024-02187GitHub · ★ 163
TravelPlanner: A Benchmark for Real-World Planning with Language Agents
International Conference on Machine Learning
2024-02481GitHub · ★ 549
WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01452GitHub · ★ 1,125
VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-0141GitHub · ★ 487
MinePlanner: A Benchmark for Long-Horizon Planning in Large Minecraft Worlds
Proceedings of the 6th ICAPS Workshop on the International Planning Competition (WIPC)
2023-128GitHub · ★ 23
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
ICLR 2024
2023-103793GitHub · ★ 5,883
AgentBench: Evaluating LLMs as Agents
International Conference on Learning Representations
2023-081307GitHub · ★ 3,742
ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs
International Conference on Learning Representations
2023-072266GitHub · ★ 5,745
WebArena: A Realistic Web Environment for Building Autonomous Agents
ICLR 2024
2023-072026GitHub · ★ 1,611
Mind2Web: Towards a Generalist Agent for the Web
Advances in Neural Information Processing Systems
2023-061441GitHub · ★ 1,028
BEHAVIOR-1K: A benchmark for embodied AI with 1,000 everyday activities and realistic simulation
Proceedings of The 6th Conference on Robot Learning
2023382GitHub · ★ 1,708
WebShop: Towards Scalable Real-World Web Interaction with Grounded Language Agents
Advances in Neural Information Processing Systems
2022-071369GitHub · ★ 598
WebGPT: Browser-assisted question-answering with human feedback
arXiv preprint arXiv:2112.09332
2021-122072
ALFRED: A Benchmark for Interpreting Grounded Instructions for Everyday Tasks
Proceedings of the IEEE/CVF conference on computer vision and pattern recognition
2019-121198GitHub · ★ 532
World of Bits: An Open-Domain Platform for Web-Based Agents
Proceedings of the 34th International Conference on Machine Learning
2017352

🛠️ Harness Design

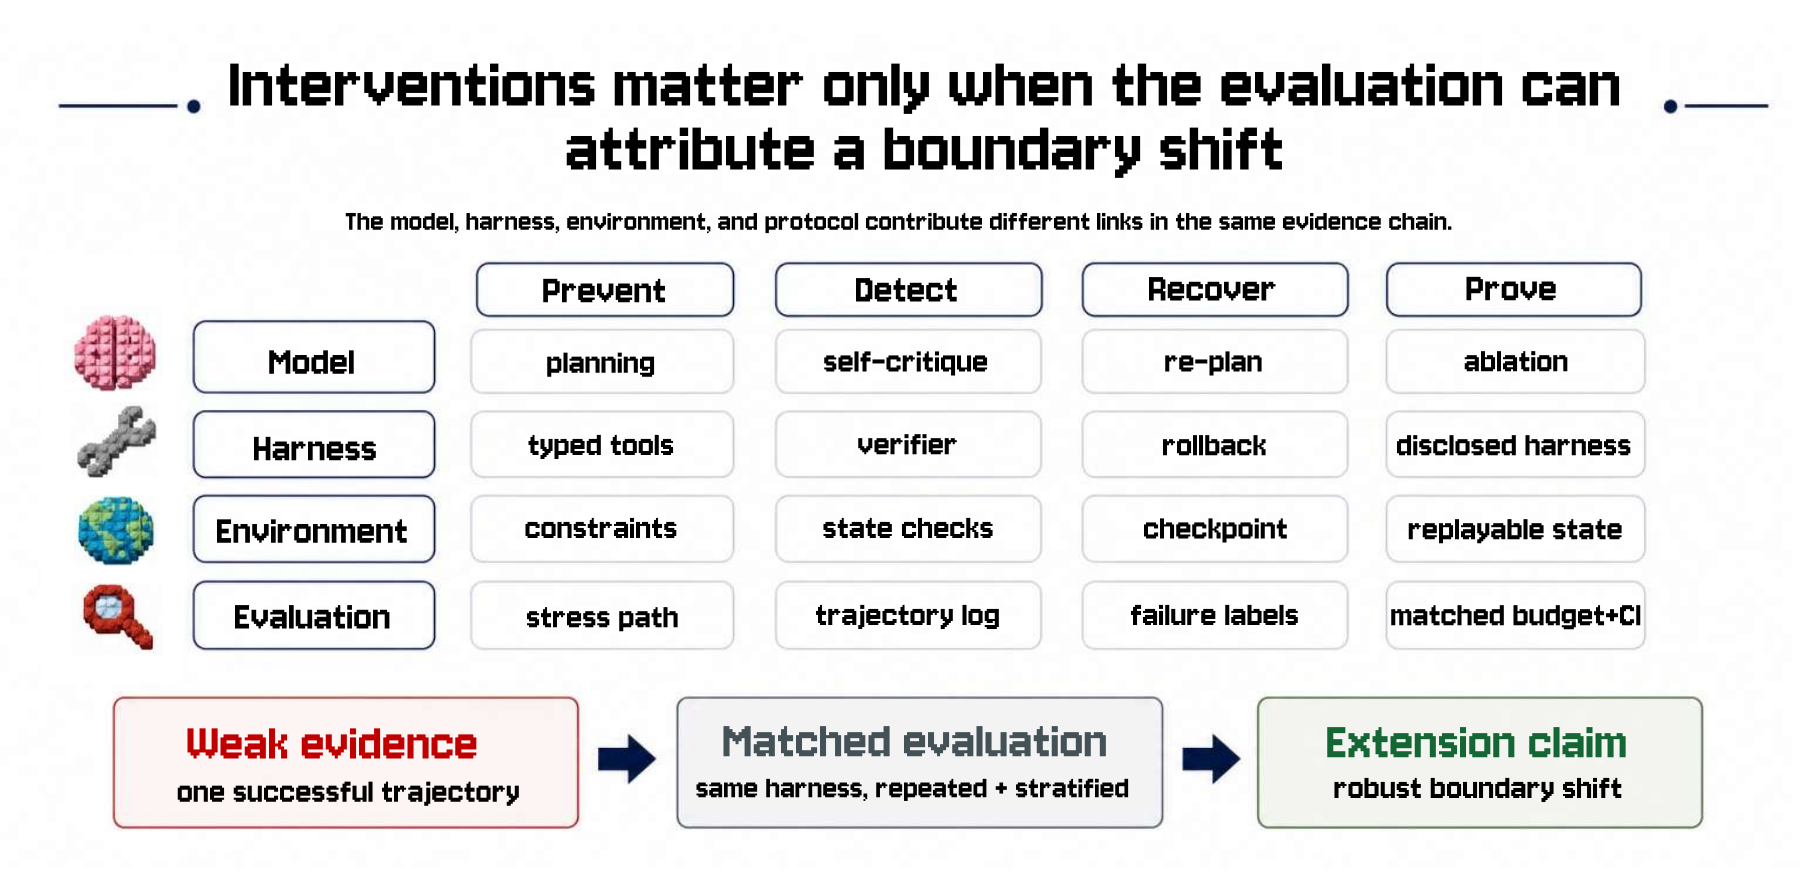
Evidence chain for reliable harness interventions

101 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

PaperDateCitationsCode
PILOT in the Loop: Live Self-Improvement for Long-Horizon Agents
arXiv
2026-081
Recursive Experiential-Working Memory Evolution for Long-Horizon Agent Harnesses
arXiv
2026-082GitHub · ★ 214
Prime Agent: A Self-Improving RLM Harness
arXiv
2026-083GitHub · ★ 21,117
Recursive Self-Improvement in AI: From Bounded Self-Refinement to Autonomous Research Loops
2026-0712
Kimi K3: Open Frontier Intelligence
arXiv
2026-0733GitHub · ★ 8,832
Recursive harness self-improvement
arXiv
2026-0712
ACM: Agentic Context Management for Long Horizon Tasks
arXiv
2026-071GitHub · ★ 38
CompactionRL: Reinforcement Learning with Context Compaction for Long-Horizon Agents
arXiv
2026-073
Structured Feedback Improves Repair in an LLM Agent Loop
arXiv
2026-071
Self-Improvements in Modern Agentic Systems: A Survey
2026-0710GitHub · ★ 497
MetaSkill-Evolve: Recursive Self-Improvement of LLM Agents via Two-Timescale Meta-Skill Evolution
arXiv
2026-079
Rethinking the Evaluation of Harness Evolution for Agents
arXiv
2026-0721GitHub · ★ 40
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-074GitHub · ★ 733
HarnessX: A Composable, Adaptive, and Evolvable Agent Harness Foundry
arXiv
2026-0625
The Past Is Prologue: A Plug-in Controller for Selective Updates in Sequentially Evolving LLM Memory
arXiv
2026-061
From Question Answering to Task Completion: A Survey on Agent System and Harness Design
arXiv
2026-065
Agent Harness for Large Language Model Agents: A Survey
Preprints
20262GitHub · ★ 357
Scaffold Effects on GAIA: A Controlled Comparison
arXiv
2026-060
Context Compression for LLM Agents: A Survey of Methods, Failure Modes, and Evaluation
Preprints
20260
The Verification Horizon: No Silver Bullet for Coding Agent Rewards
arXiv
2026-064
Self-Harness: Harnesses That Improve Themselves
arXiv
2026-0642GitHub · ★ 110
Stop Comparing LLM Agents Without Disclosing the Harness
Second Workshop on Agents in the Wild: Safety, Security, and Beyond
20268
Are We Ready For An Agent-Native Memory System?
arXiv
2026-0612GitHub · ★ 148
MOSS: Self-Evolution through Source-Level Rewriting in Autonomous Agent Systems
arXiv
2026-058GitHub · ★ 25
Ask Early, Ask Late, Ask Right: When Does Clarification Timing Matter for Long-Horizon Agents?
arXiv
2026-052
From Raw Experience to Skill Consumption: A Systematic Study of Model-Generated Agent Skills
arXiv
2026-0515
Code as Agent Harness
arXiv
2026-0526GitHub · ★ 704
SkillOS: Learning Skill Curation for Self-Evolving Agents
arXiv
2026-0536
Adapting the Interface, Not the Model: Runtime Harness Adaptation for Deterministic LLM Agents
arXiv
2026-0522GitHub · ★ 222
LoopTrap: Termination Poisoning Attacks on LLM Agents
arXiv
2026-051
Learning Agent-Compatible Context Management for Long-Horizon Tasks
arXiv
2026-056
SpecBench: Measuring Reward Hacking in Long-Horizon Coding Agents
arXiv
2026-0514GitHub · ★ 15
Toward autonomous long-horizon engineering for ML research
arXiv
2026-0410GitHub · ★ 146
Squeez: Task-Conditioned Tool-Output Pruning for Coding Agents
arXiv preprint arXiv:2604.04979
2026-042GitHub · ★ 23
Dive into Claude Code: The Design Space of Today's and Future AI Agent Systems
arXiv
2026-0433GitHub · ★ 2,119
Escher-Loop: Mutual Evolution by Closed-Loop Self-Referential Optimization
arXiv
2026-046GitHub · ★ 8
Reinforced Agent: Inference-Time Feedback for Tool-Calling Agents
Proceedings of the Fifth Workshop on Generation, Evaluation and Metrics (GEM)
2026-044
From Agent Loops to Structured Graphs:A Scheduler-Theoretic Framework for LLM Agent Execution
arXiv
2026-042
ContextBudget: Budget-Aware Context Management for Long-Horizon Search Agents
arXiv preprint arXiv:2604.01664
2026-0410GitHub · ★ 9
ContextWeaver: Selective and Dependency-Structured Memory Construction for LLM Agents
arXiv preprint arXiv:2604.23069
2026-042
Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
arXiv preprint arXiv:2604.08224
2026-0461
Meta-Harness: End-to-End Optimization of Model Harnesses
arXiv
2026-03183GitHub · ★ 1,221
Natural-Language Agent Harnesses
arXiv
2026-0343
Bilevel Autoresearch: Meta-Autoresearching Itself
arXiv
2026-035GitHub · ★ 198
Schema First Tool APIs for LLM Agents: A Controlled Study of Tool Misuse, Recovery, and Budgeted Performance
arXiv
2026-035GitHub · ★ 0
DARWIN: Dynamic Agentically Rewriting Self-Improving Network
arXiv
2026-021GitHub · ★ 0
SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
arXiv preprint arXiv:2601.16746
2026-0137GitHub · ★ 318
Beyond Static Summarization: Proactive Memory Extraction for LLM Agents
arXiv preprint arXiv:2601.04463
2026-0116
Memory in the Age of AI Agents
arXiv preprint arXiv:2512.13564
2025-12269
Step-DeepResearch Technical Report
arXiv preprint arXiv:2512.20491
2025-1213GitHub · ★ 573
Towards a Science of Scaling Agent Systems
arXiv
2025-12127GitHub · ★ 53
DoVer: Intervention-Driven Auto Debugging for LLM Multi-Agent Systems
International Conference on Learning Representations
2025-1214GitHub · ★ 41
PARC: An Autonomous Self-Reflective Coding Agent for Robust Execution of Long-Horizon Tasks
arXiv
2025-123
Solving a Million-Step LLM Task with Zero Errors
arXiv preprint arXiv:2511.09030
2025-1123GitHub · ★ 46
LongCodeZip: Compress Long Context for Code Language Models
2025 40th IEEE/ACM International Conference on Automated Software Engineering (ASE)
2025-1046GitHub · ★ 168
ACON: Optimizing Context Compression for Long-horizon LLM Agents
arXiv preprint arXiv:2510.00615
2025-1096GitHub · ★ 117
Scaling Long-Horizon LLM Agent via Context-Folding
arXiv preprint arXiv:2510.11967
2025-10111GitHub · ★ 189
AgentFold: Long-Horizon Web Agents with Proactive Context Management
arXiv preprint arXiv:2510.24699
2025-1076GitHub · ★ 19,978
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv
2025-10310GitHub · ★ 1,327
WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research
arXiv preprint arXiv:2509.13312
2025-0944GitHub · ★ 19,978
ReSum: Unlocking Long-Horizon Search Intelligence via Context Summarization
arXiv preprint arXiv:2509.13313
2025-09113GitHub · ★ 19,978
Reducing Cost of LLM Agents with Trajectory Reduction
Proceedings of the ACM on Software Engineering
2025-0944
Where LLM Agents Fail and How They can Learn From Failures
arXiv
2025-09118GitHub · ★ 107
Memp: Exploring Agent Procedural Memory
Findings of the Association for Computational Linguistics: ACL 2026
2025-0867GitHub · ★ 40
The Complexity Trap: Simple Observation Masking Is as Efficient as LLM Summarization for Agent Context Management
arXiv preprint arXiv:2508.21433
2025-0830
Magentic-UI: Towards Human-in-the-loop Agentic Systems
arXiv
2025-0751GitHub · ★ 10,091
ReVeal: Self-Evolving Code Agents via Reliable Self-Verification
The Fourteenth International Conference on Learning Representations
2025-0614
SWE-Dev: Building Software Engineering Agents with Training and Inference Scaling
Findings of the Association for Computational Linguistics: ACL 2025
2025-0627GitHub · ★ 66
MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents
arXiv preprint arXiv:2506.15841
2025-06200GitHub · ★ 336
Runaway is Ashamed, But Helpful: On the Early-Exit Behavior of Large Language Model-based Agents in Embodied Environments
Findings of the Association for Computational Linguistics: EMNLP 2025
2025-0511GitHub · ★ 2
Is there a half-life for the success rates of AI agents?
arXiv preprint arXiv:2505.05115
2025-055
Darwin Godel Machine: Open-ended evolution of self-improving agents
arXiv
2025-05239GitHub · ★ 2,354
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
European Conference on Artificial Intelligence (ECAI)
2025-04640GitHub · ★ 65,741
Process Reward Models That Think
Transactions on Machine Learning Research
2025-04111GitHub · ★ 92
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03610GitHub · ★ 415
Learning to Contextualize Web Pages for Enhanced Decision Making by LLM Agents
The Thirteenth International Conference on Learning Representations
2025-0322GitHub · ★ 7
Process Reward Models for LLM Agents: Practical Framework and Directions
arXiv
2025-0285GitHub · ★ 60
A-MEM: Agentic Memory for LLM Agents
Advances in Neural Information Processing Systems
2025-021010GitHub · ★ 974
Practical Considerations for Agentic LLM Systems
arXiv
2024-1217
Godel Agent: A self-referential agent framework for recursive self-improvement
arXiv
2024-1023GitHub · ★ 223
Agent-as-a-Judge: Evaluate Agents with Agents
Forty-second International Conference on Machine Learning
2024-10223GitHub · ★ 828
Agent Workflow Memory
Forty-second International Conference on Machine Learning
2024-09282GitHub · ★ 472
Automated design of agentic systems
ICLR 2025
2024-08322GitHub · ★ 1,638
LLM Critics Help Catch LLM Bugs
arXiv preprint arXiv:2407.00215
2024-07168
Demystifying LLM-Based Software Engineering Agents
Proceedings of the ACM on Software Engineering
2024-07500GitHub · ★ 2,112
When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs
Transactions of the Association for Computational Linguistics
2024-06352
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Advances in Neural Information Processing Systems
2024-05360GitHub · ★ 4,017
JARVIS-1: Open-World Multi-Task Agents With Memory-Augmented Multimodal Language Models
IEEE Transactions on Pattern Analysis & Machine Intelligence
2023-11217GitHub · ★ 417
Large Language Models Cannot Self-Correct Reasoning Yet
International Conference on Learning Representations
2023-101198
MemGPT: Towards LLMs as Operating Systems
arXiv preprint arXiv:2310.08560
2023-101336GitHub · ★ 24,819
Self-Taught Optimizer (STOP): Recursively self-improving code generation
Conference on Language Modeling
2023-10140GitHub · ★ 53
Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models
International Conference on Machine Learning
2023-10642GitHub · ★ 863
Cognitive Architectures for Language Agents
Transactions on Machine Learning Research
2023-09521
ExpeL: LLM Agents Are Experiential Learners
AAAI 2024
2023-08922GitHub · ★ 243
CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing
International Conference on Learning Representations
2023-05931GitHub · ★ 745
AdaPlanner: Adaptive Planning from Feedback with Language Models
Advances in Neural Information Processing Systems
2023-05251GitHub · ★ 128
Voyager: An Open-Ended Embodied Agent with Large Language Models
Transactions on Machine Learning Research
2023-052314GitHub · ★ 7,221
Generative Agents: Interactive Simulacra of Human Behavior
Proceedings of the 36th annual acm symposium on user interface software and technology
2023-045576GitHub · ★ 22,130
Self-Refine: Iterative refinement with self-feedback
NeurIPS 2023
2023-034692GitHub · ★ 822
Reflexion: language agents with verbal reinforcement learning
NeurIPS 2023
2023-035327GitHub · ★ 3,280
ReAct: Synergizing Reasoning and Acting in Language Models
International Conference on Learning Representations (ICLR)
2022-1011375GitHub · ★ 4,183

🧠 Model Design

Model-side interventions across plan, execute, feedback, and repair

26 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

PaperDateCitationsCode
Single-Rollout Asynchronous Optimization for Agentic Reinforcement Learning
arXiv preprint arXiv:2607.07508
2026-0718
Kimi K3: Open Frontier Intelligence
arXiv
2026-0733GitHub · ★ 8,832
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-074GitHub · ★ 733
Autodata: An Agentic Data Scientist to Create High Quality Synthetic Data
arXiv
2026-067
TREX: Automating LLM Fine-tuning via Agent-Driven Tree-based Exploration
arXiv preprint arXiv:2604.14116
2026-043
CAPO: Critic-Guided Action-Aligned Policy Optimization for Advancing LLM Agent Capabilities
arXiv preprint arXiv:2604.18401
2026-049GitHub · ★ 1,671
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-0334GitHub · ★ 566
Hindsight Credit Assignment for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.08754
2026-0340
ASI-Evolve: AI Accelerates AI
arXiv
2026-035GitHub · ★ 857
Towards Execution-Grounded Automated AI Research
arXiv
2026-0113GitHub · ★ 84
IterResearch: Rethinking Long-Horizon Agents with Interaction Scaling
arXiv preprint arXiv:2511.07327
2025-1117GitHub · ★ 19,978
Stabilizing Off-Policy Training for Long-Horizon LLM Agent via Turn-Level Importance Sampling and Clipping-Triggered Normalization
arXiv preprint arXiv:2511.20718
2025-115GitHub · ★ 0
SALT: Step-level Advantage Assignment for Long-horizon Agents via Trajectory Graph
Findings of the Association for Computational Linguistics: EACL 2026
2025-1020
AgentGym-RL: Training LLM Agents for Long-Horizon Decision Making through Multi-Turn Reinforcement Learning
arXiv preprint arXiv:2509.08755
2025-0967GitHub · ★ 868
AlphaEvolve: A coding agent for scientific and algorithmic discovery
arXiv
2025-06862
Group-in-Group Policy Optimization for LLM Agent Training
Advances in Neural Information Processing Systems
2025-05414GitHub · ★ 2,324
Plan-and-Act: Improving Planning of Agents for Long-Horizon Tasks
International Conference on Machine Learning
2025-03213GitHub · ★ 46
Reinforcement Learning for Long-Horizon Interactive LLM Agents
arXiv preprint arXiv:2502.01600
2025-02103
Self-rewarding language models
arXiv
2024-01716
Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models
International Conference on Machine Learning
2023-10642GitHub · ★ 863
Gorilla: Large Language Model Connected with Massive APIs
Advances in Neural Information Processing Systems
2023-051642GitHub · ★ 13,037
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Advances in Neural Information Processing Systems
2023-054909GitHub · ★ 6,068
Toolformer: Language Models Can Teach Themselves to Use Tools
Advances in Neural Information Processing Systems
2023-025659
ReAct: Synergizing Reasoning and Acting in Language Models
International Conference on Learning Representations (ICLR)
2022-1011375GitHub · ★ 4,183
STaR: Bootstrapping reasoning with reasoning
NeurIPS 2022
2022-031069
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Advances in Neural Information Processing Systems
2022-0122031GitHub · ★ 41

📚 How We Curate

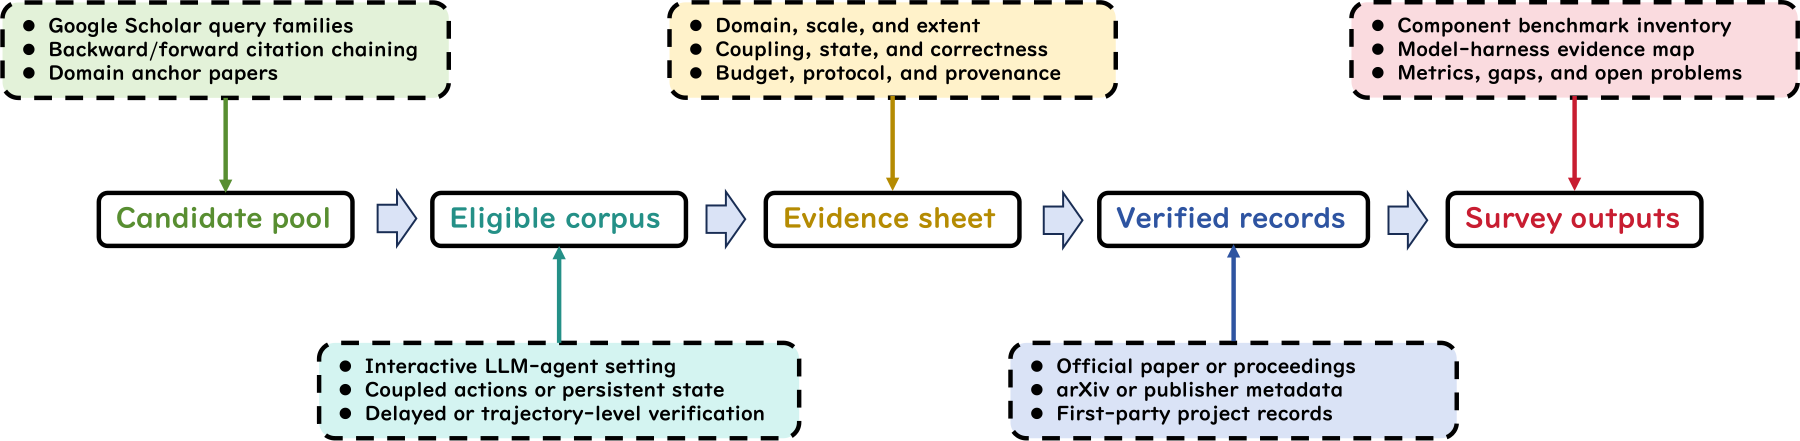
Search, screening, extraction, coding, and verification workflow

  1. Discover: survey searches, backward/forward citation chaining, and community suggestions.
  2. Verify: exact title and identifier checks against primary scholarly sources.
  3. Classify: Benchmarks, Harness Design, and Model Design, allowing justified overlap.
  4. Audit when evidence permits: stage ownership plus independent G/R/H/T coordinates.
  5. Refresh weekly: citation counts and rankings every Monday, alongside the month's top papers, releases, blogs, and research news.

📄 Citation

If this map or its evidence audit helps your work, please cite the companion survey:

Copy BibTeX
@misc{wu2026eveai4ai,
  title   = {{AI4AI} Survey: From Long-Horizon Agents to Recursive Self-Improvement---Definitions, Reliable Horizons, and Open Problems},
  author  = {Wu, Kai and Lyu, Hao and Luo, Zhen and Wang, Chaofan and
             Ye, Siyu and Lin, Jinghao and Ji, Xiaozhong and Jiang, Boyuan and
             Wang, Shengzhi and Wang, Zihan and Ye, Yiwen and Wang, Hao and
             Wang, Zimu and Liu, Wenzhe and Wang, Ruobing and Cai, Kai and
             Xiong, Mingliang and Fang, Wen and Liu, Mingqing and
             Zhang, Yifan and Yang, Lei and Hu, Xiaobin and Liu, Qingwen},
  howpublished = {Preprints.org},
  year    = {2026},
  doi     = {10.20944/preprints202608.2108.v1},
  url     = {https://doi.org/10.20944/preprints202608.2108.v1}
}

🤝 Contributing

Have something to add? Missing a paper, official code link, or stronger primary-source evidence? Open a pull request or use the paper-suggestion form. Read the contribution guide →

agent-benchmarks
agent-harness
agi
ai4ai
ai-agents
ai-research
automated-ai-research
autonomous-agents
awesome-list
benchmark
deep-learning
llm
llm-agents
long-horizon-agents
machine-learning
paper-list
recursive-self-improvement
research-papers
self-improvement
survey

Contributors

KaiWU5

24 commits

KaiWU5/Awesome-AI4AI

AI4AI Survey: can AI reliably improve AI? 223 papers on long-horizon agents, benchmarks, harness design, and recursive self-improvement · updated weekly

Python

172

29 commits

updated Sep 21, 2026

See the code

README

Towards AI that improves AI — the plan, execute, feedback, repair loop

🚀 Awesome AI4AI

AI4AI Survey: From Long-Horizon Agents to Recursive Self-Improvement
Definitions, Reliable Horizons, and Open Problems · 23 authors · 7 institutions

Updated weekly with the month's top AI-for-AI papers, news, and blogs. Stay tuned 🔥
Paper, nice layout Paper on Preprints.org Project Site RSIHub Harness Blog DOI


Why This Repo

🔄 Automatic rankings
Citations, GitHub stars, and rankings refresh every Monday.
🗞️ Weekly update
The month's top papers and releases, re-ranked every week against primary sources.
🧭 Survey-grounded map
From long-horizon agents to recursive self-improvement.

Star ⭐ to save the map · Watch 👀 for weekly updates · Share 🔁 with your lab

What's New

  • 📄 2026-08-30 — Companion survey now online. Read AI4AI Survey: From Long-Horizon Agents to Recursive Self-Improvement—Definitions, Reliable Horizons, and Open Problems.
  • 🔄 Every Monday — Automatic refresh. Citations, GitHub stars, and recent-paper/yearly rankings update automatically.
  • 🚀 2026-09-16 — Latest weekly edition published. The living catalog and source-verified news digest are up to date.
🗂️ Explore the full collection

📅 Weekly Update · Monthly Top 10

Updated 2026-09-16 · The month's top stories, refreshed every Monday alongside citation rankings.

How we select: The top stories from the trailing 30 days, scored on publisher authority, discussion volume, whether a concrete verifiable result is reported, whether it changes what agent builders do now, whether an artifact was released, and expected durability. Only primary sources are cited, and performance claims remain attributed to their publishers.

Date · TypeNewsWhy it matters
2026‑09‑11
Model release
Introducing Fugu Max and Fugu Ultra v2: Orchestrating the Pareto Frontier
Sakana AI
Sakana AI describes a model trained to route tasks across a fixed pool of open-weight and specialized models and to recursively call instances of itself. It reports 48.3 on Chartography against 27.3 for Opus 5, and says the scores are reached without Fable 5, Fable 5.1 or GPT-6 Astra in the agent pool.
2026‑09‑10
Open-weight release
DeepSeek-V4.1-Flash
DeepSeek
DeepSeek publishes weights on Hugging Face for a 552B mixture-of-experts model built on a new causal encoder-decoder architecture that activates roughly 8B parameters on input and 16B on output. It reports 90.6 on Terminal-Bench 2.1 and 74.2 on DeepSWE v1.1, and says the KV cache needs a quarter of the prior generation's HBM.
2026‑09‑10
Harness release
Introducing the Agents API
OpenAI
OpenAI ships the harness that runs Codex as a managed service in public beta, saying it handles session orchestration, context compaction, sub-agent coordination and recovery while developers supply tools and choose a sandbox. It offers versioned harness access alongside each model launch.
2026‑09‑10
Model release
Introducing SWE-2: Pushing the Pareto Frontier
Cognition
Cognition says it scaled reinforcement learning to a 2.8T-parameter Kimi K3 base for the first time, training every reasoning-effort level in a single run with a cost-penalized reward. It reports 50.0 on its own FrontierCode 1.1 Main at 64 percent lower cost than Fable 5.1, and 58 percent fewer turns than SWE-1.7.
2026‑09‑08
Paper
NeoHorse-1: Towards Recursive Self-Improvement via Agentic Post-Training with Routing Harness
arXiv
The authors log predicted capability demand, chosen service tier and interaction outcome for each turn, then reuse those routing signals as a three-stage fine-tuning curriculum and an evaluation-selection-update loop. They report macro-average gains from 58.94 to 64.87 at 4B and 65.60 to 69.04 at 9B across eleven benchmarks, with weights and code released.
2026‑09‑03
Paper
EvoHarnessBench: Can Your Agents Keep Pace with an Evolving Harness?
arXiv
The authors hold tasks fixed and instead grow the harness across tools, skills and agents over 17 multi-stage streams covering 802 tasks, 520 tools, 42 skills and 62 agents. They report harness-induced forgetting of up to 34.7 percent backward transfer on the agents axis with model parameters unchanged.
2026‑09‑03
Model release
GPT-6 Astra: A new generation of intelligence
OpenAI
OpenAI reports 64.6 percent on Terminal-Bench Science 0.1 and 57.9 percent on Terminal-Bench 4.0, and introduces experimental Codex notes and searchable history across context windows for long-running work.
2026‑09‑02
Model update
Introducing Gemini 3.8 Flash and 3.8 Flash Cyber
Google
Google reports 54.9 percent on HLE-Verified for Gemini 3.8 Flash while retaining the introductory token prices of 3.7 Flash. It says long-running agentic loops helped evaluate and refine the models, and releases Flash Cyber through trusted-defender access.
2026‑09‑01
Model release
Introducing Claude Fable 5.1 and Claude Mythos 5.1
Anthropic
Anthropic reports 52.6 percent on Terminal-Bench-Science 0.1 versus 24.7 percent for Fable 5, and estimates that lower cache-read pricing reduces highly agentic workload costs by up to roughly 45 percent.
2026‑08‑31
Paper
WHALE: A Simple Recipe for Joint Harness-Weight Optimization
arXiv
The authors alternate model-weight updates with executable harness search, reporting gains of 4.15 to 24.38 percentage points over the tested single-component and prompt-weight baselines across three domains with Qwen3.5-2B/4B agents. Code is released for reproducing the joint optimization recipe.

Want next month's news? Watch the repository. Citation counts, rankings, and the month's top stories refresh every Monday. Browse past editions →

📈 Live Rankings

Citation counts are current through 2026-09-21 from Semantic Scholar and OpenAlex. Rankings are discovery aids, not quality scores; audit evidence remains independent of popularity. GitHub stars are snapshots from 2026-09-21. For papers indexed as multiple versions, retain the largest title-verified count reported by the configured sources. All yearly rankings use first public appearance year; a later venue year never moves a paper into a newer cohort.

🔥 Recent Papers by Average Monthly Citations

PaperVenueDateCitationsAvg. cites/monthCode
AlphaEvolve: A coding agent for scientific and algorithmic discoveryarXiv2025-0686257.5
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line InterfacesarXiv2026-0142553.1GitHub · ★ 2,593
Towards End-to-End Automation of AI ResearchNature 20262026-0324941.5GitHub · ★ 7,194
Mem0: Building Production-Ready AI Agents with Scalable Long-Term MemoryEuropean Conference on Artificial Intelligence (ECAI)2025-0464037.6GitHub · ★ 65,741
Why Do Multi-Agent LLM Systems Fail?Advances in Neural Information Processing Systems2025-0361033.9GitHub · ★ 415
Meta-Harness: End-to-End Optimization of Model HarnessesarXiv2026-0318330.5GitHub · ★ 1,221
Memory in the Age of AI AgentsarXiv preprint arXiv:2512.135642025-1226929.9
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language modelsProceedings of the 42nd International Conference on Machine Learning202543529.0GitHub · ★ 13,037
Agentic Context Engineering: Evolving Contexts for Self-Improving Language ModelsarXiv2025-1031028.2GitHub · ★ 1,327
LLMs Get Lost In Multi-Turn ConversationInternational Conference on Learning Representations2025-0545028.1GitHub · ★ 297

🏆 Most-Cited Papers by Year

Top 12 of 2026 by citations
Top 12 of 2025 by citations
PaperDateCitationsCode
A-MEM: Agentic Memory for LLM Agents
Advances in Neural Information Processing Systems
2025-021010GitHub · ★ 974
AlphaEvolve: A coding agent for scientific and algorithmic discovery
arXiv
2025-06862
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
European Conference on Artificial Intelligence (ECAI)
2025-04640GitHub · ★ 65,741
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03610GitHub · ★ 415
LLMs Get Lost In Multi-Turn Conversation
International Conference on Learning Representations
2025-05450GitHub · ★ 297
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models
Proceedings of the 42nd International Conference on Machine Learning
2025435GitHub · ★ 13,037
Group-in-Group Policy Optimization for LLM Agent Training
Advances in Neural Information Processing Systems
2025-05414GitHub · ★ 2,324
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv
2025-10310GitHub · ★ 1,327
PaperBench: Evaluating AI's ability to replicate AI research
arXiv
2025-04280GitHub · ★ 1,300
Memory in the Age of AI Agents
arXiv preprint arXiv:2512.13564
2025-12269
Darwin Godel Machine: Open-ended evolution of self-improving agents
arXiv
2025-05239GitHub · ★ 2,354
DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents
arXiv preprint arXiv:2506.11763
2025-06234GitHub · ★ 832
Top 12 of 2024 by citations
PaperDateCitationsCode
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
arXiv
2024-061177GitHub · ★ 1,445
OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
NeurIPS 2024
2024-041172GitHub · ★ 3,152
Self-rewarding language models
arXiv
2024-01716
Demystifying LLM-Based Software Engineering Agents
Proceedings of the ACM on Software Engineering
2024-07500GitHub · ★ 2,112
TravelPlanner: A Benchmark for Real-World Planning with Language Agents
International Conference on Machine Learning
2024-02481GitHub · ★ 549
WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01452GitHub · ★ 1,125
AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents
International Conference on Learning Representations
2024-05434GitHub · ★ 924
MLE-bench: Evaluating machine learning agents on machine learning engineering
ICLR 2025
2024-10403GitHub · ★ 1,747
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Advances in Neural Information Processing Systems
2024-05360GitHub · ★ 4,017
When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs
Transactions of the Association for Computational Linguistics
2024-06352
WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks?
Proceedings of the 41st International Conference on Machine Learning
2024-03349GitHub · ★ 274
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
ACL 2024
2024-07327GitHub · ★ 518
Top 12 of 2023 by citations
PaperDateCitationsCode
Toolformer: Language Models Can Teach Themselves to Use Tools
Advances in Neural Information Processing Systems
2023-025659
Generative Agents: Interactive Simulacra of Human Behavior
Proceedings of the 36th annual acm symposium on user interface software and technology
2023-045576GitHub · ★ 22,130
Reflexion: language agents with verbal reinforcement learning
NeurIPS 2023
2023-035327GitHub · ★ 3,280
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Advances in Neural Information Processing Systems
2023-054909GitHub · ★ 6,068
Self-Refine: Iterative refinement with self-feedback
NeurIPS 2023
2023-034692GitHub · ★ 822
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
ICLR 2024
2023-103793GitHub · ★ 5,883
Voyager: An Open-Ended Embodied Agent with Large Language Models
Transactions on Machine Learning Research
2023-052314GitHub · ★ 7,221
ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs
International Conference on Learning Representations
2023-072266GitHub · ★ 5,745
WebArena: A Realistic Web Environment for Building Autonomous Agents
ICLR 2024
2023-072026GitHub · ★ 1,611
Gorilla: Large Language Model Connected with Massive APIs
Advances in Neural Information Processing Systems
2023-051642GitHub · ★ 13,037
Mind2Web: Towards a Generalist Agent for the Web
Advances in Neural Information Processing Systems
2023-061441GitHub · ★ 1,028
MemGPT: Towards LLMs as Operating Systems
arXiv preprint arXiv:2310.08560
2023-101336GitHub · ★ 24,819

🧪 Benchmarks

Figure 3 from the companion survey: What Is AI4AI? A Taxonomy

111 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

PaperDateCitationsCode
SWE-Bench ProMax: Benchmarking Agents on Large-Scale Multilingual Code Refactoring
arXiv
2026-085
HarnessOpt-Bench: Evaluating LLMs at Harness Optimization
arXiv preprint arXiv:2608.06301
2026-081
When History Lies: Evaluating and Improving Tool Use under Misleading Multi-Turn Histories
arXiv preprint arXiv:2608.06057
2026-080
DeepSWE: Measuring Frontier Coding Agents on Original, Long-Horizon Engineering Tasks
arXiv preprint arXiv:2607.07946
2026-0722GitHub · ★ 1,709
ChainSWE: Benchmarking Coding Agents on Multi-Bug Software Maintenance
arXiv preprint arXiv:2607.02606
2026-071
Kimi K3: Open Frontier Intelligence
arXiv
2026-0733GitHub · ★ 8,832
Can AI Agents Conduct Open-Ended AI Research? Early Evidence from Two Case Studies
arXiv
2026-076
RSIBench-Data: Benchmarking Data-Centric Research for Recursive Self-Improvement
arXiv
2026-079GitHub · ★ 159
Do Agent Benchmarks Measure Capability? Protocol Validity in the Age of Agentic AI
arXiv preprint arXiv:2607.22368
2026-074
Do Agent Optimizers Compound? A Continual-Learning Evaluation on Terminal-Bench 2.0
arXiv preprint arXiv:2607.14004
2026-072GitHub · ★ 8
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-074GitHub · ★ 733
FrontierSWE
Proximal Blog
2026GitHub · ★ 230
WeaveBench: A Long-Horizon, Real-World Benchmark for Computer-Use Agents with Hybrid Interfaces
arXiv preprint arXiv:2606.09426
2026-065
Do LLMs Catch Their Own Mistakes? A Comprehensive Benchmark for Reflective Tool Use LLMs
Findings of the Association for Computational Linguistics: ACL 2026
20260
The Meta-Agent Challenge: Are Current Agents Capable of Autonomous Agent Development?
arXiv preprint arXiv:2606.04455
2026-064GitHub · ★ 24
SWE-Explore: Benchmarking How Coding Agents Explore Repositories
arXiv
2026-0615GitHub · ★ 42
SWE-InfraBench: Evaluating Language Models on Cloud Infrastructure Code
arXiv
2026-060
SWE-Marathon: Can Agents Autonomously Complete Ultra-Long-Horizon Software Work?
arXiv
2026-0610
FARS: A Fully Automated Research System Deployed at Scale
arXiv
2026-064
DeskCraft: Benchmarking Desktop Agents on Professional Workflows and Human-in-the-Loop Collaboration
arXiv preprint arXiv:2606.03103
2026-062GitHub · ★ 92
NatureBench: Can Coding Agents Match the Published SOTA of Nature-Family Papers?
arXiv
2026-062GitHub · ★ 125
OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks
arXiv
2026-0617GitHub · ★ 322
MLS-Bench: A Holistic and Rigorous Assessment of AI Systems on Building Better AI
arXiv preprint arXiv:2605.08678
2026-058GitHub · ★ 118
ProgramBench: Can Language Models Rebuild Programs From Scratch?
arXiv
2026-0526GitHub · ★ 928
RoadmapBench: Evaluating Long-Horizon Agentic Software Development Across Version Upgrades
arXiv
2026-052GitHub · ★ 16
SWE Atlas: Benchmarking Coding Agents Beyond Issue Resolution
arXiv
2026-054GitHub · ★ 72
SWE-Chain: Benchmarking Coding Agents on Chained Release-Level Package Upgrades
arXiv
2026-055GitHub · ★ 15
SWE-Cycle: Benchmarking Code Agents across the Complete Issue Resolution Cycle
arXiv
2026-052GitHub · ★ 0
Breaking, Stale, or Missing? Benchmarking Coding Agents on Project-Level Test Evolution
arXiv
2026-051GitHub · ★ 5
How Far Are We From True Auto-Research?
arXiv
2026-056
Agent^2 RL-Bench: Can LLM Agents Engineer Agentic RL Post-Training?
arXiv preprint arXiv:2604.10547
2026-044GitHub · ★ 14,701
Toward autonomous long-horizon engineering for ML research
arXiv
2026-0410GitHub · ★ 146
KnowU-Bench: Towards Interactive, Proactive, and Personalized Mobile Agent Evaluation
arXiv preprint arXiv:2604.08455
2026-0420GitHub · ★ 77
CI-Repair-Bench: A Repository-Aware Benchmark for Automated Patch Validation via CI Workflows
arXiv
2026-041GitHub · ★ 1
Evaluating LLM-Based 0-to-1 Software Generation in End-to-End CLI Tool Scenarios
arXiv
2026-041GitHub · ★ 2
AutoSOTA: An End-to-End Automated Research System for State-of-the-Art AI Model Discovery
arXiv
2026-0416GitHub · ★ 681
The Long-Horizon Task Mirage? Diagnosing Where and Why Agentic Systems Break
arXiv preprint arXiv:2604.11978
2026-0425
SWE-Milestone: Evaluating AI Agents on Continuous Software Evolution
International Conference on Machine Learning
2026-036GitHub · ★ 73
Beyond pass@1: A Reliability Science Framework for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.29231
2026-036
Towards End-to-End Automation of AI Research
Nature 2026
2026-03249GitHub · ★ 7,194
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-0334GitHub · ★ 566
ReCUBE: Evaluating Repository-Level Context Utilization in Code Generation
arXiv
2026-031GitHub · ★ 1
SWE-CI: Evaluating Agent Capabilities in Maintaining Codebases via Continuous Integration
arXiv
2026-0317GitHub · ★ 178
FeatureBench: Benchmarking Agentic Coding for Complex Feature Development
arXiv
2026-0227GitHub · ★ 94
LongCLI-Bench: A Preliminary Benchmark and Study for Long-horizon Agentic Programming in Command-Line Interfaces
arXiv
2026-0224GitHub · ★ 47
AIRS-Bench: A Suite of Tasks for Frontier AI Research Science Agents
arXiv
2026-0222GitHub · ★ 120
SWE-rebench V2: Language-Agnostic SWE Task Collection at Scale
arXiv preprint arXiv:2602.23866
2026-0214
LUMINA: Long-horizon Understanding for Multi-turn Interactive Agents
Findings of the Association for Computational Linguistics: ACL 2026
2026-011
RepoGenesis: Benchmarking End-to-End Microservice Generation from Readme to Repository
arXiv
2026-016GitHub · ★ 101
Terminal-Bench: Benchmarking Agents on Hard, Realistic Tasks in Command Line Interfaces
arXiv
2026-01425GitHub · ★ 2,593
ARC: Active and Reflection-driven Context Management for Long-Horizon Information Seeking Agents
Findings of the Association for Computational Linguistics: ACL 2026
2026-015
DeepPlanning: Benchmarking Long-Horizon Agentic Planning with Verifiable Constraints
arXiv preprint arXiv:2601.18137
2026-0133
Toward ultra-long-horizon agentic science: Cognitive accumulation for machine learning engineering
arXiv
2026-0124
Towards a Science of Scaling Agent Systems
arXiv
2025-12127GitHub · ★ 53
DoVer: Intervention-Driven Auto Debugging for LLM Multi-Agent Systems
International Conference on Learning Representations
2025-1214GitHub · ★ 41
NL2Repo-Bench: Towards Long-Horizon Repository Generation Evaluation of Coding Agents
arXiv
2025-1247GitHub · ★ 176
SWE-EVO: Benchmarking Coding Agents in Long-Horizon Software Evolution Scenarios
arXiv
2025-1242GitHub · ★ 58
Holistic Agent Leaderboard: The Missing Infrastructure for AI Agent Evaluation
arXiv preprint arXiv:2510.11977
2025-1069GitHub · ★ 311
BuildBench: Benchmarking LLM Agents on Compiling Real-World Open-Source Software
arXiv
2025-091
SWE-Bench Pro: Can AI Agents Solve Long-Horizon Software Engineering Tasks?
arXiv
2025-09232GitHub · ★ 527
HeroBench: A Benchmark for Long-Horizon Planning and Structured Reasoning in Virtual Worlds
arXiv preprint arXiv:2508.12782
2025-086GitHub · ★ 14
Hell or High Water: Evaluating Agentic Recovery from External Failures
Second Conference on Language Modeling
2025-086GitHub · ★ 5
OdysseyBench: Evaluating LLM Agents on Long-Horizon Complex Office Application Workflows
arXiv preprint arXiv:2508.09124
2025-0853GitHub · ★ 18
Evaluation and Benchmarking of LLM Agents: A Survey
Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V.2
2025-07203GitHub · ★ 21
SWE-MERA: A Dynamic Benchmark for Agenticly Evaluating Large Language Models on Software Engineering Tasks
Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing: System Demonstrations
2025-077
The Berkeley Function Calling Leaderboard (BFCL): From tool use to agentic evaluation of large language models
Proceedings of the 42nd International Conference on Machine Learning
2025435GitHub · ★ 13,037
DeepResearch Bench: A Comprehensive Benchmark for Deep Research Agents
arXiv preprint arXiv:2506.11763
2025-06234GitHub · ★ 832
Mind2Web 2: Evaluating Agentic Search with Agent-as-a-Judge
arXiv preprint arXiv:2506.21506
2025-0674GitHub · ★ 114
RoboCerebra: A Large-scale Benchmark for Long-horizon Robotic Manipulation Evaluation
Advances in Neural Information Processing Systems
2025-0634GitHub · ★ 78
ALE-Bench: A Benchmark for Long-Horizon Objective-Driven Algorithm Engineering
Advances in Neural Information Processing Systems
2025-0630GitHub · ★ 220
ML-Master: Towards AI-for-AI via integration of exploration and reasoning
arXiv
2025-0655GitHub · ★ 450
MLR-Bench: Evaluating AI Agents on Open-Ended Machine Learning Research
arXiv preprint arXiv:2505.19955
2025-0556GitHub · ★ 36
LLMs Get Lost In Multi-Turn Conversation
International Conference on Learning Representations
2025-05450GitHub · ★ 297
SWE-bench Goes Live!
Advances in Neural Information Processing Systems
2025-0562GitHub · ★ 241
PaperBench: Evaluating AI's ability to replicate AI research
arXiv
2025-04280GitHub · ★ 1,300
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03610GitHub · ★ 415
A Survey on Evaluation of LLM-based Agents
Findings of the Association for Computational Linguistics: ACL 2026
2025-03226
Robotouille: An Asynchronous Planning Benchmark for LLM Agents
International Conference on Learning Representations
2025-0238GitHub · ★ 49
DI-BENCH: Benchmarking Large Language Models on Dependency Inference with Testable Repositories at Scale
Findings of the Association for Computational Linguistics: ACL 2025
2025-018GitHub · ★ 7
TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks
Advances in Neural Information Processing Systems (NeurIPS) Datasets and Benchmarks Track
2024-12308GitHub · ★ 781
RE-Bench: Evaluating frontier AI R&D capabilities of language model agents against human experts
arXiv
2024-11152GitHub · ★ 163
MLE-bench: Evaluating machine learning agents on machine learning engineering
ICLR 2025
2024-10403GitHub · ★ 1,747
Agent-as-a-Judge: Evaluate Agents with Agents
Forty-second International Conference on Machine Learning
2024-10223GitHub · ★ 828
Windows Agent Arena: Evaluating Multi-Modal OS Agents at Scale
International Conference on Machine Learning
2024-09208GitHub · ★ 901
ToolSandbox: A Stateful, Conversational, Interactive Evaluation Benchmark for LLM Tool Use Capabilities
Findings of the Association for Computational Linguistics: NAACL 2025
2024-08263GitHub · ★ 286
OfficeBench: Benchmarking Language Agents across Multiple Applications for Office Automation
arXiv preprint arXiv:2407.19056
2024-0754GitHub · ★ 46
AppWorld: A Controllable World of Apps and People for Benchmarking Interactive Coding Agents
ACL 2024
2024-07327GitHub · ★ 518
Introducing SWE-bench Verified
2024
WebCanvas: Benchmarking Web Agents in Online Environments
ICML 2024 Workshop on Agentic Markets
2024-06125GitHub · ★ 281
τ-bench: A Benchmark for Tool-Agent-User Interaction in Real-World Domains
arXiv
2024-061177GitHub · ★ 1,445
NATURAL PLAN: Benchmarking LLMs on Natural Language Planning
arXiv preprint arXiv:2406.04520
2024-06141GitHub · ★ 59
AndroidWorld: A Dynamic Benchmarking Environment for Autonomous Agents
International Conference on Learning Representations
2024-05434GitHub · ★ 924
Benchmarking Mobile Device Control Agents across Diverse Configurations
arXiv preprint arXiv:2404.16660
2024-0449GitHub · ★ 33
OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments
NeurIPS 2024
2024-041172GitHub · ★ 3,152
WorkArena: How Capable are Web Agents at Solving Common Knowledge Work Tasks?
Proceedings of the 41st International Conference on Machine Learning
2024-03349GitHub · ★ 274
OmniACT: A Dataset and Benchmark for Enabling Multimodal Generalist Autonomous Agents for Desktop and Web
Computer Vision -- ECCV 2024
2024-02170
WebLINX: Real-World Website Navigation with Multi-Turn Dialogue
International Conference on Machine Learning
2024-02187GitHub · ★ 163
TravelPlanner: A Benchmark for Real-World Planning with Language Agents
International Conference on Machine Learning
2024-02481GitHub · ★ 549
WebVoyager: Building an End-to-End Web Agent with Large Multimodal Models
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-01452GitHub · ★ 1,125
VisualWebArena: Evaluating Multimodal Agents on Realistic Visual Web Tasks
Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)
2024-0141GitHub · ★ 487
MinePlanner: A Benchmark for Long-Horizon Planning in Large Minecraft Worlds
Proceedings of the 6th ICAPS Workshop on the International Planning Competition (WIPC)
2023-128GitHub · ★ 23
SWE-bench: Can Language Models Resolve Real-World GitHub Issues?
ICLR 2024
2023-103793GitHub · ★ 5,883
AgentBench: Evaluating LLMs as Agents
International Conference on Learning Representations
2023-081307GitHub · ★ 3,742
ToolLLM: Facilitating Large Language Models to Master 16000+ Real-world APIs
International Conference on Learning Representations
2023-072266GitHub · ★ 5,745
WebArena: A Realistic Web Environment for Building Autonomous Agents
ICLR 2024
2023-072026GitHub · ★ 1,611
Mind2Web: Towards a Generalist Agent for the Web
Advances in Neural Information Processing Systems
2023-061441GitHub · ★ 1,028
BEHAVIOR-1K: A benchmark for embodied AI with 1,000 everyday activities and realistic simulation
Proceedings of The 6th Conference on Robot Learning
2023382GitHub · ★ 1,708
WebShop: Towards Scalable Real-World Web Interaction with Grounded Language Agents
Advances in Neural Information Processing Systems
2022-071369GitHub · ★ 598
WebGPT: Browser-assisted question-answering with human feedback
arXiv preprint arXiv:2112.09332
2021-122072
ALFRED: A Benchmark for Interpreting Grounded Instructions for Everyday Tasks
Proceedings of the IEEE/CVF conference on computer vision and pattern recognition
2019-121198GitHub · ★ 532
World of Bits: An Open-Domain Platform for Web-Based Agents
Proceedings of the 34th International Conference on Machine Learning
2017352

🛠️ Harness Design

Evidence chain for reliable harness interventions

101 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

PaperDateCitationsCode
PILOT in the Loop: Live Self-Improvement for Long-Horizon Agents
arXiv
2026-081
Recursive Experiential-Working Memory Evolution for Long-Horizon Agent Harnesses
arXiv
2026-082GitHub · ★ 214
Prime Agent: A Self-Improving RLM Harness
arXiv
2026-083GitHub · ★ 21,117
Recursive Self-Improvement in AI: From Bounded Self-Refinement to Autonomous Research Loops
2026-0712
Kimi K3: Open Frontier Intelligence
arXiv
2026-0733GitHub · ★ 8,832
Recursive harness self-improvement
arXiv
2026-0712
ACM: Agentic Context Management for Long Horizon Tasks
arXiv
2026-071GitHub · ★ 38
CompactionRL: Reinforcement Learning with Context Compaction for Long-Horizon Agents
arXiv
2026-073
Structured Feedback Improves Repair in an LLM Agent Loop
arXiv
2026-071
Self-Improvements in Modern Agentic Systems: A Survey
2026-0710GitHub · ★ 497
MetaSkill-Evolve: Recursive Self-Improvement of LLM Agents via Two-Timescale Meta-Skill Evolution
arXiv
2026-079
Rethinking the Evaluation of Harness Evolution for Agents
arXiv
2026-0721GitHub · ★ 40
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-074GitHub · ★ 733
HarnessX: A Composable, Adaptive, and Evolvable Agent Harness Foundry
arXiv
2026-0625
The Past Is Prologue: A Plug-in Controller for Selective Updates in Sequentially Evolving LLM Memory
arXiv
2026-061
From Question Answering to Task Completion: A Survey on Agent System and Harness Design
arXiv
2026-065
Agent Harness for Large Language Model Agents: A Survey
Preprints
20262GitHub · ★ 357
Scaffold Effects on GAIA: A Controlled Comparison
arXiv
2026-060
Context Compression for LLM Agents: A Survey of Methods, Failure Modes, and Evaluation
Preprints
20260
The Verification Horizon: No Silver Bullet for Coding Agent Rewards
arXiv
2026-064
Self-Harness: Harnesses That Improve Themselves
arXiv
2026-0642GitHub · ★ 110
Stop Comparing LLM Agents Without Disclosing the Harness
Second Workshop on Agents in the Wild: Safety, Security, and Beyond
20268
Are We Ready For An Agent-Native Memory System?
arXiv
2026-0612GitHub · ★ 148
MOSS: Self-Evolution through Source-Level Rewriting in Autonomous Agent Systems
arXiv
2026-058GitHub · ★ 25
Ask Early, Ask Late, Ask Right: When Does Clarification Timing Matter for Long-Horizon Agents?
arXiv
2026-052
From Raw Experience to Skill Consumption: A Systematic Study of Model-Generated Agent Skills
arXiv
2026-0515
Code as Agent Harness
arXiv
2026-0526GitHub · ★ 704
SkillOS: Learning Skill Curation for Self-Evolving Agents
arXiv
2026-0536
Adapting the Interface, Not the Model: Runtime Harness Adaptation for Deterministic LLM Agents
arXiv
2026-0522GitHub · ★ 222
LoopTrap: Termination Poisoning Attacks on LLM Agents
arXiv
2026-051
Learning Agent-Compatible Context Management for Long-Horizon Tasks
arXiv
2026-056
SpecBench: Measuring Reward Hacking in Long-Horizon Coding Agents
arXiv
2026-0514GitHub · ★ 15
Toward autonomous long-horizon engineering for ML research
arXiv
2026-0410GitHub · ★ 146
Squeez: Task-Conditioned Tool-Output Pruning for Coding Agents
arXiv preprint arXiv:2604.04979
2026-042GitHub · ★ 23
Dive into Claude Code: The Design Space of Today's and Future AI Agent Systems
arXiv
2026-0433GitHub · ★ 2,119
Escher-Loop: Mutual Evolution by Closed-Loop Self-Referential Optimization
arXiv
2026-046GitHub · ★ 8
Reinforced Agent: Inference-Time Feedback for Tool-Calling Agents
Proceedings of the Fifth Workshop on Generation, Evaluation and Metrics (GEM)
2026-044
From Agent Loops to Structured Graphs:A Scheduler-Theoretic Framework for LLM Agent Execution
arXiv
2026-042
ContextBudget: Budget-Aware Context Management for Long-Horizon Search Agents
arXiv preprint arXiv:2604.01664
2026-0410GitHub · ★ 9
ContextWeaver: Selective and Dependency-Structured Memory Construction for LLM Agents
arXiv preprint arXiv:2604.23069
2026-042
Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
arXiv preprint arXiv:2604.08224
2026-0461
Meta-Harness: End-to-End Optimization of Model Harnesses
arXiv
2026-03183GitHub · ★ 1,221
Natural-Language Agent Harnesses
arXiv
2026-0343
Bilevel Autoresearch: Meta-Autoresearching Itself
arXiv
2026-035GitHub · ★ 198
Schema First Tool APIs for LLM Agents: A Controlled Study of Tool Misuse, Recovery, and Budgeted Performance
arXiv
2026-035GitHub · ★ 0
DARWIN: Dynamic Agentically Rewriting Self-Improving Network
arXiv
2026-021GitHub · ★ 0
SWE-Pruner: Self-Adaptive Context Pruning for Coding Agents
arXiv preprint arXiv:2601.16746
2026-0137GitHub · ★ 318
Beyond Static Summarization: Proactive Memory Extraction for LLM Agents
arXiv preprint arXiv:2601.04463
2026-0116
Memory in the Age of AI Agents
arXiv preprint arXiv:2512.13564
2025-12269
Step-DeepResearch Technical Report
arXiv preprint arXiv:2512.20491
2025-1213GitHub · ★ 573
Towards a Science of Scaling Agent Systems
arXiv
2025-12127GitHub · ★ 53
DoVer: Intervention-Driven Auto Debugging for LLM Multi-Agent Systems
International Conference on Learning Representations
2025-1214GitHub · ★ 41
PARC: An Autonomous Self-Reflective Coding Agent for Robust Execution of Long-Horizon Tasks
arXiv
2025-123
Solving a Million-Step LLM Task with Zero Errors
arXiv preprint arXiv:2511.09030
2025-1123GitHub · ★ 46
LongCodeZip: Compress Long Context for Code Language Models
2025 40th IEEE/ACM International Conference on Automated Software Engineering (ASE)
2025-1046GitHub · ★ 168
ACON: Optimizing Context Compression for Long-horizon LLM Agents
arXiv preprint arXiv:2510.00615
2025-1096GitHub · ★ 117
Scaling Long-Horizon LLM Agent via Context-Folding
arXiv preprint arXiv:2510.11967
2025-10111GitHub · ★ 189
AgentFold: Long-Horizon Web Agents with Proactive Context Management
arXiv preprint arXiv:2510.24699
2025-1076GitHub · ★ 19,978
Agentic Context Engineering: Evolving Contexts for Self-Improving Language Models
arXiv
2025-10310GitHub · ★ 1,327
WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research
arXiv preprint arXiv:2509.13312
2025-0944GitHub · ★ 19,978
ReSum: Unlocking Long-Horizon Search Intelligence via Context Summarization
arXiv preprint arXiv:2509.13313
2025-09113GitHub · ★ 19,978
Reducing Cost of LLM Agents with Trajectory Reduction
Proceedings of the ACM on Software Engineering
2025-0944
Where LLM Agents Fail and How They can Learn From Failures
arXiv
2025-09118GitHub · ★ 107
Memp: Exploring Agent Procedural Memory
Findings of the Association for Computational Linguistics: ACL 2026
2025-0867GitHub · ★ 40
The Complexity Trap: Simple Observation Masking Is as Efficient as LLM Summarization for Agent Context Management
arXiv preprint arXiv:2508.21433
2025-0830
Magentic-UI: Towards Human-in-the-loop Agentic Systems
arXiv
2025-0751GitHub · ★ 10,091
ReVeal: Self-Evolving Code Agents via Reliable Self-Verification
The Fourteenth International Conference on Learning Representations
2025-0614
SWE-Dev: Building Software Engineering Agents with Training and Inference Scaling
Findings of the Association for Computational Linguistics: ACL 2025
2025-0627GitHub · ★ 66
MEM1: Learning to Synergize Memory and Reasoning for Efficient Long-Horizon Agents
arXiv preprint arXiv:2506.15841
2025-06200GitHub · ★ 336
Runaway is Ashamed, But Helpful: On the Early-Exit Behavior of Large Language Model-based Agents in Embodied Environments
Findings of the Association for Computational Linguistics: EMNLP 2025
2025-0511GitHub · ★ 2
Is there a half-life for the success rates of AI agents?
arXiv preprint arXiv:2505.05115
2025-055
Darwin Godel Machine: Open-ended evolution of self-improving agents
arXiv
2025-05239GitHub · ★ 2,354
Mem0: Building Production-Ready AI Agents with Scalable Long-Term Memory
European Conference on Artificial Intelligence (ECAI)
2025-04640GitHub · ★ 65,741
Process Reward Models That Think
Transactions on Machine Learning Research
2025-04111GitHub · ★ 92
Why Do Multi-Agent LLM Systems Fail?
Advances in Neural Information Processing Systems
2025-03610GitHub · ★ 415
Learning to Contextualize Web Pages for Enhanced Decision Making by LLM Agents
The Thirteenth International Conference on Learning Representations
2025-0322GitHub · ★ 7
Process Reward Models for LLM Agents: Practical Framework and Directions
arXiv
2025-0285GitHub · ★ 60
A-MEM: Agentic Memory for LLM Agents
Advances in Neural Information Processing Systems
2025-021010GitHub · ★ 974
Practical Considerations for Agentic LLM Systems
arXiv
2024-1217
Godel Agent: A self-referential agent framework for recursive self-improvement
arXiv
2024-1023GitHub · ★ 223
Agent-as-a-Judge: Evaluate Agents with Agents
Forty-second International Conference on Machine Learning
2024-10223GitHub · ★ 828
Agent Workflow Memory
Forty-second International Conference on Machine Learning
2024-09282GitHub · ★ 472
Automated design of agentic systems
ICLR 2025
2024-08322GitHub · ★ 1,638
LLM Critics Help Catch LLM Bugs
arXiv preprint arXiv:2407.00215
2024-07168
Demystifying LLM-Based Software Engineering Agents
Proceedings of the ACM on Software Engineering
2024-07500GitHub · ★ 2,112
When Can LLMs Actually Correct Their Own Mistakes? A Critical Survey of Self-Correction of LLMs
Transactions of the Association for Computational Linguistics
2024-06352
HippoRAG: Neurobiologically Inspired Long-Term Memory for Large Language Models
Advances in Neural Information Processing Systems
2024-05360GitHub · ★ 4,017
JARVIS-1: Open-World Multi-Task Agents With Memory-Augmented Multimodal Language Models
IEEE Transactions on Pattern Analysis & Machine Intelligence
2023-11217GitHub · ★ 417
Large Language Models Cannot Self-Correct Reasoning Yet
International Conference on Learning Representations
2023-101198
MemGPT: Towards LLMs as Operating Systems
arXiv preprint arXiv:2310.08560
2023-101336GitHub · ★ 24,819
Self-Taught Optimizer (STOP): Recursively self-improving code generation
Conference on Language Modeling
2023-10140GitHub · ★ 53
Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models
International Conference on Machine Learning
2023-10642GitHub · ★ 863
Cognitive Architectures for Language Agents
Transactions on Machine Learning Research
2023-09521
ExpeL: LLM Agents Are Experiential Learners
AAAI 2024
2023-08922GitHub · ★ 243
CRITIC: Large Language Models Can Self-Correct with Tool-Interactive Critiquing
International Conference on Learning Representations
2023-05931GitHub · ★ 745
AdaPlanner: Adaptive Planning from Feedback with Language Models
Advances in Neural Information Processing Systems
2023-05251GitHub · ★ 128
Voyager: An Open-Ended Embodied Agent with Large Language Models
Transactions on Machine Learning Research
2023-052314GitHub · ★ 7,221
Generative Agents: Interactive Simulacra of Human Behavior
Proceedings of the 36th annual acm symposium on user interface software and technology
2023-045576GitHub · ★ 22,130
Self-Refine: Iterative refinement with self-feedback
NeurIPS 2023
2023-034692GitHub · ★ 822
Reflexion: language agents with verbal reinforcement learning
NeurIPS 2023
2023-035327GitHub · ★ 3,280
ReAct: Synergizing Reasoning and Acting in Language Models
International Conference on Learning Representations (ICLR)
2022-1011375GitHub · ★ 4,183

🧠 Model Design

Model-side interventions across plan, execute, feedback, and repair

26 papers · Survey-curated collection, newest first. Cross-collection papers may appear in more than one section.

PaperDateCitationsCode
Single-Rollout Asynchronous Optimization for Agentic Reinforcement Learning
arXiv preprint arXiv:2607.07508
2026-0718
Kimi K3: Open Frontier Intelligence
arXiv
2026-0733GitHub · ★ 8,832
Frontis-MA1: Training an AI4AI Model towards Recursive Self-Improvement in Machine Learning Engineering
arXiv
2026-074GitHub · ★ 733
Autodata: An Agentic Data Scientist to Create High Quality Synthetic Data
arXiv
2026-067
TREX: Automating LLM Fine-tuning via Agent-Driven Tree-based Exploration
arXiv preprint arXiv:2604.14116
2026-043
CAPO: Critic-Guided Action-Aligned Policy Optimization for Advancing LLM Agent Capabilities
arXiv preprint arXiv:2604.18401
2026-049GitHub · ★ 1,671
PostTrainBench: Can LLM Agents Automate LLM Post-Training?
arXiv
2026-0334GitHub · ★ 566
Hindsight Credit Assignment for Long-Horizon LLM Agents
arXiv preprint arXiv:2603.08754
2026-0340
ASI-Evolve: AI Accelerates AI
arXiv
2026-035GitHub · ★ 857
Towards Execution-Grounded Automated AI Research
arXiv
2026-0113GitHub · ★ 84
IterResearch: Rethinking Long-Horizon Agents with Interaction Scaling
arXiv preprint arXiv:2511.07327
2025-1117GitHub · ★ 19,978
Stabilizing Off-Policy Training for Long-Horizon LLM Agent via Turn-Level Importance Sampling and Clipping-Triggered Normalization
arXiv preprint arXiv:2511.20718
2025-115GitHub · ★ 0
SALT: Step-level Advantage Assignment for Long-horizon Agents via Trajectory Graph
Findings of the Association for Computational Linguistics: EACL 2026
2025-1020
AgentGym-RL: Training LLM Agents for Long-Horizon Decision Making through Multi-Turn Reinforcement Learning
arXiv preprint arXiv:2509.08755
2025-0967GitHub · ★ 868
AlphaEvolve: A coding agent for scientific and algorithmic discovery
arXiv
2025-06862
Group-in-Group Policy Optimization for LLM Agent Training
Advances in Neural Information Processing Systems
2025-05414GitHub · ★ 2,324
Plan-and-Act: Improving Planning of Agents for Long-Horizon Tasks
International Conference on Machine Learning
2025-03213GitHub · ★ 46
Reinforcement Learning for Long-Horizon Interactive LLM Agents
arXiv preprint arXiv:2502.01600
2025-02103
Self-rewarding language models
arXiv
2024-01716
Language Agent Tree Search Unifies Reasoning Acting and Planning in Language Models
International Conference on Machine Learning
2023-10642GitHub · ★ 863
Gorilla: Large Language Model Connected with Massive APIs
Advances in Neural Information Processing Systems
2023-051642GitHub · ★ 13,037
Tree of Thoughts: Deliberate Problem Solving with Large Language Models
Advances in Neural Information Processing Systems
2023-054909GitHub · ★ 6,068
Toolformer: Language Models Can Teach Themselves to Use Tools
Advances in Neural Information Processing Systems
2023-025659
ReAct: Synergizing Reasoning and Acting in Language Models
International Conference on Learning Representations (ICLR)
2022-1011375GitHub · ★ 4,183
STaR: Bootstrapping reasoning with reasoning
NeurIPS 2022
2022-031069
Chain-Of-Thought Prompting Elicits Reasoning in Large Language Models
Advances in Neural Information Processing Systems
2022-0122031GitHub · ★ 41

📚 How We Curate

Search, screening, extraction, coding, and verification workflow

  1. Discover: survey searches, backward/forward citation chaining, and community suggestions.
  2. Verify: exact title and identifier checks against primary scholarly sources.
  3. Classify: Benchmarks, Harness Design, and Model Design, allowing justified overlap.
  4. Audit when evidence permits: stage ownership plus independent G/R/H/T coordinates.
  5. Refresh weekly: citation counts and rankings every Monday, alongside the month's top papers, releases, blogs, and research news.

📄 Citation

If this map or its evidence audit helps your work, please cite the companion survey:

Copy BibTeX
@misc{wu2026eveai4ai,
  title   = {{AI4AI} Survey: From Long-Horizon Agents to Recursive Self-Improvement---Definitions, Reliable Horizons, and Open Problems},
  author  = {Wu, Kai and Lyu, Hao and Luo, Zhen and Wang, Chaofan and
             Ye, Siyu and Lin, Jinghao and Ji, Xiaozhong and Jiang, Boyuan and
             Wang, Shengzhi and Wang, Zihan and Ye, Yiwen and Wang, Hao and
             Wang, Zimu and Liu, Wenzhe and Wang, Ruobing and Cai, Kai and
             Xiong, Mingliang and Fang, Wen and Liu, Mingqing and
             Zhang, Yifan and Yang, Lei and Hu, Xiaobin and Liu, Qingwen},
  howpublished = {Preprints.org},
  year    = {2026},
  doi     = {10.20944/preprints202608.2108.v1},
  url     = {https://doi.org/10.20944/preprints202608.2108.v1}
}

🤝 Contributing

Have something to add? Missing a paper, official code link, or stronger primary-source evidence? Open a pull request or use the paper-suggestion form. Read the contribution guide →

agent-benchmarks
agent-harness
agi
ai4ai
ai-agents
ai-research
automated-ai-research
autonomous-agents
awesome-list
benchmark
deep-learning
llm
llm-agents
long-horizon-agents
machine-learning
paper-list
recursive-self-improvement
research-papers
self-improvement
survey

Contributors

KaiWU5

24 commits

Languages

Python

97.2%

Shell

2.8%