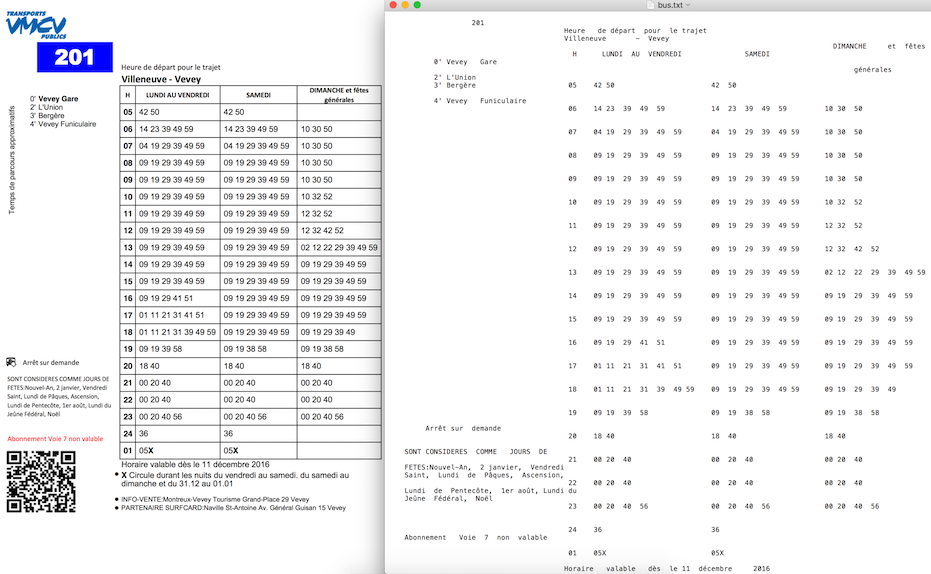
Converts a pdf file into a text file while keeping the layout of the original pdf. Useful to extract the content from a table in a pdf file for instance. This is a subclass of PDFTextStripper class (from the Apache PDFBox library).
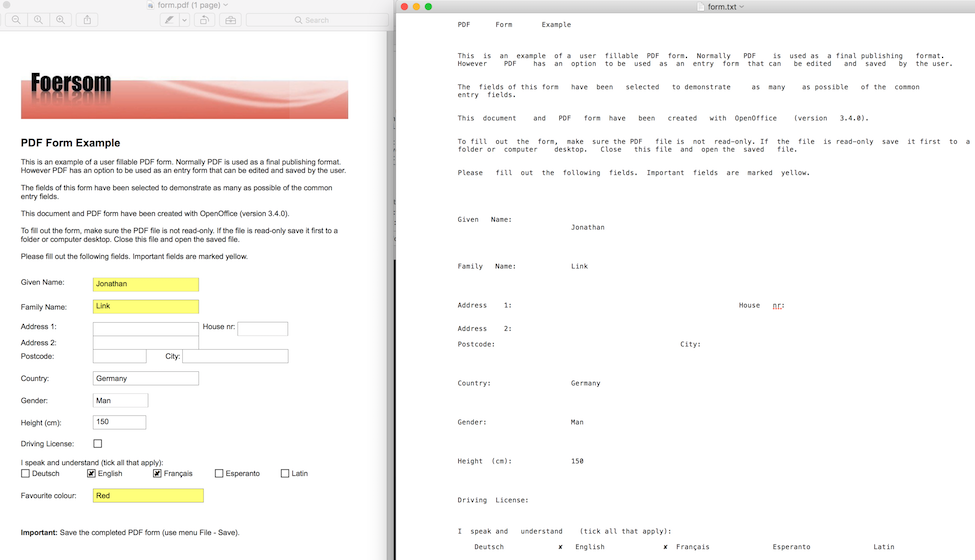
See the codeConverts a PDF file into a text file while keeping the layout of the original PDF. Useful to extract the content from a table or a form in a PDF file. PDFLayoutTextStripper is a subclass of PDFTextStripper class (from the Apache PDFBox library).
Data extraction from a form in a PDF file
<dependency>
  <groupId>io.github.jonathanlink</groupId>
  <artifactId>PDFLayoutTextStripper</artifactId>
  <version>2.2.3</version>
</dependency>
warning: only pdfbox versions from version 2.0.0 upwards are compatible with this version of PDFLayoutTextStripper.java
cd PDFLayoutTextStripper
javac -cp .:/pathto/pdfbox-2.0.6.jar:/pathto/commons-logging-1.2.jar:/pathto/PDFLayoutTextStripper/fontbox-2.0.6.jar *.java
java -cp .:/pathto/pdfbox-2.0.6.jar:/pathto/commons-logging-1.2.jar:/pathto/PDFLayoutTextStripper/fontbox-2.0.6.jar test
The same as for Linux (see above) but replace : with ;
import java.io.File;
import java.io.FileNotFoundException;
import java.io.IOException;
import org.apache.pdfbox.io.RandomAccessFile;
import org.apache.pdfbox.pdfparser.PDFParser;
import org.apache.pdfbox.pdmodel.PDDocument;
import org.apache.pdfbox.text.PDFTextStripper;

public class test {
	public static void main(String[] args) {
		String string = null;
        try {
            PDFParser pdfParser = new PDFParser(new RandomAccessFile(new File("./samples/bus.pdf"), "r"));
            pdfParser.parse();
            PDDocument pdDocument = new PDDocument(pdfParser.getDocument());
            PDFTextStripper pdfTextStripper = new PDFLayoutTextStripper();
            string = pdfTextStripper.getText(pdDocument);
        } catch (FileNotFoundException e) {
            e.printStackTrace();
        } catch (IOException e) {
            e.printStackTrace();
        };
        System.out.println(string);
	}
}
Thanks to
Overall
Maintained
Code review
Latest release
Releases this year
195 followers · starred Nov 2017
87 followers · starred Feb 2017
24,677 followers · starred Feb 2017
143 followers · starred Feb 2017
Converts a pdf file into a text file while keeping the layout of the original pdf. Useful to extract the content from a table in a pdf file for instance. This is a subclass of PDFTextStripper class (from the Apache PDFBox library).
See the codeConverts a PDF file into a text file while keeping the layout of the original PDF. Useful to extract the content from a table or a form in a PDF file. PDFLayoutTextStripper is a subclass of PDFTextStripper class (from the Apache PDFBox library).
Data extraction from a form in a PDF file
<dependency>
  <groupId>io.github.jonathanlink</groupId>
  <artifactId>PDFLayoutTextStripper</artifactId>
  <version>2.2.3</version>
</dependency>
warning: only pdfbox versions from version 2.0.0 upwards are compatible with this version of PDFLayoutTextStripper.java
cd PDFLayoutTextStripper
javac -cp .:/pathto/pdfbox-2.0.6.jar:/pathto/commons-logging-1.2.jar:/pathto/PDFLayoutTextStripper/fontbox-2.0.6.jar *.java
java -cp .:/pathto/pdfbox-2.0.6.jar:/pathto/commons-logging-1.2.jar:/pathto/PDFLayoutTextStripper/fontbox-2.0.6.jar test
The same as for Linux (see above) but replace : with ;
import java.io.File;
import java.io.FileNotFoundException;
import java.io.IOException;
import org.apache.pdfbox.io.RandomAccessFile;
import org.apache.pdfbox.pdfparser.PDFParser;
import org.apache.pdfbox.pdmodel.PDDocument;
import org.apache.pdfbox.text.PDFTextStripper;

public class test {
	public static void main(String[] args) {
		String string = null;
        try {
            PDFParser pdfParser = new PDFParser(new RandomAccessFile(new File("./samples/bus.pdf"), "r"));
            pdfParser.parse();
            PDDocument pdDocument = new PDDocument(pdfParser.getDocument());
            PDFTextStripper pdfTextStripper = new PDFLayoutTextStripper();
            string = pdfTextStripper.getText(pdDocument);
        } catch (FileNotFoundException e) {
            e.printStackTrace();
        } catch (IOException e) {
            e.printStackTrace();
        };
        System.out.println(string);
	}
}
Thanks to
Overall
Maintained
Code review
Latest release
Releases this year
195 followers · starred Nov 2017
87 followers · starred Feb 2017
24,677 followers · starred Feb 2017
143 followers · starred Feb 2017



