
StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation
See the codeREADME
StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation


StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation
Zijun Lin1,2,4, Zeqing Wang1,3, Cheston Tan4, Bihan Wen2, Yeying Jin1,3
1Tencent, 2Nanyang Technological University, 3National University of Singapore, 4A*STAR
Introduction
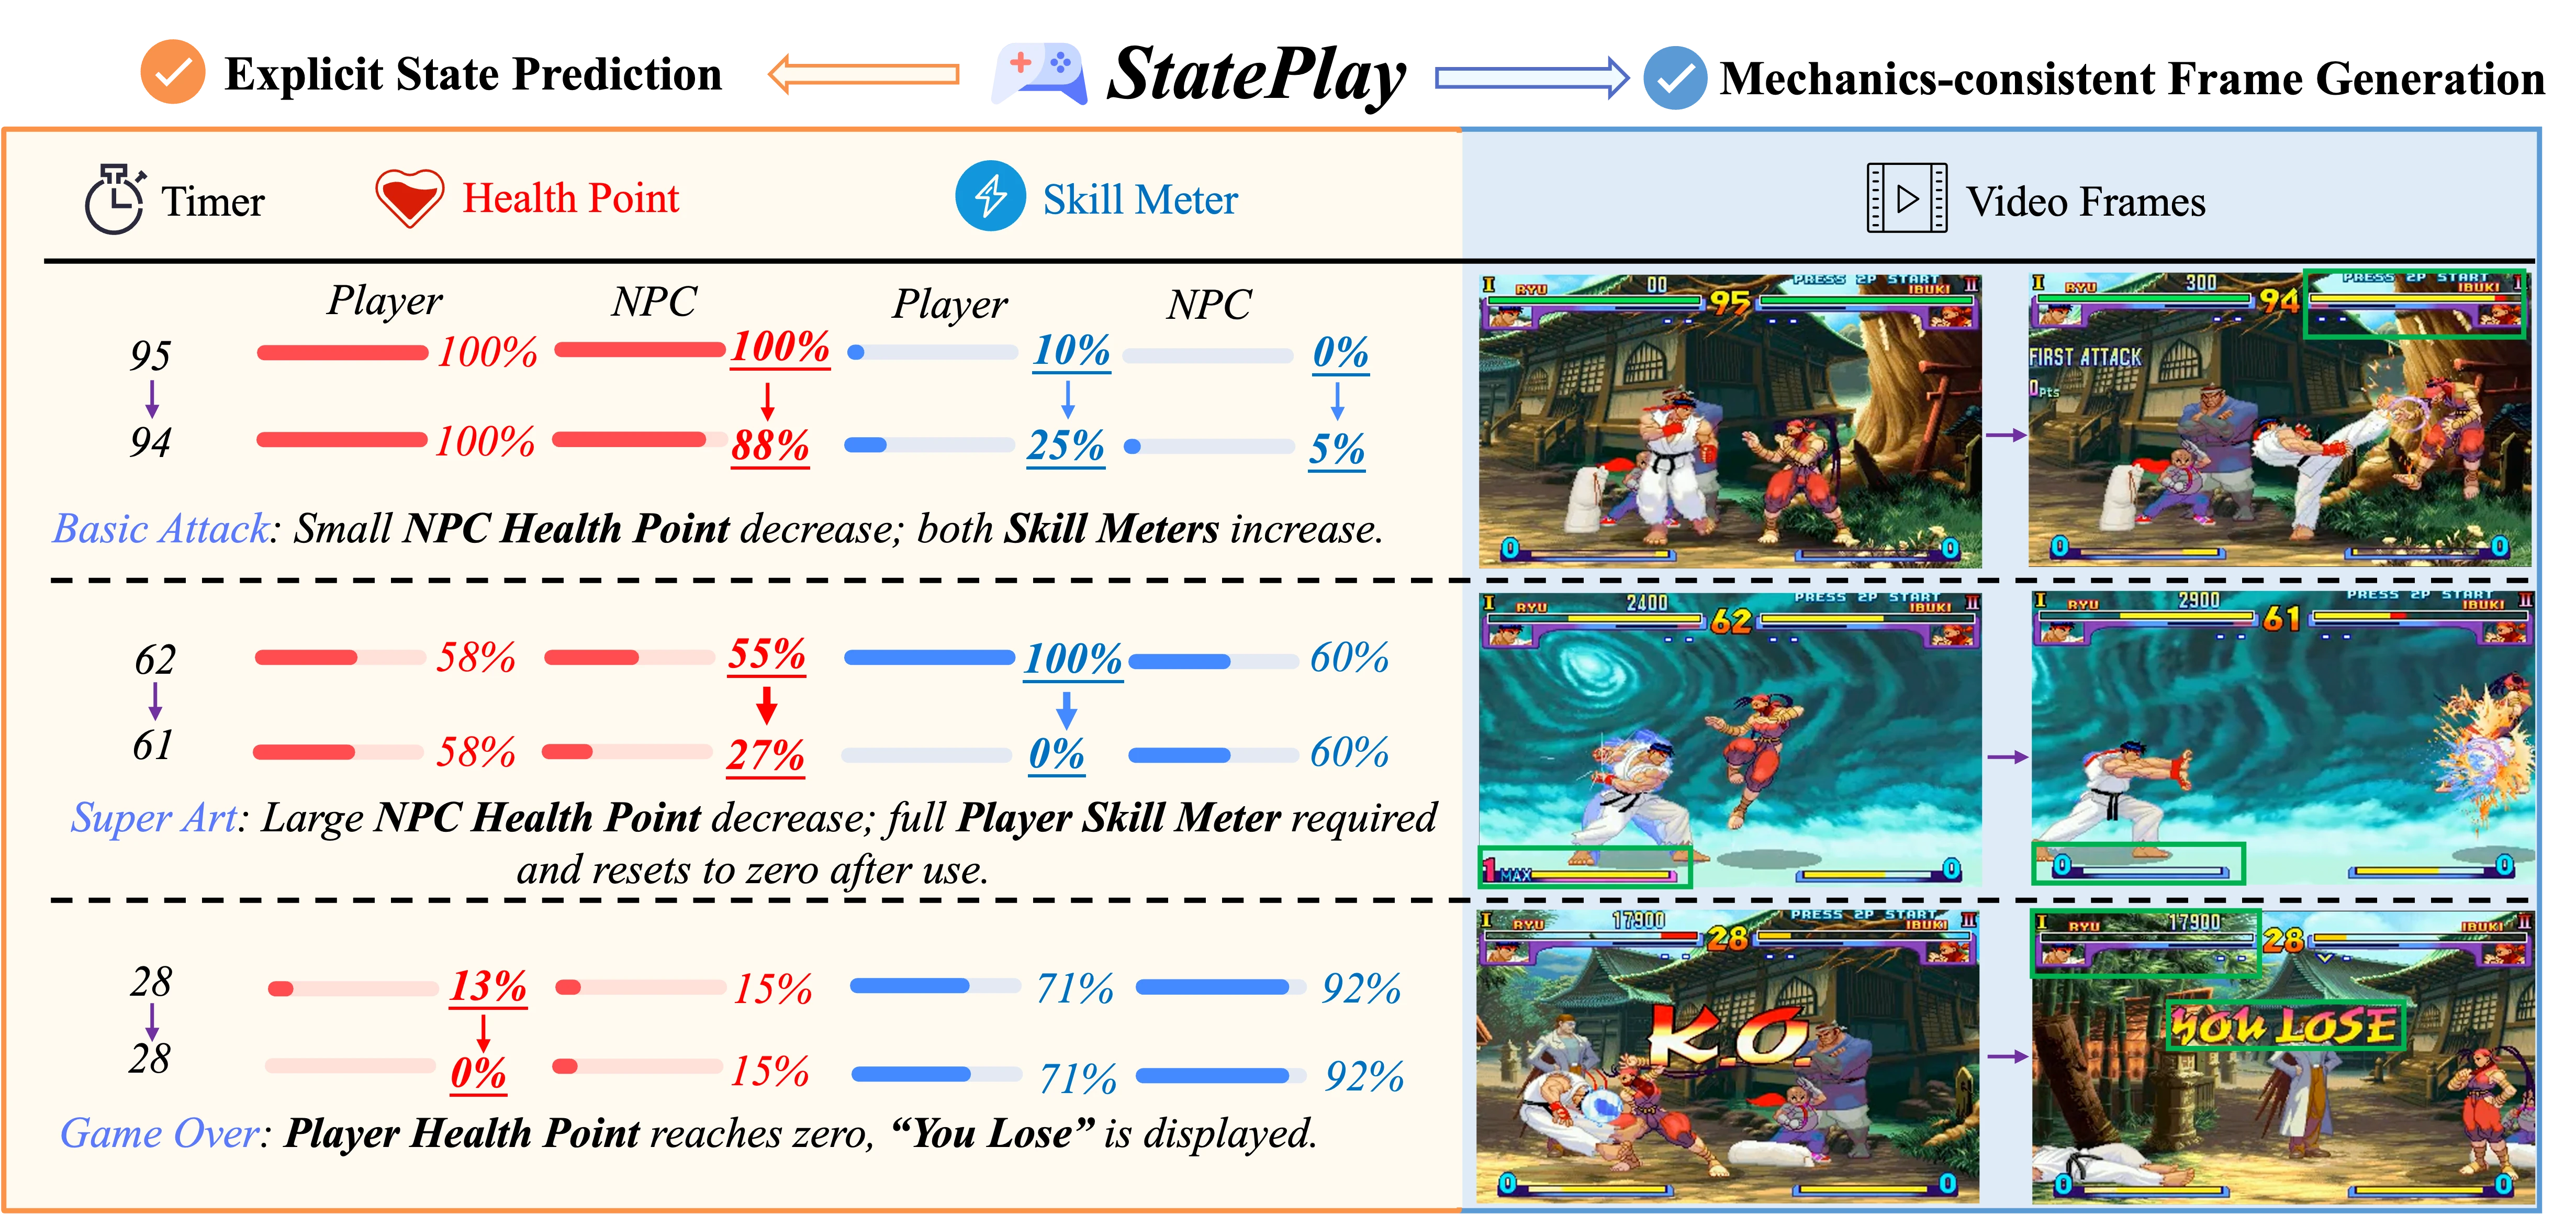
StatePlay: Beyond pixel-level realism toward mechanics-consistent Game World Models! Instead of modeling gameplay through visual observations alone, we explicitly predict internal game states and use them to guide frame generation, ensuring consistency with the underlying game mechanics.
Installation
Requirements: Python 3.10+, CUDA, and a GPU with bfloat16 support.
git clone https://github.com/Jimntu/StatePlay.git
cd StatePlay
python -m venv .venv
source .venv/bin/activate
pip install -U pip
pip install -e .
Model downloads
| Resource | Required for | Files | Download |
|---|---|---|---|
| StatePlay checkpoint | Inference | StatePlay.safetensors | Hugging Face |
| Wan2.2 VAE and T5 | Inference and training | Wan2.2_VAE.pth, models_t5_umt5-xxl-enc-bf16.pth | Hugging Face |
| UMT5 tokenizer | Inference and training | google/umt5-xxl/ | Hugging Face |
| Wan2.2 DiT base weights | Training only | Three diffusion_pytorch_model-*.safetensors shards | Hugging Face |
Expected inference layout:
StatePlay/
├── examples/checkpoint/StatePlay.safetensors
└── base_model/Wan-AI/
    ├── Wan2.2-TI2V-5B/
    │   ├── Wan2.2_VAE.pth
    │   └── models_t5_umt5-xxl-enc-bf16.pth
    └── Wan2.1-T2V-1.3B/google/umt5-xxl/
        └── ... tokenizer files ...
To keep weights elsewhere:
export STATEPLAY_BASE_MODEL=/absolute/path/to/base_model
export STATEPLAY_CHECKPOINT=/absolute/path/to/StatePlay.safetensors
STATEPLAY_BASE_MODEL must directly contain Wan-AI/.
Code architecture
StatePlay uses separate visual and state transformer branches with shared joint attention. The visual branch predicts video latents; the state branch predicts the five normalized game states. Both branches are conditioned on the initial frame, text prompt, and action sequence.
StatePlay/
├── stateplay/
│   ├── pipeline.py             # public inference pipeline
│   ├── cli.py                  # command-line inference
│   └── models/
│       ├── dit.py              # StatePlay visual/state DiT
│       ├── vae.py              # video VAE wrapper
│       └── text_encoder.py     # text encoder wrapper
├── training/
│   ├── train.py                # training entry point
│   ├── runner_with_state.py    # optimization/checkpoint loop
│   └── data/                   # SF3 action, state, and prompt loading
├── diffsynth/                  # minimal Wan/StatePlay dependencies
├── scripts/
│   ├── inference.sh
│   ├── run_examples.sh
│   └── train.sh
└── examples/
    ├── inputs/                 # eight bundled inputs
    ├── checkpoint/             # local checkpoint
    └── generated/              # generated videos and state predictions
Run examples
Generate all eight bundled examples:
export CUDA_VISIBLE_DEVICES=0
./scripts/run_examples.sh
Generate selected examples:
./scripts/run_examples.sh --only 01 03
Outputs are written to examples/generated/. Each example produces an MP4 and
a _state.txt file. The model is loaded once for the entire run.
Inference
export CUDA_VISIBLE_DEVICES=0

./scripts/inference.sh \
  --image examples/inputs/01_macro_success_clip/first_frame.png \
  --actions examples/inputs/01_macro_success_clip/actions.parquet \
  --prompt-file examples/inputs/01_macro_success_clip/prompt.txt \
  --output output.mp4
This writes output.mp4 and output_state.txt. Defaults are 101 frames,
30 denoising steps, text CFG 5.0, state/action CFG 1.0, and seed 2.
Use custom model paths through STATEPLAY_BASE_MODEL and
STATEPLAY_CHECKPOINT, or inspect all options with:
./scripts/inference.sh --help
Training
Download the StatePlay dataset and the Wan2.2 DiT initialization weights listed in the model table above.
Run training:
export STATEPLAY_BASE_MODEL="$PWD/base_model"
export STATEPLAY_DATA_ROOT="$PWD/data/StatePlay-Dataset/SF3"
export STATEPLAY_OUTPUT="$PWD/outputs/StatePlay"
export CUDA_VISIBLE_DEVICES=0,1,2,3

./scripts/train.sh
The script derives the process count from CUDA_VISIBLE_DEVICES. It trains at
480×832 with 101 frames, learning rate 5e-5, state sampling end, and saves
every 500 steps.
✉️ Feel free to email me (zijun002@e.ntu.edu.sg) or raise the issue if you have any questions about our work.
Citation
If you find our work useful in your research, please cite it as follows:
@misc{lin2026stateplaystateawaregameworld,
      title={StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation},
      author={Zijun Lin and Zeqing Wang and Cheston Tan and Bihan Wen and Yeying Jin},
      year={2026},
      eprint={2607.26754},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2607.26754},
}
Similar repos






Languages
Python
99.4%
StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation
See the codeREADME
StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation
StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation
Zijun Lin1,2,4, Zeqing Wang1,3, Cheston Tan4, Bihan Wen2, Yeying Jin1,3
1Tencent, 2Nanyang Technological University, 3National University of Singapore, 4A*STAR
Introduction
StatePlay: Beyond pixel-level realism toward mechanics-consistent Game World Models! Instead of modeling gameplay through visual observations alone, we explicitly predict internal game states and use them to guide frame generation, ensuring consistency with the underlying game mechanics.
Installation
Requirements: Python 3.10+, CUDA, and a GPU with bfloat16 support.
git clone https://github.com/Jimntu/StatePlay.git
cd StatePlay
python -m venv .venv
source .venv/bin/activate
pip install -U pip
pip install -e .
Model downloads
| Resource | Required for | Files | Download |
|---|---|---|---|
| StatePlay checkpoint | Inference | StatePlay.safetensors | Hugging Face |
| Wan2.2 VAE and T5 | Inference and training | Wan2.2_VAE.pth, models_t5_umt5-xxl-enc-bf16.pth | Hugging Face |
| UMT5 tokenizer | Inference and training | google/umt5-xxl/ | Hugging Face |
| Wan2.2 DiT base weights | Training only | Three diffusion_pytorch_model-*.safetensors shards | Hugging Face |
Expected inference layout:
StatePlay/
├── examples/checkpoint/StatePlay.safetensors
└── base_model/Wan-AI/
    ├── Wan2.2-TI2V-5B/
    │   ├── Wan2.2_VAE.pth
    │   └── models_t5_umt5-xxl-enc-bf16.pth
    └── Wan2.1-T2V-1.3B/google/umt5-xxl/
        └── ... tokenizer files ...
To keep weights elsewhere:
export STATEPLAY_BASE_MODEL=/absolute/path/to/base_model
export STATEPLAY_CHECKPOINT=/absolute/path/to/StatePlay.safetensors
STATEPLAY_BASE_MODEL must directly contain Wan-AI/.
Code architecture
StatePlay uses separate visual and state transformer branches with shared joint attention. The visual branch predicts video latents; the state branch predicts the five normalized game states. Both branches are conditioned on the initial frame, text prompt, and action sequence.
StatePlay/
├── stateplay/
│   ├── pipeline.py             # public inference pipeline
│   ├── cli.py                  # command-line inference
│   └── models/
│       ├── dit.py              # StatePlay visual/state DiT
│       ├── vae.py              # video VAE wrapper
│       └── text_encoder.py     # text encoder wrapper
├── training/
│   ├── train.py                # training entry point
│   ├── runner_with_state.py    # optimization/checkpoint loop
│   └── data/                   # SF3 action, state, and prompt loading
├── diffsynth/                  # minimal Wan/StatePlay dependencies
├── scripts/
│   ├── inference.sh
│   ├── run_examples.sh
│   └── train.sh
└── examples/
    ├── inputs/                 # eight bundled inputs
    ├── checkpoint/             # local checkpoint
    └── generated/              # generated videos and state predictions
Run examples
Generate all eight bundled examples:
export CUDA_VISIBLE_DEVICES=0
./scripts/run_examples.sh
Generate selected examples:
./scripts/run_examples.sh --only 01 03
Outputs are written to examples/generated/. Each example produces an MP4 and
a _state.txt file. The model is loaded once for the entire run.
Inference
export CUDA_VISIBLE_DEVICES=0

./scripts/inference.sh \
  --image examples/inputs/01_macro_success_clip/first_frame.png \
  --actions examples/inputs/01_macro_success_clip/actions.parquet \
  --prompt-file examples/inputs/01_macro_success_clip/prompt.txt \
  --output output.mp4
This writes output.mp4 and output_state.txt. Defaults are 101 frames,
30 denoising steps, text CFG 5.0, state/action CFG 1.0, and seed 2.
Use custom model paths through STATEPLAY_BASE_MODEL and
STATEPLAY_CHECKPOINT, or inspect all options with:
./scripts/inference.sh --help
Training
Download the StatePlay dataset and the Wan2.2 DiT initialization weights listed in the model table above.
Run training:
export STATEPLAY_BASE_MODEL="$PWD/base_model"
export STATEPLAY_DATA_ROOT="$PWD/data/StatePlay-Dataset/SF3"
export STATEPLAY_OUTPUT="$PWD/outputs/StatePlay"
export CUDA_VISIBLE_DEVICES=0,1,2,3

./scripts/train.sh
The script derives the process count from CUDA_VISIBLE_DEVICES. It trains at
480×832 with 101 frames, learning rate 5e-5, state sampling end, and saves
every 500 steps.
✉️ Feel free to email me (zijun002@e.ntu.edu.sg) or raise the issue if you have any questions about our work.
Citation
If you find our work useful in your research, please cite it as follows:
@misc{lin2026stateplaystateawaregameworld,
      title={StatePlay: State-Aware Game World Models for Mechanics-Consistent Generation},
      author={Zijun Lin and Zeqing Wang and Cheston Tan and Bihan Wen and Yeying Jin},
      year={2026},
      eprint={2607.26754},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2607.26754},
}
Similar repos
Languages
Python
99.4%