
[CVPR 2026 Highlight] Reward Forcing: Efficient Streaming Video Generation with Rewarded Distribution Matching Distillation
Python
364
13 commits
updated Dec 15, 2025
README
Reward Forcing:
Efficient Streaming Video Generation with
Rewarded Distribution Matching Distillation
Jiapeng Zhu2, Hengyuan Cao1, Zhipeng Zhang5, Xing Zhu2, Yujun Shen2, Min Zhang1,3


🚀 Progress
- 📝 Technical Report / Paper
- 🌐 Project Homepage
- 💻 Training & Inference Code
- 🤗 Pretrained Model: T2V-1.3B
- 🔜 Pretrained Model: T2V-14B (In progress)
🎯 Overview
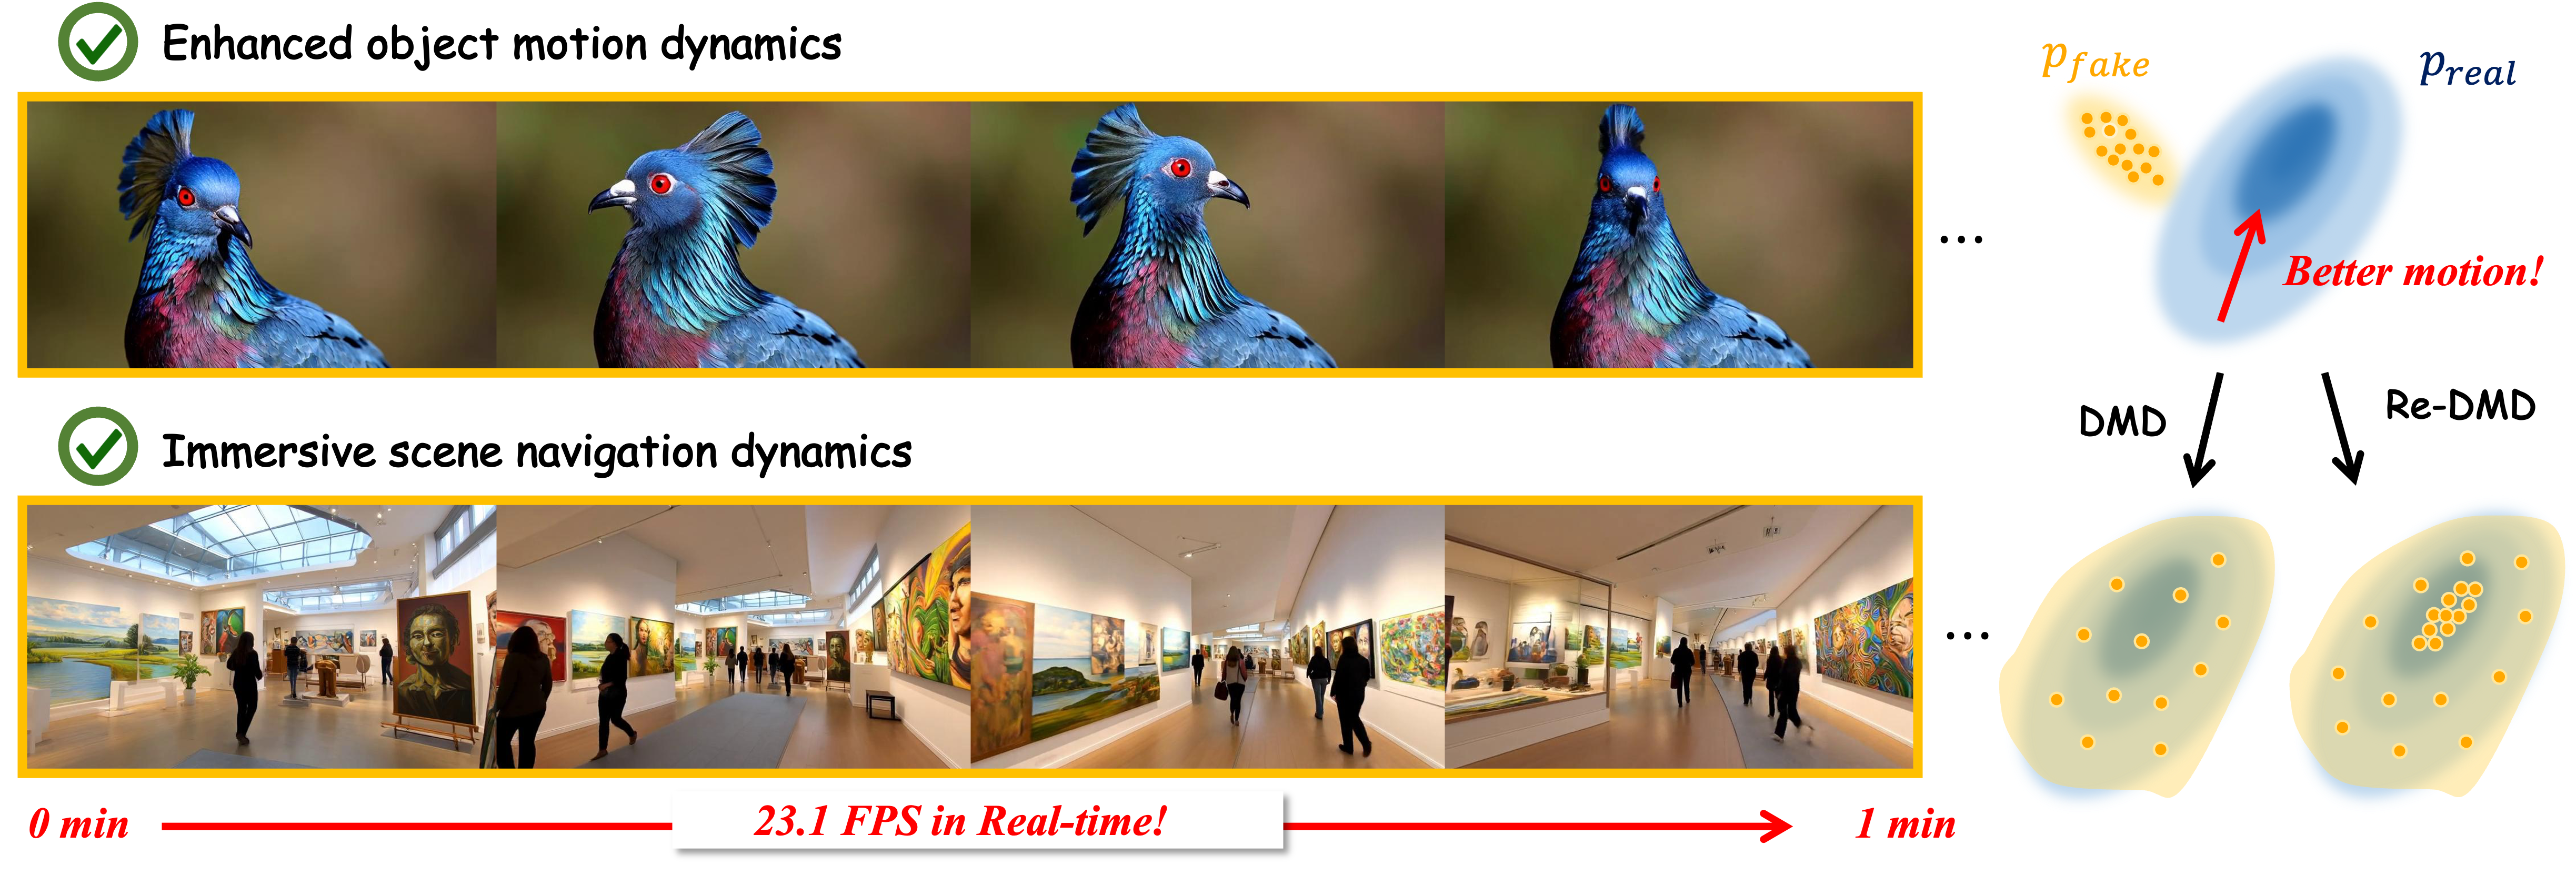
TL;DR: We propose Reward Forcing to distill a bidirectional video diffusion model into a 4-step autoregressive student model that enables real-time (23.1 FPS) streaming video generation. Instead of using vanilla distribution matching distillation (DMD), Reward Forcing adopts a novel rewarded distribution matching distillation (Re-DMD) that prioritizes matching towards high-reward regions, leading to enhanced object motion dynamics and immersive scene navigation dynamics in generated videos.
📋 Table of Contents
- Requirements
- Installation
- Pretrained Checkpoints
- Inference
- Training
- Results
- Citation
- Acknowledgements
- Contact
🔧 Requirements
- GPU: NVIDIA GPU with at least 24GB memory for inference, 80GB memory for training.
- RAM: 64GB or more recommended.
- Linux operating system.
🛠️ Installation
Step 1: Clone the repository
git clone https://github.com/JaydenLyh/Reward-Forcing.git
cd Reward-Forcing
Step 2: Create conda environment
conda create -n reward_forcing python=3.10
conda activate reward_forcing
Step 3: Install dependencies
pip install -r requirements.txt
pip install flash-attn --no-build-isolation
Step 4: Install the package
pip install -e .
📦 Pretrained Checkpoints
Download Links
| Model | Download |
|---|---|
| VideoReward | Hugging Face |
| Wan2.1-T2V-1.3B | Hugging Face |
| Wan2.1-T2V-14B | Hugging Face |
| ODE Initialization | Hugging Face |
| Reward Forcing | Hugging Face |
File Structure
After downloading, organize the checkpoints as follows:
checkpoints/
├── Videoreward/
│   ├── checkpoint-11352/
│   └── model_config.json
├── Wan2.1-T2V-1.3B/
├── Wan2.1-T2V-14B/
├── Reward-Forcing-T2V-1.3B/
└── ode_init.pt
Quick Download Script
pip install "huggingface_hub[cli]"

# Download all checkpoints
bash download_checkpoints.sh
🚀 Inference
Quick Start
# 5-seconds video inference
python inference.py \
    --num_output_frames 21 \
    --config_path configs/reward_forcing.yaml \
    --checkpoint_path checkpoints/Reward-Forcing-T2V-1.3B/rewardforcing.pt \
    --output_folder videos/rewardforcing-5s \
    --data_path prompts/MovieGenVideoBench_extended.txt \
    --use_ema

# 30-seconds video inference
python inference.py \
    --num_output_frames 120 \
    --config_path configs/reward_forcing.yaml \
    --checkpoint_path checkpoints/Reward-Forcing-T2V-1.3B/rewardforcing.pt \
    --output_folder videos/rewardforcing-30s \
    --data_path prompts/MovieGenVideoBench_extended.txt \
    --use_ema
🏋️ Training
Multi-GPU Training
# bash train.sh
torchrun --nnodes=1 --nproc_per_node=8 --rdzv_id=5235 --rdzv_backend=c10d  \
    --rdzv_endpoint=$MASTER_PORT train.py  --config_path configs/reward_forcing.yaml \
    --logdir logs/reward_forcing \
    --disable-wandb
Multi-Node Training
torchrun --nnodes=$NODE_SIZE --nproc_per_node=8 --node-rank=$NODE_RANK --rdzv_id=5235 --rdzv_backend=c10d  \
    --rdzv_endpoint=$MASTER_IP:$MASTER_PORT train.py  --config_path configs/reward_forcing.yaml \
    --logdir logs/reward_forcing \
    --disable-wandb
Configuration Files
Training configurations are in configs/:
default_config.yaml: Default configurationreward_forcing.yaml: Reward Forcing configuration
📊 Results
Quantitative Results
Performance on VBench
| Method | Total Score | Quality Score | Semantic Score | Params | FPS |
|---|---|---|---|---|---|
| SkyReels-V2 | 82.67 | 84.70 | 74.53 | 1.3B | 0.49 |
| MAGI-1 | 79.18 | 82.04 | 67.74 | 4.5B | 0.19 |
| NOVA | 80.12 | 80.39 | 79.05 | 0.6B | 0.88 |
| Pyramid Flow | 81.72 | 84.74 | 69.62 | 2B | 6.7 |
| CausVid | 82.88 | 83.93 | 78.69 | 1.3B | 17.0 |
| Self Forcing | 83.80 | 84.59 | 80.64 | 1.3B | 17.0 |
| LongLive | 83.22 | 83.68 | 81.37 | 1.3B | 20.7 |
| Ours | 84.13 | 84.84 | 81.32 | 1.3B | 23.1 |
Qualitative Results
Visualizations can be found in our Project Page.
📄 Citation
If you find this work useful, please consider citing:
@article{lu2025reward,
  title={Reward Forcing: Efficient Streaming Video Generation with Rewarded Distribution Matching Distillation},
  author={Lu, Yunhong and Zeng, Yanhong and Li, Haobo and Ouyang, Hao and Wang, Qiuyu and Cheng, Ka Leong and Zhu, Jiapeng and Cao, Hengyuan and Zhang, Zhipeng and Zhu, Xing and others},
  journal={arXiv preprint arXiv:2512.04678},
  year={2025}
}
🙏 Acknowledgements
This project is built upon several excellent works: CausVid, Self Forcing, Infinite Forcing, Wan2.1, VideoAlign
We thank the authors for their great work and open-source contribution.
📧 Contact
For questions and discussions, please:
- Open an issue on GitHub Issues
- Contact us at: yunhonglu@zju.edu.cn
Similar repos


Languages
Python
96.9%
HTML
3.0%
[CVPR 2026 Highlight] Reward Forcing: Efficient Streaming Video Generation with Rewarded Distribution Matching Distillation
Python
364
13 commits
updated Dec 15, 2025
README
Reward Forcing:
Efficient Streaming Video Generation with
Rewarded Distribution Matching Distillation
Jiapeng Zhu2, Hengyuan Cao1, Zhipeng Zhang5, Xing Zhu2, Yujun Shen2, Min Zhang1,3
🚀 Progress
- 📝 Technical Report / Paper
- 🌐 Project Homepage
- 💻 Training & Inference Code
- 🤗 Pretrained Model: T2V-1.3B
- 🔜 Pretrained Model: T2V-14B (In progress)
🎯 Overview
TL;DR: We propose Reward Forcing to distill a bidirectional video diffusion model into a 4-step autoregressive student model that enables real-time (23.1 FPS) streaming video generation. Instead of using vanilla distribution matching distillation (DMD), Reward Forcing adopts a novel rewarded distribution matching distillation (Re-DMD) that prioritizes matching towards high-reward regions, leading to enhanced object motion dynamics and immersive scene navigation dynamics in generated videos.
📋 Table of Contents
- Requirements
- Installation
- Pretrained Checkpoints
- Inference
- Training
- Results
- Citation
- Acknowledgements
- Contact
🔧 Requirements
- GPU: NVIDIA GPU with at least 24GB memory for inference, 80GB memory for training.
- RAM: 64GB or more recommended.
- Linux operating system.
🛠️ Installation
Step 1: Clone the repository
git clone https://github.com/JaydenLyh/Reward-Forcing.git
cd Reward-Forcing
Step 2: Create conda environment
conda create -n reward_forcing python=3.10
conda activate reward_forcing
Step 3: Install dependencies
pip install -r requirements.txt
pip install flash-attn --no-build-isolation
Step 4: Install the package
pip install -e .
📦 Pretrained Checkpoints
Download Links
| Model | Download |
|---|---|
| VideoReward | Hugging Face |
| Wan2.1-T2V-1.3B | Hugging Face |
| Wan2.1-T2V-14B | Hugging Face |
| ODE Initialization | Hugging Face |
| Reward Forcing | Hugging Face |
File Structure
After downloading, organize the checkpoints as follows:
checkpoints/
├── Videoreward/
│   ├── checkpoint-11352/
│   └── model_config.json
├── Wan2.1-T2V-1.3B/
├── Wan2.1-T2V-14B/
├── Reward-Forcing-T2V-1.3B/
└── ode_init.pt
Quick Download Script
pip install "huggingface_hub[cli]"

# Download all checkpoints
bash download_checkpoints.sh
🚀 Inference
Quick Start
# 5-seconds video inference
python inference.py \
    --num_output_frames 21 \
    --config_path configs/reward_forcing.yaml \
    --checkpoint_path checkpoints/Reward-Forcing-T2V-1.3B/rewardforcing.pt \
    --output_folder videos/rewardforcing-5s \
    --data_path prompts/MovieGenVideoBench_extended.txt \
    --use_ema

# 30-seconds video inference
python inference.py \
    --num_output_frames 120 \
    --config_path configs/reward_forcing.yaml \
    --checkpoint_path checkpoints/Reward-Forcing-T2V-1.3B/rewardforcing.pt \
    --output_folder videos/rewardforcing-30s \
    --data_path prompts/MovieGenVideoBench_extended.txt \
    --use_ema
🏋️ Training
Multi-GPU Training
# bash train.sh
torchrun --nnodes=1 --nproc_per_node=8 --rdzv_id=5235 --rdzv_backend=c10d  \
    --rdzv_endpoint=$MASTER_PORT train.py  --config_path configs/reward_forcing.yaml \
    --logdir logs/reward_forcing \
    --disable-wandb
Multi-Node Training
torchrun --nnodes=$NODE_SIZE --nproc_per_node=8 --node-rank=$NODE_RANK --rdzv_id=5235 --rdzv_backend=c10d  \
    --rdzv_endpoint=$MASTER_IP:$MASTER_PORT train.py  --config_path configs/reward_forcing.yaml \
    --logdir logs/reward_forcing \
    --disable-wandb
Configuration Files
Training configurations are in configs/:
default_config.yaml: Default configurationreward_forcing.yaml: Reward Forcing configuration
📊 Results
Quantitative Results
Performance on VBench
| Method | Total Score | Quality Score | Semantic Score | Params | FPS |
|---|---|---|---|---|---|
| SkyReels-V2 | 82.67 | 84.70 | 74.53 | 1.3B | 0.49 |
| MAGI-1 | 79.18 | 82.04 | 67.74 | 4.5B | 0.19 |
| NOVA | 80.12 | 80.39 | 79.05 | 0.6B | 0.88 |
| Pyramid Flow | 81.72 | 84.74 | 69.62 | 2B | 6.7 |
| CausVid | 82.88 | 83.93 | 78.69 | 1.3B | 17.0 |
| Self Forcing | 83.80 | 84.59 | 80.64 | 1.3B | 17.0 |
| LongLive | 83.22 | 83.68 | 81.37 | 1.3B | 20.7 |
| Ours | 84.13 | 84.84 | 81.32 | 1.3B | 23.1 |
Qualitative Results
Visualizations can be found in our Project Page.
📄 Citation
If you find this work useful, please consider citing:
@article{lu2025reward,
  title={Reward Forcing: Efficient Streaming Video Generation with Rewarded Distribution Matching Distillation},
  author={Lu, Yunhong and Zeng, Yanhong and Li, Haobo and Ouyang, Hao and Wang, Qiuyu and Cheng, Ka Leong and Zhu, Jiapeng and Cao, Hengyuan and Zhang, Zhipeng and Zhu, Xing and others},
  journal={arXiv preprint arXiv:2512.04678},
  year={2025}
}
🙏 Acknowledgements
This project is built upon several excellent works: CausVid, Self Forcing, Infinite Forcing, Wan2.1, VideoAlign
We thank the authors for their great work and open-source contribution.
📧 Contact
For questions and discussions, please:
- Open an issue on GitHub Issues
- Contact us at: yunhonglu@zju.edu.cn
Similar repos
Languages
Python
96.9%
HTML
3.0%