ACL 2026 & NAACL 2025: Bridging Retrieval and Inference through Evidence Fusion
See the codeJia-Chen Gu*, Junyi Zhang*, Di Wu, Yuankai Li, Kai-Wei Chang and Nanyun Peng


🔗 Paper: https://arxiv.org/abs/2510.13799
🌐 Website: https://jasonforjoy.github.io/BRIEF/
🤗 Dataset: https://huggingface.co/datasets/uclanlp/Brief-Pro
🤗 Model: https://huggingface.co/uclanlp/brief-pro
🔥 BRIEF-Pro has been accepted to ACL 2026 Findings.
🔥 We released the training and evaluation code, the model checkpoint, and the training data.
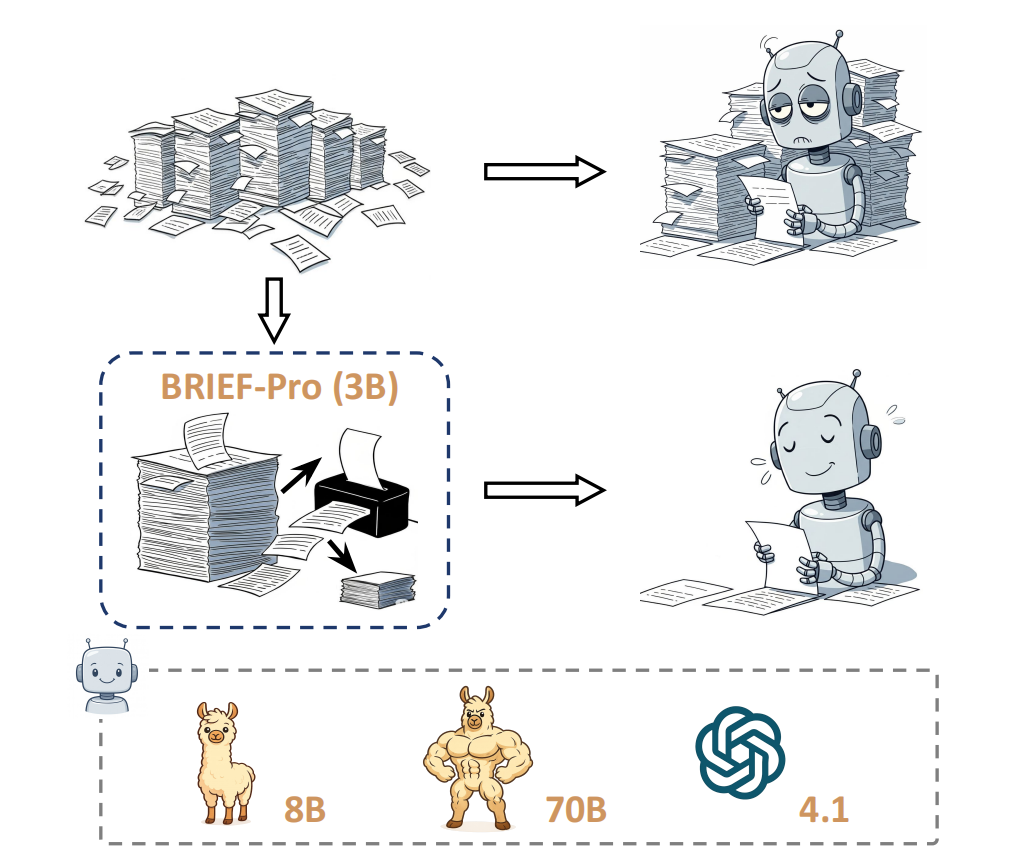
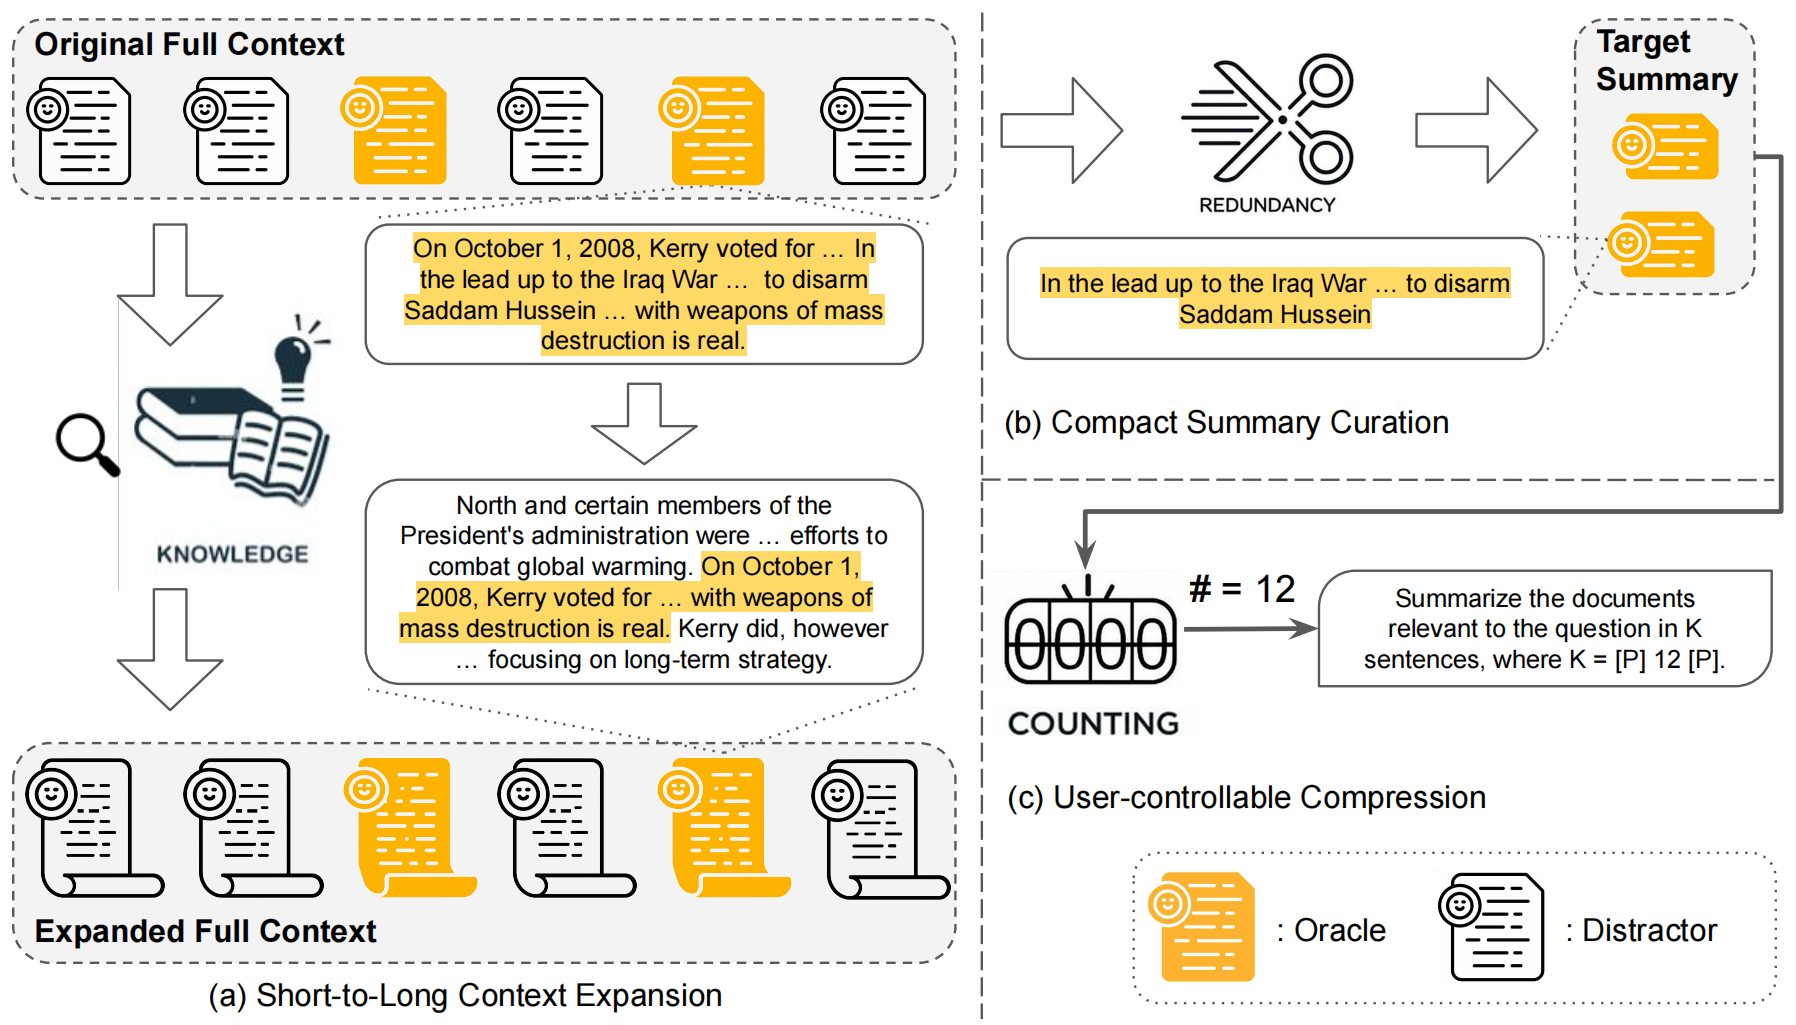
🤖 BRIEF-PRO is a universal, lightweight compressor that distills relevant evidence for a given query from multiple retrieved documents into a concise summary for seamless integration into in-context RAG.
📍 Installation:
conda create -n axolotl python=3.10 -y
conda activate axolotl

pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124

pip install packaging ninja
pip install flash-attn --no-build-isolation

cd Axolotl/
pip install --index-url https://download.pytorch.org/whl/cu124 torch==2.6.0+cu124
pip install xformers==0.0.29.post2
pip install axolotl==0.5.0 accelerate peft optimum bitsandbytes liger-kernel lm-eval

pip install -e .
pip install -e '.[deepspeed]'
You can also follow the instructions on the Axolotl website (we use axolotl==0.5.0) to set up the training environment.
💡 Running:
Then run the following command to start training:
bash ./BRIEF-Pro/train/Axolotl/examples/llama-3.2/train.sh
📍 Installation:
Follow VLLM to install the multidoc_vllm environment.
Follow LongBench to install the longbench environment.
You can also quickly set up the environments using the provided .yml files.
conda env create -f ./BRIEF-Pro/env/multidoc_vllm_env.yml
conda env create -f ./BRIEF-Pro/env/longbench_env.yml
📖 Data Preparation:
Download the musique.jsonl, hotpotqa.jsonl, and 2wikimqa.jsonl files from LongBench and place them in ./BRIEF-Pro/eval/LongBench/data/.
Run ./BRIEF-Pro/eval/LongBench/convert.py to align the test data titles with our training format.
We provide the SealQA test data file at ./BRIEF-Pro/eval/LongBench/unbiasdata/longseal.jsonl.
💡 Running:
Run the following command to for evaluation:
BRIEF-PRO as the Compressor
bash ./BRIEF-Pro/eval/test_pipe_testAll_UserControl.sh
bash ./BRIEF-Pro/eval/test_pipe_testSealQA_UserControl.sh
python ./BRIEF-Pro/eval/GPT_pred.py
@inproceedings{gu2026briefpro,
  title={BRIEF-Pro: Universal Context Compression with Short-to-Long Synthesis for Fast and Accurate Multi-Hop Reasoning},
  author={Gu, Jia-Chen and Zhang, Junyi and Wu, Di and Li, Yuankai and Chang, Kai-Wei and Peng, Nanyun},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2026},
  year={2026}
}
77 followers · starred Oct 2024
ACL 2026 & NAACL 2025: Bridging Retrieval and Inference through Evidence Fusion
See the codeJia-Chen Gu*, Junyi Zhang*, Di Wu, Yuankai Li, Kai-Wei Chang and Nanyun Peng
🔗 Paper: https://arxiv.org/abs/2510.13799
🌐 Website: https://jasonforjoy.github.io/BRIEF/
🤗 Dataset: https://huggingface.co/datasets/uclanlp/Brief-Pro
🤗 Model: https://huggingface.co/uclanlp/brief-pro
🔥 BRIEF-Pro has been accepted to ACL 2026 Findings.
🔥 We released the training and evaluation code, the model checkpoint, and the training data.
🤖 BRIEF-PRO is a universal, lightweight compressor that distills relevant evidence for a given query from multiple retrieved documents into a concise summary for seamless integration into in-context RAG.
📍 Installation:
conda create -n axolotl python=3.10 -y
conda activate axolotl

pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu124

pip install packaging ninja
pip install flash-attn --no-build-isolation

cd Axolotl/
pip install --index-url https://download.pytorch.org/whl/cu124 torch==2.6.0+cu124
pip install xformers==0.0.29.post2
pip install axolotl==0.5.0 accelerate peft optimum bitsandbytes liger-kernel lm-eval

pip install -e .
pip install -e '.[deepspeed]'
You can also follow the instructions on the Axolotl website (we use axolotl==0.5.0) to set up the training environment.
💡 Running:
Then run the following command to start training:
bash ./BRIEF-Pro/train/Axolotl/examples/llama-3.2/train.sh
📍 Installation:
Follow VLLM to install the multidoc_vllm environment.
Follow LongBench to install the longbench environment.
You can also quickly set up the environments using the provided .yml files.
conda env create -f ./BRIEF-Pro/env/multidoc_vllm_env.yml
conda env create -f ./BRIEF-Pro/env/longbench_env.yml
📖 Data Preparation:
Download the musique.jsonl, hotpotqa.jsonl, and 2wikimqa.jsonl files from LongBench and place them in ./BRIEF-Pro/eval/LongBench/data/.
Run ./BRIEF-Pro/eval/LongBench/convert.py to align the test data titles with our training format.
We provide the SealQA test data file at ./BRIEF-Pro/eval/LongBench/unbiasdata/longseal.jsonl.
💡 Running:
Run the following command to for evaluation:
BRIEF-PRO as the Compressor
bash ./BRIEF-Pro/eval/test_pipe_testAll_UserControl.sh
bash ./BRIEF-Pro/eval/test_pipe_testSealQA_UserControl.sh
python ./BRIEF-Pro/eval/GPT_pred.py
@inproceedings{gu2026briefpro,
  title={BRIEF-Pro: Universal Context Compression with Short-to-Long Synthesis for Fast and Accurate Multi-Hop Reasoning},
  author={Gu, Jia-Chen and Zhang, Junyi and Wu, Di and Li, Yuankai and Chang, Kai-Wei and Peng, Nanyun},
  booktitle={Findings of the Association for Computational Linguistics: ACL 2026},
  year={2026}
}
77 followers · starred Oct 2024



