
README
CodeV-R1: Reasoning-Enhanced Verilog Generation
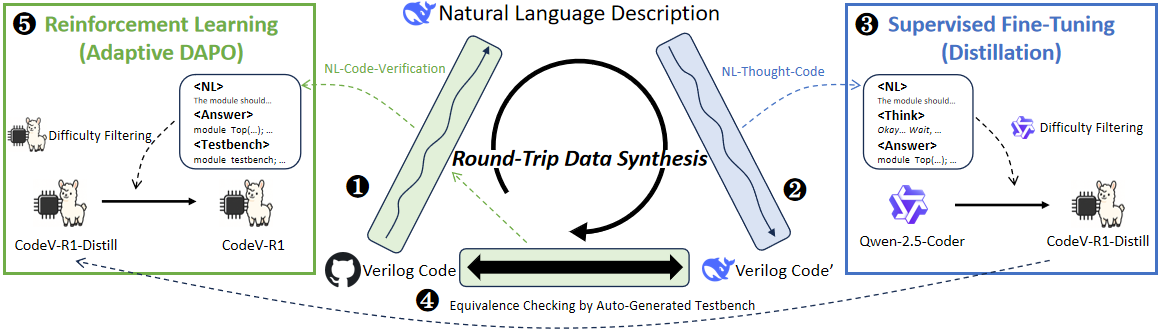
CodeV-R1 is an innovative open-source Large Language Model (LLM) specifically designed for the generation of high-quality Verilog code, addressing the challenges faced by existing models in this domain.
We have open-sourced our code for model testing, SFT and RL training. In the meantime, we have also open-sourced our SFT and RL training data in Huggingface. Below are the links:
-
Webpage: https://iprc-dip.github.io/CodeV-R1/
-
Models: CodeV-R1 and CodeV-R1-distill
-
Data: CodeV-R1-dataset
Environments
Below are the packages needed for (testing of) CodeV-R1.
conda create -n codev-r1 python=3.10 conda-forge::yosys conda-forge::iverilog
conda activate codev-r1

pip install vllm
# VerilogEval v1
pip install -e testbench/VerilogEval_v1.0.0/
# VerilogEval v2
pip install langchain langchain-community langchain-core langchain-nvidia-ai-endpoints langchain-openai langchain-text-splitters langsmith
For the environment of reinforcement learning, please refer to verl/README.md.
Testing
Here is the link for our CodeV-R1-distill and CodeV-R1. Please refer to the README under test/ for details for testing.
SFT Training
We use LLaMA-Factory to conduct SFT training, and we provide our training configuration in sft/. Please refer to sft/README.md for more details.
RL Training
We use verl to conduct RL training, and we open-source our RL training code in verl/. Please refer to verl/README.md for more details.
Automated Testbench Generation
We have provided the code for automated testbench generation in https://github.com/IPRC-DIP/CodeV-R1/tree/main/verl/verl/utils/reward_score/codev_eval_toolkit inside the RL code.
Citation
Arxiv: https://arxiv.org/abs/2505.24183
Please cite the paper if you use the code, models or datasets from CodeV-R1.
@misc{zhu2025codevr1,
  title={CodeV-R1: Reasoning-Enhanced Verilog Generation},
  author={Yaoyu Zhu and Di Huang and Hanqi Lyu and Xiaoyun Zhang and Chongxiao Li and Wenxuan Shi and Yutong Wu and Jianan Mu and Jinghua Wang and Yang Zhao and Pengwei Jin and Shuyao Cheng and Shengwen Liang and Xishan Zhang and Rui Zhang and Zidong Du and Qi Guo and Xing Hu and Yunji Chen},
  year={2025},
  eprint={2505.24183},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2505.24183},
}
Acknowledgements
DeepSeek-R1: Source model for distillation and reference method for RL
vllm: Fast LLM inference during testing
LLaMA-Factory: Code for supervised fine-tuning
verl: Code for reinforcement learning
VerilogEval & RTLLM: Benchmarks for testing
Similar repos


Languages
Python
40.2%
SystemVerilog
34.7%
Verilog
22.2%
Shell
1.4%
Makefile
1.3%
README
CodeV-R1: Reasoning-Enhanced Verilog Generation
CodeV-R1 is an innovative open-source Large Language Model (LLM) specifically designed for the generation of high-quality Verilog code, addressing the challenges faced by existing models in this domain.
We have open-sourced our code for model testing, SFT and RL training. In the meantime, we have also open-sourced our SFT and RL training data in Huggingface. Below are the links:
-
Webpage: https://iprc-dip.github.io/CodeV-R1/
-
Models: CodeV-R1 and CodeV-R1-distill
-
Data: CodeV-R1-dataset
Environments
Below are the packages needed for (testing of) CodeV-R1.
conda create -n codev-r1 python=3.10 conda-forge::yosys conda-forge::iverilog
conda activate codev-r1

pip install vllm
# VerilogEval v1
pip install -e testbench/VerilogEval_v1.0.0/
# VerilogEval v2
pip install langchain langchain-community langchain-core langchain-nvidia-ai-endpoints langchain-openai langchain-text-splitters langsmith
For the environment of reinforcement learning, please refer to verl/README.md.
Testing
Here is the link for our CodeV-R1-distill and CodeV-R1. Please refer to the README under test/ for details for testing.
SFT Training
We use LLaMA-Factory to conduct SFT training, and we provide our training configuration in sft/. Please refer to sft/README.md for more details.
RL Training
We use verl to conduct RL training, and we open-source our RL training code in verl/. Please refer to verl/README.md for more details.
Automated Testbench Generation
We have provided the code for automated testbench generation in https://github.com/IPRC-DIP/CodeV-R1/tree/main/verl/verl/utils/reward_score/codev_eval_toolkit inside the RL code.
Citation
Arxiv: https://arxiv.org/abs/2505.24183
Please cite the paper if you use the code, models or datasets from CodeV-R1.
@misc{zhu2025codevr1,
  title={CodeV-R1: Reasoning-Enhanced Verilog Generation},
  author={Yaoyu Zhu and Di Huang and Hanqi Lyu and Xiaoyun Zhang and Chongxiao Li and Wenxuan Shi and Yutong Wu and Jianan Mu and Jinghua Wang and Yang Zhao and Pengwei Jin and Shuyao Cheng and Shengwen Liang and Xishan Zhang and Rui Zhang and Zidong Du and Qi Guo and Xing Hu and Yunji Chen},
  year={2025},
  eprint={2505.24183},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2505.24183},
}
Acknowledgements
DeepSeek-R1: Source model for distillation and reference method for RL
vllm: Fast LLM inference during testing
LLaMA-Factory: Code for supervised fine-tuning
verl: Code for reinforcement learning
VerilogEval & RTLLM: Benchmarks for testing
Similar repos
Languages
Python
40.2%
SystemVerilog
34.7%
Verilog
22.2%
Shell
1.4%
Makefile
1.3%