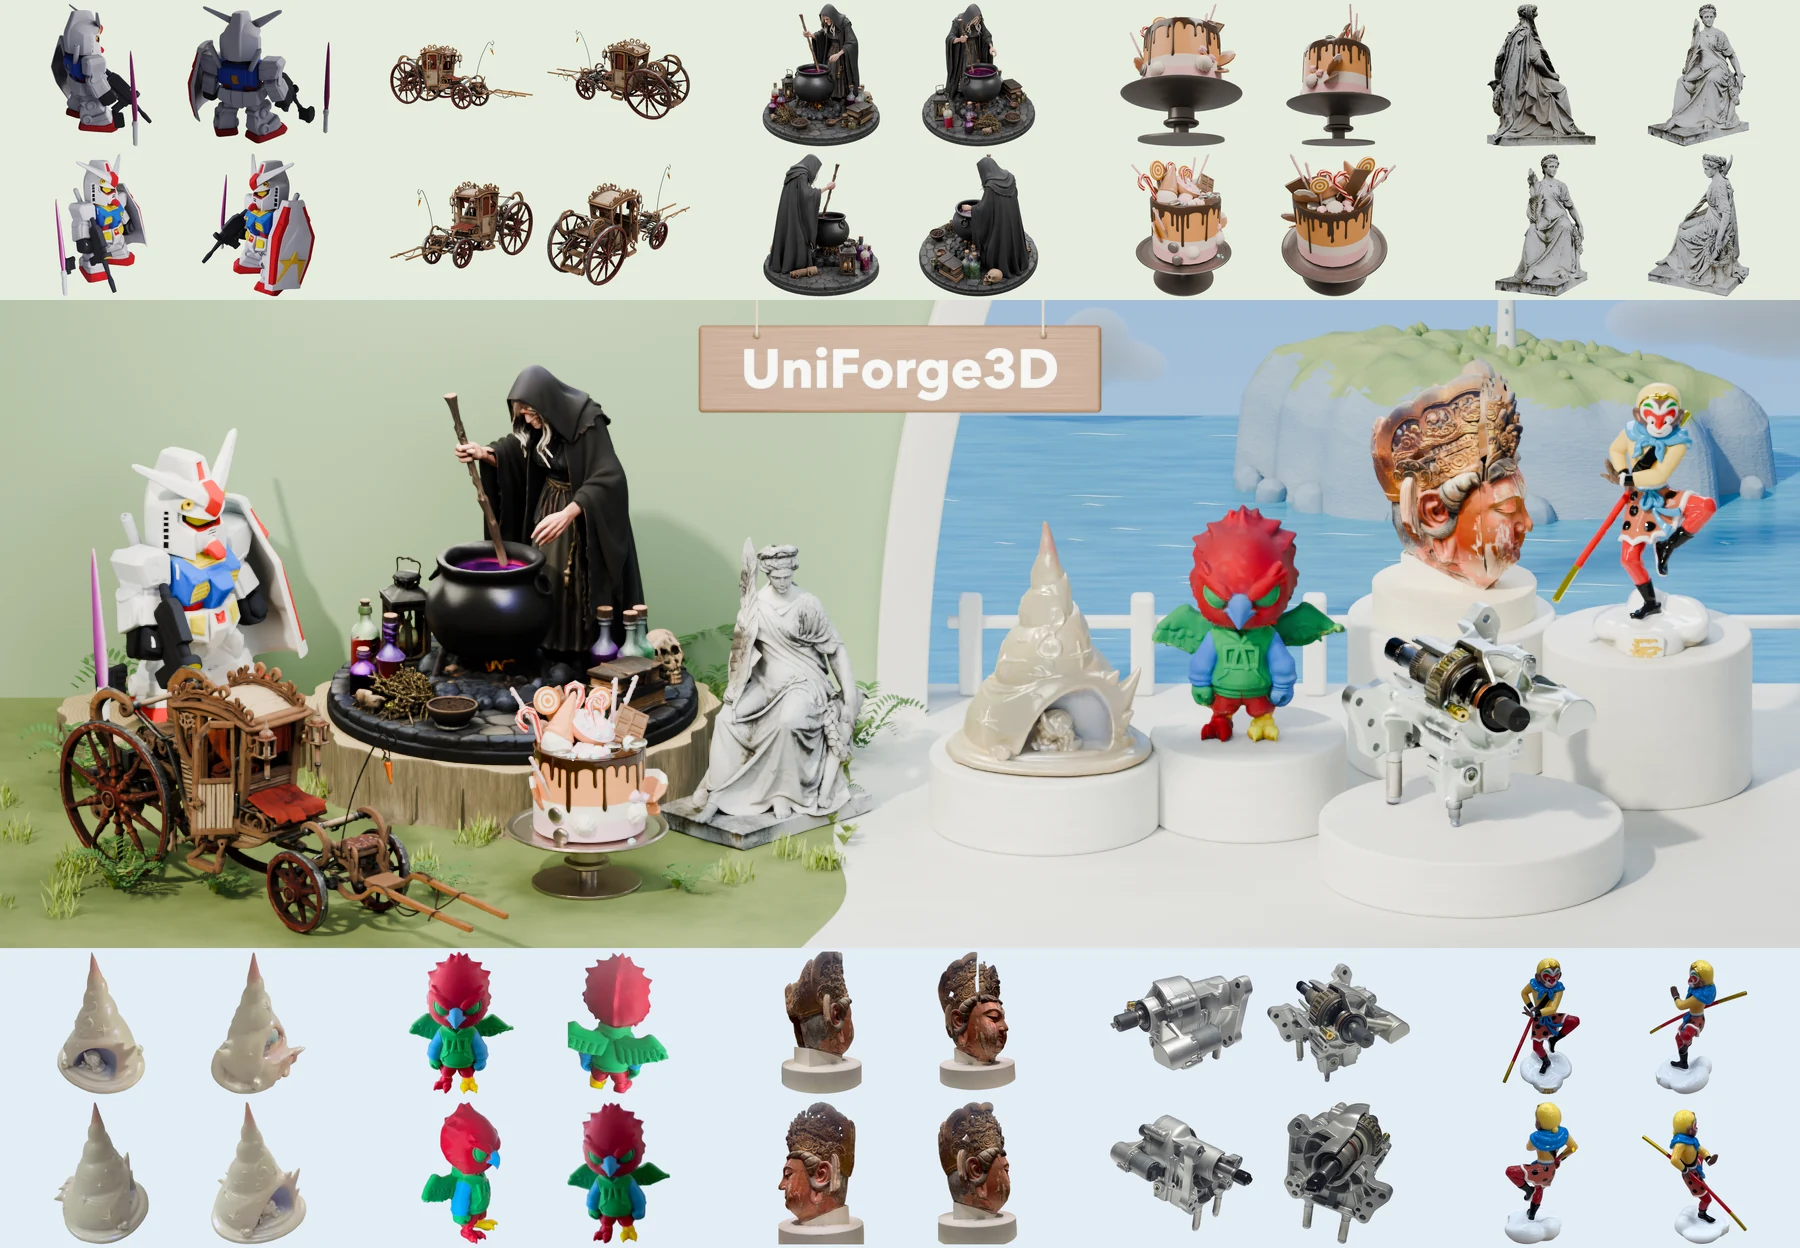
UniForge3D generates a complete 3D asset from a handful of sparse, unposed photos of one object. It jointly models reconstruction and generation in a shared anchor-guided space, so the parts you photographed stay faithful and the parts you did not are generated.
This is a fork of xibushu/UniForge3D that runs the same checkpoints on a Windows consumer machine — one 8 GB card, 64 GB of RAM, no nvcc, no conda — and adds a small web UI. Nothing about the model, its checkpoints or its output was changed: every optimisation here is bit-exact and ships with the script that proves it.
Tested configuration: Windows 11, Python 3.11, RTX 3070 Ti (8 GB), 64 GB RAM. Every number in this README was measured on that machine and is written up, with the method, in WINDOWS_LOWVRAM.md.
| Input | 2-4 photos of one object, any order — the views are sparse and unposed |
| Output | prediction.glb with baked PBR textures, plus the two texture maps as PNGs with --save-textures |
| Time | ~240 s per case at the shipped step counts (assets/case01); the most detailed examples take up to about four times that |
| First step | 21 s after launch, instead of waiting 102 s for the whole stack to load |
| VRAM | peaks at 6.3 GB of denoiser residency on an 8 GB card |
| Disk | ~30 GB of weights, or ~20 GB with the optional half-precision copies |
| RAM | 64 GB comfortable; --low-ram holds one stage's weights at a time |
o_voxel, nvdiffrast, flash-attn — comes from a cp311 win_amd64 wheel. There is no
nvcc, no conda and no 30-minute flash-attn build. scripts/fetch.py wheels pulls all of
them: torch and torchvision from the PyTorch index, flash-attn from its prebuild releases,
and the five extensions from the whl/ directory of the
TRELLIS.2-stableprojectorz
repository, which is where they are published.--low-ram additionally drops each stage's weights
once a case is done with them, so a resident server or a long batch holds one stage rather
than all of them.scripts/fetch.py pulls the ~30 GB of weights with parallel HTTP
range requests and resumes every chunk it has to retry, because pip and huggingface_hub
stalled on long transfers here.convert_weights_fp16.bat,
or scripts/convert_weights_fp16.py — writes fp16 copies of the eight fp32 checkpoints the
pipeline halves anyway (21.45 GiB down to 11.47 GiB), verifies them tensor by tensor, and
switches weights/pipeline.local.json over to them, so from then on every run uses them with
no extra flags. The originals are never modified, revert_weights_fp16.bat undoes it, and
scripts/check_fp16_weights.py proves the copies bit-identical to what the fp32 files
produce. They also take about 15 s off each --low-ram case, which reloads the weights
every time..pt files are only needed for the checkpoint-faithful float32
and --no-low-vram modes; deleting them takes weights/ from 41 GiB to 19 GiB. The tools
stay honest about it: the local config still points at the copies (the manifest records what
each came from, and a missing original is not a mismatch), check_fp16_weights.py stops with
"cannot verify" instead of reporting a pass, and convert_weights_fp16.py --revert refuses
rather than leaving the fp32 config pointing at nothing. scripts/fetch.py weights brings the
originals back.webui.py): load 2-4 images, watch progress, inspect the GLB, download it,
and optionally save the baked texture maps beside it.--save-textures (and the UI checkbox, ticked by default)
writes the pristine 2048² maps next to the GLB: basecolor.png (RGBA) and
metallic_roughness.png (G = roughness, B = metallic).| Item | Notes |
|---|---|
| Windows 11 | the installer is PowerShell. |
| Python 3.11 | every prebuilt CUDA wheel here is cp311 win_amd64. |
| NVIDIA driver | recent enough for CUDA 12.8. |
| Disk | ~30 GB of weights, ~4 GB of wheels, plus outputs. convert_weights_fp16.bat saves 10 GB of that. |
| RAM | 64 GB tested. Every group stays resident by default (42 GB committed, 27 GB working set here); --low-ram holds one group at a time (23 GB / 14 GB) and costs about 68 s per case. 16 GB is not enough: one group's load still peaks at 23 GB, because the model is built in fp32 and halved afterwards (section 5). Half-precision checkpoints save 0.5 GB of that and about 15 s of the low-RAM reload. |
git and curl.exe | git only to clone; curl.exe ships with Windows. |
git clone https://github.com/HardeNNN/UniForge3D-Low-VRAM
cd UniForge3D-Low-VRAM
python scripts\fetch.py wheels      # torch, torchvision, flash-attn and the 5 CUDA extension wheels -> whl/
scripts\install_windows.ps1         # venv + local wheels + pinned dependencies + web UI
python scripts\fetch.py weights     # the 17 model files -> weights/  (~30 GB)
python scripts\fetch.py extras      # dinov3 + RMBG-2.0 -> models/   (unzips on completion)
python scripts\make_local_config.py # weights/pipeline.local.json
Then, optionally, halve the fp32 checkpoints once — it saves about 10 GB of disk, and
weights\pipeline.local.json prefers the copies from then on, so nothing else changes:
scripts\convert_weights_fp16.bat # convert, verify, switch over; revert_weights_fp16.bat undoes it
Every step is resumable: re-run it after an interruption and it continues from what is
already on disk. fetch.py also takes --jobs N (files at once) and --connections N
(range chunks in flight). Run the download steps with Python 3.11 — every wheel here is
cp311, and fetch.py wheels says so instead of assembling an environment that cannot run.
Finish with scripts\check_env.py (below).
.\.venv\Scripts\python.exe webui.py          # http://127.0.0.1:7860
.\.venv\Scripts\python.exe webui.py --low-ram # one stage of weights resident at a time
There are double-click launchers for both: start_webui.bat and start_webui_lowram.bat.
They run these same commands from the repository root and pass any extra flags through, so
start_webui.bat --port 8000 --open works. They need no weight flags:
weights\pipeline.local.json already prefers the half-precision copies once
convert_weights_fp16.bat has run.
Load 2-4 photos of one object from different angles — the views are sparse and unposed, so
order does not matter. Jobs run one at a time, because that is all the card holds. Each job
writes its own directory under outputs/webui/, holding a copy of the exact images it ran on,
prediction.glb and — with the texture box ticked, as it is by default — the baked maps under
textures/. So a result stays reproducible.
Weights load a stage at a time, so there is no long wait before the first progress line: the
first stage starts as soon as its own models are in memory, and the rest of the stack is
loaded while the GPU works. --low-ram keeps only the stage being run in memory, which
bounds what a resident server holds at the cost of reloading the weights for every job.
--port, --host and --open are available, along with the residency flags above. The
server binds to the loopback interface and has no public share link. The interactive viewer
is Gradio's Babylon component, which needs WebGPU: with WebGPU disabled in the browser the
viewer stays empty, and the GLB preview and download still work.
.\.venv\Scripts\python.exe infer.py --config weights\pipeline.local.json --vram-debug
Cases are directories of images under --input (default assets\, which ships case01 to
case18), and --input may also be a single case directory. A case whose prediction.glb
already exists is skipped, so a batch is resumable. --limit N, --overwrite, --seed N,
--watch SECONDS, --save-textures, --low-ram, --prefetch and the precision flags are
listed in section 3 of the notes.
--weights-dtype float16 (the default under --low-vram), float32 and auto. auto
means "whatever the mode would use anyway": fp16 with the default --low-vram, and each
checkpoint's published precision with --no-low-vram. Only the last of those is
checkpoint-faithful, and the half-precision copies cannot provide it either, so point those
runs at a config built for the originals:
.\.venv\Scripts\python.exe scripts\make_local_config.py --fp32 --out weights\pipeline.local.fp32.json
.\.venv\Scripts\python.exe infer.py --config weights\pipeline.local.fp32.json --weights-dtype float32
On the tested machine the first denoiser step starts 21 s in, and one case costs about 240 s
(assets\case01, measured end to end) up to roughly four times that for the most detailed
example (assets\case05).
outputs/case01/
  prediction.glb                     the asset, PBR textures embedded
  textures/basecolor.png             2048x2048 RGBA, written with --save-textures
  textures/metallic_roughness.png    2048x2048, G = roughness, B = metallic
--save-textures writes the maps from the pristine in-memory images, so they are the same
maps that went into the GLB. The web UI always writes into outputs/webui/<job>/, with a copy
of the input images under input/ so a result can be reproduced exactly.
Every claim above has a script. They run on CPU unless noted, and most take a second:
| Script | What it checks |
|---|---|
scripts\check_env.py [--config …] | imports, every CUDA wheel, CUDA, then loads every model group and reports which weight set is in use |
scripts\check_glb.py FILE.glb | meshes, materials, images, attributes and bounding box of a result |
scripts\check_stage_loading.py [--low-ram] [--prefetch] | walks the six groups in stage order and asserts exactly what is resident after each one |
scripts\check_model_store.py | the residency store itself — lazy build, prefetch order, release, one build shared by concurrent callers; fake groups, no weights, about a second |
scripts\check_fp16_weights.py | loads every group through both configs and fails on one differing bit; about five minutes, CPU |
scripts\profile_load.py --config … | per-group load time |
scripts\bench_fp16_stage1.py --arm shipped|all-fp16 | what the fp32-pinned weights cost stage 1 (answer: about 1%) |
scripts\check_stage1_repeat.py | runs stage 1 repeatedly in one process and reports the intermittent second-call failure |
infer.py                 batch/CLI entry point
webui.py                 Gradio web UI
start_webui.bat          launcher: default residency
start_webui_lowram.bat   launcher: --low-ram
convert_weights_fp16.bat launcher: make and use the half-precision copies
revert_weights_fp16.bat  launcher: delete them and go back
WINDOWS_LOWVRAM.md       the measurement notes: VRAM, memory, timings, decisions
assets/                  example cases, case01 .. case18
scripts/                 installer, fetcher, config generator, verification, profiling
uniforge3d/models/store.py    stage-by-stage weight residency
uniforge3d/models/loaders.py  per-group loading and the dtype policy
uniforge3d/pipelines/         the pipeline itself
Nothing is committed here but code: the install fetches the weights.
xibushu/UniForge3D — the UniForge3D checkpoints.microsoft/TRELLIS.2-4B and microsoft/TRELLIS-image-large — the TRELLIS.2 decoders and
base DiT.TRELLIS.2-stableprojectorz project for the two gated
models, facebook/dinov3-vitl16-pretrain-lvd1689m and briaai/RMBG-2.0, so no Hugging
Face token is needed.The code in this repository is Apache-2.0, as upstream. The weights keep their own terms: the two gated models ship under Meta's DINOv3 licence and BRIA's RMBG-2.0 terms, both of which carry commercial-use conditions. Read those model cards before commercial use.
--low-ram trades that back for reloading each group per case (~68 s), and the
half-precision copies take about 15 s off that.--low-ram bounds what a run retains,
not that transient. A build-in-fp16 loader is designed but not written (section 5).--low-ram, and --no-prefetch so no later stage's weights
are held in host memory while the card works.--weights-dtype float32 warns about half-precision copies. The copies hold
fp16 values and cannot be raised back. Use the --fp32 config from the command-line
section for checkpoint-faithful runs.--jobs 1 --connections 4 is the
gentlest setting.illegal memory access, or Stage1 decoded an empty sparse structure. The access violations have a known cause: the host running out of commit, which
Windows reports that way. Check how much is already committed (Get-CimInstance Win32_OperatingSystem → FreeVirtualMemory) before blaming the card — a resident web UI plus
a CLI batch is ~40 GB, and the page file here is capped at 32 GB. Re-run the case; the empty
structure is a rare sampling failure on the random noise.python infer.py with no --config starts downloading from Hugging Face. Without it,
infer.py falls back to the upstream --model xibushu/UniForge3D path. Pass
--config weights\pipeline.local.json, which is what the install produces and what every
command above uses.This fork stands on UniForge3D, TRELLIS.2, VGGT, CuMesh, FlexGEMM, nvdiffrast and xatlas. The Windows path follows TRELLIS.2-stableprojectorz by Igor Aherne, which is where the prebuilt wheel builds and the ungated model mirror come from.
@article{chen2026uniforge3d,
  title   = {UniForge3D: Joint 3D Reconstruction and Generation in a Shared Anchor-Guided Space},
  author  = {Chen, Wenjue and Chen, Wenyue and Zheng, Heliang and Jia, Rongfei and Liu, Yuan and Li, Meng},
  journal = {arXiv preprint arXiv:2610.15357},
  year    = {2026}
}
Apache-2.0, the same licence as upstream — see LICENSE. This is a modified copy of UniForge3D: the staged-residency changes, the Windows installer, the downloader, the diagnostic scripts and the web UI are additions, and the differences from upstream are described in WINDOWS_LOWVRAM.md.