Meet JevEmbed — turn embeddings into decisions. Choose, score, and judge with your choice of embedding model.
See the code
One-Stop Decision Toolkit for Embedding Models: data synthesis, fine-tuning, inference, benchmarking, and interactive exploration.
Explore Choice, Score, and Noul decisions in the browser, compare models, inspect JSON results, and try model-controlled pixel games in Game Lab.
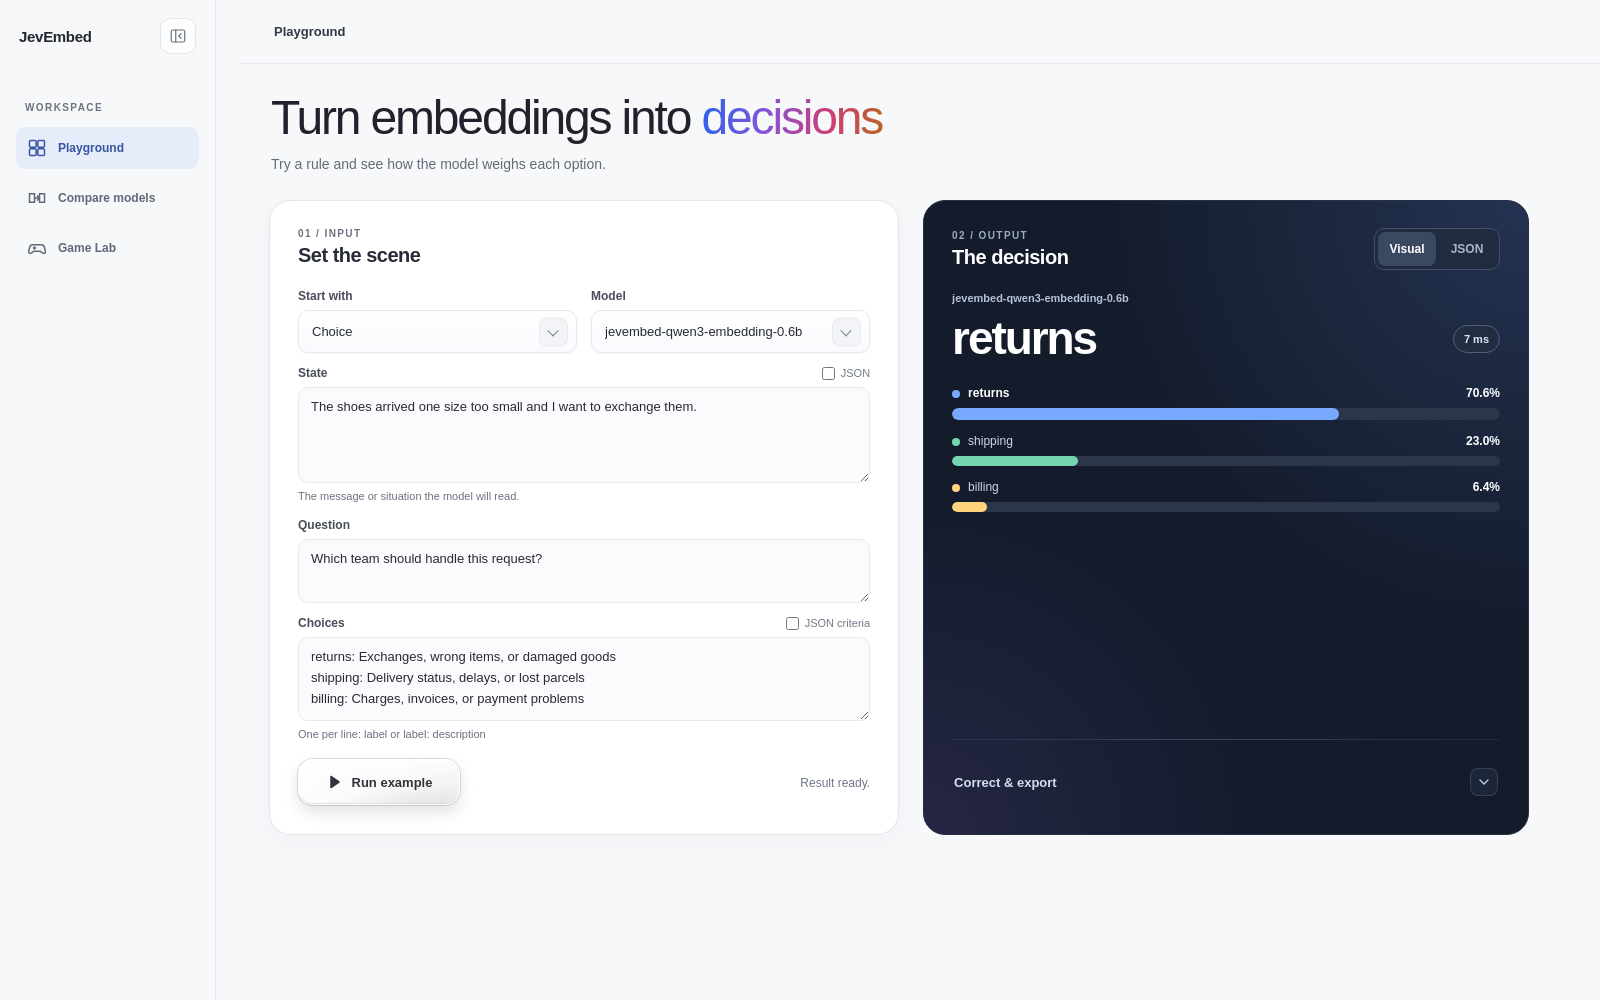
Run python -m jevembed --playground, then open http://127.0.0.1:8000/playground/. See the Playground guide for model configuration and usage.
Use Python 3.10–3.12 for the tested model stack.
Full installation
Run these commands from the project root:
python -m venv .venv
source .venv/bin/activate
# Windows PowerShell: .venv\Scripts\Activate.ps1
python -m pip install -r requirements.txt
python -m pip install -e . --no-deps
requirements.txt includes local inference and HTTP dependencies with the constraints in requirements-models-tested.txt. Contributors can install requirements-dev.txt for testing and packaging. See dependency compatibility for package roles and tested versions.
Optional installations
Install only the extras you need:
python -m pip install -e .                        # Core, configuration, and explain
python -m pip install -e '.[http,server]'          # HTTP backend and API
python -m pip install -e '.[local]' -c requirements-models-tested.txt
python -m pip install -r requirements-dev.txt     # Tests and builds, without model libraries
Core imports and --explain require no model weights or service.
Run a single request from the command line:
python -m jevembed --config configs/kalm-embedding-v2.5.yaml \
  --input examples/official_choice_exchange.json
To keep a model loaded and serve decisions over HTTP, start the server from the project root:
python -m jevembed \
  --config configs/jevembed-qwen3-embedding-0.6b.yaml \
  --serve
Send a Choice request from another terminal:
curl -sS http://127.0.0.1:8000/v1/systemone \
  -H 'Content-Type: application/json' \
  --data-binary @- <<'JSON'
{
  "model": "jevembed-qwen3-embedding-0.6b",
  "state": "My running shoes arrived in the wrong size. Can I swap them for a size 10?",
  "questions": {
    "department": {
      "type": "choice",
      "instructions": "Which team should handle this?",
      "criteria": {
        "returns": "Exchanges, wrong or damaged items",
        "shipping": "Delivery status, delays, lost packages",
        "billing": "Charges, invoices, payment problems"
      }
    }
  }
}
JSON
See the HTTP guide for Python requests, multiple models, Score and Noul examples, serving options, limits, and error responses.
To use an external /v1/embeddings service as the backend, start with http-example.yaml and follow the external service guide.
Use JevEmbed directly from Python:
import json
from pathlib import Path
from jevembed import JevEmbed, ModelConfig

config = ModelConfig.load("configs/kalm-embedding-v2.5.yaml")
client = JevEmbed(config=config)
request = json.loads(Path("examples/official_noul_escalation.json").read_text(encoding="utf-8"))
response = client.evaluate(request)
print(response)
See the Python API guide for multiple models, direct request construction, input inspection, traces, caching, and custom backends. For local model paths and offline loading, see local weights and offline use.
Supported models are listed below. Configurations use Hugging Face repository IDs; weights download on first inference if absent from the local cache.
| Weight repository | JevEmbed ID | Embedding dimensions | Max tokens | Pooling |
|---|---|---|---|---|
| KaLM-Embedding/KaLM-embedding-multilingual-mini-instruct-v2.5 | kalm-embedding-v2.5 | 896 | 32,768 | Mean |
| Qwen/Qwen3-Embedding-0.6B | qwen3-embedding-0.6b | 1,024 | 32,768 | Last-token |
| Qwen/Qwen3-Embedding-4B | qwen3-embedding-4b | 2,560 | 32,768 | Last-token |
| Qwen/Qwen3-Embedding-8B | qwen3-embedding-8b | 4,096 | 32,768 | Last-token |
| intfloat/multilingual-e5-large-instruct | multilingual-e5-large-instruct | 1,024 | 512 | Mean |
| Contrastive-LM/CLM-v0.1-8B | clm-v0.1-8b | 512 | 2,048 | Last-token + paired heads |
| HIT-TMG/JevEmbed-KaLM-Embedding-V2.5 | jevembed-kalm-embedding-v2.5 | 896 | 1,024 | Mean |
| HIT-TMG/JevEmbed-Qwen3-Embedding-0.6B | jevembed-qwen3-embedding-0.6b | 1,024 | 1,024 | Last-token |
| HIT-TMG/JevEmbed-Qwen3-Embedding-4B | jevembed-qwen3-embedding-4b | 2,560 | 1,024 | Last-token |
CLM-v0.1-8B uses Qwen/Qwen3-8B as its base encoder with separate state and action projection heads.
See model configuration and loading for aliases, truncation, remote-code trust, and model-specific behavior.
See official examples and scoring for Choice, Score, and Noul requests, saved Jev reference outputs, KaLM-embedding-multilingual-mini-instruct-v2.5 predictions, rendered embedding inputs, scoring rules, and worked cases.
Run versioned Choice, Score, and Noul JSONL benchmarks with one or more model configurations. The runner writes per-model results.json, an optional predictions.jsonl, and a comparison summary.json:
jevembed-benchmark --benchmark examples/benchmark/benchmark.json \
  --config configs/jevembed-qwen3-embedding-0.6b.yaml --output results
The benchmark guide defines the input format, targets, metrics, and result layout.
JevEmbed fine-tunes Sentence Transformers encoders on Choice, Score, and Noul supervision, including soft targets. The released JevEmbed-KaLM-Embedding-V2.5, JevEmbed-Qwen3-Embedding-0.6B, and JevEmbed-Qwen3-Embedding-4B models each trained for one epoch on all 1,601,157 JevEmbed-Data training questions, then had their LoRA weights merged into standalone models. All three used:
| Setting | Value |
|---|---|
| Precision | BF16 |
| Effective batch | 512 questions |
| LoRA rank | 64 |
| LoRA alpha | 32 |
| LoRA dropout | 0.05 |
| LoRA targets | q_proj, k_proj, and v_proj |
| Learning rate | 2 × 10⁻⁴ |
| Warmup | 10% |
| Input length | 1,024-token truncation |
| Choice/Score temperature | 0.1 |
| Noul slope | 10 |
Decision scaling follows the KaLM-embedding-multilingual-mini-instruct-v2.5 and Qwen3-Embedding-0.6B base configurations.
Install the training extra with python -m pip install -e '.[train]' -c requirements-models-tested.txt. The trainer reads supervised JSONL, so convert the dataset's train Parquet rows to the documented JSONL schema and reserve test for final evaluation. The training guide covers commands, validation, and adapter inference; the model cards give each release's exact settings.
On the held-out JevEmbed-Data test split, overall hard-label accuracy covers 64,110 of 66,482 questions:
| Model | Base | After JevEmbed-Data fine-tuning | Change |
|---|---|---|---|
KaLM-Embedding/KaLM-embedding-multilingual-mini-instruct-v2.5 | 32.33% | 76.03% | +43.70 pp |
Qwen/Qwen3-Embedding-0.6B | 33.79% | 82.30% | +48.51 pp |
Qwen/Qwen3-Embedding-4B | 36.29% | 85.86% | +49.57 pp |
The full test report gives Choice, Score, and Noul accuracy and error metrics.
The synthesis guide explains how to use an OpenAI-compatible model to create Choice, Score, and Noul training data for a fixed question. It includes example configs, schema checks, label quotas, label checks, reference rules, and resumable generation. Review the generated samples before training.
The six base models and three JevEmbed releases were evaluated on the same 66,482-question JevEmbed-Data test split. Accuracy covers 64,110 hard-labeled questions; soft labels are excluded. The released models were fine-tuned on the training split; the base rows use the original weights. Higher is better.
| Model | Choice (17,487) | Score (24,260) | Noul (22,363) | Overall (64,110) |
|---|---|---|---|---|
| KaLM-Embedding/KaLM-embedding-multilingual-mini-instruct-v2.5 | 28.61% | 27.45% | 40.52% | 32.33% |
| Qwen/Qwen3-Embedding-0.6B | 33.02% | 28.56% | 40.05% | 33.79% |
| Qwen/Qwen3-Embedding-4B | 38.11% | 30.55% | 41.09% | 36.29% |
| Qwen/Qwen3-Embedding-8B | 43.20% | 33.49% | 42.57% | 39.30% |
| intfloat/multilingual-e5-large-instruct | 32.07% | 24.27% | 40.54% | 32.07% |
| Contrastive-LM/CLM-v0.1-8B | 28.59% | 25.85% | 53.74% | 36.33% |
| JevEmbed-KaLM-Embedding-V2.5 | 71.05% | 66.17% | 90.61% | 76.03% |
| JevEmbed-Qwen3-Embedding-0.6B | 84.53% | 69.55% | 94.38% | 82.30% |
| JevEmbed-Qwen3-Embedding-4B | 90.31% | 73.41% | 95.88% | 85.86% |
The full test report gives the error metrics, denominators, and evaluation command.
See the compatibility boundaries and architecture and design for the implementation contract.
See CONTRIBUTING.md for development, testing, and build instructions.
If you find this repository useful, please consider giving it a star ⭐ and citing the following papers:
@misc{zhao2025kalmembeddingv2,
      title={KaLM-Embedding-V2: Superior Training Techniques and Data Inspire A Versatile Embedding Model},
      author={Xinping Zhao and Xinshuo Hu and Zifei Shan and Shouzheng Huang and Yao Zhou and Xin Zhang and Zetian Sun and Zhenyu Liu and Dongfang Li and Xinyuan Wei and Youcheng Pan and Yang Xiang and Meishan Zhang and Haofen Wang and Jun Yu and Baotian Hu and Min Zhang},
      year={2025},
      eprint={2506.20923},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2506.20923},
}

@misc{hu2025kalmembedding,
      title={KaLM-Embedding: Superior Training Data Brings A Stronger Embedding Model},
      author={Xinshuo Hu and Zifei Shan and Xinping Zhao and Zetian Sun and Zhenyu Liu and Dongfang Li and Shaolin Ye and Xinyuan Wei and Qian Chen and Baotian Hu and Haofen Wang and Jun Yu and Min Zhang},
      year={2025},
      eprint={2501.01028},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2501.01028},
}
587 followers · starred Sep 2026
90 followers · starred Sep 2026
Meet JevEmbed — turn embeddings into decisions. Choose, score, and judge with your choice of embedding model.
See the code
One-Stop Decision Toolkit for Embedding Models: data synthesis, fine-tuning, inference, benchmarking, and interactive exploration.
Explore Choice, Score, and Noul decisions in the browser, compare models, inspect JSON results, and try model-controlled pixel games in Game Lab.
Run python -m jevembed --playground, then open http://127.0.0.1:8000/playground/. See the Playground guide for model configuration and usage.
Use Python 3.10–3.12 for the tested model stack.
Full installation
Run these commands from the project root:
python -m venv .venv
source .venv/bin/activate
# Windows PowerShell: .venv\Scripts\Activate.ps1
python -m pip install -r requirements.txt
python -m pip install -e . --no-deps
requirements.txt includes local inference and HTTP dependencies with the constraints in requirements-models-tested.txt. Contributors can install requirements-dev.txt for testing and packaging. See dependency compatibility for package roles and tested versions.
Optional installations
Install only the extras you need:
python -m pip install -e .                        # Core, configuration, and explain
python -m pip install -e '.[http,server]'          # HTTP backend and API
python -m pip install -e '.[local]' -c requirements-models-tested.txt
python -m pip install -r requirements-dev.txt     # Tests and builds, without model libraries
Core imports and --explain require no model weights or service.
Run a single request from the command line:
python -m jevembed --config configs/kalm-embedding-v2.5.yaml \
  --input examples/official_choice_exchange.json
To keep a model loaded and serve decisions over HTTP, start the server from the project root:
python -m jevembed \
  --config configs/jevembed-qwen3-embedding-0.6b.yaml \
  --serve
Send a Choice request from another terminal:
curl -sS http://127.0.0.1:8000/v1/systemone \
  -H 'Content-Type: application/json' \
  --data-binary @- <<'JSON'
{
  "model": "jevembed-qwen3-embedding-0.6b",
  "state": "My running shoes arrived in the wrong size. Can I swap them for a size 10?",
  "questions": {
    "department": {
      "type": "choice",
      "instructions": "Which team should handle this?",
      "criteria": {
        "returns": "Exchanges, wrong or damaged items",
        "shipping": "Delivery status, delays, lost packages",
        "billing": "Charges, invoices, payment problems"
      }
    }
  }
}
JSON
See the HTTP guide for Python requests, multiple models, Score and Noul examples, serving options, limits, and error responses.
To use an external /v1/embeddings service as the backend, start with http-example.yaml and follow the external service guide.
Use JevEmbed directly from Python:
import json
from pathlib import Path
from jevembed import JevEmbed, ModelConfig

config = ModelConfig.load("configs/kalm-embedding-v2.5.yaml")
client = JevEmbed(config=config)
request = json.loads(Path("examples/official_noul_escalation.json").read_text(encoding="utf-8"))
response = client.evaluate(request)
print(response)
See the Python API guide for multiple models, direct request construction, input inspection, traces, caching, and custom backends. For local model paths and offline loading, see local weights and offline use.
Supported models are listed below. Configurations use Hugging Face repository IDs; weights download on first inference if absent from the local cache.
| Weight repository | JevEmbed ID | Embedding dimensions | Max tokens | Pooling |
|---|---|---|---|---|
| KaLM-Embedding/KaLM-embedding-multilingual-mini-instruct-v2.5 | kalm-embedding-v2.5 | 896 | 32,768 | Mean |
| Qwen/Qwen3-Embedding-0.6B | qwen3-embedding-0.6b | 1,024 | 32,768 | Last-token |
| Qwen/Qwen3-Embedding-4B | qwen3-embedding-4b | 2,560 | 32,768 | Last-token |
| Qwen/Qwen3-Embedding-8B | qwen3-embedding-8b | 4,096 | 32,768 | Last-token |
| intfloat/multilingual-e5-large-instruct | multilingual-e5-large-instruct | 1,024 | 512 | Mean |
| Contrastive-LM/CLM-v0.1-8B | clm-v0.1-8b | 512 | 2,048 | Last-token + paired heads |
| HIT-TMG/JevEmbed-KaLM-Embedding-V2.5 | jevembed-kalm-embedding-v2.5 | 896 | 1,024 | Mean |
| HIT-TMG/JevEmbed-Qwen3-Embedding-0.6B | jevembed-qwen3-embedding-0.6b | 1,024 | 1,024 | Last-token |
| HIT-TMG/JevEmbed-Qwen3-Embedding-4B | jevembed-qwen3-embedding-4b | 2,560 | 1,024 | Last-token |
CLM-v0.1-8B uses Qwen/Qwen3-8B as its base encoder with separate state and action projection heads.
See model configuration and loading for aliases, truncation, remote-code trust, and model-specific behavior.
See official examples and scoring for Choice, Score, and Noul requests, saved Jev reference outputs, KaLM-embedding-multilingual-mini-instruct-v2.5 predictions, rendered embedding inputs, scoring rules, and worked cases.
Run versioned Choice, Score, and Noul JSONL benchmarks with one or more model configurations. The runner writes per-model results.json, an optional predictions.jsonl, and a comparison summary.json:
jevembed-benchmark --benchmark examples/benchmark/benchmark.json \
  --config configs/jevembed-qwen3-embedding-0.6b.yaml --output results
The benchmark guide defines the input format, targets, metrics, and result layout.
JevEmbed fine-tunes Sentence Transformers encoders on Choice, Score, and Noul supervision, including soft targets. The released JevEmbed-KaLM-Embedding-V2.5, JevEmbed-Qwen3-Embedding-0.6B, and JevEmbed-Qwen3-Embedding-4B models each trained for one epoch on all 1,601,157 JevEmbed-Data training questions, then had their LoRA weights merged into standalone models. All three used:
| Setting | Value |
|---|---|
| Precision | BF16 |
| Effective batch | 512 questions |
| LoRA rank | 64 |
| LoRA alpha | 32 |
| LoRA dropout | 0.05 |
| LoRA targets | q_proj, k_proj, and v_proj |
| Learning rate | 2 × 10⁻⁴ |
| Warmup | 10% |
| Input length | 1,024-token truncation |
| Choice/Score temperature | 0.1 |
| Noul slope | 10 |
Decision scaling follows the KaLM-embedding-multilingual-mini-instruct-v2.5 and Qwen3-Embedding-0.6B base configurations.
Install the training extra with python -m pip install -e '.[train]' -c requirements-models-tested.txt. The trainer reads supervised JSONL, so convert the dataset's train Parquet rows to the documented JSONL schema and reserve test for final evaluation. The training guide covers commands, validation, and adapter inference; the model cards give each release's exact settings.
On the held-out JevEmbed-Data test split, overall hard-label accuracy covers 64,110 of 66,482 questions:
| Model | Base | After JevEmbed-Data fine-tuning | Change |
|---|---|---|---|
KaLM-Embedding/KaLM-embedding-multilingual-mini-instruct-v2.5 | 32.33% | 76.03% | +43.70 pp |
Qwen/Qwen3-Embedding-0.6B | 33.79% | 82.30% | +48.51 pp |
Qwen/Qwen3-Embedding-4B | 36.29% | 85.86% | +49.57 pp |
The full test report gives Choice, Score, and Noul accuracy and error metrics.
The synthesis guide explains how to use an OpenAI-compatible model to create Choice, Score, and Noul training data for a fixed question. It includes example configs, schema checks, label quotas, label checks, reference rules, and resumable generation. Review the generated samples before training.
The six base models and three JevEmbed releases were evaluated on the same 66,482-question JevEmbed-Data test split. Accuracy covers 64,110 hard-labeled questions; soft labels are excluded. The released models were fine-tuned on the training split; the base rows use the original weights. Higher is better.
| Model | Choice (17,487) | Score (24,260) | Noul (22,363) | Overall (64,110) |
|---|---|---|---|---|
| KaLM-Embedding/KaLM-embedding-multilingual-mini-instruct-v2.5 | 28.61% | 27.45% | 40.52% | 32.33% |
| Qwen/Qwen3-Embedding-0.6B | 33.02% | 28.56% | 40.05% | 33.79% |
| Qwen/Qwen3-Embedding-4B | 38.11% | 30.55% | 41.09% | 36.29% |
| Qwen/Qwen3-Embedding-8B | 43.20% | 33.49% | 42.57% | 39.30% |
| intfloat/multilingual-e5-large-instruct | 32.07% | 24.27% | 40.54% | 32.07% |
| Contrastive-LM/CLM-v0.1-8B | 28.59% | 25.85% | 53.74% | 36.33% |
| JevEmbed-KaLM-Embedding-V2.5 | 71.05% | 66.17% | 90.61% | 76.03% |
| JevEmbed-Qwen3-Embedding-0.6B | 84.53% | 69.55% | 94.38% | 82.30% |
| JevEmbed-Qwen3-Embedding-4B | 90.31% | 73.41% | 95.88% | 85.86% |
The full test report gives the error metrics, denominators, and evaluation command.
See the compatibility boundaries and architecture and design for the implementation contract.
See CONTRIBUTING.md for development, testing, and build instructions.
If you find this repository useful, please consider giving it a star ⭐ and citing the following papers:
@misc{zhao2025kalmembeddingv2,
      title={KaLM-Embedding-V2: Superior Training Techniques and Data Inspire A Versatile Embedding Model},
      author={Xinping Zhao and Xinshuo Hu and Zifei Shan and Shouzheng Huang and Yao Zhou and Xin Zhang and Zetian Sun and Zhenyu Liu and Dongfang Li and Xinyuan Wei and Youcheng Pan and Yang Xiang and Meishan Zhang and Haofen Wang and Jun Yu and Baotian Hu and Min Zhang},
      year={2025},
      eprint={2506.20923},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2506.20923},
}

@misc{hu2025kalmembedding,
      title={KaLM-Embedding: Superior Training Data Brings A Stronger Embedding Model},
      author={Xinshuo Hu and Zifei Shan and Xinping Zhao and Zetian Sun and Zhenyu Liu and Dongfang Li and Shaolin Ye and Xinyuan Wei and Qian Chen and Baotian Hu and Haofen Wang and Jun Yu and Min Zhang},
      year={2025},
      eprint={2501.01028},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2501.01028},
}
587 followers · starred Sep 2026
90 followers · starred Sep 2026



