
An AI-powered academic paper analysis system with hierarchical multi-agent architecture and interactive web interface.
Python
5
38 commits
updated Mar 14, 2026
README
Paper Reader Agent


Hierarchical Multi-Agent System for Academic Paper Deep Analysis & AI-Powered Web Research
中文文档 | English
Quick Links: Paper Reader | Deep Research | Documentation
📖 Introduction
Paper Reader Agent is an advanced AI system designed to read, analyze, and synthesize academic papers with a depth that matches human researchers.
Deep Research is a powerful AI-powered web research tool that leverages Tavily and Valyu APIs to conduct comprehensive, real-time research on any topic, generating detailed reports with citations from online sources.
Together, they form a complete research workflow: Paper Reader for deep paper analysis, and Deep Research for broad topic exploration.
📸 Click to see Screenshots (UI & Features)
Paper Reader
| Modern Web UI (Bilingual) | Real-time Progress Tracking |
|---|---|
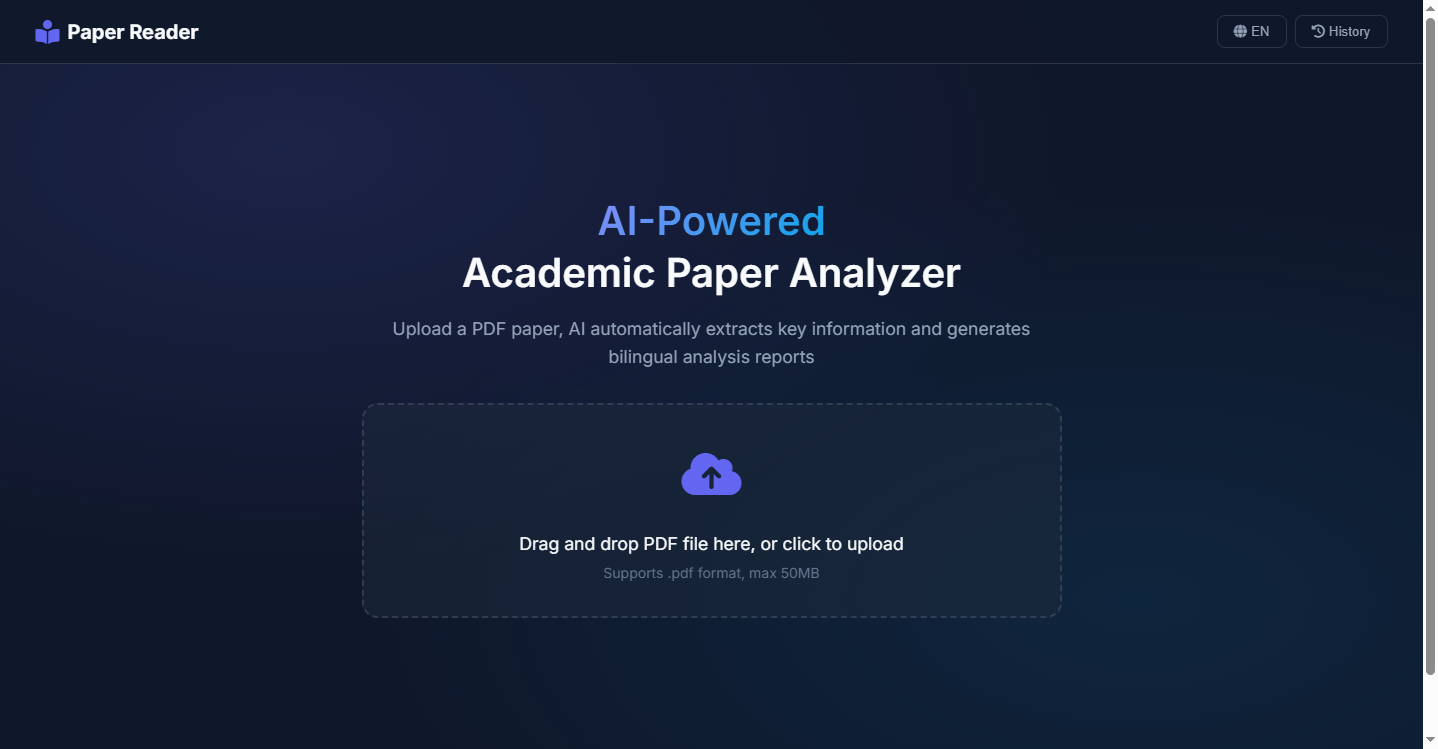 | 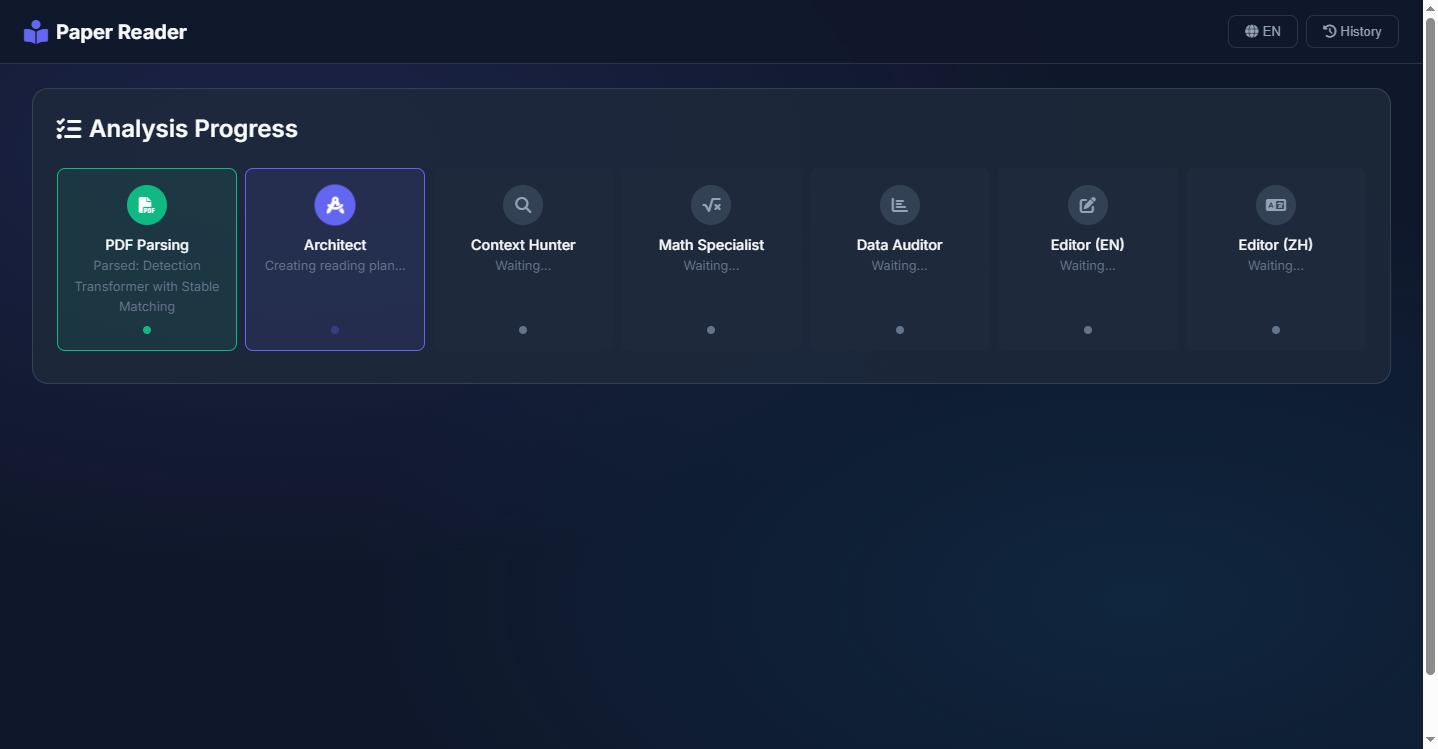 |
| Clean interface with EN/ZH switching | Visualize the 5-agent team in action |
| Publication-Quality Reports | Specialist Deep Dives |
|---|---|
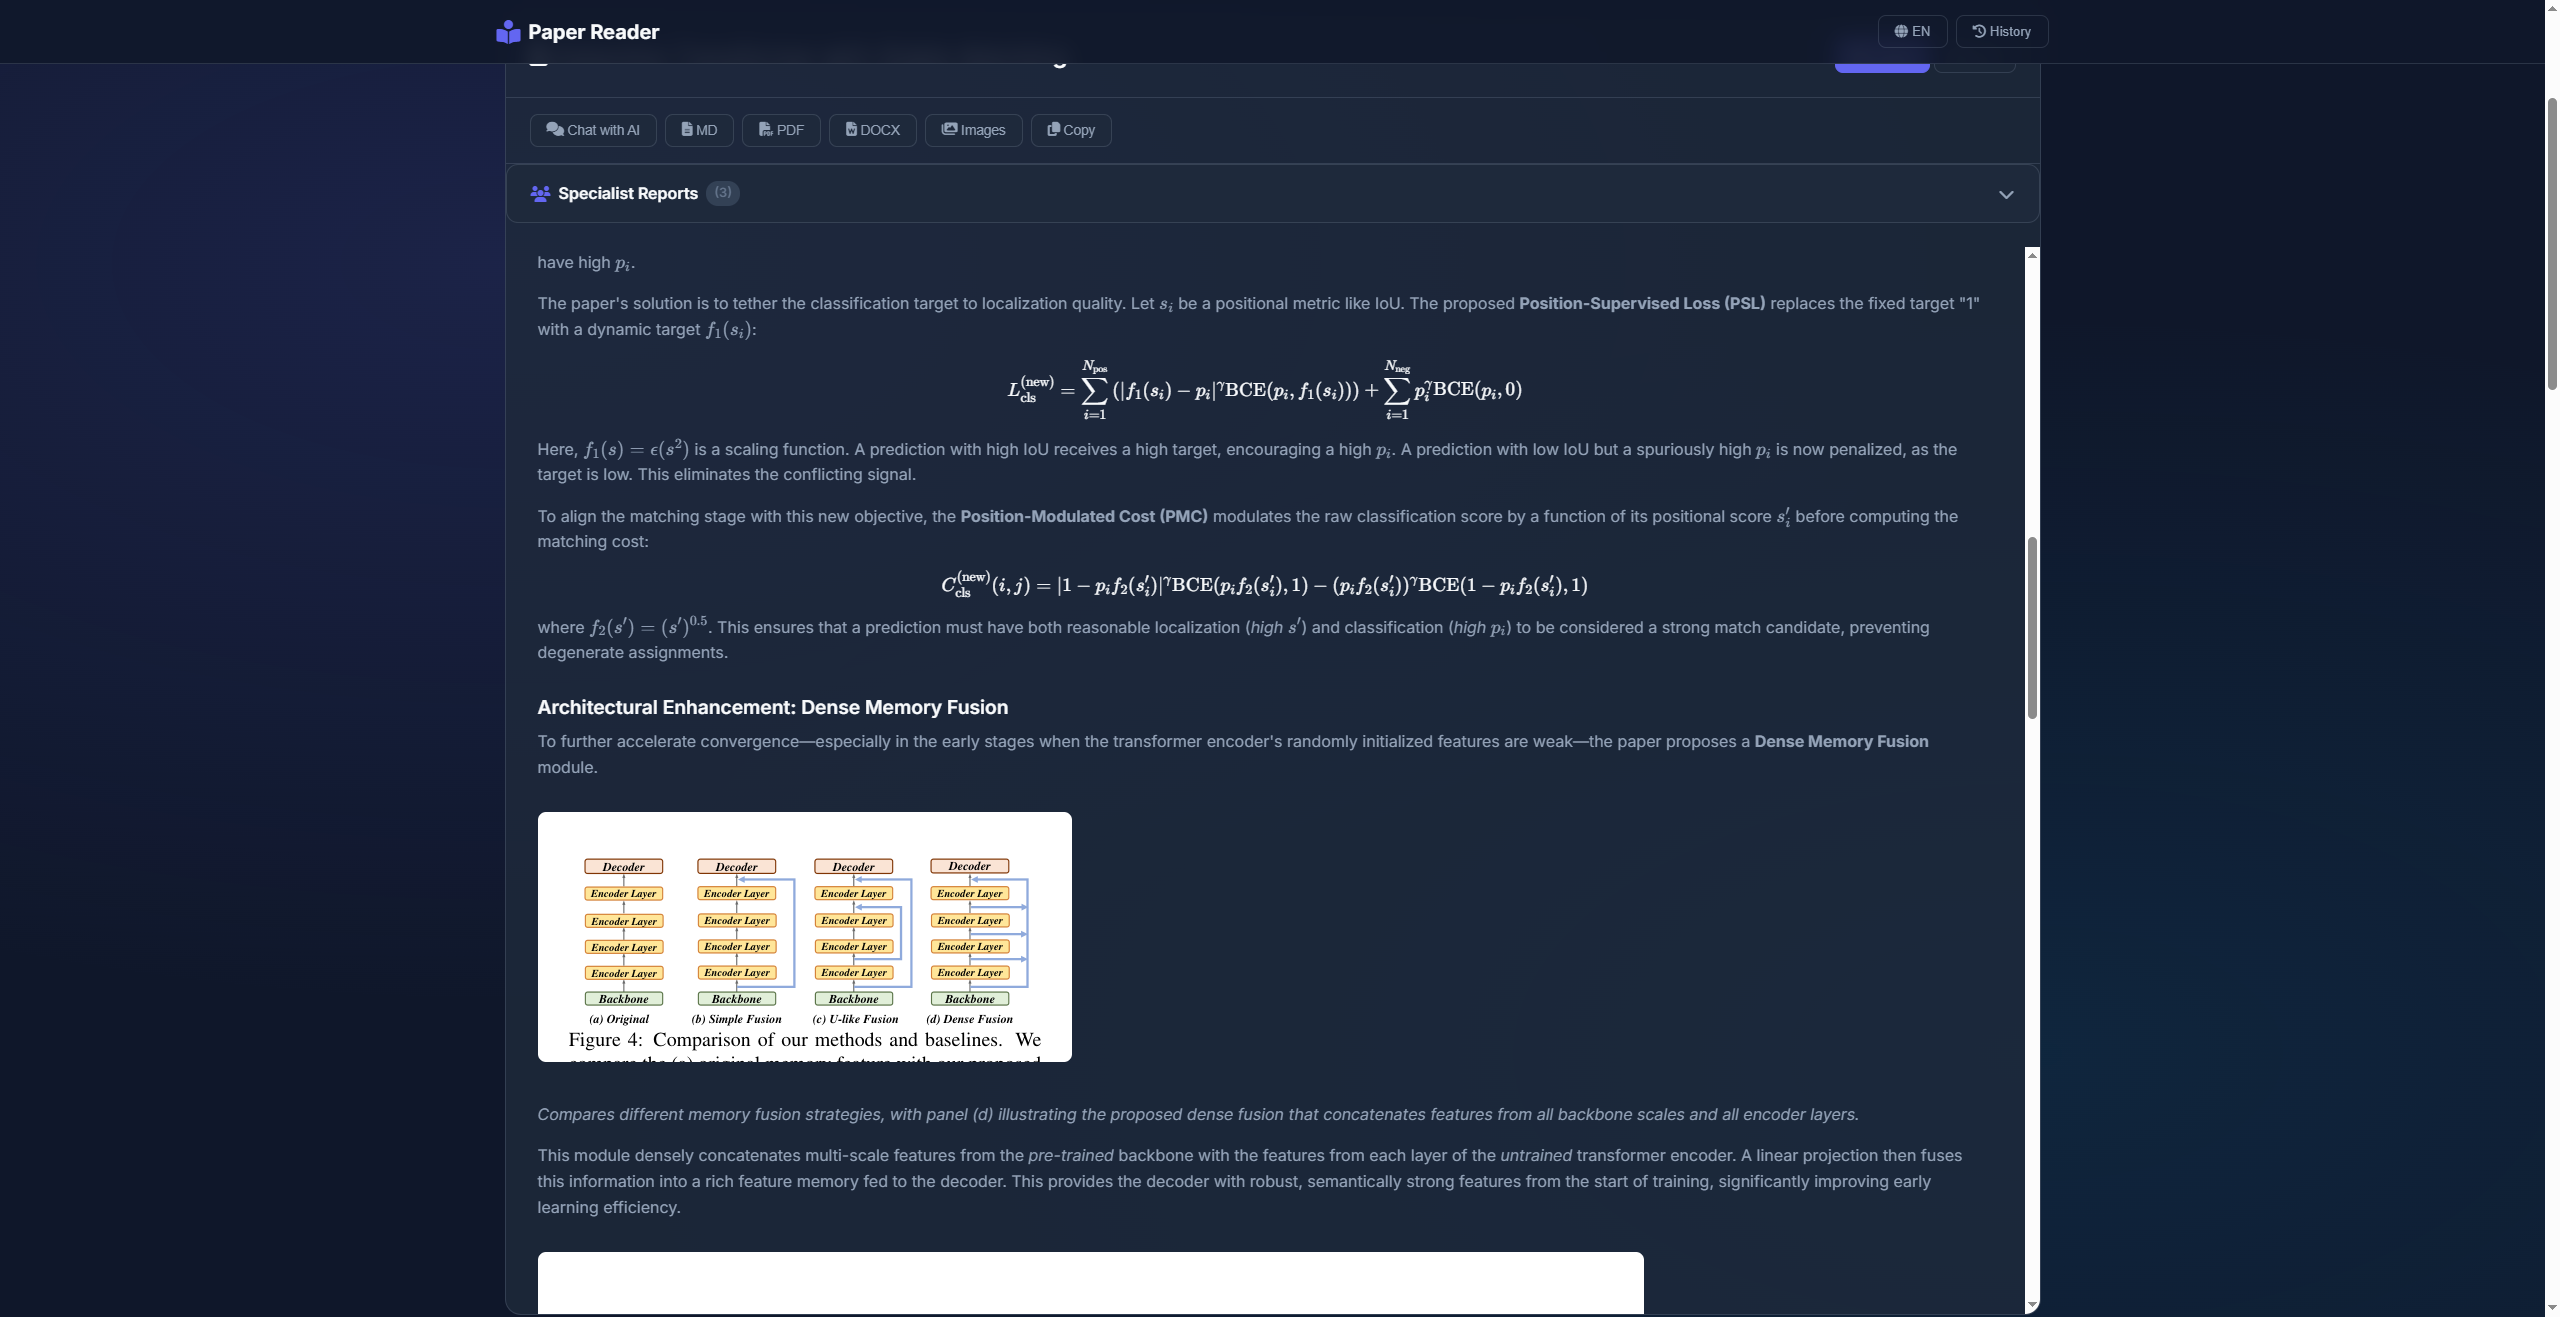 | 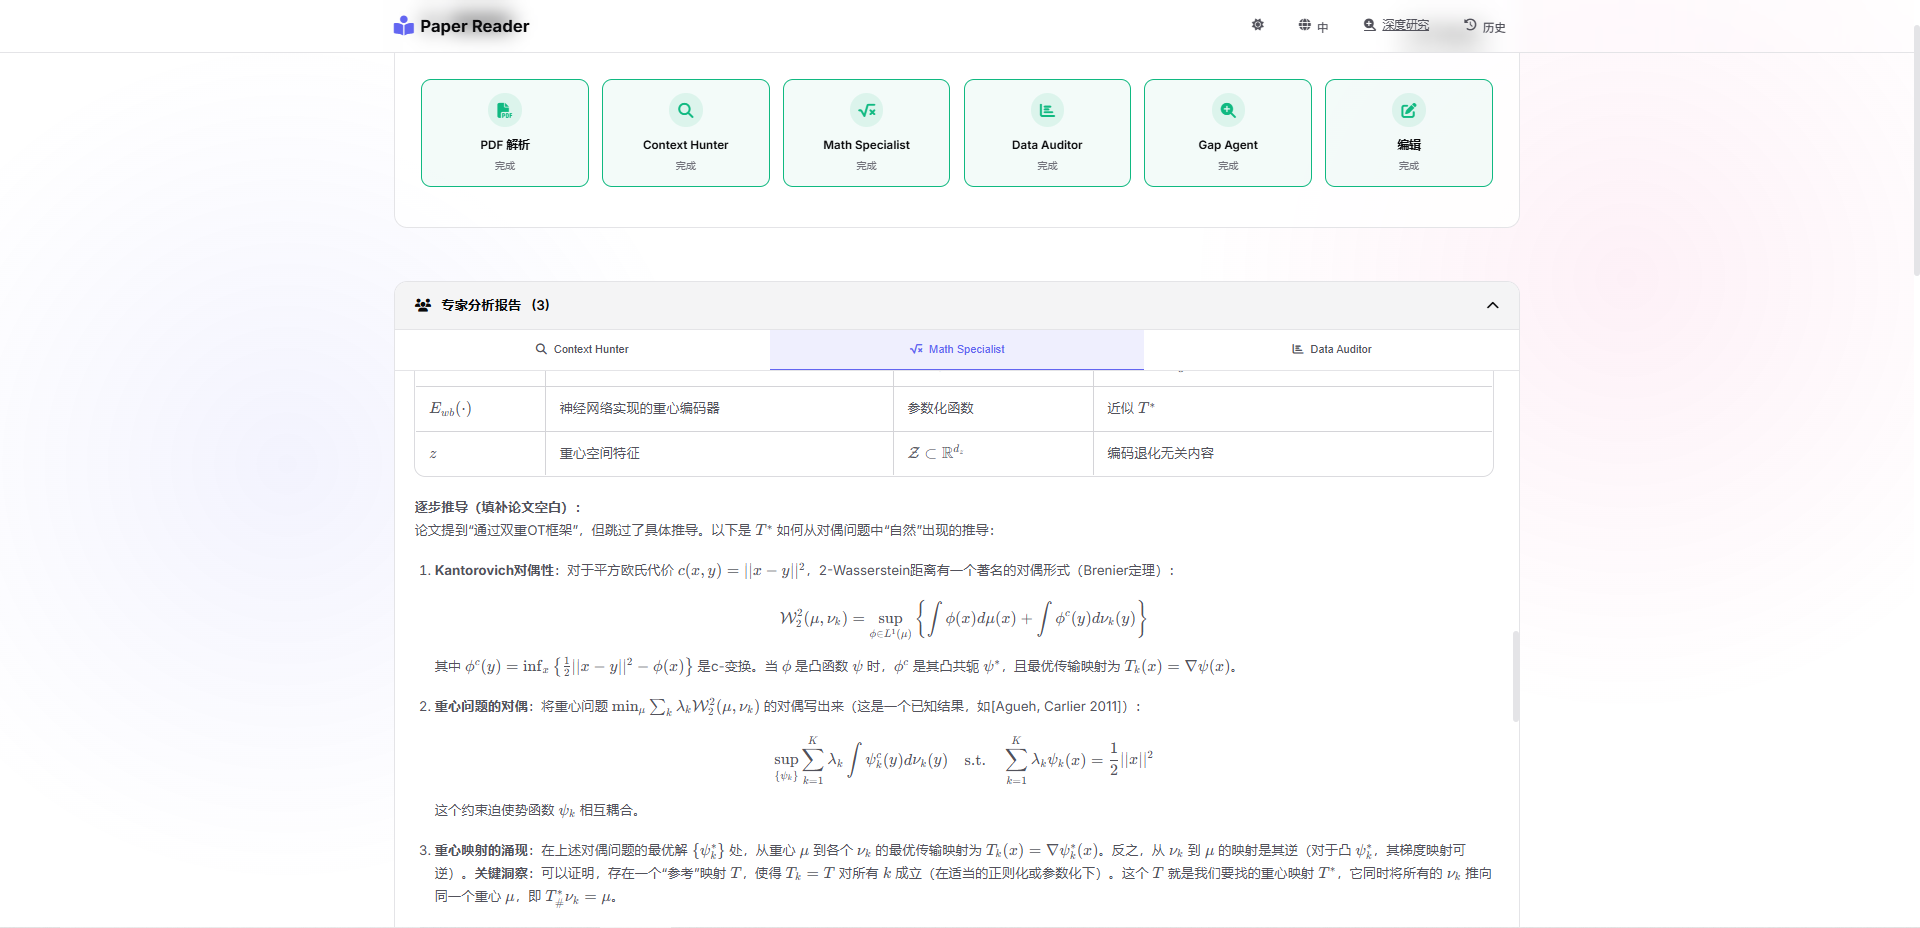 |
| Auto-embedded figures & formulas | Rich details from specific domains |
Deep Research
| Independent Research Page | Real-time Streaming Results |
|---|---|
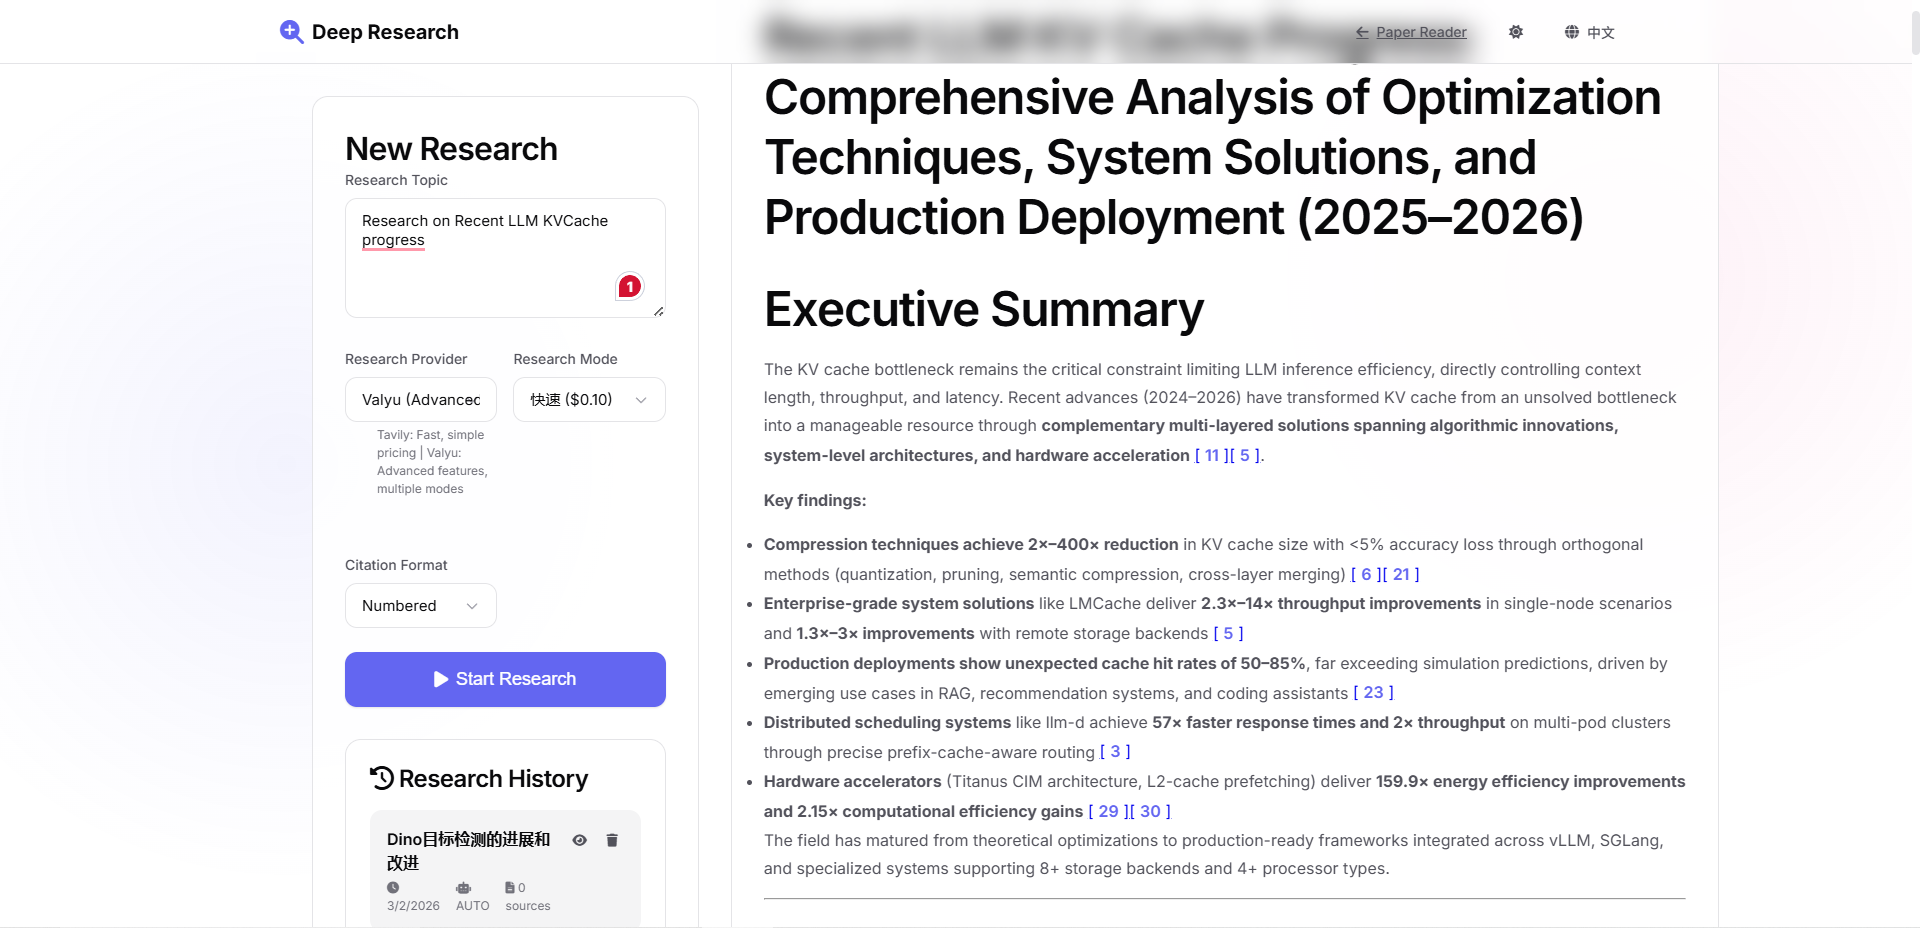 | 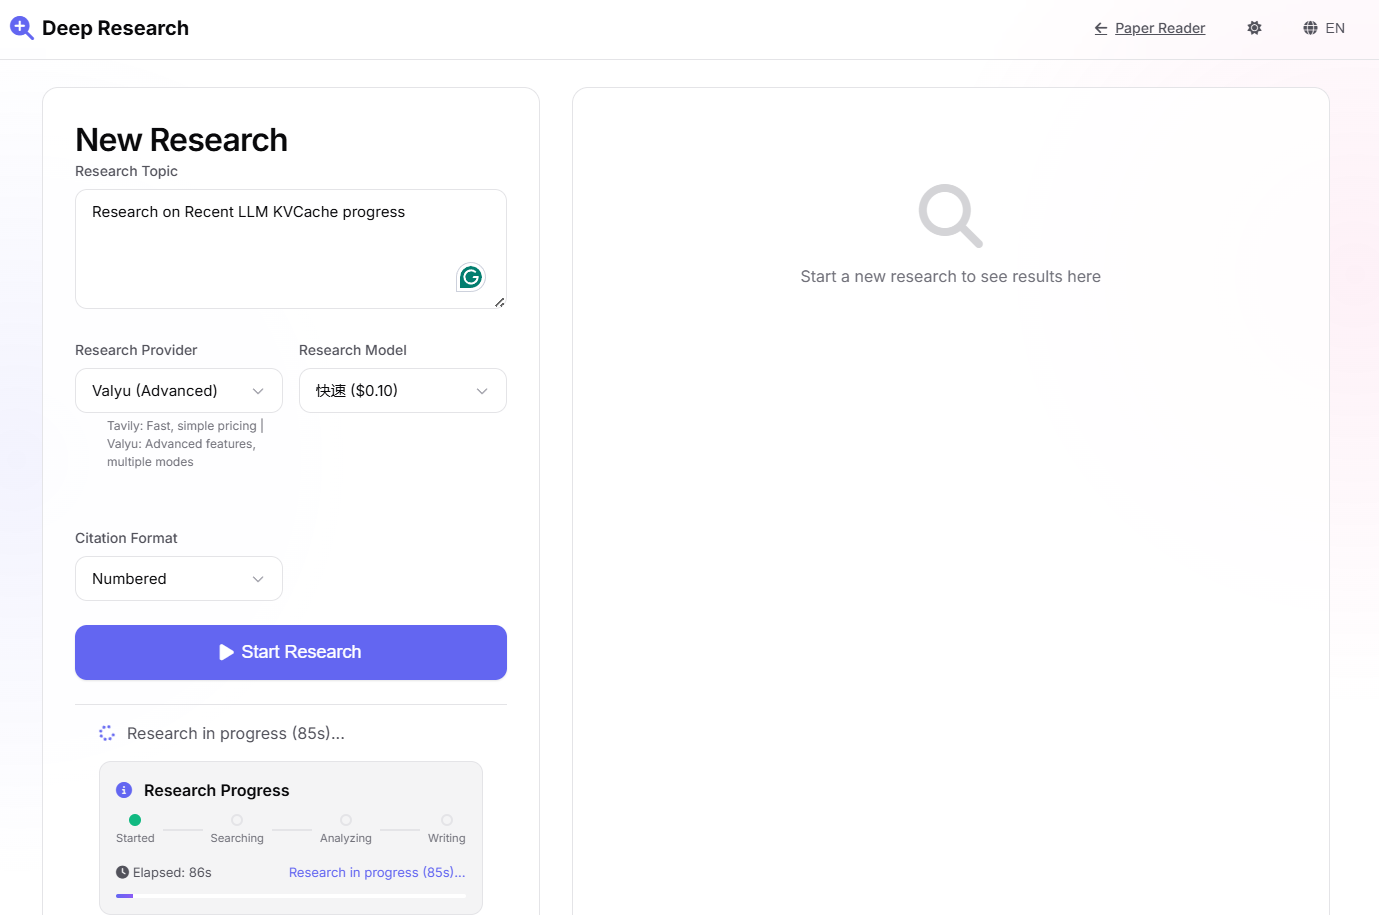 |
| Clean, focused research interface | Live streaming with progress tracking |
| Research Dashboard |
|---|
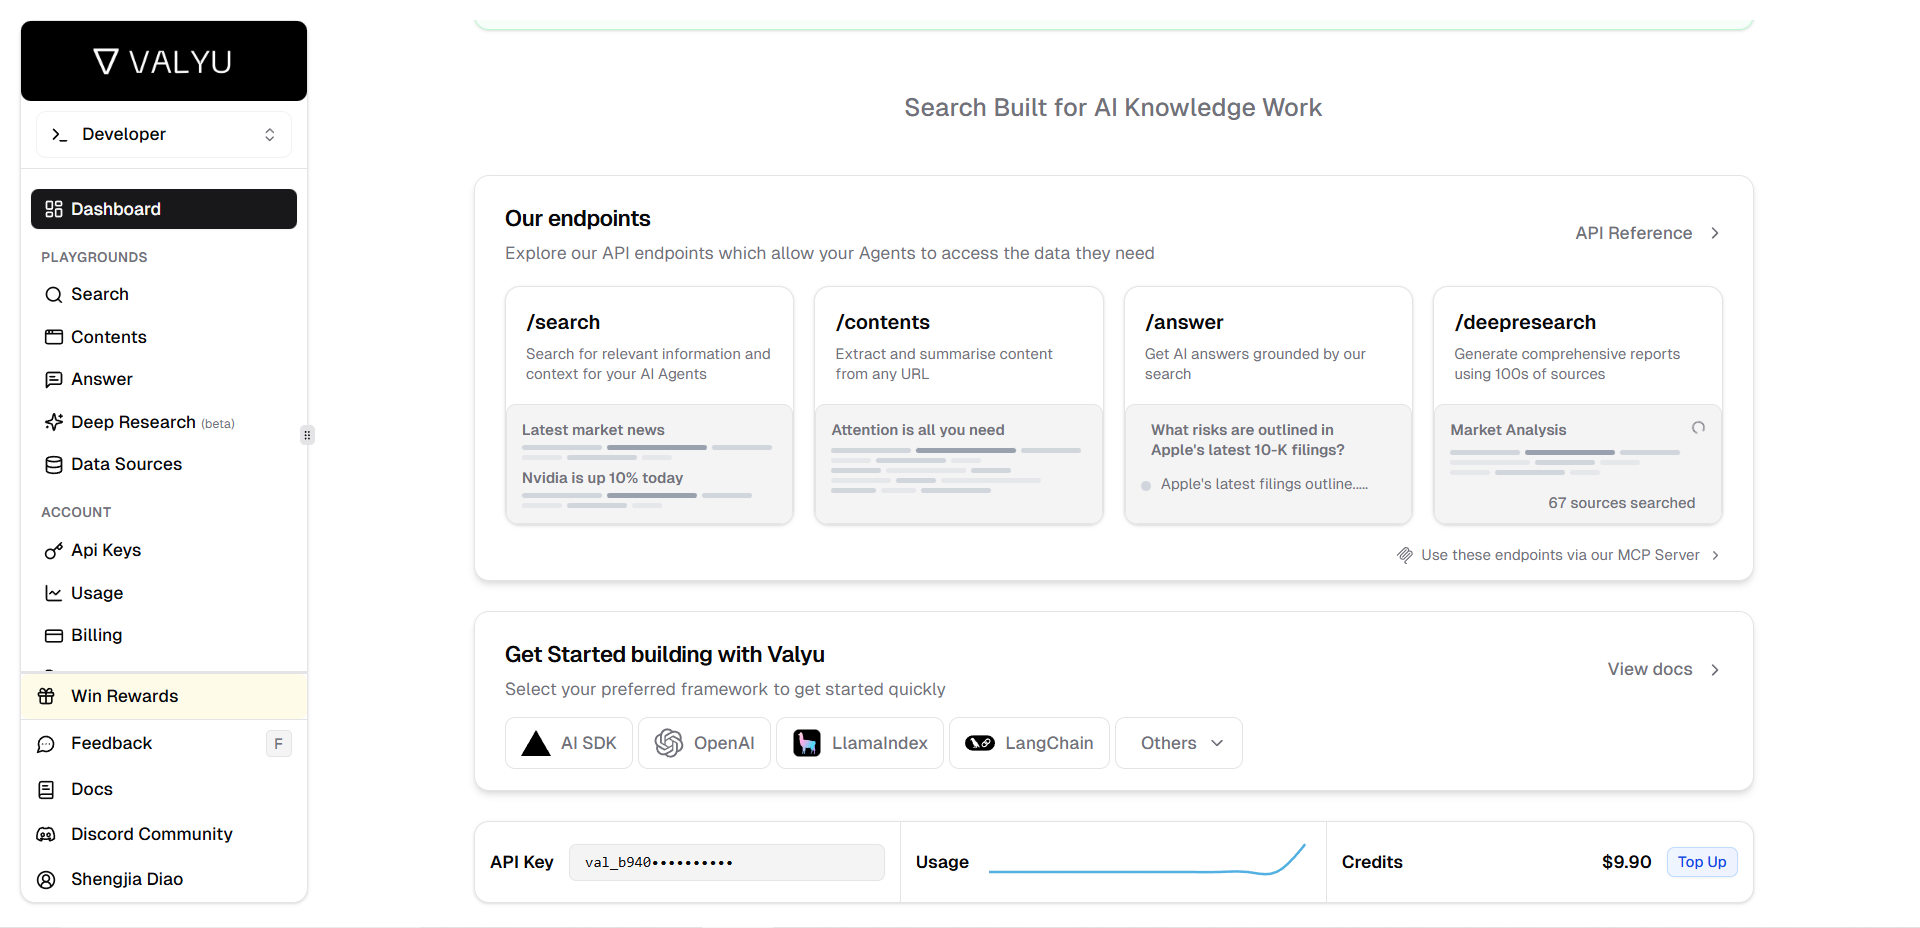 |
| Manage research history, export to Notion |
Paper Reader Agent goes beyond simple summarization...
Unlike standard summary tools, it employs a Hierarchical Multi-Agent Architecture (1+3+1) to mimic a professional research team:
- Architect: Deconstructs the paper and plans the reading strategy.
- Specialist Team: Parallel experts analyze Context, Math, and Data.
- Editor: Synthesizes a publication-quality report with embedded figures.
Key Feature: The system detects, extracts, and literally sees figures, embedding them directly into the analysis where they are discussed, maintaining full visual context.
🏗️ Architecture
The system operates using a "Divide and Conquer" strategy orchestrated by a central planner.
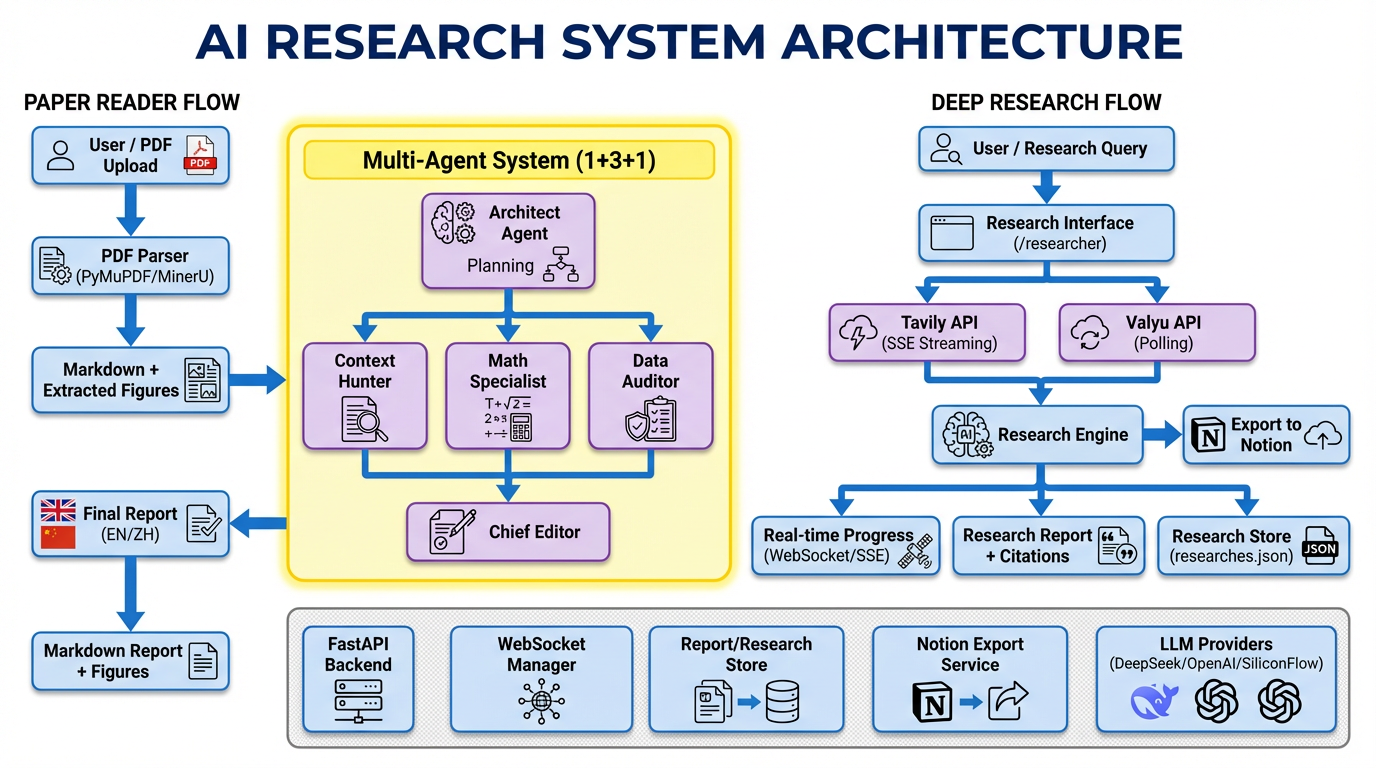
✨ Key Features
🧠 Paper Reader - Hierarchical Intelligence
- Architect Agent: Strategic planning of what to read and where to focus.
- Context Hunter: Digs for the "real" motivation and hidden assumptions.
- Math Specialist: Derives equations and explains physical intuition behind formulas.
- Data Auditor: Critically checks baselines, variance, and experimental fairness.
👁️ Paper Reader - Visual Understanding
- Smart Extraction: Custom PDF parsing pipeline (based on PyMuPDF) that segments text and images.
- Context Preservation: Figures are kept with their relevant text.
- Auto-Embedding: The AI inserts figures into the report exactly when discussing them.
🌐 Deep Research - Web-Powered Research
- Dual Provider Support: Choose between Tavily (fast, reliable) and Valyu (comprehensive, multi-tier).
- Real-time Streaming: Watch research progress live with SSE streaming technology.
- Citation Management: Multiple citation formats (Numbered, APA, MLA, Chicago).
- Research History: Persistent storage with browse, search, and delete capabilities.
- Export to Notion: One-click export with full formatting, tables, and LaTeX equations.
💻 Modern Interaction
- Web Interface: Clean, responsive UI with real-time analysis progress.
- Dual-Mode:
Simple: Quick architect + math check.Hierarchical: Full 5-agent deep dive.
- Bilingual: Generates native-quality English and Chinese reports simultaneously.
- Independent Research Page: Dedicated
/researcherpage for Deep Research with isolated history.
🚀 Quick Start
Prerequisites
- Python 3.8+
- API Key (DeepSeek or OpenAI)
- (Optional) CUDA GPU for faster layout analysis
Installation
git clone https://github.com/GoDiao/Paper-Reader.git
cd Paper-Reader
python -m venv .venv

# macOS / Linux
source .venv/bin/activate
# Windows (PowerShell)
.venv\Scripts\Activate.ps1

pip install -r requirements.txt
Optional dependencies:
# PDF export (Windows needs extra system dependencies; see weasyprint docs)
pip install weasyprint
Configuration
Copy the env template and fill in your keys (do not commit .env):
# macOS / Linux
cp .env.example .env

# Windows (PowerShell)
Copy-Item .env.example .env
Minimal .env (Paper Reader):
DEEPSEEK_API_KEY=sk-your-key
# OR
OPENAI_API_KEY=sk-your-key
Deep Research Configuration (add to .env):
# Tavily API (required for Deep Research)
TAVILY_API_KEY=tvly-your_api_key_here

# Valyu API (alternative provider for Deep Research)
VALYU_API_KEY=your_valyu_api_key_here

# Notion Export (optional)
NOTION_SECRET=your_notion_secret
NOTION_PARENT_PAGE_ID=your_parent_page_id
IMGBB_API_KEY=your_imgbb_api_key
Optional settings (web search enrichment + extra providers):
SILICONFLOW_API_KEY=your_siliconflow_api_key_here
ENABLE_WEB_SEARCH=false
GITHUB_TOKEN=your_github_token_here
HUGGINGFACE_TOKEN=your_huggingface_token_here
SERPER_API_KEY=your_serper_api_key_here
Usage
1. Web Interface (Recommended)
Start the server to enjoy the full interactive experience.
python web_server.py
Open http://localhost:8000 in your browser for Paper Reader, or visit http://localhost:8000/researcher for Deep Research.
Note (Simple mode in Web UI)
TheSimplemode in the web UI is currently a placeholder and returns a brief message. UseHierarchicalmode for full reports.
Note (Parser Backend in Web Mode)
The web server currently uses theautostrategy by default:
- If MinerU (
pip install mineru) is installed, it will try the MinerU backend first.- If MinerU is not installed or fails, it will automatically fall back to the PyMuPDF backend.
2. Deep Research - Web Interface
Access the dedicated Deep Research page at http://localhost:8000/researcher:
- Enter your research topic or question
- Select provider (Tavily or Valyu)
- Choose model and citation format
- Click "Start Research" and watch real-time streaming
- Save, export to Notion, or manage history
Deep Research Features:
- ✅ Real-time SSE streaming with progress tracking
- ✅ Markdown rendering with tables and LaTeX equations
- ✅ Persistent research history with search and delete
- ✅ One-click export to Notion with full formatting
3. Command Line
# Full hierarchical analysis (Default, auto parser backend)
python main.py paper.pdf

# Force fast PyMuPDF backend
python main.py paper.pdf --parser pymupdf

# Force high-fidelity MinerU backend (requires: pip install mineru)
python main.py paper.pdf --parser mineru

# Save intermediate agent outputs
python main.py paper.pdf --verbose

# Use OpenAI instead of DeepSeek
python main.py paper.pdf --provider openai --model gpt-4o

# Output Chinese only (can reduce cost)
python main.py paper.pdf --language zh
Note: Deep Research is currently only available through the web interface (
/researcher). CLI support is planned for future releases.
PDF Parsers: PyMuPDF vs MinerU
-
PyMuPDF (Default, Fast)
- No extra dependencies beyond
pymupdf. - Very fast, good enough for most standard papers.
- Enhanced in this project with table extraction, math-region heuristics, and smarter figure detection.
- No extra dependencies beyond
-
MinerU (Optional, High-Fidelity)
- Install via
pip install mineru(and follow MinerU's own docs for GPU/driver requirements). - Better at preserving complex layouts, multi-column structure, tables, and math-heavy pages.
- When used, this project normalizes MinerU's Markdown + images into the same
ParsedDocumentformat as PyMuPDF, so downstream agents and UI work identically.
- Install via
Repository Note
This project supportspip install mineruas an optional parsing backend; MinerU manages its own model cache (usually under your user/cache directory).
This repository also contains the upstreamMinerU/source tree (licensed under AGPL-3.0). If you want a permissive license for your app code, avoid shipping MinerU source in the same repo.
📂 Output Structure
Paper Reader (Web mode: python web_server.py)
outputs/
└── {upload_id}/
    ├── paper_analysis.md
    ├── paper_analysis_zh.md
    ├── images/
    ├── specialists/
    └── figure_index.json

data/
└── reports.json
Paper Reader (CLI mode: python main.py ...)
output/
└── {pdf_stem}/
    ├── paper_analysis.md
    ├── paper_analysis_zh.md
    ├── images/
    ├── parsed/
    ├── specialists/
    └── figure_index.json
Deep Research (Web mode: /researcher)
data/
└── researches.json  # Independent research history storage
Research results are stored separately from paper analysis reports and include:
- Full Markdown content with tables and LaTeX equations
- Source list with titles, URLs, and favicons
- Model and citation format metadata
- Creation and update timestamps
🛠️ Project Structure
paper_reader/
├── agents/                 # 🤖 The Brains
│   ├── hierarchical_orchestrator.py
│   ├── hierarchical_prompts.py
│   └── ...
├── parsers/                # 👁️ The Eyes
│   └── pdf_parser.py       # Custom Layout Analysis
├── generators/             # 📝 The Scribe
│   └── report_generator.py # Report Assembly
├── backend/                # 🔌 API Server
│   ├── app.py              # Main FastAPI application
│   ├── research_store.py   # Deep Research storage
│   ├── deep_research_utils.py  # Deep Research utilities
│   └── ...
├── frontend/               # 🖥️ Web UI
│   ├── index.html          # Paper Reader UI
│   └── researcher.html     # Deep Research UI (Independent page)
├── services/               # 🌐 External Services
│   ├── tavily_service.py   # Tavily Deep Research API wrapper
│   ├── valyu_service.py    # Valyu Deep Research API wrapper
│   └── ...
└── deep_research/          # 📚 Documentation
    ├── tavily/             # Tavily API documentation
    └── valyu/              # Valyu API documentation
🚀 Changelog
v2.0.0 - Deep Research Integration
🎉 Major Addition: Deep Research - AI-Powered Web Research Tool
-
🌐 Deep Research Feature:
- Independent research page at
/researcherwith dedicated UI - Dual provider support: Tavily (fast, reliable) and Valyu (comprehensive, multi-tier)
- Real-time SSE streaming with live progress tracking
- Multiple citation formats: Numbered, APA, MLA, Chicago
- Persistent research history with search and delete
- One-click export to Notion with full formatting
- Independent research page at
-
🔧 Backend Infrastructure:
ResearchStorefor independent research storageTavilyServiceandValyuServicewrappers- Unified polling and progress tracking
- Structured error handling with code/details
-
🖥️ Frontend Features:
- Dedicated
researcher.htmlpage with modern glassmorphism design - Real-time Markdown rendering with tables and LaTeX equations
- Research history panel with isolated storage
- Export to Notion with native tables and equations
- Dedicated
-
📊 API Endpoints:
POST /api/deep-research- Start research via WebSocketGET /api/deep-research/stream- SSE streaming endpointGET /api/research- List research historyPOST /api/research/save- Save researchDELETE /api/research/{id}- Delete researchPOST /api/research/{id}/export/notion- Export to Notion
-
📚 Documentation:
- Comprehensive API documentation for Tavily and Valyu
- Streaming implementation guide
- Independent page design documentation
v1.7.0 - Iterative Analysis & Gap Agent
🎉 Major Announcement: Starting from v1.7.0, Paper Reader officially supports one-click export to Notion!
-
🔄 Iterative Analysis:
- Specialists can proactively raise information gaps (
<TENTATIVE_GAPS>), triggering automatic refinement cycles. - Configurable iteration rounds (
max_iterations), with each round resolving requests from the previous iteration. - New frontend iteration panel displaying request type, content, and resolution status per round.
- Specialists can proactively raise information gaps (
-
🧩 Gap Agent (Gap Analysis Specialist):
- New independent Gap Agent that reviews all three specialist reports to identify cross-domain information gaps.
- Generates global confidence score (0.0–1.0) with natural language explanation for iteration recommendations.
- Outputs standardized
unified_requestslist, auto-classified assection_needed,cross_reference,clarification, orfigure_detail.
-
📊 Frontend Enhancements:
- Gap Agent Panel: Displays per-specialist assessments (completeness, coherence, gaps found), global confidence, iteration recommendation, and request list.
- Round Tracking Fix: WebSocket events now carry correct round numbers, displaying "Round N" accurately.
- Config Display Fix:
max_iterations=0no longer incorrectly shows as "2".
-
🛠️ Backend Optimizations:
- Round Logic Fix:
max_iterations=Nnow truly executesN+1specialist rounds (initial + N refinements). - JSON Parsing Enhancement: Added
json-repairfallback to handle unescaped quotes, newlines, and other malformed JSON from LLMs. - Cache Optimization: Empty parse results (0 characters) are no longer cached to prevent pollution.
- MinerU Compatibility: Handles Magika returning
unknownfor PDF identification, improving success rate for complex PDFs.
- Round Logic Fix:
-
📦 New Dependency:
json-repair>=0.55.0: Automatically repairs malformed JSON from LLM outputs.
tonotion (tag) - Notion Export (Side Feature)
- 📝 Native Notion Export: One-click export to Notion pages with full support for:
- Native Tables: Clean, editable Notion tables (replacing image-based or LaTeX tables).
- Rich Math Support: Perfect rendering of inline ($...$) and block ($$...$$) equations.
- Nested Lists: Correct indentation for complex nested lists.
- 🖼️ Image Optimization: Improved figure resolution and caption handling during export.
- ⚡ Core Stability: Fixed edge cases in list parsing and table generation.
v1.6.0 - History, Export & Performance
- 🗂️ Report History: Persistent report store with browse/search/delete, plus reloadable specialist reports and chat history.
- 📤 One-click Export: Export reports as Markdown/DOCX, download extracted figures as a ZIP (PDF export supported via optional dependencies).
- ⚡ PDF Parse Cache: SHA256-based parse caching (parsed content + figures) to significantly speed up repeated analyses.
- 🌐 Web Search Toggle: UI switch to enable/disable reproduction resource discovery, with GitHub/HuggingFace token support.
- 🤝 Provider Expansion: Added SiliconFlow provider support in the web UI with concurrency tuning to reduce rate-limit errors.
- 🈯 Output Language Control: Choose EN or ZH output to reduce cost and avoid empty report tabs.
v1.5.0 - UI Modernization & Resource Discovery
- 🎨 Modern UI Overhaul: Complete redesign with a new Zinc-based dark theme, high-contrast tables for better readability, and refined typography.
- 🔍 Resource Discovery Services: Integrated automated search for reproduction resources (GitHub code repositories, HuggingFace models/datasets) directly into the analysis pipeline.
- 📋 Reproduction Checklist: New dedicated section to extract and verify hardware requirements, hyperparameters, and datasets.
- 📉 Variable Tracking: Added support for tracking mathematical variables and their definitions across the paper.
- ⚡ UX Refinements: Streamlined the agent progress view by removing the redundant Architect tab, focusing on the specialist analysis.
v1.3.0 - MinerU Parsing Upgrade
- 🧠 MinerU Parser Backend: Integrated MinerU (Magic-PDF 2.x pipeline) as a high-fidelity PDF parser for complex academic papers, with better layout, table, and math structure preservation.
- ⚙️ Switchable PDF Backend: Added a selectable parser backend in CLI (
--parser auto|pymupdf|mineru) and web mode, so you can choose fast PyMuPDF, high-quality MinerU, or anautostrategy that tries MinerU first and falls back to PyMuPDF if unavailable or failing. - 📂 Unified Output Pipeline: Normalized MinerU outputs into the existing
ParsedDocument+ figure index flow so that downstream LLM agents, report generation, and UI work seamlessly regardless of which parser backend you choose.
v1.2.0 - Architecture & Performance Improvements
- 🔧 Unified LLM Client Factory: Centralized LLM configuration, retry/backoff, and timeout handling across all agents. Added optional global concurrency limiting to prevent API rate limits.
- 📊 Fine-grained Progress Events: Real-time progress updates for each agent (Architect, Context Hunter, Math Specialist, Data Auditor, Editors) with detailed status messages during LLM calls and retries.
- ⚡ Concurrency Optimization: Eliminated nested thread pools, unified executor management, and improved resource utilization for better performance under concurrent loads.
- 📄 Enhanced PDF Parser: Improved PyMuPDF implementation with table extraction (Markdown format), mathematical formula region detection, better text structure preservation, and smarter image caption detection (searches above/below images).
- 🔧 Configuration: New environment variables (
LLM_TIMEOUT_S,LLM_MAX_RETRIES,LLM_MAX_CONCURRENCY) for fine-tuning API behavior. - 📡 Real-time Streaming: Implemented streaming responses for expert agents (Math, Data, Context), allowing users to see reports generating token-by-token.
- 📐 Math Formula Fix: Solved critical rendering issues for streamed LaTeX formulas by protecting delimiters (
\[...\],\(...\)) from Markdown processing. - 🏗️ Architect Report: Added a new dedicated "Architect" tab to visualize the reading plan and agent assignments immediately after the planning phase.
- 🖥️ UI UX Improvements: Moved Specialist Reports to the main view for better visibility and added auto-focus logic to follow the active agent.
v1.1.0 - Premium UI & Chat Upgrade
- ✨ New UI: Introduced a "Deep Space" glassmorphism theme for a premium reading experience.
- 🤖 Smart Chat: Added context summarization to the Chat AI, allowing for longer, more coherent discussions about the paper.
- 📊 Specialist Reports: View detailed analysis from specific agents (Context Hunter, Math Specialist, Data Auditor) in dedicated tabs.
- 🌐 Bilingual: Added full English/Chinese language switching.
- 🐛 Fixes: Resolved table rendering issues and improved chat interface scrolling.
📄 Documentation
For detailed information about Deep Research features:
- Deep Research Overview - Complete guide to Deep Research features
- Tavily API Documentation - Tavily provider usage guide
- Valyu API Documentation - Valyu provider usage guide
- Streaming Implementation - SSE streaming technical details
🤝 Contributing
Contributions are welcome! Whether it's a new specialist agent, better parsing logic, or UI improvements.
- Fork the Project
- Create your Feature Branch
- Commit your Changes
- Push to the Branch
- Open a Pull Request
📄 License
This repository includes MinerU/ (AGPL-3.0), so redistribution must follow AGPL-3.0. See LICENSE.md.
Contributors

38 commits
Similar repos


Languages
Python
86.9%
HTML
6.1%
JavaScript
4.3%
CSS
2.0%
An AI-powered academic paper analysis system with hierarchical multi-agent architecture and interactive web interface.
Python
5
38 commits
updated Mar 14, 2026
README
Paper Reader Agent
Hierarchical Multi-Agent System for Academic Paper Deep Analysis & AI-Powered Web Research
中文文档 | English
Quick Links: Paper Reader | Deep Research | Documentation
📖 Introduction
Paper Reader Agent is an advanced AI system designed to read, analyze, and synthesize academic papers with a depth that matches human researchers.
Deep Research is a powerful AI-powered web research tool that leverages Tavily and Valyu APIs to conduct comprehensive, real-time research on any topic, generating detailed reports with citations from online sources.
Together, they form a complete research workflow: Paper Reader for deep paper analysis, and Deep Research for broad topic exploration.
📸 Click to see Screenshots (UI & Features)
Paper Reader
| Modern Web UI (Bilingual) | Real-time Progress Tracking |
|---|---|
| |
| Clean interface with EN/ZH switching | Visualize the 5-agent team in action |
| Publication-Quality Reports | Specialist Deep Dives |
|---|---|
| |
| Auto-embedded figures & formulas | Rich details from specific domains |
Deep Research
| Independent Research Page | Real-time Streaming Results |
|---|---|
| |
| Clean, focused research interface | Live streaming with progress tracking |
| Research Dashboard |
|---|
|
| Manage research history, export to Notion |
Paper Reader Agent goes beyond simple summarization...
Unlike standard summary tools, it employs a Hierarchical Multi-Agent Architecture (1+3+1) to mimic a professional research team:
- Architect: Deconstructs the paper and plans the reading strategy.
- Specialist Team: Parallel experts analyze Context, Math, and Data.
- Editor: Synthesizes a publication-quality report with embedded figures.
Key Feature: The system detects, extracts, and literally sees figures, embedding them directly into the analysis where they are discussed, maintaining full visual context.
🏗️ Architecture
The system operates using a "Divide and Conquer" strategy orchestrated by a central planner.
✨ Key Features
🧠 Paper Reader - Hierarchical Intelligence
- Architect Agent: Strategic planning of what to read and where to focus.
- Context Hunter: Digs for the "real" motivation and hidden assumptions.
- Math Specialist: Derives equations and explains physical intuition behind formulas.
- Data Auditor: Critically checks baselines, variance, and experimental fairness.
👁️ Paper Reader - Visual Understanding
- Smart Extraction: Custom PDF parsing pipeline (based on PyMuPDF) that segments text and images.
- Context Preservation: Figures are kept with their relevant text.
- Auto-Embedding: The AI inserts figures into the report exactly when discussing them.
🌐 Deep Research - Web-Powered Research
- Dual Provider Support: Choose between Tavily (fast, reliable) and Valyu (comprehensive, multi-tier).
- Real-time Streaming: Watch research progress live with SSE streaming technology.
- Citation Management: Multiple citation formats (Numbered, APA, MLA, Chicago).
- Research History: Persistent storage with browse, search, and delete capabilities.
- Export to Notion: One-click export with full formatting, tables, and LaTeX equations.
💻 Modern Interaction
- Web Interface: Clean, responsive UI with real-time analysis progress.
- Dual-Mode:
Simple: Quick architect + math check.Hierarchical: Full 5-agent deep dive.
- Bilingual: Generates native-quality English and Chinese reports simultaneously.
- Independent Research Page: Dedicated
/researcherpage for Deep Research with isolated history.
🚀 Quick Start
Prerequisites
- Python 3.8+
- API Key (DeepSeek or OpenAI)
- (Optional) CUDA GPU for faster layout analysis
Installation
git clone https://github.com/GoDiao/Paper-Reader.git
cd Paper-Reader
python -m venv .venv

# macOS / Linux
source .venv/bin/activate
# Windows (PowerShell)
.venv\Scripts\Activate.ps1

pip install -r requirements.txt
Optional dependencies:
# PDF export (Windows needs extra system dependencies; see weasyprint docs)
pip install weasyprint
Configuration
Copy the env template and fill in your keys (do not commit .env):
# macOS / Linux
cp .env.example .env

# Windows (PowerShell)
Copy-Item .env.example .env
Minimal .env (Paper Reader):
DEEPSEEK_API_KEY=sk-your-key
# OR
OPENAI_API_KEY=sk-your-key
Deep Research Configuration (add to .env):
# Tavily API (required for Deep Research)
TAVILY_API_KEY=tvly-your_api_key_here

# Valyu API (alternative provider for Deep Research)
VALYU_API_KEY=your_valyu_api_key_here

# Notion Export (optional)
NOTION_SECRET=your_notion_secret
NOTION_PARENT_PAGE_ID=your_parent_page_id
IMGBB_API_KEY=your_imgbb_api_key
Optional settings (web search enrichment + extra providers):
SILICONFLOW_API_KEY=your_siliconflow_api_key_here
ENABLE_WEB_SEARCH=false
GITHUB_TOKEN=your_github_token_here
HUGGINGFACE_TOKEN=your_huggingface_token_here
SERPER_API_KEY=your_serper_api_key_here
Usage
1. Web Interface (Recommended)
Start the server to enjoy the full interactive experience.
python web_server.py
Open http://localhost:8000 in your browser for Paper Reader, or visit http://localhost:8000/researcher for Deep Research.
Note (Simple mode in Web UI)
TheSimplemode in the web UI is currently a placeholder and returns a brief message. UseHierarchicalmode for full reports.
Note (Parser Backend in Web Mode)
The web server currently uses theautostrategy by default:
- If MinerU (
pip install mineru) is installed, it will try the MinerU backend first.- If MinerU is not installed or fails, it will automatically fall back to the PyMuPDF backend.
2. Deep Research - Web Interface
Access the dedicated Deep Research page at http://localhost:8000/researcher:
- Enter your research topic or question
- Select provider (Tavily or Valyu)
- Choose model and citation format
- Click "Start Research" and watch real-time streaming
- Save, export to Notion, or manage history
Deep Research Features:
- ✅ Real-time SSE streaming with progress tracking
- ✅ Markdown rendering with tables and LaTeX equations
- ✅ Persistent research history with search and delete
- ✅ One-click export to Notion with full formatting
3. Command Line
# Full hierarchical analysis (Default, auto parser backend)
python main.py paper.pdf

# Force fast PyMuPDF backend
python main.py paper.pdf --parser pymupdf

# Force high-fidelity MinerU backend (requires: pip install mineru)
python main.py paper.pdf --parser mineru

# Save intermediate agent outputs
python main.py paper.pdf --verbose

# Use OpenAI instead of DeepSeek
python main.py paper.pdf --provider openai --model gpt-4o

# Output Chinese only (can reduce cost)
python main.py paper.pdf --language zh
Note: Deep Research is currently only available through the web interface (
/researcher). CLI support is planned for future releases.
PDF Parsers: PyMuPDF vs MinerU
-
PyMuPDF (Default, Fast)
- No extra dependencies beyond
pymupdf. - Very fast, good enough for most standard papers.
- Enhanced in this project with table extraction, math-region heuristics, and smarter figure detection.
- No extra dependencies beyond
-
MinerU (Optional, High-Fidelity)
- Install via
pip install mineru(and follow MinerU's own docs for GPU/driver requirements). - Better at preserving complex layouts, multi-column structure, tables, and math-heavy pages.
- When used, this project normalizes MinerU's Markdown + images into the same
ParsedDocumentformat as PyMuPDF, so downstream agents and UI work identically.
- Install via
Repository Note
This project supportspip install mineruas an optional parsing backend; MinerU manages its own model cache (usually under your user/cache directory).
This repository also contains the upstreamMinerU/source tree (licensed under AGPL-3.0). If you want a permissive license for your app code, avoid shipping MinerU source in the same repo.
📂 Output Structure
Paper Reader (Web mode: python web_server.py)
outputs/
└── {upload_id}/
    ├── paper_analysis.md
    ├── paper_analysis_zh.md
    ├── images/
    ├── specialists/
    └── figure_index.json

data/
└── reports.json
Paper Reader (CLI mode: python main.py ...)
output/
└── {pdf_stem}/
    ├── paper_analysis.md
    ├── paper_analysis_zh.md
    ├── images/
    ├── parsed/
    ├── specialists/
    └── figure_index.json
Deep Research (Web mode: /researcher)
data/
└── researches.json  # Independent research history storage
Research results are stored separately from paper analysis reports and include:
- Full Markdown content with tables and LaTeX equations
- Source list with titles, URLs, and favicons
- Model and citation format metadata
- Creation and update timestamps
🛠️ Project Structure
paper_reader/
├── agents/                 # 🤖 The Brains
│   ├── hierarchical_orchestrator.py
│   ├── hierarchical_prompts.py
│   └── ...
├── parsers/                # 👁️ The Eyes
│   └── pdf_parser.py       # Custom Layout Analysis
├── generators/             # 📝 The Scribe
│   └── report_generator.py # Report Assembly
├── backend/                # 🔌 API Server
│   ├── app.py              # Main FastAPI application
│   ├── research_store.py   # Deep Research storage
│   ├── deep_research_utils.py  # Deep Research utilities
│   └── ...
├── frontend/               # 🖥️ Web UI
│   ├── index.html          # Paper Reader UI
│   └── researcher.html     # Deep Research UI (Independent page)
├── services/               # 🌐 External Services
│   ├── tavily_service.py   # Tavily Deep Research API wrapper
│   ├── valyu_service.py    # Valyu Deep Research API wrapper
│   └── ...
└── deep_research/          # 📚 Documentation
    ├── tavily/             # Tavily API documentation
    └── valyu/              # Valyu API documentation
🚀 Changelog
v2.0.0 - Deep Research Integration
🎉 Major Addition: Deep Research - AI-Powered Web Research Tool
-
🌐 Deep Research Feature:
- Independent research page at
/researcherwith dedicated UI - Dual provider support: Tavily (fast, reliable) and Valyu (comprehensive, multi-tier)
- Real-time SSE streaming with live progress tracking
- Multiple citation formats: Numbered, APA, MLA, Chicago
- Persistent research history with search and delete
- One-click export to Notion with full formatting
- Independent research page at
-
🔧 Backend Infrastructure:
ResearchStorefor independent research storageTavilyServiceandValyuServicewrappers- Unified polling and progress tracking
- Structured error handling with code/details
-
🖥️ Frontend Features:
- Dedicated
researcher.htmlpage with modern glassmorphism design - Real-time Markdown rendering with tables and LaTeX equations
- Research history panel with isolated storage
- Export to Notion with native tables and equations
- Dedicated
-
📊 API Endpoints:
POST /api/deep-research- Start research via WebSocketGET /api/deep-research/stream- SSE streaming endpointGET /api/research- List research historyPOST /api/research/save- Save researchDELETE /api/research/{id}- Delete researchPOST /api/research/{id}/export/notion- Export to Notion
-
📚 Documentation:
- Comprehensive API documentation for Tavily and Valyu
- Streaming implementation guide
- Independent page design documentation
v1.7.0 - Iterative Analysis & Gap Agent
🎉 Major Announcement: Starting from v1.7.0, Paper Reader officially supports one-click export to Notion!
-
🔄 Iterative Analysis:
- Specialists can proactively raise information gaps (
<TENTATIVE_GAPS>), triggering automatic refinement cycles. - Configurable iteration rounds (
max_iterations), with each round resolving requests from the previous iteration. - New frontend iteration panel displaying request type, content, and resolution status per round.
- Specialists can proactively raise information gaps (
-
🧩 Gap Agent (Gap Analysis Specialist):
- New independent Gap Agent that reviews all three specialist reports to identify cross-domain information gaps.
- Generates global confidence score (0.0–1.0) with natural language explanation for iteration recommendations.
- Outputs standardized
unified_requestslist, auto-classified assection_needed,cross_reference,clarification, orfigure_detail.
-
📊 Frontend Enhancements:
- Gap Agent Panel: Displays per-specialist assessments (completeness, coherence, gaps found), global confidence, iteration recommendation, and request list.
- Round Tracking Fix: WebSocket events now carry correct round numbers, displaying "Round N" accurately.
- Config Display Fix:
max_iterations=0no longer incorrectly shows as "2".
-
🛠️ Backend Optimizations:
- Round Logic Fix:
max_iterations=Nnow truly executesN+1specialist rounds (initial + N refinements). - JSON Parsing Enhancement: Added
json-repairfallback to handle unescaped quotes, newlines, and other malformed JSON from LLMs. - Cache Optimization: Empty parse results (0 characters) are no longer cached to prevent pollution.
- MinerU Compatibility: Handles Magika returning
unknownfor PDF identification, improving success rate for complex PDFs.
- Round Logic Fix:
-
📦 New Dependency:
json-repair>=0.55.0: Automatically repairs malformed JSON from LLM outputs.
tonotion (tag) - Notion Export (Side Feature)
- 📝 Native Notion Export: One-click export to Notion pages with full support for:
- Native Tables: Clean, editable Notion tables (replacing image-based or LaTeX tables).
- Rich Math Support: Perfect rendering of inline ($...$) and block ($$...$$) equations.
- Nested Lists: Correct indentation for complex nested lists.
- 🖼️ Image Optimization: Improved figure resolution and caption handling during export.
- ⚡ Core Stability: Fixed edge cases in list parsing and table generation.
v1.6.0 - History, Export & Performance
- 🗂️ Report History: Persistent report store with browse/search/delete, plus reloadable specialist reports and chat history.
- 📤 One-click Export: Export reports as Markdown/DOCX, download extracted figures as a ZIP (PDF export supported via optional dependencies).
- ⚡ PDF Parse Cache: SHA256-based parse caching (parsed content + figures) to significantly speed up repeated analyses.
- 🌐 Web Search Toggle: UI switch to enable/disable reproduction resource discovery, with GitHub/HuggingFace token support.
- 🤝 Provider Expansion: Added SiliconFlow provider support in the web UI with concurrency tuning to reduce rate-limit errors.
- 🈯 Output Language Control: Choose EN or ZH output to reduce cost and avoid empty report tabs.
v1.5.0 - UI Modernization & Resource Discovery
- 🎨 Modern UI Overhaul: Complete redesign with a new Zinc-based dark theme, high-contrast tables for better readability, and refined typography.
- 🔍 Resource Discovery Services: Integrated automated search for reproduction resources (GitHub code repositories, HuggingFace models/datasets) directly into the analysis pipeline.
- 📋 Reproduction Checklist: New dedicated section to extract and verify hardware requirements, hyperparameters, and datasets.
- 📉 Variable Tracking: Added support for tracking mathematical variables and their definitions across the paper.
- ⚡ UX Refinements: Streamlined the agent progress view by removing the redundant Architect tab, focusing on the specialist analysis.
v1.3.0 - MinerU Parsing Upgrade
- 🧠 MinerU Parser Backend: Integrated MinerU (Magic-PDF 2.x pipeline) as a high-fidelity PDF parser for complex academic papers, with better layout, table, and math structure preservation.
- ⚙️ Switchable PDF Backend: Added a selectable parser backend in CLI (
--parser auto|pymupdf|mineru) and web mode, so you can choose fast PyMuPDF, high-quality MinerU, or anautostrategy that tries MinerU first and falls back to PyMuPDF if unavailable or failing. - 📂 Unified Output Pipeline: Normalized MinerU outputs into the existing
ParsedDocument+ figure index flow so that downstream LLM agents, report generation, and UI work seamlessly regardless of which parser backend you choose.
v1.2.0 - Architecture & Performance Improvements
- 🔧 Unified LLM Client Factory: Centralized LLM configuration, retry/backoff, and timeout handling across all agents. Added optional global concurrency limiting to prevent API rate limits.
- 📊 Fine-grained Progress Events: Real-time progress updates for each agent (Architect, Context Hunter, Math Specialist, Data Auditor, Editors) with detailed status messages during LLM calls and retries.
- ⚡ Concurrency Optimization: Eliminated nested thread pools, unified executor management, and improved resource utilization for better performance under concurrent loads.
- 📄 Enhanced PDF Parser: Improved PyMuPDF implementation with table extraction (Markdown format), mathematical formula region detection, better text structure preservation, and smarter image caption detection (searches above/below images).
- 🔧 Configuration: New environment variables (
LLM_TIMEOUT_S,LLM_MAX_RETRIES,LLM_MAX_CONCURRENCY) for fine-tuning API behavior. - 📡 Real-time Streaming: Implemented streaming responses for expert agents (Math, Data, Context), allowing users to see reports generating token-by-token.
- 📐 Math Formula Fix: Solved critical rendering issues for streamed LaTeX formulas by protecting delimiters (
\[...\],\(...\)) from Markdown processing. - 🏗️ Architect Report: Added a new dedicated "Architect" tab to visualize the reading plan and agent assignments immediately after the planning phase.
- 🖥️ UI UX Improvements: Moved Specialist Reports to the main view for better visibility and added auto-focus logic to follow the active agent.
v1.1.0 - Premium UI & Chat Upgrade
- ✨ New UI: Introduced a "Deep Space" glassmorphism theme for a premium reading experience.
- 🤖 Smart Chat: Added context summarization to the Chat AI, allowing for longer, more coherent discussions about the paper.
- 📊 Specialist Reports: View detailed analysis from specific agents (Context Hunter, Math Specialist, Data Auditor) in dedicated tabs.
- 🌐 Bilingual: Added full English/Chinese language switching.
- 🐛 Fixes: Resolved table rendering issues and improved chat interface scrolling.
📄 Documentation
For detailed information about Deep Research features:
- Deep Research Overview - Complete guide to Deep Research features
- Tavily API Documentation - Tavily provider usage guide
- Valyu API Documentation - Valyu provider usage guide
- Streaming Implementation - SSE streaming technical details
🤝 Contributing
Contributions are welcome! Whether it's a new specialist agent, better parsing logic, or UI improvements.
- Fork the Project
- Create your Feature Branch
- Commit your Changes
- Push to the Branch
- Open a Pull Request
📄 License
This repository includes MinerU/ (AGPL-3.0), so redistribution must follow AGPL-3.0. See LICENSE.md.
Similar repos
Contributors
38 commits
Languages
Python
86.9%
HTML
6.1%
JavaScript
4.3%
CSS
2.0%