
README
English | 中文 | 🌐 Project Site
kube-llmops






🏆 The most comprehensive Kubernetes-native LLMOps Platform — One command to deploy, manage, monitor, and optimize your entire LLM infrastructure.
[!NOTE] v1.0.0 released -- the v1.0 trio is complete: Operator (LLMPlatform / ModelDeployment / FineTuneRun CRDs) + kubectl-llmops CLI (15+ commands,
kubectl llmops <cmd>) + Headlamp Dashboard (Kubernetes UI +kube-llmops-portalplugin). See CHANGELOG for details.
What is kube-llmops?
kube-llmops is an opinionated, batteries-included Helm chart that deploys a complete LLM operations stack on Kubernetes:
- Model Serving -- vLLM, llama.cpp, or TEI, auto-selected based on model format (engine auto-detection from source name)
- CLI (
kubectl-llmops) -- kubectl plugin with 15+ imperative commands:deploy,list,status,scale,canary,logs,test,port-forward,finetune,rag,platform,migrate, ... - AI Gateway -- LiteLLM for unified OpenAI-compatible API, key management, rate limiting, budget control
- Observability -- Prometheus + Grafana (11 dashboards + 8 alert rules) + Langfuse v3 LLM tracing + node-exporter + kube-state-metrics
- Logging -- Fluent Bit + Loki, queryable in Grafana Explore
- Autoscaling -- KEDA scales vLLM pods based on queue depth, TTFT P95, and TPOT P95; supports scale-to-zero with fallback
- Security -- Keycloak SSO for Grafana/Langfuse, LLM-Guard prompt injection defense, NetworkPolicy isolation
- RAG Infrastructure -- Dify platform + pgvector + TEI embedding/reranking + Ragas evaluation + quality gate
- Fine-tuning -- LLaMA-Factory LoRA/QLoRA/Full fine-tuning with Argo Workflows pipeline + MLflow tracking
- Model Distribution -- MinIO model cache + HuggingFace fallback + hf-transfer multi-threaded downloads
- Storage -- MinIO S3-compatible model storage, PVC model cache
# Install from local source (recommended)
helm install kube-llmops charts/kube-llmops-stack -f values-minimal.yaml
Use Cases
- "I want to deploy DeepSeek-R1-0528 and let 5 teams share it with token budget limits"
- "I want to see which team burned the most GPU hours this month"
- "I want a GGUF model on llama.cpp and a full-precision model on vLLM behind the same API"
- "I want every LLM request traced with full prompt, tokens, cost, and latency"
Architecture
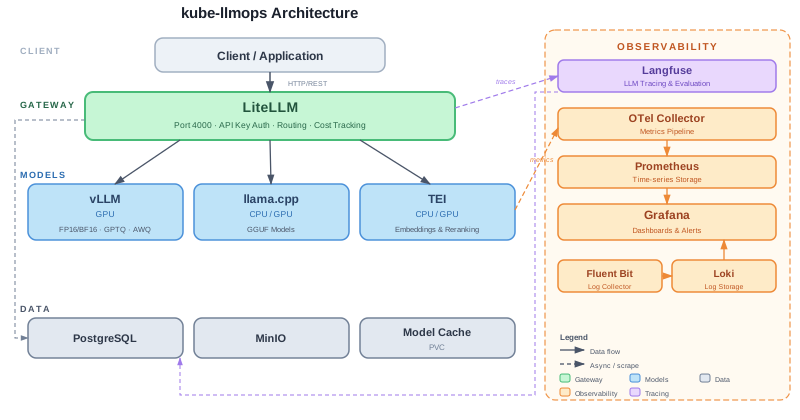
See ARCHITECTURE.md for the full technical design.
Screenshots
API Demo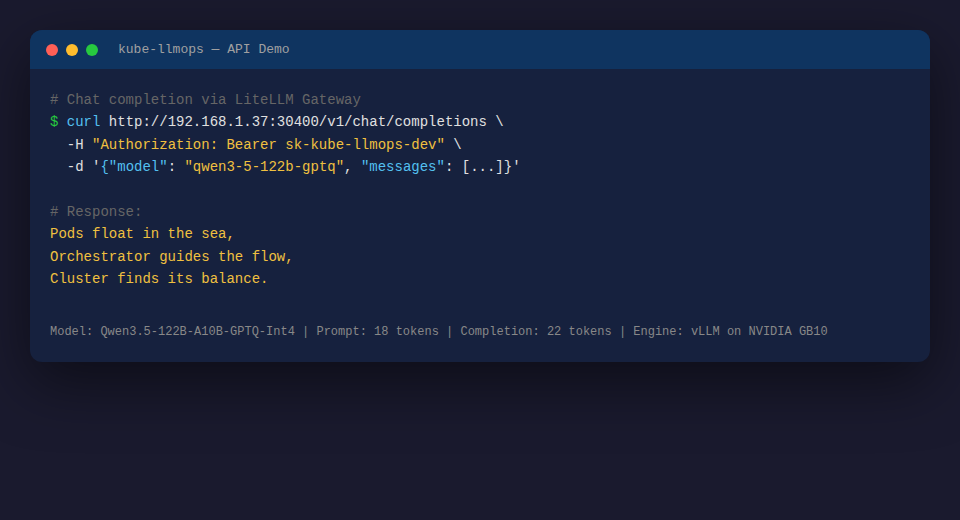 | Grafana Dashboards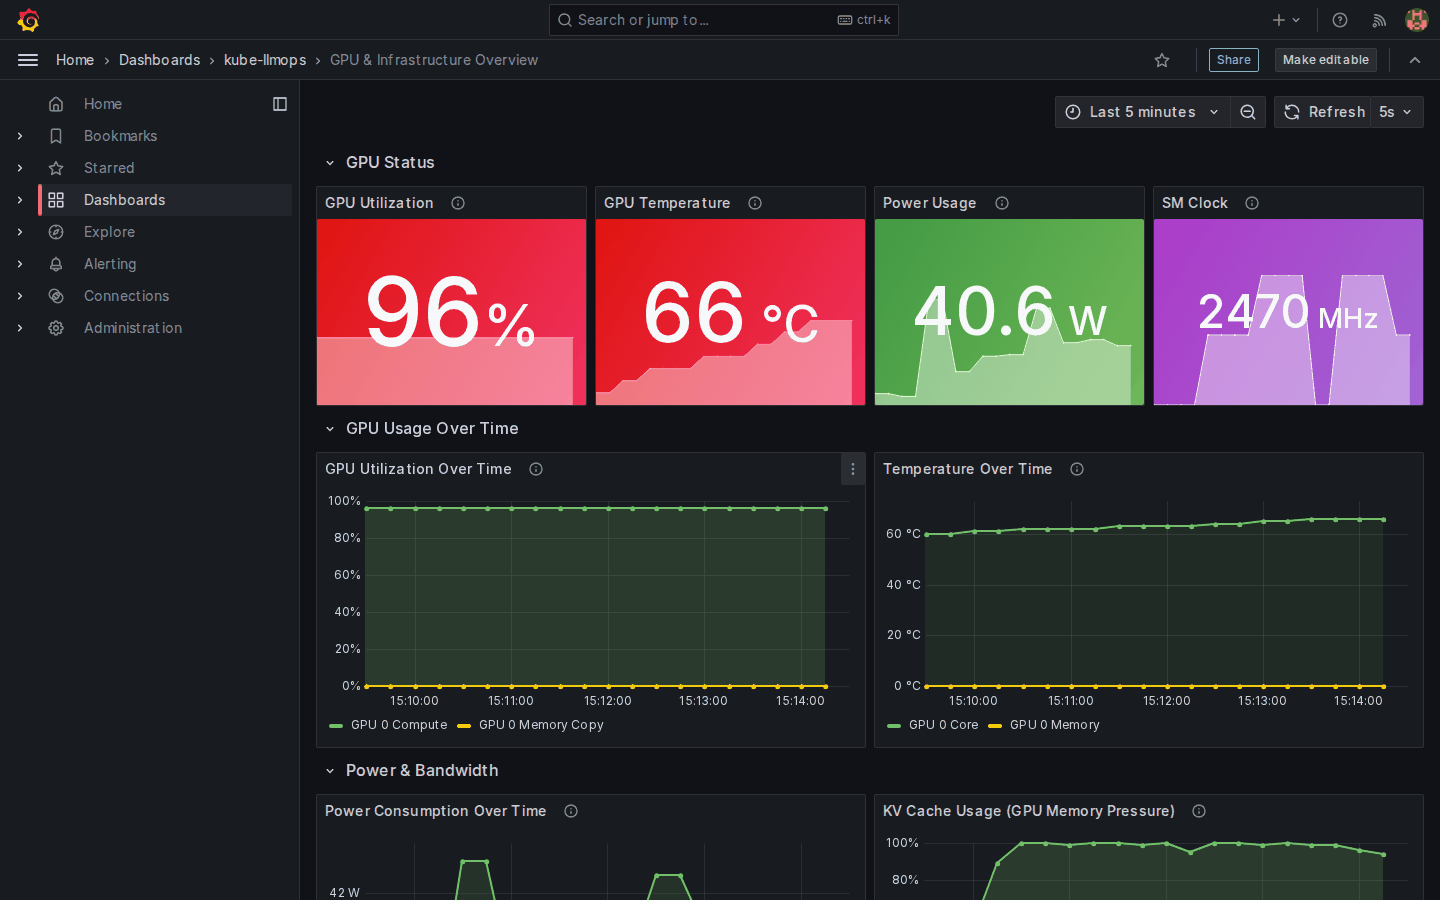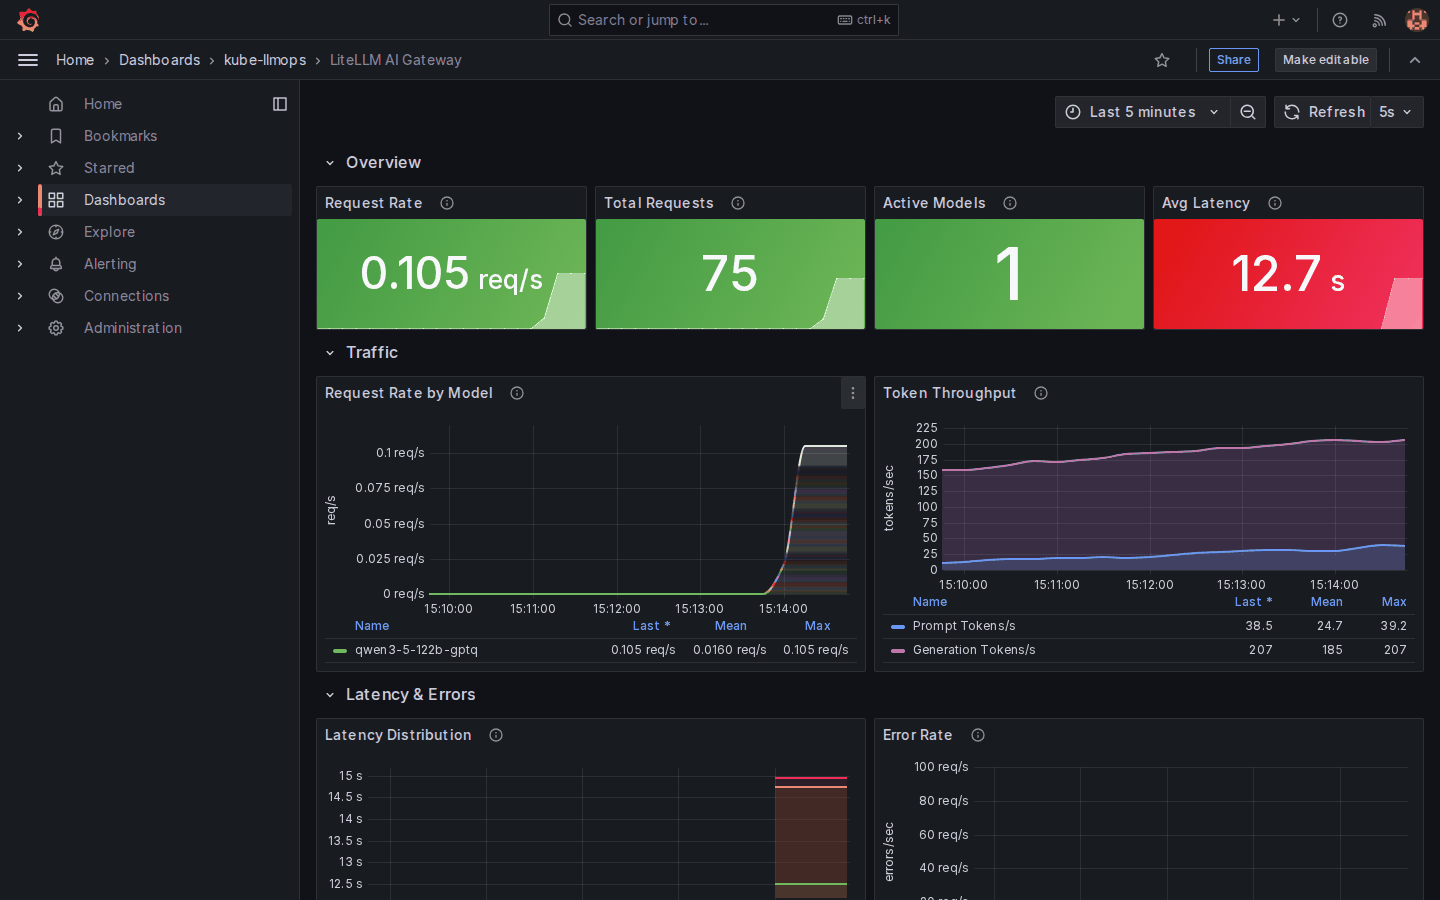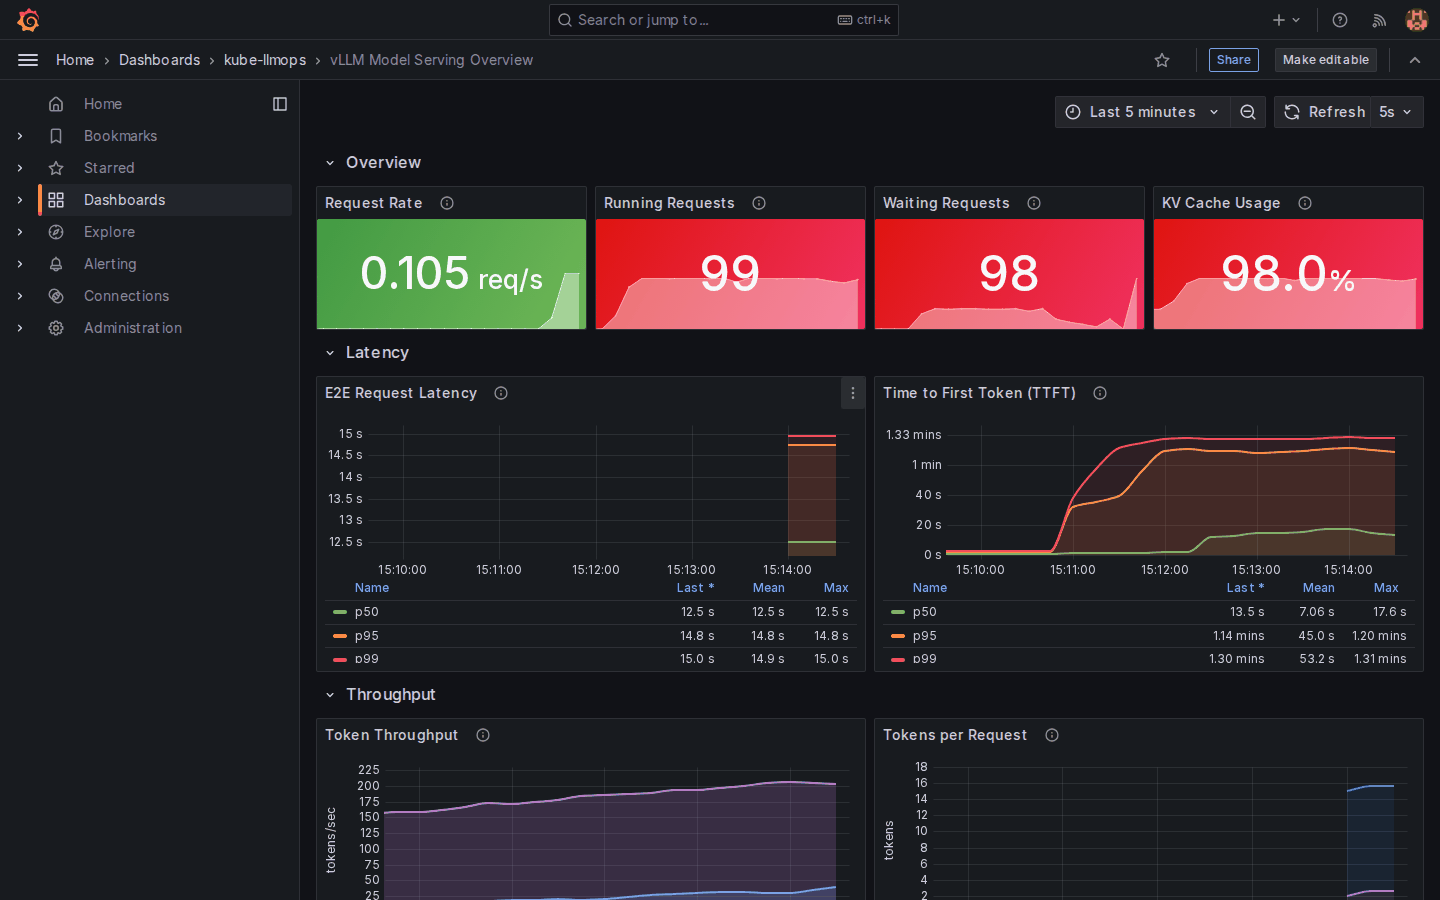 |
GPU Monitoring (DCGM)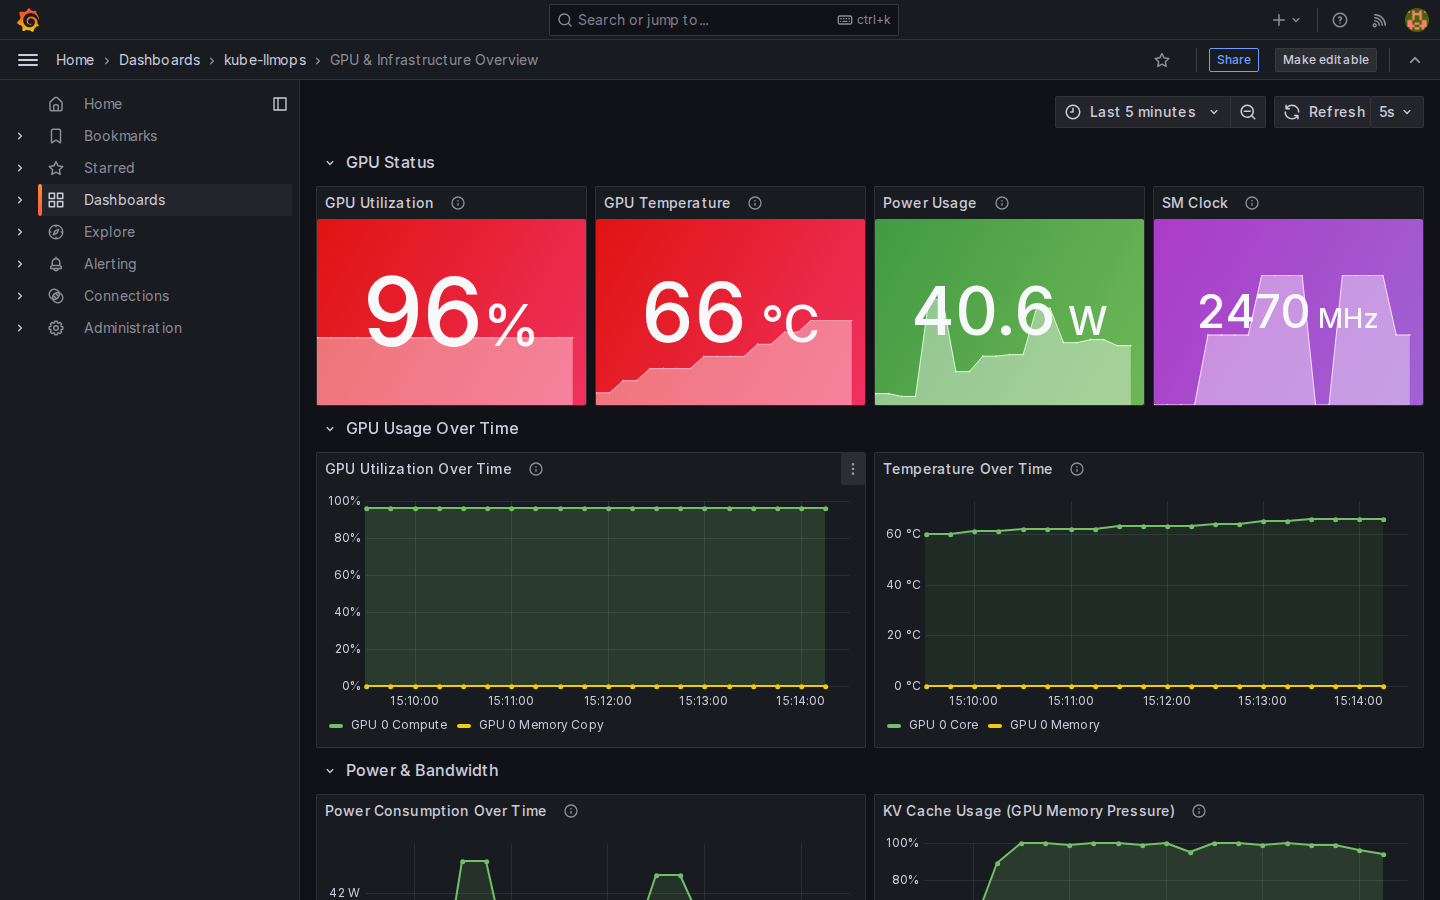 | vLLM Model Serving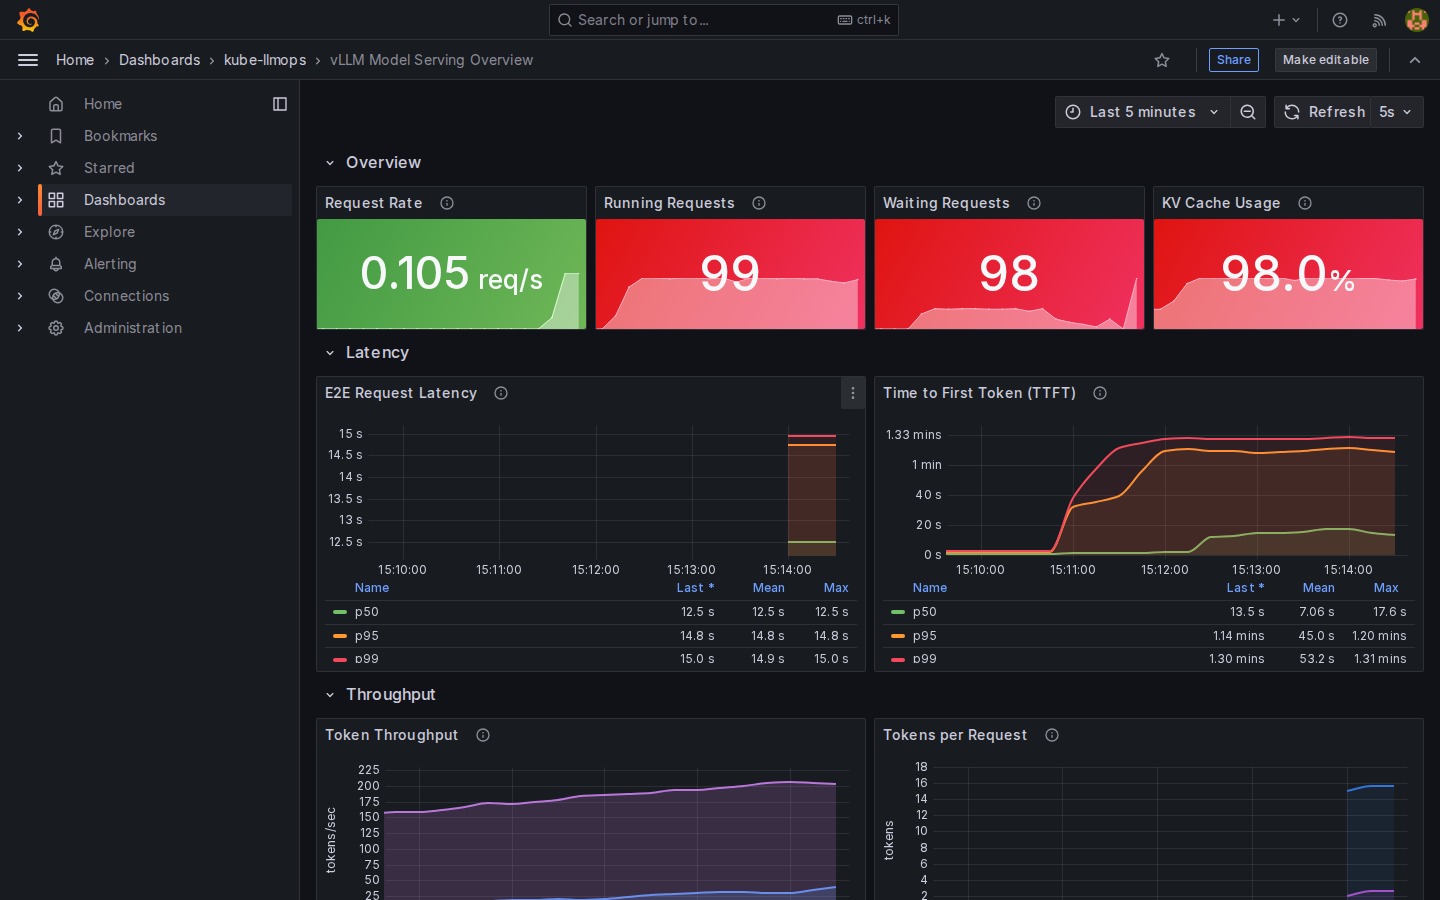 |
Langfuse LLM Tracing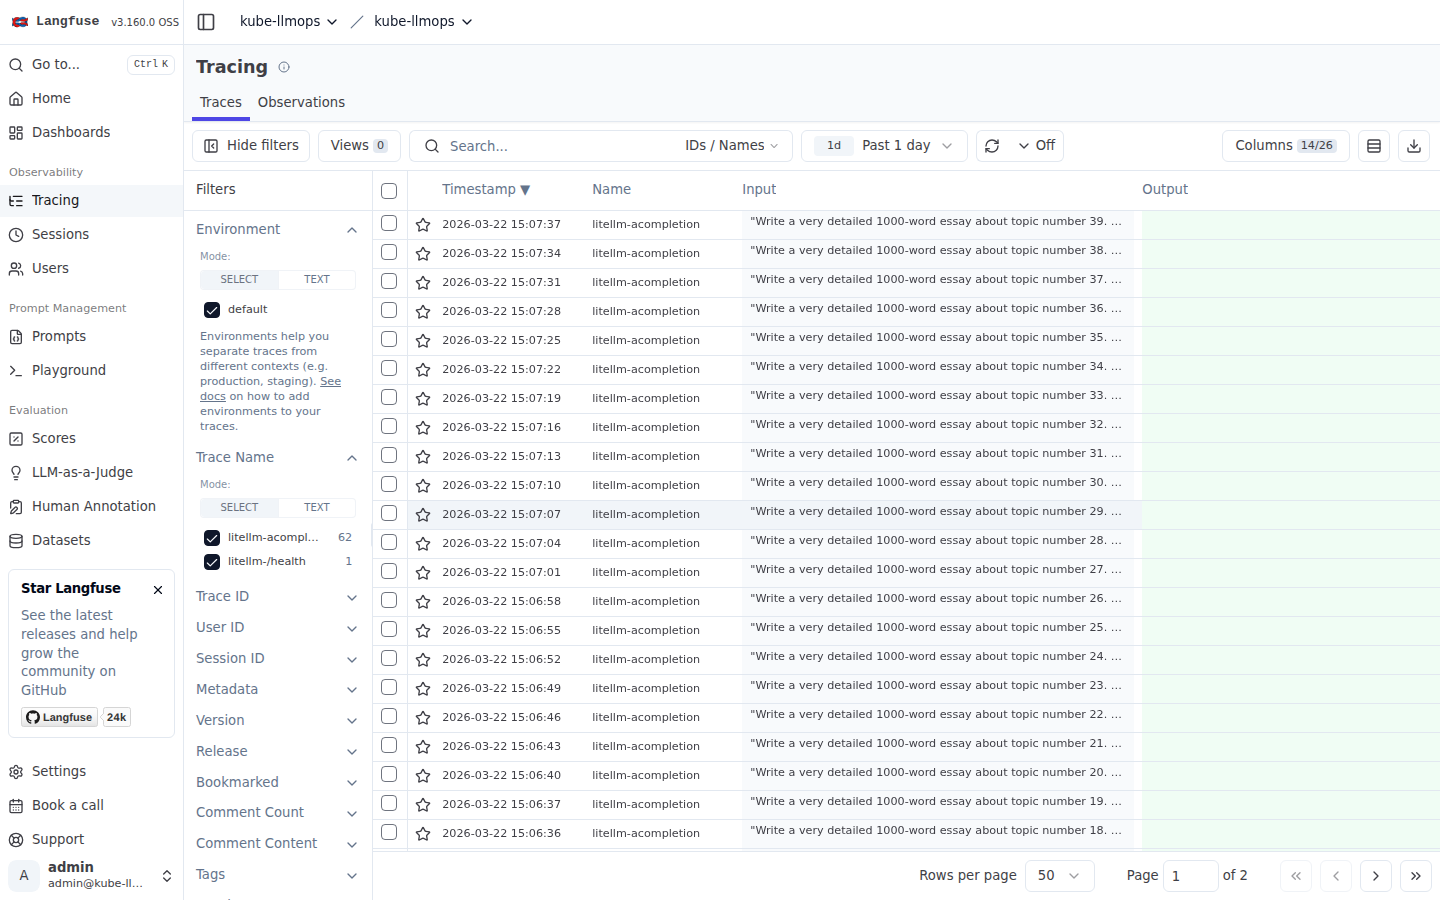 | MinIO Model Storage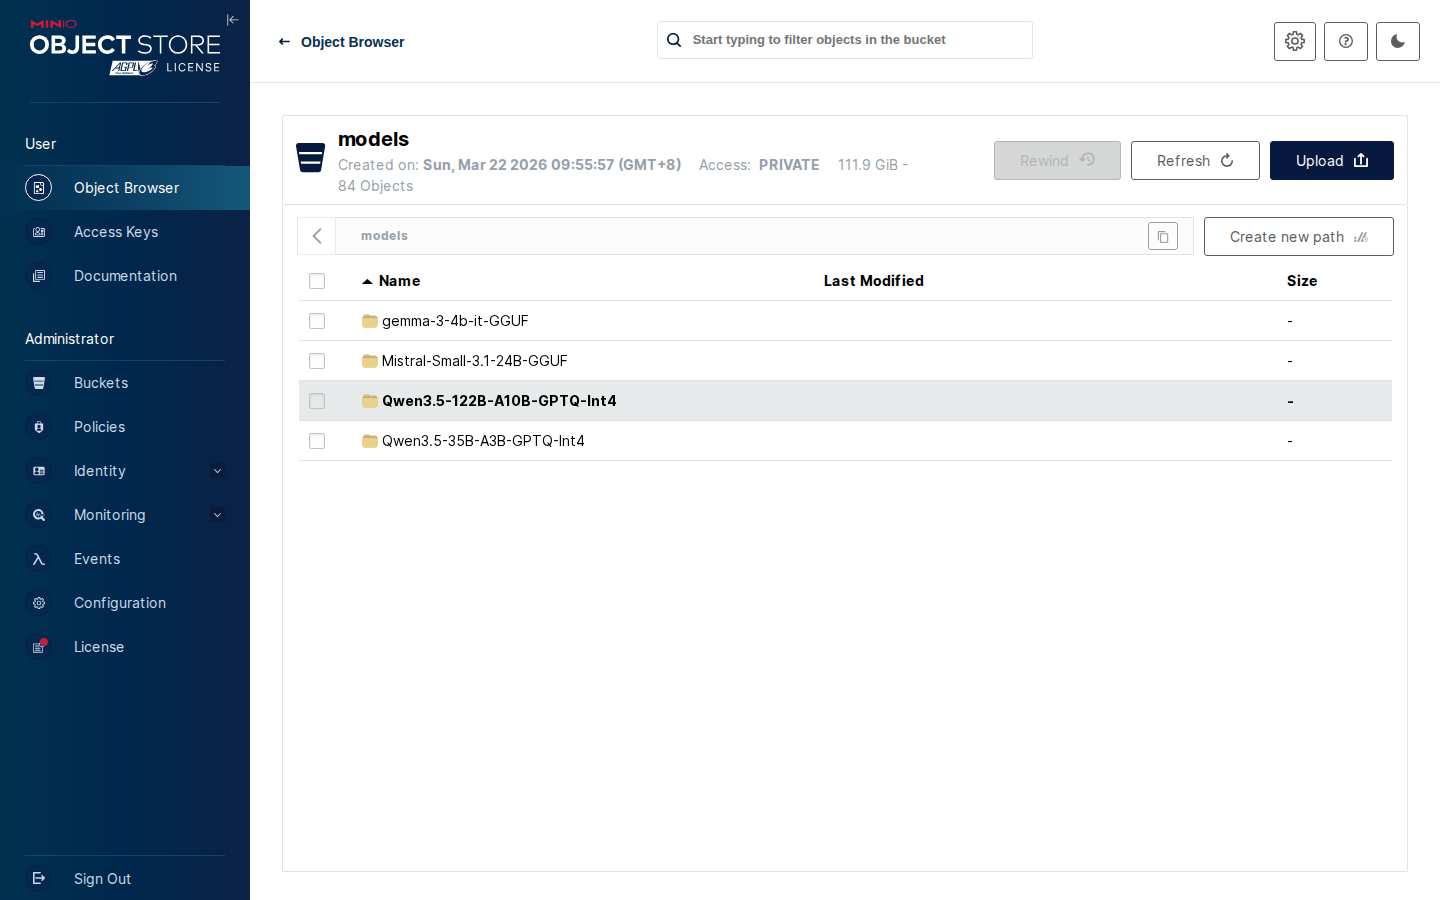 |
Keycloak SSO | LiteLLM Gateway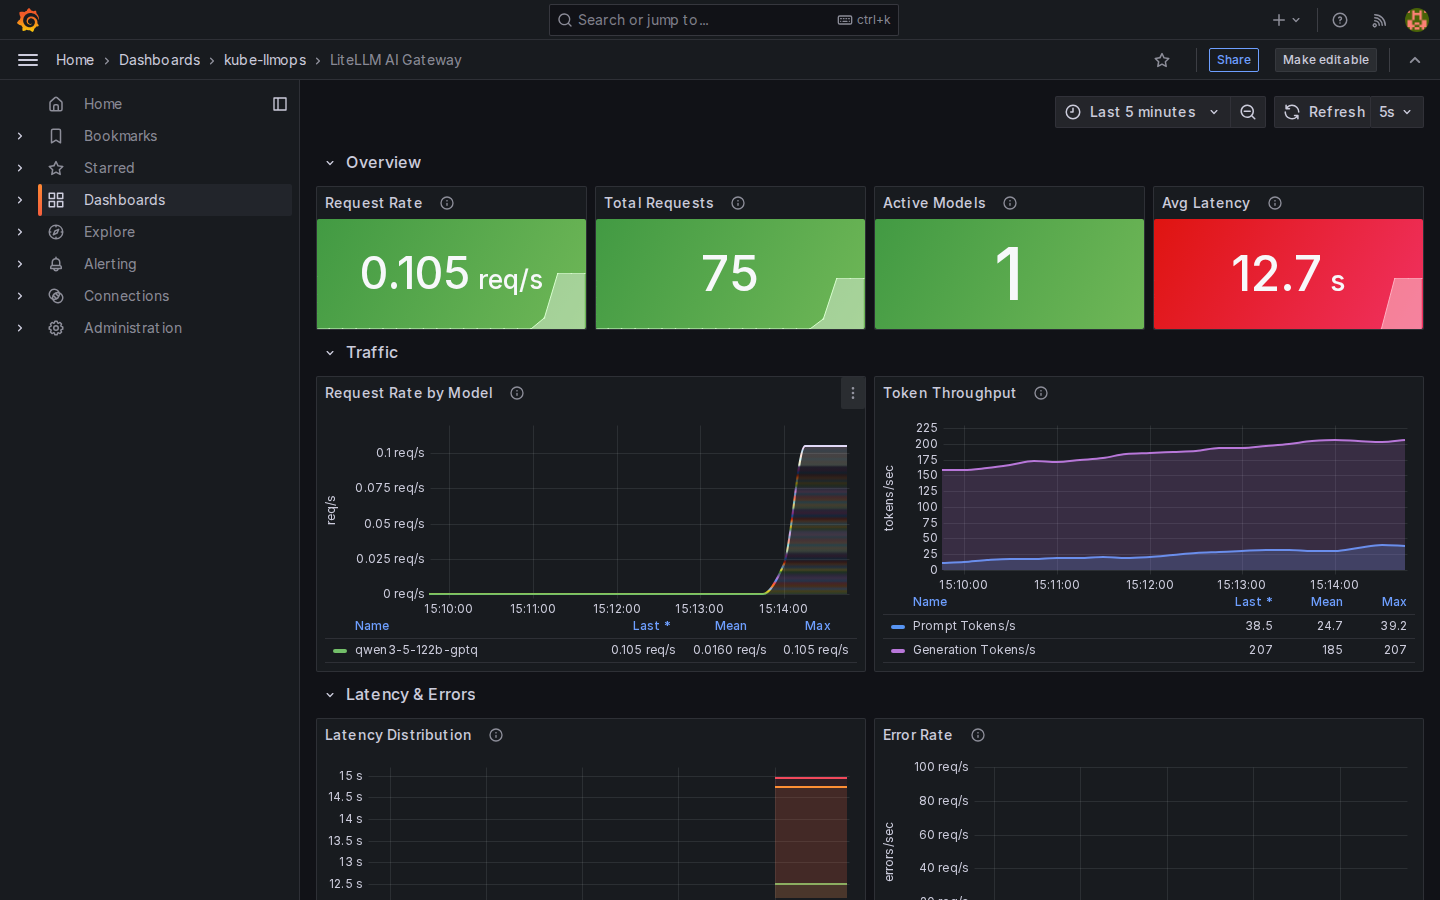 |
Quick Start
Prerequisites
- Kubernetes cluster (1.28+) with GPU node, or
kindfor CPU-only demo - Helm 3.x
- kubectl
Install
# Install from local source
helm install kube-llmops charts/kube-llmops-stack \
  -f charts/kube-llmops-stack/values-single-node.yaml \
  --set global.nodePort.enabled=true \
  --set global.nodePort.host=$NODE_IP

# Or install with ingress
helm install kube-llmops charts/kube-llmops-stack \
  -f values-minimal.yaml \
  --set ingress.enabled=true \
  --set ingress.host=llmops.local

# Or: CPU-only demo (no GPU required)
helm install kube-llmops charts/kube-llmops-stack -f values-ci.yaml
Chat with your model
curl http://litellm.llmops.local/v1/chat/completions \
  -H "Authorization: Bearer sk-kube-llmops-dev" \
  -H "Content-Type: application/json" \
  -d '{"model":"qwen2-5-0-5b","messages":[{"role":"user","content":"Hello!"}]}'
Access the UIs
Option A: Ingress (recommended — no port-forward needed)
# Enable ingress during install
helm install kube-llmops charts/kube-llmops-stack \
  -f values-minimal.yaml \
  --set ingress.enabled=true \
  --set ingress.host=llmops.local    # or your real domain

# If no real domain, add to /etc/hosts:
NODE_IP=$(kubectl get node -o jsonpath='{.items[0].status.addresses[0].address}')
echo "$NODE_IP litellm.llmops.local grafana.llmops.local langfuse.llmops.local keycloak.llmops.local minio.llmops.local prometheus.llmops.local" | sudo tee -a /etc/hosts
| Service | Ingress URL | Default Credentials |
|---|---|---|
| LiteLLM (AI Gateway) | http://litellm.llmops.local | any username / sk-kube-llmops-dev |
| Grafana (Dashboards) | http://grafana.llmops.local | admin / admin123! |
| Langfuse (LLM Tracing) | http://langfuse.llmops.local | admin@kube-llmops.local / admin123! |
| Keycloak (SSO) | http://keycloak.llmops.local | admin / admin123! |
| MinIO (Object Storage) | http://minio.llmops.local | minioadmin / minioadmin |
| Prometheus (Metrics) | http://prometheus.llmops.local | No auth |
Option B: Port-forward (fallback)
kubectl port-forward svc/kube-llmops-litellm 4000:4000 &
kubectl port-forward svc/kube-llmops-grafana 3000:3000 &
kubectl port-forward svc/kube-llmops-langfuse 3001:3000 &
[!TIP] When SSO is enabled, use Keycloak credentials (
admin/admin123!) to log in to Grafana, Langfuse, and MinIO. The Keycloak user email (admin@kube-llmops.local) matches the Langfuse init user, so SSO login automatically sees existing projects and traces.
[!WARNING] These are development defaults. For production, override via
--set:helm install kube-llmops charts/kube-llmops-stack \ --set litellm.masterKey=sk-your-secret-key \ --set observability.grafana.adminPassword=your-grafana-pw \ --set langfuse.init.userPassword=your-langfuse-pw \ --set langfuse.externalUrl=https://langfuse.your-domain.com
Features
| Feature | kube-llmops | Raw vLLM | KAITO | KServe |
|---|---|---|---|---|
| Engine auto-selection (GPTQ->vLLM, GGUF->llama.cpp) | Yes | N/A | No | No |
| AI Gateway (key mgmt, cost tracking, rate limit) | Yes | No | No | No |
| LLM tracing (prompt, tokens, cost per request) | Yes | No | No | No |
| Pre-built Grafana dashboards (11) + alert rules (8) | Yes | No | No | No |
| GPU monitoring (DCGM) | Yes | DIY | No | No |
| KEDA autoscaling (queue + TTFT + TPOT, scale-to-zero) | Yes | No | No | Partial |
| SSO integration (Keycloak OIDC) | Yes | No | No | No |
| S3 model storage (MinIO) | Yes | No | No | No |
| Container log aggregation (Fluent Bit + Loki) | Yes | No | No | No |
| RAG infrastructure (Dify + eval + guardrails) | Yes | No | No | No |
| One-click full stack | Yes | N/A | No | No |
| Cloud-agnostic | Yes | Yes | Azure only | Yes |
Deployment Profiles
| Profile | GPU | Models | Monitoring | Tracing | Logging | Use Case |
|---|---|---|---|---|---|---|
values-ci.yaml | None | None (CPU) | Basic | Off | Off | CI / Demo |
values-minimal.yaml | 1x | 1 small | Prometheus + Grafana | Langfuse | Fluent Bit + Loki | Development |
values-standard.yaml | 4-8x | 2-3 | Full OTel stack | Langfuse | Fluent Bit + Loki | Team |
values-production.yaml | 16+x | N | Full + HA | Full | Full | Enterprise |
Documentation
- Getting Started -- Installation, configuration, troubleshooting
- Architecture -- Full technical design and technology choices
- Changelog -- Release notes
- Contributing -- How to contribute
- RAG Infrastructure -- RAG components, evaluation, and safety
- ADR -- Architecture Decision Records
Roadmap
- v0.1.0 (MVP) -- Model serving + Gateway + Metrics + Tracing
- v0.2.0 -- Langfuse v3 + Keycloak SSO + Infra automation + NodePort
- v0.3.0 -- RAG infra (Dify + pgvector + TEI embedding/reranking + Ragas eval + LLM-Guard + Quality Gate)
- v0.4.0 -- Fine-tuning pipeline (LLaMA-Factory + Argo Workflows + MLflow) + JupyterHub + Terraform
- v0.5.0 -- Advanced Inference (latency routing, prefix caching, multi-trigger KEDA, scale-to-zero, canary, llm-d, multi-accelerator)
- v1.0.0 (current) -- Operator + kubectl-llmops CLI (15+ commands) + Headlamp Dashboard
License
License Notice
This project is Apache 2.0 licensed. However, some optional dependencies have different licenses:
| Component | License | Required? |
|---|---|---|
| Grafana | AGPL-3.0 | Optional (can bring your own) |
| Loki | AGPL-3.0 | Optional (can use OpenSearch) |
| All other components | Apache 2.0 / MIT / BSD | Yes |
If AGPL is a concern for your organization, Grafana and Loki can be disabled and replaced with your own visualization and log storage solutions.
Contributing
Contributions welcome! See CONTRIBUTING.md for guidelines.
Star History
If you find this project useful, please give it a star! ⭐
🤝 Community
- 💬 Discussions — Ask questions, share your setups, suggest features
- 🐛 Issues — Report bugs or request features
- 📖 CONTRIBUTING.md — Guide for first-time contributors
- 🏷️ Look for
good first issueandhelp wantedlabels to get started contributing
We need your help to reach 1,000 stars! Every star, issue, PR, and discussion helps the project grow. Share kube-llmops with your team, write a blog post, or contribute a feature — all contributions are welcome ❤️
Contributors

269 commits

1 commits
Similar repos


Languages
Go
46.8%
Python
35.0%
HCL
6.5%
Go Template
4.0%
Shell
4.0%
Makefile
2.1%
TypeScript
1.1%
README
English | 中文 | 🌐 Project Site
kube-llmops
🏆 The most comprehensive Kubernetes-native LLMOps Platform — One command to deploy, manage, monitor, and optimize your entire LLM infrastructure.
[!NOTE] v1.0.0 released -- the v1.0 trio is complete: Operator (LLMPlatform / ModelDeployment / FineTuneRun CRDs) + kubectl-llmops CLI (15+ commands,
kubectl llmops <cmd>) + Headlamp Dashboard (Kubernetes UI +kube-llmops-portalplugin). See CHANGELOG for details.
What is kube-llmops?
kube-llmops is an opinionated, batteries-included Helm chart that deploys a complete LLM operations stack on Kubernetes:
- Model Serving -- vLLM, llama.cpp, or TEI, auto-selected based on model format (engine auto-detection from source name)
- CLI (
kubectl-llmops) -- kubectl plugin with 15+ imperative commands:deploy,list,status,scale,canary,logs,test,port-forward,finetune,rag,platform,migrate, ... - AI Gateway -- LiteLLM for unified OpenAI-compatible API, key management, rate limiting, budget control
- Observability -- Prometheus + Grafana (11 dashboards + 8 alert rules) + Langfuse v3 LLM tracing + node-exporter + kube-state-metrics
- Logging -- Fluent Bit + Loki, queryable in Grafana Explore
- Autoscaling -- KEDA scales vLLM pods based on queue depth, TTFT P95, and TPOT P95; supports scale-to-zero with fallback
- Security -- Keycloak SSO for Grafana/Langfuse, LLM-Guard prompt injection defense, NetworkPolicy isolation
- RAG Infrastructure -- Dify platform + pgvector + TEI embedding/reranking + Ragas evaluation + quality gate
- Fine-tuning -- LLaMA-Factory LoRA/QLoRA/Full fine-tuning with Argo Workflows pipeline + MLflow tracking
- Model Distribution -- MinIO model cache + HuggingFace fallback + hf-transfer multi-threaded downloads
- Storage -- MinIO S3-compatible model storage, PVC model cache
# Install from local source (recommended)
helm install kube-llmops charts/kube-llmops-stack -f values-minimal.yaml
Use Cases
- "I want to deploy DeepSeek-R1-0528 and let 5 teams share it with token budget limits"
- "I want to see which team burned the most GPU hours this month"
- "I want a GGUF model on llama.cpp and a full-precision model on vLLM behind the same API"
- "I want every LLM request traced with full prompt, tokens, cost, and latency"
Architecture
See ARCHITECTURE.md for the full technical design.
Screenshots
| API Demo | Grafana Dashboards |
| GPU Monitoring (DCGM) | vLLM Model Serving |
| Langfuse LLM Tracing | MinIO Model Storage |
| Keycloak SSO | LiteLLM Gateway |
Quick Start
Prerequisites
- Kubernetes cluster (1.28+) with GPU node, or
kindfor CPU-only demo - Helm 3.x
- kubectl
Install
# Install from local source
helm install kube-llmops charts/kube-llmops-stack \
  -f charts/kube-llmops-stack/values-single-node.yaml \
  --set global.nodePort.enabled=true \
  --set global.nodePort.host=$NODE_IP

# Or install with ingress
helm install kube-llmops charts/kube-llmops-stack \
  -f values-minimal.yaml \
  --set ingress.enabled=true \
  --set ingress.host=llmops.local

# Or: CPU-only demo (no GPU required)
helm install kube-llmops charts/kube-llmops-stack -f values-ci.yaml
Chat with your model
curl http://litellm.llmops.local/v1/chat/completions \
  -H "Authorization: Bearer sk-kube-llmops-dev" \
  -H "Content-Type: application/json" \
  -d '{"model":"qwen2-5-0-5b","messages":[{"role":"user","content":"Hello!"}]}'
Access the UIs
Option A: Ingress (recommended — no port-forward needed)
# Enable ingress during install
helm install kube-llmops charts/kube-llmops-stack \
  -f values-minimal.yaml \
  --set ingress.enabled=true \
  --set ingress.host=llmops.local    # or your real domain

# If no real domain, add to /etc/hosts:
NODE_IP=$(kubectl get node -o jsonpath='{.items[0].status.addresses[0].address}')
echo "$NODE_IP litellm.llmops.local grafana.llmops.local langfuse.llmops.local keycloak.llmops.local minio.llmops.local prometheus.llmops.local" | sudo tee -a /etc/hosts
| Service | Ingress URL | Default Credentials |
|---|---|---|
| LiteLLM (AI Gateway) | http://litellm.llmops.local | any username / sk-kube-llmops-dev |
| Grafana (Dashboards) | http://grafana.llmops.local | admin / admin123! |
| Langfuse (LLM Tracing) | http://langfuse.llmops.local | admin@kube-llmops.local / admin123! |
| Keycloak (SSO) | http://keycloak.llmops.local | admin / admin123! |
| MinIO (Object Storage) | http://minio.llmops.local | minioadmin / minioadmin |
| Prometheus (Metrics) | http://prometheus.llmops.local | No auth |
Option B: Port-forward (fallback)
kubectl port-forward svc/kube-llmops-litellm 4000:4000 &
kubectl port-forward svc/kube-llmops-grafana 3000:3000 &
kubectl port-forward svc/kube-llmops-langfuse 3001:3000 &
[!TIP] When SSO is enabled, use Keycloak credentials (
admin/admin123!) to log in to Grafana, Langfuse, and MinIO. The Keycloak user email (admin@kube-llmops.local) matches the Langfuse init user, so SSO login automatically sees existing projects and traces.
[!WARNING] These are development defaults. For production, override via
--set:helm install kube-llmops charts/kube-llmops-stack \ --set litellm.masterKey=sk-your-secret-key \ --set observability.grafana.adminPassword=your-grafana-pw \ --set langfuse.init.userPassword=your-langfuse-pw \ --set langfuse.externalUrl=https://langfuse.your-domain.com
Features
| Feature | kube-llmops | Raw vLLM | KAITO | KServe |
|---|---|---|---|---|
| Engine auto-selection (GPTQ->vLLM, GGUF->llama.cpp) | Yes | N/A | No | No |
| AI Gateway (key mgmt, cost tracking, rate limit) | Yes | No | No | No |
| LLM tracing (prompt, tokens, cost per request) | Yes | No | No | No |
| Pre-built Grafana dashboards (11) + alert rules (8) | Yes | No | No | No |
| GPU monitoring (DCGM) | Yes | DIY | No | No |
| KEDA autoscaling (queue + TTFT + TPOT, scale-to-zero) | Yes | No | No | Partial |
| SSO integration (Keycloak OIDC) | Yes | No | No | No |
| S3 model storage (MinIO) | Yes | No | No | No |
| Container log aggregation (Fluent Bit + Loki) | Yes | No | No | No |
| RAG infrastructure (Dify + eval + guardrails) | Yes | No | No | No |
| One-click full stack | Yes | N/A | No | No |
| Cloud-agnostic | Yes | Yes | Azure only | Yes |
Deployment Profiles
| Profile | GPU | Models | Monitoring | Tracing | Logging | Use Case |
|---|---|---|---|---|---|---|
values-ci.yaml | None | None (CPU) | Basic | Off | Off | CI / Demo |
values-minimal.yaml | 1x | 1 small | Prometheus + Grafana | Langfuse | Fluent Bit + Loki | Development |
values-standard.yaml | 4-8x | 2-3 | Full OTel stack | Langfuse | Fluent Bit + Loki | Team |
values-production.yaml | 16+x | N | Full + HA | Full | Full | Enterprise |
Documentation
- Getting Started -- Installation, configuration, troubleshooting
- Architecture -- Full technical design and technology choices
- Changelog -- Release notes
- Contributing -- How to contribute
- RAG Infrastructure -- RAG components, evaluation, and safety
- ADR -- Architecture Decision Records
Roadmap
- v0.1.0 (MVP) -- Model serving + Gateway + Metrics + Tracing
- v0.2.0 -- Langfuse v3 + Keycloak SSO + Infra automation + NodePort
- v0.3.0 -- RAG infra (Dify + pgvector + TEI embedding/reranking + Ragas eval + LLM-Guard + Quality Gate)
- v0.4.0 -- Fine-tuning pipeline (LLaMA-Factory + Argo Workflows + MLflow) + JupyterHub + Terraform
- v0.5.0 -- Advanced Inference (latency routing, prefix caching, multi-trigger KEDA, scale-to-zero, canary, llm-d, multi-accelerator)
- v1.0.0 (current) -- Operator + kubectl-llmops CLI (15+ commands) + Headlamp Dashboard
License
License Notice
This project is Apache 2.0 licensed. However, some optional dependencies have different licenses:
| Component | License | Required? |
|---|---|---|
| Grafana | AGPL-3.0 | Optional (can bring your own) |
| Loki | AGPL-3.0 | Optional (can use OpenSearch) |
| All other components | Apache 2.0 / MIT / BSD | Yes |
If AGPL is a concern for your organization, Grafana and Loki can be disabled and replaced with your own visualization and log storage solutions.
Contributing
Contributions welcome! See CONTRIBUTING.md for guidelines.
Star History
If you find this project useful, please give it a star! ⭐
🤝 Community
- 💬 Discussions — Ask questions, share your setups, suggest features
- 🐛 Issues — Report bugs or request features
- 📖 CONTRIBUTING.md — Guide for first-time contributors
- 🏷️ Look for
good first issueandhelp wantedlabels to get started contributing
We need your help to reach 1,000 stars! Every star, issue, PR, and discussion helps the project grow. Share kube-llmops with your team, write a blog post, or contribute a feature — all contributions are welcome ❤️
Similar repos
Contributors
269 commits
1 commits
Languages
Go
46.8%
Python
35.0%
HCL
6.5%
Go Template
4.0%
Shell
4.0%
Makefile
2.1%
TypeScript
1.1%