
[CVPR 2026 Findings] TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis
See the codeREADME
TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis
🚀🚀🚀 Official implementation of TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis
-
Authors: Shunian Chen*, Hejin Huang*, Yexin Liu*, Zihan Ye, Pengcheng Chen, Chenghao Zhu, Michael Guan, Rongsheng Wang, Junying Chen, Guanbin Li, Ser-Nam Lim†, Harry Yang†, Benyou Wang†
-
Institutions: The Chinese University of Hong Kong, Shenzhen; Sun Yat-sen University; The Hong Kong University of Science and Technology
-
Resources: 📄Paper 🤗Dataset 🌐Project Page
💡 Highlights
- 🔥 Large-scale high-quality talking head dataset TalkVid with over 1,244 hours of HD/4K footage
- 🔥 Multimodal diversified content covering 15 languages and wide age ranges (0–60+ years)
- 🔥 Advanced data pipeline with comprehensive quality filtering and motion analysis
- 🔥 Full-body presence including upper-body visual context unlike previous datasets
- 🔥 Rich annotations with high-quality captions and comprehensive metadata
📜 News
[2026/06/06] 🎉 Our paper has been accepted by CVPR 2026 Findings!
[2025/08/19] 🚀 Our paper TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis is available!
[2025/08/19] 🚀 Released TalkVid dataset and training/inference code!
[2025/08/19] 🚀 Released comprehensive data processing pipeline including quality filtering and motion analysis tools!
📊 Dataset
TalkVid Dataset Overview
TalkVid is a large-scale and diversified open-source dataset for audio-driven talking head synthesis, featuring:
- Scale: 7,729 unique speakers with over 1,244 hours of HD/4K footage
- Diversity: Covers 15 languages and wide age range (0–60+ years)
- Quality: High-resolution videos (1080p & 2160p) with comprehensive quality filtering
- Rich Context: Full upper-body presence unlike head-only datasets
- Annotations: High-quality captions and comprehensive metadata
Download Link: 🤗 Hugging Face
More example videos can be found in our 🌐 Project Page.
📥 Data Download
To download video clips from YouTube using the TalkVid dataset:
# Use the JSON metadata from HuggingFace
cd data_pipeline/0_video_download
python download_clips.py --input input.json --output output --limit 50
For detailed instructions, see data_pipeline/0_video_download/README.md.
Data Format
{
    "id": "videovideoTr6MMsoWAog-scene1-scene1",
    "height": 1080,
    "width": 1920,
    "fps": 24.0,
    "start-time": 0.1,
    "start-frame": 0,
    "end-time": 5.141666666666667,
    "end-frame": 121,
    "durations": "5.042s",
    "info": {
        "Person ID": "597",
        "Ethnicity": "White",
        "Age Group": "60+",
        "Gender": "Male",
        "Video Link": "https://www.youtube.com/watch?v=Tr6MMsoWAog",
        "Language": "English",
        "Video Category": "Personal Experience"
    },
    "description": "The provided image sequence shows an older man in a suit, likely being interviewed or participating in a recorded conversation. He is seated and maintains a consistent, upright posture. Across the frames, his head rotates incrementally towards the camera's right, suggesting he is addressing someone off-screen in that direction. His facial expressions also show subtle shifts, likely related to speaking or reacting. No significant movements of the hands, arms, or torso are observed.  Because these are still images, any dynamic motion analysis is limited to inferring likely movements from the subtle positional changes between frames.",
    "dover_scores": 8.9,
    "cotracker_ratio": 0.9271857142448425,
    "head_detail": {
        "scores": {
            "avg_movement": 97.92236052453518,
            "min_movement": 89.4061028957367,
            "avg_rotation": 93.79223716779671,
            "min_rotation": 70.42514759667668,
            "avg_completeness": 100.0,
            "min_completeness": 100.0,
            "avg_resolution": 383.14267156972596,
            "min_resolution": 349.6849455656829,
            "avg_orientation": 80.29047955896623,
            "min_orientation": 73.27433271185937
        }
    }
}
Data Statistics
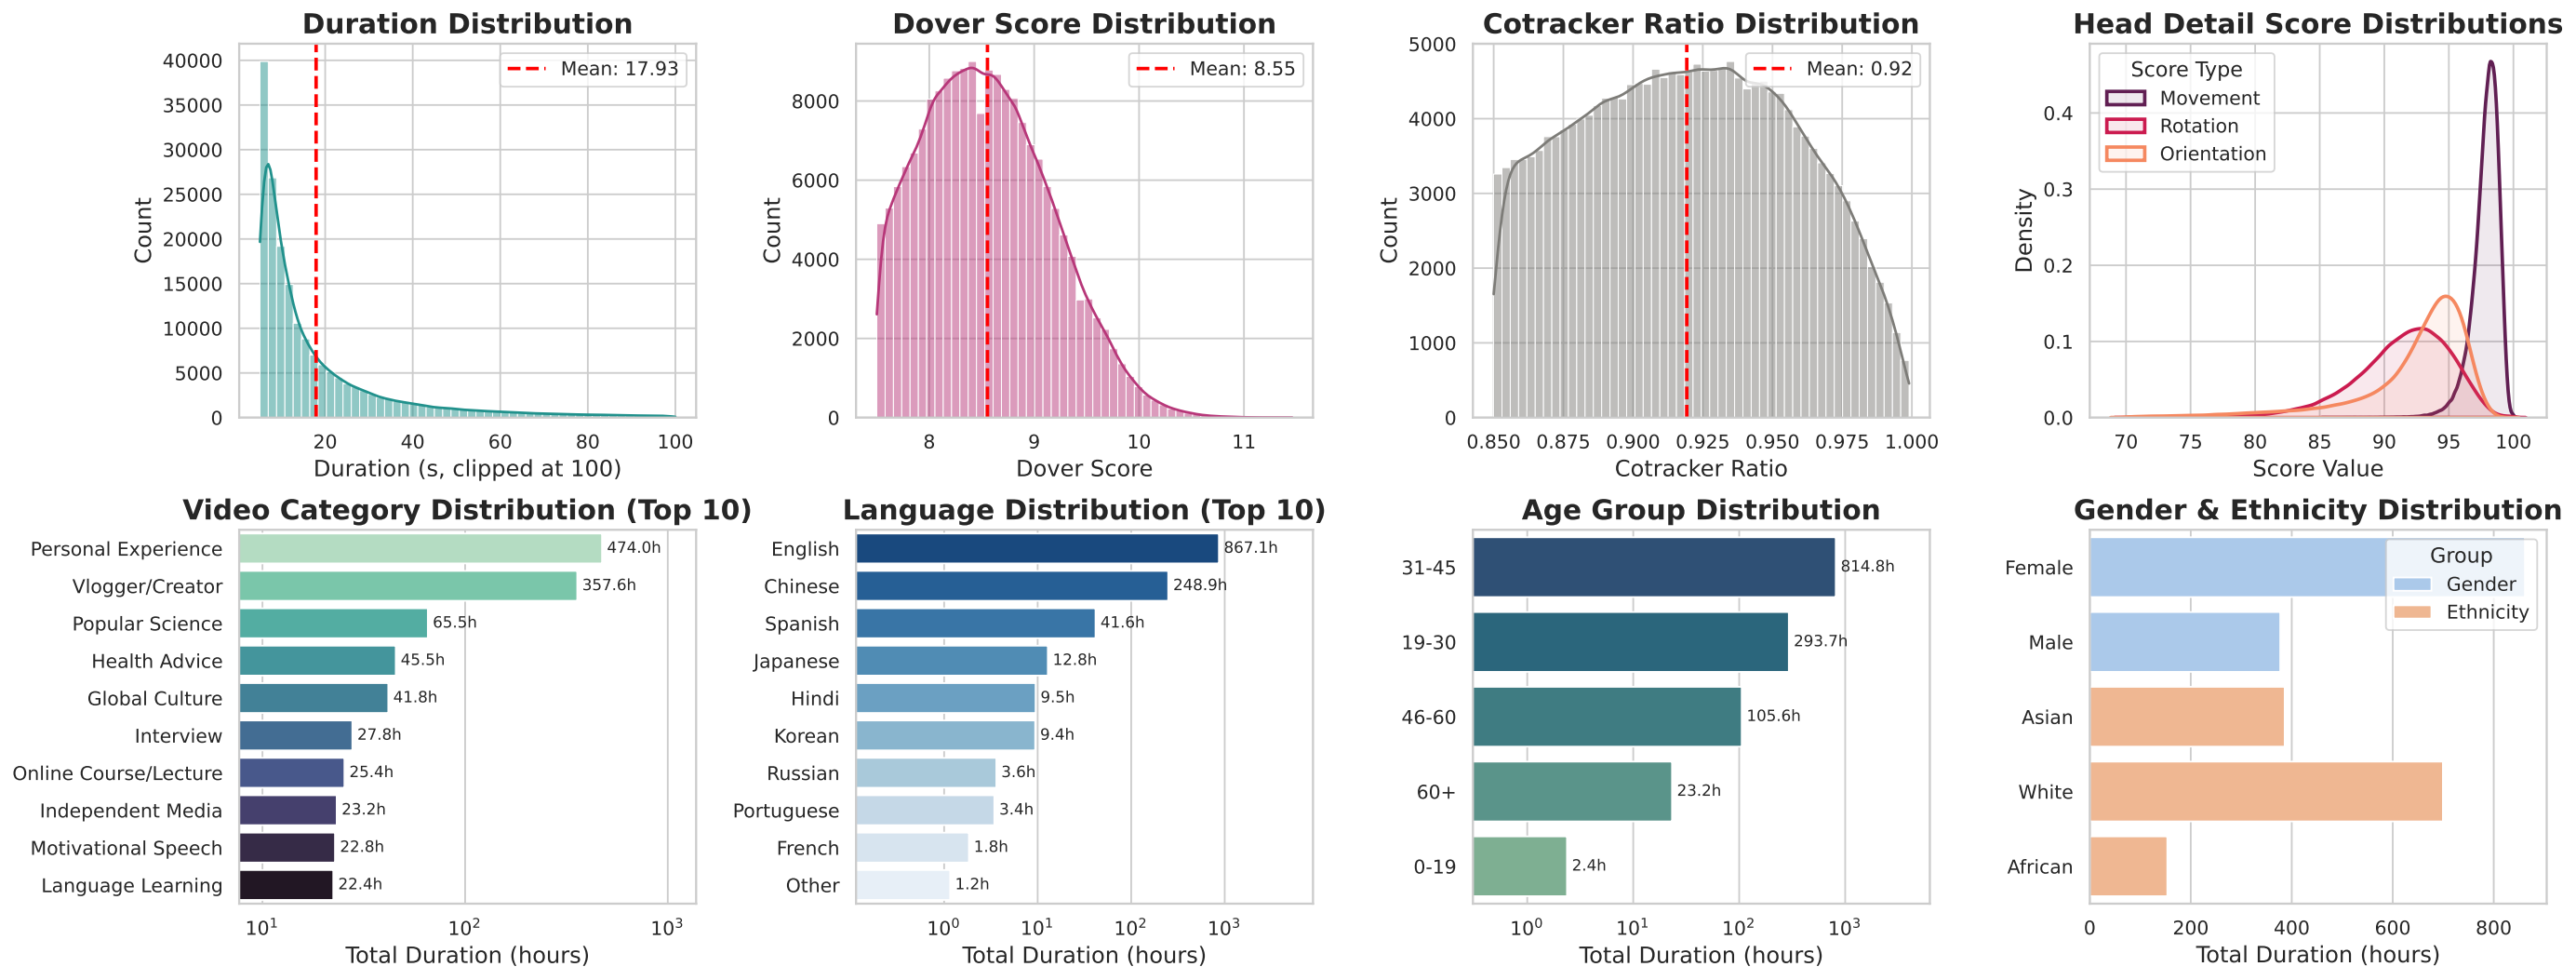
The dataset exhibits excellent diversity across multiple dimensions:
- Languages: English, Chinese, Arabic, Polish, German, Russian, French, Korean, Portuguese, Japanese, Thai, Spanish, Italian, Hindi
- Age Groups: 0–19, 19–30, 31–45, 46–60, 60+
- Video Quality: HD (1080p) and 4K (2160p) resolution with Dover score (mean ≈ 8.55), Cotracker ratio (mean ≈ 0.92), and head-detail scores concentrated in the 90–100 range
- Duration Distribution: Balanced segments from 3-30 seconds for optimal training
⚖️ Comparison with Other Datasets
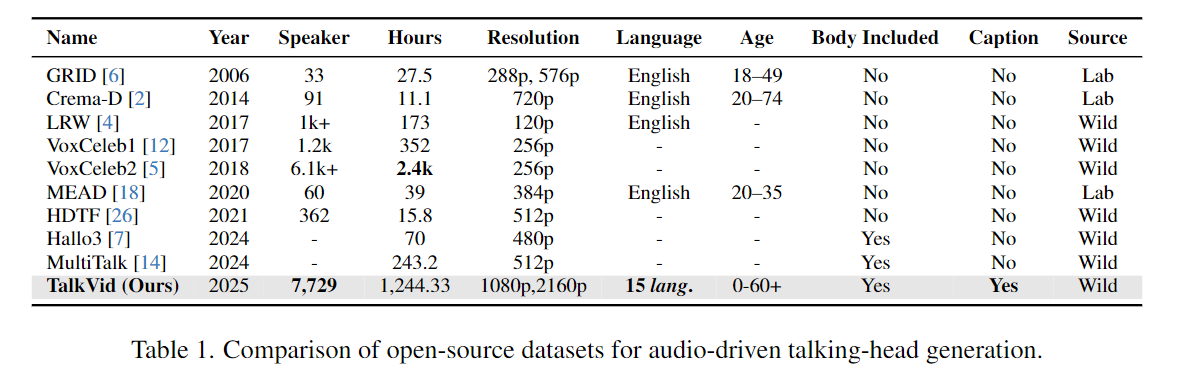
TalkVid stands as the largest and most diverse open-source dataset for audio-driven talking-head generation to date.
| 🔍 Aspect | Description |
|---|---|
| 📈 Scale | 7,729 speakers, over 1,244 hours of HD/4K footage |
| 🌍 Diversity | Covers 15 languages and a wide age range (0–60+ years) |
| 🧍♀️ Upper-body presence | Unlike many prior datasets, TalkVid includes upper-body visual context |
| 📝 Rich Annotations | Comes with high-quality captions for every sample |
| 🏞️ In-the-wild quality | Entirely collected in real-world, unconstrained environments |
| 🎯 Quality Assurance | Multi-stage filtering with DOVER, CoTracker, and head quality assessment |
Compared to existing benchmarks such as GRID, VoxCeleb, MEAD, or MultiTalk, TalkVid is the first dataset to combine:
- Large-scale multilinguality across 15+ languages
- Wild setting with upper-body inclusion for more natural synthesis
- High-resolution (1080p & 2160p) video for detailed facial features
- Comprehensive metadata including age, language, quality scores, and captions
🧪 Want to push the boundaries of talking-head generation, personalization, or cross-lingual synthesis? TalkVid is your new go-to dataset.
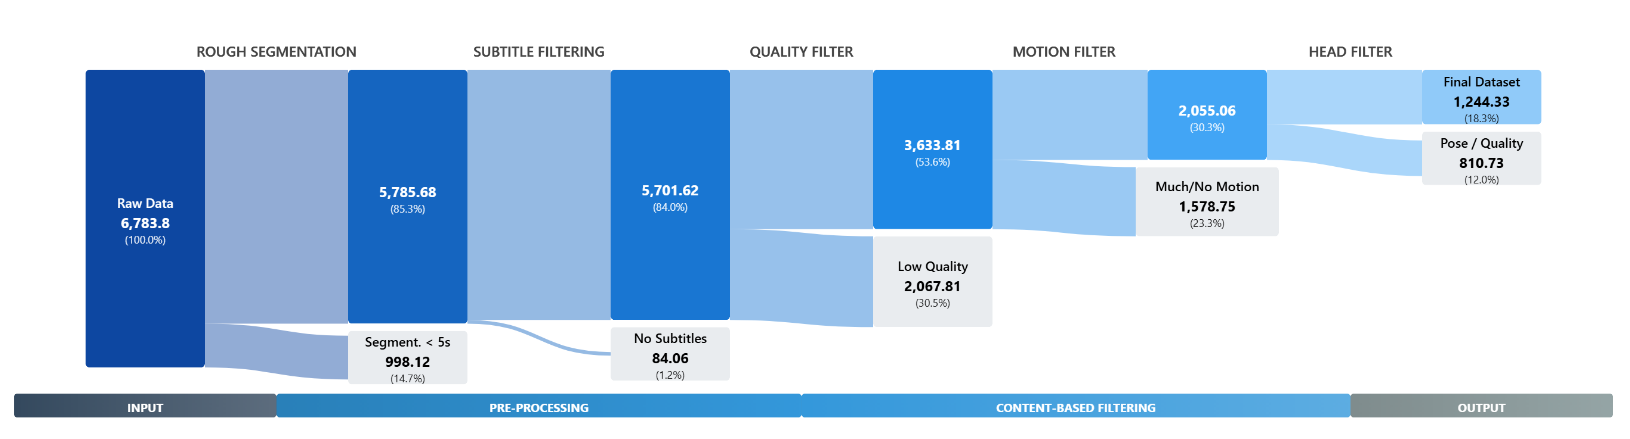
🏗️ Data Filtering Pipeline
Our comprehensive data filtering pipeline ensures high-quality dataset construction:
1. Video Rough Segmentation
cd data_pipeline/1_video_rough_segmentation
conda env create -f datapipe.yaml
conda activate video-py310
bash rough_segementation.sh
2. Video Quality & Motion Filtering
cd data_pipeline/2_video_quality_motion_filtering

# Quality assessment using DOVER
bash video_quality_dover.sh

# Motion analysis using CoTracker
bash video_motion_cotracker.sh
3. Head Detail Filtering
cd data_pipeline/3_head_detail_filtering
conda env create -f env_head.yml
conda activate env_head
bash head_filter.sh
🚀 Quick Start
Environment Setup
# Create conda environment
conda create -n talkvid python=3.10 -y
conda activate talkvid

# Install dependencies
pip install -r requirements.txt

# Install additional dependencies for video processing
conda install -c conda-forge 'ffmpeg<7' -y
conda install torchaudio==2.4.0 pytorch-cuda=12.1 -c pytorch -c nvidia -y
Model Downloads
Before running inference, download the required model checkpoints:
# Download the model checkpoints
huggingface-cli download tk93/V-Express --local-dir V-Express
mv V-Express/model_ckpts model_ckpts
mv V-Express/*.bin model_ckpts/v-express
rm -rf V-Express/
Quick Inference
We provide an easy-to-use inference script for generating talking head videos.
Command Line Usage
# Single sample inference
bash scripts/inference.sh

# Or run directly with Python
cd src
python src/inference.py \
    --reference_image_path "./test_samples/short_case/tys/ref.jpg" \
    --audio_path "./test_samples/short_case/tys/aud.mp3" \
    --kps_path "./test_samples/short_case/tys/kps.pth" \
    --output_path "./output.mp4" \
    --retarget_strategy "naive_retarget" \
    --num_inference_steps 25 \
    --guidance_scale 3.5 \
    --context_frames 24
Key Parameters
--reference_image_path: Path to the reference portrait image--audio_path: Path to the driving audio file--kps_path: Path to keypoints file (can be generated automatically)--retarget_strategy: Keypoint retargeting strategy (fix_face,naive_retarget, etc.)--num_inference_steps: Number of denoising steps (trade-off between quality and speed)--context_frames: Number of context frames for temporal consistency
🏋️ Training
Data Preprocessing
Before training, preprocess your data:
cd src/data_preprocess
bash env.sh  # Setup preprocessing environment
# Follow data preprocessing instructions in data_preprocess/readme.md
Multi-Stage Training
Our model uses a progressive 3-stage training strategy:
# Stage 1: Basic motion learning
export STAGE=1 TRAIN="TalkVid-Core" GPU="0,1"
bash scripts/train.sh

# Stage 2: Audio-visual alignment
export STAGE=2 TRAIN="TalkVid-Core" GPU="0,1"
bash scripts/train.sh

# Stage 3: Temporal consistency and refinement
export STAGE=3 TRAIN="TalkVid-Core" GPU="0,1"
bash scripts/train.sh
Training Configuration
Key configuration files:
src/configs/stage_1.yaml: Basic motion and reference net trainingsrc/configs/stage_2.yaml: Audio projection and alignment trainingsrc/configs/stage_3.yaml: Full model with motion module training
Training supports:
- Multi-GPU training with DeepSpeed ZeRO-2
- Mixed precision (fp16/bf16) for memory efficiency
- Gradient checkpointing to reduce memory usage
- Flexible data loading with configurable batch sizes and augmentations
📊 Evaluation & Benchmarks
Evaluation Metrics
We evaluate our model on multiple aspects:
- Lip Synchronization: Sync-C, Sync-D,
- Perceptual Quality: FID, FVD
TalkVid-Bench
TalkVid-Bench comprises 500 carefully sampled and stratified video clips along four critical demographic and language dimensions: age, gender, ethnicity, and language. This stratified design enables granular analysis of model performance across diverse subgroups, mitigating biases hidden in traditional aggregate evaluations. Each dimension is divided into balanced categories:
- Age: 0–19, 19–30, 31–45, 46–60, 60+, with a total of 105 samples.
- Gender: Male, Female, with a total of 100 samples.
- Ethnicity: Black, White, Asian, with a total of 100 samples.
- Language: English, Chinese, Arabic, Polish, German, Russian, French, Korean, Portuguese, Japanese, Thai, Spanish, Italian, Hindi, and Other languages, with a total of 195 samples.
Benchmark Results
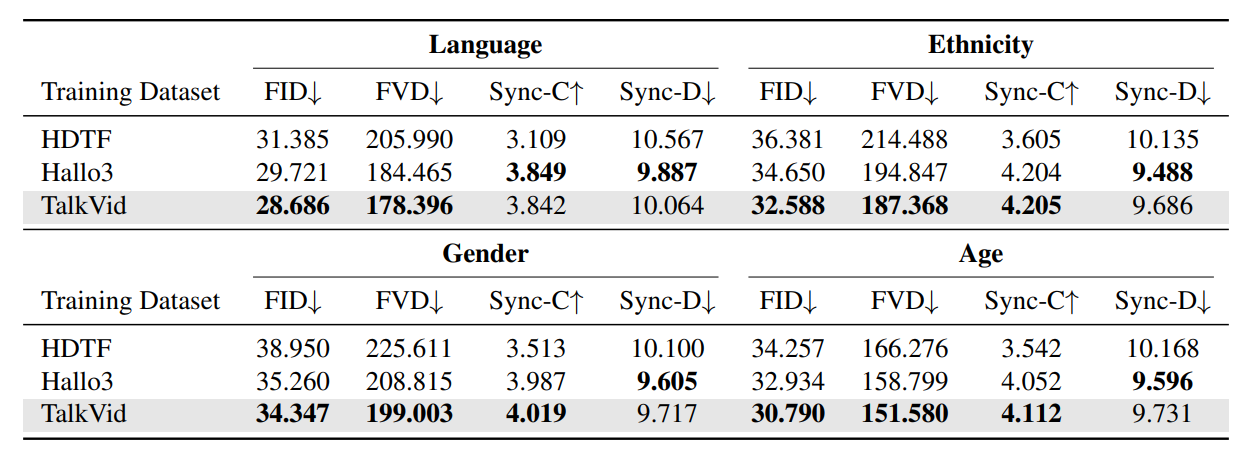
Comparison with other baseline training datasets, including HDTF and Hallo3 on TalkVid-bench across four dimensions in general.
🤝 Contributing
We welcome contributions to improve TalkVid! Here's how you can help:
How to Contribute
- Fork the repository and create your feature branch
- Follow our coding standards and add appropriate tests
- Update documentation for any new features
- Submit a pull request with detailed description
Areas for Contribution
- 🎨 Model improvements: New architectures, loss functions, training strategies
- 🔧 Data processing: Enhanced filtering, augmentation techniques
- 📊 Evaluation metrics: New benchmarks and evaluation protocols
- 🌐 Multi-language support: Extend to more languages and cultures
- ⚡ Optimization: Speed and memory improvements
❤️ Acknowledgments
We gratefully acknowledge the following projects and datasets that made TalkVid possible:
- V-Express: Foundation architecture and training framework
- Stable Diffusion: Diffusion model backbone
- InsightFace: Face detection and analysis tools
- DOVER: Video quality assessment
- CoTracker: Motion tracking and analysis
- Wav2Vec2: Audio feature extraction
- Open source community: All contributors and researchers advancing talking head synthesis
Special thanks to the V-Express team for providing excellent open-source infrastructure that enabled this work.
📚 Citation
If our work is helpful for your research, please consider giving a star ⭐ and citing our paper 📝
@misc{chen2025talkvidlargescalediversifieddataset,
      title={TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis},
      author={Shunian Chen and Hejin Huang and Yexin Liu and Zihan Ye and Pengcheng Chen and Chenghao Zhu and Michael Guan and Rongsheng Wang and Junying Chen and Guanbin Li and Ser-Nam Lim and Harry Yang and Benyou Wang},
      year={2025},
      eprint={2508.13618},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2508.13618},
}
📄 License
Dataset License
The TalkVid dataset is released under Creative Commons Attribution-NonCommercial 4.0 International License (CC BY-NC 4.0), allowing only non-commercial research use.
Code License
The source code is released under Apache License 2.0, allowing both academic and commercial use with proper attribution.
🌟 Star History


Significant stargazers

809 followers · starred Aug 2025

88 followers · starred Aug 2025
Similar repos


[CVPR 2026 Findings] TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis
See the codeREADME
TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis
🚀🚀🚀 Official implementation of TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis
-
Authors: Shunian Chen*, Hejin Huang*, Yexin Liu*, Zihan Ye, Pengcheng Chen, Chenghao Zhu, Michael Guan, Rongsheng Wang, Junying Chen, Guanbin Li, Ser-Nam Lim†, Harry Yang†, Benyou Wang†
-
Institutions: The Chinese University of Hong Kong, Shenzhen; Sun Yat-sen University; The Hong Kong University of Science and Technology
-
Resources: 📄Paper 🤗Dataset 🌐Project Page
💡 Highlights
- 🔥 Large-scale high-quality talking head dataset TalkVid with over 1,244 hours of HD/4K footage
- 🔥 Multimodal diversified content covering 15 languages and wide age ranges (0–60+ years)
- 🔥 Advanced data pipeline with comprehensive quality filtering and motion analysis
- 🔥 Full-body presence including upper-body visual context unlike previous datasets
- 🔥 Rich annotations with high-quality captions and comprehensive metadata
📜 News
[2026/06/06] 🎉 Our paper has been accepted by CVPR 2026 Findings!
[2025/08/19] 🚀 Our paper TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis is available!
[2025/08/19] 🚀 Released TalkVid dataset and training/inference code!
[2025/08/19] 🚀 Released comprehensive data processing pipeline including quality filtering and motion analysis tools!
📊 Dataset
TalkVid Dataset Overview
TalkVid is a large-scale and diversified open-source dataset for audio-driven talking head synthesis, featuring:
- Scale: 7,729 unique speakers with over 1,244 hours of HD/4K footage
- Diversity: Covers 15 languages and wide age range (0–60+ years)
- Quality: High-resolution videos (1080p & 2160p) with comprehensive quality filtering
- Rich Context: Full upper-body presence unlike head-only datasets
- Annotations: High-quality captions and comprehensive metadata
Download Link: 🤗 Hugging Face
More example videos can be found in our 🌐 Project Page.
📥 Data Download
To download video clips from YouTube using the TalkVid dataset:
# Use the JSON metadata from HuggingFace
cd data_pipeline/0_video_download
python download_clips.py --input input.json --output output --limit 50
For detailed instructions, see data_pipeline/0_video_download/README.md.
Data Format
{
    "id": "videovideoTr6MMsoWAog-scene1-scene1",
    "height": 1080,
    "width": 1920,
    "fps": 24.0,
    "start-time": 0.1,
    "start-frame": 0,
    "end-time": 5.141666666666667,
    "end-frame": 121,
    "durations": "5.042s",
    "info": {
        "Person ID": "597",
        "Ethnicity": "White",
        "Age Group": "60+",
        "Gender": "Male",
        "Video Link": "https://www.youtube.com/watch?v=Tr6MMsoWAog",
        "Language": "English",
        "Video Category": "Personal Experience"
    },
    "description": "The provided image sequence shows an older man in a suit, likely being interviewed or participating in a recorded conversation. He is seated and maintains a consistent, upright posture. Across the frames, his head rotates incrementally towards the camera's right, suggesting he is addressing someone off-screen in that direction. His facial expressions also show subtle shifts, likely related to speaking or reacting. No significant movements of the hands, arms, or torso are observed.  Because these are still images, any dynamic motion analysis is limited to inferring likely movements from the subtle positional changes between frames.",
    "dover_scores": 8.9,
    "cotracker_ratio": 0.9271857142448425,
    "head_detail": {
        "scores": {
            "avg_movement": 97.92236052453518,
            "min_movement": 89.4061028957367,
            "avg_rotation": 93.79223716779671,
            "min_rotation": 70.42514759667668,
            "avg_completeness": 100.0,
            "min_completeness": 100.0,
            "avg_resolution": 383.14267156972596,
            "min_resolution": 349.6849455656829,
            "avg_orientation": 80.29047955896623,
            "min_orientation": 73.27433271185937
        }
    }
}
Data Statistics
The dataset exhibits excellent diversity across multiple dimensions:
- Languages: English, Chinese, Arabic, Polish, German, Russian, French, Korean, Portuguese, Japanese, Thai, Spanish, Italian, Hindi
- Age Groups: 0–19, 19–30, 31–45, 46–60, 60+
- Video Quality: HD (1080p) and 4K (2160p) resolution with Dover score (mean ≈ 8.55), Cotracker ratio (mean ≈ 0.92), and head-detail scores concentrated in the 90–100 range
- Duration Distribution: Balanced segments from 3-30 seconds for optimal training
⚖️ Comparison with Other Datasets
TalkVid stands as the largest and most diverse open-source dataset for audio-driven talking-head generation to date.
| 🔍 Aspect | Description |
|---|---|
| 📈 Scale | 7,729 speakers, over 1,244 hours of HD/4K footage |
| 🌍 Diversity | Covers 15 languages and a wide age range (0–60+ years) |
| 🧍♀️ Upper-body presence | Unlike many prior datasets, TalkVid includes upper-body visual context |
| 📝 Rich Annotations | Comes with high-quality captions for every sample |
| 🏞️ In-the-wild quality | Entirely collected in real-world, unconstrained environments |
| 🎯 Quality Assurance | Multi-stage filtering with DOVER, CoTracker, and head quality assessment |
Compared to existing benchmarks such as GRID, VoxCeleb, MEAD, or MultiTalk, TalkVid is the first dataset to combine:
- Large-scale multilinguality across 15+ languages
- Wild setting with upper-body inclusion for more natural synthesis
- High-resolution (1080p & 2160p) video for detailed facial features
- Comprehensive metadata including age, language, quality scores, and captions
🧪 Want to push the boundaries of talking-head generation, personalization, or cross-lingual synthesis? TalkVid is your new go-to dataset.
🏗️ Data Filtering Pipeline
Our comprehensive data filtering pipeline ensures high-quality dataset construction:
1. Video Rough Segmentation
cd data_pipeline/1_video_rough_segmentation
conda env create -f datapipe.yaml
conda activate video-py310
bash rough_segementation.sh
2. Video Quality & Motion Filtering
cd data_pipeline/2_video_quality_motion_filtering

# Quality assessment using DOVER
bash video_quality_dover.sh

# Motion analysis using CoTracker
bash video_motion_cotracker.sh
3. Head Detail Filtering
cd data_pipeline/3_head_detail_filtering
conda env create -f env_head.yml
conda activate env_head
bash head_filter.sh
🚀 Quick Start
Environment Setup
# Create conda environment
conda create -n talkvid python=3.10 -y
conda activate talkvid

# Install dependencies
pip install -r requirements.txt

# Install additional dependencies for video processing
conda install -c conda-forge 'ffmpeg<7' -y
conda install torchaudio==2.4.0 pytorch-cuda=12.1 -c pytorch -c nvidia -y
Model Downloads
Before running inference, download the required model checkpoints:
# Download the model checkpoints
huggingface-cli download tk93/V-Express --local-dir V-Express
mv V-Express/model_ckpts model_ckpts
mv V-Express/*.bin model_ckpts/v-express
rm -rf V-Express/
Quick Inference
We provide an easy-to-use inference script for generating talking head videos.
Command Line Usage
# Single sample inference
bash scripts/inference.sh

# Or run directly with Python
cd src
python src/inference.py \
    --reference_image_path "./test_samples/short_case/tys/ref.jpg" \
    --audio_path "./test_samples/short_case/tys/aud.mp3" \
    --kps_path "./test_samples/short_case/tys/kps.pth" \
    --output_path "./output.mp4" \
    --retarget_strategy "naive_retarget" \
    --num_inference_steps 25 \
    --guidance_scale 3.5 \
    --context_frames 24
Key Parameters
--reference_image_path: Path to the reference portrait image--audio_path: Path to the driving audio file--kps_path: Path to keypoints file (can be generated automatically)--retarget_strategy: Keypoint retargeting strategy (fix_face,naive_retarget, etc.)--num_inference_steps: Number of denoising steps (trade-off between quality and speed)--context_frames: Number of context frames for temporal consistency
🏋️ Training
Data Preprocessing
Before training, preprocess your data:
cd src/data_preprocess
bash env.sh  # Setup preprocessing environment
# Follow data preprocessing instructions in data_preprocess/readme.md
Multi-Stage Training
Our model uses a progressive 3-stage training strategy:
# Stage 1: Basic motion learning
export STAGE=1 TRAIN="TalkVid-Core" GPU="0,1"
bash scripts/train.sh

# Stage 2: Audio-visual alignment
export STAGE=2 TRAIN="TalkVid-Core" GPU="0,1"
bash scripts/train.sh

# Stage 3: Temporal consistency and refinement
export STAGE=3 TRAIN="TalkVid-Core" GPU="0,1"
bash scripts/train.sh
Training Configuration
Key configuration files:
src/configs/stage_1.yaml: Basic motion and reference net trainingsrc/configs/stage_2.yaml: Audio projection and alignment trainingsrc/configs/stage_3.yaml: Full model with motion module training
Training supports:
- Multi-GPU training with DeepSpeed ZeRO-2
- Mixed precision (fp16/bf16) for memory efficiency
- Gradient checkpointing to reduce memory usage
- Flexible data loading with configurable batch sizes and augmentations
📊 Evaluation & Benchmarks
Evaluation Metrics
We evaluate our model on multiple aspects:
- Lip Synchronization: Sync-C, Sync-D,
- Perceptual Quality: FID, FVD
TalkVid-Bench
TalkVid-Bench comprises 500 carefully sampled and stratified video clips along four critical demographic and language dimensions: age, gender, ethnicity, and language. This stratified design enables granular analysis of model performance across diverse subgroups, mitigating biases hidden in traditional aggregate evaluations. Each dimension is divided into balanced categories:
- Age: 0–19, 19–30, 31–45, 46–60, 60+, with a total of 105 samples.
- Gender: Male, Female, with a total of 100 samples.
- Ethnicity: Black, White, Asian, with a total of 100 samples.
- Language: English, Chinese, Arabic, Polish, German, Russian, French, Korean, Portuguese, Japanese, Thai, Spanish, Italian, Hindi, and Other languages, with a total of 195 samples.
Benchmark Results
Comparison with other baseline training datasets, including HDTF and Hallo3 on TalkVid-bench across four dimensions in general.
🤝 Contributing
We welcome contributions to improve TalkVid! Here's how you can help:
How to Contribute
- Fork the repository and create your feature branch
- Follow our coding standards and add appropriate tests
- Update documentation for any new features
- Submit a pull request with detailed description
Areas for Contribution
- 🎨 Model improvements: New architectures, loss functions, training strategies
- 🔧 Data processing: Enhanced filtering, augmentation techniques
- 📊 Evaluation metrics: New benchmarks and evaluation protocols
- 🌐 Multi-language support: Extend to more languages and cultures
- ⚡ Optimization: Speed and memory improvements
❤️ Acknowledgments
We gratefully acknowledge the following projects and datasets that made TalkVid possible:
- V-Express: Foundation architecture and training framework
- Stable Diffusion: Diffusion model backbone
- InsightFace: Face detection and analysis tools
- DOVER: Video quality assessment
- CoTracker: Motion tracking and analysis
- Wav2Vec2: Audio feature extraction
- Open source community: All contributors and researchers advancing talking head synthesis
Special thanks to the V-Express team for providing excellent open-source infrastructure that enabled this work.
📚 Citation
If our work is helpful for your research, please consider giving a star ⭐ and citing our paper 📝
@misc{chen2025talkvidlargescalediversifieddataset,
      title={TalkVid: A Large-Scale Diversified Dataset for Audio-Driven Talking Head Synthesis},
      author={Shunian Chen and Hejin Huang and Yexin Liu and Zihan Ye and Pengcheng Chen and Chenghao Zhu and Michael Guan and Rongsheng Wang and Junying Chen and Guanbin Li and Ser-Nam Lim and Harry Yang and Benyou Wang},
      year={2025},
      eprint={2508.13618},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2508.13618},
}
📄 License
Dataset License
The TalkVid dataset is released under Creative Commons Attribution-NonCommercial 4.0 International License (CC BY-NC 4.0), allowing only non-commercial research use.
Code License
The source code is released under Apache License 2.0, allowing both academic and commercial use with proper attribution.
🌟 Star History
Similar repos
Significant stargazers
809 followers · starred Aug 2025
88 followers · starred Aug 2025