


Fork notice. This repository is a downstream fork of Tencent-Hunyuan/HY-Motion-1.0 maintained by FoxEngine.ai. All credit for the underlying model, training pipeline, and research belongs to the original Tencent Hunyuan 3D Digital Human Team.
This fork adds the production-shape glue we needed for live integrations (Voxta in particular): pip-installability, real-time frame streaming, motion continuation across clips, GGUF / 4-bit quantization paths, and Docker deployment. The core inference code is unchanged.
| Feature | What it does | Where to read more |
|---|---|---|
| Pip-installable | pip install git+... produces a usable library — assets bundled, paths resolved relative to package | this README |
| Real-time streaming | Generates motion frame-by-frame and streams to the UI as it goes, instead of holding everything until generation completes | STREAMING.md |
| Motion continuation | Use the last frames of one generation as the seed for the next — chain "walk → run → jump" without seam discontinuities | STREAMING.md |
| GGUF text encoder | Run Qwen3-8B as a 4 GB GGUF on CPU via llama-cpp-python instead of the full 16 GB safetensors download | DEPLOYMENT.md |
| 4-bit / 8-bit quantization | bitsandbytes-backed quantization for the prompter model + main motion encoder | DEPLOYMENT.md |
| REST API server | Headless inference endpoint (streaming_server.py) for embedding into other applications | STREAMING.md |
| Docker + Makefile | Reproducible builds for deployment, with make shortcuts for the common workflows | DEPLOYMENT.md |
pip install git+https://github.com/FoxEngine-ai/hy-motion-streaming.git
This installs the hymotion Python package along with its dependencies. The
wooden-mesh assets needed by WoodenMesh ship inside the wheel so no
auxiliary asset download is required for that path.
You still need to download the HY-Motion model checkpoint and the Qwen3-8B text encoder separately — they're large and not bundled with the package. See Model weights below.
For development:
git clone https://github.com/FoxEngine-ai/hy-motion-streaming.git
cd hy-motion-streaming
pip install -e .
from hymotion.utils.t2m_runtime import T2MRuntime

runtime = T2MRuntime(
    config_path="path/to/HY-Motion-1.0/config.yml",
    ckpt_name="latest.ckpt",                    # bare filename, resolved against config_path's dir
    device_ids=[0],                             # GPU ids; pass an empty list or use force_cpu=True for CPU
    use_gguf=True,                              # GGUF path for the Qwen text encoder (CPU-friendly)
    disable_prompt_engineering=True,            # skip the OpenAI-backed prompt rewriter
)

html, files, motion_dict = runtime.generate_motion(
    prompt="a person waving",
    duration_seconds=3.0,
    cfg_scale=5.0,
    seed=42,
)

# motion_dict carries rot6d, transl, keypoints3d for the generated frames
To override the text-encoder paths without editing code, set environment variables before starting the process:
export HYMOTION_QWEN_PATH=/path/to/your/Qwen3-8B-GGUF/
export HYMOTION_CLIP_PATH=openai/clip-vit-large-patch14   # or a local path
The HY-Motion checkpoint and Qwen3 / CLIP text encoders are downloaded separately:
| Asset | Source | Notes |
|---|---|---|
| HY-Motion-1.0 (1B) | HF: tencent/HY-Motion-1.0 | Standard model, ~45 GB |
| HY-Motion-1.0-Lite (0.46B) | HF: tencent/HY-Motion-1.0/HY-Motion-1.0-Lite | Lightweight variant |
| Qwen3-8B (full) | HF: Qwen/Qwen3-8B | 16 GB safetensors |
| Qwen3-8B (GGUF, 4-bit) | HF: unsloth/Qwen3-8B-GGUF | ~5 GB, runs on CPU via llama-cpp-python |
| CLIP ViT-L/14 | HF: openai/clip-vit-large-patch14 | Auto-downloaded by transformers if path is the hub ID |
See ckpts/README.md for the original Tencent download
instructions. Tools like huggingface-cli download work fine.
The remainder of this file is the upstream Tencent README, preserved verbatim — the model architecture, training pipeline, and research credits remain unchanged from Tencent's release.
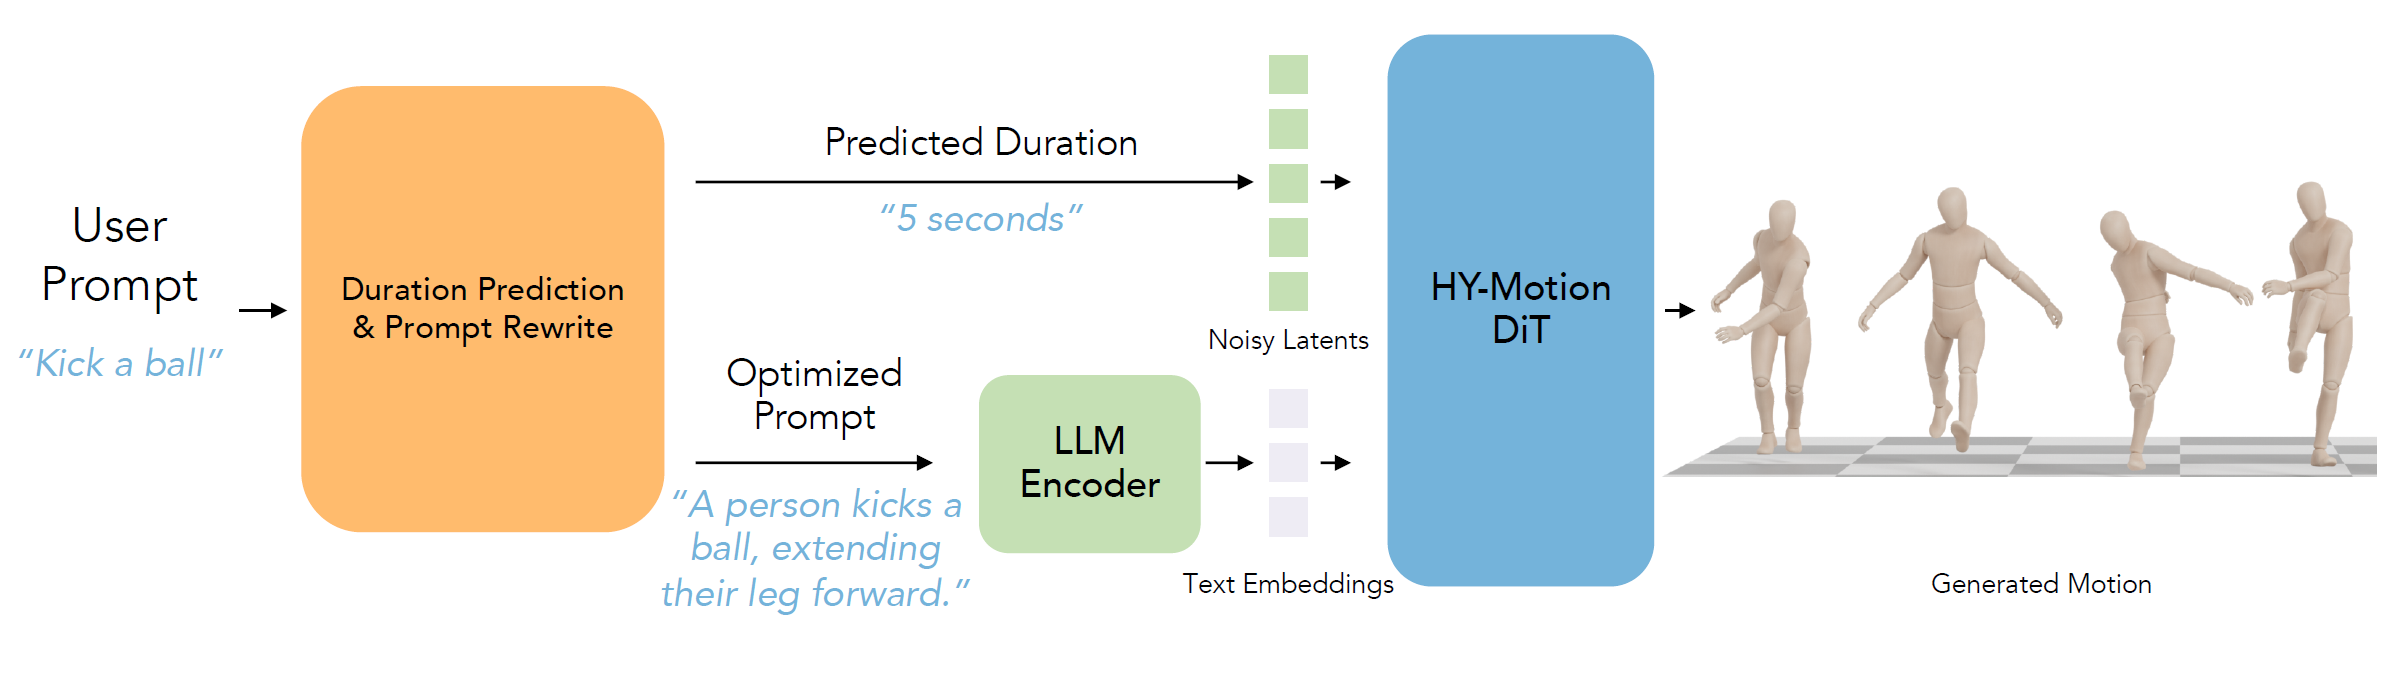
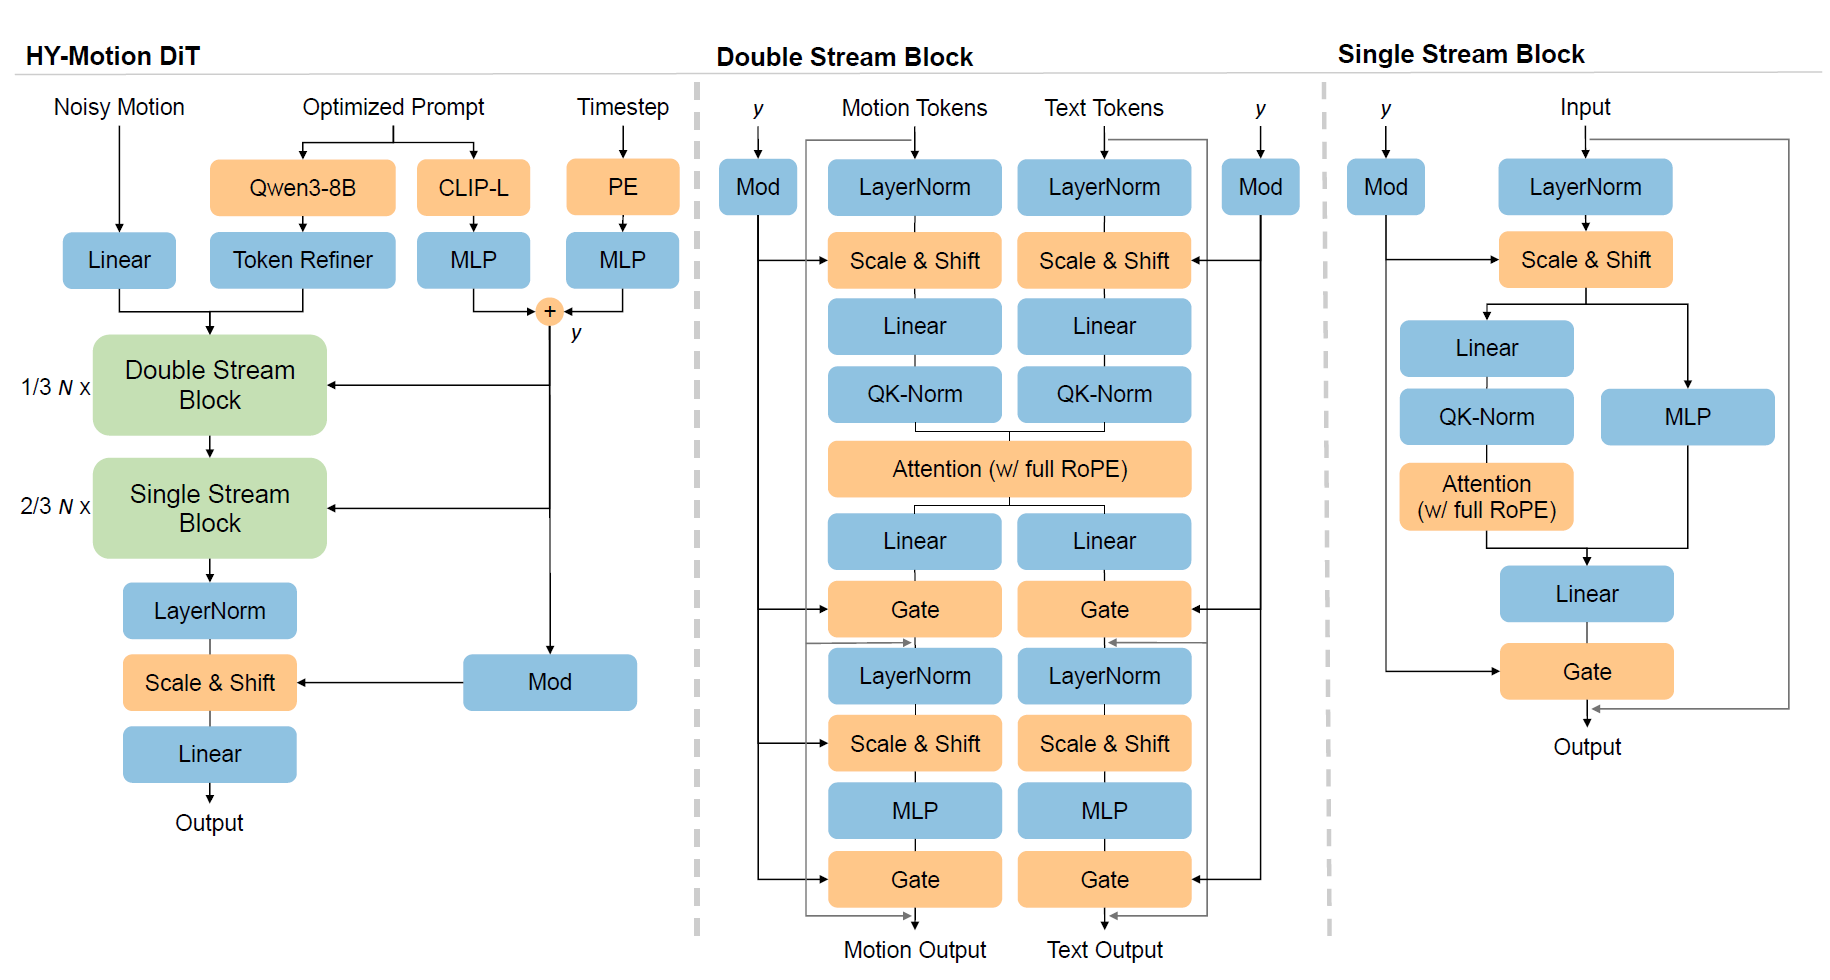
HY-Motion 1.0 is a series of text-to-3D human motion generation models based on Diffusion Transformer (DiT) and Flow Matching. It allows developers to generate skeleton-based 3D character animations from simple text prompts, which can be directly integrated into various 3D animation pipelines. This model series is the first to scale DiT-based text-to-motion models to the billion-parameter level, achieving significant improvements in instruction-following capabilities and motion quality over existing open-source models.
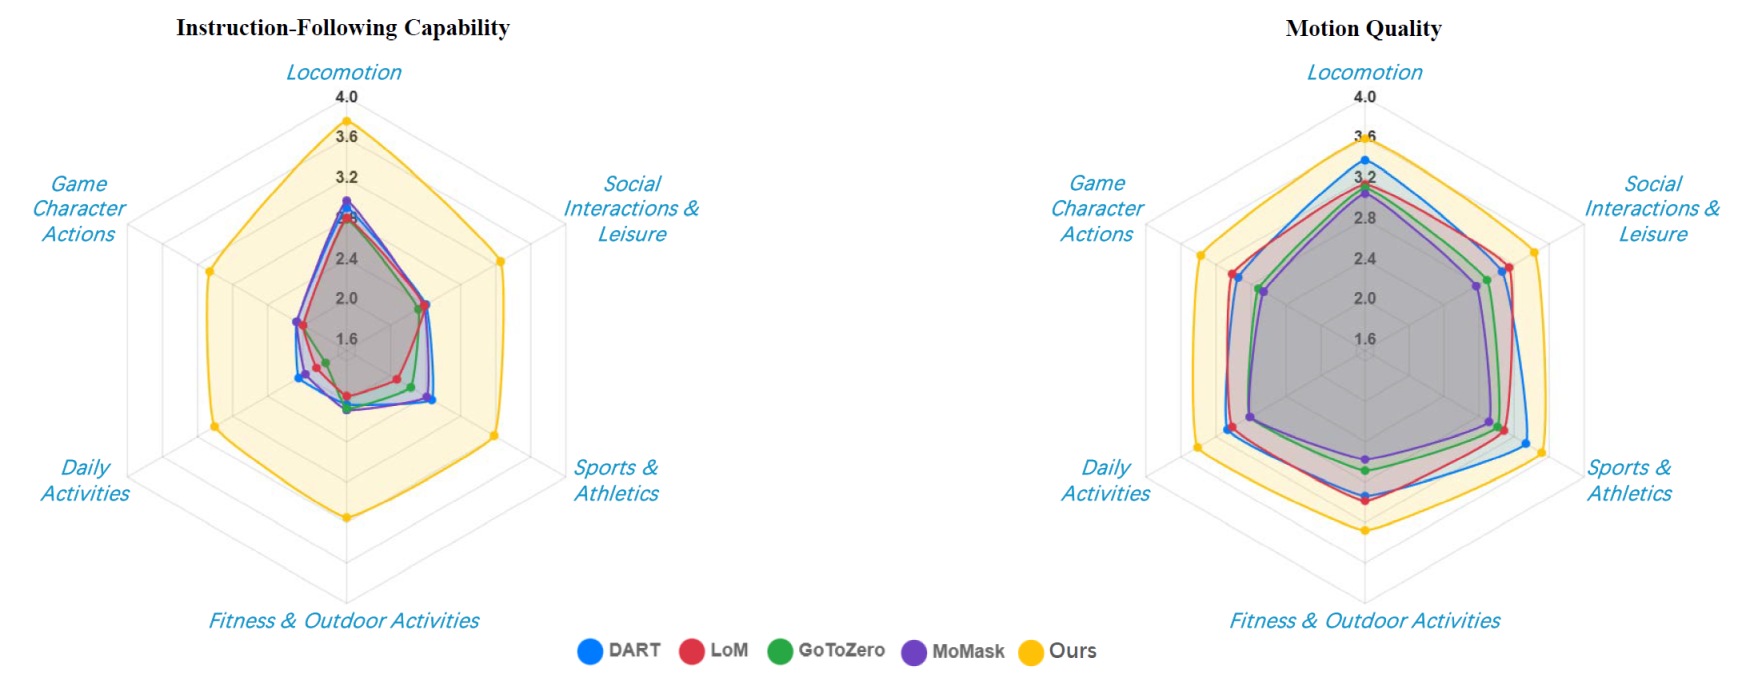
State-of-the-Art Performance: Achieves state-of-the-art performance in both instruction-following capability and generated motion quality.
Billion-Scale Models: We are the first to successfully scale DiT-based models to the billion-parameter level for text-to-motion generation. This results in superior instruction understanding and following capabilities, outperforming comparable open-source models.
Advanced Three-Stage Training: Our models are trained using a comprehensive three-stage process:
Large-Scale Pre-training: Trained on over 3,000 hours of diverse motion data to learn a broad motion prior.
High-Quality Fine-tuning: Fine-tuned on 400 hours of curated, high-quality 3D motion data to enhance motion detail and smoothness.
Reinforcement Learning: Utilizes Reinforcement Learning from human feedback and reward models to further refine instruction-following and motion naturalness.
HY-Motion 1.0 Series
| Model | Description | Date | Size | Huggingface |
|---|---|---|---|---|
| HY-Motion-1.0 | Standard Text to Motion Generation Model | 2025-12-30 | 1.0B | Download |
| HY-Motion-1.0-Lite | Lightweight Text to Motion Generation Model | 2025-12-30 | 0.46B | Download |
The instructions below run Tencent's original gradio demo from a source checkout. For library / pip-install usage, see Library usage further up. For streaming, REST API, or Docker deployment, see the dedicated guides linked at the top of this README.
HY-Motion 1.0 supports macOS, Windows, and Linux.
First, install PyTorch via the official site. Then install the dependencies:
pip install -r requirements.txt
Please follow the instructions in ckpts/README.md to download the necessary model weights.
We provide a script for local batch inference, suitable for processing large amounts of prompts.
# HY-Motion-1.0
python3 local_infer.py --model_path ckpts/tencent/HY-Motion-1.0

# HY-Motion-1.0-Lite
python3 local_infer.py --model_path ckpts/tencent/HY-Motion-1.0-Lite
Common Parameters:
--input_text_dir: Directory containing .txt or .json prompt files.--output_dir: Directory to save results (default: output/local_infer).--disable_duration_est: Disable LLM-based duration estimation.--disable_rewrite: Disable LLM-based prompt rewriting.--prompt_engineering_host / --prompt_engineering_model_path: (Optional) Host address / local checkpoint for the Duration Prediction & Prompt Rewrite Module.
--disable_duration_est and --disable_rewrite. Otherwise, the script will raise an error due to host unavailable.You can host a Gradio web interface on your local machine for interactive visualization:
python3 gradio_app.py
After running the command, open your browser and visit http://localhost:7860.
For the streaming variant of the gradio app added by this fork, see STREAMING.md.
If you found this repository helpful, please cite the upstream report:
@article{hymotion2025,
  title={HY-Motion 1.0: Scaling Flow Matching Models for Text-To-Motion Generation},
  author={Tencent Hunyuan 3D Digital Human Team},
  journal={arXiv preprint arXiv:2512.23464},
  year={2025}
}
We would like to thank the contributors to the FLUX, diffusers, HuggingFace, SMPL/SMPLH, CLIP, Qwen3, PyTorch3D, kornia, transforms3d, FBX-SDK, GVHMR, and HunyuanVideo repositories or tools, for their open research and exploration.
Fork notice. This repository is a downstream fork of Tencent-Hunyuan/HY-Motion-1.0 maintained by FoxEngine.ai. All credit for the underlying model, training pipeline, and research belongs to the original Tencent Hunyuan 3D Digital Human Team.
This fork adds the production-shape glue we needed for live integrations (Voxta in particular): pip-installability, real-time frame streaming, motion continuation across clips, GGUF / 4-bit quantization paths, and Docker deployment. The core inference code is unchanged.
| Feature | What it does | Where to read more |
|---|---|---|
| Pip-installable | pip install git+... produces a usable library — assets bundled, paths resolved relative to package | this README |
| Real-time streaming | Generates motion frame-by-frame and streams to the UI as it goes, instead of holding everything until generation completes | STREAMING.md |
| Motion continuation | Use the last frames of one generation as the seed for the next — chain "walk → run → jump" without seam discontinuities | STREAMING.md |
| GGUF text encoder | Run Qwen3-8B as a 4 GB GGUF on CPU via llama-cpp-python instead of the full 16 GB safetensors download | DEPLOYMENT.md |
| 4-bit / 8-bit quantization | bitsandbytes-backed quantization for the prompter model + main motion encoder | DEPLOYMENT.md |
| REST API server | Headless inference endpoint (streaming_server.py) for embedding into other applications | STREAMING.md |
| Docker + Makefile | Reproducible builds for deployment, with make shortcuts for the common workflows | DEPLOYMENT.md |
pip install git+https://github.com/FoxEngine-ai/hy-motion-streaming.git
This installs the hymotion Python package along with its dependencies. The
wooden-mesh assets needed by WoodenMesh ship inside the wheel so no
auxiliary asset download is required for that path.
You still need to download the HY-Motion model checkpoint and the Qwen3-8B text encoder separately — they're large and not bundled with the package. See Model weights below.
For development:
git clone https://github.com/FoxEngine-ai/hy-motion-streaming.git
cd hy-motion-streaming
pip install -e .
from hymotion.utils.t2m_runtime import T2MRuntime

runtime = T2MRuntime(
    config_path="path/to/HY-Motion-1.0/config.yml",
    ckpt_name="latest.ckpt",                    # bare filename, resolved against config_path's dir
    device_ids=[0],                             # GPU ids; pass an empty list or use force_cpu=True for CPU
    use_gguf=True,                              # GGUF path for the Qwen text encoder (CPU-friendly)
    disable_prompt_engineering=True,            # skip the OpenAI-backed prompt rewriter
)

html, files, motion_dict = runtime.generate_motion(
    prompt="a person waving",
    duration_seconds=3.0,
    cfg_scale=5.0,
    seed=42,
)

# motion_dict carries rot6d, transl, keypoints3d for the generated frames
To override the text-encoder paths without editing code, set environment variables before starting the process:
export HYMOTION_QWEN_PATH=/path/to/your/Qwen3-8B-GGUF/
export HYMOTION_CLIP_PATH=openai/clip-vit-large-patch14   # or a local path
The HY-Motion checkpoint and Qwen3 / CLIP text encoders are downloaded separately:
| Asset | Source | Notes |
|---|---|---|
| HY-Motion-1.0 (1B) | HF: tencent/HY-Motion-1.0 | Standard model, ~45 GB |
| HY-Motion-1.0-Lite (0.46B) | HF: tencent/HY-Motion-1.0/HY-Motion-1.0-Lite | Lightweight variant |
| Qwen3-8B (full) | HF: Qwen/Qwen3-8B | 16 GB safetensors |
| Qwen3-8B (GGUF, 4-bit) | HF: unsloth/Qwen3-8B-GGUF | ~5 GB, runs on CPU via llama-cpp-python |
| CLIP ViT-L/14 | HF: openai/clip-vit-large-patch14 | Auto-downloaded by transformers if path is the hub ID |
See ckpts/README.md for the original Tencent download
instructions. Tools like huggingface-cli download work fine.
The remainder of this file is the upstream Tencent README, preserved verbatim — the model architecture, training pipeline, and research credits remain unchanged from Tencent's release.
HY-Motion 1.0 is a series of text-to-3D human motion generation models based on Diffusion Transformer (DiT) and Flow Matching. It allows developers to generate skeleton-based 3D character animations from simple text prompts, which can be directly integrated into various 3D animation pipelines. This model series is the first to scale DiT-based text-to-motion models to the billion-parameter level, achieving significant improvements in instruction-following capabilities and motion quality over existing open-source models.
State-of-the-Art Performance: Achieves state-of-the-art performance in both instruction-following capability and generated motion quality.
Billion-Scale Models: We are the first to successfully scale DiT-based models to the billion-parameter level for text-to-motion generation. This results in superior instruction understanding and following capabilities, outperforming comparable open-source models.
Advanced Three-Stage Training: Our models are trained using a comprehensive three-stage process:
Large-Scale Pre-training: Trained on over 3,000 hours of diverse motion data to learn a broad motion prior.
High-Quality Fine-tuning: Fine-tuned on 400 hours of curated, high-quality 3D motion data to enhance motion detail and smoothness.
Reinforcement Learning: Utilizes Reinforcement Learning from human feedback and reward models to further refine instruction-following and motion naturalness.
HY-Motion 1.0 Series
| Model | Description | Date | Size | Huggingface |
|---|---|---|---|---|
| HY-Motion-1.0 | Standard Text to Motion Generation Model | 2025-12-30 | 1.0B | Download |
| HY-Motion-1.0-Lite | Lightweight Text to Motion Generation Model | 2025-12-30 | 0.46B | Download |
The instructions below run Tencent's original gradio demo from a source checkout. For library / pip-install usage, see Library usage further up. For streaming, REST API, or Docker deployment, see the dedicated guides linked at the top of this README.
HY-Motion 1.0 supports macOS, Windows, and Linux.
First, install PyTorch via the official site. Then install the dependencies:
pip install -r requirements.txt
Please follow the instructions in ckpts/README.md to download the necessary model weights.
We provide a script for local batch inference, suitable for processing large amounts of prompts.
# HY-Motion-1.0
python3 local_infer.py --model_path ckpts/tencent/HY-Motion-1.0

# HY-Motion-1.0-Lite
python3 local_infer.py --model_path ckpts/tencent/HY-Motion-1.0-Lite
Common Parameters:
--input_text_dir: Directory containing .txt or .json prompt files.--output_dir: Directory to save results (default: output/local_infer).--disable_duration_est: Disable LLM-based duration estimation.--disable_rewrite: Disable LLM-based prompt rewriting.--prompt_engineering_host / --prompt_engineering_model_path: (Optional) Host address / local checkpoint for the Duration Prediction & Prompt Rewrite Module.
--disable_duration_est and --disable_rewrite. Otherwise, the script will raise an error due to host unavailable.You can host a Gradio web interface on your local machine for interactive visualization:
python3 gradio_app.py
After running the command, open your browser and visit http://localhost:7860.
For the streaming variant of the gradio app added by this fork, see STREAMING.md.
If you found this repository helpful, please cite the upstream report:
@article{hymotion2025,
  title={HY-Motion 1.0: Scaling Flow Matching Models for Text-To-Motion Generation},
  author={Tencent Hunyuan 3D Digital Human Team},
  journal={arXiv preprint arXiv:2512.23464},
  year={2025}
}
We would like to thank the contributors to the FLUX, diffusers, HuggingFace, SMPL/SMPLH, CLIP, Qwen3, PyTorch3D, kornia, transforms3d, FBX-SDK, GVHMR, and HunyuanVideo repositories or tools, for their open research and exploration.






