A lightweight JAX/Flax inference engine and PyTorch-to-JAX weight translator for video generative models.
Python
21
48 commits
updated Sep 24, 2026
Documentation | arXiv | Blog | Benchmark | Gallery


vidax is a lightweight JAX/Flax inference engine and
PyTorch-to-JAX weight translator for modern Video Diffusion Transformers
(DiTs) and beyond. Built for Google Cloud TPUs, it
eliminates framework overhead with clean, explicit PyTree architectures and
native multi-chip parallelism (Megatron tensor parallelism and
DeepSpeed-Ulysses sequence parallelism) across architecturally distinct
model families.
jax.sharding device meshes, a real Pallas
flash-attention kernel (not jax.nn's materializing default), and a
custom scan/vmap-based windowed neighborhood-attention kernel where no
native TPU kernel exists..safetensors/.pth
checkpoints straight into Flax pytrees — key mappings and layout
transpositions handled automatically, verified against every model via
exact 1:1 parameter-tree matches.docs/hardware_and_sharding.md.--offload_dit_weights keeps a DiT's
weights host-resident and streams one --offload_chunk_size-block group
into HBM at a time, extending every model's reach to resolutions/frame
counts that don't fit fully device-resident on a given chip count — see
docs/weight_offloading.md.Current tested TPU types: v4 | v7
Rows are merged across tasks when one script/checkpoint handles all of them (e.g. Wan2.2 TI2V-5B, Cosmos-Predict2.5); kept separate when the reference ships them as genuinely distinct checkpoints/pipelines (e.g. Wan2.1's T2V vs. I2V, Wan2.2's A14B).
| Model Family | Variant | Task | TPU test | Guide | Weights |
|---|---|---|---|---|---|
| Cosmos3 | Nano (16B) | T2V/I2V | ✅ | cosmos3.md | 🤗Link |
| Cosmos3 | Edge (4B) | T2V/I2V | ✅ | cosmos3.md | 🤗Link |
| Cosmos-Predict2.5 | 14B | T2V/I2V/V2V | ✅ | cosmos2_5.md | 🤗Link |
| Cosmos-Predict2.5 | 2B | T2V/I2V/V2V | ✅ | cosmos2_5.md | 🤗Link |
| Wan2.2 | A14B | T2V | ✅ | wan2_2.md | 🤗Link |
| Wan2.2 | A14B | I2V | ✅ | wan2_2.md | 🤗Link |
| Wan2.2 | 5B | T2V/I2V | ✅ | wan2_2.md | 🤗Link |
| Wan2.1 | 14B | T2V | ✅ | wan2_1.md | 🤗Link |
| Wan2.1 | 14B (720P) | I2V | ✅ | wan2_1.md | 🤗Link |
| Wan2.1 | 14B (480P) | I2V | ✅ | wan2_1.md | 🤗Link |
| Wan2.1 | 1.3B | T2V | ✅ | wan2_1.md | 🤗Link |
| LTX-2.5 | 22B (dev) | T2V/I2V | ✅ | ltx2_5.md | 🤗Link |
| LTX-2.5 | 22B (distilled) | T2V/I2V | ✅ | ltx2_5.md | 🤗Link |
| LTX-Video (0.9.8) | 13B (dev) | T2V/I2V | ✅ | ltx_video.md | 🤗Link |
| LTX-Video (0.9.8) | 13B (distilled) | T2V/I2V | ✅ | ltx_video.md | 🤗Link |
| LTX-Video (0.9.8) | 2B (distilled) | T2V/I2V | ✅ | ltx_video.md | 🤗Link |
| HunyuanVideo-1.5 | 8.3B | T2V/I2V | ✅ | hunyuan_video1_5.md | 🤗Link |
| HunyuanVideo | 13B | T2V/I2V | ✅ | hunyuan_video.md | 🤗Link |
| CogVideoX1.5 | 5B | I2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX1.5 | 5B | T2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX | 5B | T2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX | 5B | I2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX | 2B | T2V | ✅ | cogvideox.md | 🤗Link |
Per-model checkpoint sources, CLI flags, and architecture notes live in
each Guide link above. Measured latency/memory numbers for every row
above live in docs/benchmarking.md.
# Clone and install (editable). On a Cloud TPU VM add the "tpu" extra for the
# right jaxlib wheel: pip install -e ".[tpu]"
git clone https://github.com/FlyingGiraffe/vidax.git
cd vidax
pip install -e .

# Generate a video (Wan2.1 T2V, 1.3B)
python examples/generate_wan2_1_t2v.py \
  --dit_checkpoint_path "./checkpoints/Wan2.1-T2V-1.3B/diffusion_pytorch_model.safetensors" \
  --vae_checkpoint_path "./checkpoints/Wan2.1-T2V-1.3B/Wan2.1_VAE.pth" \
  --t5_checkpoint_path "./checkpoints/Wan2.1-T2V-1.3B/models_t5_umt5-xxl-enc-bf16.pth" \
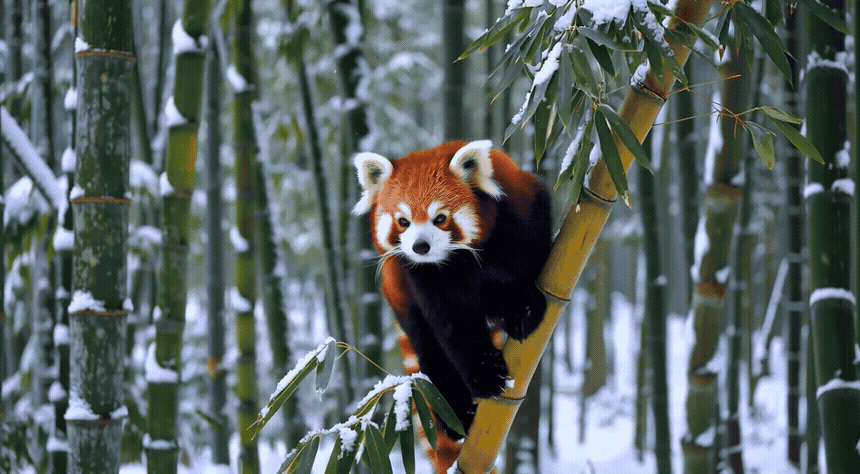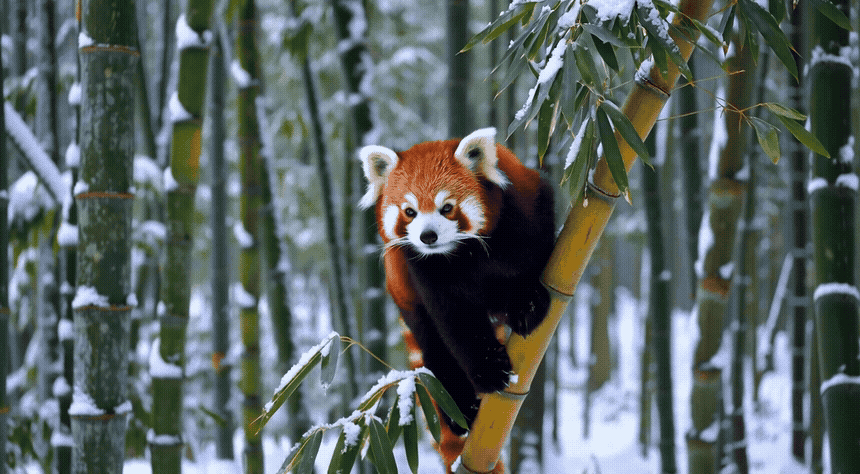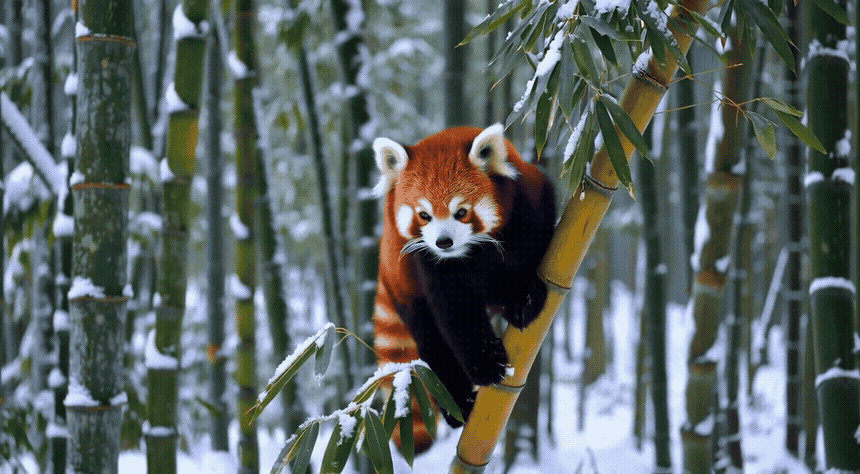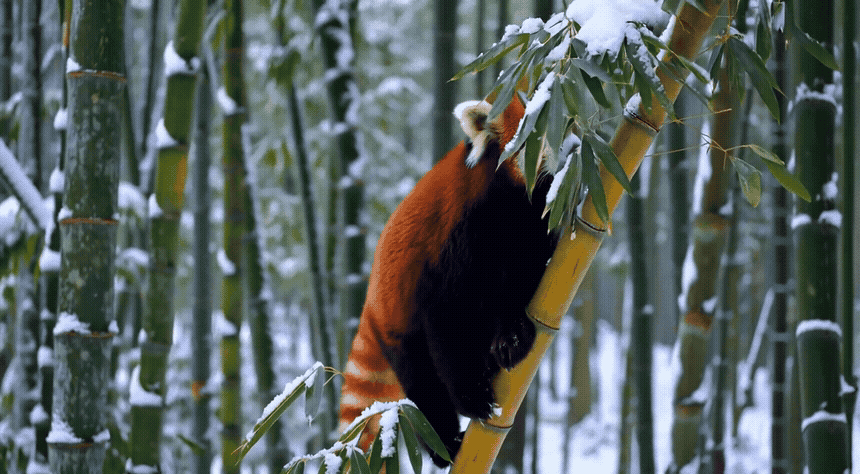
  --prompt "A majestic red panda climbing a bamboo tree in the snow, 4k" \
  --num_steps 50 \
  --output_path "out/output.mp4"
Beyond the examples/ scripts, vidax is usable as a library — reuse the
Pallas flash-attention kernel, the diffusion schedulers, the PyTorch→JAX
translator, or a model's DiT/VAE modules directly:
from vidax.core import dot_product_attention, build_tpu_mesh
from vidax.schedulers import RectifiedFlowScheduler
from vidax.translator import load_torch_checkpoint_to_jax

params = load_torch_checkpoint_to_jax("model.safetensors", model_type="wan_dit")
out = dot_product_attention(q, k, v)          # real O(seq)-memory flash attn on TPU
See docs/library_usage.md for worked examples
(standalone attention, schedulers, checkpoint translation, and a full model),
and docs/api/ for the full per-function API reference.
Standard Python src-layout: one subpackage per model family under
models/, one usage guide per family under docs/models/, one standalone
inference script per family/task under examples/. See
docs/directory_layout.md for the full tree, and
docs/index.md for the documentation map.
vidax's source code is released under the Apache License 2.0,
except for the JAX re-implementations of HunyuanVideo,
HunyuanVideo-1.5 and LTX-2.5. Those were written with reference to
upstream code released under the Tencent Hunyuan Community License and the
LTX-2.x Community License respectively, and use of those modules is
additionally subject to those licenses — which are not permissive
open-source licenses (they carry territorial restrictions and acceptable-use /
commercial-scale conditions). The affected paths are listed in
NOTICE, with a LICENSE file in each affected directory. If you
can't accept those terms, don't use those modules; the rest of vidax remains
available to you under Apache 2.0.
No model weights are included. Every checkpoint is governed by its own
license (the License column below is each model's weights license — the
upstream source-code licenses that govern vidax's re-implementations are in
NOTICE). You are responsible for complying with the license of any
weights you download.
| Model | Developer | Code | Report | Weights | License |
|---|---|---|---|---|---|
| Wan2.2 | Alibaba (Wan team) | code | report | weights | Apache 2.0 |
| Wan2.1 | Alibaba (Wan team) | code | report | weights | Apache 2.0 |
| Cosmos 3 | NVIDIA | code | report | weights | OpenMDW-1.1 |
| Cosmos-Predict2.5 | NVIDIA | code | report | weights | NVIDIA Open Model License |
| LTX-2.5 | Lightricks | code | report | weights | LTX-2.x Community License |
| LTX-Video (0.9.8) | Lightricks | code | report | weights | LTX-Video Open Weights License |
| HunyuanVideo-1.5 | Tencent | code | report | weights | Tencent Hunyuan Community License |
| HunyuanVideo | Tencent | code | report | weights | Tencent Hunyuan Community License |
| CogVideoX / 1.5 | THUDM / ZhipuAI | code | report | weights | CogVideoX License |
Parallelism techniques implemented in this repo:
See docs/hardware_and_sharding.md for how
both are implemented here.
This project is supported by the Google TPU Research Cloud (TRC) program.
A lightweight JAX/Flax inference engine and PyTorch-to-JAX weight translator for video generative models.
Python
21
48 commits
updated Sep 24, 2026
Documentation | arXiv | Blog | Benchmark | Gallery
vidax is a lightweight JAX/Flax inference engine and
PyTorch-to-JAX weight translator for modern Video Diffusion Transformers
(DiTs) and beyond. Built for Google Cloud TPUs, it
eliminates framework overhead with clean, explicit PyTree architectures and
native multi-chip parallelism (Megatron tensor parallelism and
DeepSpeed-Ulysses sequence parallelism) across architecturally distinct
model families.
jax.sharding device meshes, a real Pallas
flash-attention kernel (not jax.nn's materializing default), and a
custom scan/vmap-based windowed neighborhood-attention kernel where no
native TPU kernel exists..safetensors/.pth
checkpoints straight into Flax pytrees — key mappings and layout
transpositions handled automatically, verified against every model via
exact 1:1 parameter-tree matches.docs/hardware_and_sharding.md.--offload_dit_weights keeps a DiT's
weights host-resident and streams one --offload_chunk_size-block group
into HBM at a time, extending every model's reach to resolutions/frame
counts that don't fit fully device-resident on a given chip count — see
docs/weight_offloading.md.Current tested TPU types: v4 | v7
Rows are merged across tasks when one script/checkpoint handles all of them (e.g. Wan2.2 TI2V-5B, Cosmos-Predict2.5); kept separate when the reference ships them as genuinely distinct checkpoints/pipelines (e.g. Wan2.1's T2V vs. I2V, Wan2.2's A14B).
| Model Family | Variant | Task | TPU test | Guide | Weights |
|---|---|---|---|---|---|
| Cosmos3 | Nano (16B) | T2V/I2V | ✅ | cosmos3.md | 🤗Link |
| Cosmos3 | Edge (4B) | T2V/I2V | ✅ | cosmos3.md | 🤗Link |
| Cosmos-Predict2.5 | 14B | T2V/I2V/V2V | ✅ | cosmos2_5.md | 🤗Link |
| Cosmos-Predict2.5 | 2B | T2V/I2V/V2V | ✅ | cosmos2_5.md | 🤗Link |
| Wan2.2 | A14B | T2V | ✅ | wan2_2.md | 🤗Link |
| Wan2.2 | A14B | I2V | ✅ | wan2_2.md | 🤗Link |
| Wan2.2 | 5B | T2V/I2V | ✅ | wan2_2.md | 🤗Link |
| Wan2.1 | 14B | T2V | ✅ | wan2_1.md | 🤗Link |
| Wan2.1 | 14B (720P) | I2V | ✅ | wan2_1.md | 🤗Link |
| Wan2.1 | 14B (480P) | I2V | ✅ | wan2_1.md | 🤗Link |
| Wan2.1 | 1.3B | T2V | ✅ | wan2_1.md | 🤗Link |
| LTX-2.5 | 22B (dev) | T2V/I2V | ✅ | ltx2_5.md | 🤗Link |
| LTX-2.5 | 22B (distilled) | T2V/I2V | ✅ | ltx2_5.md | 🤗Link |
| LTX-Video (0.9.8) | 13B (dev) | T2V/I2V | ✅ | ltx_video.md | 🤗Link |
| LTX-Video (0.9.8) | 13B (distilled) | T2V/I2V | ✅ | ltx_video.md | 🤗Link |
| LTX-Video (0.9.8) | 2B (distilled) | T2V/I2V | ✅ | ltx_video.md | 🤗Link |
| HunyuanVideo-1.5 | 8.3B | T2V/I2V | ✅ | hunyuan_video1_5.md | 🤗Link |
| HunyuanVideo | 13B | T2V/I2V | ✅ | hunyuan_video.md | 🤗Link |
| CogVideoX1.5 | 5B | I2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX1.5 | 5B | T2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX | 5B | T2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX | 5B | I2V | ✅ | cogvideox.md | 🤗Link |
| CogVideoX | 2B | T2V | ✅ | cogvideox.md | 🤗Link |
Per-model checkpoint sources, CLI flags, and architecture notes live in
each Guide link above. Measured latency/memory numbers for every row
above live in docs/benchmarking.md.
# Clone and install (editable). On a Cloud TPU VM add the "tpu" extra for the
# right jaxlib wheel: pip install -e ".[tpu]"
git clone https://github.com/FlyingGiraffe/vidax.git
cd vidax
pip install -e .

# Generate a video (Wan2.1 T2V, 1.3B)
python examples/generate_wan2_1_t2v.py \
  --dit_checkpoint_path "./checkpoints/Wan2.1-T2V-1.3B/diffusion_pytorch_model.safetensors" \
  --vae_checkpoint_path "./checkpoints/Wan2.1-T2V-1.3B/Wan2.1_VAE.pth" \
  --t5_checkpoint_path "./checkpoints/Wan2.1-T2V-1.3B/models_t5_umt5-xxl-enc-bf16.pth" \
  --prompt "A majestic red panda climbing a bamboo tree in the snow, 4k" \
  --num_steps 50 \
  --output_path "out/output.mp4"
Beyond the examples/ scripts, vidax is usable as a library — reuse the
Pallas flash-attention kernel, the diffusion schedulers, the PyTorch→JAX
translator, or a model's DiT/VAE modules directly:
from vidax.core import dot_product_attention, build_tpu_mesh
from vidax.schedulers import RectifiedFlowScheduler
from vidax.translator import load_torch_checkpoint_to_jax

params = load_torch_checkpoint_to_jax("model.safetensors", model_type="wan_dit")
out = dot_product_attention(q, k, v)          # real O(seq)-memory flash attn on TPU
See docs/library_usage.md for worked examples
(standalone attention, schedulers, checkpoint translation, and a full model),
and docs/api/ for the full per-function API reference.
Standard Python src-layout: one subpackage per model family under
models/, one usage guide per family under docs/models/, one standalone
inference script per family/task under examples/. See
docs/directory_layout.md for the full tree, and
docs/index.md for the documentation map.
vidax's source code is released under the Apache License 2.0,
except for the JAX re-implementations of HunyuanVideo,
HunyuanVideo-1.5 and LTX-2.5. Those were written with reference to
upstream code released under the Tencent Hunyuan Community License and the
LTX-2.x Community License respectively, and use of those modules is
additionally subject to those licenses — which are not permissive
open-source licenses (they carry territorial restrictions and acceptable-use /
commercial-scale conditions). The affected paths are listed in
NOTICE, with a LICENSE file in each affected directory. If you
can't accept those terms, don't use those modules; the rest of vidax remains
available to you under Apache 2.0.
No model weights are included. Every checkpoint is governed by its own
license (the License column below is each model's weights license — the
upstream source-code licenses that govern vidax's re-implementations are in
NOTICE). You are responsible for complying with the license of any
weights you download.
| Model | Developer | Code | Report | Weights | License |
|---|---|---|---|---|---|
| Wan2.2 | Alibaba (Wan team) | code | report | weights | Apache 2.0 |
| Wan2.1 | Alibaba (Wan team) | code | report | weights | Apache 2.0 |
| Cosmos 3 | NVIDIA | code | report | weights | OpenMDW-1.1 |
| Cosmos-Predict2.5 | NVIDIA | code | report | weights | NVIDIA Open Model License |
| LTX-2.5 | Lightricks | code | report | weights | LTX-2.x Community License |
| LTX-Video (0.9.8) | Lightricks | code | report | weights | LTX-Video Open Weights License |
| HunyuanVideo-1.5 | Tencent | code | report | weights | Tencent Hunyuan Community License |
| HunyuanVideo | Tencent | code | report | weights | Tencent Hunyuan Community License |
| CogVideoX / 1.5 | THUDM / ZhipuAI | code | report | weights | CogVideoX License |
Parallelism techniques implemented in this repo:
See docs/hardware_and_sharding.md for how
both are implemented here.
This project is supported by the Google TPU Research Cloud (TRC) program.



