An open-source tool based on the Nougat-LaTeX-OCR model, designed to automatically convert PDF files to DOCX format. It retains the information from the original files and converts all equations to LaTeX format representation.
Python
0
14 commits
updated Aug 6, 2024
Setup venv:
python3.11 -m venv .venv
source .venv/bin/activate
Install requirements:
python.exe -m pip install --upgrade pip

pip install --upgrade pip -i https://pypi.tuna.tsinghua.edu.cn/simple
pip install -r requirements.txt -i https://pypi.tuna.tsinghua.edu.cn/simple
pip install -r requirements.txt --upgrade
Test Cuda (optional):
nvidia-smi
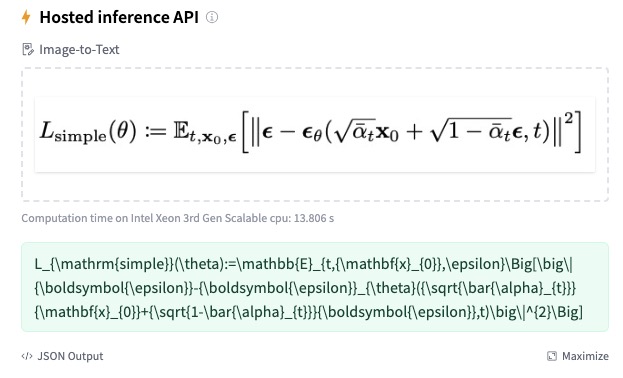
Nougat-LaTeX-based is fine-tuned from facebook/nougat-base with im2latex-100k to boost its proficiency in generating LaTeX code from images. Since the initial encoder input image size of nougat was unsuitable for equation image segments, leading to potential rescaling artifacts that degrades the generation quality of LaTeX code. To address this, Nougat-LaTeX-based adjusts the input resolution and uses an adaptive padding approach to ensure that equation image segments in the wild are resized to closely match the resolution of the training data. Download the model here 👈🏻.
config/base.yamlpython tools/train_experiment.py --config_file config/base.yaml --phase 'train'
from transformers import pipeline
pipe = pipeline("image-to-text", model="Norm/nougat-latex-base")
from transformers import AutoTokenizer, AutoModel
tokenizer = AutoTokenizer.from_pretrained("Norm/nougat-latex-base")
model = AutoModel.from_pretrained("Norm/nougat-latex-base")
Check the model application information in https://huggingface.co/Norm/nougat-latex-base You can find an example in examples_for_latex folder
python examples/run_latex_ocr.py --img_path "examples/test_data/eq1.png"
An open-source tool based on the Nougat-LaTeX-OCR model, designed to automatically convert PDF files to DOCX format. It retains the information from the original files and converts all equations to LaTeX format representation.
Python
0
14 commits
updated Aug 6, 2024
Setup venv:
python3.11 -m venv .venv
source .venv/bin/activate
Install requirements:
python.exe -m pip install --upgrade pip

pip install --upgrade pip -i https://pypi.tuna.tsinghua.edu.cn/simple
pip install -r requirements.txt -i https://pypi.tuna.tsinghua.edu.cn/simple
pip install -r requirements.txt --upgrade
Test Cuda (optional):
nvidia-smi
Nougat-LaTeX-based is fine-tuned from facebook/nougat-base with im2latex-100k to boost its proficiency in generating LaTeX code from images. Since the initial encoder input image size of nougat was unsuitable for equation image segments, leading to potential rescaling artifacts that degrades the generation quality of LaTeX code. To address this, Nougat-LaTeX-based adjusts the input resolution and uses an adaptive padding approach to ensure that equation image segments in the wild are resized to closely match the resolution of the training data. Download the model here 👈🏻.
config/base.yamlpython tools/train_experiment.py --config_file config/base.yaml --phase 'train'
from transformers import pipeline
pipe = pipeline("image-to-text", model="Norm/nougat-latex-base")
from transformers import AutoTokenizer, AutoModel
tokenizer = AutoTokenizer.from_pretrained("Norm/nougat-latex-base")
model = AutoModel.from_pretrained("Norm/nougat-latex-base")
Check the model application information in https://huggingface.co/Norm/nougat-latex-base You can find an example in examples_for_latex folder
python examples/run_latex_ocr.py --img_path "examples/test_data/eq1.png"



