[ICLR 2026] Astra : General Interactive World Model with Autoregressive Denoising"
Python
340
17 commits
updated Jun 9, 2026
 : General Interactive World Model with Autoregressive Denoising (ICLR 2026)
Yixuan Zhu1, Jiaqi Feng1, Wenzhao Zheng1 †, Yuan Gao2, Xin Tao2, Pengfei Wan2, Jie Zhou 1, Jiwen Lu1
(† Project leader)
1Tsinghua University, 2Kuaishou Technology.
TL;DR: Astra is an interactive world model that delivers realistic long-horizon video rollouts under a wide range of scenarios and action inputs.
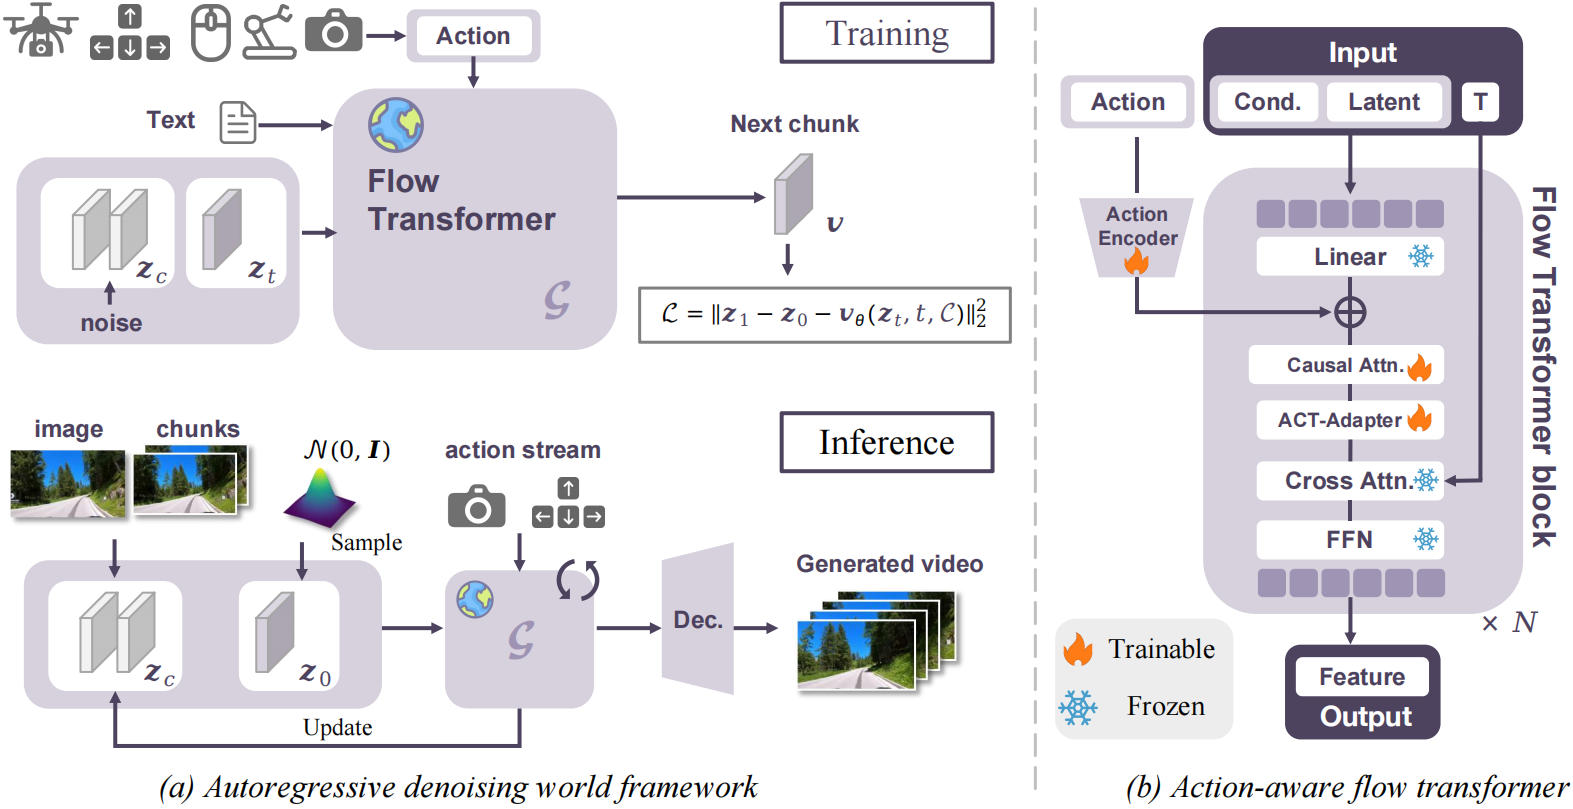
Astra is an interactive, action-driven world model that predicts long-horizon future videos across diverse real-world scenarios. Built on an autoregressive diffusion transformer with temporal causal attention, Astra supports streaming prediction while preserving strong temporal coherence. Astra introduces noise-augmented history memory to stabilize long rollouts, an action-aware adapter for precise control signals, and a mixture of action experts to route heterogeneous action modalities. Through these key innovations, Astra delivers consistent, controllable, and high-fidelity video futures for applications such as autonomous driving, robot manipulation, and camera motion.
Release dataset preprocessing tools
Release full inference pipelines for additional scenarios:
Open-source training scripts:
Provide unified evaluation toolkit
Astra is built upon Wan2.1-1.3B, a diffusion-based video generation model. We provide inference scripts to help you quickly generate videos from images and action inputs. Follow the steps below:
DiffSynth-Studio requires Rust and Cargo to compile extensions. You can install them using the following command:
curl --proto '=https' --tlsv1.2 -sSf [https://sh.rustup.rs](https://sh.rustup.rs/) | sh
. "$HOME/.cargo/env"
Install DiffSynth-Studio:
git clone https://github.com/EternalEvan/Astra.git
cd Astra
pip install -e .
cd script
python download_wan2.1.py
Please download from huggingface and place it in models/Astra/checkpoints.
python infer_demo.py \
  --dit_path ../models/Astra/checkpoints/diffusion_pytorch_model.ckpt \
  --wan_model_path ../models/Wan-AI/Wan2.1-T2V-1.3B \
  --condition_image ../examples/condition_images/garden_1.png \
  --cam_type 4 \
  --prompt "A sunlit European street lined with historic buildings and vibrant greenery creates a warm, charming, and inviting atmosphere. The scene shows a picturesque open square paved with red bricks, surrounded by classic narrow townhouses featuring tall windows, gabled roofs, and dark-painted facades. On the right side, a lush arrangement of potted plants and blooming flowers adds rich color and texture to the foreground. A vintage-style streetlamp stands prominently near the center-right, contributing to the timeless character of the street. Mature trees frame the background, their leaves glowing in the warm afternoon sunlight. Bicycles are visible along the edges of the buildings, reinforcing the urban yet leisurely feel. The sky is bright blue with scattered clouds, and soft sun flares enter the frame from the left, enhancing the scene’s inviting, peaceful mood."  \
  --output_path ../examples/output_videos/output_moe_framepack_sliding.mp4 \
This inference can be conducted on a single 24GB GPU, such as the NVIDIA 3090.
To test with your own custom images, you need to prepare the target images and their corresponding text prompts. We recommend that the size of the input images is close to 832×480 (width × height, 16:9), which is consistent with the resolution of the generated video and can help achieve better video generation effects. For prompts generation, you can refer to the Prompt Extension section in Wan2.1 for guidance on crafting the captions.
python infer_demo.py \
  --dit_path path/to/your/dit_ckpt \
  --wan_model_path path/to/your/Wan2.1-T2V-1.3B \
  --condition_image path/to/your/image \
  --cam_type your_cam_type \
  --prompt your_prompt \
  --output_path path/to/your/output_video
We provide several preset camera types, as shown in the table below. Additionally, you can generate new trajectories for testing.
| cam_type | Trajectory |
|---|---|
| 1 | Move Forward (Straight) |
| 2 | Rotate Left In Place |
| 3 | Rotate Right In Place |
| 4 | Move Forward + Rotate Left |
| 5 | Move Forward + Rotate Right |
| 6 | S-shaped Trajectory |
| 7 | Rotate Left → Rotate Right |
To facilitate joint training across large-scale open-source datasets, we implement a preprocessing pipeline designed for maximum training efficiency. This process involves three key steps:
This preprocessing stage must be completed prior to starting the training loop. You can find the implementation scripts and detailed usage instructions in the ./data directory.
Once the data is preprocessed, you can initiate training on a specific dataset. This stage allows for initial model validation or fine-tuning on a targeted domain.
Execute the training script using the following command:
python train_single.py
The training requires about 60G GPU memory.
--max_condition_frames can be shortened to reduce VRAM consumption and computational costs.Looking ahead, we plan to further enhance Astra in several directions:
These directions aim to push Astra towards more robust and interactive video world modeling.
Feel free to explore these outstanding related works, including but not limited to:
ReCamMaster: ReCamMaster re-captures in-the-wild videos with novel camera trajectories.
GCD: GCD synthesizes large-angle novel viewpoints of 4D dynamic scenes from a monocular video.
ReCapture: a method for generating new videos with novel camera trajectories from a single user-provided video.
Trajectory Attention: Trajectory Attention facilitates various tasks like camera motion control on images and videos, and video editing.
GS-DiT: GS-DiT provides 4D video control for a single monocular video.
Diffusion as Shader: a versatile video generation control model for various tasks.
TrajectoryCrafter: TrajectoryCrafter achieves high-fidelity novel views generation from casually captured monocular video.
GEN3C: a generative video model with precise Camera Control and temporal 3D Consistency.
Please leave us a star 🌟 and cite our paper if you find our work helpful.
@article{zhu2025astra,
  title={Astra: General Interactive World Model with Autoregressive Denoising},
  author={Zhu, Yixuan and Feng, Jiaqi and Zheng, Wenzhao and Gao, Yuan and Tao, Xin and Wan, Pengfei and Zhou, Jie and Lu, Jiwen},
  journal={arXiv preprint arXiv:2512.08931},
  year={2025}
}
[ICLR 2026] Astra : General Interactive World Model with Autoregressive Denoising"
Python
340
17 commits
updated Jun 9, 2026
: General Interactive World Model with Autoregressive Denoising (ICLR 2026)
Yixuan Zhu1, Jiaqi Feng1, Wenzhao Zheng1 †, Yuan Gao2, Xin Tao2, Pengfei Wan2, Jie Zhou 1, Jiwen Lu1
(† Project leader)
1Tsinghua University, 2Kuaishou Technology.
TL;DR: Astra is an interactive world model that delivers realistic long-horizon video rollouts under a wide range of scenarios and action inputs.
Astra is an interactive, action-driven world model that predicts long-horizon future videos across diverse real-world scenarios. Built on an autoregressive diffusion transformer with temporal causal attention, Astra supports streaming prediction while preserving strong temporal coherence. Astra introduces noise-augmented history memory to stabilize long rollouts, an action-aware adapter for precise control signals, and a mixture of action experts to route heterogeneous action modalities. Through these key innovations, Astra delivers consistent, controllable, and high-fidelity video futures for applications such as autonomous driving, robot manipulation, and camera motion.
Release dataset preprocessing tools
Release full inference pipelines for additional scenarios:
Open-source training scripts:
Provide unified evaluation toolkit
Astra is built upon Wan2.1-1.3B, a diffusion-based video generation model. We provide inference scripts to help you quickly generate videos from images and action inputs. Follow the steps below:
DiffSynth-Studio requires Rust and Cargo to compile extensions. You can install them using the following command:
curl --proto '=https' --tlsv1.2 -sSf [https://sh.rustup.rs](https://sh.rustup.rs/) | sh
. "$HOME/.cargo/env"
Install DiffSynth-Studio:
git clone https://github.com/EternalEvan/Astra.git
cd Astra
pip install -e .
cd script
python download_wan2.1.py
Please download from huggingface and place it in models/Astra/checkpoints.
python infer_demo.py \
  --dit_path ../models/Astra/checkpoints/diffusion_pytorch_model.ckpt \
  --wan_model_path ../models/Wan-AI/Wan2.1-T2V-1.3B \
  --condition_image ../examples/condition_images/garden_1.png \
  --cam_type 4 \
  --prompt "A sunlit European street lined with historic buildings and vibrant greenery creates a warm, charming, and inviting atmosphere. The scene shows a picturesque open square paved with red bricks, surrounded by classic narrow townhouses featuring tall windows, gabled roofs, and dark-painted facades. On the right side, a lush arrangement of potted plants and blooming flowers adds rich color and texture to the foreground. A vintage-style streetlamp stands prominently near the center-right, contributing to the timeless character of the street. Mature trees frame the background, their leaves glowing in the warm afternoon sunlight. Bicycles are visible along the edges of the buildings, reinforcing the urban yet leisurely feel. The sky is bright blue with scattered clouds, and soft sun flares enter the frame from the left, enhancing the scene’s inviting, peaceful mood."  \
  --output_path ../examples/output_videos/output_moe_framepack_sliding.mp4 \
This inference can be conducted on a single 24GB GPU, such as the NVIDIA 3090.
To test with your own custom images, you need to prepare the target images and their corresponding text prompts. We recommend that the size of the input images is close to 832×480 (width × height, 16:9), which is consistent with the resolution of the generated video and can help achieve better video generation effects. For prompts generation, you can refer to the Prompt Extension section in Wan2.1 for guidance on crafting the captions.
python infer_demo.py \
  --dit_path path/to/your/dit_ckpt \
  --wan_model_path path/to/your/Wan2.1-T2V-1.3B \
  --condition_image path/to/your/image \
  --cam_type your_cam_type \
  --prompt your_prompt \
  --output_path path/to/your/output_video
We provide several preset camera types, as shown in the table below. Additionally, you can generate new trajectories for testing.
| cam_type | Trajectory |
|---|---|
| 1 | Move Forward (Straight) |
| 2 | Rotate Left In Place |
| 3 | Rotate Right In Place |
| 4 | Move Forward + Rotate Left |
| 5 | Move Forward + Rotate Right |
| 6 | S-shaped Trajectory |
| 7 | Rotate Left → Rotate Right |
To facilitate joint training across large-scale open-source datasets, we implement a preprocessing pipeline designed for maximum training efficiency. This process involves three key steps:
This preprocessing stage must be completed prior to starting the training loop. You can find the implementation scripts and detailed usage instructions in the ./data directory.
Once the data is preprocessed, you can initiate training on a specific dataset. This stage allows for initial model validation or fine-tuning on a targeted domain.
Execute the training script using the following command:
python train_single.py
The training requires about 60G GPU memory.
--max_condition_frames can be shortened to reduce VRAM consumption and computational costs.Looking ahead, we plan to further enhance Astra in several directions:
These directions aim to push Astra towards more robust and interactive video world modeling.
Feel free to explore these outstanding related works, including but not limited to:
ReCamMaster: ReCamMaster re-captures in-the-wild videos with novel camera trajectories.
GCD: GCD synthesizes large-angle novel viewpoints of 4D dynamic scenes from a monocular video.
ReCapture: a method for generating new videos with novel camera trajectories from a single user-provided video.
Trajectory Attention: Trajectory Attention facilitates various tasks like camera motion control on images and videos, and video editing.
GS-DiT: GS-DiT provides 4D video control for a single monocular video.
Diffusion as Shader: a versatile video generation control model for various tasks.
TrajectoryCrafter: TrajectoryCrafter achieves high-fidelity novel views generation from casually captured monocular video.
GEN3C: a generative video model with precise Camera Control and temporal 3D Consistency.
Please leave us a star 🌟 and cite our paper if you find our work helpful.
@article{zhu2025astra,
  title={Astra: General Interactive World Model with Autoregressive Denoising},
  author={Zhu, Yixuan and Feng, Jiaqi and Zheng, Wenzhao and Gao, Yuan and Tao, Xin and Wan, Pengfei and Zhou, Jie and Lu, Jiwen},
  journal={arXiv preprint arXiv:2512.08931},
  year={2025}
}



