[ICCV 2025] Official implementation of the paper: REPA-E: Unlocking VAE for End-to-End Tuning of Latent Diffusion Transformers
Python
526
5 commits
updated Dec 6, 2025
Xingjian Leng1* · Jaskirat Singh1* · Yunzhong Hou1 · Zhenchang Xing2 · Saining Xie3 · Liang Zheng1
1 Australian National University 2Data61-CSIRO 3New York University
*Project Leads
🌐 Project Page
🤗 Models
📃 Paper
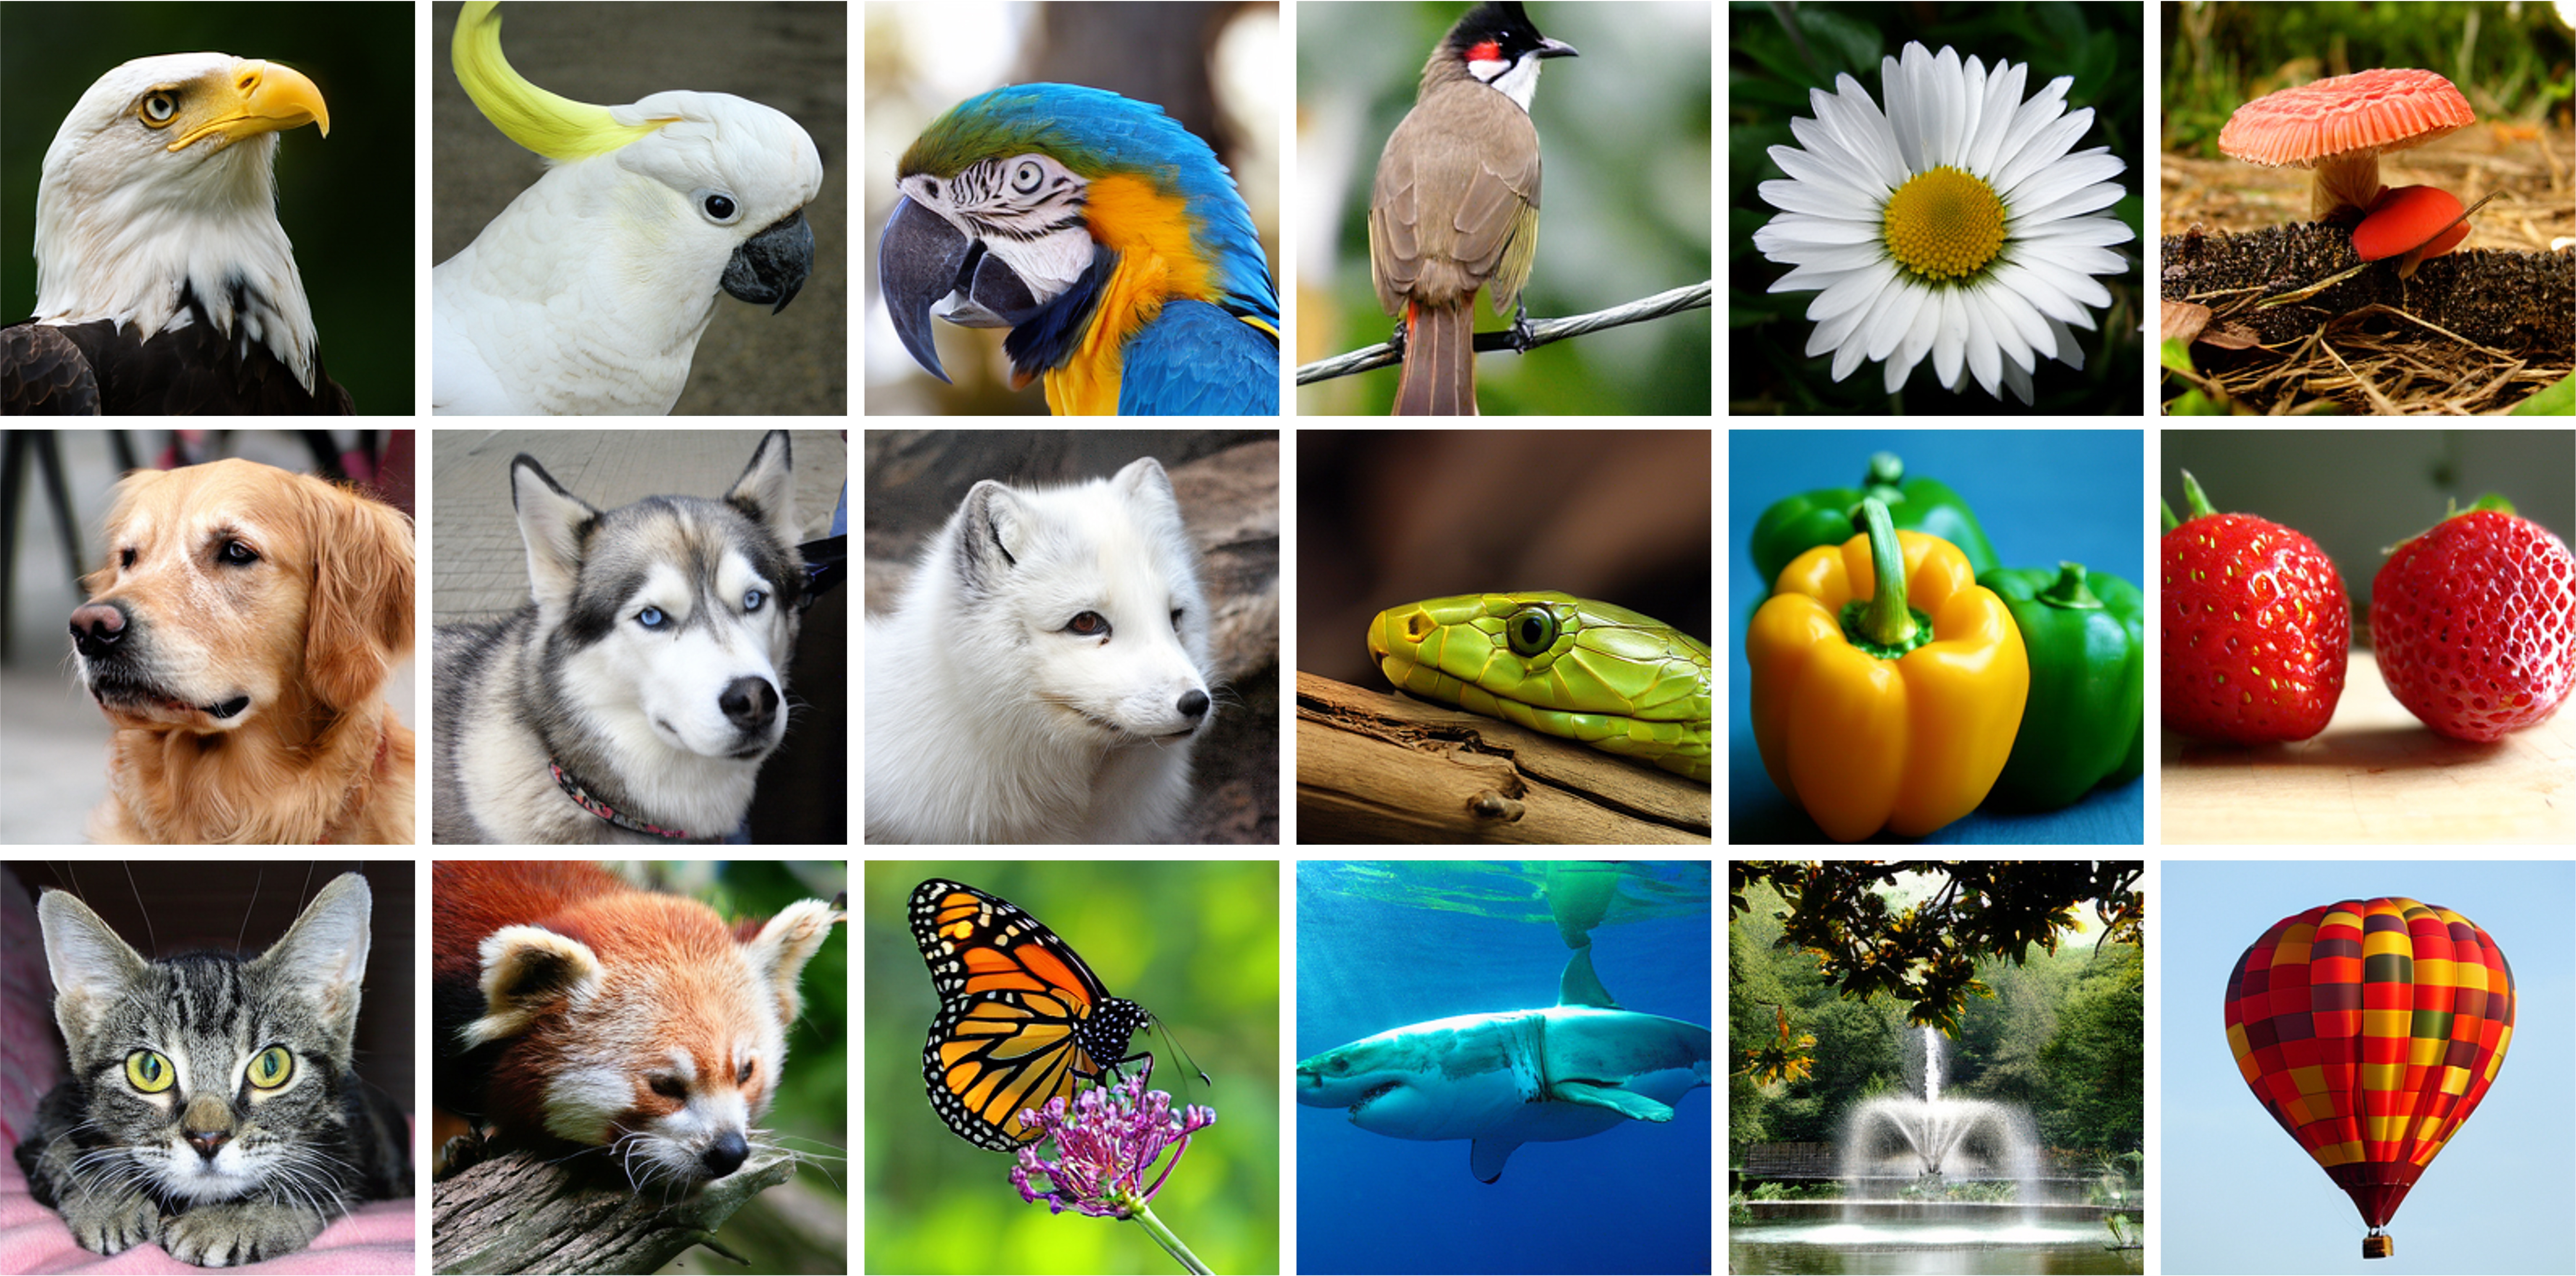
We address a fundamental question: Can latent diffusion models and their VAE tokenizer be trained end-to-end? While training both components jointly with standard diffusion loss is observed to be ineffective — often degrading final performance — we show that this limitation can be overcome using a simple representation-alignment (REPA) loss. Our proposed method, REPA-E, enables stable and effective joint training of both the VAE and the diffusion model.
REPA-E significantly accelerates training — achieving over 17× speedup compared to REPA and 45× over the vanilla training recipe. Interestingly, end-to-end tuning also improves the VAE itself: the resulting E2E-VAE provides better latent structure and serves as a drop-in replacement for existing VAEs (e.g., SD-VAE), improving convergence and generation quality across diverse LDM architectures. Our method achieves state-of-the-art FID scores on ImageNet 256×256: 1.12 with CFG and 1.69 without CFG.
diffusers API, no custom wrapper neededWe are excited to release the family of End-to-End tuned VAEs as Hugging Face AutoencoderKL compatible checkpoints, ready to use with diffusers out of the box. This release includes both our text-to-image VAEs and ImageNet-trained VAEs.
Note: Please refer to our T2I codebase training codebase to reproduce the text-to-image experiments with end-to-end VAEs.
| Model | Hugging Face |
|---|---|
| E2E-FLUX-VAE | 🤗 REPA-E/e2e-flux-vae |
| E2E-SD-3.5-VAE | 🤗 REPA-E/e2e-sd3.5-vae |
| E2E-Qwen-Image-VAE | 🤗 REPA-E/e2e-qwenimage-vae |
| E2E-VAVAE-HF | 🤗 REPA-E/e2e-vavae-hf |
| E2E-SDVAE-HF | 🤗 REPA-E/e2e-sdvae-hf |
| E2E-INVAE-HF | 🤗 REPA-E/e2e-invae-hf |
from diffusers import AutoencoderKL

# Load end-to-end tuned VAE (ImageNet VAE example)
vae = AutoencoderKL.from_pretrained("REPA-E/e2e-vavae-hf").to("cuda")

# Or load a text-to-image VAE
vae = AutoencoderKL.from_pretrained("REPA-E/e2e-flux-vae").to("cuda")

# Use in your pipeline with vae.encode(...) / vae.decode(...)
Full workflow for encoding and decoding images:
from io import BytesIO
import requests
from diffusers import AutoencoderKLQwenImage
import numpy as np
import torch
from PIL import Image

response = requests.get("https://raw.githubusercontent.com/End2End-Diffusion/fuse-dit/main/assets/example.png")
device = "cuda"

image = torch.from_numpy(
    np.array(
        Image.open(BytesIO(response.content))
    )
).permute(2, 0, 1).unsqueeze(0).to(torch.float32) / 127.5 - 1
image = image.to(device)

vae = AutoencoderKLQwenImage.from_pretrained("REPA-E/e2e-qwenimage-vae").to(device)

# Add frame dimension (required for QwenImage VAE)
image_ = image.unsqueeze(2)

with torch.no_grad():
    latents = vae.encode(image_).latent_dist.sample()
    reconstructed = vae.decode(latents).sample

# Remove frame dimension
latents = latents.squeeze(2)
reconstructed = reconstructed.squeeze(2)
To set up our environment, please run:
git clone https://github.com/REPA-E/REPA-E.git
cd REPA-E
conda env create -f environment.yml -y
conda activate repa-e
Download and extract the training split of the ImageNet-1K dataset. Once it's ready, run the following command to preprocess the dataset:
python preprocessing.py --imagenet-path /PATH/TO/IMAGENET_TRAIN
Replace /PATH/TO/IMAGENET_TRAIN with the actual path to the extracted training images.
To train the REPA-E model, you first need to download the following pre-trained VAE checkpoints:
Recommended directory structure:
pretrained/
├── invae/
├── sdvae/
└── vavae/
Once you've downloaded the VAE checkpoint, you can launch REPA-E training with:
accelerate launch train_repae.py \
    --max-train-steps=400000 \
    --report-to="wandb" \
    --allow-tf32 \
    --mixed-precision="fp16" \
    --seed=0 \
    --data-dir="data" \
    --output-dir="exps" \
    --batch-size=256 \
    --path-type="linear" \
    --prediction="v" \
    --weighting="uniform" \
    --model="SiT-XL/2" \
    --checkpointing-steps=50000 \
    --loss-cfg-path="configs/l1_lpips_kl_gan.yaml" \
    --vae="f8d4" \
    --vae-ckpt="pretrained/sdvae/sdvae-f8d4.pt" \
    --disc-pretrained-ckpt="pretrained/sdvae/sdvae-f8d4-discriminator-ckpt.pt" \
    --enc-type="dinov2-vit-b" \
    --proj-coeff=0.5 \
    --encoder-depth=8 \
    --vae-align-proj-coeff=1.5 \
    --bn-momentum=0.1 \
    --exp-name="sit-xl-dinov2-b-enc8-repae-sdvae-0.5-1.5-400k"
Then this script will automatically create the folder in exps to save logs and checkpoints. You can adjust the following options:
--output-dir: Directory to save checkpoints and logs--exp-name: Experiment name (a subfolder will be created under output-dir)--vae: Choose between [f8d4, f16d32]--vae-ckpt: Path to a provided or custom VAE checkpoint--disc-pretrained-ckpt: Path to a provided or custom VAE discriminator checkpoint--models: Choose from [SiT-B/2, SiT-L/2, SiT-XL/2, SiT-B/1, SiT-L/1, SiT-XL/1]. The number indicates the patch size. Select a model compatible with your VAE architecture.--enc-type: [dinov2-vit-b, dinov2-vit-l, dinov2-vit-g, dinov1-vit-b, mocov3-vit-b, mocov3-vit-l, clip-vit-L, jepa-vit-h, mae-vit-l]--encoder-depth: Any integer from 1 up to the full depth of the selected encoder--proj-coeff: REPA-E projection coefficient for SiT alignment (float > 0)--vae-align-proj-coeff: REPA-E projection coefficient for VAE alignment (float > 0)--bn-momentum: Batchnorm layer momentum (float)This section shows how to use the REPA-E fine-tuned VAE (E2E-VAE) in latent diffusion training. E2E-VAE acts as a drop-in replacement for the original VAE, enabling significantly accelerated generation performance. You can either download a pre-trained VAE or extract it from a REPA-E checkpoint.
Step 1: Obtain the fine-tuned VAE from REPA-E checkpoints:
Option 1: Download pre-trained REPA-E VAEs directly from Hugging Face:
Recommended directory structure:
pretrained/
├── e2e-sdvae/
├── e2e-invae/
└── e2e-vavae/
Option 2: Extract the VAE from a full REPA-E checkpoint manually:
python save_vae_weights.py \
    --repae-ckpt pretrained/sit-repae-vavae/checkpoints/0400000.pt \
    --vae-name e2e-vavae \
    --save-dir exps
Step 2: Cache latents to enable fast training:
accelerate launch --num_machines=1 --num_processes=8 cache_latents.py \
    --vae-arch="f16d32" \
    --vae-ckpt-path="pretrained/e2e-vavae/e2e-vavae-400k.pt" \
    --vae-latents-name="e2e-vavae" \
    --pproc-batch-size=128
Step 3: Train the SiT generation model using the cached latents:
accelerate launch train_ldm_only.py \
    --max-train-steps=4000000 \
    --report-to="wandb" \
    --allow-tf32 \
    --mixed-precision="fp16" \
    --seed=0 \
    --data-dir="data" \
    --batch-size=256 \
    --path-type="linear" \
    --prediction="v" \
    --weighting="uniform" \
    --model="SiT-XL/1" \
    --checkpointing-steps=50000 \
    --vae="f16d32" \
    --vae-ckpt="pretrained/e2e-vavae/e2e-vavae-400k.pt" \
    --vae-latents-name="e2e-vavae" \
    --learning-rate=1e-4 \
    --enc-type="dinov2-vit-b" \
    --proj-coeff=0.5 \
    --encoder-depth=8 \
    --output-dir="exps" \
    --exp-name="sit-xl-1-dinov2-b-enc8-ldm-only-e2e-vavae-0.5-4m"
For details on the available training options and argument descriptions, refer to Section 3.
You can generate samples and save them as .npz files using the following script. Simply set the --exp-path and --train-steps corresponding to your trained model (REPA-E or Traditional LDM Training).
torchrun --nnodes=1 --nproc_per_node=8 generate.py \
    --num-fid-samples 50000 \
    --path-type linear \
    --mode sde \
    --num-steps 250 \
    --cfg-scale 1.0 \
    --guidance-high 1.0 \
    --guidance-low 0.0 \
    --exp-path pretrained/sit-ldm-e2e-vavae \
    --train-steps 4000000 \
You can adjust the following options for sampling:
--path-type linear: Noise schedule type, choose from [linear, cosine]--mode: Sampling mode, [ode, sde]--num-steps: Number of denoising steps--cfg-scale: Guidance scale (float ≥ 1), setting it to 1 disables classifier-free guidance (CFG)--guidance-high: Upper guidance interval (float in [0, 1])--guidance-low: Lower guidance interval (float in [0, 1], must be < --guidance-high)--exp-path: Path to the experiment directory--train-steps: Training step of the checkpoint to evaluate--label-sampling: Class label sampling strategy, [equal, random] (default: equal)You can then use the ADM evaluation suite to compute image generation quality metrics, including gFID, sFID, Inception Score (IS), Precision, and Recall.
Tables below report generation performance using gFID on 50k samples, with and without classifier-free guidance (CFG). We compare models trained end-to-end with REPA-E and models using a frozen REPA-E fine-tuned VAE (E2E-VAE). Lower is better. All linked checkpoints below are hosted on our 🤗 Hugging Face Hub. To reproduce these results, download the respective checkpoints to the pretrained folder and run the evaluation script as detailed in Section 5.
| Tokenizer | Generation Model | Epochs | gFID-50k ↓ | gFID-50k (CFG) ↓ |
|---|---|---|---|---|
| SD-VAE* | SiT-XL/2 | 80 | 4.07 | 1.67a |
| IN-VAE* | SiT-XL/1 | 80 | 4.09 | 1.61b |
| VA-VAE* | SiT-XL/1 | 80 | 4.05 | 1.73c |
* The "Tokenizer" column refers to the initial VAE used for joint REPA-E training. The final (jointly optimized) VAE is bundled within the generation model checkpoint.
--cfg-scale=2.2, --guidance-low=0.0, --guidance-high=0.65--cfg-scale=1.8, --guidance-low=0.0, --guidance-high=0.825--cfg-scale=1.9, --guidance-low=0.0, --guidance-high=0.825| Tokenizer | Generation Model | Method | Epochs | gFID-50k ↓ | gFID-50k (CFG) ↓ |
|---|---|---|---|---|---|
| SD-VAE | SiT-XL/2 | SiT | 1400 | 8.30 | 2.06 |
| SD-VAE | SiT-XL/2 | REPA | 800 | 5.84 | 1.28 |
| VA-VAE | LightningDiT-XL/1 | LightningDiT | 800 | 2.05 | 1.25 |
| E2E-VAVAE (Ours) | SiT-XL/1 | REPA | 800 | 1.69 | 1.12† |
In this setup, the VAE is kept frozen and only the generator is trained. Models using our E2E-VAE (fine-tuned via REPA-E) consistently outperform baselines such as SD-VAE and VA-VAE, achieving state-of-the-art performance when incorporating the REPA alignment objective.
Note: The results for the last three rows (REPA, LightningDiT, and E2E-VAE) are obtained using the class-balanced sampling protocol (50 images per class).
--cfg-scale=2.4, --guidance-low=0.0, --guidance-high=0.73This codebase builds upon several excellent open-source projects, including:
We sincerely thank the authors for making their work publicly available.
If you find our work useful, please consider citing:
@article{leng2025repae,
  title={REPA-E: Unlocking VAE for End-to-End Tuning with Latent Diffusion Transformers},
  author={Xingjian Leng and Jaskirat Singh and Yunzhong Hou and Zhenchang Xing and Saining Xie and Liang Zheng},
  year={2025},
  journal={arXiv preprint arXiv:2504.10483},
}
@misc{repaet2i2025,
    title={Family of End-to-End Tuned VAEs for Supercharging T2I Diffusion Transformers},
    author={Leng, Xingjian and Singh, Jaskirat and Murdock, Ryan and Smith, Ethan and Li, Rebecca and Hou, Yunzhong and Xing, Zhenchang and Xie, Saining and Zheng, Liang},
    howpublished={\url{https://end2end-diffusion.github.io/repa-e-t2i/}},
    year={2025}
}
274 followers · starred Apr 2025
9,331 followers · starred Jun 2025
146 followers · starred Apr 2025
198 followers · starred Oct 2025
[ICCV 2025] Official implementation of the paper: REPA-E: Unlocking VAE for End-to-End Tuning of Latent Diffusion Transformers
Python
526
5 commits
updated Dec 6, 2025
Xingjian Leng1* · Jaskirat Singh1* · Yunzhong Hou1 · Zhenchang Xing2 · Saining Xie3 · Liang Zheng1
1 Australian National University 2Data61-CSIRO 3New York University
*Project Leads
🌐 Project Page
🤗 Models
📃 Paper
We address a fundamental question: Can latent diffusion models and their VAE tokenizer be trained end-to-end? While training both components jointly with standard diffusion loss is observed to be ineffective — often degrading final performance — we show that this limitation can be overcome using a simple representation-alignment (REPA) loss. Our proposed method, REPA-E, enables stable and effective joint training of both the VAE and the diffusion model.
REPA-E significantly accelerates training — achieving over 17× speedup compared to REPA and 45× over the vanilla training recipe. Interestingly, end-to-end tuning also improves the VAE itself: the resulting E2E-VAE provides better latent structure and serves as a drop-in replacement for existing VAEs (e.g., SD-VAE), improving convergence and generation quality across diverse LDM architectures. Our method achieves state-of-the-art FID scores on ImageNet 256×256: 1.12 with CFG and 1.69 without CFG.
diffusers API, no custom wrapper neededWe are excited to release the family of End-to-End tuned VAEs as Hugging Face AutoencoderKL compatible checkpoints, ready to use with diffusers out of the box. This release includes both our text-to-image VAEs and ImageNet-trained VAEs.
Note: Please refer to our T2I codebase training codebase to reproduce the text-to-image experiments with end-to-end VAEs.
| Model | Hugging Face |
|---|---|
| E2E-FLUX-VAE | 🤗 REPA-E/e2e-flux-vae |
| E2E-SD-3.5-VAE | 🤗 REPA-E/e2e-sd3.5-vae |
| E2E-Qwen-Image-VAE | 🤗 REPA-E/e2e-qwenimage-vae |
| E2E-VAVAE-HF | 🤗 REPA-E/e2e-vavae-hf |
| E2E-SDVAE-HF | 🤗 REPA-E/e2e-sdvae-hf |
| E2E-INVAE-HF | 🤗 REPA-E/e2e-invae-hf |
from diffusers import AutoencoderKL

# Load end-to-end tuned VAE (ImageNet VAE example)
vae = AutoencoderKL.from_pretrained("REPA-E/e2e-vavae-hf").to("cuda")

# Or load a text-to-image VAE
vae = AutoencoderKL.from_pretrained("REPA-E/e2e-flux-vae").to("cuda")

# Use in your pipeline with vae.encode(...) / vae.decode(...)
Full workflow for encoding and decoding images:
from io import BytesIO
import requests
from diffusers import AutoencoderKLQwenImage
import numpy as np
import torch
from PIL import Image

response = requests.get("https://raw.githubusercontent.com/End2End-Diffusion/fuse-dit/main/assets/example.png")
device = "cuda"

image = torch.from_numpy(
    np.array(
        Image.open(BytesIO(response.content))
    )
).permute(2, 0, 1).unsqueeze(0).to(torch.float32) / 127.5 - 1
image = image.to(device)

vae = AutoencoderKLQwenImage.from_pretrained("REPA-E/e2e-qwenimage-vae").to(device)

# Add frame dimension (required for QwenImage VAE)
image_ = image.unsqueeze(2)

with torch.no_grad():
    latents = vae.encode(image_).latent_dist.sample()
    reconstructed = vae.decode(latents).sample

# Remove frame dimension
latents = latents.squeeze(2)
reconstructed = reconstructed.squeeze(2)
To set up our environment, please run:
git clone https://github.com/REPA-E/REPA-E.git
cd REPA-E
conda env create -f environment.yml -y
conda activate repa-e
Download and extract the training split of the ImageNet-1K dataset. Once it's ready, run the following command to preprocess the dataset:
python preprocessing.py --imagenet-path /PATH/TO/IMAGENET_TRAIN
Replace /PATH/TO/IMAGENET_TRAIN with the actual path to the extracted training images.
To train the REPA-E model, you first need to download the following pre-trained VAE checkpoints:
Recommended directory structure:
pretrained/
├── invae/
├── sdvae/
└── vavae/
Once you've downloaded the VAE checkpoint, you can launch REPA-E training with:
accelerate launch train_repae.py \
    --max-train-steps=400000 \
    --report-to="wandb" \
    --allow-tf32 \
    --mixed-precision="fp16" \
    --seed=0 \
    --data-dir="data" \
    --output-dir="exps" \
    --batch-size=256 \
    --path-type="linear" \
    --prediction="v" \
    --weighting="uniform" \
    --model="SiT-XL/2" \
    --checkpointing-steps=50000 \
    --loss-cfg-path="configs/l1_lpips_kl_gan.yaml" \
    --vae="f8d4" \
    --vae-ckpt="pretrained/sdvae/sdvae-f8d4.pt" \
    --disc-pretrained-ckpt="pretrained/sdvae/sdvae-f8d4-discriminator-ckpt.pt" \
    --enc-type="dinov2-vit-b" \
    --proj-coeff=0.5 \
    --encoder-depth=8 \
    --vae-align-proj-coeff=1.5 \
    --bn-momentum=0.1 \
    --exp-name="sit-xl-dinov2-b-enc8-repae-sdvae-0.5-1.5-400k"
Then this script will automatically create the folder in exps to save logs and checkpoints. You can adjust the following options:
--output-dir: Directory to save checkpoints and logs--exp-name: Experiment name (a subfolder will be created under output-dir)--vae: Choose between [f8d4, f16d32]--vae-ckpt: Path to a provided or custom VAE checkpoint--disc-pretrained-ckpt: Path to a provided or custom VAE discriminator checkpoint--models: Choose from [SiT-B/2, SiT-L/2, SiT-XL/2, SiT-B/1, SiT-L/1, SiT-XL/1]. The number indicates the patch size. Select a model compatible with your VAE architecture.--enc-type: [dinov2-vit-b, dinov2-vit-l, dinov2-vit-g, dinov1-vit-b, mocov3-vit-b, mocov3-vit-l, clip-vit-L, jepa-vit-h, mae-vit-l]--encoder-depth: Any integer from 1 up to the full depth of the selected encoder--proj-coeff: REPA-E projection coefficient for SiT alignment (float > 0)--vae-align-proj-coeff: REPA-E projection coefficient for VAE alignment (float > 0)--bn-momentum: Batchnorm layer momentum (float)This section shows how to use the REPA-E fine-tuned VAE (E2E-VAE) in latent diffusion training. E2E-VAE acts as a drop-in replacement for the original VAE, enabling significantly accelerated generation performance. You can either download a pre-trained VAE or extract it from a REPA-E checkpoint.
Step 1: Obtain the fine-tuned VAE from REPA-E checkpoints:
Option 1: Download pre-trained REPA-E VAEs directly from Hugging Face:
Recommended directory structure:
pretrained/
├── e2e-sdvae/
├── e2e-invae/
└── e2e-vavae/
Option 2: Extract the VAE from a full REPA-E checkpoint manually:
python save_vae_weights.py \
    --repae-ckpt pretrained/sit-repae-vavae/checkpoints/0400000.pt \
    --vae-name e2e-vavae \
    --save-dir exps
Step 2: Cache latents to enable fast training:
accelerate launch --num_machines=1 --num_processes=8 cache_latents.py \
    --vae-arch="f16d32" \
    --vae-ckpt-path="pretrained/e2e-vavae/e2e-vavae-400k.pt" \
    --vae-latents-name="e2e-vavae" \
    --pproc-batch-size=128
Step 3: Train the SiT generation model using the cached latents:
accelerate launch train_ldm_only.py \
    --max-train-steps=4000000 \
    --report-to="wandb" \
    --allow-tf32 \
    --mixed-precision="fp16" \
    --seed=0 \
    --data-dir="data" \
    --batch-size=256 \
    --path-type="linear" \
    --prediction="v" \
    --weighting="uniform" \
    --model="SiT-XL/1" \
    --checkpointing-steps=50000 \
    --vae="f16d32" \
    --vae-ckpt="pretrained/e2e-vavae/e2e-vavae-400k.pt" \
    --vae-latents-name="e2e-vavae" \
    --learning-rate=1e-4 \
    --enc-type="dinov2-vit-b" \
    --proj-coeff=0.5 \
    --encoder-depth=8 \
    --output-dir="exps" \
    --exp-name="sit-xl-1-dinov2-b-enc8-ldm-only-e2e-vavae-0.5-4m"
For details on the available training options and argument descriptions, refer to Section 3.
You can generate samples and save them as .npz files using the following script. Simply set the --exp-path and --train-steps corresponding to your trained model (REPA-E or Traditional LDM Training).
torchrun --nnodes=1 --nproc_per_node=8 generate.py \
    --num-fid-samples 50000 \
    --path-type linear \
    --mode sde \
    --num-steps 250 \
    --cfg-scale 1.0 \
    --guidance-high 1.0 \
    --guidance-low 0.0 \
    --exp-path pretrained/sit-ldm-e2e-vavae \
    --train-steps 4000000 \
You can adjust the following options for sampling:
--path-type linear: Noise schedule type, choose from [linear, cosine]--mode: Sampling mode, [ode, sde]--num-steps: Number of denoising steps--cfg-scale: Guidance scale (float ≥ 1), setting it to 1 disables classifier-free guidance (CFG)--guidance-high: Upper guidance interval (float in [0, 1])--guidance-low: Lower guidance interval (float in [0, 1], must be < --guidance-high)--exp-path: Path to the experiment directory--train-steps: Training step of the checkpoint to evaluate--label-sampling: Class label sampling strategy, [equal, random] (default: equal)You can then use the ADM evaluation suite to compute image generation quality metrics, including gFID, sFID, Inception Score (IS), Precision, and Recall.
Tables below report generation performance using gFID on 50k samples, with and without classifier-free guidance (CFG). We compare models trained end-to-end with REPA-E and models using a frozen REPA-E fine-tuned VAE (E2E-VAE). Lower is better. All linked checkpoints below are hosted on our 🤗 Hugging Face Hub. To reproduce these results, download the respective checkpoints to the pretrained folder and run the evaluation script as detailed in Section 5.
| Tokenizer | Generation Model | Epochs | gFID-50k ↓ | gFID-50k (CFG) ↓ |
|---|---|---|---|---|
| SD-VAE* | SiT-XL/2 | 80 | 4.07 | 1.67a |
| IN-VAE* | SiT-XL/1 | 80 | 4.09 | 1.61b |
| VA-VAE* | SiT-XL/1 | 80 | 4.05 | 1.73c |
* The "Tokenizer" column refers to the initial VAE used for joint REPA-E training. The final (jointly optimized) VAE is bundled within the generation model checkpoint.
--cfg-scale=2.2, --guidance-low=0.0, --guidance-high=0.65--cfg-scale=1.8, --guidance-low=0.0, --guidance-high=0.825--cfg-scale=1.9, --guidance-low=0.0, --guidance-high=0.825| Tokenizer | Generation Model | Method | Epochs | gFID-50k ↓ | gFID-50k (CFG) ↓ |
|---|---|---|---|---|---|
| SD-VAE | SiT-XL/2 | SiT | 1400 | 8.30 | 2.06 |
| SD-VAE | SiT-XL/2 | REPA | 800 | 5.84 | 1.28 |
| VA-VAE | LightningDiT-XL/1 | LightningDiT | 800 | 2.05 | 1.25 |
| E2E-VAVAE (Ours) | SiT-XL/1 | REPA | 800 | 1.69 | 1.12† |
In this setup, the VAE is kept frozen and only the generator is trained. Models using our E2E-VAE (fine-tuned via REPA-E) consistently outperform baselines such as SD-VAE and VA-VAE, achieving state-of-the-art performance when incorporating the REPA alignment objective.
Note: The results for the last three rows (REPA, LightningDiT, and E2E-VAE) are obtained using the class-balanced sampling protocol (50 images per class).
--cfg-scale=2.4, --guidance-low=0.0, --guidance-high=0.73This codebase builds upon several excellent open-source projects, including:
We sincerely thank the authors for making their work publicly available.
If you find our work useful, please consider citing:
@article{leng2025repae,
  title={REPA-E: Unlocking VAE for End-to-End Tuning with Latent Diffusion Transformers},
  author={Xingjian Leng and Jaskirat Singh and Yunzhong Hou and Zhenchang Xing and Saining Xie and Liang Zheng},
  year={2025},
  journal={arXiv preprint arXiv:2504.10483},
}
@misc{repaet2i2025,
    title={Family of End-to-End Tuned VAEs for Supercharging T2I Diffusion Transformers},
    author={Leng, Xingjian and Singh, Jaskirat and Murdock, Ryan and Smith, Ethan and Li, Rebecca and Hou, Yunzhong and Xing, Zhenchang and Xie, Saining and Zheng, Liang},
    howpublished={\url{https://end2end-diffusion.github.io/repa-e-t2i/}},
    year={2025}
}
274 followers · starred Apr 2025
9,331 followers · starred Jun 2025
146 followers · starred Apr 2025
198 followers · starred Oct 2025