A pure Python HTML5 parser that just works. No C extensions to compile. No system dependencies to install. No complex API to learn.
See the codeHTML from the real web is messy. It is often malformed, user supplied, scraped from unknown pages, or headed for a browser where small parsing differences can become security bugs.
JustHTML gives Python projects one small dependency for the common HTML jobs:
pip install justhtml
Requires Python 3.10 or later.
Documentation | Comparison | Playground | Security policy
Most Python HTML libraries optimize for one part of the problem.
html.parser is built in, but not HTML5-correct. BeautifulSoup is convenient, but depends heavily on the parser underneath. lxml and C/Rust-backed parsers are fast, but usually leave sanitization as a separate concern. html5lib and Bleach shaped the Python ecosystem, but both are no longer the obvious foundation for new projects.
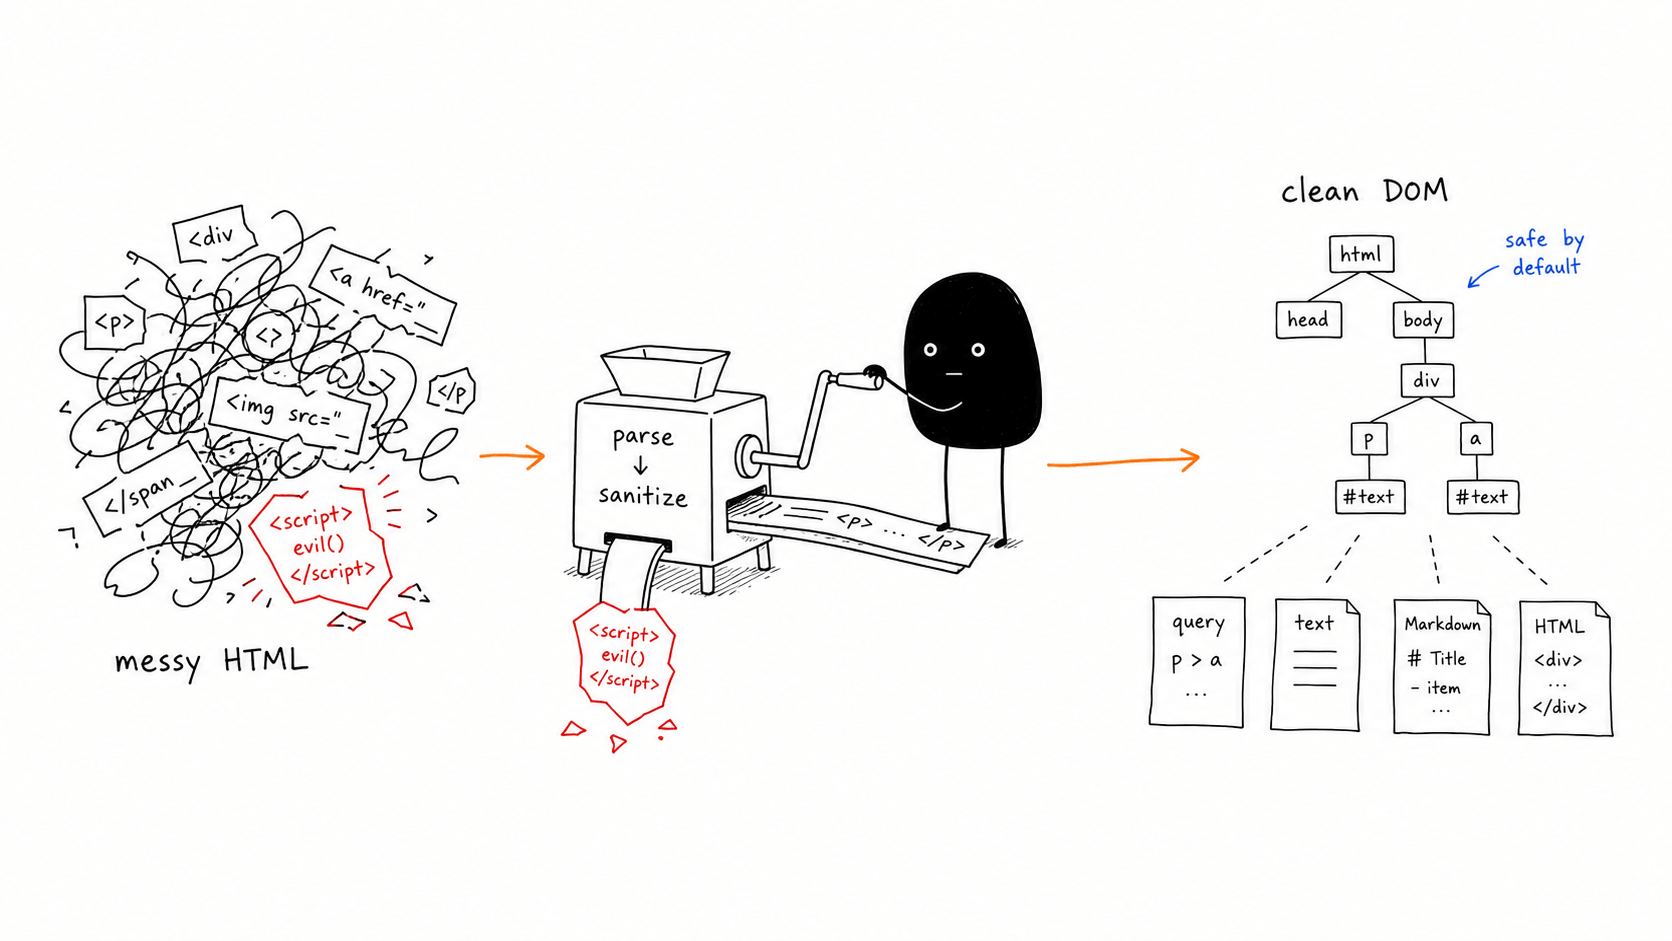
JustHTML is for applications that want a boring, inspectable, pure-Python default:
JustHTML(html) sanitizes before you query or serialize.Real-world signal: Mozilla Support migrated from Bleach to JustHTML in Kitsune, the Django application behind support.mozilla.org.
from justhtml import JustHTML

doc = JustHTML(
    "<p>Hello<script>alert(1)</script> "
    "<a href='javascript:alert(1)'>bad</a> "
    "<a href='https://example.com'>ok</a></p>",
    fragment=True,
)

print(doc.to_html(pretty=False))
# => <p>Hello <a>bad</a> <a href="https://example.com">ok</a></p>
Sanitization is enabled by default. Disable it only for trusted input:
doc = JustHTML("<main><p class='intro'>Hello</p></main>", sanitize=False)
intro = doc.query_one("p.intro")

print(intro.to_text())
# => Hello
from justhtml import JustHTML, Linkify, SetAttrs, Unwrap

doc = JustHTML(
    "<p>Hello <span>world</span> example.com</p>",
    fragment=True,
    sanitize=False,
    transforms=[
        Unwrap("span"),
        Linkify(),
        SetAttrs("a", rel="nofollow"),
    ],
)

print(doc.to_html(pretty=False))
# => <p>Hello world <a href="http://example.com" rel="nofollow">example.com</a></p>
JustHTML includes:
query() and query_one()to_text() and Markdown generation# Pretty-print an HTML file
justhtml index.html
# Parse from stdin
curl -s https://example.com | justhtml -
# Extract text from selected nodes
justhtml index.html --selector "main p" --format text
# Convert selected HTML to Markdown
justhtml index.html --selector "article" --format markdown
JustHTML is tested against the web platform html5 treebuilder tests, plus html5lib serializer/encoding fixtures and project-specific sanitizer, selector, transform, CLI, and regression tests.
The current test suite enforces 100% combined line and branch coverage, including the parser engine. The parser engine additionally requires exact agreement with the reference path across the web platform html5 treebuilder suite. See Correctness Testing for details.
JustHTML sanitizes by default, but output safety still depends on where you put it. HTML body output is not automatically safe inside JavaScript, CSS, URL attributes, or other contexts.
For the supported-version policy and vulnerability reporting, see SECURITY.md.
MIT. Free to use for commercial and non-commercial projects.
(top 24 of 27)
4,596 followers · starred Oct 2026
445 followers · starred Dec 2025
30,138 followers · starred Dec 2025
788 followers · starred Dec 2025
A pure Python HTML5 parser that just works. No C extensions to compile. No system dependencies to install. No complex API to learn.
See the codeHTML from the real web is messy. It is often malformed, user supplied, scraped from unknown pages, or headed for a browser where small parsing differences can become security bugs.
JustHTML gives Python projects one small dependency for the common HTML jobs:
pip install justhtml
Requires Python 3.10 or later.
Documentation | Comparison | Playground | Security policy
Most Python HTML libraries optimize for one part of the problem.
html.parser is built in, but not HTML5-correct. BeautifulSoup is convenient, but depends heavily on the parser underneath. lxml and C/Rust-backed parsers are fast, but usually leave sanitization as a separate concern. html5lib and Bleach shaped the Python ecosystem, but both are no longer the obvious foundation for new projects.
JustHTML is for applications that want a boring, inspectable, pure-Python default:
JustHTML(html) sanitizes before you query or serialize.Real-world signal: Mozilla Support migrated from Bleach to JustHTML in Kitsune, the Django application behind support.mozilla.org.
from justhtml import JustHTML

doc = JustHTML(
    "<p>Hello<script>alert(1)</script> "
    "<a href='javascript:alert(1)'>bad</a> "
    "<a href='https://example.com'>ok</a></p>",
    fragment=True,
)

print(doc.to_html(pretty=False))
# => <p>Hello <a>bad</a> <a href="https://example.com">ok</a></p>
Sanitization is enabled by default. Disable it only for trusted input:
doc = JustHTML("<main><p class='intro'>Hello</p></main>", sanitize=False)
intro = doc.query_one("p.intro")

print(intro.to_text())
# => Hello
from justhtml import JustHTML, Linkify, SetAttrs, Unwrap

doc = JustHTML(
    "<p>Hello <span>world</span> example.com</p>",
    fragment=True,
    sanitize=False,
    transforms=[
        Unwrap("span"),
        Linkify(),
        SetAttrs("a", rel="nofollow"),
    ],
)

print(doc.to_html(pretty=False))
# => <p>Hello world <a href="http://example.com" rel="nofollow">example.com</a></p>
JustHTML includes:
query() and query_one()to_text() and Markdown generation# Pretty-print an HTML file
justhtml index.html
# Parse from stdin
curl -s https://example.com | justhtml -
# Extract text from selected nodes
justhtml index.html --selector "main p" --format text
# Convert selected HTML to Markdown
justhtml index.html --selector "article" --format markdown
JustHTML is tested against the web platform html5 treebuilder tests, plus html5lib serializer/encoding fixtures and project-specific sanitizer, selector, transform, CLI, and regression tests.
The current test suite enforces 100% combined line and branch coverage, including the parser engine. The parser engine additionally requires exact agreement with the reference path across the web platform html5 treebuilder suite. See Correctness Testing for details.
JustHTML sanitizes by default, but output safety still depends on where you put it. HTML body output is not automatically safe inside JavaScript, CSS, URL attributes, or other contexts.
For the supported-version policy and vulnerability reporting, see SECURITY.md.
MIT. Free to use for commercial and non-commercial projects.
(top 24 of 27)
4,596 followers · starred Oct 2026
445 followers · starred Dec 2025
30,138 followers · starred Dec 2025
788 followers · starred Dec 2025