
【ICLR 2026 🔥】This work introduces MMEVOKE benchmark to reveal challenges in knowledge injection and explores potential solutions.
See the codeREADME
When Large Multimodal Models Confront Evolving Knowledge: Challenges and Pathways




Table of Contents
🤗EVOKE
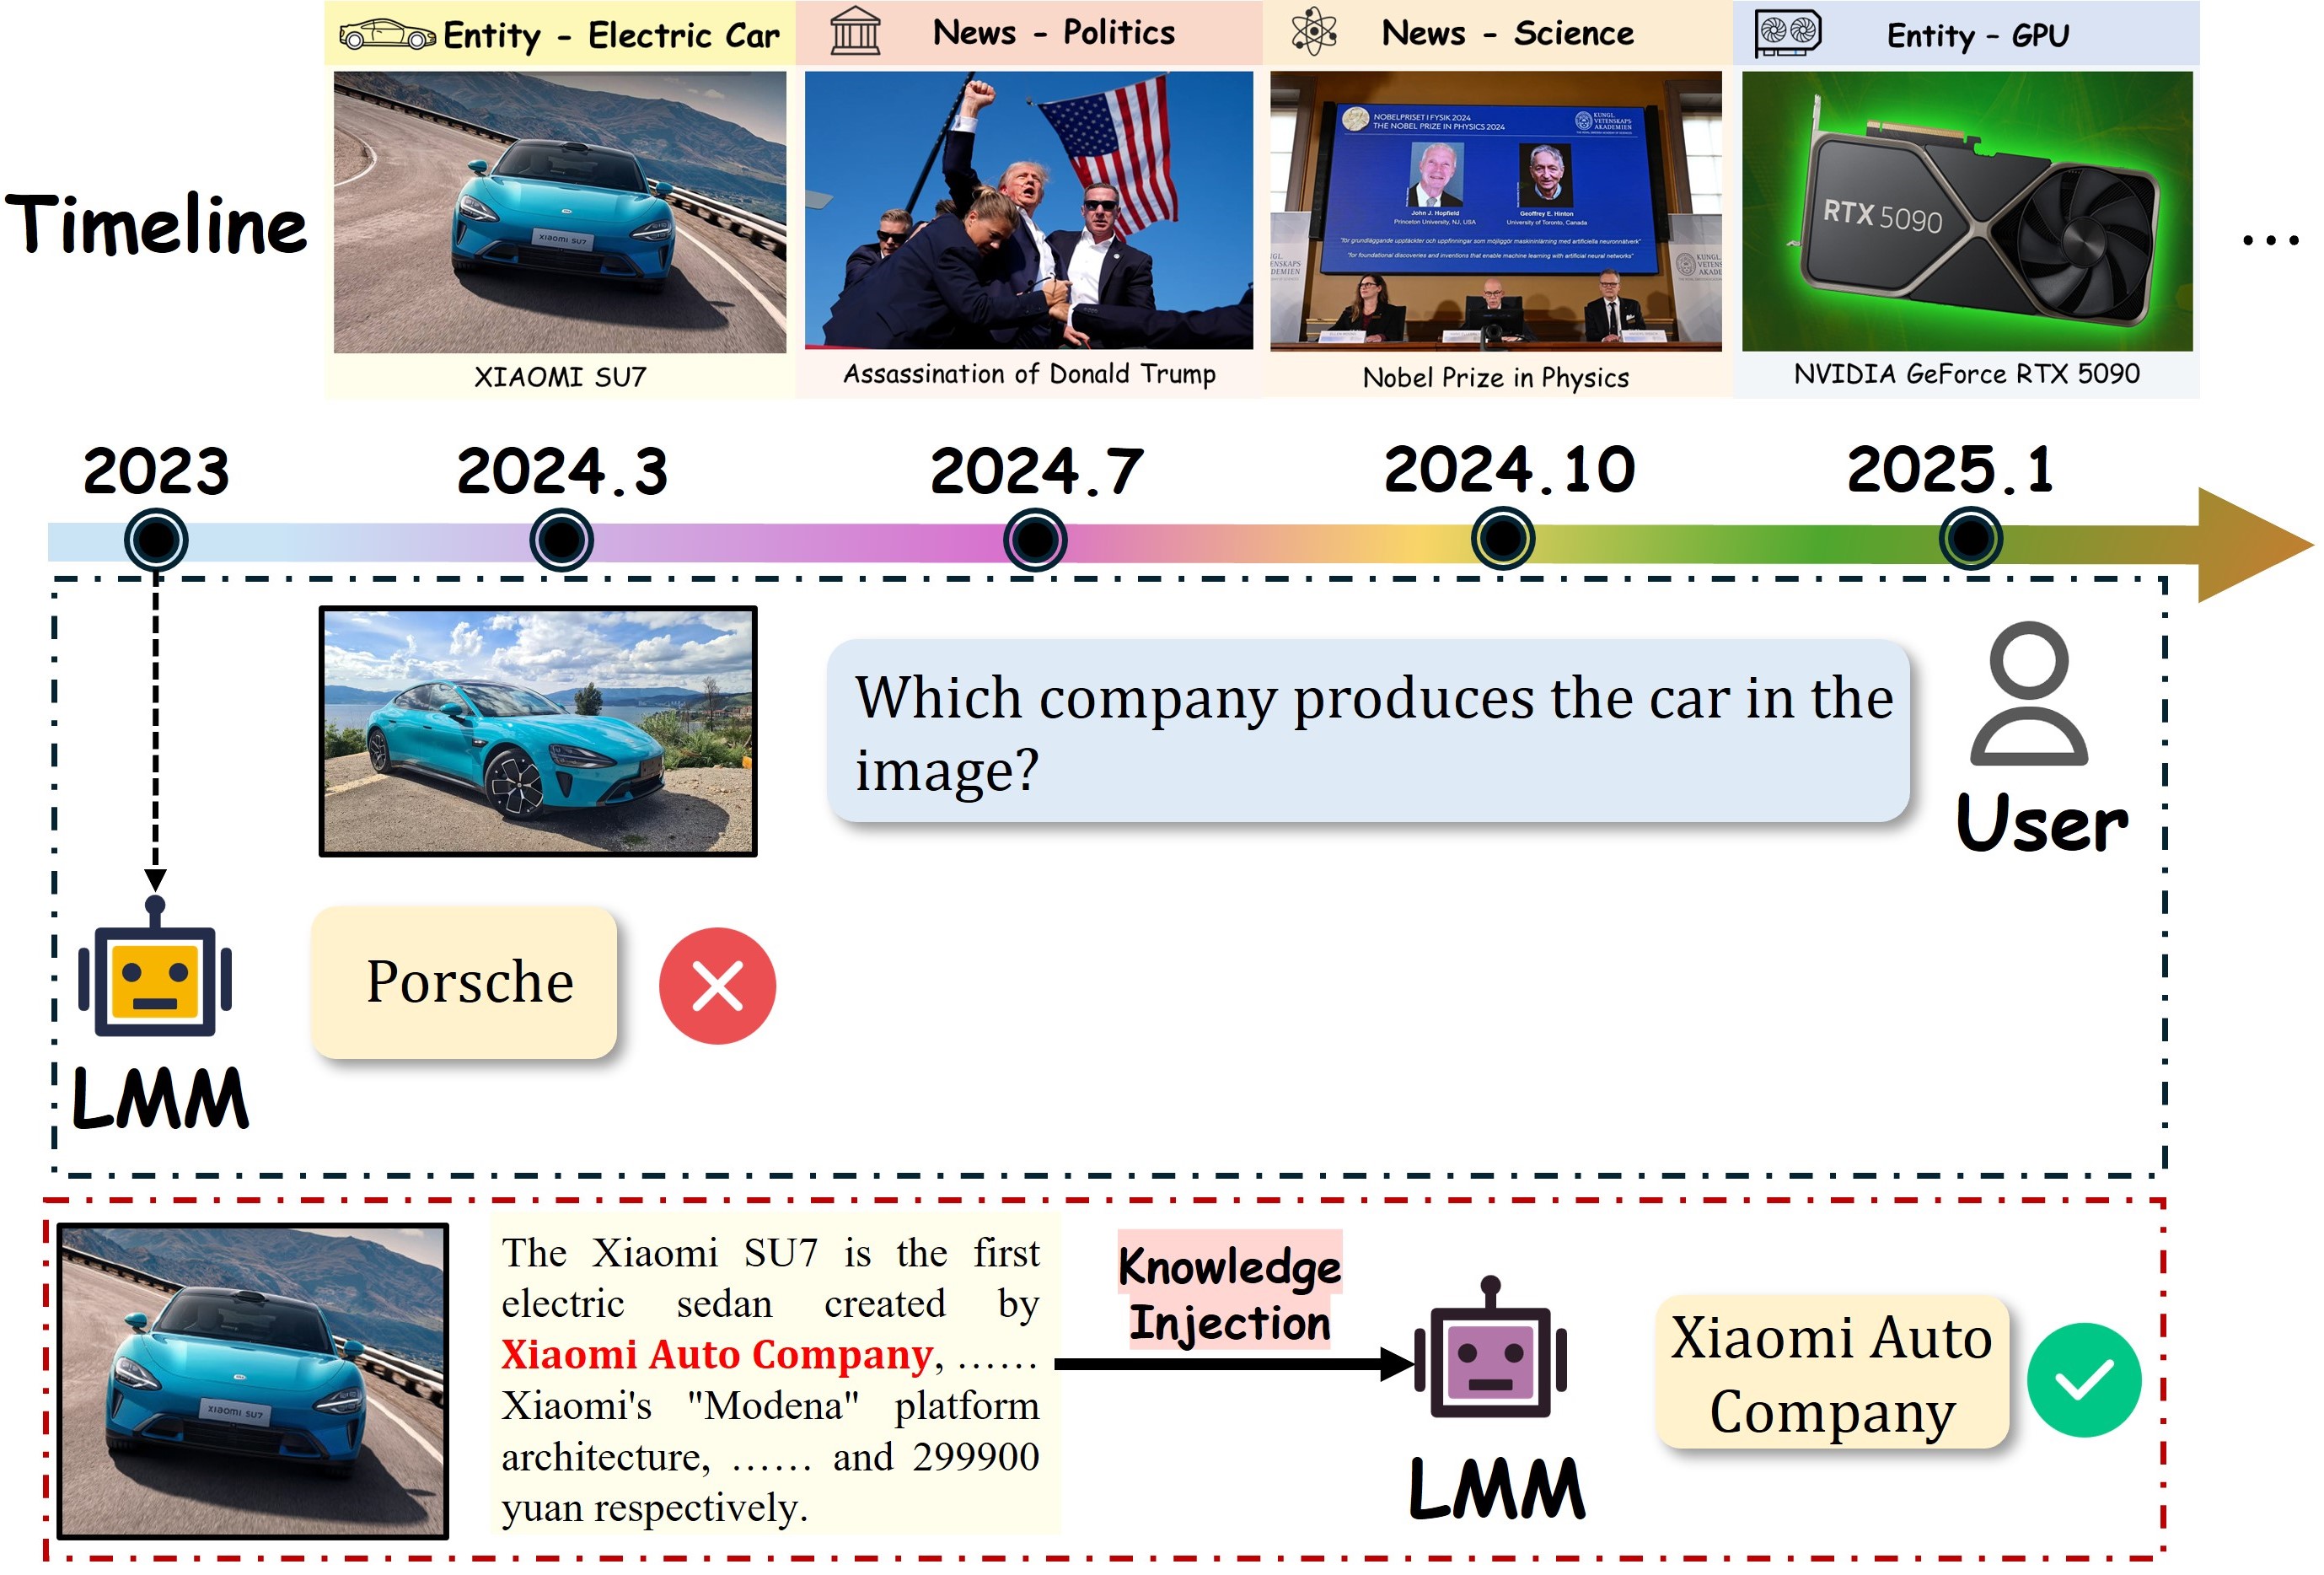
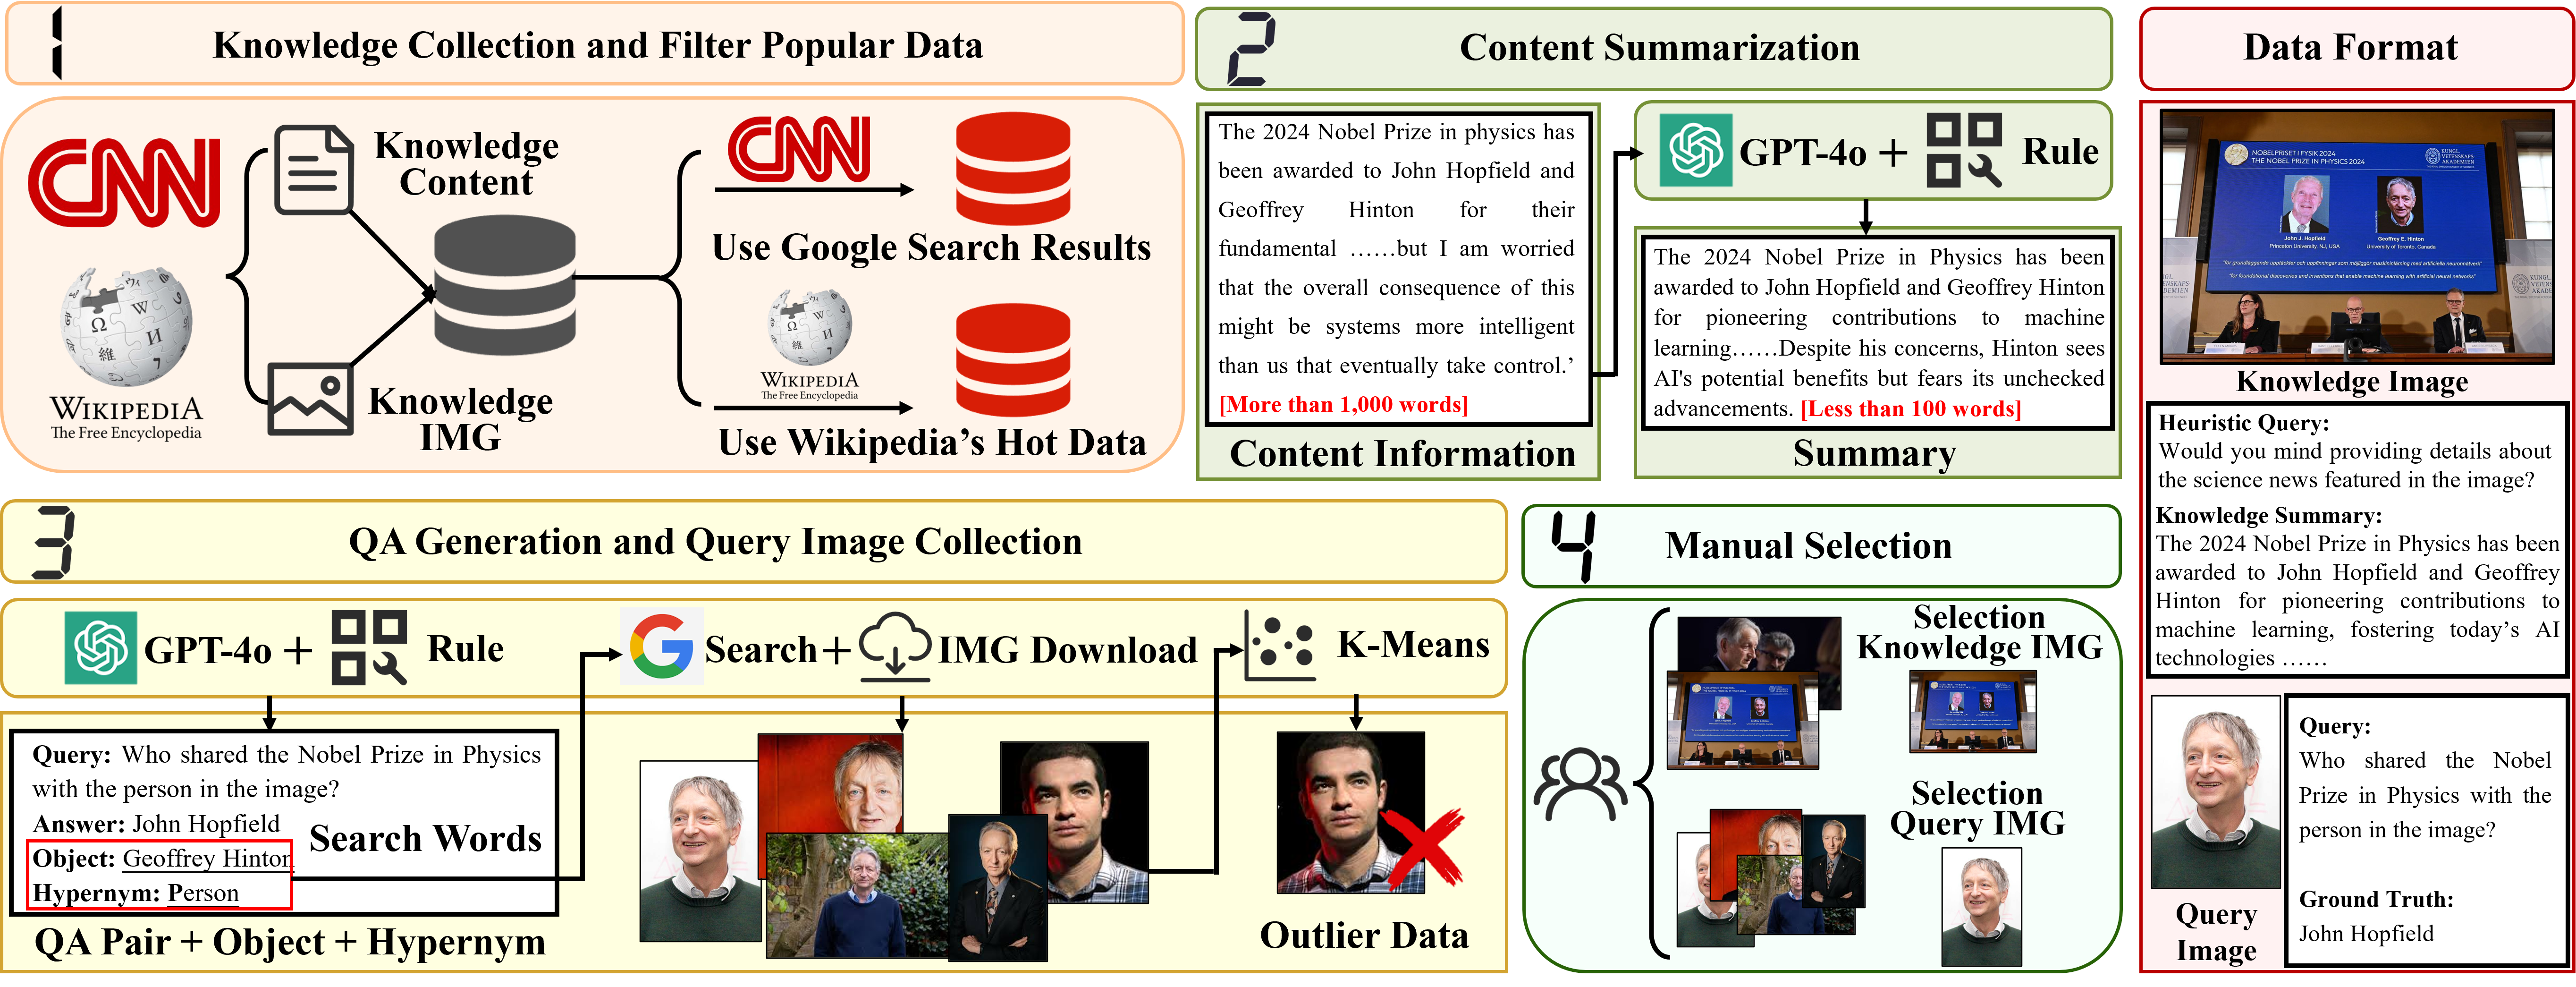
To evaluate evolving knowledge injection in LMMs, we propose a pipeline to automatically collect evolving knowledge, constructing the EVOlving KnowledgE (EVOKE) benchmark.
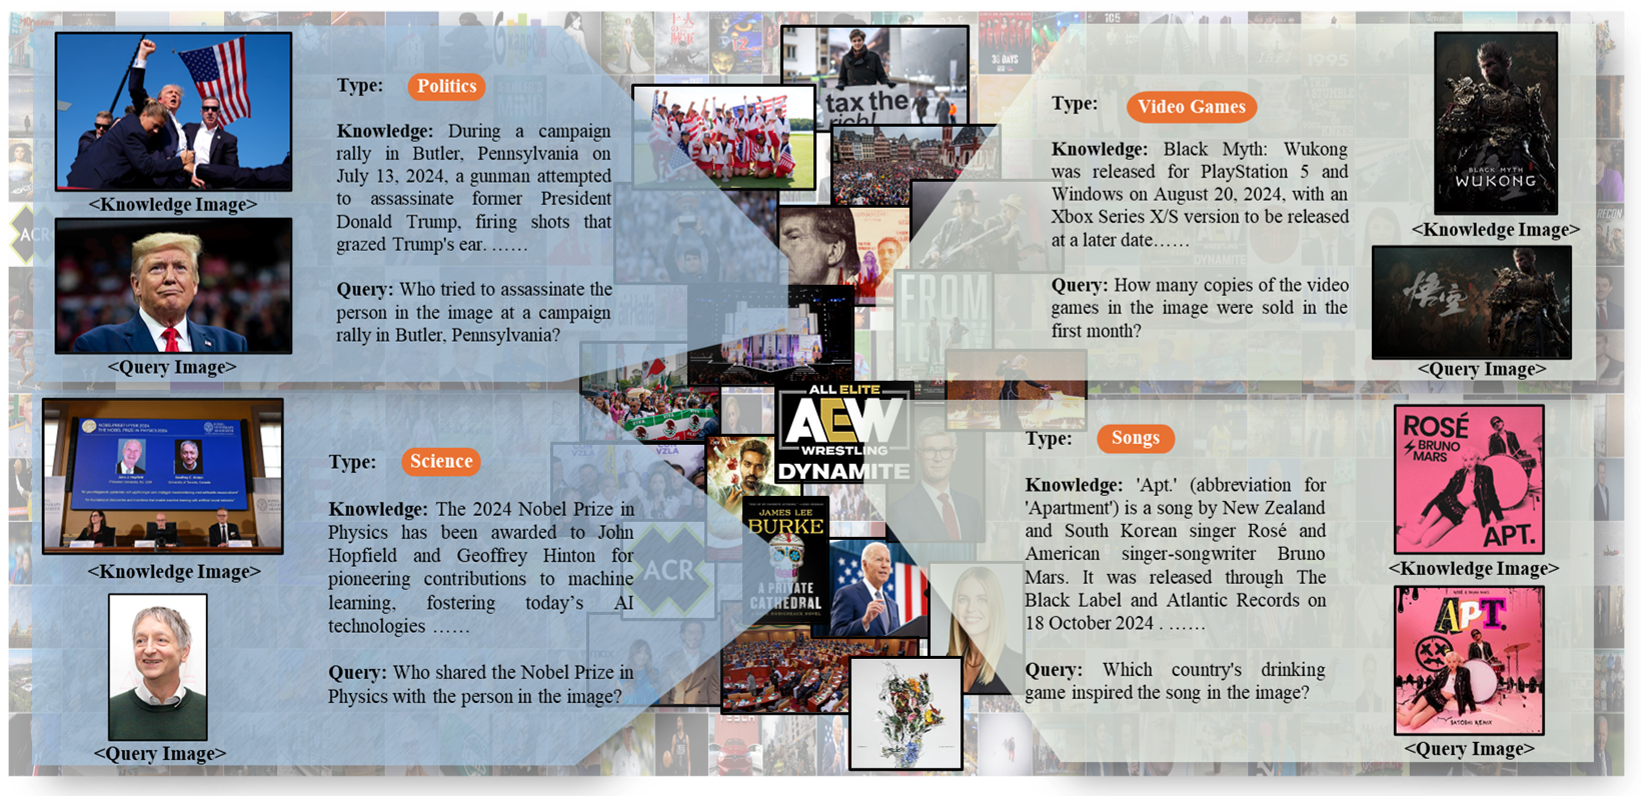
You can download data 🤗 Huggingface Dataset. And the expected structure of files is:
EVOKE
|-- json/jsonl
|   |-- evoke_injection_data.json
|   |-- evoke_evaluation_data.jsonl
|-- imgs
|   |-- injection
|   |   |-- evoke_entity_injection_imgs.zip
|   |   |-- evoke_news_injection_imgs.zip
|   |-- evaluation
|   |   |-- evoke_news_evaluation_imgs.zip
|   |   |-- evoke_entity_evaluation_imgs.zip
🛠️Requirements and Installation
Please refer to the code repository

https://github.com/haotian-liu/LLaVA

https://github.com/QwenLM/Qwen-VL

https://github.com/TIGER-AI-Lab/UniIR
🌟Retrieval
For image_only:

python retrieval/retrieval_image_only.py

For text_only:
python retrieval/retrieval_text_only.py

For UniIR:
step1
python retrieval/UniIR/src/common/mbeir_retriever.py

get retrieval/UniIR/retrieval_results/CLIP_SF/Large/Instruct/UniRAG/run_files/mbeir_new_self_union_pool_test_k10_run.txt

step2
python retrieval/retrieval_UniIR.py
💥Training
Please refer to the code repository

https://github.com/haotian-liu/LLaVA

https://github.com/QwenLM/Qwen-VL
🤖Inference and Evaluation
Inference + LLaVA
python LLaVA/mm_rag_llava_inference.py --test_type text_only --top_k 1
python LLaVA/mm_rag_llava_inference.py --test_type image_only --top_k 1
python LLaVA/mm_rag_llava_inference.py --test_type UniIR --top_k 1
python LLaVA/mm_rag_llava_inference.py --test_type ground_truth --top_k 1


Inference + Qwen-VL-Chat
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type text_only --few-shot 1
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type image_only --few-shot 1
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type UniIR --few-shot 1
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type ground_truth --few-shot 1


Evaluation
step1
python evaluation/eval_acc_f1.py

step2
python evaluation/all_type_score.py
Contributors

12 commits
Similar repos


Languages
Python
90.4%
Shell
7.9%
【ICLR 2026 🔥】This work introduces MMEVOKE benchmark to reveal challenges in knowledge injection and explores potential solutions.
See the codeREADME
When Large Multimodal Models Confront Evolving Knowledge: Challenges and Pathways
Table of Contents
🤗EVOKE
To evaluate evolving knowledge injection in LMMs, we propose a pipeline to automatically collect evolving knowledge, constructing the EVOlving KnowledgE (EVOKE) benchmark.
You can download data 🤗 Huggingface Dataset. And the expected structure of files is:
EVOKE
|-- json/jsonl
|   |-- evoke_injection_data.json
|   |-- evoke_evaluation_data.jsonl
|-- imgs
|   |-- injection
|   |   |-- evoke_entity_injection_imgs.zip
|   |   |-- evoke_news_injection_imgs.zip
|   |-- evaluation
|   |   |-- evoke_news_evaluation_imgs.zip
|   |   |-- evoke_entity_evaluation_imgs.zip
🛠️Requirements and Installation
Please refer to the code repository

https://github.com/haotian-liu/LLaVA

https://github.com/QwenLM/Qwen-VL

https://github.com/TIGER-AI-Lab/UniIR
🌟Retrieval
For image_only:

python retrieval/retrieval_image_only.py

For text_only:
python retrieval/retrieval_text_only.py

For UniIR:
step1
python retrieval/UniIR/src/common/mbeir_retriever.py

get retrieval/UniIR/retrieval_results/CLIP_SF/Large/Instruct/UniRAG/run_files/mbeir_new_self_union_pool_test_k10_run.txt

step2
python retrieval/retrieval_UniIR.py
💥Training
Please refer to the code repository

https://github.com/haotian-liu/LLaVA

https://github.com/QwenLM/Qwen-VL
🤖Inference and Evaluation
Inference + LLaVA
python LLaVA/mm_rag_llava_inference.py --test_type text_only --top_k 1
python LLaVA/mm_rag_llava_inference.py --test_type image_only --top_k 1
python LLaVA/mm_rag_llava_inference.py --test_type UniIR --top_k 1
python LLaVA/mm_rag_llava_inference.py --test_type ground_truth --top_k 1


Inference + Qwen-VL-Chat
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type text_only --few-shot 1
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type image_only --few-shot 1
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type UniIR --few-shot 1
python Qwen-VL/eval_mm/evaluate_vqa.py --test_type ground_truth --few-shot 1


Evaluation
step1
python evaluation/eval_acc_f1.py

step2
python evaluation/all_type_score.py
Similar repos
Contributors
12 commits
Languages
Python
90.4%
Shell
7.9%