
[ICML 2024 Oral] Official code repository for MLLM-as-a-Judge.
See the codeREADME
MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark



Updates & News
- [01/06/2024] :star: Our paper is accepted by ICML 2024 Oral!
- [20/03/2024] :star: We release our complete dataset with guidelines and scripts for benchmarking current VLMs!
- [14/02/2024] :page_facing_up: We release our paper on Arxiv today!
Contents
- Updates & News
- Contents
- Benchmark:MLLM-as-a-Judge
- Benchmark mainstream MLLMs
- Contributing
- Acknowledgments
- Citation
Benchmark:MLLM-as-a-Judge
This benchmark is structured into three main components: images, the main dataset, and sub-datasets. The arrangement is as follows:
/MLLM-Judge
├── Figures (images for github repository)
├── Datasets
│   ├── Images (images for Benchmark)
│   ├── Benchmark
│   │   ├── batch.jsonl
│   │   ├── pair.jsonl
│   │   └── score.jsonl
│   │
│   └── raw_data
│       ├── step1
│       ├── step2
│       └── step3
│
└── Hard & HQ
    ├── Hard
    └── HQ
-
Figures: Contains images for the GitHub repository. These images are used to illustrate and explain the contents of the repository, aiding users in better understanding the project.
-
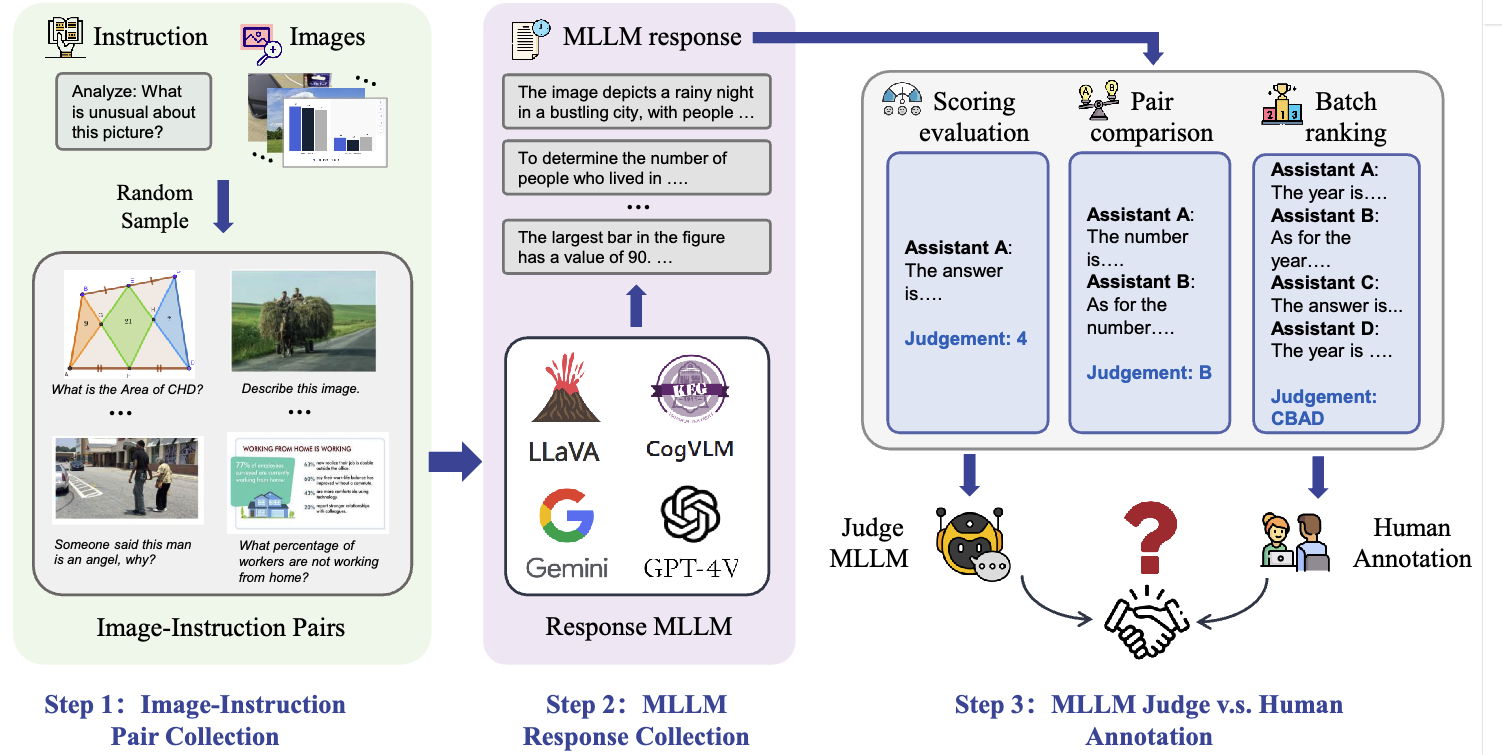
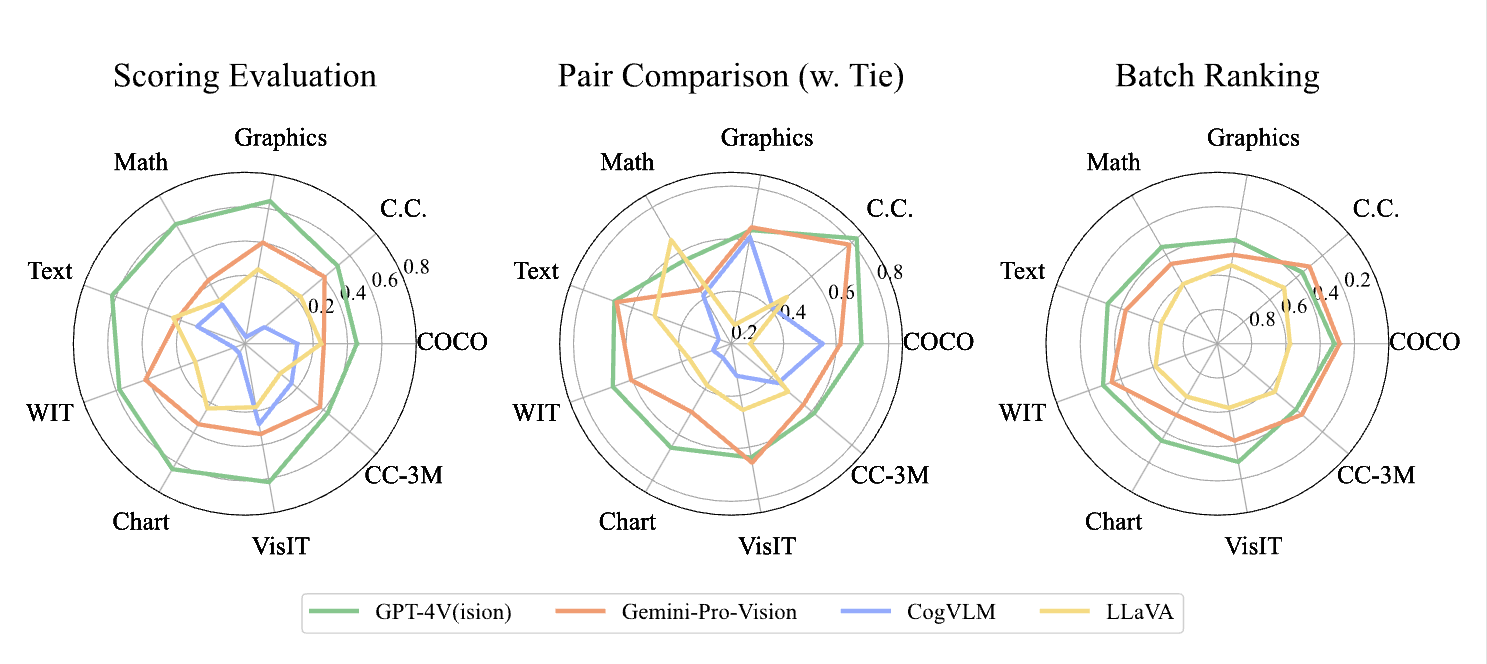
Dataset/: This part of the dataset is developed in three steps, mirroring the structure outlined in our article. It includes MLLM outputs under three different settings: Scoring Evaluation, Pair Comparison, and Batch Ranking. Additionally, this section encompasses human annotation results and agreement data. In Scoring Evaluation, we also include responses data in a verbose setting for our ablation study.
- Benchmark: The Final dataset with human annotations used as a benchmark to assess model performance. These annotations provide a reliable reference to verify if the model's judgments align with human evaluations.
raw_data/step1: Contains original image-instruction pairs selected from 10 datasets. This is the starting point for data processing and model training, containing the initial input data.raw_data/step2: Contains response data generated by four different MLLMs. This step aims to enrich the dataset and increase its diversity by generating data through multiple models.raw_data/step3: Divides the data from step2 into three parts, each under different settings, containing responses from various MLLM Judges. This helps analyze and compare the performance differences across models under the same tasks.
-
Dataset/Hard & HQ: Contains two specially curated datasets for specific data analysis and model training purposes:- Hard: Includes samples considered difficult under three different settings. This data is used to test and improve MLLM capabilities in dealing with complex scenarios.
- HQ (High Quality): Contains samples where the MLLM-as-a-Judge performed well. These high-quality samples help understand under what conditions the model performs best.
-
Dataset/image: All images utilized in our study are contained in this section. You can download all images by cloning this repository.
Benchmark mainstream MLLMs
via API
We benchmark GPT-4V(ision), Gemini, Qwen, LLaVA-1.6 via API. You can replicate our experiment result by running the following scripts:
python scripts/api_benchmark.py \
--model <> \ # 'gemini', 'gpt-4v', 'gpt-4o', 'llava-1.6-34b', 'llava-1.6-13b', 'llava-1.6-7b', 'qwen-vl-plus', 'qwen-vl-max', 'qwen-vl-chat'
--judge_mode <> \ # 'score', 'batch', 'pair'
--temperature <> \ # default as 0.4
--top_p <> \ # default as 0.2
--image_dir <path to image> \
--setting <> \ # ablation study for COT, default as No COT
Contributing
Contributions to this project are welcome. Please consider the following ways to contribute:
- Reporting issues
- Proposing new features or improvements
- Benchmark other mainstream MLLMs
Acknowledgments
This project is based on the findings and methodologies presented in the paper LLM-as-a-Judge and HallusionBench.
Citation
@misc{chen2024mllmasajudge,
      title={MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark},
      author={Dongping Chen and Ruoxi Chen and Shilin Zhang and Yinuo Liu and Yaochen Wang and Huichi Zhou and Qihui Zhang and Pan Zhou and Yao Wan and Lichao Sun},
      year={2024},
      eprint={2402.04788},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
Significant stargazers

8 followers · starred Aug 2024
Similar repos





Languages
Python
60.1%
Jupyter Notebook
39.9%
[ICML 2024 Oral] Official code repository for MLLM-as-a-Judge.
See the codeREADME
MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark
Updates & News
- [01/06/2024] :star: Our paper is accepted by ICML 2024 Oral!
- [20/03/2024] :star: We release our complete dataset with guidelines and scripts for benchmarking current VLMs!
- [14/02/2024] :page_facing_up: We release our paper on Arxiv today!
Contents
- Updates & News
- Contents
- Benchmark:MLLM-as-a-Judge
- Benchmark mainstream MLLMs
- Contributing
- Acknowledgments
- Citation
Benchmark:MLLM-as-a-Judge
This benchmark is structured into three main components: images, the main dataset, and sub-datasets. The arrangement is as follows:
/MLLM-Judge
├── Figures (images for github repository)
├── Datasets
│   ├── Images (images for Benchmark)
│   ├── Benchmark
│   │   ├── batch.jsonl
│   │   ├── pair.jsonl
│   │   └── score.jsonl
│   │
│   └── raw_data
│       ├── step1
│       ├── step2
│       └── step3
│
└── Hard & HQ
    ├── Hard
    └── HQ
-
Figures: Contains images for the GitHub repository. These images are used to illustrate and explain the contents of the repository, aiding users in better understanding the project.
-
Dataset/: This part of the dataset is developed in three steps, mirroring the structure outlined in our article. It includes MLLM outputs under three different settings: Scoring Evaluation, Pair Comparison, and Batch Ranking. Additionally, this section encompasses human annotation results and agreement data. In Scoring Evaluation, we also include responses data in a verbose setting for our ablation study.
- Benchmark: The Final dataset with human annotations used as a benchmark to assess model performance. These annotations provide a reliable reference to verify if the model's judgments align with human evaluations.
raw_data/step1: Contains original image-instruction pairs selected from 10 datasets. This is the starting point for data processing and model training, containing the initial input data.raw_data/step2: Contains response data generated by four different MLLMs. This step aims to enrich the dataset and increase its diversity by generating data through multiple models.raw_data/step3: Divides the data from step2 into three parts, each under different settings, containing responses from various MLLM Judges. This helps analyze and compare the performance differences across models under the same tasks.
-
Dataset/Hard & HQ: Contains two specially curated datasets for specific data analysis and model training purposes:- Hard: Includes samples considered difficult under three different settings. This data is used to test and improve MLLM capabilities in dealing with complex scenarios.
- HQ (High Quality): Contains samples where the MLLM-as-a-Judge performed well. These high-quality samples help understand under what conditions the model performs best.
-
Dataset/image: All images utilized in our study are contained in this section. You can download all images by cloning this repository.
Benchmark mainstream MLLMs
via API
We benchmark GPT-4V(ision), Gemini, Qwen, LLaVA-1.6 via API. You can replicate our experiment result by running the following scripts:
python scripts/api_benchmark.py \
--model <> \ # 'gemini', 'gpt-4v', 'gpt-4o', 'llava-1.6-34b', 'llava-1.6-13b', 'llava-1.6-7b', 'qwen-vl-plus', 'qwen-vl-max', 'qwen-vl-chat'
--judge_mode <> \ # 'score', 'batch', 'pair'
--temperature <> \ # default as 0.4
--top_p <> \ # default as 0.2
--image_dir <path to image> \
--setting <> \ # ablation study for COT, default as No COT
Contributing
Contributions to this project are welcome. Please consider the following ways to contribute:
- Reporting issues
- Proposing new features or improvements
- Benchmark other mainstream MLLMs
Acknowledgments
This project is based on the findings and methodologies presented in the paper LLM-as-a-Judge and HallusionBench.
Citation
@misc{chen2024mllmasajudge,
      title={MLLM-as-a-Judge: Assessing Multimodal LLM-as-a-Judge with Vision-Language Benchmark},
      author={Dongping Chen and Ruoxi Chen and Shilin Zhang and Yinuo Liu and Yaochen Wang and Huichi Zhou and Qihui Zhang and Pan Zhou and Yao Wan and Lichao Sun},
      year={2024},
      eprint={2402.04788},
      archivePrefix={arXiv},
      primaryClass={cs.CL}
}
Similar repos
Significant stargazers
8 followers · starred Aug 2024
Languages
Python
60.1%
Jupyter Notebook
39.9%