FinnewsHunter: Multi-agent financial intelligence platform powered by AgenticX. Real-time news analysis, sentiment fusion, and alpha factor mining.
Python
1,499
353 commits
updated Oct 1, 2026
An enterprise-grade financial news analysis system built on the AgenticX framework, integrating real-time news streams, deep quantitative analysis, and multi-agent debate mechanisms.
FinnewsHunter goes beyond traditional text classification by deploying multi-agent teams (NewsAnalyst, Researcher, etc.) to monitor multiple financial news sources in real-time, including Sina Finance, National Business Daily, Financial World, Securities Times, and more. It leverages large language models for deep interpretation, sentiment analysis, and market impact assessment, combined with knowledge graphs to mine potential investment opportunities and risks, providing decision-level alpha signals for quantitative trading.
BailianEmbeddingProvider and MilvusStorage, avoiding reinventing the wheel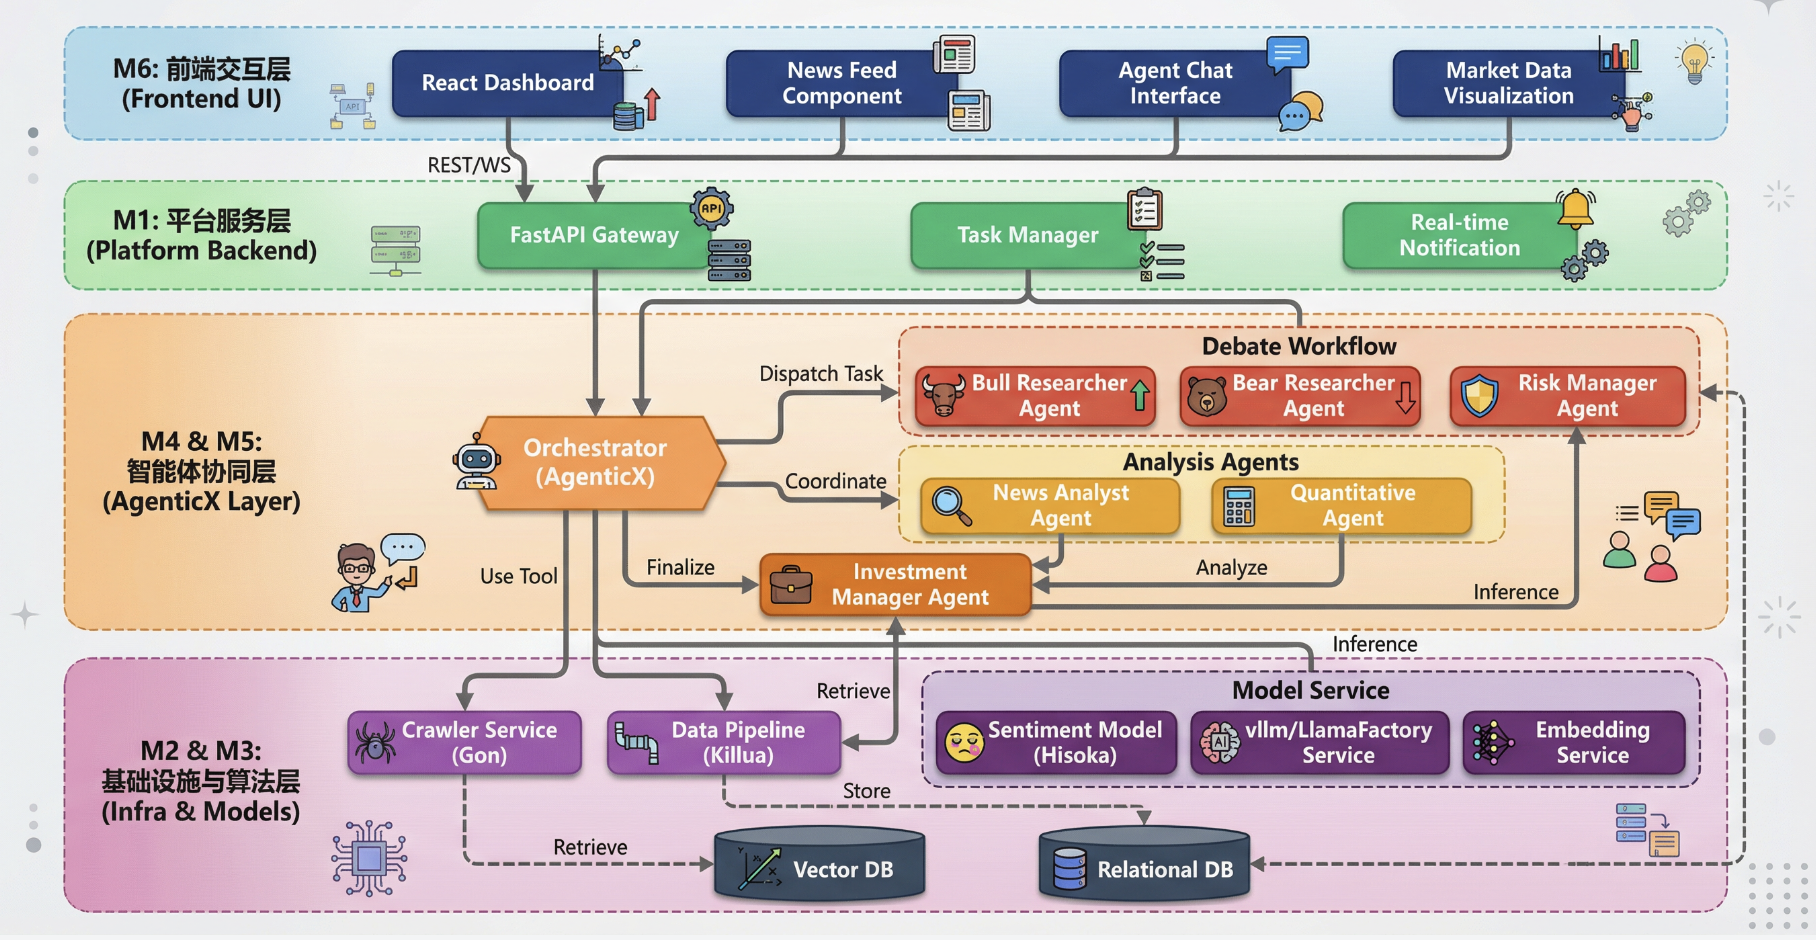
The system adopts a layered architecture design:
cd /Users/damon/myWork/AgenticX
pip install -e .
cd FinnewsHunter/backend
pip install -r requirements.txt
cd FinnewsHunter/backend
cp env.example .env
# Edit .env file and fill in LLM API Key and other configurations
Multi-Provider LLM Configuration:
The system supports 5 LLM providers, at least one needs to be configured:
| Provider | Environment Variable | Registration URL |
|---|---|---|
| Bailian (Alibaba Cloud) | DASHSCOPE_API_KEY | https://dashscope.console.aliyun.com/ |
| OpenAI | OPENAI_API_KEY | https://platform.openai.com/api-keys |
| DeepSeek | DEEPSEEK_API_KEY | https://platform.deepseek.com/ |
| Kimi (Moonshot) | MOONSHOT_API_KEY | https://platform.moonshot.cn/ |
| Zhipu | ZHIPU_API_KEY | https://open.bigmodel.cn/ |
Example Configuration (Recommended: Bailian):
# Bailian (Alibaba Cloud) - Recommended, fast access in China
DASHSCOPE_API_KEY=sk-your-dashscope-key
DASHSCOPE_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
BAILIAN_MODELS=qwen-plus,qwen-max,qwen-turbo

# Optional: Other providers
OPENAI_API_KEY=sk-your-openai-key
DEEPSEEK_API_KEY=sk-your-deepseek-key
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml up -d postgres redis milvus-etcd milvus-minio milvus-standalone
cd FinnewsHunter/backend
python init_db.py
cd FinnewsHunter/backend
python -m app.scripts.init_stocks
# Will fetch all A-share data (approximately 5000+ stocks) from akshare and save to database
cd FinnewsHunter/backend
uvicorn app.main:app --reload --host 0.0.0.0 --port 8000
# Open a new terminal
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml up -d celery-worker celery-beat
# Open a new terminal
cd FinnewsHunter/frontend
npm install  # First time requires dependency installation
npm run dev
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml ps
cd FinnewsHunter

# Restart Docker services (infrastructure + Celery)
docker compose -f deploy/docker-compose.dev.yml restart

# If backend API is started independently, manually restart it
# Press Ctrl+C to stop backend process, then rerun:
cd backend
uvicorn app.main:app --reload --host 0.0.0.0 --port 8000
cd FinnewsHunter

# Restart only Celery (after code changes)
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat

# Restart only database
docker compose -f deploy/docker-compose.dev.yml restart postgres

# Restart only Redis
docker compose -f deploy/docker-compose.dev.yml restart redis
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml down
cd FinnewsHunter

# View Celery Worker logs
docker compose -f deploy/docker-compose.dev.yml logs -f celery-worker

# View Celery Beat logs (scheduled task dispatch)
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat

# View PostgreSQL logs
docker compose -f deploy/docker-compose.dev.yml logs -f postgres

# View all service logs
docker compose -f deploy/docker-compose.dev.yml logs -f
cd FinnewsHunter

# Execute reset script
./reset_all_data.sh

# Enter yes to confirm
The script will automatically complete:
After execution, wait:
# Enter PostgreSQL container
docker exec -it finnews_postgres psql -U finnews -d finnews_db
Execute in PostgreSQL command line:
-- Clear news table
DELETE FROM news;

-- Clear task table
DELETE FROM crawl_tasks;

-- Clear analysis table
DELETE FROM analyses;

-- Reset auto-increment IDs
ALTER SEQUENCE news_id_seq RESTART WITH 1;
ALTER SEQUENCE crawl_tasks_id_seq RESTART WITH 1;
ALTER SEQUENCE analyses_id_seq RESTART WITH 1;

-- Verify results (should all be 0)
SELECT 'news table', COUNT(*) FROM news;
SELECT 'crawl_tasks table', COUNT(*) FROM crawl_tasks;
SELECT 'analyses table', COUNT(*) FROM analyses;

-- Exit
\q
cd FinnewsHunter
docker exec finnews_redis redis-cli FLUSHDB
cd FinnewsHunter/backend
rm -f celerybeat-schedule*
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat
# Check news count (should be 0)
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT COUNT(*) FROM news;"

# Check Redis (should be 0 or very small)
docker exec finnews_redis redis-cli DBSIZE

# Check if Celery has started crawling
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat
# Should see 10 crawl tasks triggered per minute
cd FinnewsHunter/backend
python reset_database.py
# Enter yes to confirm
Use Case: When reset script doesn't work, this is the fastest method
cd FinnewsHunter

# Step 1: Clear database tables
docker exec finnews_postgres psql -U finnews -d finnews_db -c "DELETE FROM news; DELETE FROM crawl_tasks; DELETE FROM analyses;"

# Step 2: Reset auto-increment IDs
docker exec finnews_postgres psql -U finnews -d finnews_db -c "ALTER SEQUENCE news_id_seq RESTART WITH 1; ALTER SEQUENCE crawl_tasks_id_seq RESTART WITH 1; ALTER SEQUENCE analyses_id_seq RESTART WITH 1;"

# Step 3: Clear Redis cache
docker exec finnews_redis redis-cli FLUSHDB

# Step 4: Clear Celery schedule files
rm -f backend/celerybeat-schedule*

# Step 5: Restart Celery services
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat

# Step 6: Verify cleared (should display 0)
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT COUNT(*) FROM news;"
Immediately refresh browser after execution:
Command + Shift + RCtrl + Shift + RAfter data is cleared, frontend may still display old data due to browser cache.
Mac System:
Press Command + Shift + R
or Command + Option + R
Windows/Linux System:
Press Ctrl + Shift + R
or Ctrl + F5
F12 to open developer toolsChrome/Edge:
Command + Shift + Delete (Mac) or Ctrl + Shift + Delete (Windows)After refreshing page, hard refresh again
# Press Ctrl+C in frontend terminal to stop service
# Then restart
cd FinnewsHunter/frontend
npm run dev
| Time | Event | Expected Result |
|---|---|---|
| 0 min | Execute reset script | Database cleared, Redis cleared |
| 1 min | Celery Beat starts scheduling | 10 crawl tasks triggered |
| 2-5 min | First batch of news saved | Database starts having data |
| 5-10 min | All sources have data | Frontend can see 100+ news |
| 30 min | Data continues growing | 500+ news |
| 1 hour | Stable operation | 1000-2000 news |
Notes:
Steps to immediately hard refresh frontend after reset:
Command + Shift + R (Mac) or Ctrl + Shift + R (Windows) in browsercd FinnewsHunter
# View news count by source
docker exec finnews_postgres psql -U finnews -d finnews_db -c "
SELECT source, COUNT(*) as count
FROM news
WHERE created_at > NOW() - INTERVAL '1 hour'
GROUP BY source
ORDER BY count DESC;
"
# View recent crawl task status
docker exec finnews_postgres psql -U finnews -d finnews_db -c "
SELECT source,
crawled_count,
saved_count,
status,
error_message
FROM crawl_tasks
WHERE created_at > NOW() - INTERVAL '10 minutes'
ORDER BY created_at DESC
LIMIT 20;
"
cd FinnewsHunter

# View ERROR logs
docker compose -f deploy/docker-compose.dev.yml logs celery-worker | grep ERROR

# View specific source issues
docker compose -f deploy/docker-compose.dev.yml logs celery-worker | grep "jwview"
System is configured with automatic crawling for 10 news sources:
How it works:
View crawl progress:
# View Celery Beat scheduling logs
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat

# View Celery Worker execution logs
docker compose -f deploy/docker-compose.dev.yml logs -f celery-worker
Method 1: Via Frontend
Method 2: Via API
# Force refresh Sina Finance
curl -X POST "http://localhost:8000/api/v1/news/refresh?source=sina"

# Force refresh all sources (need to call individually)
for source in sina tencent jwview eeo caijing jingji21 nbd yicai 163 eastmoney; do
  curl -X POST "http://localhost:8000/api/v1/news/refresh?source=$source"
  sleep 1
done
Method 1: Via Frontend (Recommended)
Method 2: Via API
# Get latest news from all sources (200 items)
curl "http://localhost:8000/api/v1/news/latest?limit=200"

# Get news from specific source
curl "http://localhost:8000/api/v1/news/latest?source=sina&limit=50"

# Filter by sentiment (using old API)
curl "http://localhost:8000/api/v1/news/?sentiment=positive&limit=20"

# Get all available news source list
curl "http://localhost:8000/api/v1/news/sources"
Frontend Operations:
Batch Selection:
Batch Delete:
Batch Analysis:
API Operations:
# Batch delete news
curl -X POST "http://localhost:8000/api/v1/news/batch/delete" \
  -H "Content-Type: application/json" \
  -d '{"news_ids": [1, 2, 3]}'

# Batch analyze news
curl -X POST "http://localhost:8000/api/v1/analysis/batch" \
  -H "Content-Type: application/json" \
  -d '{"news_ids": [1, 2, 3], "provider": "bailian", "model": "qwen-plus"}'
Method 1: Via Frontend
Method 2: Via API
# Analyze news with specified ID (using default model)
curl -X POST http://localhost:8000/api/v1/analysis/news/1

# Analyze news (specify model)
curl -X POST http://localhost:8000/api/v1/analysis/news/1 \
  -H "Content-Type: application/json" \
  -d '{"provider": "bailian", "model": "qwen-max"}'

# View analysis results
curl http://localhost:8000/api/v1/analysis/1
Frontend Operations:
Supported Models:
API to Get Available Model List:
curl http://localhost:8000/api/v1/llm/config
Frontend Operations:
Search Examples:
600519 (Kweichow Moutai)新能源 (new energy), 半导体 (semiconductor)sina, eastmoneyFrontend Operations:
Frontend Operations:
茅台 (Moutai), 600519)API Operations:
# Get K-line data (daily, default 180 items)
curl "http://localhost:8000/api/v1/stocks/SH600519/kline?period=daily&limit=180"

# Get minute K-line (60-minute line)
curl "http://localhost:8000/api/v1/stocks/SH600519/kline?period=60m&limit=200"

# Search stocks
curl "http://localhost:8000/api/v1/stocks/search/realtime?q=茅台&limit=10"

# View stock count in database
curl "http://localhost:8000/api/v1/stocks/count"
Frontend Operations:
Homepage (Dashboard)
News Feed Page
API Operations:
# View Sina Finance news
curl "http://localhost:8000/api/v1/news/latest?source=sina&limit=50"

# View National Business Daily news
curl "http://localhost:8000/api/v1/news/latest?source=nbd&limit=50"

# View all sources
curl "http://localhost:8000/api/v1/news/latest?limit=200"
FinnewsHunter/
├── backend/                    # Backend service
│   ├── app/
│   │   ├── agents/            # Agent definitions (NewsAnalyst, debate agents, etc.)
│   │   ├── api/v1/            # FastAPI routes
│   │   │   ├── analysis.py    # Analysis API (supports batch analysis)
│   │   │   ├── llm_config.py  # LLM config API
│   │   │   ├── news_v2.py     # News API (supports batch delete)
│   │   │   └── ...
│   │   ├── core/              # Core configuration (config, database, redis, neo4j)
│   │   ├── models/            # SQLAlchemy data models
│   │   ├── services/          # Business services
│   │   │   ├── llm_service.py      # LLM service (multi-provider support)
│   │   │   ├── analysis_service.py # Analysis service (async vectorization)
│   │   │   ├── embedding_service.py # Vectorization service (based on AgenticX BailianEmbeddingProvider)
│   │   │   └── stock_data_service.py # Stock data service
│   │   ├── storage/           # Storage wrapper
│   │   │   └── vector_storage.py # Milvus vector storage (based on AgenticX MilvusStorage)
│   │   ├── tasks/             # Celery tasks
│   │   └── tools/              # AgenticX tools (Crawler, Cleaner)
│   ├── tests/                 # Test and utility scripts
│   │   ├── check_milvus_data.py           # Check Milvus vector storage data
│   │   ├── check_news_embedding_status.py # Check news vectorization status
│   │   └── manual_vectorize.py           # Manually vectorize specified news
│   ├── env.example            # Environment variable template
│   └── requirements.txt       # Python dependencies
├── frontend/                  # React frontend
│   └── src/
│       ├── components/        # Components
│       │   ├── ModelSelector.tsx    # LLM model selector
│       │   ├── NewsDetailDrawer.tsx # News detail drawer
│       │   └── HighlightText.tsx    # Keyword highlighting
│       ├── context/           # React Context
│       ├── hooks/             # Custom Hooks
│       │   └── useDebounce.ts # Debounce Hook
│       ├── layout/            # Layout components
│       └── pages/             # Page components
│           └── NewsListPage.tsx # News list page (supports batch operations)
├── deploy/                    # Deployment configuration
│   ├── docker-compose.dev.yml # Docker Compose configuration
│   ├── Dockerfile.celery     # Celery image build file
│   └── celery-entrypoint.sh  # Celery container startup script
├── conclusions/               # Module summary documentation
│   ├── backend/              # Backend module summaries
│   └── frontend/             # Frontend module summaries
└── .dev-docs/                 # Development documentation
Start All Services
./start.sh
Check Docker Container Status
docker ps
# Should see: postgres, redis, milvus-standalone, milvus-etcd, milvus-minio
Test News Crawling
curl -X POST http://localhost:8000/api/v1/news/crawl \
  -H "Content-Type: application/json" \
  -d '{"source": "sina", "start_page": 1, "end_page": 1}'

# Wait 5-10 seconds then check results
curl http://localhost:8000/api/v1/news/?limit=5
Test Agent Analysis
# Get first news ID
NEWS_ID=$(curl -s http://localhost:8000/api/v1/news/?limit=1 | jq '.[0].id')

# Trigger analysis
curl -X POST http://localhost:8000/api/v1/analysis/news/$NEWS_ID

# View analysis results
curl http://localhost:8000/api/v1/analysis/1
Test Frontend Interface
frontend/index.htmlSymptom: Backend startup error could not connect to database
Solution:
cd FinnewsHunter

# Check if PostgreSQL is running
docker ps | grep postgres

# View logs
docker compose -f deploy/docker-compose.dev.yml logs postgres

# Restart container
docker compose -f deploy/docker-compose.dev.yml restart postgres

# Wait 30 seconds then retry backend startup
Symptom: Frontend shows 0 news count, no automatic crawling
Troubleshooting Steps:
cd FinnewsHunter

# 1. Check if Celery Worker is running
docker ps | grep celery

# 2. View Celery Beat logs (should see tasks triggered every minute)
docker compose -f deploy/docker-compose.dev.yml logs celery-beat --tail=100

# 3. View Celery Worker logs (check task execution)
docker compose -f deploy/docker-compose.dev.yml logs celery-worker --tail=100

# 4. Check Redis connection
docker exec finnews_redis redis-cli PING
# Should return PONG

# 5. Restart Celery services
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat
Symptom: Celery logs show 404 Client Error: Not Found
Cause: News website URL has changed
Solution:
# 1. Manually visit URL to verify if available
curl -I https://finance.caijing.com.cn/

# 2. If URL changed, update corresponding crawler configuration
# Edit backend/app/tools/{source}_crawler.py
# Update BASE_URL and STOCK_URL

# 3. Clear Python cache
cd FinnewsHunter/backend
find . -type d -name __pycache__ -exec rm -rf {} + 2>/dev/null || true

# 4. Restart Celery
cd ..
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat
Symptom: Other 9 sources have no news
Possible Causes:
Solution:
cd FinnewsHunter

# 1. Check Celery Beat configuration
docker compose -f deploy/docker-compose.dev.yml logs celery-beat | grep "crawl-"
# Should see 10 scheduled tasks (crawl-sina, crawl-tencent, ..., crawl-eastmoney)

# 2. Manually test single source crawling
docker exec -it finnews_celery_worker python -c "
from app.tools import get_crawler_tool
crawler = get_crawler_tool('nbd')  # Test National Business Daily
news = crawler.crawl()
print(f'Crawled {len(news)} news items')
"

# 3. View data volume by source in database
docker exec finnews_postgres psql -U finnews -d finnews_db -c "
SELECT source, COUNT(*) as count
FROM news
GROUP BY source
ORDER BY count DESC;
"

# 4. If a source keeps failing, view detailed errors
docker compose -f deploy/docker-compose.dev.yml logs celery-worker | grep "ERROR"
Symptom: Analysis functionality not working, error LLM Provider NOT provided
Solution:
cd FinnewsHunter/backend

# 1. Check if API Key is configured
grep -E "DASHSCOPE_API_KEY|OPENAI_API_KEY|DEEPSEEK_API_KEY" .env

# 2. Check if Base URL is correct (Bailian must configure)
grep DASHSCOPE_BASE_URL .env
# Should be: https://dashscope.aliyuncs.com/compatible-mode/v1

# 3. Verify LLM config API is normal
curl http://localhost:8000/api/v1/llm/config | jq '.providers[].has_api_key'
# At least one should return true

# 4. If using Bailian, ensure complete configuration
cat >> .env << EOF
DASHSCOPE_API_KEY=sk-your-key
DASHSCOPE_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
BAILIAN_MODELS=qwen-plus,qwen-max
EOF

# 5. Restart backend service
Symptom: Frontend cannot load data, browser Console shows CORS error
Solution:
# 1. Check backend CORS configuration
cd FinnewsHunter/backend
grep BACKEND_CORS_ORIGINS .env
# Should include http://localhost:3000

# 2. Check frontend API address configuration
cd ../frontend
cat .env
# VITE_API_URL should be http://localhost:8000

# 3. Hard refresh browser
# Chrome/Edge: Ctrl+Shift+R (Windows) or Cmd+Shift+R (Mac)

# 4. Restart frontend dev server
npm run dev
Symptom: Vector search functionality not working
Solution:
cd FinnewsHunter

# Milvus requires longer startup time (approximately 60 seconds)
docker compose -f deploy/docker-compose.dev.yml logs milvus-standalone

# Check health status
docker inspect finnews_milvus | grep -A 10 Health

# Restart Milvus related services
docker compose -f deploy/docker-compose.dev.yml restart milvus-etcd milvus-minio milvus-standalone
Symptom: Homepage shows news count doesn't match actual
Solution:
# Use reset script to clear data and start fresh
cd FinnewsHunter
./reset_all_data.sh
cd FinnewsHunter

# View all container status
docker compose -f deploy/docker-compose.dev.yml ps

# View complete logs for a service
docker compose -f deploy/docker-compose.dev.yml logs celery-worker --tail=500

# Enter container for debugging
docker exec -it finnews_celery_worker bash

# View database connection
docker exec finnews_postgres psql -U finnews -d finnews_db -c "\conninfo"

# View Redis connection
docker exec finnews_redis redis-cli INFO

# Test network connectivity
docker exec finnews_celery_worker ping -c 3 postgres
cd FinnewsHunter
# Start all services
docker compose -f deploy/docker-compose.dev.yml up -d

# Stop all services
docker compose -f deploy/docker-compose.dev.yml down

# Restart Celery (after code updates)
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat

# Clear all data and start fresh
./reset_all_data.sh
# Service status
docker compose -f deploy/docker-compose.dev.yml ps

# News count
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT source, COUNT(*) FROM news GROUP BY source;"

# Task count
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT status, COUNT(*) FROM crawl_tasks GROUP BY status;"

# Redis cache
docker exec finnews_redis redis-cli DBSIZE
# Celery Beat (scheduled dispatch)
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat

# Celery Worker (task execution)
docker compose -f deploy/docker-compose.dev.yml logs -f celery-worker

# PostgreSQL
docker compose -f deploy/docker-compose.dev.yml logs -f postgres

# All services
docker compose -f deploy/docker-compose.dev.yml logs -f
BaseCrawler classcrawl() methodtools/__init__.pyExample:
# backend/app/tools/custom_crawler.py
from .crawler_base import BaseCrawler

class CustomCrawlerTool(BaseCrawler):
    name = "custom_crawler"

    def crawl(self, start_page, end_page):
        # Implement crawling logic
        pass
For scenarios requiring JS rendering or intelligent content extraction, use enhanced crawler:
from app.tools.crawler_enhanced import crawl_url, EnhancedCrawler

# Quick crawl single URL
article = crawl_url("https://finance.sina.com.cn/xxx", engine='auto')
print(article.to_markdown())

# Get LLM message format (multimodal)
llm_messages = article.to_llm_message()

# Batch crawl (with cache)
crawler = EnhancedCrawler(use_cache=True)
articles = crawler.crawl_batch(urls, delay=1.0)
Supported Engines:
requests: Basic HTTP requests (default)playwright: JS rendering (requires playwright install chromium)jina: Jina Reader API (requires JINA_API_KEY configuration)auto: Automatically select best engineInstall Optional Dependencies:
pip install markdownify readabilipy playwright
playwright install chromium  # Optional, for JS rendering
Agent classExample:
# backend/app/agents/risk_analyst.py
from agenticx import Agent

class RiskAnalystAgent(Agent):
    def __init__(self, llm_provider):
        super().__init__(
            name="RiskAnalyst",
            role="Risk Analyst",
            goal="Assess investment risks",
            llm_provider=llm_provider
        )
FinnewsHunter deeply integrates AgenticX framework core components to avoid reinventing the wheel:
The system uses agenticx.embeddings.BailianEmbeddingProvider as the core embedding engine:
from app.services.embedding_service import EmbeddingService

# Synchronous interface (for sync contexts)
embedding_service = EmbeddingService()
vector = embedding_service.embed_text("text content")

# Asynchronous interface (recommended for async contexts)
vector = await embedding_service.aembed_text("text content")

# Batch processing (Provider handles internal batching)
vectors = embedding_service.embed_batch(["text1", "text2", "text3"])
Features:
The system uses agenticx.storage.vectordb_storages.milvus.MilvusStorage as the vector database:
from app.storage.vector_storage import VectorStorage

vector_storage = VectorStorage()

# Store single vector
vector_storage.store_embedding(
    news_id=1,
    text="news content",
    embedding=[0.1, 0.2, ...]
)

# Batch storage
vector_storage.store_embeddings_batch([
    {"news_id": 1, "text": "content1", "embedding": [...]},
    {"news_id": 2, "text": "content2", "embedding": [...]}
])

# Similarity search
results = vector_storage.search_similar(query_vector=[...], top_k=10)

# Get statistics (with query count fallback mechanism)
stats = vector_storage.get_stats()
Features:
num_entities is inaccurateIn async contexts (e.g., FastAPI routes), use async interfaces:
from app.services.embedding_service import EmbeddingService
from app.storage.vector_storage import VectorStorage

async def analyze_news(news_id: int, text: str):
    embedding_service = EmbeddingService()
    vector_storage = VectorStorage()

    # Use async interface to avoid event loop conflicts
    embedding = await embedding_service.aembed_text(text)

    # Store vector asynchronously in background (non-blocking)
    asyncio.create_task(
        vector_storage.store_embedding(news_id, text, embedding)
    )

    # Continue with analysis logic...
Notes:
aembed_text() instead of embed_text()flush() operation is optimized, not executed by default (relies on auto-flush)FinnewsHunter's core feature is the bull-bear debate mechanism, through collaboration and confrontation of multiple professional agents, deeply mining investment value and risks of individual stocks.
| Agent | Role | Core Responsibilities |
|---|---|---|
| BullResearcher | Bull Researcher | Mine growth potential, core positives, valuation advantages |
| BearResearcher | Bear Researcher | Identify downside risks, negative catalysts, refute optimistic expectations |
| SearchAnalyst | Search Analyst | Dynamically acquire data (AkShare/BochaAI/browser search) |
| InvestmentManager | Investment Manager | Host debate, evaluate argument quality, make final decisions |
graph TD
    subgraph Debate Initiation
        Manager[Investment Manager] -->|Opening Statement| Orchestrator[Debate Orchestrator]
    end

    subgraph Multi-Round Debate
        Orchestrator -->|Round N| Bull[Bull Researcher]
        Bull -->|Statement + Data Request| Orchestrator
        Orchestrator -->|Trigger Search| Searcher[Search Analyst]

        Searcher -->|Financial Data| AkShare[AkShare]
        Searcher -->|Real-time News| BochaAI[BochaAI]
        Searcher -->|Web Search| Browser[Browser Engine]

        AkShare --> Context[Update Context]
        BochaAI --> Context
        Browser --> Context

        Context --> Orchestrator
        Orchestrator -->|Round N| Bear[Bear Researcher]
        Bear -->|Statement + Data Request| Orchestrator
    end

    subgraph Final Decision
        Orchestrator -->|Intelligent Data Supplement| Searcher
        Orchestrator -->|Comprehensive Judgment| Manager
        Manager -->|Investment Rating| Result[Final Report]
    end
During debate, agents can request additional data through specific format:
[SEARCH: "Recent gross margin data" source:akshare]   -- Get financial data from AkShare
[SEARCH: "Industry competition analysis" source:bochaai]   -- Search news from BochaAI
[SEARCH: "Recent fund flows" source:akshare]       -- Get fund flows
[SEARCH: "Competitor comparison analysis"]                       -- Automatically select best data source
Supported Data Sources:
/api/v1/llm/config)This project follows the AgenticX license.
If you find this project helpful, please give it a Star ⭐️!
Built with ❤️ using AgenticX
FinnewsHunter: Multi-agent financial intelligence platform powered by AgenticX. Real-time news analysis, sentiment fusion, and alpha factor mining.
Python
1,499
353 commits
updated Oct 1, 2026
An enterprise-grade financial news analysis system built on the AgenticX framework, integrating real-time news streams, deep quantitative analysis, and multi-agent debate mechanisms.
FinnewsHunter goes beyond traditional text classification by deploying multi-agent teams (NewsAnalyst, Researcher, etc.) to monitor multiple financial news sources in real-time, including Sina Finance, National Business Daily, Financial World, Securities Times, and more. It leverages large language models for deep interpretation, sentiment analysis, and market impact assessment, combined with knowledge graphs to mine potential investment opportunities and risks, providing decision-level alpha signals for quantitative trading.
BailianEmbeddingProvider and MilvusStorage, avoiding reinventing the wheel
The system adopts a layered architecture design:
cd /Users/damon/myWork/AgenticX
pip install -e .
cd FinnewsHunter/backend
pip install -r requirements.txt
cd FinnewsHunter/backend
cp env.example .env
# Edit .env file and fill in LLM API Key and other configurations
Multi-Provider LLM Configuration:
The system supports 5 LLM providers, at least one needs to be configured:
| Provider | Environment Variable | Registration URL |
|---|---|---|
| Bailian (Alibaba Cloud) | DASHSCOPE_API_KEY | https://dashscope.console.aliyun.com/ |
| OpenAI | OPENAI_API_KEY | https://platform.openai.com/api-keys |
| DeepSeek | DEEPSEEK_API_KEY | https://platform.deepseek.com/ |
| Kimi (Moonshot) | MOONSHOT_API_KEY | https://platform.moonshot.cn/ |
| Zhipu | ZHIPU_API_KEY | https://open.bigmodel.cn/ |
Example Configuration (Recommended: Bailian):
# Bailian (Alibaba Cloud) - Recommended, fast access in China
DASHSCOPE_API_KEY=sk-your-dashscope-key
DASHSCOPE_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
BAILIAN_MODELS=qwen-plus,qwen-max,qwen-turbo

# Optional: Other providers
OPENAI_API_KEY=sk-your-openai-key
DEEPSEEK_API_KEY=sk-your-deepseek-key
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml up -d postgres redis milvus-etcd milvus-minio milvus-standalone
cd FinnewsHunter/backend
python init_db.py
cd FinnewsHunter/backend
python -m app.scripts.init_stocks
# Will fetch all A-share data (approximately 5000+ stocks) from akshare and save to database
cd FinnewsHunter/backend
uvicorn app.main:app --reload --host 0.0.0.0 --port 8000
# Open a new terminal
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml up -d celery-worker celery-beat
# Open a new terminal
cd FinnewsHunter/frontend
npm install  # First time requires dependency installation
npm run dev
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml ps
cd FinnewsHunter

# Restart Docker services (infrastructure + Celery)
docker compose -f deploy/docker-compose.dev.yml restart

# If backend API is started independently, manually restart it
# Press Ctrl+C to stop backend process, then rerun:
cd backend
uvicorn app.main:app --reload --host 0.0.0.0 --port 8000
cd FinnewsHunter

# Restart only Celery (after code changes)
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat

# Restart only database
docker compose -f deploy/docker-compose.dev.yml restart postgres

# Restart only Redis
docker compose -f deploy/docker-compose.dev.yml restart redis
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml down
cd FinnewsHunter

# View Celery Worker logs
docker compose -f deploy/docker-compose.dev.yml logs -f celery-worker

# View Celery Beat logs (scheduled task dispatch)
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat

# View PostgreSQL logs
docker compose -f deploy/docker-compose.dev.yml logs -f postgres

# View all service logs
docker compose -f deploy/docker-compose.dev.yml logs -f
cd FinnewsHunter

# Execute reset script
./reset_all_data.sh

# Enter yes to confirm
The script will automatically complete:
After execution, wait:
# Enter PostgreSQL container
docker exec -it finnews_postgres psql -U finnews -d finnews_db
Execute in PostgreSQL command line:
-- Clear news table
DELETE FROM news;

-- Clear task table
DELETE FROM crawl_tasks;

-- Clear analysis table
DELETE FROM analyses;

-- Reset auto-increment IDs
ALTER SEQUENCE news_id_seq RESTART WITH 1;
ALTER SEQUENCE crawl_tasks_id_seq RESTART WITH 1;
ALTER SEQUENCE analyses_id_seq RESTART WITH 1;

-- Verify results (should all be 0)
SELECT 'news table', COUNT(*) FROM news;
SELECT 'crawl_tasks table', COUNT(*) FROM crawl_tasks;
SELECT 'analyses table', COUNT(*) FROM analyses;

-- Exit
\q
cd FinnewsHunter
docker exec finnews_redis redis-cli FLUSHDB
cd FinnewsHunter/backend
rm -f celerybeat-schedule*
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat
# Check news count (should be 0)
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT COUNT(*) FROM news;"

# Check Redis (should be 0 or very small)
docker exec finnews_redis redis-cli DBSIZE

# Check if Celery has started crawling
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat
# Should see 10 crawl tasks triggered per minute
cd FinnewsHunter/backend
python reset_database.py
# Enter yes to confirm
Use Case: When reset script doesn't work, this is the fastest method
cd FinnewsHunter

# Step 1: Clear database tables
docker exec finnews_postgres psql -U finnews -d finnews_db -c "DELETE FROM news; DELETE FROM crawl_tasks; DELETE FROM analyses;"

# Step 2: Reset auto-increment IDs
docker exec finnews_postgres psql -U finnews -d finnews_db -c "ALTER SEQUENCE news_id_seq RESTART WITH 1; ALTER SEQUENCE crawl_tasks_id_seq RESTART WITH 1; ALTER SEQUENCE analyses_id_seq RESTART WITH 1;"

# Step 3: Clear Redis cache
docker exec finnews_redis redis-cli FLUSHDB

# Step 4: Clear Celery schedule files
rm -f backend/celerybeat-schedule*

# Step 5: Restart Celery services
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat

# Step 6: Verify cleared (should display 0)
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT COUNT(*) FROM news;"
Immediately refresh browser after execution:
Command + Shift + RCtrl + Shift + RAfter data is cleared, frontend may still display old data due to browser cache.
Mac System:
Press Command + Shift + R
or Command + Option + R
Windows/Linux System:
Press Ctrl + Shift + R
or Ctrl + F5
F12 to open developer toolsChrome/Edge:
Command + Shift + Delete (Mac) or Ctrl + Shift + Delete (Windows)After refreshing page, hard refresh again
# Press Ctrl+C in frontend terminal to stop service
# Then restart
cd FinnewsHunter/frontend
npm run dev
| Time | Event | Expected Result |
|---|---|---|
| 0 min | Execute reset script | Database cleared, Redis cleared |
| 1 min | Celery Beat starts scheduling | 10 crawl tasks triggered |
| 2-5 min | First batch of news saved | Database starts having data |
| 5-10 min | All sources have data | Frontend can see 100+ news |
| 30 min | Data continues growing | 500+ news |
| 1 hour | Stable operation | 1000-2000 news |
Notes:
Steps to immediately hard refresh frontend after reset:
Command + Shift + R (Mac) or Ctrl + Shift + R (Windows) in browsercd FinnewsHunter
# View news count by source
docker exec finnews_postgres psql -U finnews -d finnews_db -c "
SELECT source, COUNT(*) as count
FROM news
WHERE created_at > NOW() - INTERVAL '1 hour'
GROUP BY source
ORDER BY count DESC;
"
# View recent crawl task status
docker exec finnews_postgres psql -U finnews -d finnews_db -c "
SELECT source,
crawled_count,
saved_count,
status,
error_message
FROM crawl_tasks
WHERE created_at > NOW() - INTERVAL '10 minutes'
ORDER BY created_at DESC
LIMIT 20;
"
cd FinnewsHunter

# View ERROR logs
docker compose -f deploy/docker-compose.dev.yml logs celery-worker | grep ERROR

# View specific source issues
docker compose -f deploy/docker-compose.dev.yml logs celery-worker | grep "jwview"
System is configured with automatic crawling for 10 news sources:
How it works:
View crawl progress:
# View Celery Beat scheduling logs
cd FinnewsHunter
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat

# View Celery Worker execution logs
docker compose -f deploy/docker-compose.dev.yml logs -f celery-worker
Method 1: Via Frontend
Method 2: Via API
# Force refresh Sina Finance
curl -X POST "http://localhost:8000/api/v1/news/refresh?source=sina"

# Force refresh all sources (need to call individually)
for source in sina tencent jwview eeo caijing jingji21 nbd yicai 163 eastmoney; do
  curl -X POST "http://localhost:8000/api/v1/news/refresh?source=$source"
  sleep 1
done
Method 1: Via Frontend (Recommended)
Method 2: Via API
# Get latest news from all sources (200 items)
curl "http://localhost:8000/api/v1/news/latest?limit=200"

# Get news from specific source
curl "http://localhost:8000/api/v1/news/latest?source=sina&limit=50"

# Filter by sentiment (using old API)
curl "http://localhost:8000/api/v1/news/?sentiment=positive&limit=20"

# Get all available news source list
curl "http://localhost:8000/api/v1/news/sources"
Frontend Operations:
Batch Selection:
Batch Delete:
Batch Analysis:
API Operations:
# Batch delete news
curl -X POST "http://localhost:8000/api/v1/news/batch/delete" \
  -H "Content-Type: application/json" \
  -d '{"news_ids": [1, 2, 3]}'

# Batch analyze news
curl -X POST "http://localhost:8000/api/v1/analysis/batch" \
  -H "Content-Type: application/json" \
  -d '{"news_ids": [1, 2, 3], "provider": "bailian", "model": "qwen-plus"}'
Method 1: Via Frontend
Method 2: Via API
# Analyze news with specified ID (using default model)
curl -X POST http://localhost:8000/api/v1/analysis/news/1

# Analyze news (specify model)
curl -X POST http://localhost:8000/api/v1/analysis/news/1 \
  -H "Content-Type: application/json" \
  -d '{"provider": "bailian", "model": "qwen-max"}'

# View analysis results
curl http://localhost:8000/api/v1/analysis/1
Frontend Operations:
Supported Models:
API to Get Available Model List:
curl http://localhost:8000/api/v1/llm/config
Frontend Operations:
Search Examples:
600519 (Kweichow Moutai)新能源 (new energy), 半导体 (semiconductor)sina, eastmoneyFrontend Operations:
Frontend Operations:
茅台 (Moutai), 600519)API Operations:
# Get K-line data (daily, default 180 items)
curl "http://localhost:8000/api/v1/stocks/SH600519/kline?period=daily&limit=180"

# Get minute K-line (60-minute line)
curl "http://localhost:8000/api/v1/stocks/SH600519/kline?period=60m&limit=200"

# Search stocks
curl "http://localhost:8000/api/v1/stocks/search/realtime?q=茅台&limit=10"

# View stock count in database
curl "http://localhost:8000/api/v1/stocks/count"
Frontend Operations:
Homepage (Dashboard)
News Feed Page
API Operations:
# View Sina Finance news
curl "http://localhost:8000/api/v1/news/latest?source=sina&limit=50"

# View National Business Daily news
curl "http://localhost:8000/api/v1/news/latest?source=nbd&limit=50"

# View all sources
curl "http://localhost:8000/api/v1/news/latest?limit=200"
FinnewsHunter/
├── backend/                    # Backend service
│   ├── app/
│   │   ├── agents/            # Agent definitions (NewsAnalyst, debate agents, etc.)
│   │   ├── api/v1/            # FastAPI routes
│   │   │   ├── analysis.py    # Analysis API (supports batch analysis)
│   │   │   ├── llm_config.py  # LLM config API
│   │   │   ├── news_v2.py     # News API (supports batch delete)
│   │   │   └── ...
│   │   ├── core/              # Core configuration (config, database, redis, neo4j)
│   │   ├── models/            # SQLAlchemy data models
│   │   ├── services/          # Business services
│   │   │   ├── llm_service.py      # LLM service (multi-provider support)
│   │   │   ├── analysis_service.py # Analysis service (async vectorization)
│   │   │   ├── embedding_service.py # Vectorization service (based on AgenticX BailianEmbeddingProvider)
│   │   │   └── stock_data_service.py # Stock data service
│   │   ├── storage/           # Storage wrapper
│   │   │   └── vector_storage.py # Milvus vector storage (based on AgenticX MilvusStorage)
│   │   ├── tasks/             # Celery tasks
│   │   └── tools/              # AgenticX tools (Crawler, Cleaner)
│   ├── tests/                 # Test and utility scripts
│   │   ├── check_milvus_data.py           # Check Milvus vector storage data
│   │   ├── check_news_embedding_status.py # Check news vectorization status
│   │   └── manual_vectorize.py           # Manually vectorize specified news
│   ├── env.example            # Environment variable template
│   └── requirements.txt       # Python dependencies
├── frontend/                  # React frontend
│   └── src/
│       ├── components/        # Components
│       │   ├── ModelSelector.tsx    # LLM model selector
│       │   ├── NewsDetailDrawer.tsx # News detail drawer
│       │   └── HighlightText.tsx    # Keyword highlighting
│       ├── context/           # React Context
│       ├── hooks/             # Custom Hooks
│       │   └── useDebounce.ts # Debounce Hook
│       ├── layout/            # Layout components
│       └── pages/             # Page components
│           └── NewsListPage.tsx # News list page (supports batch operations)
├── deploy/                    # Deployment configuration
│   ├── docker-compose.dev.yml # Docker Compose configuration
│   ├── Dockerfile.celery     # Celery image build file
│   └── celery-entrypoint.sh  # Celery container startup script
├── conclusions/               # Module summary documentation
│   ├── backend/              # Backend module summaries
│   └── frontend/             # Frontend module summaries
└── .dev-docs/                 # Development documentation
Start All Services
./start.sh
Check Docker Container Status
docker ps
# Should see: postgres, redis, milvus-standalone, milvus-etcd, milvus-minio
Test News Crawling
curl -X POST http://localhost:8000/api/v1/news/crawl \
  -H "Content-Type: application/json" \
  -d '{"source": "sina", "start_page": 1, "end_page": 1}'

# Wait 5-10 seconds then check results
curl http://localhost:8000/api/v1/news/?limit=5
Test Agent Analysis
# Get first news ID
NEWS_ID=$(curl -s http://localhost:8000/api/v1/news/?limit=1 | jq '.[0].id')

# Trigger analysis
curl -X POST http://localhost:8000/api/v1/analysis/news/$NEWS_ID

# View analysis results
curl http://localhost:8000/api/v1/analysis/1
Test Frontend Interface
frontend/index.htmlSymptom: Backend startup error could not connect to database
Solution:
cd FinnewsHunter

# Check if PostgreSQL is running
docker ps | grep postgres

# View logs
docker compose -f deploy/docker-compose.dev.yml logs postgres

# Restart container
docker compose -f deploy/docker-compose.dev.yml restart postgres

# Wait 30 seconds then retry backend startup
Symptom: Frontend shows 0 news count, no automatic crawling
Troubleshooting Steps:
cd FinnewsHunter

# 1. Check if Celery Worker is running
docker ps | grep celery

# 2. View Celery Beat logs (should see tasks triggered every minute)
docker compose -f deploy/docker-compose.dev.yml logs celery-beat --tail=100

# 3. View Celery Worker logs (check task execution)
docker compose -f deploy/docker-compose.dev.yml logs celery-worker --tail=100

# 4. Check Redis connection
docker exec finnews_redis redis-cli PING
# Should return PONG

# 5. Restart Celery services
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat
Symptom: Celery logs show 404 Client Error: Not Found
Cause: News website URL has changed
Solution:
# 1. Manually visit URL to verify if available
curl -I https://finance.caijing.com.cn/

# 2. If URL changed, update corresponding crawler configuration
# Edit backend/app/tools/{source}_crawler.py
# Update BASE_URL and STOCK_URL

# 3. Clear Python cache
cd FinnewsHunter/backend
find . -type d -name __pycache__ -exec rm -rf {} + 2>/dev/null || true

# 4. Restart Celery
cd ..
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat
Symptom: Other 9 sources have no news
Possible Causes:
Solution:
cd FinnewsHunter

# 1. Check Celery Beat configuration
docker compose -f deploy/docker-compose.dev.yml logs celery-beat | grep "crawl-"
# Should see 10 scheduled tasks (crawl-sina, crawl-tencent, ..., crawl-eastmoney)

# 2. Manually test single source crawling
docker exec -it finnews_celery_worker python -c "
from app.tools import get_crawler_tool
crawler = get_crawler_tool('nbd')  # Test National Business Daily
news = crawler.crawl()
print(f'Crawled {len(news)} news items')
"

# 3. View data volume by source in database
docker exec finnews_postgres psql -U finnews -d finnews_db -c "
SELECT source, COUNT(*) as count
FROM news
GROUP BY source
ORDER BY count DESC;
"

# 4. If a source keeps failing, view detailed errors
docker compose -f deploy/docker-compose.dev.yml logs celery-worker | grep "ERROR"
Symptom: Analysis functionality not working, error LLM Provider NOT provided
Solution:
cd FinnewsHunter/backend

# 1. Check if API Key is configured
grep -E "DASHSCOPE_API_KEY|OPENAI_API_KEY|DEEPSEEK_API_KEY" .env

# 2. Check if Base URL is correct (Bailian must configure)
grep DASHSCOPE_BASE_URL .env
# Should be: https://dashscope.aliyuncs.com/compatible-mode/v1

# 3. Verify LLM config API is normal
curl http://localhost:8000/api/v1/llm/config | jq '.providers[].has_api_key'
# At least one should return true

# 4. If using Bailian, ensure complete configuration
cat >> .env << EOF
DASHSCOPE_API_KEY=sk-your-key
DASHSCOPE_BASE_URL=https://dashscope.aliyuncs.com/compatible-mode/v1
BAILIAN_MODELS=qwen-plus,qwen-max
EOF

# 5. Restart backend service
Symptom: Frontend cannot load data, browser Console shows CORS error
Solution:
# 1. Check backend CORS configuration
cd FinnewsHunter/backend
grep BACKEND_CORS_ORIGINS .env
# Should include http://localhost:3000

# 2. Check frontend API address configuration
cd ../frontend
cat .env
# VITE_API_URL should be http://localhost:8000

# 3. Hard refresh browser
# Chrome/Edge: Ctrl+Shift+R (Windows) or Cmd+Shift+R (Mac)

# 4. Restart frontend dev server
npm run dev
Symptom: Vector search functionality not working
Solution:
cd FinnewsHunter

# Milvus requires longer startup time (approximately 60 seconds)
docker compose -f deploy/docker-compose.dev.yml logs milvus-standalone

# Check health status
docker inspect finnews_milvus | grep -A 10 Health

# Restart Milvus related services
docker compose -f deploy/docker-compose.dev.yml restart milvus-etcd milvus-minio milvus-standalone
Symptom: Homepage shows news count doesn't match actual
Solution:
# Use reset script to clear data and start fresh
cd FinnewsHunter
./reset_all_data.sh
cd FinnewsHunter

# View all container status
docker compose -f deploy/docker-compose.dev.yml ps

# View complete logs for a service
docker compose -f deploy/docker-compose.dev.yml logs celery-worker --tail=500

# Enter container for debugging
docker exec -it finnews_celery_worker bash

# View database connection
docker exec finnews_postgres psql -U finnews -d finnews_db -c "\conninfo"

# View Redis connection
docker exec finnews_redis redis-cli INFO

# Test network connectivity
docker exec finnews_celery_worker ping -c 3 postgres
cd FinnewsHunter
# Start all services
docker compose -f deploy/docker-compose.dev.yml up -d

# Stop all services
docker compose -f deploy/docker-compose.dev.yml down

# Restart Celery (after code updates)
docker compose -f deploy/docker-compose.dev.yml restart celery-worker celery-beat

# Clear all data and start fresh
./reset_all_data.sh
# Service status
docker compose -f deploy/docker-compose.dev.yml ps

# News count
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT source, COUNT(*) FROM news GROUP BY source;"

# Task count
docker exec finnews_postgres psql -U finnews -d finnews_db -c "SELECT status, COUNT(*) FROM crawl_tasks GROUP BY status;"

# Redis cache
docker exec finnews_redis redis-cli DBSIZE
# Celery Beat (scheduled dispatch)
docker compose -f deploy/docker-compose.dev.yml logs -f celery-beat

# Celery Worker (task execution)
docker compose -f deploy/docker-compose.dev.yml logs -f celery-worker

# PostgreSQL
docker compose -f deploy/docker-compose.dev.yml logs -f postgres

# All services
docker compose -f deploy/docker-compose.dev.yml logs -f
BaseCrawler classcrawl() methodtools/__init__.pyExample:
# backend/app/tools/custom_crawler.py
from .crawler_base import BaseCrawler

class CustomCrawlerTool(BaseCrawler):
    name = "custom_crawler"

    def crawl(self, start_page, end_page):
        # Implement crawling logic
        pass
For scenarios requiring JS rendering or intelligent content extraction, use enhanced crawler:
from app.tools.crawler_enhanced import crawl_url, EnhancedCrawler

# Quick crawl single URL
article = crawl_url("https://finance.sina.com.cn/xxx", engine='auto')
print(article.to_markdown())

# Get LLM message format (multimodal)
llm_messages = article.to_llm_message()

# Batch crawl (with cache)
crawler = EnhancedCrawler(use_cache=True)
articles = crawler.crawl_batch(urls, delay=1.0)
Supported Engines:
requests: Basic HTTP requests (default)playwright: JS rendering (requires playwright install chromium)jina: Jina Reader API (requires JINA_API_KEY configuration)auto: Automatically select best engineInstall Optional Dependencies:
pip install markdownify readabilipy playwright
playwright install chromium  # Optional, for JS rendering
Agent classExample:
# backend/app/agents/risk_analyst.py
from agenticx import Agent

class RiskAnalystAgent(Agent):
    def __init__(self, llm_provider):
        super().__init__(
            name="RiskAnalyst",
            role="Risk Analyst",
            goal="Assess investment risks",
            llm_provider=llm_provider
        )
FinnewsHunter deeply integrates AgenticX framework core components to avoid reinventing the wheel:
The system uses agenticx.embeddings.BailianEmbeddingProvider as the core embedding engine:
from app.services.embedding_service import EmbeddingService

# Synchronous interface (for sync contexts)
embedding_service = EmbeddingService()
vector = embedding_service.embed_text("text content")

# Asynchronous interface (recommended for async contexts)
vector = await embedding_service.aembed_text("text content")

# Batch processing (Provider handles internal batching)
vectors = embedding_service.embed_batch(["text1", "text2", "text3"])
Features:
The system uses agenticx.storage.vectordb_storages.milvus.MilvusStorage as the vector database:
from app.storage.vector_storage import VectorStorage

vector_storage = VectorStorage()

# Store single vector
vector_storage.store_embedding(
    news_id=1,
    text="news content",
    embedding=[0.1, 0.2, ...]
)

# Batch storage
vector_storage.store_embeddings_batch([
    {"news_id": 1, "text": "content1", "embedding": [...]},
    {"news_id": 2, "text": "content2", "embedding": [...]}
])

# Similarity search
results = vector_storage.search_similar(query_vector=[...], top_k=10)

# Get statistics (with query count fallback mechanism)
stats = vector_storage.get_stats()
Features:
num_entities is inaccurateIn async contexts (e.g., FastAPI routes), use async interfaces:
from app.services.embedding_service import EmbeddingService
from app.storage.vector_storage import VectorStorage

async def analyze_news(news_id: int, text: str):
    embedding_service = EmbeddingService()
    vector_storage = VectorStorage()

    # Use async interface to avoid event loop conflicts
    embedding = await embedding_service.aembed_text(text)

    # Store vector asynchronously in background (non-blocking)
    asyncio.create_task(
        vector_storage.store_embedding(news_id, text, embedding)
    )

    # Continue with analysis logic...
Notes:
aembed_text() instead of embed_text()flush() operation is optimized, not executed by default (relies on auto-flush)FinnewsHunter's core feature is the bull-bear debate mechanism, through collaboration and confrontation of multiple professional agents, deeply mining investment value and risks of individual stocks.
| Agent | Role | Core Responsibilities |
|---|---|---|
| BullResearcher | Bull Researcher | Mine growth potential, core positives, valuation advantages |
| BearResearcher | Bear Researcher | Identify downside risks, negative catalysts, refute optimistic expectations |
| SearchAnalyst | Search Analyst | Dynamically acquire data (AkShare/BochaAI/browser search) |
| InvestmentManager | Investment Manager | Host debate, evaluate argument quality, make final decisions |
graph TD
    subgraph Debate Initiation
        Manager[Investment Manager] -->|Opening Statement| Orchestrator[Debate Orchestrator]
    end

    subgraph Multi-Round Debate
        Orchestrator -->|Round N| Bull[Bull Researcher]
        Bull -->|Statement + Data Request| Orchestrator
        Orchestrator -->|Trigger Search| Searcher[Search Analyst]

        Searcher -->|Financial Data| AkShare[AkShare]
        Searcher -->|Real-time News| BochaAI[BochaAI]
        Searcher -->|Web Search| Browser[Browser Engine]

        AkShare --> Context[Update Context]
        BochaAI --> Context
        Browser --> Context

        Context --> Orchestrator
        Orchestrator -->|Round N| Bear[Bear Researcher]
        Bear -->|Statement + Data Request| Orchestrator
    end

    subgraph Final Decision
        Orchestrator -->|Intelligent Data Supplement| Searcher
        Orchestrator -->|Comprehensive Judgment| Manager
        Manager -->|Investment Rating| Result[Final Report]
    end
During debate, agents can request additional data through specific format:
[SEARCH: "Recent gross margin data" source:akshare]   -- Get financial data from AkShare
[SEARCH: "Industry competition analysis" source:bochaai]   -- Search news from BochaAI
[SEARCH: "Recent fund flows" source:akshare]       -- Get fund flows
[SEARCH: "Competitor comparison analysis"]                       -- Automatically select best data source
Supported Data Sources:
/api/v1/llm/config)This project follows the AgenticX license.
If you find this project helpful, please give it a Star ⭐️!
Built with ❤️ using AgenticX



