
Official implementation of "STAR: Scale-wise Text-to-image generation via Auto-Regressive representations"
See the codeREADME
STAR: Scale-wise Text-conditioned AutoRegressive image generation


News
1. Introduction
STAR, a novel scale-wise text-to-image model, is the first to extend the category-based VAR model from a 256-pixel resolution to a 1024-pixel resolution for text-to-image synthesis.
Performance & Comparison
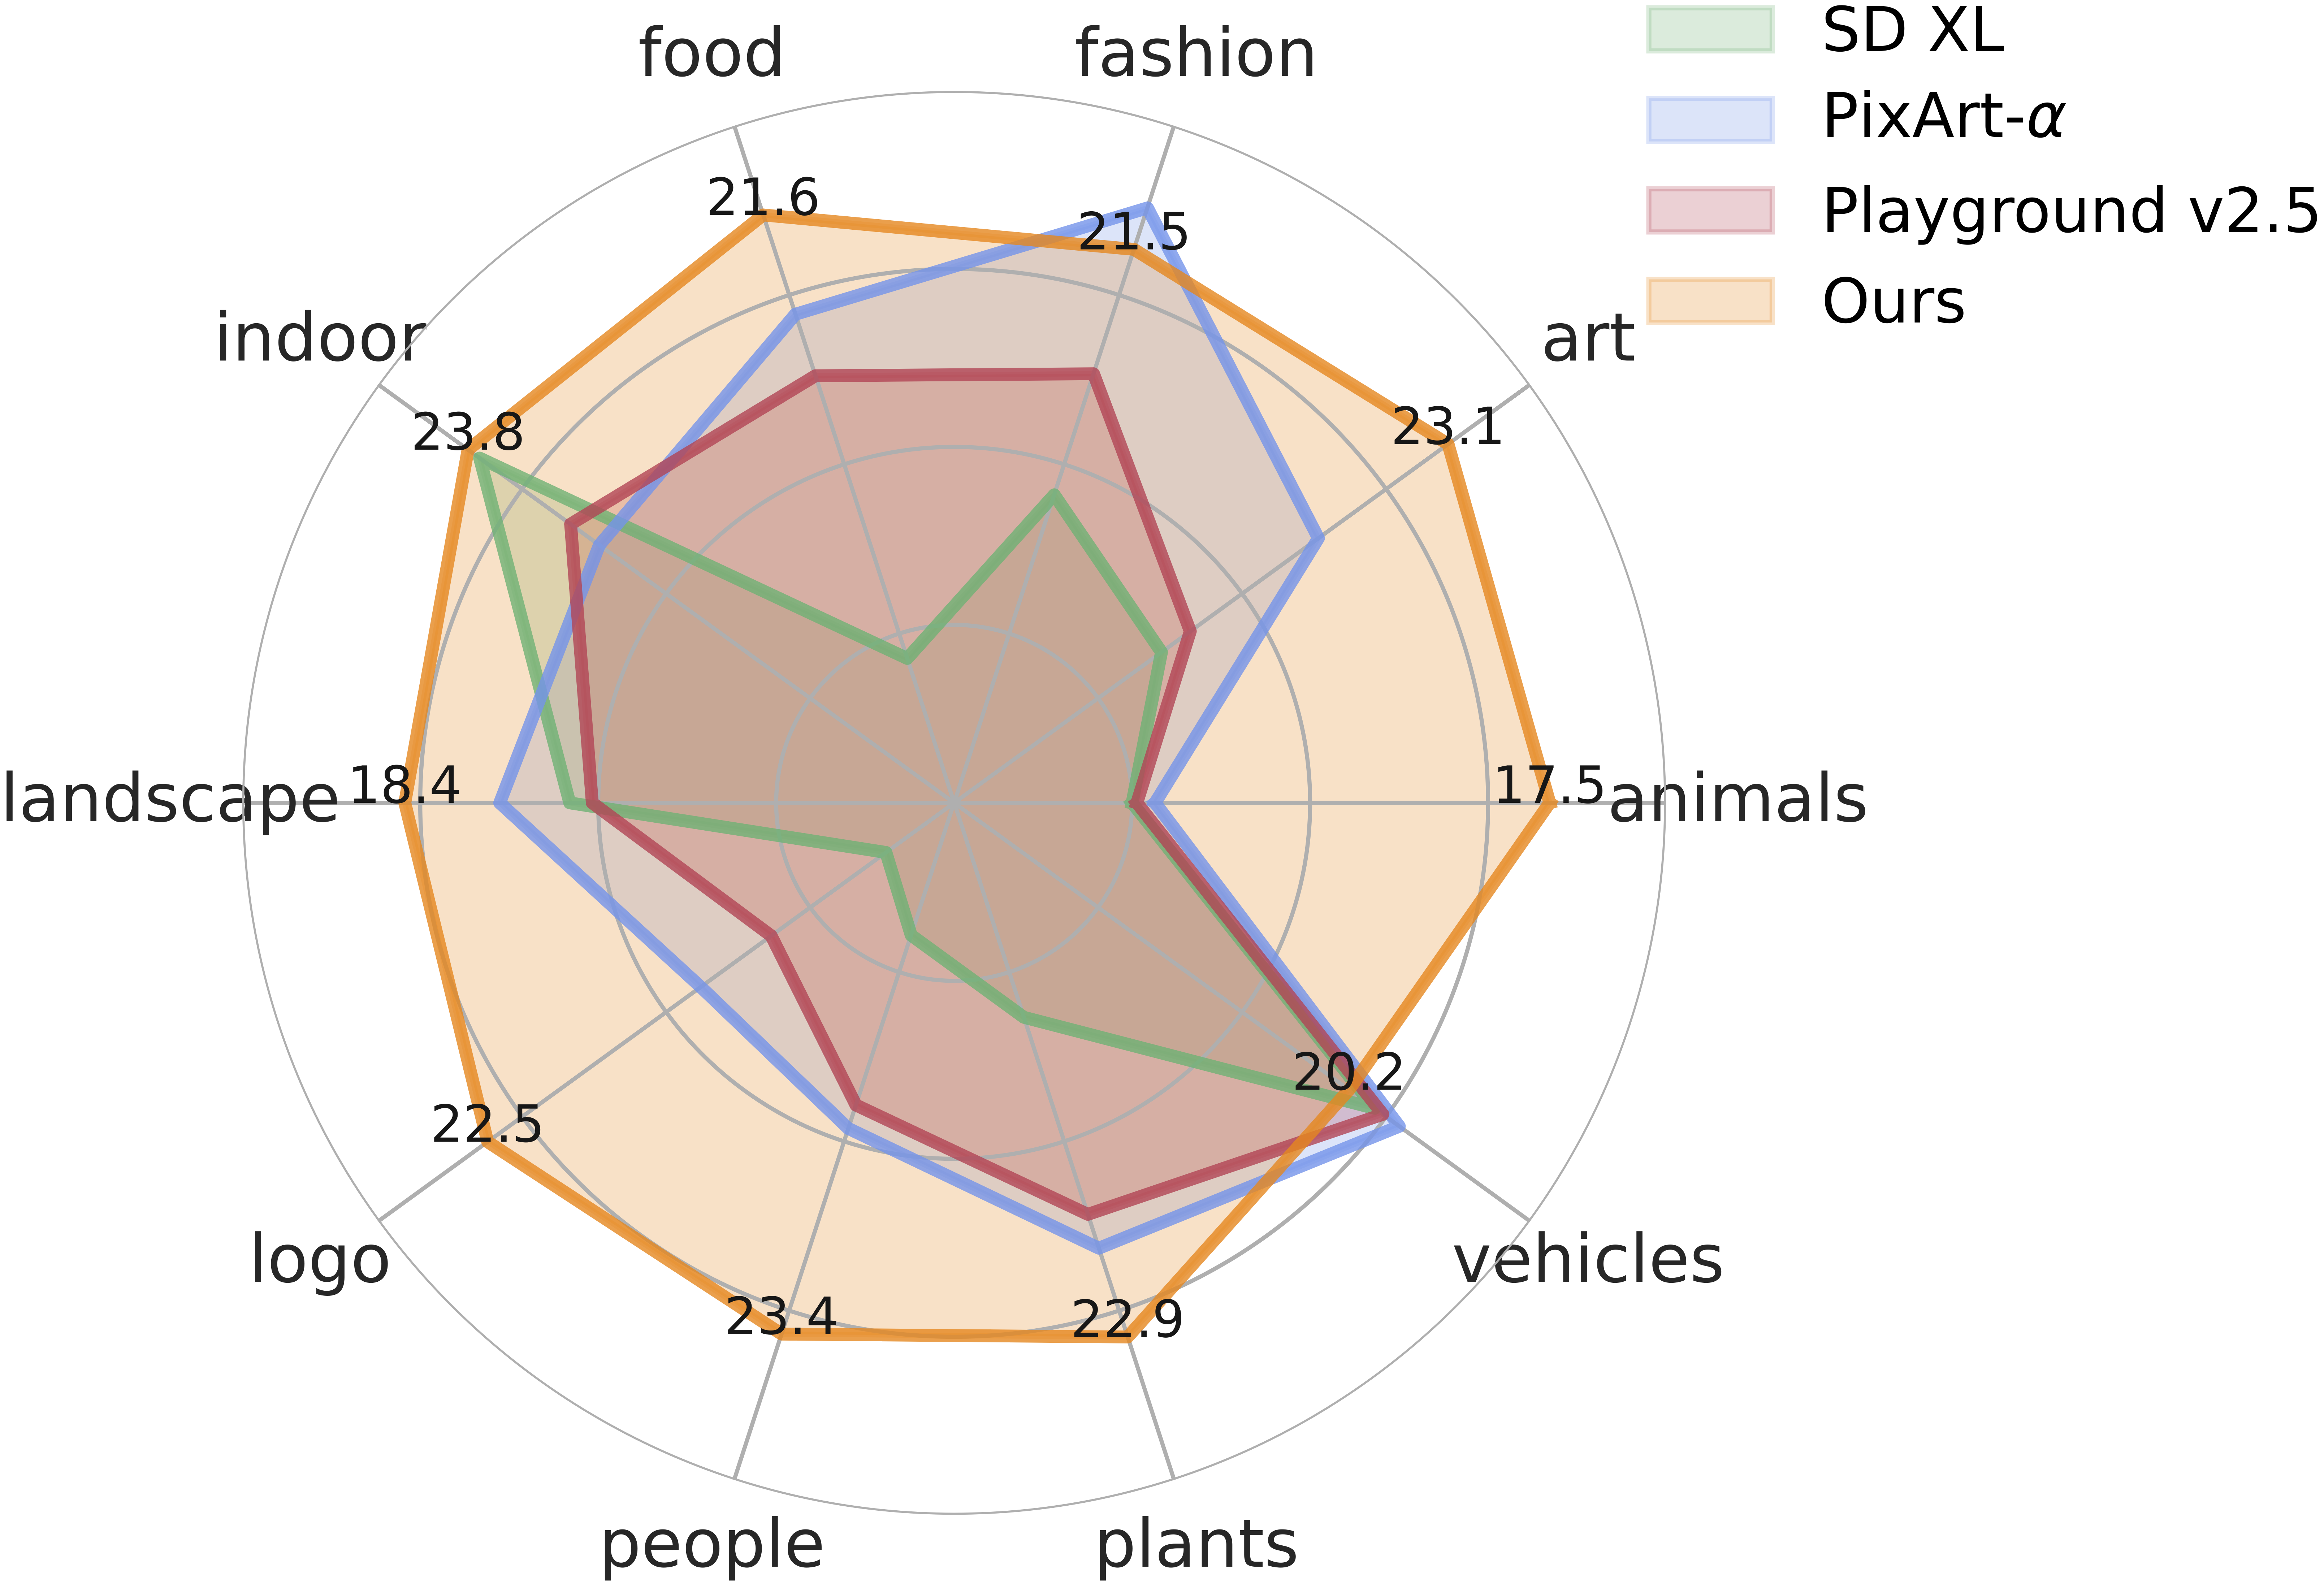
Per-category FID on MJHQ-30K |
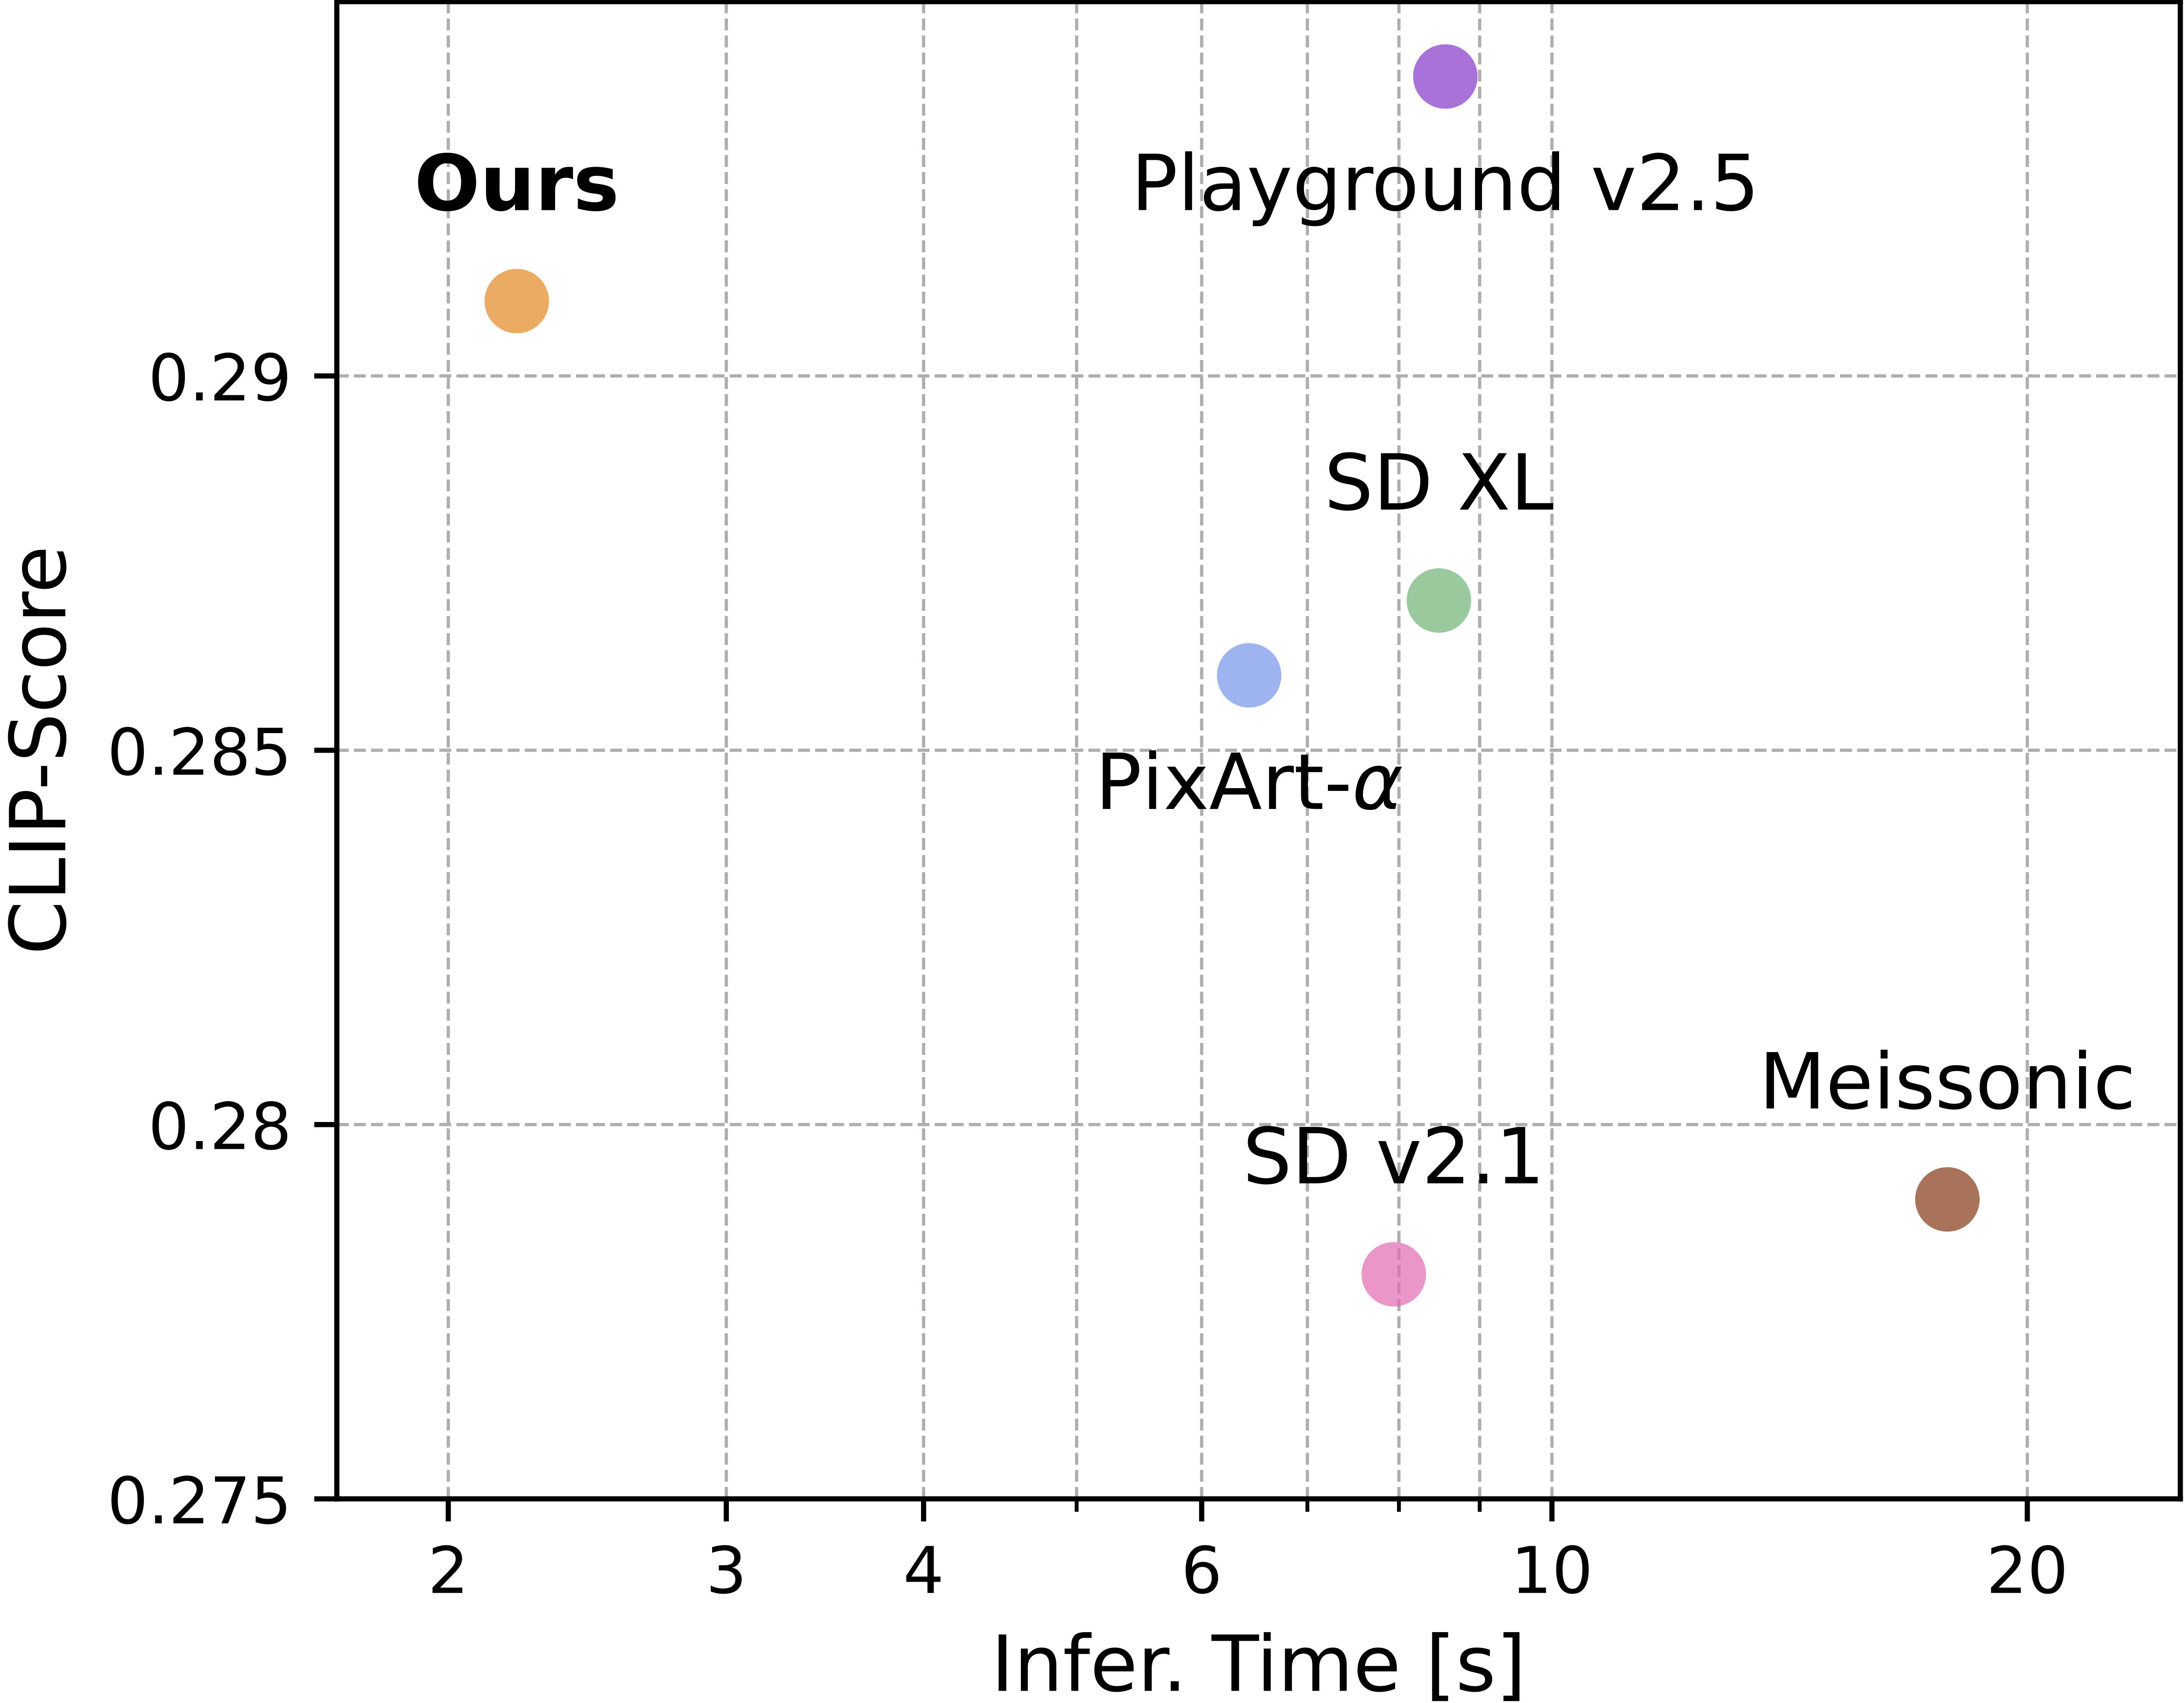
Efficiency & CLIP-Score of 1024x1024 generation |
Architecture of STAR
Unlike VAR, which focuses on a toy category-based auto-regressive generation for 256 images, STAR explores the potential of this scale-wise auto-regressive paradigm in real-world scenarios, aiming to make AR as effective as diffusion models. To achieve this, we:
- replace the single category token with a text encoder and cross-attention for detailed text guidance;
- introduce cross-scale normalized RoPE to stabilize structural learning and reduce training costs, unleasing the power for high-resolution training;
- propose a new sampling method to overcome the intrinsic simultaneous sampling issue in AR models. While these approaches have been (partially) explored to diffusion models, we are the first to validate and apply them in auto-regressive image generation, resulting in high-resolution, text-conditioned synthesis and can get StableDiffusion 2 performance.
framework of STAR
Sample Generations

2. Model Download
We release STAR to the public to support a broader and more diverse range of research within both academic and commercial communities. Please note that the use of this model is subject to the terms outlined in License section. Commercial usage is permitted under these terms.
| Model | depth | Download |
|---|---|---|
| star-256 | 16 | 🤗 Hugging Face |
| star-256 | 30 | 🤗 Hugging Face |
| star-512 | 30 | 🤗 Hugging Face |
| star-1024 | 30 | 🤗 Hugging Face |
| star-1024-sampler | 30 | 🤗 Hugging Face |
3. Quick Start
Installation
- Install
torch>=2.0.0. - Install other pip packages via
pip3 install -r requirements.txt.
Dataset
- Prepare the text2image dataset: To accelerate the training process, we organize text-to-image dataset pairs into the LMDB (Lightning Memory-Mapped Database) format. For more detailed to pack dataset, please refer to
test_pack.py.
Gradio Demo
python demo_gradio.py
Training Scripts
To train STAR-{d16, d30} on 256x256、512x512、1024x1024, you can run the following command (train_ddp.sh/trian_ddp_samplev3.sh):
d16, 256x256 (from scratch)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=16 --bs=512 --ep=10 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d16_256.json
d30, 256x256 (from scratch)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=30 ---bs=480 --ep=10 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_stage2_256.json
d30, 512x512 (pretrained from d30, 256x256)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=30 --bs=192 --ep=10 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_512.json
d30, 1024x1024 (pretrained from d30, 512x512)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=30 --bs=64 --ep=5 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_1024.json
d30, sampler (Causal-Driven Stable Sampling), 1024x1024 (pretrained from d30, 512x512)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train_sampler.py \
--depth=30 --bs=64 --ep=5 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_samplev3_1024.json
- A folder named
local_out_dir_pathfrom config_*.json will be created to save the checkpoints and logs. - You can start training from a specific checkpoint by setting the
pretrained_ckpt. - You can monitor the training process by checking the logs in
local_out_dir_path/log.txtandlocal_out_dir_path/stdout.txt, or usingtensorboard --logdir=local_out_dir_path/. - If your experiment is interrupted, just rerun the command, and the training will automatically resume from the last checkpoint in
local_out_dir_path/ckpt*.pth.
Evalution & Sampling
For evaluation on MJHQ, refer to the script metrics/compare_models/eval_fid_topk.py, use the var_wo_ddp.autoregressive_infer_cfg(..., cfg=4.0, top_p=0.8, top_k=4096, w_mask=True, more_smooth=False, sample_version='1024') to sample 30,000 images and save them as PNG (not JPEG) files in a folder.
Then, you can use metrics/clip_score_mjhq.py to calculate the per-category CLIP score, or use pytorch-fid to compute the FID.
All evaluation-related scripts are located in the metrics. Feel free to explore them.
4. License
This project is licensed under the MIT License - see the LICENSE file for details.
5. Citation
Thanks to the developers of Visual Autoregressive Modeling for their excellent work. Our code is adapted from VAR. If our work assists your research, feel free to give us a star ⭐ or cite us using:
@article{ma2024star,
  title={STAR: Scale-wise Text-to-image generation via Auto-Regressive representations},
  author={Ma, Xiaoxiao and Zhou, Mohan and Liang, Tao and Bai, Yalong and Zhao, Tiejun and Chen, Huaian and Jin, Yi},
  journal={arXiv preprint arXiv:2406.10797},
  year={2024}
}
6. Join Our Team!
We’re looking for interns focused on multimodal generation and understanding. If interested, feel free to send your resume to liang0305tao@163.com.
Similar repos




Languages
Python
98.0%
Shell
2.0%
Official implementation of "STAR: Scale-wise Text-to-image generation via Auto-Regressive representations"
See the codeREADME
STAR: Scale-wise Text-conditioned AutoRegressive image generation
News
1. Introduction
STAR, a novel scale-wise text-to-image model, is the first to extend the category-based VAR model from a 256-pixel resolution to a 1024-pixel resolution for text-to-image synthesis.
Performance & Comparison
|
Per-category FID on MJHQ-30K |
Efficiency & CLIP-Score of 1024x1024 generation |
Architecture of STAR
Unlike VAR, which focuses on a toy category-based auto-regressive generation for 256 images, STAR explores the potential of this scale-wise auto-regressive paradigm in real-world scenarios, aiming to make AR as effective as diffusion models. To achieve this, we:
- replace the single category token with a text encoder and cross-attention for detailed text guidance;
- introduce cross-scale normalized RoPE to stabilize structural learning and reduce training costs, unleasing the power for high-resolution training;
- propose a new sampling method to overcome the intrinsic simultaneous sampling issue in AR models. While these approaches have been (partially) explored to diffusion models, we are the first to validate and apply them in auto-regressive image generation, resulting in high-resolution, text-conditioned synthesis and can get StableDiffusion 2 performance.
framework of STAR
Sample Generations
2. Model Download
We release STAR to the public to support a broader and more diverse range of research within both academic and commercial communities. Please note that the use of this model is subject to the terms outlined in License section. Commercial usage is permitted under these terms.
| Model | depth | Download |
|---|---|---|
| star-256 | 16 | 🤗 Hugging Face |
| star-256 | 30 | 🤗 Hugging Face |
| star-512 | 30 | 🤗 Hugging Face |
| star-1024 | 30 | 🤗 Hugging Face |
| star-1024-sampler | 30 | 🤗 Hugging Face |
3. Quick Start
Installation
- Install
torch>=2.0.0. - Install other pip packages via
pip3 install -r requirements.txt.
Dataset
- Prepare the text2image dataset: To accelerate the training process, we organize text-to-image dataset pairs into the LMDB (Lightning Memory-Mapped Database) format. For more detailed to pack dataset, please refer to
test_pack.py.
Gradio Demo
python demo_gradio.py
Training Scripts
To train STAR-{d16, d30} on 256x256、512x512、1024x1024, you can run the following command (train_ddp.sh/trian_ddp_samplev3.sh):
d16, 256x256 (from scratch)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=16 --bs=512 --ep=10 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d16_256.json
d30, 256x256 (from scratch)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=30 ---bs=480 --ep=10 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_stage2_256.json
d30, 512x512 (pretrained from d30, 256x256)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=30 --bs=192 --ep=10 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_512.json
d30, 1024x1024 (pretrained from d30, 512x512)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train.py \
--depth=30 --bs=64 --ep=5 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_1024.json
d30, sampler (Causal-Driven Stable Sampling), 1024x1024 (pretrained from d30, 512x512)
python -m torch.distributed.launch --nproc_per_node=$NPROC_PER_NODE --nnodes=$NNODES --node_rank=0 --master_addr=$hostname --master_port=$PORT train_sampler.py \
--depth=30 --bs=64 --ep=5 --fp16=1 --alng=5e-5 --wpe=0.01 --config=config_d30_samplev3_1024.json
- A folder named
local_out_dir_pathfrom config_*.json will be created to save the checkpoints and logs. - You can start training from a specific checkpoint by setting the
pretrained_ckpt. - You can monitor the training process by checking the logs in
local_out_dir_path/log.txtandlocal_out_dir_path/stdout.txt, or usingtensorboard --logdir=local_out_dir_path/. - If your experiment is interrupted, just rerun the command, and the training will automatically resume from the last checkpoint in
local_out_dir_path/ckpt*.pth.
Evalution & Sampling
For evaluation on MJHQ, refer to the script metrics/compare_models/eval_fid_topk.py, use the var_wo_ddp.autoregressive_infer_cfg(..., cfg=4.0, top_p=0.8, top_k=4096, w_mask=True, more_smooth=False, sample_version='1024') to sample 30,000 images and save them as PNG (not JPEG) files in a folder.
Then, you can use metrics/clip_score_mjhq.py to calculate the per-category CLIP score, or use pytorch-fid to compute the FID.
All evaluation-related scripts are located in the metrics. Feel free to explore them.
4. License
This project is licensed under the MIT License - see the LICENSE file for details.
5. Citation
Thanks to the developers of Visual Autoregressive Modeling for their excellent work. Our code is adapted from VAR. If our work assists your research, feel free to give us a star ⭐ or cite us using:
@article{ma2024star,
  title={STAR: Scale-wise Text-to-image generation via Auto-Regressive representations},
  author={Ma, Xiaoxiao and Zhou, Mohan and Liang, Tao and Bai, Yalong and Zhao, Tiejun and Chen, Huaian and Jin, Yi},
  journal={arXiv preprint arXiv:2406.10797},
  year={2024}
}
6. Join Our Team!
We’re looking for interns focused on multimodal generation and understanding. If interested, feel free to send your resume to liang0305tao@163.com.
Similar repos
Languages
Python
98.0%
Shell
2.0%