
README
Awesome-Federated-LLM-Learning
📢 Updates
We released a survey paper "A Survey on Federated Fine-tuning of Large Language Models". Feel free to cite or open pull requests.
⚠️ NOTE: If there is any missing or new relevant literature, please feel free to submit an issue. we will update the Github and Arxiv papers regularly. 😊
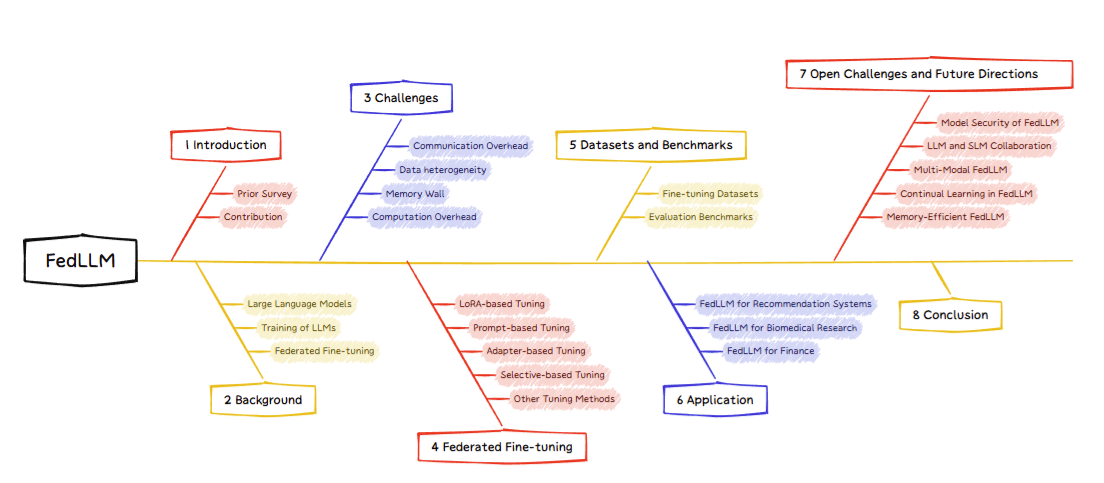
👀 Overall Structure
📒 Table of Contents
- Awesome-Federated-LLM-Learning
- Datasets and Benchmarks
Part 1: LoRA-based Tuning
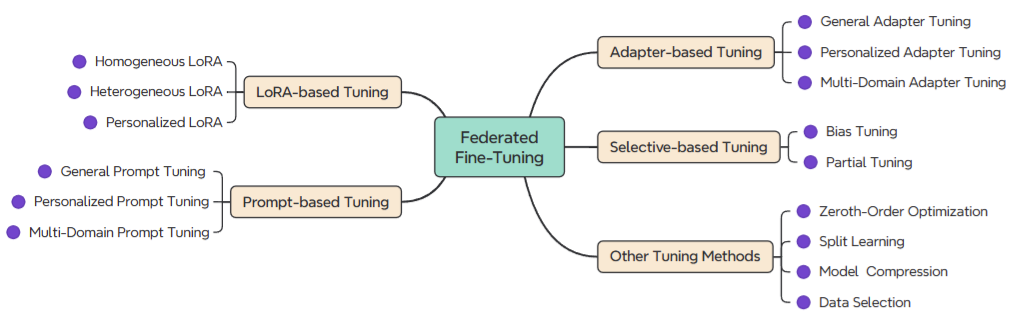
1.1 Homogeneous LoRA
- Fedra: A random allocation strategy for federated tuning to unleash the power of heterogeneous clients. [Paper]
- Towards building the federatedGPT: Federated instruction tuning.[Paper]
- Communication-Efficient and Tensorized Federated Fine-Tuning of Large Language Models. [Paper]
- Selective Aggregation for Low-Rank Adaptation in Federated Learning. [Paper]
- Federa: Efficient fine-tuning of language models in federated learning leveraging weight decomposition. [Paper]
- LoRA-FAIR: Federated LoRA Fine-Tuning with Aggregation and Initialization Refinement. [Paper]
- Federated LoRA with Sparse Communication. [Paper]
- SA-FedLora: Adaptive Parameter Allocation for Efficient Federated Learning with LoRA Tuning. [Paper]
- SLoRA: Federated parameter efficient fine-tuning of language models. [Paper]
- FederatedScope-LLM: A Comprehensive Package for Fine-tuning Large Language Models in Federated Learning [Paper]
- Robust Federated Finetuning of Foundation Models via Alternating Minimization of LoRA. [Paper]
- Automated federated pipeline for parameter-efficient fine-tuning of large language models. [Paper]
- Low-Parameter Federated Learning with Large Language Models. [Paper]
- Towards Robust and Efficient Federated Low-Rank Adaptation with Heterogeneous Clients. [Paper]
- FedRA: A Random Allocation Strategy for Federated Tuning to Unleash the Power of Heterogeneous Clients. [Paper]
- Fed-piLot: Optimizing LoRA Assignment for Efficient Federated Foundation Model Fine-Tuning. [Paper]
1.2 Heterogeneous LoRA
- Heterogeneous lora for federated fine-tuning of on-device foundation models. [Paper]
- Flora: Federated fine-tuning large language models with heterogeneous low-rank adaptations. [Paper]
- Federated fine-tuning of large language models under heterogeneous tasks and client resources. [Paper]
- Federated LLMs Fine-tuned with Adaptive Importance-Aware LoRA. [Paper]
- Towards Federated Low-Rank Adaptation of Language Models with Rank Heterogeneity. [Paper]
- Fedhm: Efficient federated learning for heterogeneous models via low-rank factorization. [Paper]
- RBLA: Rank-Based-LoRA-Aggregation for Fine-Tuning Heterogeneous Models. [Paper]
1.3 Personalized LoRA
- FDLoRA: Personalized Federated Learning of Large Language Model via Dual LoRA Tuning. [Paper]
- Fedlora: Model-heterogeneous personalized federated learning with lora tuning. [Paper]
- FedLoRA: When Personalized Federated Learning Meets Low-Rank Adaptation. [Paper]
- Dual-Personalizing Adapter for Federated Foundation Models. [Paper]
- Personalized Federated Instruction Tuning via Neural Architecture Search. [Paper]
- Communication-Efficient Personalized Federated Learning for Speech-to-Text Tasks. [Paper]
- Personalized Federated Fine-Tuning for LLMs via Data-Driven Heterogeneous Model Architectures. [Paper]
Part 2: Prompt-based Tuning
2.1 General Prompt Tuning
- Prompt federated learning for weather forecasting: Toward foundation models on meteorological data. [Paper]
- Promptfl: Let federated participants cooperatively learn prompts instead of models-federated learning in age of foundation model. [Paper]
- Fedbpt: Efficient federated black-box prompt tuning for large language models. [Paper]
- Federated learning of large language models with parameter-efficient prompt tuning and adaptive optimization. [Paper]
- Efficient federated prompt tuning for black-box large pre-trained models. [Paper]
- Text-driven prompt generation for vision-language models in federated learning. [Paper]
- Learning federated visual prompt in null space for mri reconstruction. [Paper]
- Fed-cprompt: Contrastive prompt for rehearsal-free federated continual learning. [Paper]
- Fedprompt: Communication-efficient and privacy-preserving prompt tuning in federated learning. [Paper]
- Tunable soft prompts are messengers in federated learning. [Paper]
- Hepco: Data-free heterogeneous prompt consolidation for continual federated learning. [Paper]
- Prompt-enhanced Federated Learning for Aspect-Based Sentiment Analysis. [Paper]
- Towards practical few-shot federated nlp. [Paper]
- Federated prompting and chain-of-thought reasoning for improving llms answering. [Paper]
- FedHPL: Efficient Heterogeneous Federated Learning with Prompt Tuning and Logit Distillation. [Paper]
- Probabilistic Federated Prompt-Tuning with Non-IID and Imbalanced Data. [Paper]
- Federated Class-Incremental Learning with Prompting. [Paper]
- Explore and Cure: Unveiling Sample Effectiveness with Context-Aware Federated Prompt Tuning. [Paper]
- Federated Prompt Learning for Weather Foundation Models on Devices. [Paper]
2.2 Personalized Prompt Tuning
- Efficient model personalization in federated learning via client-specific prompt generation. [Paper]
- Unlocking the potential of prompt-tuning in bridging generalized and personalized federated learning. [Paper]
- Pfedprompt: Learning personalized prompt for vision-language models in federated learning. [Paper]
- Global and local prompts cooperation via optimal transport for federated learning. [Paper]
- Visual prompt based personalized federated learning. [Paper]
- Personalized federated continual learning via multi-granularity prompt. [Paper]
- FedLPPA: Learning Personalized Prompt and Aggregation for Federated Weakly-supervised Medical Image Segmentation. [Paper]
- Harmonizing Generalization and Personalization in Federated Prompt Learning. [Paper]
- Tackling Feature-Classifier Mismatch in Federated Learning via Prompt-Driven Feature Transformation. [Paper]
- Personalized Federated Learning for Text Classification with Gradient-Free Prompt Tuning. [Paper]
- Mixture of Experts Made Personalized: Federated Prompt Learning for Vision-Language Models. [Paper]
- CP 2 GFed: Cross-granular and Personalized Prompt-based Green Federated Tuning for Giant Models. [Paper]
2.3 Multi-domain Prompt Tuning
- DiPrompT: Disentangled Prompt Tuning for Multiple Latent Domain Generalization in Federated Learning. [Paper]
- Prompt-enhanced Federated Content Representation Learning for Cross-domain Recommendation. [Paper]
- Dual prompt tuning for domain-aware federated learning. [Paper]
- Federated adaptive prompt tuning for multi-domain collaborative learning. [Paper]
- Breaking physical and linguistic borders: Multilingual federated prompt tuning for low-resource languages. [Paper]
- Federated Domain Generalization via Prompt Learning and Aggregation. [Paper]
- CP-Prompt: Composition-Based Cross-modal Prompting for Domain-Incremental Continual Learning. [Paper]
Part 3: Adapter-based Tuning
3.1 General Adapter Tuning
- Efficient federated learning for modern nlp. [Paper]
- Efficient federated learning with pre-trained large language model using several adapter mechanisms. [Paper]
3.2 Personalized Adapter Tuning
- Client-customized adaptation for parameter-efficient federated learning. [Paper]
- Fedclip: Fast generalization and personalization for clip in federated learning. [Paper]
3.3 Multi-domain Adapter Tuning
- Communication efficient federated learning for multilingual neural machine translation with adapter. [Paper]
- Adapter-based Selective Knowledge Distillation for Federated Multi-domain Meeting Summarization. [Paper]
- Feddat: An approach for foundation model finetuning in multi-modal heterogeneous federated learning. [Paper]
Part 4: Selective-based Tuning
4.1 Bias Tuning
- Differentially private bias-term only fine-tuning of foundation models. [Paper]
- Conquering the communication constraints to enable large pre-trained models in federated learning. [Paper]
4.2 Partial Tuning
- Bridging the gap between foundation models and heterogeneous federated learning. [Paper]
- Exploring Selective Layer Fine-Tuning in Federated Learning. [Paper]
Part 5: Other Tuning Methods
5.1 Zero-Order Optimization
- Federated full-parameter tuning of billion-sized language models with communication cost under 18 kilobytes. [Paper]
- ${$FwdLLM$}$: Efficient Federated Finetuning of Large Language Models with Perturbed Inferences. [Paper]
- ZooPFL: Exploring black-box foundation models for personalized federated learning. [Paper]
- On the convergence of zeroth-order federated tuning for large language models. [Paper]
- Thinking Forward: Memory-Efficient Federated Finetuning of Language Models. [Paper]
- Communication-Efficient Byzantine-Resilient Federated Zero-Order Optimization. [Paper]
5.2 Split Learning
- FedBERT: When federated learning meets pre-training. [Paper]
- Federated split bert for heterogeneous text classification. [Paper]
- FedSplitX: Federated Split Learning for Computationally-Constrained Heterogeneous Clients. [Paper]
5.3 Model Compression
- Fedbiot: Llm local fine-tuning in federated learning without full model. [Paper]
5.4 Data Selection
- Federated Data-Efficient Instruction Tuning for Large Language Models. [Paper]
Datasets and Benchmarks
Prompt-tuning Datasets
Domain: General
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| Alpaca [paper] [github] [huggingface] | English | Model Construct | Generated by Text-Davinci-003 with Alpaca-style instruction prompts. |
| Alpaca-GPT4 [paper] [github] [huggingface] | English | Model Construct | Generated by GPT-4 based on Alpaca prompts with richer multi-turn instructions. |
| Self-Instruct [paper] [github] [huggingface] | English | Human + Model Construct | Seed instructions expanded by GPT-3 to improve model generalization. |
| UltraChat 200k [paper] [github] [huggingface] | English | Model Construct | High-quality multi-turn dialogue subset filtered from UltraChat. |
| OpenOrca [paper] [github] [huggingface] | English | Model Construct | ~4.2 M GPT-3.5/4-augmented FLAN examples for instruction following. |
| ShareGPT90K [github] [huggingface] | English | Model Construct | 90 K multi-turn dialogues extracted from ShareGPT. |
| WizardLM Evol-Instruct V2 196k [paper] [github] [huggingface] | English | Model Construct | 196 K examples generated via Evol-Instruct. |
| Databricks Dolly 15K [paper] [github] [huggingface] | English | Human Construct | 15 K human-written prompt-response pairs across diverse tasks. |
| Baize [paper] [github] [huggingface] | English | Model Construct | Instruction-following dialogues generated via ChatGPT self-chat. |
| OpenChat [paper] [github] [huggingface] | English | Model Construct | Mixed-quality data alignment using C-RLFT for open LLMs. |
| Flan-v2 [paper] [github] [huggingface] | English | Model Construct | Aggregates Flan, P3, Super-Natural Instructions, CoT, Dialog tasks. |
| BELLE-train-0.5M-CN [paper] [github] [huggingface] | Chinese | Human + Model Construct | 519 K Chinese instruction-following examples. |
| BELLE-train-1M-CN [paper] [github] [huggingface] | Chinese | Human + Model Construct | 917 K Chinese instruction samples. |
| BELLE-train-2M-CN [paper] [github] [huggingface] | Chinese | Human + Model Construct | 2 M Chinese instruction samples. |
| Firefly-train-1.1M [paper] [github] [huggingface] | Chinese | Human Construct | 1.65 M Chinese samples across 23 tasks with human templates. |
| Wizard-LM-Chinese-instruct-evol [paper] [github] [huggingface] | Chinese | Human + Model Construct | 70 K WizardLM instructions translated into Chinese. |
| HC3-Chinese [paper] [github] [huggingface] | Chinese | Human + Model Construct | Human-ChatGPT QA pairs in Chinese. |
| HC3 [paper] [github] [huggingface] | English / Chinese | Human + Model Construct | Bilingual Human-ChatGPT QA pairs. |
| ShareGPT-Chinese-English-90k [github] [huggingface] | English / Chinese | Model Construct | 90 K bilingual user queries from ShareGPT logs. |
Domain: Finance
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| FinGPT [paper] [github] [huggingface] | English | Human + Model Construct | Instruction-tuning data for diverse financial tasks. |
| Finance-Instruct-500k [paper] [github] [huggingface] | English | Human + Model Construct | Large-scale (500 K) instruction dataset for finance reasoning. |
| Finance-Alpaca [github] [huggingface] | English | Human + Model Construct | Alpaca-style instructions combined with FiQA and custom Q&A. |
| Financial PhraseBank [paper] [github] [huggingface] | English | Human Construct | Manually annotated news sentences for sentiment classification. |
| Yahoo-Finance-Data [huggingface] | English | Human Construct | Historical prices and fundamentals scraped from Yahoo Finance. |
| Financial-QA-10K [github] [huggingface] | English | Model Construct | 10 K contextual QA pairs generated from SEC 10-K filings. |
| Financial-Classification [huggingface] | English | Human Construct | Merged Financial PhraseBank + Kaggle texts for sentiment/topic classification. |
| Twitter-Financial-News-Topic [github] [huggingface] | English | Human Construct | 21 K annotated tweets for multi-class financial topic tagging. |
| Financial-News-Articles [github] [huggingface] | English | Human Construct | 300 K+ news articles for text classification and sentiment analysis. |
| FiQA [paper] [github] [huggingface] | English | Human Construct | Financial question-answering dataset from forums and texts. |
| Earnings-Call [paper] [huggingface] | English | Human Construct | QA pairs extracted from CEO/CFO earnings-call transcripts. |
| Doc2EDAG [paper] [github] | Chinese | Human Construct | Chinese financial reports annotated for document-level event graphs. |
| Synthetic-PII-Finance-Multilingual [paper] [github] [huggingface] | Multilingual | Synthetic | Synthetic financial documents with labeled PII for privacy-preserving NER. |
Domain: Medicine
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| ChatDoctor-200K [paper] [github] [huggingface] | English | Human + Model Construct | Instruction tuning dataset for medical QA and dialogue generation. |
| ChatDoctor-HealthCareMagic-100k [paper] [github] [huggingface] | English | Human Construct | Real-world doctor-patient conversations from HealthCareMagic. |
| Medical Meadow CORD-19 [paper] [github] [huggingface] | English | Human Construct | Summaries of biomedical papers from CORD-19 for instruction tuning. |
| Medical Meadow MedQA [paper] [github] [huggingface] | English | Human Construct | Multiple-choice medical QA derived from MedQA exam questions. |
| HealthCareMagic-100k-en [paper] [github] [huggingface] | English | Human Construct | English subset of HealthCareMagic doctor-patient consultations. |
| ChatMed-Consult-Dataset [github] [huggingface] | Chinese | Human + Model Construct | Chinese medical consultations with GPT-3.5 answers. |
| CMtMedQA [paper] [github] | Chinese | Human Construct | 70 K multi-turn doctor-patient QA dialogues for Chinese medical reasoning. |
| DISC-Med-SFT [paper] [github] [huggingface] | Chinese | Human + Model Construct | 470 K instruction pairs combining real dialogues and KG-based QA. |
| Huatuo-26M [paper] [github] [huggingface] | Chinese | Human Construct | 26 M QA pairs extracted from encyclopedias, KBs and consultations. |
| Huatuo26M-Lite [paper] [github] [huggingface] | Chinese | Human + Model Construct | Refined subset of Huatuo-26M with ChatGPT-rewritten answers. |
| ShenNong-TCM-Dataset [github] [huggingface] | Chinese | Human + Model Construct | 110 K TCM-centric instructions generated via entity-centric self-instruct. |
| HuatuoGPT-sft-data-v1 [paper] [github] [huggingface] | Chinese | Human + Model Construct | SFT corpus mixing ChatGPT-distilled and real doctor data for HuatuoGPT. |
| MedDialog [paper] [github] [huggingface] | English / Chinese | Human Construct | Large-scale doctor-patient dialogue corpora (0.3 M EN / 3.4 M CN conversations). |
Domain: Code
| Dataset / Benchmark Name | Language | Construction Method | Description |
|---|---|---|---|
| CodeAlpaca [github] [huggingface] | English | Model Construct | GPT-generated code instruction-following dataset in Alpaca style. |
| Code Instructions 120k Alpaca [huggingface] | English | Human + Model Construct | 120 k natural-language ↔ code instruction pairs with Alpaca-format prompts. |
| CodeContests [github] [huggingface] | English | Human Construct | Competitive-programming problems and solutions for program-synthesis research. |
| CommitPackFT [paper] [github] [huggingface] | English | Human Construct | 2 GB filtered Git commits with high-quality messages for code instruction tuning. |
| ToolBench [paper] [github] | English | Human + Model Construct | Instruction dataset for multi-tool API usage and tool-calling agents. |
| CodeParrot-Clean [huggingface] | English | Human Construct | Deduplicated & filtered GitHub Python corpus for code-generation pre-training. |
| The Stack v2 Dedup [paper] [huggingface] | English | Human Construct | Large-scale (600 + languages) deduplicated source-code dataset from BigCode. |
| CodeSearchNet [paper] [github] [huggingface] | English | Human Construct | 6 M code–doc pairs across six languages for code search & retrieval. |
| CodeForces-CoTs [github] [huggingface] | English | Human + Model Construct | 10 k CodeForces problems with chain-of-thought traces distilled by DeepSeek R1. |
| CodeXGLUE Code Refinement [paper] [github] [huggingface] | English | Human Construct | Buggy ↔ fixed Java function pairs for automatic code repair and refinement. |
Domain: Math
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| GSM8K [paper] [github] [huggingface] | English | Human Construct | A dataset of 8.5 K grade-school arithmetic word problems with step-by-step solutions. |
| CoT-GSM8k [huggingface] | English | Human + Model Construct | Extended GSM8K with explicit chain-of-thought reasoning traces. |
| MathInstruct [paper] [github] [huggingface] | English | Human + Model Construct | Hybrid CoT + PoT rationales spanning diverse mathematical fields. |
| MetaMathQA [paper] [github] [huggingface] | English | Human + Model Construct | Multi-perspective question augmentations bootstrapped from GSM8K & MATH. |
| OpenR1-Math-220k [github] [huggingface] | English | Human + Model Construct | 220 K problems with multiple DeepSeek R1 reasoning traces. |
| Hendrycks MATH Benchmark [paper] [github] [huggingface] | English | Human Construct | 12.5 K high-school competition problems with detailed solutions. |
| DeepMind Mathematics Dataset [paper] [github] [huggingface] | English | Synthetic | Algorithmically generated problems covering many school-math topics. |
| OpenMathInstruct-1 [paper] [github] [huggingface] | English | Human + Model Construct | 1.8 M problems with Mixtral code-interpreter solutions. |
| Orca-Math Word Problems 200k [paper] [huggingface] | English | Synthetic | 200 K grade-school word problems distilled with GPT-4 Turbo. |
| DAPO-Math-17k [paper] [huggingface] | English | Human + Model Construct | 17 K math prompts curated for large-scale RL (GRPO) experiments. |
| Big-Math-RL-Verified [paper] [github] [huggingface] | English | Human + Model Construct | 251 K verifiable problems filtered for reinforcement-learning fine-tuning. |
| BELLE-math-zh [github] [huggingface] | Chinese | Human + Model Construct | 250 K Chinese elementary-math problems with step-by-step solutions. |
| MathInstruct-Chinese [huggingface] | Chinese | Model Construct | Chinese translation/extension of MathInstruct for instruction tuning. |
Domain: Law
| Dataset / Benchmark Name | Language | Construction Method | Description |
|---|---|---|---|
| Legal-QA-v1 [huggingface] | English | Human Construct | 3.7 K QA pairs sourced from legal forums. |
| Pile of Law [paper] [github] [huggingface] | English | Human Construct | 256 GB corpus of U.S. legal and administrative text for domain pre-training. |
| CUAD [paper] [github] [huggingface] | English | Human Construct | 26 K expert-annotated contract QA pairs spanning 41 clause types. |
| LEDGAR [paper] [github] [huggingface] | English | Human Construct | 1.45 M labeled contract clauses for multi-label classification. |
| DISC-Law-SFT [paper] [github] [huggingface] | Chinese | Human + Model Construct | 295 K supervised fine-tuning samples covering extraction, judgment prediction, QA, & summarization. |
| Law-GPT-zh [paper] [github] [huggingface] | Chinese | Human Construct | Sentence-pair corpus devised for Chinese legal sentence embedding & instructional tuning. |
| Lawyer LLaMA Data [paper] [github] [huggingface] | Chinese | Human + Model Construct | Instruction data for legal consultation and bar-exam QA used to train Lawyer LLaMA. |
Evaluation Benchmarks
Domain: General
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| MMLU [paper] [github] [huggingface] | No | Evaluate multitask language understanding across 57 subjects | Multitask accuracy |
| BIG-bench [paper] [github] [huggingface] | No | Evaluate advanced reasoning capabilities | Model performance and calibration |
| DROP [paper] [github] [huggingface] | No | Evaluate discrete reasoning over paragraphs | Exact match and F1 score |
| CRASS [paper] [github] | No | Evaluate counterfactual reasoning ability in LLMs | Multiple-choice accuracy |
| ARC [paper] [github] [huggingface] | No | Assess science reasoning at grade-school level | Multiple-choice accuracy |
| AGIEval [paper] [github] [huggingface] | No | Evaluate foundation models on human-centric standardized exam tasks | Multi-task accuracy across disciplines |
| M3Exam [paper] [github] | No | Evaluate multilingual, multimodal, and multilevel reasoning across real exam questions | Multiple-choice accuracy |
| SCIBENCH [paper] [github] | No | Evaluate college-level scientific problem-solving in math, physics, and chemistry | Open-ended accuracy and skill-specific error attribution |
| Vicuna Evaluation [paper] [github] | No | Evaluate instruction-following quality in chat settings | Human / GPT-4 preference comparison accuracy |
| MT-Bench [paper] [github] | No | Evaluate multi-turn conversational and instruction-following capabilities | Win-rate judged by GPT-4 |
| AlpacaEval [paper] [github] | No | Evaluate instruction-following via LLM-based auto-annotation | Length-controlled win-rate correlated with human preference |
| Chatbot Arena [github] | No | Evaluate LLMs via human-voted battles using Elo rating | Elo score and head-to-head win rate |
| PandaLM [paper] [github] | No | Evaluate instruction-following quality and hyperparameter impact | Win-rate judged by PandaLM |
| HellaSwag [paper] [github] [huggingface] | No | Evaluate commonsense inference | Multiple-choice accuracy |
| TruthfulQA [paper] [github] [huggingface] | No | Evaluate LLM truthfulness and avoidance of imitative falsehoods | Truthfulness rate and MC accuracy |
| ScienceQA [paper] [github] [huggingface] | No | Evaluate multimodal scientific reasoning and explanation generation | Multiple-choice accuracy and explanation quality |
| Chain-of-Thought Hub [paper] [github] | No | Evaluate LLMs’ multi-step reasoning with CoT prompting | Few-shot CoT accuracy |
| NeuLR [paper] [github] | No | Evaluate deductive, inductive, and abductive reasoning | Multi-dimensional accuracy |
| ALCUNA [paper] [github] | No | Evaluate comprehension & reasoning over novel knowledge | Accuracy on 84 351 queries |
| LMExamQA [paper] [github] | No | Evaluate knowledge recall, understanding, and analysis | Accuracy on 10 090 questions |
| SocKET [paper] [github] | No | Evaluate LLMs’ sociability & social knowledge | Accuracy and other metrics |
| Choice-75 [paper] | No | Evaluate decision reasoning in scripted scenarios | Accuracy on binary multiple-choice questions |
| HELM [paper] [github] | No | Evaluate LMs via multi-metric scenarios | Composite normalized performance |
| OpenLLM [github] | No | Evaluate open-style reasoning across multiple benchmarks | Normalized accuracy aggregate |
| BOSS [paper] [github] | No | Evaluate OOD robustness across NLP tasks | OOD accuracy drop & ID–OOD correlation |
| GLUE-X [github] | No | Evaluate OOD robustness | Average OOD accuracy drop |
| PromptBench [paper] [github] | No | Evaluate robustness / prompt-engineering | Adversarial success & robustness |
| DynaBench [paper] [github] | No | Evaluate robustness via dynamic human-in-loop data | Error rate on human-crafted challenges |
| KoLA [paper] [github] | No | Evaluate world knowledge across 19 evolving tasks | Self-contrast calibration |
| CELLO [paper] [github] | No | Evaluate following complex real-world instructions | Multi-criteria compliance rate |
| LLMEval [github] | No | Meta-evaluate LLM evaluators | Meta-evaluator accuracy |
| Xiezhi [paper] [github] | No | Evaluate holistic domain knowledge (516 disciplines) | MRR |
| C-Eval [paper] [github] | No | Evaluate Chinese domain knowledge & reasoning | Multiple-choice accuracy |
| BELLE-eval [github] | No | Evaluate Chinese instruction-following & multi-skill | GPT-4 win-rate & per-task scores |
| SuperCLUE [github] | No | Evaluate Chinese instruction-following with alignment | GPT-4 win-rate & Elo |
| M3KE [paper] [github] | No | Evaluate Chinese LLM knowledge (71 disciplines) | Zero-/few-shot multitask accuracy |
| BayLing-80 [github] | No | Evaluate cross-lingual & conversational capabilities | GPT-4 adjudicated win-rate |
| MMCU [paper] [github] [huggingface] | No | Evaluate multitask Chinese understanding | Multitask accuracy |
| C-CLUE [github] | No | Evaluate classical Chinese NER & RE | Weighted F1 |
| LongBench [paper] [github] [huggingface] | Yes | Evaluate bilingual long-context understanding | Accuracy & generation quality |
| L-Eval [paper] [github] | Yes | Evaluate long-context reasoning up to 60 K tokens | Multi-metric assessment |
| InfinityBench [paper] [github] | Yes | Evaluate contexts beyond 100 K tokens | Accuracy & task-specific metrics |
| Marathon [paper] [github] | Yes | Evaluate long-context reasoning across domains | EM / F1 / ROUGE-L / accuracy |
| LongEval [paper] [github] | Yes | Evaluate effectiveness in long-context retrieval | Retrieval accuracy |
| BABILong [paper] [github] | Yes | Evaluate long-context reasoning in haystack settings | Accuracy |
| DetectiveQA [paper] [github] | Yes | Evaluate narrative reasoning via detective novels | Instruction-following accuracy |
| NoCha [paper] [github] | Yes | Evaluate narrative comprehension & coreference | Exact match & accuracy |
| Loong [paper] [github] | Yes | Evaluate multi-document reasoning & QA | Answer accuracy & doc coverage |
| TCELongBench [paper] [github] | Yes | Evaluate temporal reasoning over long event narratives | Temporal ordering & QA accuracy |
| DENIAHL [paper] [github] | Yes | Evaluate in-context feature influence on NIAH | Retrieval & reasoning accuracy |
| LongMemEval [paper] | Yes | Benchmark memory retention in dialogue | Memory retention & utilization |
| Long2RAG [paper] | Yes | Evaluate long-form generation & retrieval grounding | Key-point recall & factuality |
| L-CiteEval [paper] [github] | Yes | Evaluate citation usage & contextual evidence | Citation recall & faithfulness |
| LIFBENCH [paper] [github] | Yes | Evaluate instruction-following performance & stability | Accuracy & response stability |
| LongReason [paper] | Yes | Evaluate synthetic long-context reasoning | Instruction-following accuracy |
| BAMBOO [paper] [github] | Yes | Evaluate long-text modeling across tasks | Accuracy & win-rate |
| ETHIC [paper] | Yes | Evaluate instruction-following on high-info long tasks | EM / F1 & consistency |
| LooGLE [paper] [github] | Yes | Evaluate understanding & reasoning over 20 K-word inputs | Accuracy |
| HELMET [paper] [github] | Yes | Evaluate retrieval, reasoning, summarization, long-context | Task-specific automatic & human metrics |
| HoloBench [paper] | Yes | Evaluate holistic reasoning over DB-style inputs | Execution accuracy & consistency |
| LOFT [paper] | Yes | Evaluate replacing RAG with long-context LLMs | EM / F1 / SQL accuracy |
| Lv-Eval [paper] [github] | Yes | Evaluate comprehension across length levels ≤ 256 K | Exact match & factuality |
| ManyICLBench [paper] | Yes | Evaluate many-shot ICL under long contexts | Average accuracy |
| ZeroSCROLLS [paper] | Yes | Evaluate zero-shot inference on diverse long-text tasks | Accuracy |
| LongICLBench [paper] | Yes | Evaluate ICL under extended input lengths | Win-rate judged by PandaLM |
| LIBRA [paper] [github] | Yes | Evaluate long-context understanding in Russian | Accuracy, BLEU, faithfulness |
Domain: Finance
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| FinBen [paper] [github] [huggingface] | No | Evaluate holistic financial capabilities across 24 tasks | Automatic metrics, agent/RAG performance, and human expert assessment |
| PIXIU [paper] [github] [huggingface] | No | Evaluate LLMs across multiple financial NLP tasks | Sentiment accuracy, QA accuracy, stock prediction F1 |
| FLUE [paper] [github] [huggingface] | No | Evaluate diverse financial NLP competencies | Accuracy, F1, nDCG |
| BBF-CFLEB [paper] [github] | No | Evaluate LLMs on Chinese financial language understanding and generation across six task types | Rouge, F1, and accuracy |
| CFinBench [paper] [github] | No | Evaluate Chinese financial knowledge across subjects, certifications, practice, and legal compliance | Accuracy across single-choice, multiple-choice, and judgment questions |
| SuperCLUEFin [paper] | No | Evaluate Chinese financial assistant capabilities | Win-rate and multi-criteria performance |
| ICE-PIXIU [paper] [github] | No | Evaluate bilingual (Chinese–English) financial reasoning and analysis capabilities | Task-specific accuracy and bilingual win-rate |
| FLARE-ES [paper] | No | Evaluate bilingual Spanish–English financial reasoning | Task-specific accuracy and cross-lingual transfer win-rate |
| FinanceBench [paper] [github] | No | Evaluate financial open-book QA using real-world company-related questions | Factual correctness and evidence alignment |
| FiNER-ORD [paper] [github] [huggingface] | No | Evaluate financial NER capability in financial texts | Entity F1 |
| FinRED [paper] [github] [huggingface] | No | Evaluate financial relation extraction performance on news and earnings transcripts | F1, Entity F1 |
| FinQA [paper] [github] [huggingface] | No | Evaluate multi-step numerical reasoning over financial reports with structured evidence | EM Accuracy |
| BizBench [paper] [huggingface] | No | Evaluate quantitative reasoning on realistic financial problems | Numeric EM, code execution pass rate, QA accuracy |
| EconLogicQA [paper] [huggingface] | No | Evaluate economic sequential reasoning across multi-event scenarios | Multiple-choice accuracy |
| FinEval [github] | No | Evaluate Chinese financial domain knowledge and reasoning | Multiple-choice accuracy and task-level weighted scores |
| CFBenchmark [paper] [github] | No | Evaluate Chinese financial assistant capabilities | Win-rate and task-specific metrics |
| BBT-Fin [paper] [github] | No | Evaluate Chinese financial language understanding and generation | Accuracy, F1, ROUGE |
| Hirano [paper] [github] | No | Evaluate Japanese financial language understanding | Multiple-choice accuracy and macro-F1 scores |
| MultiFin [paper] [github] [huggingface] | No | Evaluate multilingual financial topic classification | F1, Multi-class accuracy |
| DocFinQA [paper] [huggingface] | Yes | Evaluate long-context financial reasoning over documents like financial reports | EM and F1 for multi-step answer prediction, and reasoning accuracy |
| FinTextQA [huggingface] | Yes | Evaluate long-form financial question answering with long textual context | Answer accuracy, BLEU, and ROUGE |
Domain: Medicine
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| CBLUE [paper] [github] | No | Evaluate Chinese biomedical language understanding across multiple clinical and QA tasks | Accuracy, F1-score, and macro-average metrics across subtasks |
| PromptCBLUE [paper] [github] [huggingface] | No | Evaluate LLMs on prompt-based generation across 16 Chinese medical NLP tasks | Accuracy, BLEU, and ROUGE scores |
| CMB [paper] [github] [huggingface] | No | Evaluate comprehensive Chinese medical knowledge via exam-style QA and clinical diagnosis | Accuracy, expert grading, and model-based evaluation |
| HuaTuo26M-test [paper] [github] [huggingface] | No | Evaluate Chinese medical knowledge and QA ability using real-world clinical queries | Accuracy and relevance |
| CMExam [paper] [github] [huggingface] | No | Evaluate LLMs on Chinese medical licensing exam QA with fine-grained annotations | Accuracy, weighted F1, and expert-judged reasoning quality |
| MultiMedQA [paper] | No | Evaluate LLMs’ clinical knowledge via multiple-choice and open-ended medical QA tasks | Expert-rated helpfulness, factuality, and safety |
| QiZhenGPT eval [github] | No | Evaluate LLMs' ability to identify drug indications from natural-language prompts | Expert-annotated correctness score |
| MedExQA [paper] [github] | No | Evaluate medical knowledge and explanation generation across under-represented specialties | Explanation quality and expert-aligned relevance |
| JAMA and Medbullets [paper] [github] | No | Evaluate LLMs' ability to answer and explain challenging clinical questions | Answer accuracy, explanation quality, and human-aligned reasoning assessment |
| MedXpertQA [paper] [github] [huggingface] | No | Evaluate expert-level medical reasoning and multimodal clinical understanding | Answer accuracy, image-text reasoning, and expert-aligned scoring |
| MedJourney [paper] | No | Evaluate LLM performance across full clinical patient journey stages and tasks | Task-specific automatic metrics and human expert evaluations |
| MedAgentsBench [paper] [github] | No | Evaluate complex multi-step clinical reasoning including diagnosis and treatment planning | Multi-aspect evaluation: correctness, efficiency, human expert ratings |
| LongHealth [paper] [github] | Yes | Evaluate question answering over long-form clinical documents | EM, F1, and long-context QA accuracy |
| MedOdyssey [paper] [github] | Yes | Evaluate long-context understanding in the medical domain (up to 200 K tokens) | Task-specific EM, ROUGE, and human preference scoring |
Domain: Code
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| HumanEval [paper] [github] [huggingface] | No | Evaluate code generation, algorithmic reasoning, and language understanding with functional correctness | Test-case execution accuracy (pass@k) |
| MBPP [paper] [github] [huggingface] | No | Evaluate basic Python code generation on crowdsourced programming tasks | Functional correctness via pass@k using automated test cases |
| APPS [paper] [github] [huggingface] | No | Evaluate coding-challenge competence through real-world programming problems | Pass@k and exact match for functional correctness |
| DS-1000 [paper] [github] [huggingface] | No | Evaluate data-science code generation across real queries from 7 Python libraries | Functional correctness via automated test-based execution accuracy |
| CodeXGLUE [paper] [github] | No | Evaluate code understanding and generation across 9 tasks in 4 I/O types | BLEU, EM, F1, Accuracy, MAP (task-specific) |
| CruxEval [paper] [github] | No | Evaluate code reasoning, understanding, and execution | pass@1 accuracy |
| ODEX [paper] [github] [huggingface] | No | Evaluate cross-lingual code generation from NL queries in four languages | Execution-based functional correctness |
| MTPB [paper] [github] | No | Evaluate multi-turn program synthesis | Functional correctness via pass@k on step-wise sub-programs |
| ClassEval [paper] [github] [huggingface] | No | Evaluate class-level code generation from NL descriptions (Python) | pass@1, class completeness, dependency consistency |
| BigCodeBench [paper] [github] [huggingface] | No | Evaluate LLMs’ ability to follow complex instructions and invoke diverse function calls | Pass@k, test-case execution accuracy, branch coverage |
| HumanEvalPack [github] [huggingface] | No | Evaluate multilingual code generation, correction, and comment synthesis across six languages | Functional correctness via pass@k and task-specific metrics |
| BIRD [pape] [github] | No | Evaluate database-grounded text-to-SQL generation over large, noisy databases | Execution accuracy and exact match |
| RepoQA [github] | Yes | Evaluate long-context code understanding in real software repositories | Exact-match accuracy and retrieval-augmented correctness |
| LongCodeArena [paper] [github] [huggingface] | Yes | Evaluate long-context code comprehension, generation, and editing across project-wide tasks | Task-specific accuracy, exact match, and human evaluation |
Domain: Math
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| GSM8K [paper] [github] [huggingface] | No | Assess grade school math reasoning | Exact match accuracy |
| MATH [paper] [github] [huggingface] | No | Evaluate competition-level math problem-solving with step-by-step reasoning | Final answer accuracy & derivation correctness |
| MathOdyssey [paper] [github] [huggingface] | No | Benchmark high-school → Olympiad → university math across difficulty tiers | Answer accuracy across difficulty levels |
| MathBench [paper] [github] | No | Evaluate theoretical & applied math knowledge across five levels | Accuracy on theoretical and application problems |
| CHAMP [paper] [github] | No | Fine-grained competition-level reasoning with concept/hint annotations | Answer accuracy & reasoning-path correctness |
| LILA [paper] [github] [huggingface] | No | Unified benchmark across 23 math tasks & formats | Accuracy across tasks |
| MiniF2F-v1 [paper] [github] | No | Formal theorem-proving at Olympiad level | Proof accuracy on 488 problems |
| ProofNet [paper] [github] [huggingface] | No | Auto-formalization & formal proof generation (Lean 3) | Formalization accuracy & proof success rate |
| AlphaGeometry [paper] [github] | No | Neuro-symbolic reasoning on Olympiad Euclidean geometry | Proof success, correctness, completeness, readability |
| MathVerse [paper] [github] [huggingface] | No | Visual-diagram math reasoning for MLLMs | Diagram-sensitive answer accuracy & CoT score |
| We-Math [paper] [github] [huggingface] | No | Human-like visual mathematical reasoning with knowledge hierarchy | Four-dimensional diagnostic metrics |
| U-MATH [paper] [github] | No | Open-ended university-level problem-solving (20 % multimodal) | LLM-judged solution correctness (expert-verified F1) |
| TabMWP [paper] [github] | No | Math reasoning over textual + tabular data | Accuracy on QA & MC questions |
| MathHay [paper] [github] | Yes | Long-context mathematical reasoning with multi-step dependencies | Accuracy, exact match, reasoning-chain consistency |
Domain: Law
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| LegalBench [paper] [github] [huggingface] | No | Evaluate legal reasoning across six types including rule application and interpretation | Task-specific accuracy, rule-consistency, LLM-as-a-judge ratings |
| LexGLUE [paper] [github] [huggingface] | No | Evaluate legal language understanding across classification and QA tasks | Task-specific accuracy & F1 |
| LEXTREME [paper] [github] [huggingface] | No | Evaluate multilingual & multitask legal understanding (24 languages, 18 tasks) | Macro-F1, accuracy, other classification metrics |
| LawBench [paper] [github] | No | Evaluate Chinese legal LLMs across retention, understanding & application (20 tasks) | Task-specific accuracy & F1 |
| LAiW [paper] [github] | No | Evaluate Chinese legal LLMs across fundamental → advanced tasks (13 assignments) | Task-specific accuracy & F1 |
| LexEval [paper] [github] [huggingface] | No | Evaluate Chinese legal reasoning via a taxonomy of cognitive abilities | Task-specific accuracy |
| CitaLaw [paper] | No | Evaluate citation-grounded legal answering with statutes & precedents | Syllogism-alignment, citation accuracy, legal consistency |
| LegalAgentBench [paper] [github] | No | Evaluate LLM agents solving complex real-world legal tasks | Task success rate & intermediate progress |
| SCALE [paper] [github] | Yes | Evaluate long-doc, multilingual, multitask legal reasoning (≤ 50 K tokens) | Accuracy, F1, code-based assessment for long-context legal tasks |
⭐ Citation
If you find this work useful, welcome to cite us.
@misc{wu2025surveyfederatedfinetuninglarge,
      title={A Survey on Federated Fine-tuning of Large Language Models},
      author={Yebo Wu and Chunlin Tian and Jingguang Li and He Sun and Kahou Tam and Zhanting Zhou and Haicheng Liao and Zhijiang Guo and Li Li and Chengzhong Xu},
      year={2025},
      eprint={2503.12016},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2503.12016},
}
Contributors

Clin0212
4 commits
Similar repos


README
Awesome-Federated-LLM-Learning
📢 Updates
We released a survey paper "A Survey on Federated Fine-tuning of Large Language Models". Feel free to cite or open pull requests.
⚠️ NOTE: If there is any missing or new relevant literature, please feel free to submit an issue. we will update the Github and Arxiv papers regularly. 😊
👀 Overall Structure
📒 Table of Contents
- Awesome-Federated-LLM-Learning
- Datasets and Benchmarks
Part 1: LoRA-based Tuning
1.1 Homogeneous LoRA
- Fedra: A random allocation strategy for federated tuning to unleash the power of heterogeneous clients. [Paper]
- Towards building the federatedGPT: Federated instruction tuning.[Paper]
- Communication-Efficient and Tensorized Federated Fine-Tuning of Large Language Models. [Paper]
- Selective Aggregation for Low-Rank Adaptation in Federated Learning. [Paper]
- Federa: Efficient fine-tuning of language models in federated learning leveraging weight decomposition. [Paper]
- LoRA-FAIR: Federated LoRA Fine-Tuning with Aggregation and Initialization Refinement. [Paper]
- Federated LoRA with Sparse Communication. [Paper]
- SA-FedLora: Adaptive Parameter Allocation for Efficient Federated Learning with LoRA Tuning. [Paper]
- SLoRA: Federated parameter efficient fine-tuning of language models. [Paper]
- FederatedScope-LLM: A Comprehensive Package for Fine-tuning Large Language Models in Federated Learning [Paper]
- Robust Federated Finetuning of Foundation Models via Alternating Minimization of LoRA. [Paper]
- Automated federated pipeline for parameter-efficient fine-tuning of large language models. [Paper]
- Low-Parameter Federated Learning with Large Language Models. [Paper]
- Towards Robust and Efficient Federated Low-Rank Adaptation with Heterogeneous Clients. [Paper]
- FedRA: A Random Allocation Strategy for Federated Tuning to Unleash the Power of Heterogeneous Clients. [Paper]
- Fed-piLot: Optimizing LoRA Assignment for Efficient Federated Foundation Model Fine-Tuning. [Paper]
1.2 Heterogeneous LoRA
- Heterogeneous lora for federated fine-tuning of on-device foundation models. [Paper]
- Flora: Federated fine-tuning large language models with heterogeneous low-rank adaptations. [Paper]
- Federated fine-tuning of large language models under heterogeneous tasks and client resources. [Paper]
- Federated LLMs Fine-tuned with Adaptive Importance-Aware LoRA. [Paper]
- Towards Federated Low-Rank Adaptation of Language Models with Rank Heterogeneity. [Paper]
- Fedhm: Efficient federated learning for heterogeneous models via low-rank factorization. [Paper]
- RBLA: Rank-Based-LoRA-Aggregation for Fine-Tuning Heterogeneous Models. [Paper]
1.3 Personalized LoRA
- FDLoRA: Personalized Federated Learning of Large Language Model via Dual LoRA Tuning. [Paper]
- Fedlora: Model-heterogeneous personalized federated learning with lora tuning. [Paper]
- FedLoRA: When Personalized Federated Learning Meets Low-Rank Adaptation. [Paper]
- Dual-Personalizing Adapter for Federated Foundation Models. [Paper]
- Personalized Federated Instruction Tuning via Neural Architecture Search. [Paper]
- Communication-Efficient Personalized Federated Learning for Speech-to-Text Tasks. [Paper]
- Personalized Federated Fine-Tuning for LLMs via Data-Driven Heterogeneous Model Architectures. [Paper]
Part 2: Prompt-based Tuning
2.1 General Prompt Tuning
- Prompt federated learning for weather forecasting: Toward foundation models on meteorological data. [Paper]
- Promptfl: Let federated participants cooperatively learn prompts instead of models-federated learning in age of foundation model. [Paper]
- Fedbpt: Efficient federated black-box prompt tuning for large language models. [Paper]
- Federated learning of large language models with parameter-efficient prompt tuning and adaptive optimization. [Paper]
- Efficient federated prompt tuning for black-box large pre-trained models. [Paper]
- Text-driven prompt generation for vision-language models in federated learning. [Paper]
- Learning federated visual prompt in null space for mri reconstruction. [Paper]
- Fed-cprompt: Contrastive prompt for rehearsal-free federated continual learning. [Paper]
- Fedprompt: Communication-efficient and privacy-preserving prompt tuning in federated learning. [Paper]
- Tunable soft prompts are messengers in federated learning. [Paper]
- Hepco: Data-free heterogeneous prompt consolidation for continual federated learning. [Paper]
- Prompt-enhanced Federated Learning for Aspect-Based Sentiment Analysis. [Paper]
- Towards practical few-shot federated nlp. [Paper]
- Federated prompting and chain-of-thought reasoning for improving llms answering. [Paper]
- FedHPL: Efficient Heterogeneous Federated Learning with Prompt Tuning and Logit Distillation. [Paper]
- Probabilistic Federated Prompt-Tuning with Non-IID and Imbalanced Data. [Paper]
- Federated Class-Incremental Learning with Prompting. [Paper]
- Explore and Cure: Unveiling Sample Effectiveness with Context-Aware Federated Prompt Tuning. [Paper]
- Federated Prompt Learning for Weather Foundation Models on Devices. [Paper]
2.2 Personalized Prompt Tuning
- Efficient model personalization in federated learning via client-specific prompt generation. [Paper]
- Unlocking the potential of prompt-tuning in bridging generalized and personalized federated learning. [Paper]
- Pfedprompt: Learning personalized prompt for vision-language models in federated learning. [Paper]
- Global and local prompts cooperation via optimal transport for federated learning. [Paper]
- Visual prompt based personalized federated learning. [Paper]
- Personalized federated continual learning via multi-granularity prompt. [Paper]
- FedLPPA: Learning Personalized Prompt and Aggregation for Federated Weakly-supervised Medical Image Segmentation. [Paper]
- Harmonizing Generalization and Personalization in Federated Prompt Learning. [Paper]
- Tackling Feature-Classifier Mismatch in Federated Learning via Prompt-Driven Feature Transformation. [Paper]
- Personalized Federated Learning for Text Classification with Gradient-Free Prompt Tuning. [Paper]
- Mixture of Experts Made Personalized: Federated Prompt Learning for Vision-Language Models. [Paper]
- CP 2 GFed: Cross-granular and Personalized Prompt-based Green Federated Tuning for Giant Models. [Paper]
2.3 Multi-domain Prompt Tuning
- DiPrompT: Disentangled Prompt Tuning for Multiple Latent Domain Generalization in Federated Learning. [Paper]
- Prompt-enhanced Federated Content Representation Learning for Cross-domain Recommendation. [Paper]
- Dual prompt tuning for domain-aware federated learning. [Paper]
- Federated adaptive prompt tuning for multi-domain collaborative learning. [Paper]
- Breaking physical and linguistic borders: Multilingual federated prompt tuning for low-resource languages. [Paper]
- Federated Domain Generalization via Prompt Learning and Aggregation. [Paper]
- CP-Prompt: Composition-Based Cross-modal Prompting for Domain-Incremental Continual Learning. [Paper]
Part 3: Adapter-based Tuning
3.1 General Adapter Tuning
- Efficient federated learning for modern nlp. [Paper]
- Efficient federated learning with pre-trained large language model using several adapter mechanisms. [Paper]
3.2 Personalized Adapter Tuning
- Client-customized adaptation for parameter-efficient federated learning. [Paper]
- Fedclip: Fast generalization and personalization for clip in federated learning. [Paper]
3.3 Multi-domain Adapter Tuning
- Communication efficient federated learning for multilingual neural machine translation with adapter. [Paper]
- Adapter-based Selective Knowledge Distillation for Federated Multi-domain Meeting Summarization. [Paper]
- Feddat: An approach for foundation model finetuning in multi-modal heterogeneous federated learning. [Paper]
Part 4: Selective-based Tuning
4.1 Bias Tuning
- Differentially private bias-term only fine-tuning of foundation models. [Paper]
- Conquering the communication constraints to enable large pre-trained models in federated learning. [Paper]
4.2 Partial Tuning
- Bridging the gap between foundation models and heterogeneous federated learning. [Paper]
- Exploring Selective Layer Fine-Tuning in Federated Learning. [Paper]
Part 5: Other Tuning Methods
5.1 Zero-Order Optimization
- Federated full-parameter tuning of billion-sized language models with communication cost under 18 kilobytes. [Paper]
- ${$FwdLLM$}$: Efficient Federated Finetuning of Large Language Models with Perturbed Inferences. [Paper]
- ZooPFL: Exploring black-box foundation models for personalized federated learning. [Paper]
- On the convergence of zeroth-order federated tuning for large language models. [Paper]
- Thinking Forward: Memory-Efficient Federated Finetuning of Language Models. [Paper]
- Communication-Efficient Byzantine-Resilient Federated Zero-Order Optimization. [Paper]
5.2 Split Learning
- FedBERT: When federated learning meets pre-training. [Paper]
- Federated split bert for heterogeneous text classification. [Paper]
- FedSplitX: Federated Split Learning for Computationally-Constrained Heterogeneous Clients. [Paper]
5.3 Model Compression
- Fedbiot: Llm local fine-tuning in federated learning without full model. [Paper]
5.4 Data Selection
- Federated Data-Efficient Instruction Tuning for Large Language Models. [Paper]
Datasets and Benchmarks
Prompt-tuning Datasets
Domain: General
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| Alpaca [paper] [github] [huggingface] | English | Model Construct | Generated by Text-Davinci-003 with Alpaca-style instruction prompts. |
| Alpaca-GPT4 [paper] [github] [huggingface] | English | Model Construct | Generated by GPT-4 based on Alpaca prompts with richer multi-turn instructions. |
| Self-Instruct [paper] [github] [huggingface] | English | Human + Model Construct | Seed instructions expanded by GPT-3 to improve model generalization. |
| UltraChat 200k [paper] [github] [huggingface] | English | Model Construct | High-quality multi-turn dialogue subset filtered from UltraChat. |
| OpenOrca [paper] [github] [huggingface] | English | Model Construct | ~4.2 M GPT-3.5/4-augmented FLAN examples for instruction following. |
| ShareGPT90K [github] [huggingface] | English | Model Construct | 90 K multi-turn dialogues extracted from ShareGPT. |
| WizardLM Evol-Instruct V2 196k [paper] [github] [huggingface] | English | Model Construct | 196 K examples generated via Evol-Instruct. |
| Databricks Dolly 15K [paper] [github] [huggingface] | English | Human Construct | 15 K human-written prompt-response pairs across diverse tasks. |
| Baize [paper] [github] [huggingface] | English | Model Construct | Instruction-following dialogues generated via ChatGPT self-chat. |
| OpenChat [paper] [github] [huggingface] | English | Model Construct | Mixed-quality data alignment using C-RLFT for open LLMs. |
| Flan-v2 [paper] [github] [huggingface] | English | Model Construct | Aggregates Flan, P3, Super-Natural Instructions, CoT, Dialog tasks. |
| BELLE-train-0.5M-CN [paper] [github] [huggingface] | Chinese | Human + Model Construct | 519 K Chinese instruction-following examples. |
| BELLE-train-1M-CN [paper] [github] [huggingface] | Chinese | Human + Model Construct | 917 K Chinese instruction samples. |
| BELLE-train-2M-CN [paper] [github] [huggingface] | Chinese | Human + Model Construct | 2 M Chinese instruction samples. |
| Firefly-train-1.1M [paper] [github] [huggingface] | Chinese | Human Construct | 1.65 M Chinese samples across 23 tasks with human templates. |
| Wizard-LM-Chinese-instruct-evol [paper] [github] [huggingface] | Chinese | Human + Model Construct | 70 K WizardLM instructions translated into Chinese. |
| HC3-Chinese [paper] [github] [huggingface] | Chinese | Human + Model Construct | Human-ChatGPT QA pairs in Chinese. |
| HC3 [paper] [github] [huggingface] | English / Chinese | Human + Model Construct | Bilingual Human-ChatGPT QA pairs. |
| ShareGPT-Chinese-English-90k [github] [huggingface] | English / Chinese | Model Construct | 90 K bilingual user queries from ShareGPT logs. |
Domain: Finance
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| FinGPT [paper] [github] [huggingface] | English | Human + Model Construct | Instruction-tuning data for diverse financial tasks. |
| Finance-Instruct-500k [paper] [github] [huggingface] | English | Human + Model Construct | Large-scale (500 K) instruction dataset for finance reasoning. |
| Finance-Alpaca [github] [huggingface] | English | Human + Model Construct | Alpaca-style instructions combined with FiQA and custom Q&A. |
| Financial PhraseBank [paper] [github] [huggingface] | English | Human Construct | Manually annotated news sentences for sentiment classification. |
| Yahoo-Finance-Data [huggingface] | English | Human Construct | Historical prices and fundamentals scraped from Yahoo Finance. |
| Financial-QA-10K [github] [huggingface] | English | Model Construct | 10 K contextual QA pairs generated from SEC 10-K filings. |
| Financial-Classification [huggingface] | English | Human Construct | Merged Financial PhraseBank + Kaggle texts for sentiment/topic classification. |
| Twitter-Financial-News-Topic [github] [huggingface] | English | Human Construct | 21 K annotated tweets for multi-class financial topic tagging. |
| Financial-News-Articles [github] [huggingface] | English | Human Construct | 300 K+ news articles for text classification and sentiment analysis. |
| FiQA [paper] [github] [huggingface] | English | Human Construct | Financial question-answering dataset from forums and texts. |
| Earnings-Call [paper] [huggingface] | English | Human Construct | QA pairs extracted from CEO/CFO earnings-call transcripts. |
| Doc2EDAG [paper] [github] | Chinese | Human Construct | Chinese financial reports annotated for document-level event graphs. |
| Synthetic-PII-Finance-Multilingual [paper] [github] [huggingface] | Multilingual | Synthetic | Synthetic financial documents with labeled PII for privacy-preserving NER. |
Domain: Medicine
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| ChatDoctor-200K [paper] [github] [huggingface] | English | Human + Model Construct | Instruction tuning dataset for medical QA and dialogue generation. |
| ChatDoctor-HealthCareMagic-100k [paper] [github] [huggingface] | English | Human Construct | Real-world doctor-patient conversations from HealthCareMagic. |
| Medical Meadow CORD-19 [paper] [github] [huggingface] | English | Human Construct | Summaries of biomedical papers from CORD-19 for instruction tuning. |
| Medical Meadow MedQA [paper] [github] [huggingface] | English | Human Construct | Multiple-choice medical QA derived from MedQA exam questions. |
| HealthCareMagic-100k-en [paper] [github] [huggingface] | English | Human Construct | English subset of HealthCareMagic doctor-patient consultations. |
| ChatMed-Consult-Dataset [github] [huggingface] | Chinese | Human + Model Construct | Chinese medical consultations with GPT-3.5 answers. |
| CMtMedQA [paper] [github] | Chinese | Human Construct | 70 K multi-turn doctor-patient QA dialogues for Chinese medical reasoning. |
| DISC-Med-SFT [paper] [github] [huggingface] | Chinese | Human + Model Construct | 470 K instruction pairs combining real dialogues and KG-based QA. |
| Huatuo-26M [paper] [github] [huggingface] | Chinese | Human Construct | 26 M QA pairs extracted from encyclopedias, KBs and consultations. |
| Huatuo26M-Lite [paper] [github] [huggingface] | Chinese | Human + Model Construct | Refined subset of Huatuo-26M with ChatGPT-rewritten answers. |
| ShenNong-TCM-Dataset [github] [huggingface] | Chinese | Human + Model Construct | 110 K TCM-centric instructions generated via entity-centric self-instruct. |
| HuatuoGPT-sft-data-v1 [paper] [github] [huggingface] | Chinese | Human + Model Construct | SFT corpus mixing ChatGPT-distilled and real doctor data for HuatuoGPT. |
| MedDialog [paper] [github] [huggingface] | English / Chinese | Human Construct | Large-scale doctor-patient dialogue corpora (0.3 M EN / 3.4 M CN conversations). |
Domain: Code
| Dataset / Benchmark Name | Language | Construction Method | Description |
|---|---|---|---|
| CodeAlpaca [github] [huggingface] | English | Model Construct | GPT-generated code instruction-following dataset in Alpaca style. |
| Code Instructions 120k Alpaca [huggingface] | English | Human + Model Construct | 120 k natural-language ↔ code instruction pairs with Alpaca-format prompts. |
| CodeContests [github] [huggingface] | English | Human Construct | Competitive-programming problems and solutions for program-synthesis research. |
| CommitPackFT [paper] [github] [huggingface] | English | Human Construct | 2 GB filtered Git commits with high-quality messages for code instruction tuning. |
| ToolBench [paper] [github] | English | Human + Model Construct | Instruction dataset for multi-tool API usage and tool-calling agents. |
| CodeParrot-Clean [huggingface] | English | Human Construct | Deduplicated & filtered GitHub Python corpus for code-generation pre-training. |
| The Stack v2 Dedup [paper] [huggingface] | English | Human Construct | Large-scale (600 + languages) deduplicated source-code dataset from BigCode. |
| CodeSearchNet [paper] [github] [huggingface] | English | Human Construct | 6 M code–doc pairs across six languages for code search & retrieval. |
| CodeForces-CoTs [github] [huggingface] | English | Human + Model Construct | 10 k CodeForces problems with chain-of-thought traces distilled by DeepSeek R1. |
| CodeXGLUE Code Refinement [paper] [github] [huggingface] | English | Human Construct | Buggy ↔ fixed Java function pairs for automatic code repair and refinement. |
Domain: Math
| Dataset | Language | Construction Method | Description |
|---|---|---|---|
| GSM8K [paper] [github] [huggingface] | English | Human Construct | A dataset of 8.5 K grade-school arithmetic word problems with step-by-step solutions. |
| CoT-GSM8k [huggingface] | English | Human + Model Construct | Extended GSM8K with explicit chain-of-thought reasoning traces. |
| MathInstruct [paper] [github] [huggingface] | English | Human + Model Construct | Hybrid CoT + PoT rationales spanning diverse mathematical fields. |
| MetaMathQA [paper] [github] [huggingface] | English | Human + Model Construct | Multi-perspective question augmentations bootstrapped from GSM8K & MATH. |
| OpenR1-Math-220k [github] [huggingface] | English | Human + Model Construct | 220 K problems with multiple DeepSeek R1 reasoning traces. |
| Hendrycks MATH Benchmark [paper] [github] [huggingface] | English | Human Construct | 12.5 K high-school competition problems with detailed solutions. |
| DeepMind Mathematics Dataset [paper] [github] [huggingface] | English | Synthetic | Algorithmically generated problems covering many school-math topics. |
| OpenMathInstruct-1 [paper] [github] [huggingface] | English | Human + Model Construct | 1.8 M problems with Mixtral code-interpreter solutions. |
| Orca-Math Word Problems 200k [paper] [huggingface] | English | Synthetic | 200 K grade-school word problems distilled with GPT-4 Turbo. |
| DAPO-Math-17k [paper] [huggingface] | English | Human + Model Construct | 17 K math prompts curated for large-scale RL (GRPO) experiments. |
| Big-Math-RL-Verified [paper] [github] [huggingface] | English | Human + Model Construct | 251 K verifiable problems filtered for reinforcement-learning fine-tuning. |
| BELLE-math-zh [github] [huggingface] | Chinese | Human + Model Construct | 250 K Chinese elementary-math problems with step-by-step solutions. |
| MathInstruct-Chinese [huggingface] | Chinese | Model Construct | Chinese translation/extension of MathInstruct for instruction tuning. |
Domain: Law
| Dataset / Benchmark Name | Language | Construction Method | Description |
|---|---|---|---|
| Legal-QA-v1 [huggingface] | English | Human Construct | 3.7 K QA pairs sourced from legal forums. |
| Pile of Law [paper] [github] [huggingface] | English | Human Construct | 256 GB corpus of U.S. legal and administrative text for domain pre-training. |
| CUAD [paper] [github] [huggingface] | English | Human Construct | 26 K expert-annotated contract QA pairs spanning 41 clause types. |
| LEDGAR [paper] [github] [huggingface] | English | Human Construct | 1.45 M labeled contract clauses for multi-label classification. |
| DISC-Law-SFT [paper] [github] [huggingface] | Chinese | Human + Model Construct | 295 K supervised fine-tuning samples covering extraction, judgment prediction, QA, & summarization. |
| Law-GPT-zh [paper] [github] [huggingface] | Chinese | Human Construct | Sentence-pair corpus devised for Chinese legal sentence embedding & instructional tuning. |
| Lawyer LLaMA Data [paper] [github] [huggingface] | Chinese | Human + Model Construct | Instruction data for legal consultation and bar-exam QA used to train Lawyer LLaMA. |
Evaluation Benchmarks
Domain: General
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| MMLU [paper] [github] [huggingface] | No | Evaluate multitask language understanding across 57 subjects | Multitask accuracy |
| BIG-bench [paper] [github] [huggingface] | No | Evaluate advanced reasoning capabilities | Model performance and calibration |
| DROP [paper] [github] [huggingface] | No | Evaluate discrete reasoning over paragraphs | Exact match and F1 score |
| CRASS [paper] [github] | No | Evaluate counterfactual reasoning ability in LLMs | Multiple-choice accuracy |
| ARC [paper] [github] [huggingface] | No | Assess science reasoning at grade-school level | Multiple-choice accuracy |
| AGIEval [paper] [github] [huggingface] | No | Evaluate foundation models on human-centric standardized exam tasks | Multi-task accuracy across disciplines |
| M3Exam [paper] [github] | No | Evaluate multilingual, multimodal, and multilevel reasoning across real exam questions | Multiple-choice accuracy |
| SCIBENCH [paper] [github] | No | Evaluate college-level scientific problem-solving in math, physics, and chemistry | Open-ended accuracy and skill-specific error attribution |
| Vicuna Evaluation [paper] [github] | No | Evaluate instruction-following quality in chat settings | Human / GPT-4 preference comparison accuracy |
| MT-Bench [paper] [github] | No | Evaluate multi-turn conversational and instruction-following capabilities | Win-rate judged by GPT-4 |
| AlpacaEval [paper] [github] | No | Evaluate instruction-following via LLM-based auto-annotation | Length-controlled win-rate correlated with human preference |
| Chatbot Arena [github] | No | Evaluate LLMs via human-voted battles using Elo rating | Elo score and head-to-head win rate |
| PandaLM [paper] [github] | No | Evaluate instruction-following quality and hyperparameter impact | Win-rate judged by PandaLM |
| HellaSwag [paper] [github] [huggingface] | No | Evaluate commonsense inference | Multiple-choice accuracy |
| TruthfulQA [paper] [github] [huggingface] | No | Evaluate LLM truthfulness and avoidance of imitative falsehoods | Truthfulness rate and MC accuracy |
| ScienceQA [paper] [github] [huggingface] | No | Evaluate multimodal scientific reasoning and explanation generation | Multiple-choice accuracy and explanation quality |
| Chain-of-Thought Hub [paper] [github] | No | Evaluate LLMs’ multi-step reasoning with CoT prompting | Few-shot CoT accuracy |
| NeuLR [paper] [github] | No | Evaluate deductive, inductive, and abductive reasoning | Multi-dimensional accuracy |
| ALCUNA [paper] [github] | No | Evaluate comprehension & reasoning over novel knowledge | Accuracy on 84 351 queries |
| LMExamQA [paper] [github] | No | Evaluate knowledge recall, understanding, and analysis | Accuracy on 10 090 questions |
| SocKET [paper] [github] | No | Evaluate LLMs’ sociability & social knowledge | Accuracy and other metrics |
| Choice-75 [paper] | No | Evaluate decision reasoning in scripted scenarios | Accuracy on binary multiple-choice questions |
| HELM [paper] [github] | No | Evaluate LMs via multi-metric scenarios | Composite normalized performance |
| OpenLLM [github] | No | Evaluate open-style reasoning across multiple benchmarks | Normalized accuracy aggregate |
| BOSS [paper] [github] | No | Evaluate OOD robustness across NLP tasks | OOD accuracy drop & ID–OOD correlation |
| GLUE-X [github] | No | Evaluate OOD robustness | Average OOD accuracy drop |
| PromptBench [paper] [github] | No | Evaluate robustness / prompt-engineering | Adversarial success & robustness |
| DynaBench [paper] [github] | No | Evaluate robustness via dynamic human-in-loop data | Error rate on human-crafted challenges |
| KoLA [paper] [github] | No | Evaluate world knowledge across 19 evolving tasks | Self-contrast calibration |
| CELLO [paper] [github] | No | Evaluate following complex real-world instructions | Multi-criteria compliance rate |
| LLMEval [github] | No | Meta-evaluate LLM evaluators | Meta-evaluator accuracy |
| Xiezhi [paper] [github] | No | Evaluate holistic domain knowledge (516 disciplines) | MRR |
| C-Eval [paper] [github] | No | Evaluate Chinese domain knowledge & reasoning | Multiple-choice accuracy |
| BELLE-eval [github] | No | Evaluate Chinese instruction-following & multi-skill | GPT-4 win-rate & per-task scores |
| SuperCLUE [github] | No | Evaluate Chinese instruction-following with alignment | GPT-4 win-rate & Elo |
| M3KE [paper] [github] | No | Evaluate Chinese LLM knowledge (71 disciplines) | Zero-/few-shot multitask accuracy |
| BayLing-80 [github] | No | Evaluate cross-lingual & conversational capabilities | GPT-4 adjudicated win-rate |
| MMCU [paper] [github] [huggingface] | No | Evaluate multitask Chinese understanding | Multitask accuracy |
| C-CLUE [github] | No | Evaluate classical Chinese NER & RE | Weighted F1 |
| LongBench [paper] [github] [huggingface] | Yes | Evaluate bilingual long-context understanding | Accuracy & generation quality |
| L-Eval [paper] [github] | Yes | Evaluate long-context reasoning up to 60 K tokens | Multi-metric assessment |
| InfinityBench [paper] [github] | Yes | Evaluate contexts beyond 100 K tokens | Accuracy & task-specific metrics |
| Marathon [paper] [github] | Yes | Evaluate long-context reasoning across domains | EM / F1 / ROUGE-L / accuracy |
| LongEval [paper] [github] | Yes | Evaluate effectiveness in long-context retrieval | Retrieval accuracy |
| BABILong [paper] [github] | Yes | Evaluate long-context reasoning in haystack settings | Accuracy |
| DetectiveQA [paper] [github] | Yes | Evaluate narrative reasoning via detective novels | Instruction-following accuracy |
| NoCha [paper] [github] | Yes | Evaluate narrative comprehension & coreference | Exact match & accuracy |
| Loong [paper] [github] | Yes | Evaluate multi-document reasoning & QA | Answer accuracy & doc coverage |
| TCELongBench [paper] [github] | Yes | Evaluate temporal reasoning over long event narratives | Temporal ordering & QA accuracy |
| DENIAHL [paper] [github] | Yes | Evaluate in-context feature influence on NIAH | Retrieval & reasoning accuracy |
| LongMemEval [paper] | Yes | Benchmark memory retention in dialogue | Memory retention & utilization |
| Long2RAG [paper] | Yes | Evaluate long-form generation & retrieval grounding | Key-point recall & factuality |
| L-CiteEval [paper] [github] | Yes | Evaluate citation usage & contextual evidence | Citation recall & faithfulness |
| LIFBENCH [paper] [github] | Yes | Evaluate instruction-following performance & stability | Accuracy & response stability |
| LongReason [paper] | Yes | Evaluate synthetic long-context reasoning | Instruction-following accuracy |
| BAMBOO [paper] [github] | Yes | Evaluate long-text modeling across tasks | Accuracy & win-rate |
| ETHIC [paper] | Yes | Evaluate instruction-following on high-info long tasks | EM / F1 & consistency |
| LooGLE [paper] [github] | Yes | Evaluate understanding & reasoning over 20 K-word inputs | Accuracy |
| HELMET [paper] [github] | Yes | Evaluate retrieval, reasoning, summarization, long-context | Task-specific automatic & human metrics |
| HoloBench [paper] | Yes | Evaluate holistic reasoning over DB-style inputs | Execution accuracy & consistency |
| LOFT [paper] | Yes | Evaluate replacing RAG with long-context LLMs | EM / F1 / SQL accuracy |
| Lv-Eval [paper] [github] | Yes | Evaluate comprehension across length levels ≤ 256 K | Exact match & factuality |
| ManyICLBench [paper] | Yes | Evaluate many-shot ICL under long contexts | Average accuracy |
| ZeroSCROLLS [paper] | Yes | Evaluate zero-shot inference on diverse long-text tasks | Accuracy |
| LongICLBench [paper] | Yes | Evaluate ICL under extended input lengths | Win-rate judged by PandaLM |
| LIBRA [paper] [github] | Yes | Evaluate long-context understanding in Russian | Accuracy, BLEU, faithfulness |
Domain: Finance
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| FinBen [paper] [github] [huggingface] | No | Evaluate holistic financial capabilities across 24 tasks | Automatic metrics, agent/RAG performance, and human expert assessment |
| PIXIU [paper] [github] [huggingface] | No | Evaluate LLMs across multiple financial NLP tasks | Sentiment accuracy, QA accuracy, stock prediction F1 |
| FLUE [paper] [github] [huggingface] | No | Evaluate diverse financial NLP competencies | Accuracy, F1, nDCG |
| BBF-CFLEB [paper] [github] | No | Evaluate LLMs on Chinese financial language understanding and generation across six task types | Rouge, F1, and accuracy |
| CFinBench [paper] [github] | No | Evaluate Chinese financial knowledge across subjects, certifications, practice, and legal compliance | Accuracy across single-choice, multiple-choice, and judgment questions |
| SuperCLUEFin [paper] | No | Evaluate Chinese financial assistant capabilities | Win-rate and multi-criteria performance |
| ICE-PIXIU [paper] [github] | No | Evaluate bilingual (Chinese–English) financial reasoning and analysis capabilities | Task-specific accuracy and bilingual win-rate |
| FLARE-ES [paper] | No | Evaluate bilingual Spanish–English financial reasoning | Task-specific accuracy and cross-lingual transfer win-rate |
| FinanceBench [paper] [github] | No | Evaluate financial open-book QA using real-world company-related questions | Factual correctness and evidence alignment |
| FiNER-ORD [paper] [github] [huggingface] | No | Evaluate financial NER capability in financial texts | Entity F1 |
| FinRED [paper] [github] [huggingface] | No | Evaluate financial relation extraction performance on news and earnings transcripts | F1, Entity F1 |
| FinQA [paper] [github] [huggingface] | No | Evaluate multi-step numerical reasoning over financial reports with structured evidence | EM Accuracy |
| BizBench [paper] [huggingface] | No | Evaluate quantitative reasoning on realistic financial problems | Numeric EM, code execution pass rate, QA accuracy |
| EconLogicQA [paper] [huggingface] | No | Evaluate economic sequential reasoning across multi-event scenarios | Multiple-choice accuracy |
| FinEval [github] | No | Evaluate Chinese financial domain knowledge and reasoning | Multiple-choice accuracy and task-level weighted scores |
| CFBenchmark [paper] [github] | No | Evaluate Chinese financial assistant capabilities | Win-rate and task-specific metrics |
| BBT-Fin [paper] [github] | No | Evaluate Chinese financial language understanding and generation | Accuracy, F1, ROUGE |
| Hirano [paper] [github] | No | Evaluate Japanese financial language understanding | Multiple-choice accuracy and macro-F1 scores |
| MultiFin [paper] [github] [huggingface] | No | Evaluate multilingual financial topic classification | F1, Multi-class accuracy |
| DocFinQA [paper] [huggingface] | Yes | Evaluate long-context financial reasoning over documents like financial reports | EM and F1 for multi-step answer prediction, and reasoning accuracy |
| FinTextQA [huggingface] | Yes | Evaluate long-form financial question answering with long textual context | Answer accuracy, BLEU, and ROUGE |
Domain: Medicine
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| CBLUE [paper] [github] | No | Evaluate Chinese biomedical language understanding across multiple clinical and QA tasks | Accuracy, F1-score, and macro-average metrics across subtasks |
| PromptCBLUE [paper] [github] [huggingface] | No | Evaluate LLMs on prompt-based generation across 16 Chinese medical NLP tasks | Accuracy, BLEU, and ROUGE scores |
| CMB [paper] [github] [huggingface] | No | Evaluate comprehensive Chinese medical knowledge via exam-style QA and clinical diagnosis | Accuracy, expert grading, and model-based evaluation |
| HuaTuo26M-test [paper] [github] [huggingface] | No | Evaluate Chinese medical knowledge and QA ability using real-world clinical queries | Accuracy and relevance |
| CMExam [paper] [github] [huggingface] | No | Evaluate LLMs on Chinese medical licensing exam QA with fine-grained annotations | Accuracy, weighted F1, and expert-judged reasoning quality |
| MultiMedQA [paper] | No | Evaluate LLMs’ clinical knowledge via multiple-choice and open-ended medical QA tasks | Expert-rated helpfulness, factuality, and safety |
| QiZhenGPT eval [github] | No | Evaluate LLMs' ability to identify drug indications from natural-language prompts | Expert-annotated correctness score |
| MedExQA [paper] [github] | No | Evaluate medical knowledge and explanation generation across under-represented specialties | Explanation quality and expert-aligned relevance |
| JAMA and Medbullets [paper] [github] | No | Evaluate LLMs' ability to answer and explain challenging clinical questions | Answer accuracy, explanation quality, and human-aligned reasoning assessment |
| MedXpertQA [paper] [github] [huggingface] | No | Evaluate expert-level medical reasoning and multimodal clinical understanding | Answer accuracy, image-text reasoning, and expert-aligned scoring |
| MedJourney [paper] | No | Evaluate LLM performance across full clinical patient journey stages and tasks | Task-specific automatic metrics and human expert evaluations |
| MedAgentsBench [paper] [github] | No | Evaluate complex multi-step clinical reasoning including diagnosis and treatment planning | Multi-aspect evaluation: correctness, efficiency, human expert ratings |
| LongHealth [paper] [github] | Yes | Evaluate question answering over long-form clinical documents | EM, F1, and long-context QA accuracy |
| MedOdyssey [paper] [github] | Yes | Evaluate long-context understanding in the medical domain (up to 200 K tokens) | Task-specific EM, ROUGE, and human preference scoring |
Domain: Code
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| HumanEval [paper] [github] [huggingface] | No | Evaluate code generation, algorithmic reasoning, and language understanding with functional correctness | Test-case execution accuracy (pass@k) |
| MBPP [paper] [github] [huggingface] | No | Evaluate basic Python code generation on crowdsourced programming tasks | Functional correctness via pass@k using automated test cases |
| APPS [paper] [github] [huggingface] | No | Evaluate coding-challenge competence through real-world programming problems | Pass@k and exact match for functional correctness |
| DS-1000 [paper] [github] [huggingface] | No | Evaluate data-science code generation across real queries from 7 Python libraries | Functional correctness via automated test-based execution accuracy |
| CodeXGLUE [paper] [github] | No | Evaluate code understanding and generation across 9 tasks in 4 I/O types | BLEU, EM, F1, Accuracy, MAP (task-specific) |
| CruxEval [paper] [github] | No | Evaluate code reasoning, understanding, and execution | pass@1 accuracy |
| ODEX [paper] [github] [huggingface] | No | Evaluate cross-lingual code generation from NL queries in four languages | Execution-based functional correctness |
| MTPB [paper] [github] | No | Evaluate multi-turn program synthesis | Functional correctness via pass@k on step-wise sub-programs |
| ClassEval [paper] [github] [huggingface] | No | Evaluate class-level code generation from NL descriptions (Python) | pass@1, class completeness, dependency consistency |
| BigCodeBench [paper] [github] [huggingface] | No | Evaluate LLMs’ ability to follow complex instructions and invoke diverse function calls | Pass@k, test-case execution accuracy, branch coverage |
| HumanEvalPack [github] [huggingface] | No | Evaluate multilingual code generation, correction, and comment synthesis across six languages | Functional correctness via pass@k and task-specific metrics |
| BIRD [pape] [github] | No | Evaluate database-grounded text-to-SQL generation over large, noisy databases | Execution accuracy and exact match |
| RepoQA [github] | Yes | Evaluate long-context code understanding in real software repositories | Exact-match accuracy and retrieval-augmented correctness |
| LongCodeArena [paper] [github] [huggingface] | Yes | Evaluate long-context code comprehension, generation, and editing across project-wide tasks | Task-specific accuracy, exact match, and human evaluation |
Domain: Math
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| GSM8K [paper] [github] [huggingface] | No | Assess grade school math reasoning | Exact match accuracy |
| MATH [paper] [github] [huggingface] | No | Evaluate competition-level math problem-solving with step-by-step reasoning | Final answer accuracy & derivation correctness |
| MathOdyssey [paper] [github] [huggingface] | No | Benchmark high-school → Olympiad → university math across difficulty tiers | Answer accuracy across difficulty levels |
| MathBench [paper] [github] | No | Evaluate theoretical & applied math knowledge across five levels | Accuracy on theoretical and application problems |
| CHAMP [paper] [github] | No | Fine-grained competition-level reasoning with concept/hint annotations | Answer accuracy & reasoning-path correctness |
| LILA [paper] [github] [huggingface] | No | Unified benchmark across 23 math tasks & formats | Accuracy across tasks |
| MiniF2F-v1 [paper] [github] | No | Formal theorem-proving at Olympiad level | Proof accuracy on 488 problems |
| ProofNet [paper] [github] [huggingface] | No | Auto-formalization & formal proof generation (Lean 3) | Formalization accuracy & proof success rate |
| AlphaGeometry [paper] [github] | No | Neuro-symbolic reasoning on Olympiad Euclidean geometry | Proof success, correctness, completeness, readability |
| MathVerse [paper] [github] [huggingface] | No | Visual-diagram math reasoning for MLLMs | Diagram-sensitive answer accuracy & CoT score |
| We-Math [paper] [github] [huggingface] | No | Human-like visual mathematical reasoning with knowledge hierarchy | Four-dimensional diagnostic metrics |
| U-MATH [paper] [github] | No | Open-ended university-level problem-solving (20 % multimodal) | LLM-judged solution correctness (expert-verified F1) |
| TabMWP [paper] [github] | No | Math reasoning over textual + tabular data | Accuracy on QA & MC questions |
| MathHay [paper] [github] | Yes | Long-context mathematical reasoning with multi-step dependencies | Accuracy, exact match, reasoning-chain consistency |
Domain: Law
| Benchmark | Long-context or not | Evaluation Objective | Main Evaluation Criteria |
|---|---|---|---|
| LegalBench [paper] [github] [huggingface] | No | Evaluate legal reasoning across six types including rule application and interpretation | Task-specific accuracy, rule-consistency, LLM-as-a-judge ratings |
| LexGLUE [paper] [github] [huggingface] | No | Evaluate legal language understanding across classification and QA tasks | Task-specific accuracy & F1 |
| LEXTREME [paper] [github] [huggingface] | No | Evaluate multilingual & multitask legal understanding (24 languages, 18 tasks) | Macro-F1, accuracy, other classification metrics |
| LawBench [paper] [github] | No | Evaluate Chinese legal LLMs across retention, understanding & application (20 tasks) | Task-specific accuracy & F1 |
| LAiW [paper] [github] | No | Evaluate Chinese legal LLMs across fundamental → advanced tasks (13 assignments) | Task-specific accuracy & F1 |
| LexEval [paper] [github] [huggingface] | No | Evaluate Chinese legal reasoning via a taxonomy of cognitive abilities | Task-specific accuracy |
| CitaLaw [paper] | No | Evaluate citation-grounded legal answering with statutes & precedents | Syllogism-alignment, citation accuracy, legal consistency |
| LegalAgentBench [paper] [github] | No | Evaluate LLM agents solving complex real-world legal tasks | Task success rate & intermediate progress |
| SCALE [paper] [github] | Yes | Evaluate long-doc, multilingual, multitask legal reasoning (≤ 50 K tokens) | Accuracy, F1, code-based assessment for long-context legal tasks |
⭐ Citation
If you find this work useful, welcome to cite us.
@misc{wu2025surveyfederatedfinetuninglarge,
      title={A Survey on Federated Fine-tuning of Large Language Models},
      author={Yebo Wu and Chunlin Tian and Jingguang Li and He Sun and Kahou Tam and Zhanting Zhou and Haicheng Liao and Zhijiang Guo and Li Li and Chengzhong Xu},
      year={2025},
      eprint={2503.12016},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2503.12016},
}
Similar repos
Contributors
Clin0212
4 commits