
Seeing from Another Perspective: Evaluating Multi-View Understanding in MLLMs
Python
71
48 commits
updated Mar 22, 2026
README
 Seeing from Another Perspective: Evaluating Multi-View Understanding in MLLMs (AAAI 2026)
Chun-Hsiao Yeh*, Chenyu Wang*, Shengbang Tong, Ta-Ying Cheng, Ruoyu Wang, Tianzhe Chu, Yuexiang Zhai, Yubei Chen, Shenghua Gao, and Yi Ma
UC Berkeley, TranscEngram, NYU, University of Oxford, UC Davis, LSAI, and HKU
(*Equal Contribution)


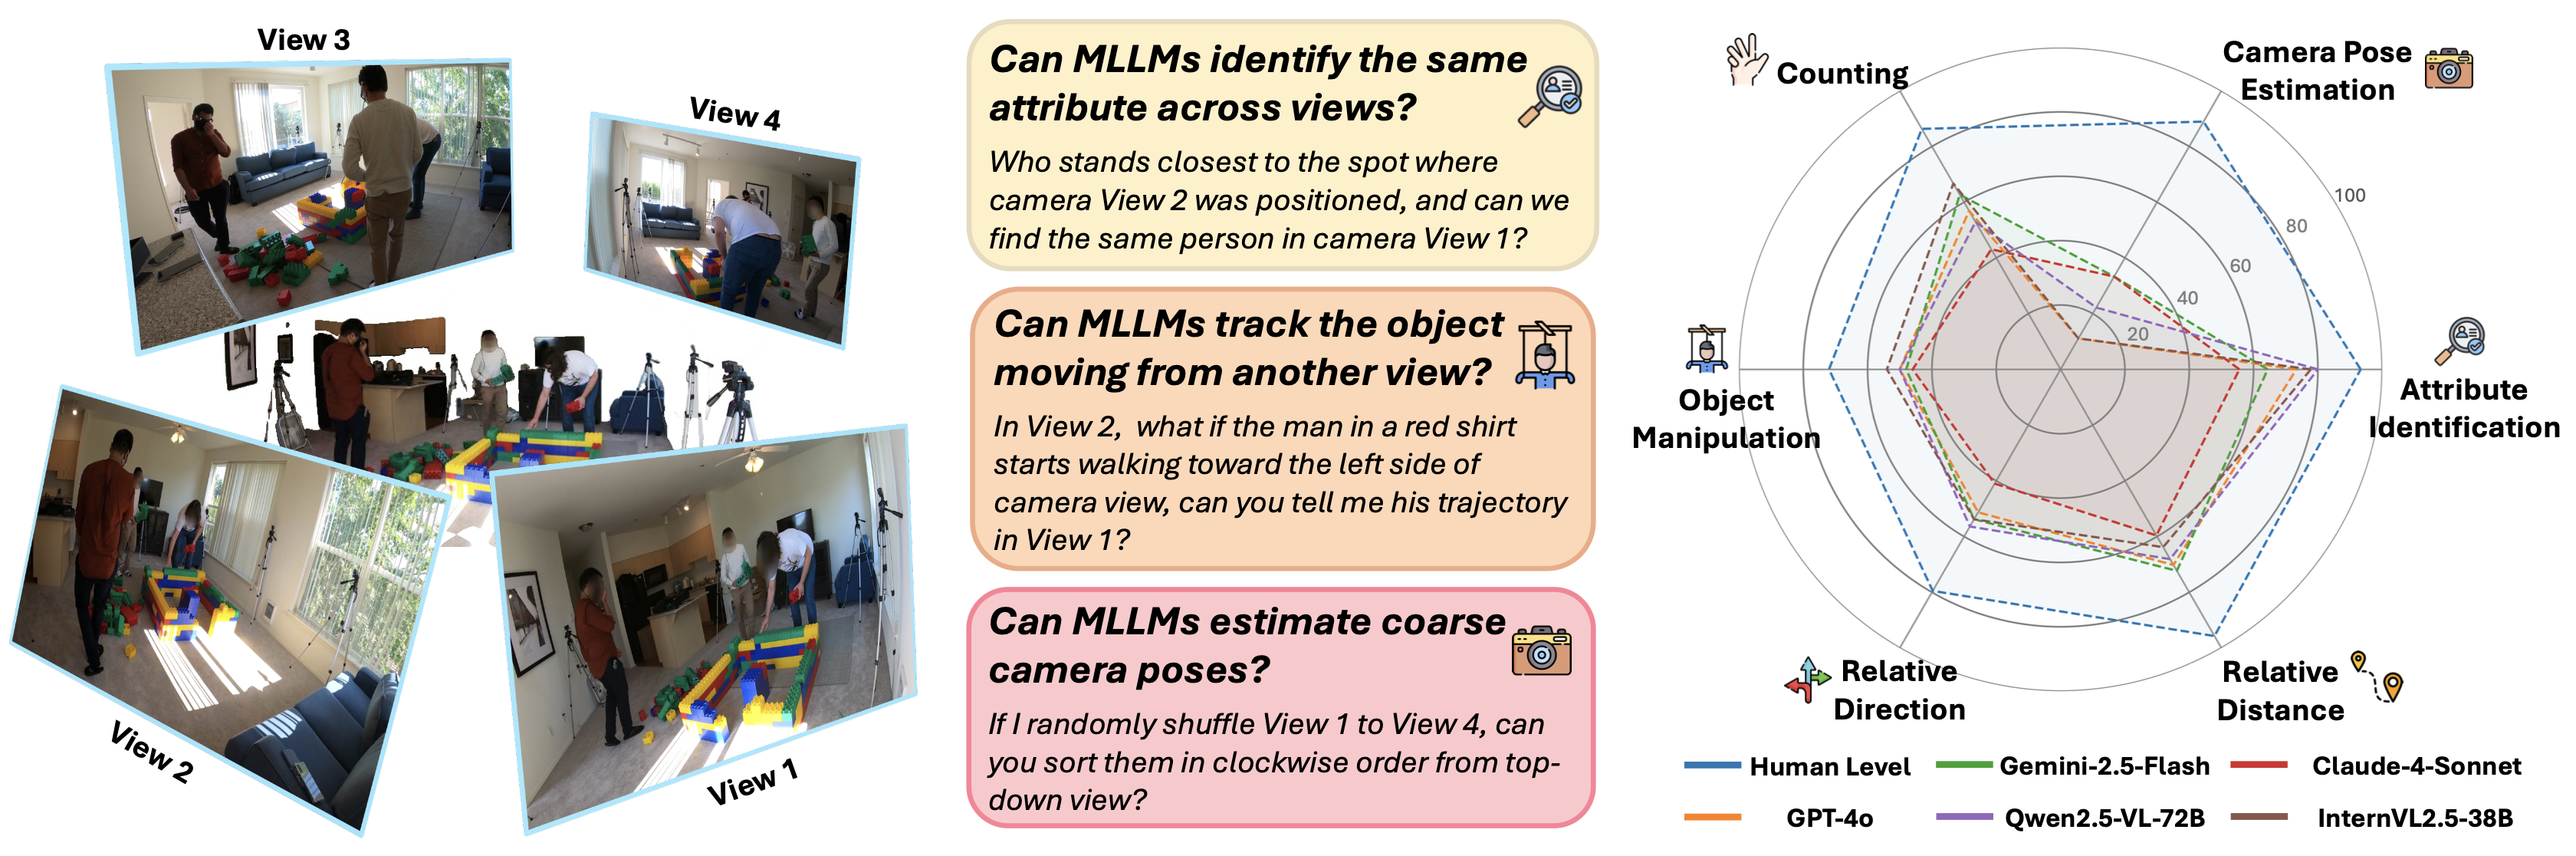
📌 A Benchmark for Multi-View Understanding: We present All-Angles Bench, a comprehensive benchmark featuring over 2,100 human-annotated multi-view QA pairs across 90 real-world scenes.
📊 Performance Evaluation: We evaluate 27 state-of-the-art MLLMs, including Gemini-2.5-Flash, Claude-4-Sonnet, and GPT-4o. Our findings highlight a significant performance gap between MLLMs and human-level understanding.
🔍 Decoding MLLM Shortcomings: We pinpoint two primary failure modes in MLLMs: (1) inadequate cross-view correspondence in the presence of occlusions and (2) inaccurate estimation of rough camera poses.
🎉 News
- [2025.11] 🔥🔥 All-Angles Bench is accepted to AAAI 2026!
- [2025.05] 🔥🔥🔥 Release the Evaluation Code on All-Angles Bench
- [2025.04] 📢📢📢 Release the All-Angles Benchmark on HuggingFace 🤗
- [2025.04] 📢📢📢 Release arXiv paper and init project
To Do List
- [NEW] Release Evaluation Code
- Release the process scripts of the part of All-Angles Benchmark sourced from Ego-Exo4D Dataset
- Release the part of All-Angles Benchmark sourced from EgoHumans Dataset
- Release Project Page & Technical Report
All-Angles Bench
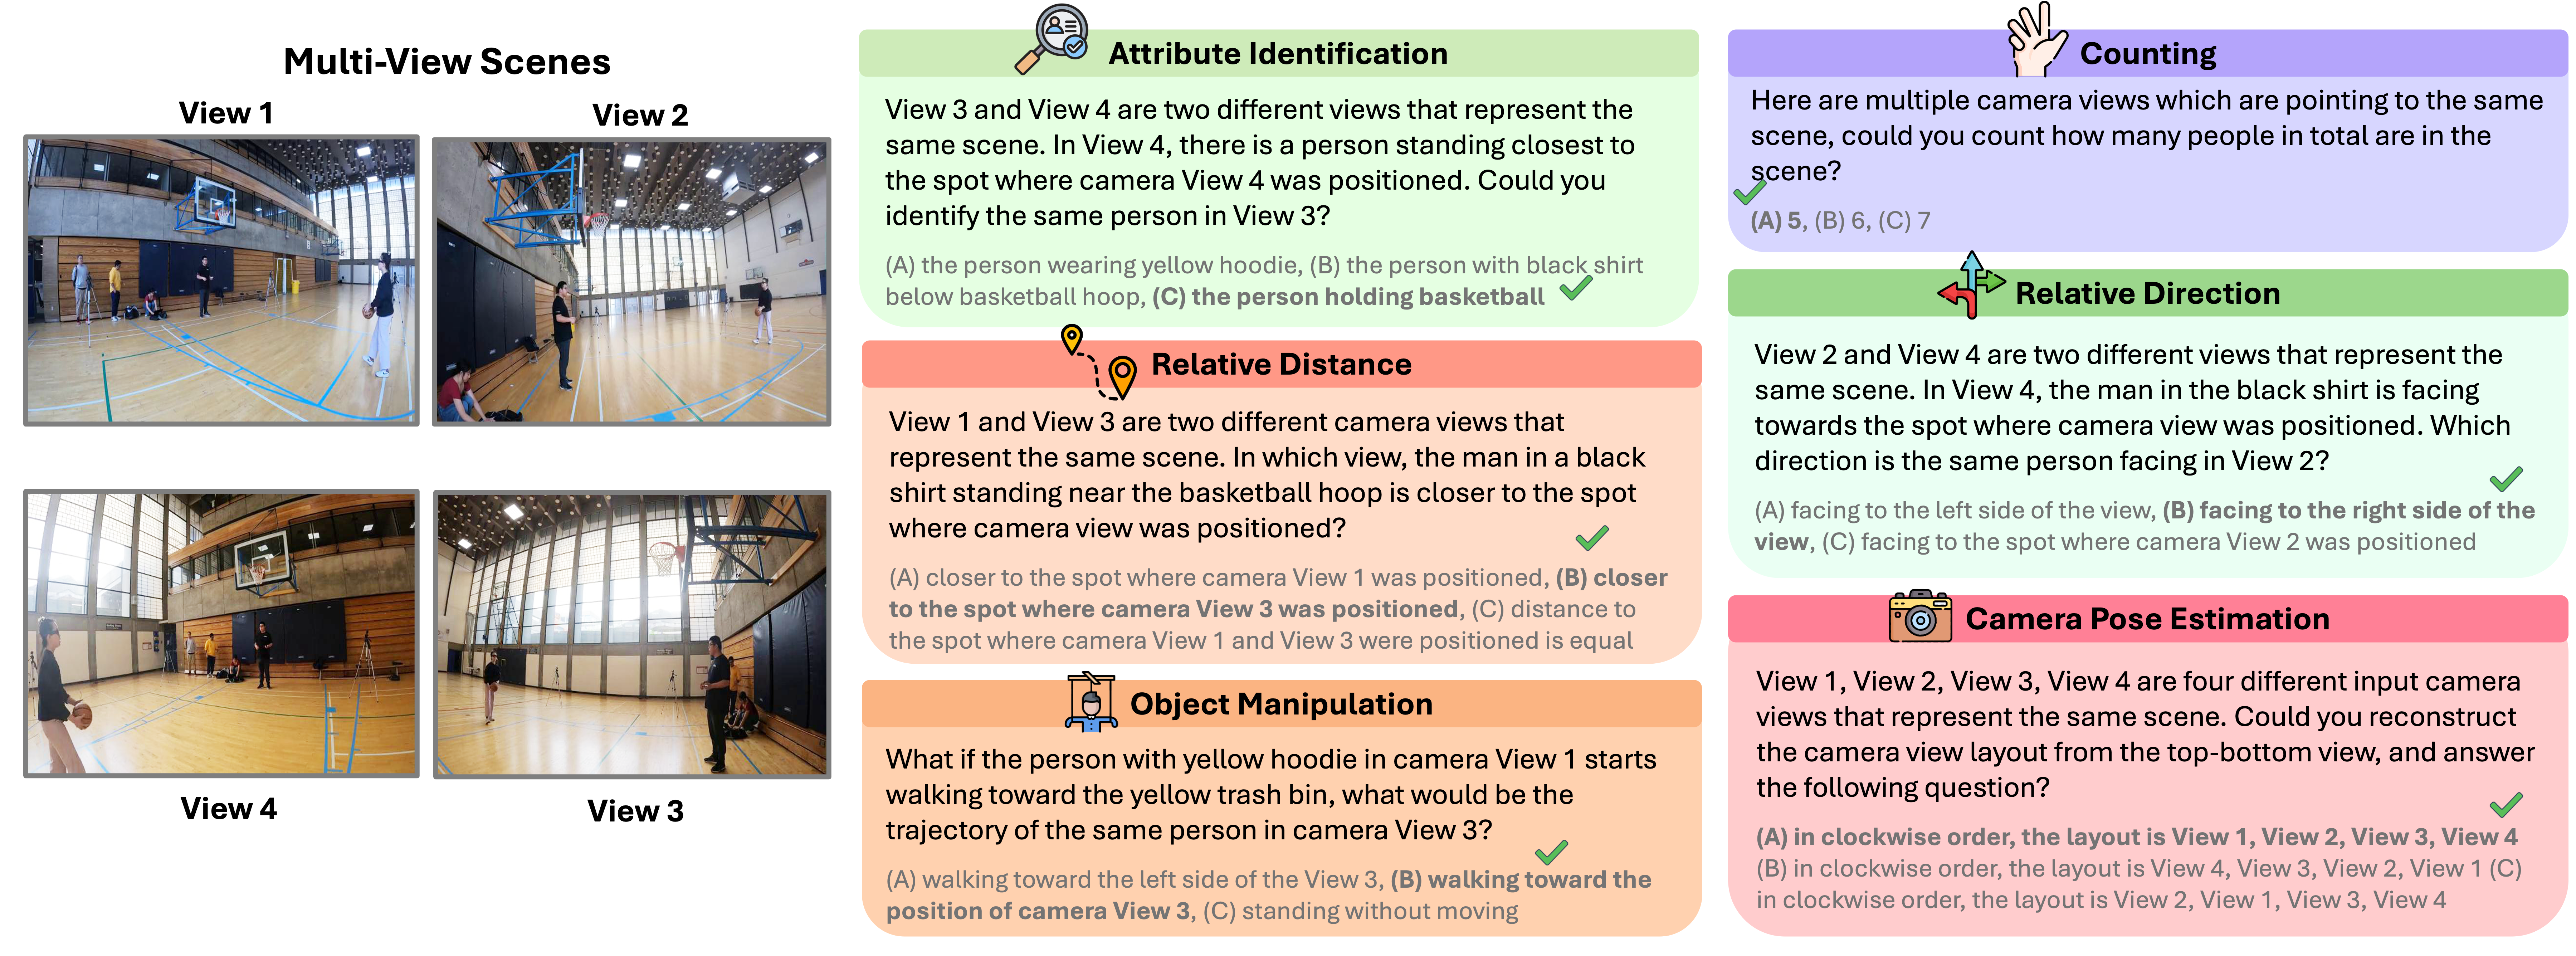
Benchmark Overview: We introduce All-Angles Bench, a benchmark designed to evaluate the multi-view reasoning capabilities of MLLMs, containing 2,132 question-answer pairs carefully annotated across 90 diverse real-world scenes sourced from EGO4D-EXO and EgoHumans. All-Angles Bench comprises six challenging tasks including counting, attribute identification, relative distance, relative direction, manipulation, and camera pose estimation.These question types are designed to investigate several major aspects of 3D scene understanding, from creating correspondence between objects to associating relative object and camera poses.
🏆 Evaluation on All-Angles Bench:
You can evaluate our All-Angles Bench using our extended VLMEvalKit platform. Full setup instructions and evaluation scripts are provided in our repository.
Contact
For any questions or feedback, feel free to contact Chun-Hsiao Yeh and Chenyu Wang.
🌟 Citation
If you find All-Angles Bench useful in your research tasks or applications, please consider to give star🌟 and kindly cite:
@inproceedings{yeh2026seeing,
  title={Seeing from another perspective: Evaluating multi-view understanding in mllms},
  author={Yeh, Chun-Hsiao and Wang, Chenyu and Tong, Shengbang and Cheng, Ta-Ying and Wang, Ruoyu and Chu, Tianzhe and Zhai, Yuexiang and Chen, Yubei and Gao, Shenghua and Ma, Yi},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={40},
  number={14},
  pages={12000--12008},
  year={2026}
}
Acknowledgements
You may refer to related works that serve as foundations for our database and code repository, EgoHumans, Ego-Exo4D, VLMEvalKit. Thanks for their wonderful work and data.
License Notices
This repository is under MIT License. All-Angles Bench is a research project intended for non-commercial use only. One must NOT use the code of All-Angles Bench for any illegal, harmful, violent, racist, or sexual purposes. One is strictly prohibited from engaging in any activity that will potentially violate these guidelines. Any potential commercial use of this code should be approved by the authors.
Contributors

40 commits

8 commits
Similar repos


Languages
Python
96.4%
Shell
2.8%
Seeing from Another Perspective: Evaluating Multi-View Understanding in MLLMs
Python
71
48 commits
updated Mar 22, 2026
README
Seeing from Another Perspective: Evaluating Multi-View Understanding in MLLMs (AAAI 2026)
Chun-Hsiao Yeh*, Chenyu Wang*, Shengbang Tong, Ta-Ying Cheng, Ruoyu Wang, Tianzhe Chu, Yuexiang Zhai, Yubei Chen, Shenghua Gao, and Yi Ma
UC Berkeley, TranscEngram, NYU, University of Oxford, UC Davis, LSAI, and HKU
(*Equal Contribution)
📌 A Benchmark for Multi-View Understanding: We present All-Angles Bench, a comprehensive benchmark featuring over 2,100 human-annotated multi-view QA pairs across 90 real-world scenes.
📊 Performance Evaluation: We evaluate 27 state-of-the-art MLLMs, including Gemini-2.5-Flash, Claude-4-Sonnet, and GPT-4o. Our findings highlight a significant performance gap between MLLMs and human-level understanding.
🔍 Decoding MLLM Shortcomings: We pinpoint two primary failure modes in MLLMs: (1) inadequate cross-view correspondence in the presence of occlusions and (2) inaccurate estimation of rough camera poses.
🎉 News
- [2025.11] 🔥🔥 All-Angles Bench is accepted to AAAI 2026!
- [2025.05] 🔥🔥🔥 Release the Evaluation Code on All-Angles Bench
- [2025.04] 📢📢📢 Release the All-Angles Benchmark on HuggingFace 🤗
- [2025.04] 📢📢📢 Release arXiv paper and init project
To Do List
- [NEW] Release Evaluation Code
- Release the process scripts of the part of All-Angles Benchmark sourced from Ego-Exo4D Dataset
- Release the part of All-Angles Benchmark sourced from EgoHumans Dataset
- Release Project Page & Technical Report
All-Angles Bench
Benchmark Overview: We introduce All-Angles Bench, a benchmark designed to evaluate the multi-view reasoning capabilities of MLLMs, containing 2,132 question-answer pairs carefully annotated across 90 diverse real-world scenes sourced from EGO4D-EXO and EgoHumans. All-Angles Bench comprises six challenging tasks including counting, attribute identification, relative distance, relative direction, manipulation, and camera pose estimation.These question types are designed to investigate several major aspects of 3D scene understanding, from creating correspondence between objects to associating relative object and camera poses.
🏆 Evaluation on All-Angles Bench:
You can evaluate our All-Angles Bench using our extended VLMEvalKit platform. Full setup instructions and evaluation scripts are provided in our repository.
Contact
For any questions or feedback, feel free to contact Chun-Hsiao Yeh and Chenyu Wang.
🌟 Citation
If you find All-Angles Bench useful in your research tasks or applications, please consider to give star🌟 and kindly cite:
@inproceedings{yeh2026seeing,
  title={Seeing from another perspective: Evaluating multi-view understanding in mllms},
  author={Yeh, Chun-Hsiao and Wang, Chenyu and Tong, Shengbang and Cheng, Ta-Ying and Wang, Ruoyu and Chu, Tianzhe and Zhai, Yuexiang and Chen, Yubei and Gao, Shenghua and Ma, Yi},
  booktitle={Proceedings of the AAAI Conference on Artificial Intelligence},
  volume={40},
  number={14},
  pages={12000--12008},
  year={2026}
}
Acknowledgements
You may refer to related works that serve as foundations for our database and code repository, EgoHumans, Ego-Exo4D, VLMEvalKit. Thanks for their wonderful work and data.
License Notices
This repository is under MIT License. All-Angles Bench is a research project intended for non-commercial use only. One must NOT use the code of All-Angles Bench for any illegal, harmful, violent, racist, or sexual purposes. One is strictly prohibited from engaging in any activity that will potentially violate these guidelines. Any potential commercial use of this code should be approved by the authors.
Similar repos
Contributors
40 commits
8 commits
Languages
Python
96.4%
Shell
2.8%