
A summary of technical reports for various large language models (LLMs).
Python
39
17 commits
updated Aug 19, 2026
README
📄 LLM Technical Reports
A curated collection of technical reports, system cards, and model cards from major LLM labs — organized by company, with links to official documents.
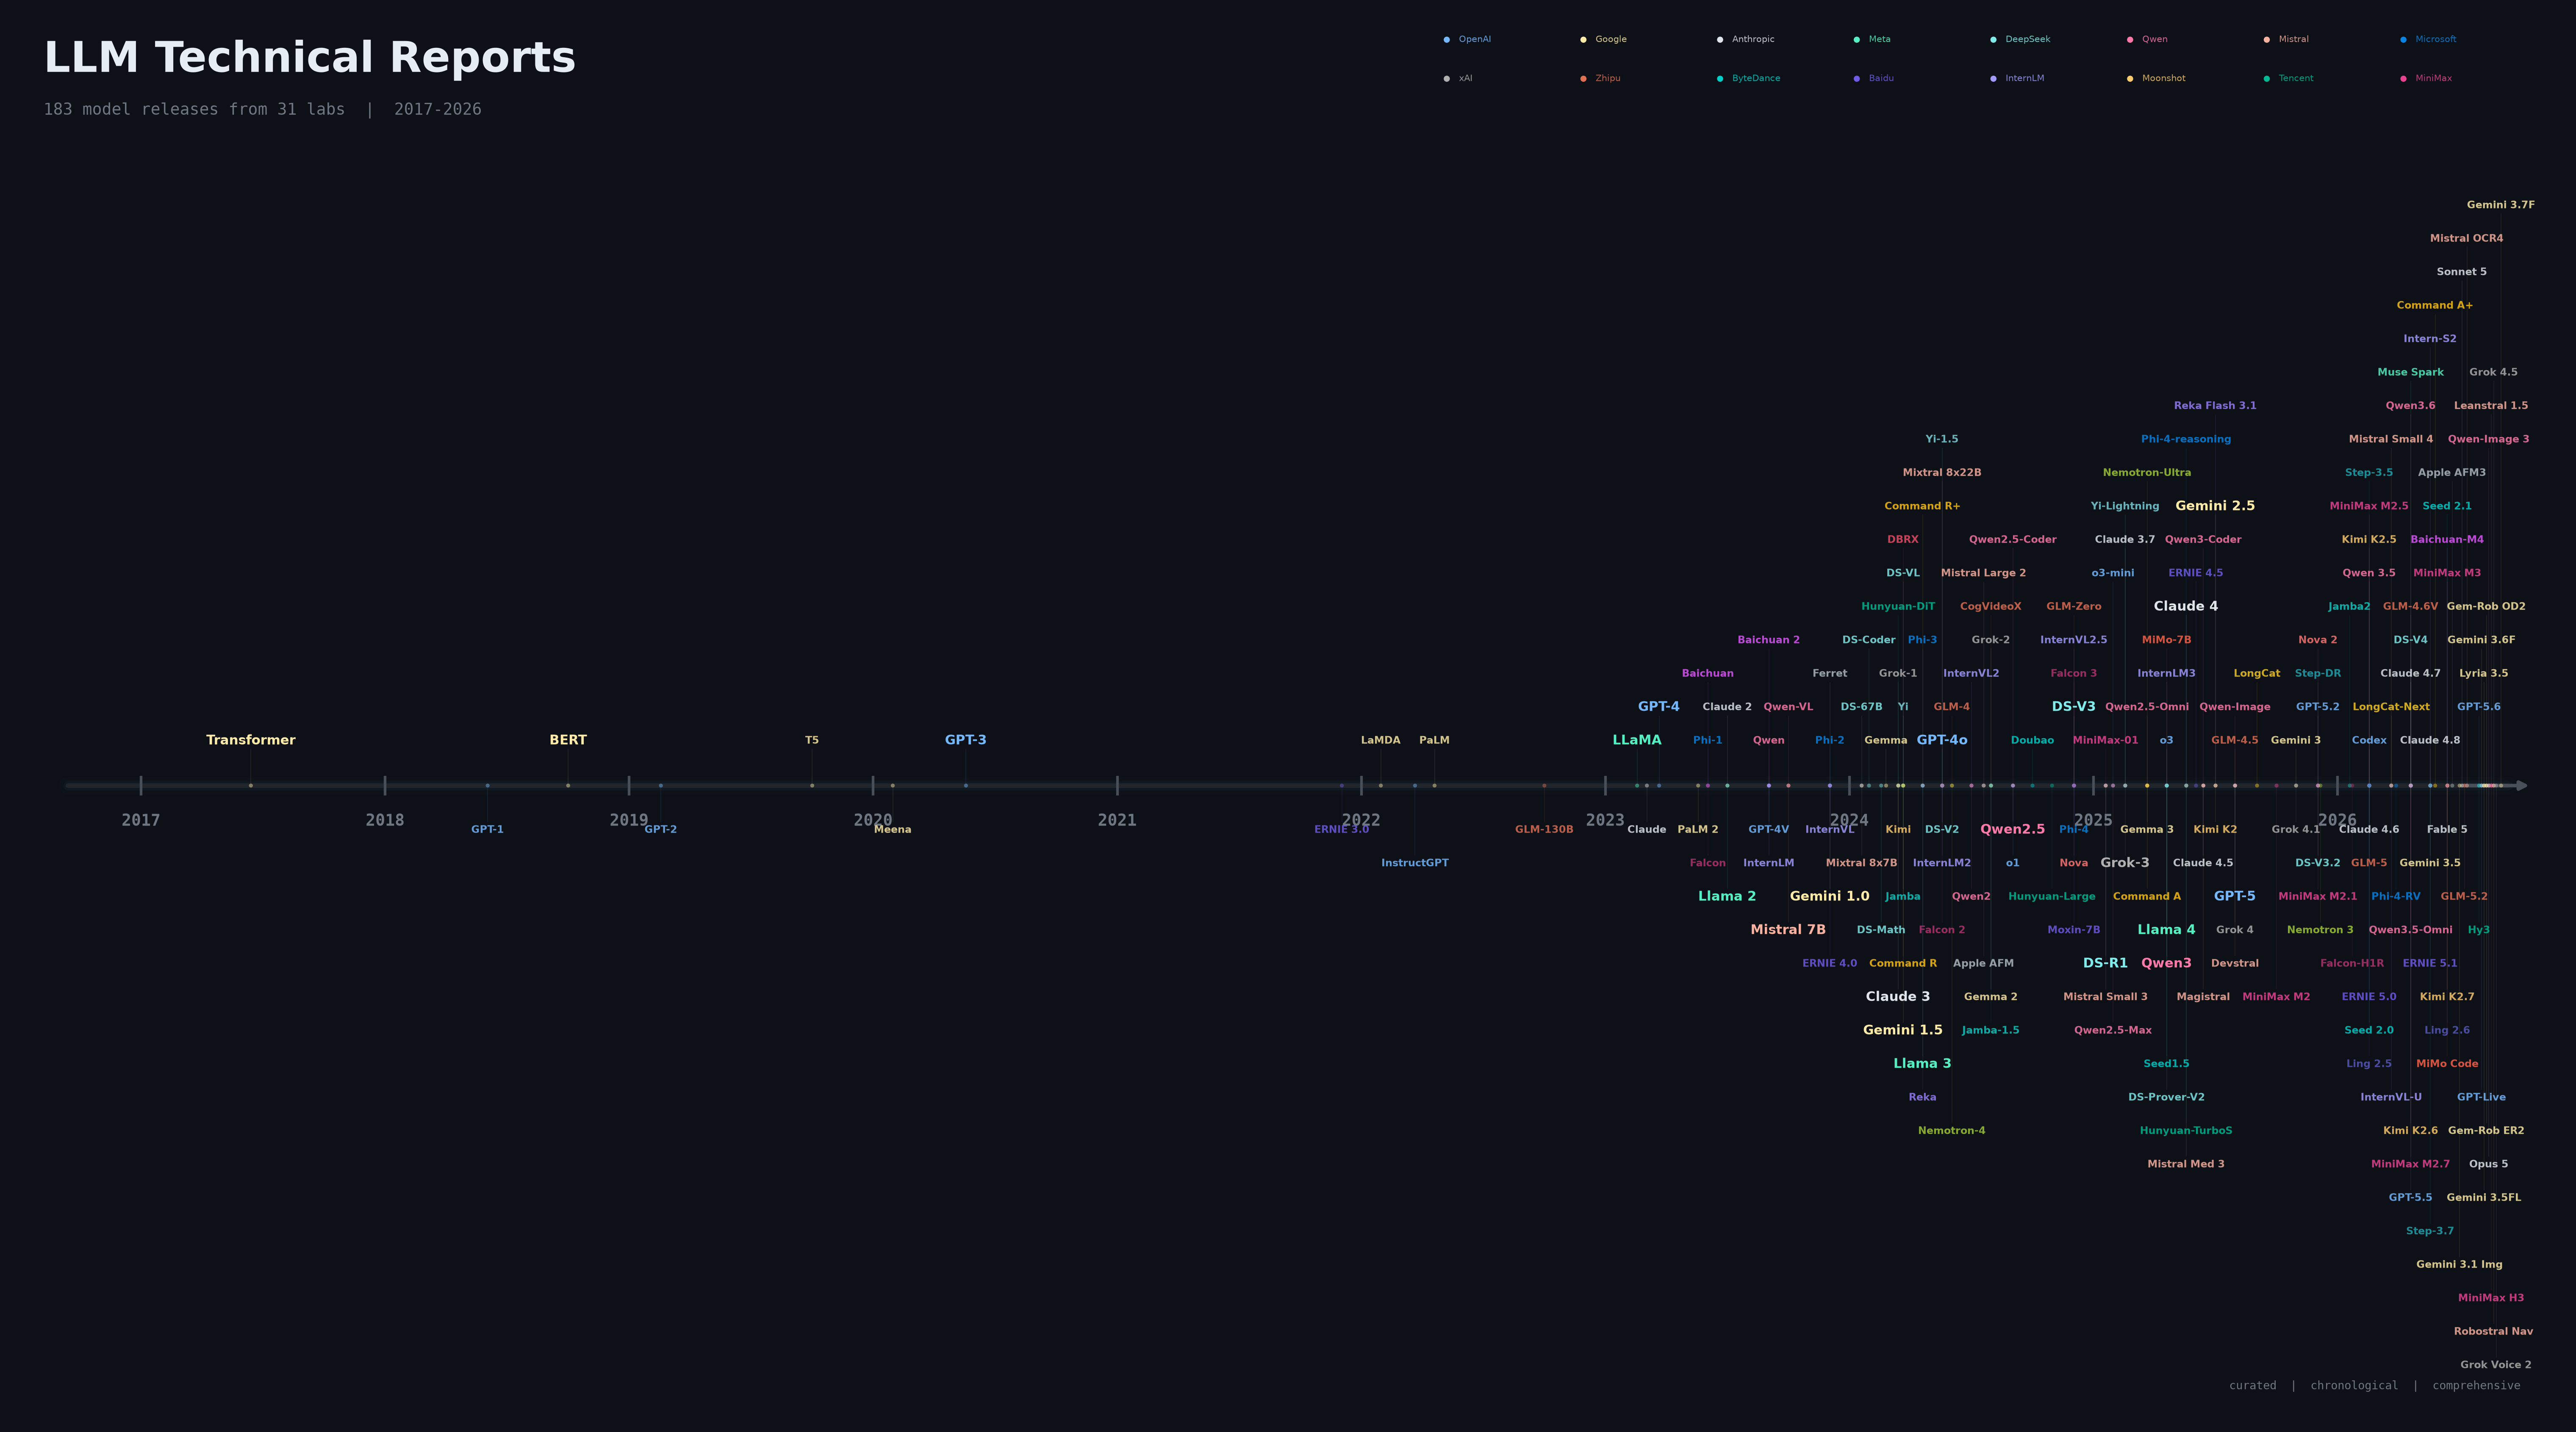


- 🏢 Organized by company — easy to track a lab's model evolution
- 📅 Chronological — each company's reports sorted by release date
- 🌐 Comprehensive — covers both Western and Chinese AI labs
Table of Contents
- OpenAI
- Google / DeepMind
- Anthropic
- Meta
- DeepSeek
- Alibaba / Qwen
- Shanghai AI Lab / InternLM
- ByteDance
- Zhipu AI / GLM
- Moonshot AI / Kimi
- Baidu / ERNIE
- Tencent / Hunyuan
- MiniMax
- Mistral AI
- xAI / Grok
- Microsoft / Phi
- Amazon
- Nvidia
- AI21 Labs
- Databricks
- TII / Falcon
- Reka AI
- Cohere
- Apple
- Baichuan
- 01.AI / Yi
- Meituan
- StepFun
- InclusionAI (Ant Group)
- Xiaomi / MiMo
- Zhijiang Lab / Moxin
OpenAI
Google / DeepMind
Anthropic
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-03 | Claude (Constitutional AI) | Paper | Constitutional AI: Harmlessness from AI Feedback |
| 2023-07 | Claude 2 | Model Card | Claude 2 Model Card |
| 2024-03 | Claude 3 Family | Model Card | The Claude 3 Model Family |
| 2025-02 | Claude 3.7 Sonnet | System Card | Claude 3.7 Sonnet System Card |
| 2025-05 | Claude Opus 4 / Sonnet 4 | System Card | Claude Opus 4 and Sonnet 4 System Card |
| 2025-06 | Claude Opus 4.5 | System Card | Claude Opus 4.5 System Card |
| 2025-06 | Claude Sonnet 4.5 | System Card | Claude Sonnet 4.5 System Card |
| 2026-02 | Claude Opus 4.6 | System Card | Claude Opus 4.6 System Card |
| 2026-04 | Claude Opus 4.7 / Sonnet 4.6 | System Card | Claude Opus 4.7 and Sonnet 4.6 System Card |
| 2026-05 | Claude Opus 4.8 | System Card | Claude Opus 4.8 |
| 2026-06 | Claude Fable 5 / Mythos 5 | System Card | Claude Fable 5 and Mythos 5 |
| 2026-06 | Claude Sonnet 5 | System Card | Claude Sonnet 5 System Card |
| 2026-07 | Claude Opus 5 | System Card | Claude Opus 5 System Card |
Meta
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-02 | LLaMA | Paper | LLaMA: Open and Efficient Foundation Language Models |
| 2023-07 | Llama 2 | Paper | Llama 2: Open Foundation and Fine-Tuned Chat Models |
| 2024-04 | Llama 3.1 | Paper | The Llama 3 Herd of Models |
| 2024-07 | Llama 3 | Paper | The Llama 3 Herd of Models |
| 2025-04 | Llama 4 Scout / Maverick | Blog | Llama 4: Open, Multimodal Intelligence |
| 2025-06 | Llama 4 Behemoth | Blog | Llama 4 Behemoth |
| 2026-04 | Muse Spark | Blog | Introducing Muse Spark |
DeepSeek
Alibaba / Qwen
Shanghai AI Lab / InternLM
ByteDance
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-10 | Doubao/Seed1.0 | Blog | Doubao Model Family |
| 2025-04 | Seed1.5-Thinking | Paper | Seed1.5-Thinking: Advancing Superb Reasoning Models with Reinforcement Learning |
| 2025-05 | Seed1.5-VL | Paper | Seed1.5-VL: Better Vision-Language Understanding with Mixture of Experts |
| 2026-02 | MedXIAOHE | Paper | MedXIAOHE: A Medical Vision-Language Foundation Model |
| 2026-02 | Seed 2.0 | Model Card | Seed 2.0 Model Card |
| 2026-04 | Seeduplex | Blog | Introducing Seed Full-Duplex Speech LLM |
| 2026-04 | Seedance 2.0 | Technical Report | Seedance 2.0: Advancing Video Generation for World Complexity |
| 2026-05 | Seed3D 2.0 | Technical Report | Seed3D 2.0: Advancing High-Fidelity Simulation-Ready 3D Content Generation |
| 2026-05 | Cola DLM | Paper | Continuous Latent Diffusion Language Model |
| 2026-05 | TaskMem | Paper | Task-Focused Memorization for Multimodal Agents |
| 2026-06 | Seed-2.1-Pro-Preview | Blog | Seed-2.1-Preview Model Release on Arena |
Zhipu AI / GLM
| Date | Model | Type | Link |
|---|---|---|---|
| 2022-10 | GLM-130B | Paper | GLM-130B: An Open Bilingual Pre-trained Model |
| 2024-01 | CogVLM | Paper | CogVLM: Visual Expert for Pretrained Language Models |
| 2024-06 | GLM-4 | Paper | ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools |
| 2024-08 | CogVideoX | Paper | CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer |
| 2024-12 | GLM-Zero | Blog | GLM-Zero-Preview |
| 2025-08 | GLM-4.5 | Paper | GLM-4.5: An Open Mixture-of-Experts LLM |
| 2026-02 | GLM-5 | Paper | GLM-5 |
| 2026-04 | GLM-4.6V | Blog | GLM-4.6V |
| 2026-06 | GLM-5.2 | Blog | GLM-5.2: Built for Long-Horizon Tasks |
Moonshot AI / Kimi
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Kimi (Moonshot-v1) | Blog | Kimi — First 200k context length model |
| 2025-07 | Kimi K2.0 | Paper | Kimi K2.0 Technical Report |
| 2026-02 | Kimi K2.5 | Paper | Kimi K2.5 Technical Report |
| 2026-04 | Kimi K2.6 | Blog | Kimi K2.6 |
Baidu / ERNIE
| Date | Model | Type | Link |
|---|---|---|---|
| 2021-12 | ERNIE 3.0 | Paper | ERNIE 3.0: Large-scale Knowledge Enhanced Pre-training for Language Understanding and Generation |
| 2023-12 | ERNIE Bot (3.5/4.0) | Paper | ERNIE Bot: Advanced Language Model |
| 2025-06 | ERNIE 4.5 | Technical Report | ERNIE 4.5 Technical Report |
| 2026-02 | ERNIE 5.0 | Paper | ERNIE 5.0 |
| 2026-05 | ERNIE-Image | Technical Report | ERNIE-Image Technical Report |
| 2026-05 | ERNIE 5.1 | Blog | ERNIE 5.1 Officially Released |
| 2026-06 | PaddleOCR-VL-1.6 | Technical Report | PaddleOCR-VL-1.6 Technical Report |
Tencent / Hunyuan
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Hunyuan-DiT | Paper | Hunyuan-DiT: A Powerful Multi-Resolution Diffusion Transformer with Fine-Grained Chinese Understanding |
| 2024-11 | Hunyuan-Large | Paper | Hunyuan-Large: An Open-Source MoE Model with 52 Billion Activated Parameters |
| 2025-03 | Hunyuan-T1 | Blog | Hunyuan Turbomind T1 |
| 2025-05 | Yuanbao (Hunyuan-TurboS) | Paper | Hunyuan-TurboS: A Hybrid Transformer-Mamba MoE Model |
| 2026-04 | Hy3-preview | GitHub | Hy3-preview |
| 2026-06 | Hy-Embodied-0.5-VLA | GitHub | Hy-Embodied-0.5-VLA |
| 2026-07 | Hy3 | Blog | Tencent Hunyuan Officially Releases Hy3 |
MiniMax
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-01 | MiniMax-01 | Paper | MiniMax-01: Scaling Foundation Models with Lightning Attention |
| 2025-10 | MiniMax M2.0 | Paper | MiniMax M2.0 |
| 2025-12 | MiniMax M2.1 | GitHub | MiniMax M2.1 |
| 2026-02 | MiniMax M2.5 | Blog | MiniMax M2.5 |
| 2026-04 | MiniMax M2.7 | Blog | MiniMax M2.7 |
| 2026-06 | MiniMax M3 | Model Card | MiniMax-M3 |
| 2026-06 | MiniMax Sparse Attention | Paper | MiniMax Sparse Attention |
| 2026-07 | MiniMax H3 | Blog | MiniMax H3: An Open Model Breaking the Boundaries Between Tasks and Modalities |
Mistral AI
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-10 | Mistral 7B | Paper | Mistral 7B |
| 2024-01 | Mixtral 8x7B | Paper | Mixtral of Experts |
| 2024-05 | Mistral 8x22B | Blog | Cheaper, Better, Faster, Stronger |
| 2024-07 | Mistral Large 2 | Blog | Mistral Large 2 |
| 2024-09 | Mistral Pixtral 12B | Blog | Pixtral 12B |
| 2024-11 | Mistral Pixtral Large | Blog | Pixtral Large |
| 2025-01 | Mistral Small 3 | Blog | Mistral Small 3 |
| 2025-02 | Mistral Saba | Blog | Mistral Saba |
| 2025-03 | Mistral Small 3.1 | Blog | Mistral Small 3.1 |
| 2025-05 | Mistral Medium 3 | Blog | Mistral Medium 3 |
| 2025-06 | Magistral | Paper | Magistral |
| 2025-08 | Devstral | Paper | Devstral: Fine-tuning Language Models for Coding Agent Applications |
| 2026-03 | Mistral Small 4 | Blog | Introducing Mistral Small 4 |
| 2026-06 | Mistral OCR 4 | Blog | Introducing Mistral OCR 4 |
| 2026-07 | Leanstral 1.5 | Blog | Leanstral 1.5: Proof Abundance for All |
| 2026-07 | Robostral Navigate | Paper | Robostral Navigate |
xAI / Grok
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Grok-1 | Blog | Open Release of Grok-1 |
| 2024-08 | Grok-2 | Blog | Grok-2 Beta Release |
| 2025-02 | Grok-3 | Blog | Grok 3 |
| 2025-08 | Grok 4 | Model Card | Grok 4 Model Card |
| 2025-11 | Grok 4.1 | Model Card | Grok 4.1 Model Card |
| 2026-07 | Grok 4.5 | Model Card | Grok 4.5 Model Card |
| 2026-07 | Grok Voice Think Fast 2.0 | Blog | Introducing Grok Voice Think Fast 2.0 |
Microsoft / Phi
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-06 | Phi-1 | Paper | Textbooks Are All You Need |
| 2023-12 | Phi-2 | Paper | Phi-2: The surprising power of small language models |
| 2024-04 | Phi-3 | Paper | Phi-3 Technical Report |
| 2024-12 | Phi-4 | Paper | Phi-4 Technical Report |
| 2025-02 | Phi-4-mini | Paper | Phi-4-mini Technical Report |
| 2025-05 | Phi-4-reasoning | Paper | Phi-4-reasoning Technical Report |
| 2025-06 | Phi-4-multimodal | Paper | Phi-4-multimodal Technical Report |
| 2026-03 | Phi-4-reasoning-vision-15B | Paper | Phi-4-reasoning-vision-15B Technical Report |
Amazon
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-12 | Nova (Micro/Lite/Pro) | Blog | Introducing Amazon Nova Foundation Models |
| 2025-06 | Nova Family | Paper | The Amazon Nova Family of Models: Technical Report and Model Card |
| 2025-12 | Amazon Nova 2 | Technical Report | Amazon Nova 2: Multimodal Reasoning and Generation Models |
Nvidia
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-06 | Nemotron-4 340B | Paper | Nemotron-4 340B Technical Report |
| 2024-10 | Llama-3.1-Nemotron-70B | Model Card | Llama-3.1-Nemotron-70B-Instruct |
| 2025-03 | Llama-3.1-Nemotron-Ultra-253B | Paper | Llama-Nemotron: An Open Reasoning Model Family |
| 2025-12 | NVIDIA Nemotron 3 | Paper | NVIDIA Nemotron 3: Efficient and Open Intelligence |
AI21 Labs
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Jamba | Paper | Jamba: A Hybrid Transformer-Mamba Language Model |
| 2024-08 | Jamba-1.5 | Paper | Jamba-1.5: Hybrid Transformer-Mamba Models at Scale |
| 2026-01 | Jamba2 | Blog | Introducing Jamba2 |
Databricks
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | DBRX | Blog | Introducing DBRX: A New State-of-the-Art Open LLM |
TII / Falcon
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-06 | Falcon (7B/40B/180B) | Paper | The Falcon Series of Open Language Models |
| 2024-05 | Falcon 2 (11B) | Blog | Falcon 2: An 11B Parameter Multilingual Model |
| 2024-12 | Falcon 3 | Blog | Falcon 3 |
| 2026-01 | Falcon-H1R 7B | Blog | Introducing Falcon H1R 7B |
Reka AI
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-04 | Reka Core/Flash/Edge | Paper | Reka Core, Flash, and Edge: A Series of Powerful Multimodal Language Models |
| 2025-07 | Reka Flash 3.1 | Blog | Reka Flash 3.1 and Reka Quant |
Baichuan
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-06 | Baichuan | Paper | Baichuan 2: Open Large-scale Language Models |
| 2023-09 | Baichuan 2 | Paper | Baichuan 2: Open Large-scale Language Models |
| 2025-09 | Baichuan-M2 | Paper | Baichuan-M2: A Medical LLM |
| 2026-02 | Baichuan-M3 | Paper | Baichuan-M3 |
| 2026-06 | Baichuan-M4 | Paper | Baichuan-M4: A Clinical-Grade Medical Agent System for Continuous Care |
01.AI / Yi
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Yi | Paper | Yi: Open Foundation Models by 01.AI |
| 2024-05 | Yi-1.5 | GitHub | Yi-1.5: Updated, Stronger |
| 2024-09 | Yi-Coder | Blog | Yi-Coder: A Small but Mighty LLM for Code |
| 2025-02 | Yi-Lightning | Paper | Yi-Lightning Technical Report |
Meituan
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-09 | LongCat-Flash | Paper | LongCat-Flash |
| 2025-09 | LongCat-Flash-Thinking | Paper | LongCat-Flash-Thinking |
| 2025-10 | LongCat-Flash-Omni | Paper | LongCat-Flash-Omni |
| 2025-12 | LongCat-Image | Paper | LongCat-Image Technical Report |
| 2026-01 | LongCat-Flash-Thinking-2601 | Technical Report | LongCat-Flash-Thinking-2601 Technical Report |
| 2026-03 | LongCat-Next | Paper | LongCat-Next: Lexicalizing Modalities as Discrete Tokens |
| 2026-05 | LongCat-Video-Avatar-1.5 | Model Card | LongCat-Video-Avatar-1.5 |
StepFun
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-12 | Step-DeepResearch | Paper | Step-DeepResearch |
| 2026-02 | Step-3.5-Flash | Paper | Step-3.5-Flash |
| 2026-05 | StepAudio 2.5 | Technical Report | StepAudio 2.5 Technical Report |
| 2026-05 | Step-3.7-Flash | Blog | Step 3.7 Flash |
InclusionAI (Ant Group)
| Date | Model | Type | Link |
|---|---|---|---|
| 2026-02 | Ling 2.5 | GitHub | Ling 2.5 |
| 2026-04 | LLaDA2.0-Uni | Paper | LLaDA2.0-Uni: Unifying Multimodal Understanding and Generation with Diffusion LLM |
| 2026-04 | DR-Venus | Paper | DR-Venus: Frontier Edge-Scale Deep Research Agents |
| 2026-04 | Ling-2.6-1T | Model Card | Ling-2.6-1T |
| 2026-04 | Ling-2.6-flash | Model Card | Ling-2.6-flash |
| 2026-04 | cuLA | GitHub | cuLA |
| 2026-06 | Ling/Ring 2.6 | Technical Report | Ling and Ring 2.6 Technical Report |
| 2026-06 | Sing-Guard | GitHub | Sing-Guard |
Zhijiang Lab / Moxin
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-12 | Moxin-7B | Paper | Fully Open Source Moxin-7B Technical Report |
| 2025-09 | CC-MoE | Paper | Collaborative Compression for Large-Scale MoE Deployment on Edge |
| 2025-12 | Moxin-VLM/VLA | Paper | Open-Source Multimodal Moxin Models with Moxin-VLM and Moxin-VLA |
Xiaomi / MiMo
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-04 | MiMo-7B | Paper | MiMo: Unlocking the Reasoning Potential of Language Model |
| 2025-07 | MiMo-V2-Flash | GitHub | MiMo-V2-Flash |
| 2025-11 | MiMo-Embodied | Technical Report | MiMo-Embodied: X-Embodied Foundation Model Technical Report |
| 2025-12 | MiMo-VL-Miloco | Technical Report | Xiaomi MiMo-VL-Miloco Technical Report |
| 2025-12 | MiMo-Audio | Technical Report | MiMo-Audio: Audio Language Models are Few-Shot Learners |
| 2026-01 | MiMo-V2-Flash | Technical Report | MiMo-V2-Flash Technical Report |
| 2026-04 | MiMo-V2.5-ASR | GitHub | MiMo-V2.5-ASR |
| 2026-06 | MiMo-Code | GitHub | MiMo-Code |
Cohere
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Command R | Blog | Introducing Command R |
| 2024-04 | Command R+ | Blog | Command R+ |
| 2024-08 | Aya-23 | Paper | Aya 23: Open Weight Releases to Further Multilingual Progress |
| 2024-12 | Aya Expanse | Paper | Aya Expanse: Connecting the Global Majority |
| 2025-03 | Command A | Blog | Command A |
| 2026-05 | Command A+ | Blog | Introducing Command A+ |
Apple
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-12 | Ferret | Paper | Ferret: Refer and Ground Anything Anywhere at Any Granularity |
| 2024-07 | Apple Intelligence (AFM) | Paper | Apple Intelligence Foundation Language Models |
| 2024-12 | AIMv2 | Paper | AIMv2: A Family of Strong Image Encoders |
| 2026-06 | Apple Foundation Models (3rd gen) | Blog | Introducing the Third Generation of Apple's Foundation Models |
Contributing
Contributions welcome! To add a new report:
- Fork this repo
- Add the entry to the appropriate company section in
README.md - Follow the format:
| Date | Model | Type | Link | - Submit a PR
Guidelines:
- Only include official publications: technical reports, papers, system cards, model cards, or official blog posts
- Use the original source link (arxiv, official CDN, company blog)
- Date format:
YYYY-MM - Sort entries chronologically within each company section
🤖 AI-assisted maintenance: This repo ships native instruction files for AI assistants — Claude Code skills (
.claude/skills/), Cursor rules (.cursor/rules/), and Codex (AGENTS.md) — so your assistant follows the schema and guardrails automatically. See CONTRIBUTING.md.
License
This project is licensed under the MIT License.
Acknowledgements
This project is inspired by:
Contributors

17 commits
Similar repos


Languages
Python
100.0%
A summary of technical reports for various large language models (LLMs).
Python
39
17 commits
updated Aug 19, 2026
README
📄 LLM Technical Reports
A curated collection of technical reports, system cards, and model cards from major LLM labs — organized by company, with links to official documents.
- 🏢 Organized by company — easy to track a lab's model evolution
- 📅 Chronological — each company's reports sorted by release date
- 🌐 Comprehensive — covers both Western and Chinese AI labs
Table of Contents
- OpenAI
- Google / DeepMind
- Anthropic
- Meta
- DeepSeek
- Alibaba / Qwen
- Shanghai AI Lab / InternLM
- ByteDance
- Zhipu AI / GLM
- Moonshot AI / Kimi
- Baidu / ERNIE
- Tencent / Hunyuan
- MiniMax
- Mistral AI
- xAI / Grok
- Microsoft / Phi
- Amazon
- Nvidia
- AI21 Labs
- Databricks
- TII / Falcon
- Reka AI
- Cohere
- Apple
- Baichuan
- 01.AI / Yi
- Meituan
- StepFun
- InclusionAI (Ant Group)
- Xiaomi / MiMo
- Zhijiang Lab / Moxin
OpenAI
Google / DeepMind
Anthropic
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-03 | Claude (Constitutional AI) | Paper | Constitutional AI: Harmlessness from AI Feedback |
| 2023-07 | Claude 2 | Model Card | Claude 2 Model Card |
| 2024-03 | Claude 3 Family | Model Card | The Claude 3 Model Family |
| 2025-02 | Claude 3.7 Sonnet | System Card | Claude 3.7 Sonnet System Card |
| 2025-05 | Claude Opus 4 / Sonnet 4 | System Card | Claude Opus 4 and Sonnet 4 System Card |
| 2025-06 | Claude Opus 4.5 | System Card | Claude Opus 4.5 System Card |
| 2025-06 | Claude Sonnet 4.5 | System Card | Claude Sonnet 4.5 System Card |
| 2026-02 | Claude Opus 4.6 | System Card | Claude Opus 4.6 System Card |
| 2026-04 | Claude Opus 4.7 / Sonnet 4.6 | System Card | Claude Opus 4.7 and Sonnet 4.6 System Card |
| 2026-05 | Claude Opus 4.8 | System Card | Claude Opus 4.8 |
| 2026-06 | Claude Fable 5 / Mythos 5 | System Card | Claude Fable 5 and Mythos 5 |
| 2026-06 | Claude Sonnet 5 | System Card | Claude Sonnet 5 System Card |
| 2026-07 | Claude Opus 5 | System Card | Claude Opus 5 System Card |
Meta
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-02 | LLaMA | Paper | LLaMA: Open and Efficient Foundation Language Models |
| 2023-07 | Llama 2 | Paper | Llama 2: Open Foundation and Fine-Tuned Chat Models |
| 2024-04 | Llama 3.1 | Paper | The Llama 3 Herd of Models |
| 2024-07 | Llama 3 | Paper | The Llama 3 Herd of Models |
| 2025-04 | Llama 4 Scout / Maverick | Blog | Llama 4: Open, Multimodal Intelligence |
| 2025-06 | Llama 4 Behemoth | Blog | Llama 4 Behemoth |
| 2026-04 | Muse Spark | Blog | Introducing Muse Spark |
DeepSeek
Alibaba / Qwen
Shanghai AI Lab / InternLM
ByteDance
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-10 | Doubao/Seed1.0 | Blog | Doubao Model Family |
| 2025-04 | Seed1.5-Thinking | Paper | Seed1.5-Thinking: Advancing Superb Reasoning Models with Reinforcement Learning |
| 2025-05 | Seed1.5-VL | Paper | Seed1.5-VL: Better Vision-Language Understanding with Mixture of Experts |
| 2026-02 | MedXIAOHE | Paper | MedXIAOHE: A Medical Vision-Language Foundation Model |
| 2026-02 | Seed 2.0 | Model Card | Seed 2.0 Model Card |
| 2026-04 | Seeduplex | Blog | Introducing Seed Full-Duplex Speech LLM |
| 2026-04 | Seedance 2.0 | Technical Report | Seedance 2.0: Advancing Video Generation for World Complexity |
| 2026-05 | Seed3D 2.0 | Technical Report | Seed3D 2.0: Advancing High-Fidelity Simulation-Ready 3D Content Generation |
| 2026-05 | Cola DLM | Paper | Continuous Latent Diffusion Language Model |
| 2026-05 | TaskMem | Paper | Task-Focused Memorization for Multimodal Agents |
| 2026-06 | Seed-2.1-Pro-Preview | Blog | Seed-2.1-Preview Model Release on Arena |
Zhipu AI / GLM
| Date | Model | Type | Link |
|---|---|---|---|
| 2022-10 | GLM-130B | Paper | GLM-130B: An Open Bilingual Pre-trained Model |
| 2024-01 | CogVLM | Paper | CogVLM: Visual Expert for Pretrained Language Models |
| 2024-06 | GLM-4 | Paper | ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools |
| 2024-08 | CogVideoX | Paper | CogVideoX: Text-to-Video Diffusion Models with An Expert Transformer |
| 2024-12 | GLM-Zero | Blog | GLM-Zero-Preview |
| 2025-08 | GLM-4.5 | Paper | GLM-4.5: An Open Mixture-of-Experts LLM |
| 2026-02 | GLM-5 | Paper | GLM-5 |
| 2026-04 | GLM-4.6V | Blog | GLM-4.6V |
| 2026-06 | GLM-5.2 | Blog | GLM-5.2: Built for Long-Horizon Tasks |
Moonshot AI / Kimi
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Kimi (Moonshot-v1) | Blog | Kimi — First 200k context length model |
| 2025-07 | Kimi K2.0 | Paper | Kimi K2.0 Technical Report |
| 2026-02 | Kimi K2.5 | Paper | Kimi K2.5 Technical Report |
| 2026-04 | Kimi K2.6 | Blog | Kimi K2.6 |
Baidu / ERNIE
| Date | Model | Type | Link |
|---|---|---|---|
| 2021-12 | ERNIE 3.0 | Paper | ERNIE 3.0: Large-scale Knowledge Enhanced Pre-training for Language Understanding and Generation |
| 2023-12 | ERNIE Bot (3.5/4.0) | Paper | ERNIE Bot: Advanced Language Model |
| 2025-06 | ERNIE 4.5 | Technical Report | ERNIE 4.5 Technical Report |
| 2026-02 | ERNIE 5.0 | Paper | ERNIE 5.0 |
| 2026-05 | ERNIE-Image | Technical Report | ERNIE-Image Technical Report |
| 2026-05 | ERNIE 5.1 | Blog | ERNIE 5.1 Officially Released |
| 2026-06 | PaddleOCR-VL-1.6 | Technical Report | PaddleOCR-VL-1.6 Technical Report |
Tencent / Hunyuan
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Hunyuan-DiT | Paper | Hunyuan-DiT: A Powerful Multi-Resolution Diffusion Transformer with Fine-Grained Chinese Understanding |
| 2024-11 | Hunyuan-Large | Paper | Hunyuan-Large: An Open-Source MoE Model with 52 Billion Activated Parameters |
| 2025-03 | Hunyuan-T1 | Blog | Hunyuan Turbomind T1 |
| 2025-05 | Yuanbao (Hunyuan-TurboS) | Paper | Hunyuan-TurboS: A Hybrid Transformer-Mamba MoE Model |
| 2026-04 | Hy3-preview | GitHub | Hy3-preview |
| 2026-06 | Hy-Embodied-0.5-VLA | GitHub | Hy-Embodied-0.5-VLA |
| 2026-07 | Hy3 | Blog | Tencent Hunyuan Officially Releases Hy3 |
MiniMax
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-01 | MiniMax-01 | Paper | MiniMax-01: Scaling Foundation Models with Lightning Attention |
| 2025-10 | MiniMax M2.0 | Paper | MiniMax M2.0 |
| 2025-12 | MiniMax M2.1 | GitHub | MiniMax M2.1 |
| 2026-02 | MiniMax M2.5 | Blog | MiniMax M2.5 |
| 2026-04 | MiniMax M2.7 | Blog | MiniMax M2.7 |
| 2026-06 | MiniMax M3 | Model Card | MiniMax-M3 |
| 2026-06 | MiniMax Sparse Attention | Paper | MiniMax Sparse Attention |
| 2026-07 | MiniMax H3 | Blog | MiniMax H3: An Open Model Breaking the Boundaries Between Tasks and Modalities |
Mistral AI
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-10 | Mistral 7B | Paper | Mistral 7B |
| 2024-01 | Mixtral 8x7B | Paper | Mixtral of Experts |
| 2024-05 | Mistral 8x22B | Blog | Cheaper, Better, Faster, Stronger |
| 2024-07 | Mistral Large 2 | Blog | Mistral Large 2 |
| 2024-09 | Mistral Pixtral 12B | Blog | Pixtral 12B |
| 2024-11 | Mistral Pixtral Large | Blog | Pixtral Large |
| 2025-01 | Mistral Small 3 | Blog | Mistral Small 3 |
| 2025-02 | Mistral Saba | Blog | Mistral Saba |
| 2025-03 | Mistral Small 3.1 | Blog | Mistral Small 3.1 |
| 2025-05 | Mistral Medium 3 | Blog | Mistral Medium 3 |
| 2025-06 | Magistral | Paper | Magistral |
| 2025-08 | Devstral | Paper | Devstral: Fine-tuning Language Models for Coding Agent Applications |
| 2026-03 | Mistral Small 4 | Blog | Introducing Mistral Small 4 |
| 2026-06 | Mistral OCR 4 | Blog | Introducing Mistral OCR 4 |
| 2026-07 | Leanstral 1.5 | Blog | Leanstral 1.5: Proof Abundance for All |
| 2026-07 | Robostral Navigate | Paper | Robostral Navigate |
xAI / Grok
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Grok-1 | Blog | Open Release of Grok-1 |
| 2024-08 | Grok-2 | Blog | Grok-2 Beta Release |
| 2025-02 | Grok-3 | Blog | Grok 3 |
| 2025-08 | Grok 4 | Model Card | Grok 4 Model Card |
| 2025-11 | Grok 4.1 | Model Card | Grok 4.1 Model Card |
| 2026-07 | Grok 4.5 | Model Card | Grok 4.5 Model Card |
| 2026-07 | Grok Voice Think Fast 2.0 | Blog | Introducing Grok Voice Think Fast 2.0 |
Microsoft / Phi
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-06 | Phi-1 | Paper | Textbooks Are All You Need |
| 2023-12 | Phi-2 | Paper | Phi-2: The surprising power of small language models |
| 2024-04 | Phi-3 | Paper | Phi-3 Technical Report |
| 2024-12 | Phi-4 | Paper | Phi-4 Technical Report |
| 2025-02 | Phi-4-mini | Paper | Phi-4-mini Technical Report |
| 2025-05 | Phi-4-reasoning | Paper | Phi-4-reasoning Technical Report |
| 2025-06 | Phi-4-multimodal | Paper | Phi-4-multimodal Technical Report |
| 2026-03 | Phi-4-reasoning-vision-15B | Paper | Phi-4-reasoning-vision-15B Technical Report |
Amazon
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-12 | Nova (Micro/Lite/Pro) | Blog | Introducing Amazon Nova Foundation Models |
| 2025-06 | Nova Family | Paper | The Amazon Nova Family of Models: Technical Report and Model Card |
| 2025-12 | Amazon Nova 2 | Technical Report | Amazon Nova 2: Multimodal Reasoning and Generation Models |
Nvidia
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-06 | Nemotron-4 340B | Paper | Nemotron-4 340B Technical Report |
| 2024-10 | Llama-3.1-Nemotron-70B | Model Card | Llama-3.1-Nemotron-70B-Instruct |
| 2025-03 | Llama-3.1-Nemotron-Ultra-253B | Paper | Llama-Nemotron: An Open Reasoning Model Family |
| 2025-12 | NVIDIA Nemotron 3 | Paper | NVIDIA Nemotron 3: Efficient and Open Intelligence |
AI21 Labs
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Jamba | Paper | Jamba: A Hybrid Transformer-Mamba Language Model |
| 2024-08 | Jamba-1.5 | Paper | Jamba-1.5: Hybrid Transformer-Mamba Models at Scale |
| 2026-01 | Jamba2 | Blog | Introducing Jamba2 |
Databricks
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | DBRX | Blog | Introducing DBRX: A New State-of-the-Art Open LLM |
TII / Falcon
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-06 | Falcon (7B/40B/180B) | Paper | The Falcon Series of Open Language Models |
| 2024-05 | Falcon 2 (11B) | Blog | Falcon 2: An 11B Parameter Multilingual Model |
| 2024-12 | Falcon 3 | Blog | Falcon 3 |
| 2026-01 | Falcon-H1R 7B | Blog | Introducing Falcon H1R 7B |
Reka AI
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-04 | Reka Core/Flash/Edge | Paper | Reka Core, Flash, and Edge: A Series of Powerful Multimodal Language Models |
| 2025-07 | Reka Flash 3.1 | Blog | Reka Flash 3.1 and Reka Quant |
Baichuan
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-06 | Baichuan | Paper | Baichuan 2: Open Large-scale Language Models |
| 2023-09 | Baichuan 2 | Paper | Baichuan 2: Open Large-scale Language Models |
| 2025-09 | Baichuan-M2 | Paper | Baichuan-M2: A Medical LLM |
| 2026-02 | Baichuan-M3 | Paper | Baichuan-M3 |
| 2026-06 | Baichuan-M4 | Paper | Baichuan-M4: A Clinical-Grade Medical Agent System for Continuous Care |
01.AI / Yi
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Yi | Paper | Yi: Open Foundation Models by 01.AI |
| 2024-05 | Yi-1.5 | GitHub | Yi-1.5: Updated, Stronger |
| 2024-09 | Yi-Coder | Blog | Yi-Coder: A Small but Mighty LLM for Code |
| 2025-02 | Yi-Lightning | Paper | Yi-Lightning Technical Report |
Meituan
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-09 | LongCat-Flash | Paper | LongCat-Flash |
| 2025-09 | LongCat-Flash-Thinking | Paper | LongCat-Flash-Thinking |
| 2025-10 | LongCat-Flash-Omni | Paper | LongCat-Flash-Omni |
| 2025-12 | LongCat-Image | Paper | LongCat-Image Technical Report |
| 2026-01 | LongCat-Flash-Thinking-2601 | Technical Report | LongCat-Flash-Thinking-2601 Technical Report |
| 2026-03 | LongCat-Next | Paper | LongCat-Next: Lexicalizing Modalities as Discrete Tokens |
| 2026-05 | LongCat-Video-Avatar-1.5 | Model Card | LongCat-Video-Avatar-1.5 |
StepFun
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-12 | Step-DeepResearch | Paper | Step-DeepResearch |
| 2026-02 | Step-3.5-Flash | Paper | Step-3.5-Flash |
| 2026-05 | StepAudio 2.5 | Technical Report | StepAudio 2.5 Technical Report |
| 2026-05 | Step-3.7-Flash | Blog | Step 3.7 Flash |
InclusionAI (Ant Group)
| Date | Model | Type | Link |
|---|---|---|---|
| 2026-02 | Ling 2.5 | GitHub | Ling 2.5 |
| 2026-04 | LLaDA2.0-Uni | Paper | LLaDA2.0-Uni: Unifying Multimodal Understanding and Generation with Diffusion LLM |
| 2026-04 | DR-Venus | Paper | DR-Venus: Frontier Edge-Scale Deep Research Agents |
| 2026-04 | Ling-2.6-1T | Model Card | Ling-2.6-1T |
| 2026-04 | Ling-2.6-flash | Model Card | Ling-2.6-flash |
| 2026-04 | cuLA | GitHub | cuLA |
| 2026-06 | Ling/Ring 2.6 | Technical Report | Ling and Ring 2.6 Technical Report |
| 2026-06 | Sing-Guard | GitHub | Sing-Guard |
Zhijiang Lab / Moxin
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-12 | Moxin-7B | Paper | Fully Open Source Moxin-7B Technical Report |
| 2025-09 | CC-MoE | Paper | Collaborative Compression for Large-Scale MoE Deployment on Edge |
| 2025-12 | Moxin-VLM/VLA | Paper | Open-Source Multimodal Moxin Models with Moxin-VLM and Moxin-VLA |
Xiaomi / MiMo
| Date | Model | Type | Link |
|---|---|---|---|
| 2025-04 | MiMo-7B | Paper | MiMo: Unlocking the Reasoning Potential of Language Model |
| 2025-07 | MiMo-V2-Flash | GitHub | MiMo-V2-Flash |
| 2025-11 | MiMo-Embodied | Technical Report | MiMo-Embodied: X-Embodied Foundation Model Technical Report |
| 2025-12 | MiMo-VL-Miloco | Technical Report | Xiaomi MiMo-VL-Miloco Technical Report |
| 2025-12 | MiMo-Audio | Technical Report | MiMo-Audio: Audio Language Models are Few-Shot Learners |
| 2026-01 | MiMo-V2-Flash | Technical Report | MiMo-V2-Flash Technical Report |
| 2026-04 | MiMo-V2.5-ASR | GitHub | MiMo-V2.5-ASR |
| 2026-06 | MiMo-Code | GitHub | MiMo-Code |
Cohere
| Date | Model | Type | Link |
|---|---|---|---|
| 2024-03 | Command R | Blog | Introducing Command R |
| 2024-04 | Command R+ | Blog | Command R+ |
| 2024-08 | Aya-23 | Paper | Aya 23: Open Weight Releases to Further Multilingual Progress |
| 2024-12 | Aya Expanse | Paper | Aya Expanse: Connecting the Global Majority |
| 2025-03 | Command A | Blog | Command A |
| 2026-05 | Command A+ | Blog | Introducing Command A+ |
Apple
| Date | Model | Type | Link |
|---|---|---|---|
| 2023-12 | Ferret | Paper | Ferret: Refer and Ground Anything Anywhere at Any Granularity |
| 2024-07 | Apple Intelligence (AFM) | Paper | Apple Intelligence Foundation Language Models |
| 2024-12 | AIMv2 | Paper | AIMv2: A Family of Strong Image Encoders |
| 2026-06 | Apple Foundation Models (3rd gen) | Blog | Introducing the Third Generation of Apple's Foundation Models |
Contributing
Contributions welcome! To add a new report:
- Fork this repo
- Add the entry to the appropriate company section in
README.md - Follow the format:
| Date | Model | Type | Link | - Submit a PR
Guidelines:
- Only include official publications: technical reports, papers, system cards, model cards, or official blog posts
- Use the original source link (arxiv, official CDN, company blog)
- Date format:
YYYY-MM - Sort entries chronologically within each company section
🤖 AI-assisted maintenance: This repo ships native instruction files for AI assistants — Claude Code skills (
.claude/skills/), Cursor rules (.cursor/rules/), and Codex (AGENTS.md) — so your assistant follows the schema and guardrails automatically. See CONTRIBUTING.md.
License
This project is licensed under the MIT License.
Acknowledgements
This project is inspired by:
Similar repos
Contributors
17 commits
Languages
Python
100.0%