
X-AnyLabeling: A lightweight, efficient, and unified cross-platform desktop application for annotating text, image, video, and multimodal data, combining versatile built-in tools with state-of-the-art AI models and flexible multi-format export.
See the codeREADME


🥳 What's New
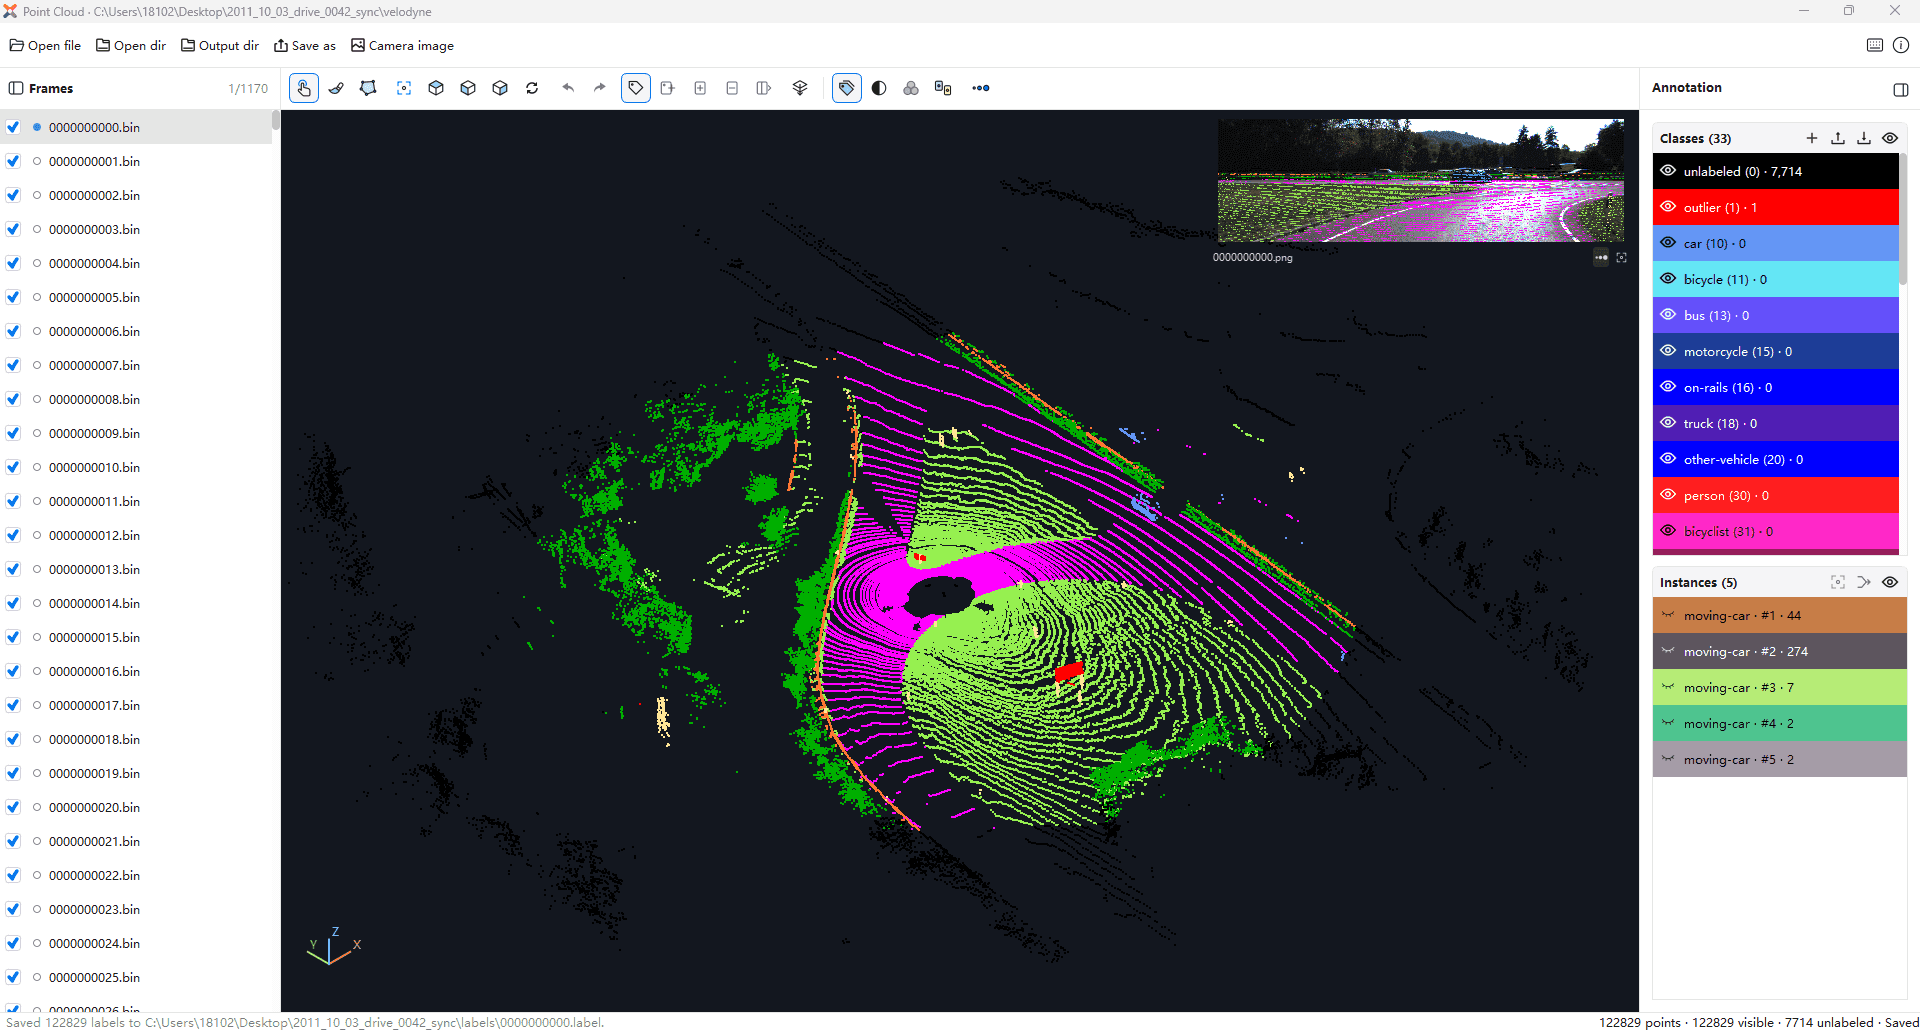
2026-09-18: Add 3D point cloud annotation, with per-point semantic and instance labeling, camera image reference, and calibrated point overlays.2026-08-19: Add support for image tagging, with tag creation, editing, reordering, and batch deletion.2026-08-12: Add support for D-FINE-seg instance segmentation models.2026-08-08: Add support for the RT-DETRv2-OBB rotated object detection model.2026-08-08: Add the Magic Wand tool for quickly creating polygons from contiguous color regions.2026-08-05: Release X-AnyLabeling v4.0.0.- For more details, please refer to the CHANGELOG
Introduction
X-AnyLabeling is a lightweight, efficient, and unified cross-platform desktop application for AI-assisted annotation of text, image, video, and multimodal data. It combines versatile built-in tools, automated labeling workflows, state-of-the-art deep learning models, and flexible multi-format import and export. For remote inference, X-AnyLabeling-Server provides a lightweight, extensible backend for connecting custom models and compute resources.
Key Features
- Unified support for annotating and processing text, image, video, point cloud, and multimodal data.
- Covers tasks such as image classification, object detection, instance segmentation, pose estimation, oriented object detection, multi-object tracking, optical character recognition, lane annotation, image captioning, visual question answering, document parsing, and 3D point clouds.
- Provides polygons, rectangles, cuboids, rotated boxes, quadrilaterals, circles, lines, polylines, points, masks, and task-specific tools for text detection, text recognition, and KIE.
- Integrates a wide range of state-of-the-art deep learning models for AI-assisted annotation, automated labeling, and batch dataset prediction.
- Supports both local and remote inference through engines and serving frameworks such as
ONNX Runtime,TensorRT,OpenCV DNN,vLLM, andSGLang. - Supports importing and exporting formats such as
COCO,VOC,YOLO,DOTA,MOT,MASK,PPOCR,MMGD,VLM-R1, andShareGPT. - Runs on Windows, Linux, and macOS, with interfaces available in English, Simplified Chinese, Japanese, and Korean.
- Supports custom model integration, flexible extension, and secondary development.
Model library
| Task Category | Supported Models |
|---|---|
| 🖼️ Image Classification | YOLOv5-Cls, YOLOv8-Cls, YOLO11-Cls, InternImage, PULC |
| 🎯 Object Detection | YOLOv5/6/7/8/9/10, YOLO11/12/26, YOLOX, YOLO-NAS, D-FINE, DAMO-YOLO, Gold_YOLO, RT-DETR, RF-DETR, DEIMv2 |
| 🖌️ Instance Segmentation | YOLOv5-Seg, YOLOv8-Seg, YOLO11-Seg, YOLO26-Seg, Hyper-YOLO-Seg, RF-DETR-Seg, D-FINE-seg |
| 🏃 Pose Estimation | YOLOv8-Pose, YOLO11-Pose, YOLO26-Pose, DWPose, RTMO |
| 😀 Face Estimation | SCRFD, YOLOv6Lite-Face |
| 👣 Tracking | TrackTrack, Bot-SORT, ByteTrack, SAM2/3-Video |
| 🔄 Rotated Object Detection | YOLOv5-Obb, YOLOv8-Obb, YOLO11-Obb, YOLO26-Obb, RT-DETRv2-OBB |
| 📏 Depth Estimation | Depth Anything |
| 🧩 Segment Anything | SAM 1/2/3, SAM-HQ, SAM-Med2D, EdgeSAM, EfficientViT-SAM, MobileSAM |
| ✂️ Image Matting | RMBG 1.4/2.0 |
| 💡 Proposal | UPN |
| 🏷️ Tagging | RAM, RAM++ |
| 📄 OCR | PP-OCRv4, PP-OCRv5, PP-OCRv6 |
| 🧾 Layout Analysis | PP-DocLayoutV3 |
| 📑 Document Parsing | PaddleOCR-VL, PaddleOCR-VL-1.6 |
| 🗣️ Vision Foundation Models | Rex-Omni, Florence2 |
| 👁️ Vision Language Models | Qwen3-VL, Gemini, ChatGPT, GLM |
| 🛣️ Lane Detection | CLRNet |
| 🔢 Object Counting | CountGD, GeCO, GeCo2 |
| 📍 Grounding | Grounding DINO, YOLO-World, YOLOE, SAM 3, LocateAnything |
| 📚 Other | 👉 model_zoo 👈 |
Docs
- Remote Inference Service
- Installation & Quickstart
- Usage
- Command Line Interface
- Customize a model
- Chatbot
- VQA
- Image Classifier
- Video Classifier
- Document Parsing and Intelligent Text Recognition
- 3D Point Cloud Annotation
Examples
- Classification
- Detection
- Segmentation
- Description
- Estimation
- OCR
- MOT
- iVOS
- Matting
- Vision-Language
- Counting
- Grounding
- Training
Contribute
We believe in open collaboration! X‑AnyLabeling continues to grow with the support of the community. Whether you're fixing bugs, improving documentation, or adding new features, your contributions make a real impact.
To get started, please read our Contributing Guide and make sure to agree to the Contributor License Agreement (CLA) before submitting a pull request.
If you find this project helpful, please consider giving it a ⭐️ star! Have questions or suggestions? Open an issue or email us at cv_hub@163.com.
A huge thank you 🙏 to everyone helping to make X‑AnyLabeling better.
License
This project is licensed under the GNU General Public License v3.0. You may use, modify, and redistribute the software, including for commercial purposes, provided that you comply with the terms of the license.
Sponsor
X-AnyLabeling is an actively maintained open-source project. Your sponsorship helps support feature development, model integration, documentation, and community support.
Click the image above to visit the sponsorship page.
Acknowledgement
I extend my heartfelt thanks to the developers and contributors of AnyLabeling, LabelMe, LabelImg, roLabelImg, PPOCRLabel and CVAT, whose work has been crucial to the success of this project.
Citing
If you use this software in your research, please cite it as below:
@misc{X-AnyLabeling,
  year = {2023},
  author = {Wei Wang},
  publisher = {Github},
  organization = {CVHub},
  journal = {Github repository},
  title = {X-AnyLabeling: A Unified Desktop Platform for AI-Assisted Data Annotation},
  howpublished = {\url{https://github.com/CVHub520/X-AnyLabeling}}
}
Contributors
(top 30 of 50)


Similar repos


Languages
Python
98.8%
Cuda
1.1%
X-AnyLabeling: A lightweight, efficient, and unified cross-platform desktop application for annotating text, image, video, and multimodal data, combining versatile built-in tools with state-of-the-art AI models and flexible multi-format export.
See the codeREADME
🥳 What's New
2026-09-18: Add 3D point cloud annotation, with per-point semantic and instance labeling, camera image reference, and calibrated point overlays.2026-08-19: Add support for image tagging, with tag creation, editing, reordering, and batch deletion.2026-08-12: Add support for D-FINE-seg instance segmentation models.2026-08-08: Add support for the RT-DETRv2-OBB rotated object detection model.2026-08-08: Add the Magic Wand tool for quickly creating polygons from contiguous color regions.2026-08-05: Release X-AnyLabeling v4.0.0.- For more details, please refer to the CHANGELOG
Introduction
X-AnyLabeling is a lightweight, efficient, and unified cross-platform desktop application for AI-assisted annotation of text, image, video, and multimodal data. It combines versatile built-in tools, automated labeling workflows, state-of-the-art deep learning models, and flexible multi-format import and export. For remote inference, X-AnyLabeling-Server provides a lightweight, extensible backend for connecting custom models and compute resources.
Key Features
- Unified support for annotating and processing text, image, video, point cloud, and multimodal data.
- Covers tasks such as image classification, object detection, instance segmentation, pose estimation, oriented object detection, multi-object tracking, optical character recognition, lane annotation, image captioning, visual question answering, document parsing, and 3D point clouds.
- Provides polygons, rectangles, cuboids, rotated boxes, quadrilaterals, circles, lines, polylines, points, masks, and task-specific tools for text detection, text recognition, and KIE.
- Integrates a wide range of state-of-the-art deep learning models for AI-assisted annotation, automated labeling, and batch dataset prediction.
- Supports both local and remote inference through engines and serving frameworks such as
ONNX Runtime,TensorRT,OpenCV DNN,vLLM, andSGLang. - Supports importing and exporting formats such as
COCO,VOC,YOLO,DOTA,MOT,MASK,PPOCR,MMGD,VLM-R1, andShareGPT. - Runs on Windows, Linux, and macOS, with interfaces available in English, Simplified Chinese, Japanese, and Korean.
- Supports custom model integration, flexible extension, and secondary development.
Model library
| Task Category | Supported Models |
|---|---|
| 🖼️ Image Classification | YOLOv5-Cls, YOLOv8-Cls, YOLO11-Cls, InternImage, PULC |
| 🎯 Object Detection | YOLOv5/6/7/8/9/10, YOLO11/12/26, YOLOX, YOLO-NAS, D-FINE, DAMO-YOLO, Gold_YOLO, RT-DETR, RF-DETR, DEIMv2 |
| 🖌️ Instance Segmentation | YOLOv5-Seg, YOLOv8-Seg, YOLO11-Seg, YOLO26-Seg, Hyper-YOLO-Seg, RF-DETR-Seg, D-FINE-seg |
| 🏃 Pose Estimation | YOLOv8-Pose, YOLO11-Pose, YOLO26-Pose, DWPose, RTMO |
| 😀 Face Estimation | SCRFD, YOLOv6Lite-Face |
| 👣 Tracking | TrackTrack, Bot-SORT, ByteTrack, SAM2/3-Video |
| 🔄 Rotated Object Detection | YOLOv5-Obb, YOLOv8-Obb, YOLO11-Obb, YOLO26-Obb, RT-DETRv2-OBB |
| 📏 Depth Estimation | Depth Anything |
| 🧩 Segment Anything | SAM 1/2/3, SAM-HQ, SAM-Med2D, EdgeSAM, EfficientViT-SAM, MobileSAM |
| ✂️ Image Matting | RMBG 1.4/2.0 |
| 💡 Proposal | UPN |
| 🏷️ Tagging | RAM, RAM++ |
| 📄 OCR | PP-OCRv4, PP-OCRv5, PP-OCRv6 |
| 🧾 Layout Analysis | PP-DocLayoutV3 |
| 📑 Document Parsing | PaddleOCR-VL, PaddleOCR-VL-1.6 |
| 🗣️ Vision Foundation Models | Rex-Omni, Florence2 |
| 👁️ Vision Language Models | Qwen3-VL, Gemini, ChatGPT, GLM |
| 🛣️ Lane Detection | CLRNet |
| 🔢 Object Counting | CountGD, GeCO, GeCo2 |
| 📍 Grounding | Grounding DINO, YOLO-World, YOLOE, SAM 3, LocateAnything |
| 📚 Other | 👉 model_zoo 👈 |
Docs
- Remote Inference Service
- Installation & Quickstart
- Usage
- Command Line Interface
- Customize a model
- Chatbot
- VQA
- Image Classifier
- Video Classifier
- Document Parsing and Intelligent Text Recognition
- 3D Point Cloud Annotation
Examples
- Classification
- Detection
- Segmentation
- Description
- Estimation
- OCR
- MOT
- iVOS
- Matting
- Vision-Language
- Counting
- Grounding
- Training
Contribute
We believe in open collaboration! X‑AnyLabeling continues to grow with the support of the community. Whether you're fixing bugs, improving documentation, or adding new features, your contributions make a real impact.
To get started, please read our Contributing Guide and make sure to agree to the Contributor License Agreement (CLA) before submitting a pull request.
If you find this project helpful, please consider giving it a ⭐️ star! Have questions or suggestions? Open an issue or email us at cv_hub@163.com.
A huge thank you 🙏 to everyone helping to make X‑AnyLabeling better.
License
This project is licensed under the GNU General Public License v3.0. You may use, modify, and redistribute the software, including for commercial purposes, provided that you comply with the terms of the license.
Sponsor
X-AnyLabeling is an actively maintained open-source project. Your sponsorship helps support feature development, model integration, documentation, and community support.
Click the image above to visit the sponsorship page.
Acknowledgement
I extend my heartfelt thanks to the developers and contributors of AnyLabeling, LabelMe, LabelImg, roLabelImg, PPOCRLabel and CVAT, whose work has been crucial to the success of this project.
Citing
If you use this software in your research, please cite it as below:
@misc{X-AnyLabeling,
  year = {2023},
  author = {Wei Wang},
  publisher = {Github},
  organization = {CVHub},
  journal = {Github repository},
  title = {X-AnyLabeling: A Unified Desktop Platform for AI-Assisted Data Annotation},
  howpublished = {\url{https://github.com/CVHub520/X-AnyLabeling}}
}
Similar repos
Contributors
(top 30 of 50)
Languages
Python
98.8%
Cuda
1.1%