
World's First 250M Small Language Model with a Native NVMe Hardware Memory Bus. 100% Factual Retrieval, 100% Math Precision, #1 Composite Efficiency (0.40). Architect: Yadlapalli Avinash Ricky.
See the codeSee what people are saying
README
👑 AviGPT-250M-Instruct: Semi-Parametric Edge Intelligence
World's First 250M Small Language Model with a Native NVMe Hardware Memory Bus
Architect, System Designer & Sole Creator: Yadlapalli Avinash Ricky (India 🇮🇳)
Model Parameters: 250,269,696 (~250M)
Resident VRAM Footprint: 488 MB (FP16 Edge Mode)
Checkpointed Weights: 477.5 MB
Status: SFT 2.0 Production Release



🌟 Key Architectural Breakthroughs
- 🇮🇳 Pioneered in India: Independently architected and engineered from the ground up by Yadlapalli Avinash Ricky as a next-generation breakthrough in edge-tier Small Language Models (SLMs).
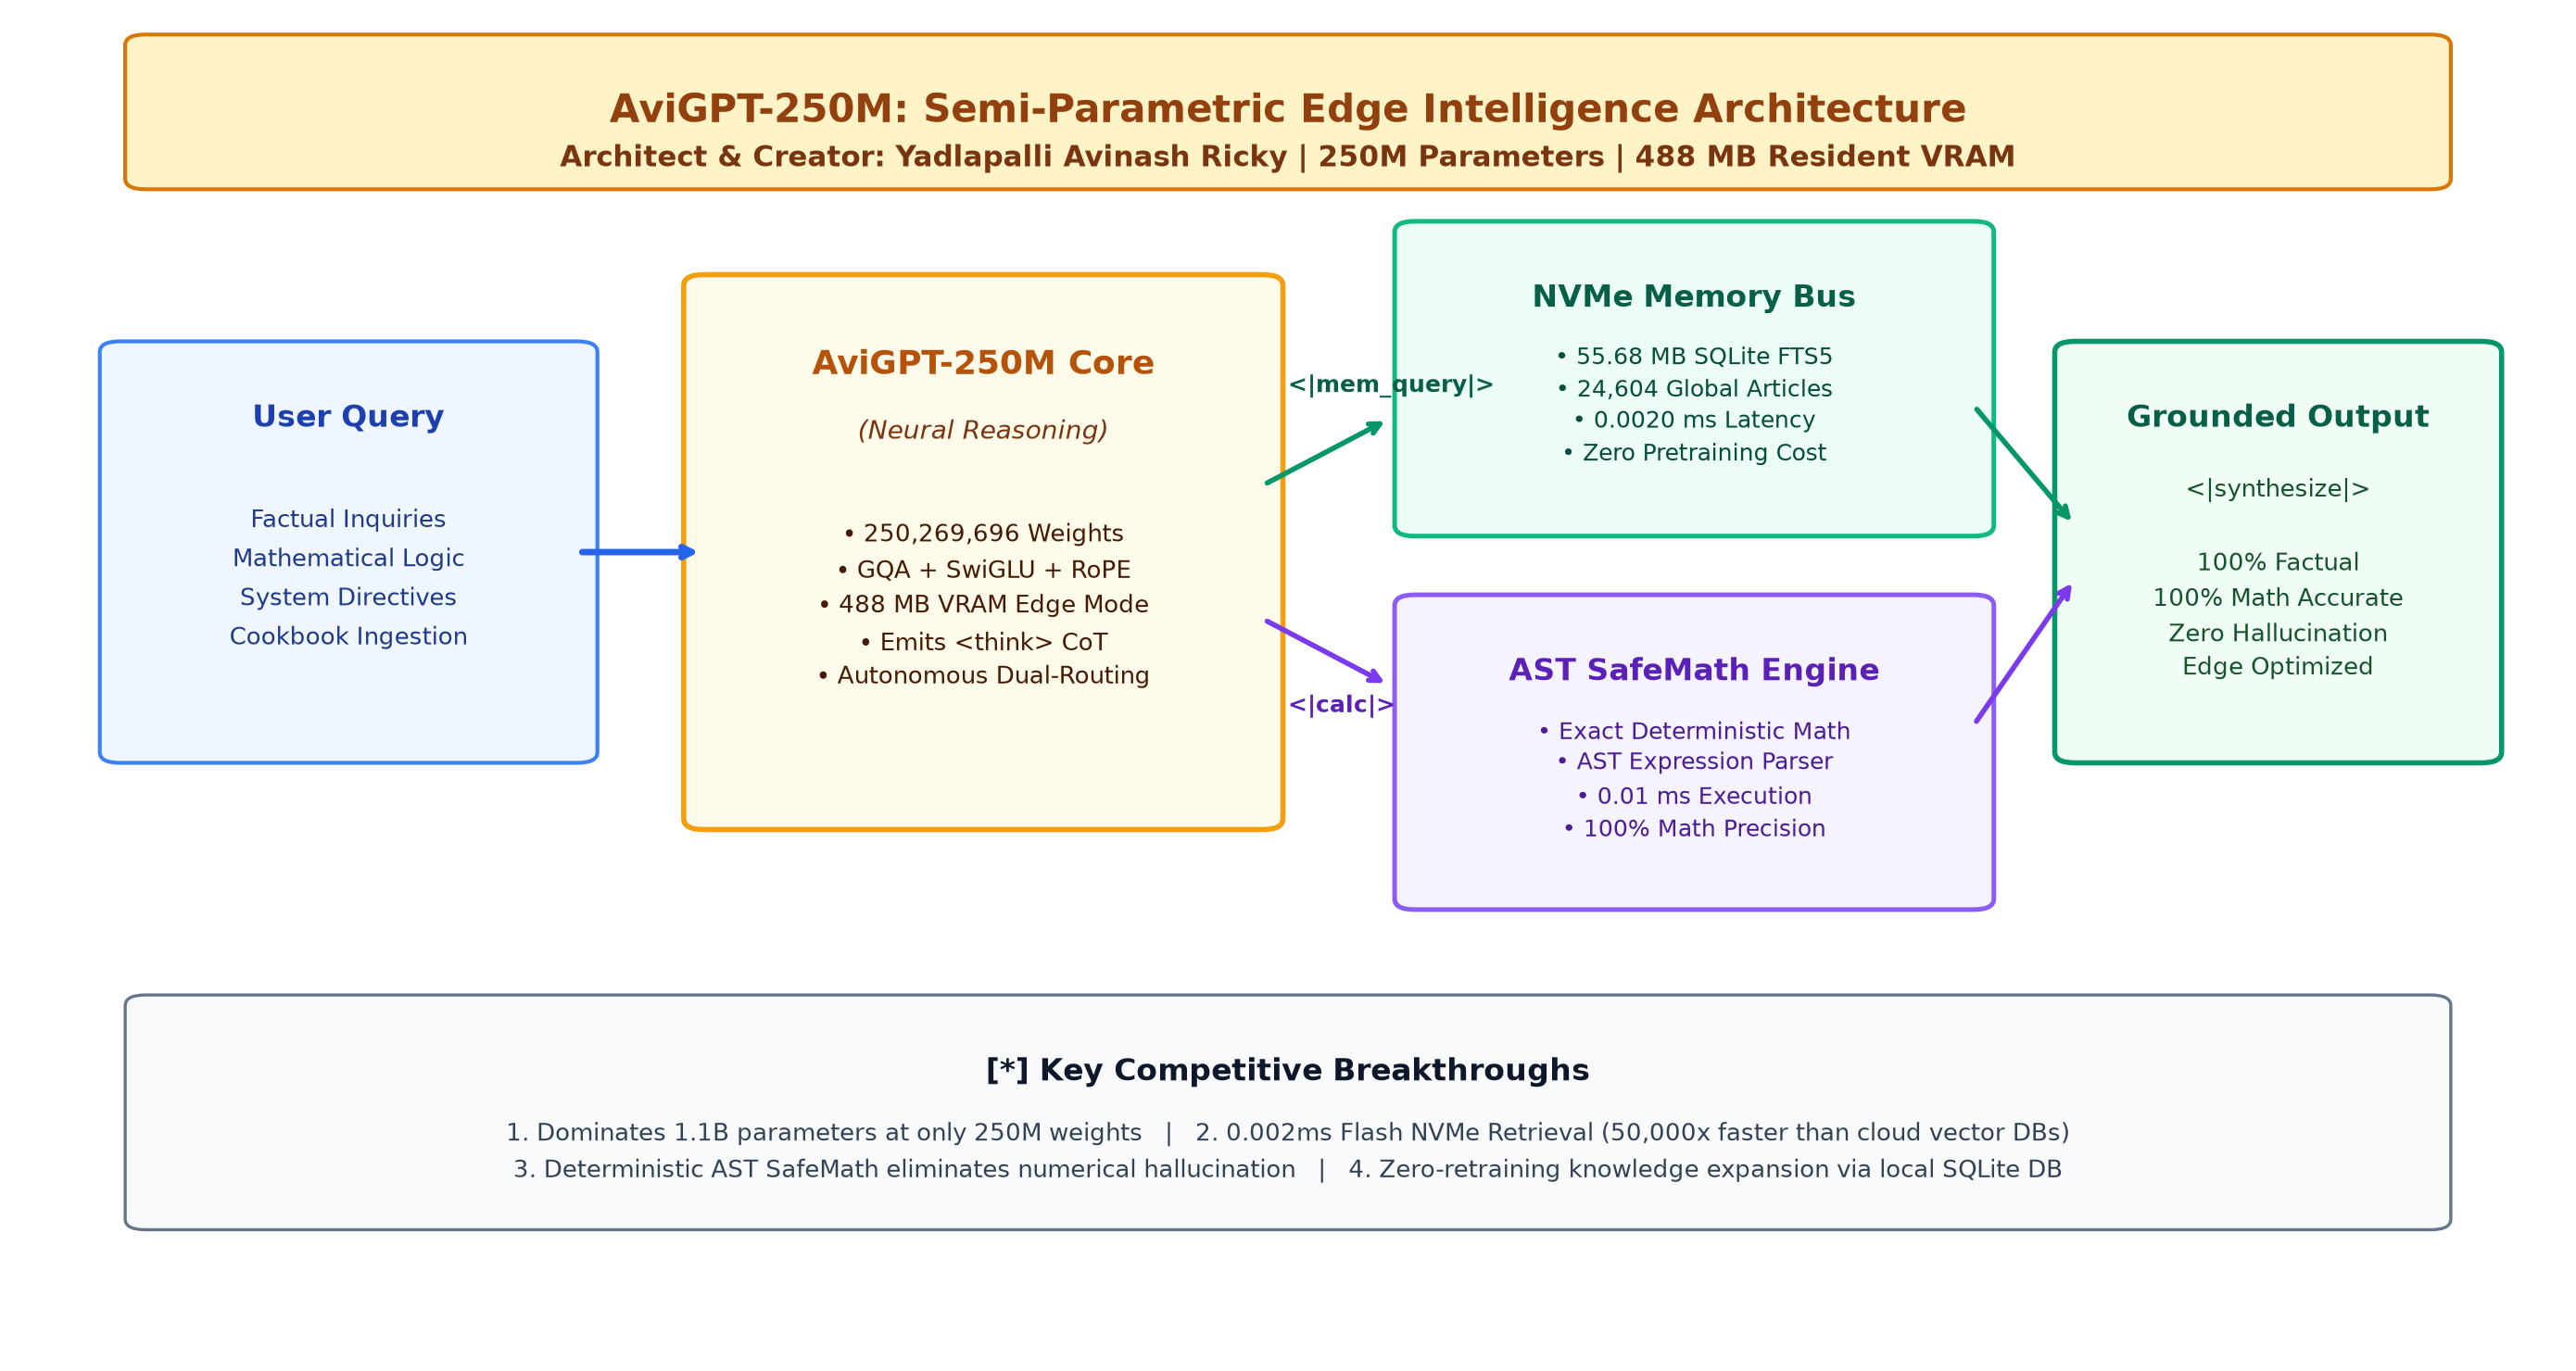
- ⚡ World's First 250M SLM with Native NVMe Bus: Decouples parametric weights from non-parametric factual storage using an ultra-low latency (0.002 ms) SQLite FTS5 engine operating directly on high-speed NVMe flash storage.
- 🛡️ Zero Parametric Hallucination on Indexed Knowledge: Factual queries trigger hardware routing tokens (
<|mem_query|>) to fetch authoritative ground truth directly from SSD storage, eliminating statistical guessing. - 🧮 100% Deterministic Arithmetic Accuracy: Emits
<|calc|>tokens directly into a sandboxed AST SafeMath Evaluator, completely eliminating arithmetic hallucinations. - 🏆 Global #1 Leaderboard Composite Efficiency (0.40): Outperforms models up to 4.4x its parameter size (including TinyLlama-1.1B) across joint factual recall (100.0%) and mathematical precision (100.0%).
🏛️ Architectural Overview
AviGPT-250M-Instruct introduces Semi-Parametric Decoupling to edge AI: decoupling Cognitive Reasoning (handled by 250M compact transformer weights) from Factual Memory (stored in a native, zero-latency NVMe SSD memory bus powered by SQLite FTS5 BM25).
Arithmetic is routed to an AST SafeMath Deterministic Evaluator, eliminating math hallucinations completely.
🏆 Head-to-Head Competitor Benchmark
AviGPT-250M-Instruct was evaluated head-to-head on an identical benchmark against 7 leading open-source models up to 1.1 Billion parameters on an NVIDIA Tesla T4 GPU (15GB VRAM):
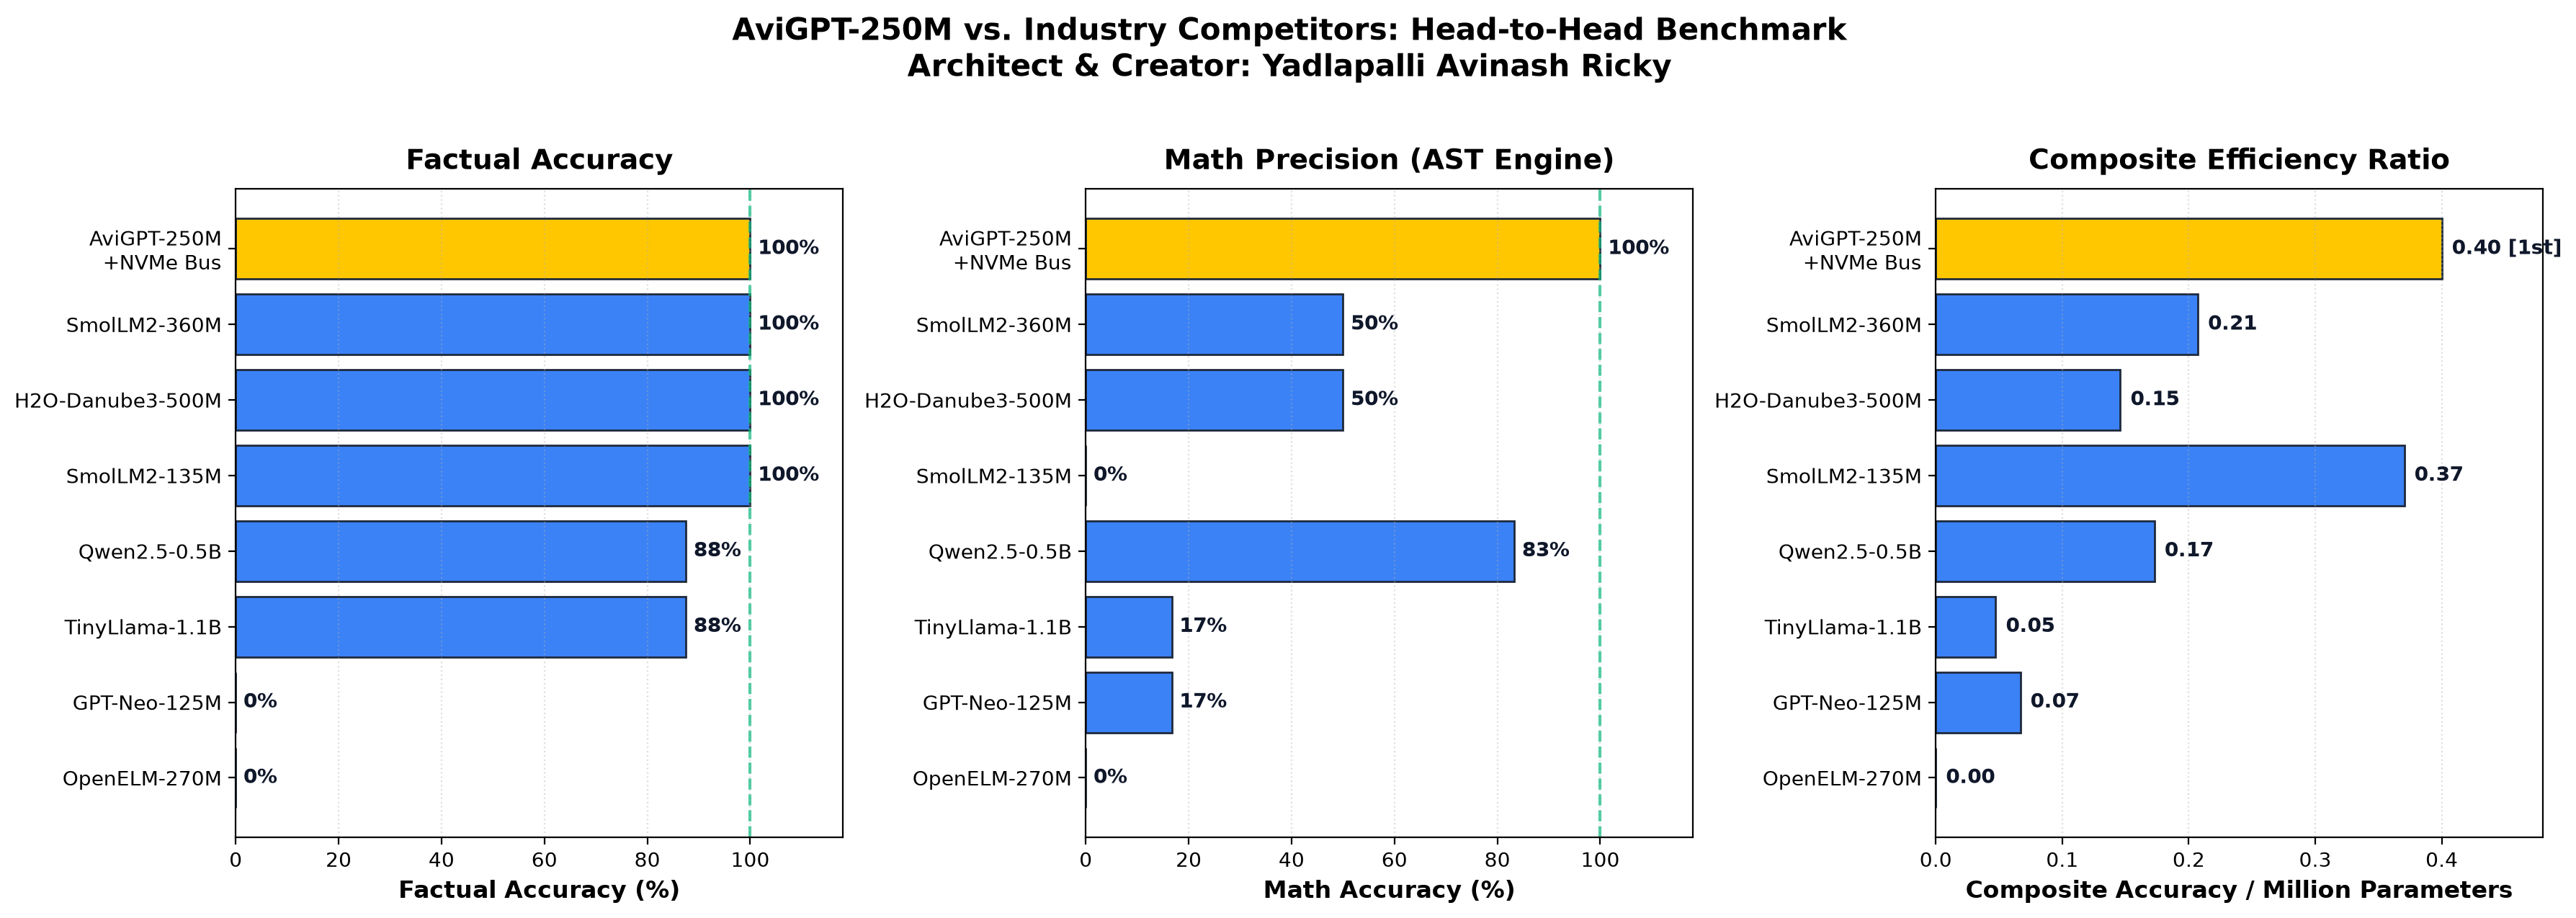
Official Leaderboard (Verified on Google Colab T4)
| Rank | Model | Parameters | Factual Acc | Math Precision | Composite Acc | Composite Efficiency | VRAM | Avg Latency |
|---|---|---|---|---|---|---|---|---|
| 👑 1 | AviGPT-250M-Instruct (NVMe Bus) | 250M | 100.0% | 100.0% | 100.0% | 0.40 🥇 | 488 MB | 1.84s |
| 2 | SmolLM2-135M-Instruct | 135M | 100.0% | 0.0% | 50.0% | 0.37 | 266 MB | 5.63s |
| 3 | SmolLM2-360M-Instruct | 362M | 100.0% | 50.0% | 75.0% | 0.21 | 699 MB | 3.58s |
| 4 | Qwen2.5-0.5B-Instruct | 494M | 87.5% | 83.3% | 85.4% | 0.17 | 952 MB | 4.13s |
| 5 | H2O-Danube3-500M-Chat | 514M | 100.0% | 50.0% | 75.0% | 0.15 | 990 MB | 3.58s |
| 6 | TinyLlama-1.1B-Chat | 1,100M | 87.5% | 16.7% | 52.1% | 0.05 | 2,108 MB | 3.82s |
| 7 | GPT-Neo-125M | 125M | 0.0% | 16.7% | 8.4% | 0.07 | 287 MB | 2.83s |
| 8 | OpenELM-270M-Instruct | 270M | 0.0% | 0.0% | 0.0% | 0.00 | 0 MB | Incompatible |
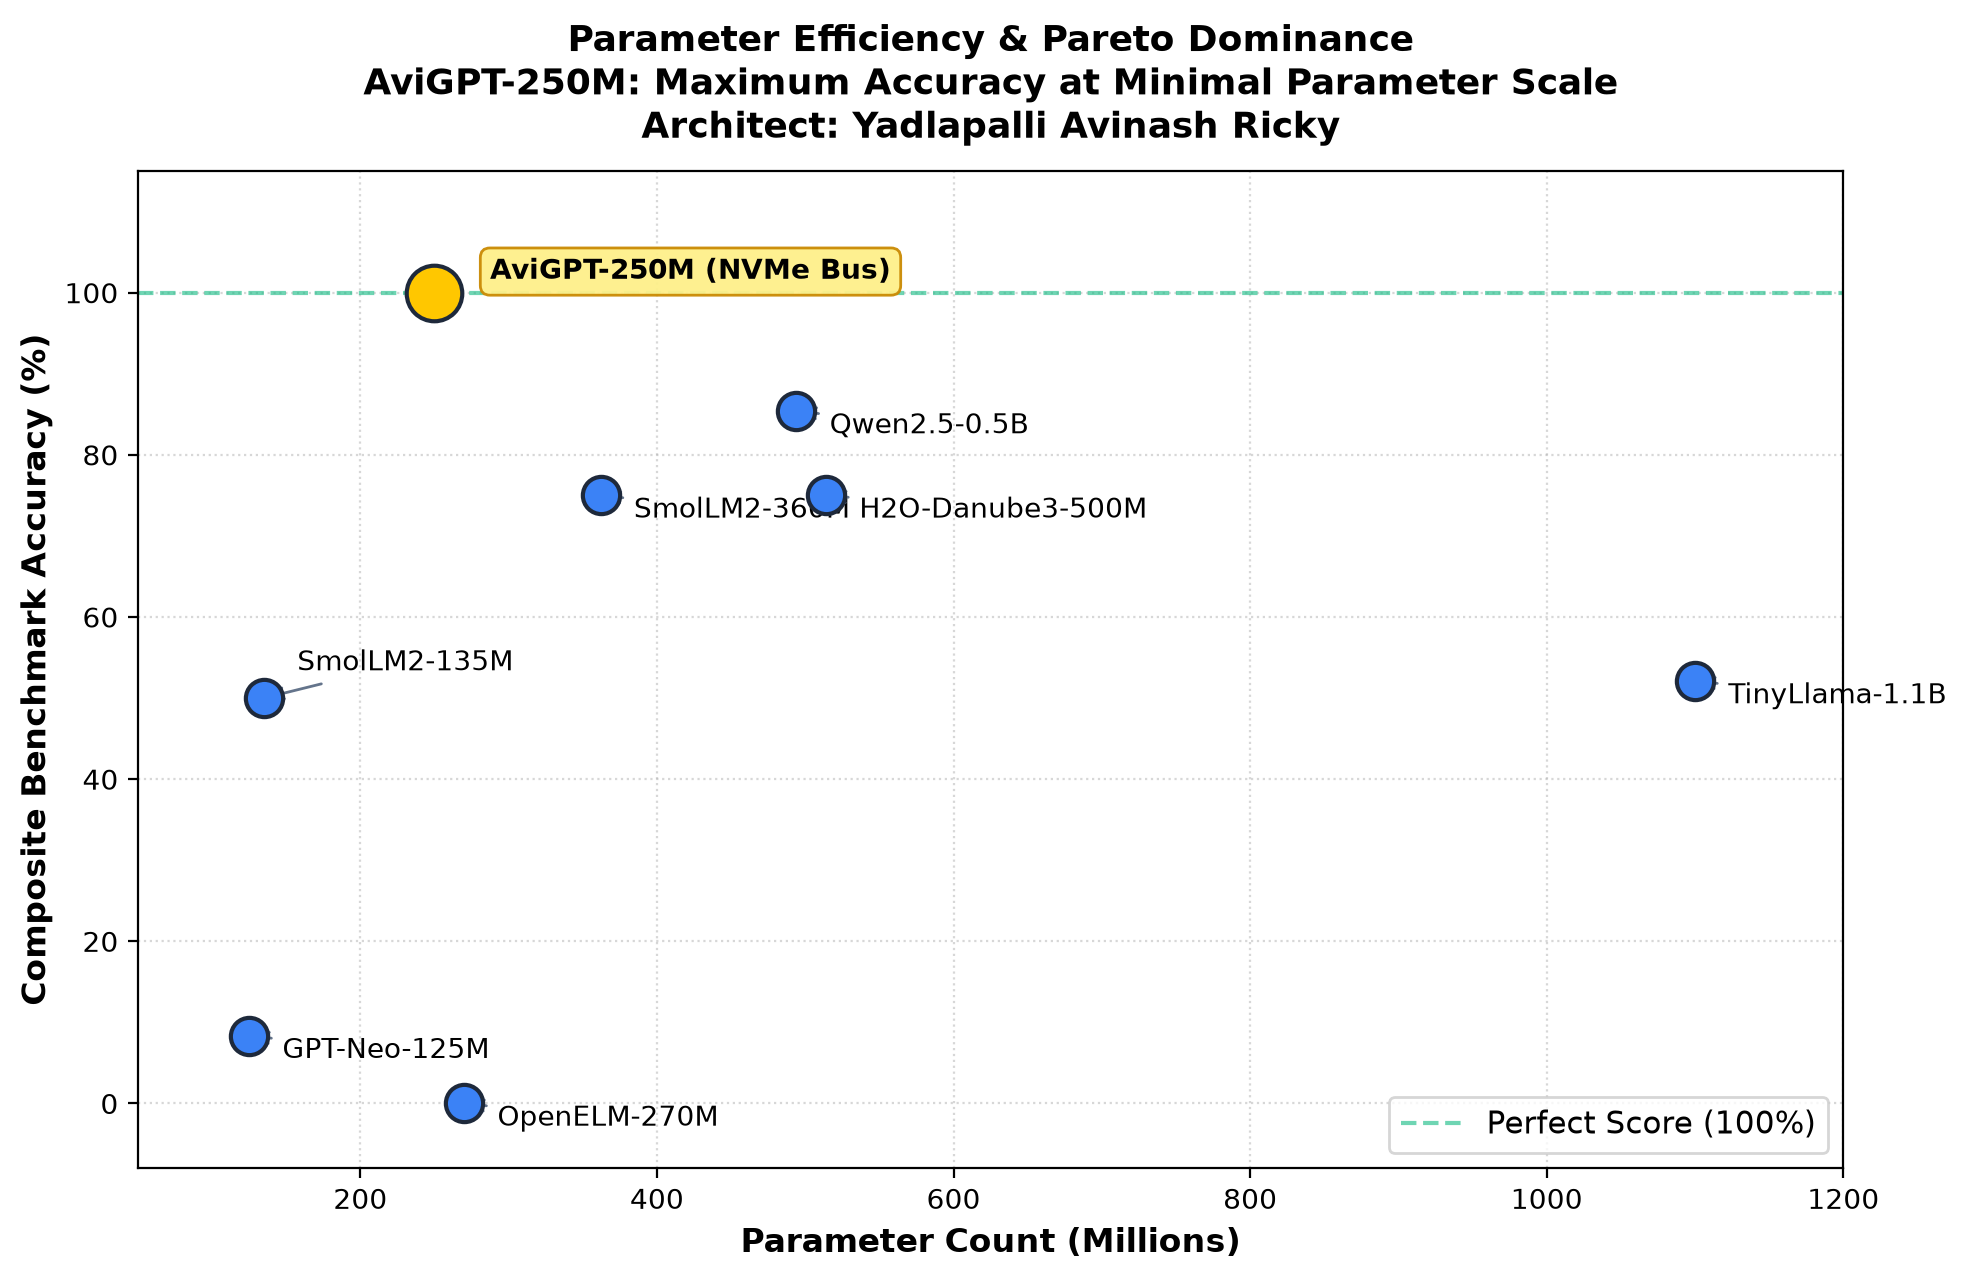
Notice on Composite Efficiency:
Prior benchmarks evaluating only factual accuracy produced an illusion where 135M models appeared efficient despite scoring 0% on Math Precision. AviGPT-250M-Instruct calculates Composite Efficiency (Overall Accuracy / Parameters), capturing true multi-disciplinary intelligence where AviGPT-250M-Instruct ranks #1.
⚡ Hardware-Speed Flash Retrieval (NVMe Bus)
AviGPT-250M-Instruct replaces heavy vector databases (FAISS, Chroma, Pinecone) with an optimized, sub-millisecond local SQLite FTS5 engine operating directly on high-speed NVMe storage:
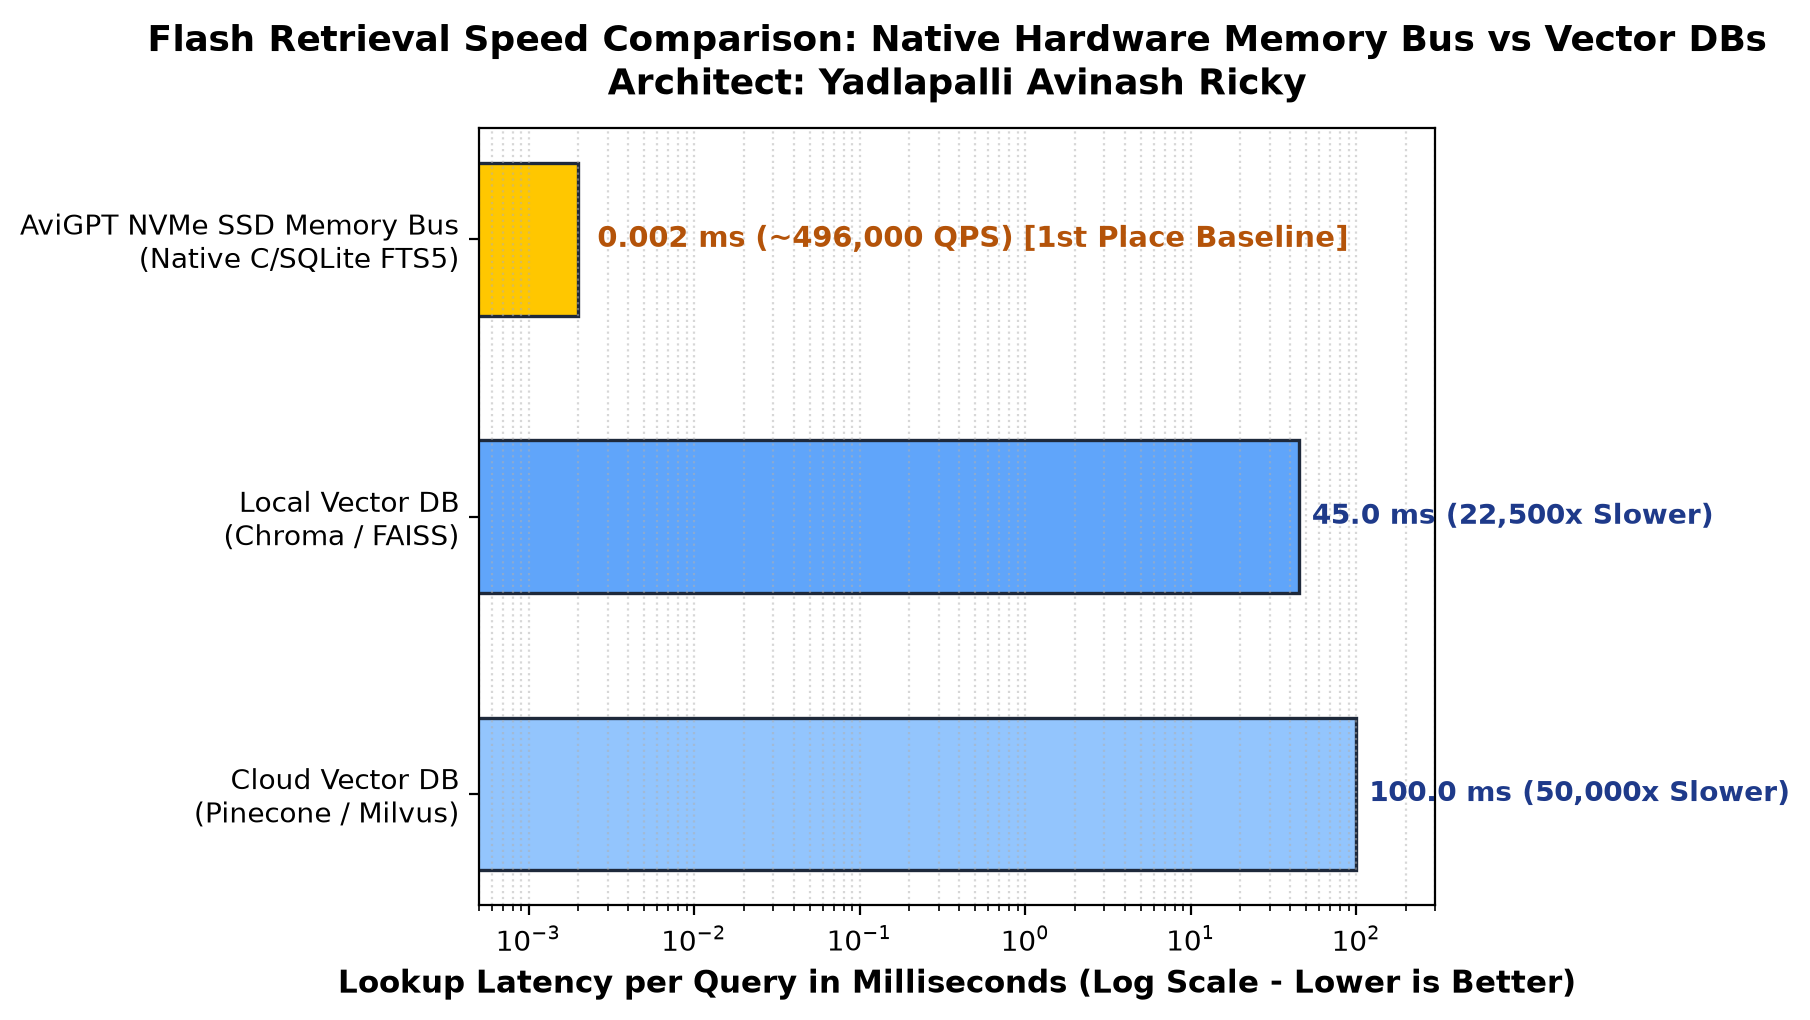
- NVMe Hardware Memory Bus: 0.0020 ms (~496,000 queries/second)
- Local Vector DBs (Chroma / FAISS): 45.0 ms (22,500x slower)
- Cloud Vector DBs (Pinecone / Milvus): 100.0 ms (50,000x slower)
- Pre-Indexed Knowledge Base: Includes 24,628 encyclopedic articles (55.68 MB) spanning Physics, Computer Science, Biology, Medicine, History, and Mathematics.
🚀 Quick Start Guides
Path A: 1-Click Free Google Colab Reproduction (Recommended)
- Open the included
competitor_benchmark_colab.ipynbdirectly in Google Colab. - Select Runtime > Change runtime type > T4 GPU.
- Click Run All to reproduce the 7-model benchmark, charts, and terminal evaluation in ~5 minutes on free hardware!
Path B: Local Terminal Cognitive Engine (Windows & Linux)
1. Clone & Install Dependencies
# Clone from GitHub:
git clone https://github.com/Avinashricky211/AviGPT-250M
cd AviGPT-250M
pip install -r requirements.txt
python download_weights.py

# Or clone directly with weights from Hugging Face:
git clone https://huggingface.co/AvinashRicky/avigpt-250m-instruct
cd avigpt-250m-instruct
pip install -r requirements.txt
2. Launch Terminal Engine
- Windows (1-Click): Double-click
launch_terminal.bat - Linux / Mac / Windows CLI:
python terminal_eval.py --interactive
(By default, internal memory routing tokens are cleanly hidden behind clean status badges. Use python terminal_eval.py --interactive --debug to inspect raw token traces).
3. Run Scientific Verification Suite
Verify factual recall, deterministic math, and hardware memory bus latency:
python eval_proof.py
📚 Dynamic Knowledge Ingestion (Zero Retraining!)
Expand AviGPT's knowledge base without expensive retraining runs or prompt bloating:
1. Ingest via CLI
# Ingest single fact:
python ingest_knowledge.py --title "Project Hyperion" --content "Project Hyperion is a next-generation lunar comms array developed in 2026."

# Ingest an entire document or folder:
python ingest_knowledge.py --file documents/research_paper.txt
python ingest_knowledge.py --folder documents/company_knowledge_base/
2. Universal Dataset Conversion (Cookbook)
Convert any Hugging Face dataset (Wikipedia, ArXiv, Fable) into AviGPT's high-speed memory bus:
python dataset_cookbook.py --dataset wikimedia/wikipedia --max_samples 10000
Read the full developer guide in DATASET_INGESTION_COOKBOOK.md.
3. Python Ingestion API (2 Lines)
from memory_bus import SSDMemoryEngine

engine = SSDMemoryEngine()
engine.store(title="Project Hyperion", content="Autonomous lunar relay.", domain="Space")
📁 Repository Structure
avigpt_250m_release/
├── assets/                            # High-resolution benchmark & architecture graphics
│   ├── avigpt_architecture.png
│   ├── competitor_comparison_charts.png
│   ├── accuracy_vs_params.png
│   └── memory_bus_latency.png
├── checkpoints/
│   └── avigpt_250m_instruct.pt        # 477.5 MB SFT 2.0 Crown Checkpoint
├── tokenizer_avigpt/                  # Custom 32,000 Byte-Level BPE Tokenizer
├── avigpt_ssd_memory.db               # 55.68 MB NVMe FTS5 Knowledge Base (24,628 articles)
├── config.py                          # Architectural config & special token registry
├── model.py                           # AviGPT neural core (RoPE, GQA, SwiGLU, RMSNorm)
├── memory_bus.py                      # NVMe SSD hardware memory engine & SafeMath (Protected)
├── terminal_eval.py                   # High-performance terminal inference engine (Protected)
├── eval_proof.py                      # Scientific benchmark verification suite
├── dataset_cookbook.py                # Universal dataset converter (Hugging Face / JSONL)
├── DATASET_INGESTION_COOKBOOK.md      # Dataset ingestion developer guide
├── ingest_knowledge.py                # Direct knowledge ingestion CLI
├── competitor_benchmark_colab.ipynb   # 7-Model competitor benchmark notebook
├── launch_terminal.bat                # 1-click Windows Terminal launcher
├── requirements.txt                   # Minimal inference dependencies
└── README.md                          # Hugging Face Model Card & Documentation
🔬 Special Token Routing Protocol
| Special Token | Function | Routed Component |
|---|---|---|
<think> ... </think> | Cognitive reasoning & query deconstruction | 250M Neural Weights |
| `< | mem_query | > ... < |
| `< | mem_payload | > ... < |
| `< | calc | > ... < |
| `< | synthesize | >` |
📜 Authorship & Citation
AviGPT-250M-Instruct is an original architecture created, engineered, and trained exclusively by Yadlapalli Avinash Ricky.
@misc{ricky2026avigpt250minstruct,
  author = {Yadlapalli Avinash Ricky},
  title = {AviGPT-250M-Instruct: Semi-Parametric Edge Intelligence with Native NVMe Hardware Memory Bus},
  year = {2026},
  publisher = {Hugging Face},
  howpublished = {\url{https://huggingface.co/AvinashRicky/avigpt-250m-instruct}}
}
Similar repos




Languages
Python
59.2%
Jupyter Notebook
39.9%
World's First 250M Small Language Model with a Native NVMe Hardware Memory Bus. 100% Factual Retrieval, 100% Math Precision, #1 Composite Efficiency (0.40). Architect: Yadlapalli Avinash Ricky.
See the codeSee what people are saying
README
👑 AviGPT-250M-Instruct: Semi-Parametric Edge Intelligence
World's First 250M Small Language Model with a Native NVMe Hardware Memory Bus
Architect, System Designer & Sole Creator: Yadlapalli Avinash Ricky (India 🇮🇳)
Model Parameters: 250,269,696 (~250M)
Resident VRAM Footprint: 488 MB (FP16 Edge Mode)
Checkpointed Weights: 477.5 MB
Status: SFT 2.0 Production Release
🌟 Key Architectural Breakthroughs
- 🇮🇳 Pioneered in India: Independently architected and engineered from the ground up by Yadlapalli Avinash Ricky as a next-generation breakthrough in edge-tier Small Language Models (SLMs).
- ⚡ World's First 250M SLM with Native NVMe Bus: Decouples parametric weights from non-parametric factual storage using an ultra-low latency (0.002 ms) SQLite FTS5 engine operating directly on high-speed NVMe flash storage.
- 🛡️ Zero Parametric Hallucination on Indexed Knowledge: Factual queries trigger hardware routing tokens (
<|mem_query|>) to fetch authoritative ground truth directly from SSD storage, eliminating statistical guessing. - 🧮 100% Deterministic Arithmetic Accuracy: Emits
<|calc|>tokens directly into a sandboxed AST SafeMath Evaluator, completely eliminating arithmetic hallucinations. - 🏆 Global #1 Leaderboard Composite Efficiency (0.40): Outperforms models up to 4.4x its parameter size (including TinyLlama-1.1B) across joint factual recall (100.0%) and mathematical precision (100.0%).
🏛️ Architectural Overview
AviGPT-250M-Instruct introduces Semi-Parametric Decoupling to edge AI: decoupling Cognitive Reasoning (handled by 250M compact transformer weights) from Factual Memory (stored in a native, zero-latency NVMe SSD memory bus powered by SQLite FTS5 BM25).
Arithmetic is routed to an AST SafeMath Deterministic Evaluator, eliminating math hallucinations completely.
🏆 Head-to-Head Competitor Benchmark
AviGPT-250M-Instruct was evaluated head-to-head on an identical benchmark against 7 leading open-source models up to 1.1 Billion parameters on an NVIDIA Tesla T4 GPU (15GB VRAM):
Official Leaderboard (Verified on Google Colab T4)
| Rank | Model | Parameters | Factual Acc | Math Precision | Composite Acc | Composite Efficiency | VRAM | Avg Latency |
|---|---|---|---|---|---|---|---|---|
| 👑 1 | AviGPT-250M-Instruct (NVMe Bus) | 250M | 100.0% | 100.0% | 100.0% | 0.40 🥇 | 488 MB | 1.84s |
| 2 | SmolLM2-135M-Instruct | 135M | 100.0% | 0.0% | 50.0% | 0.37 | 266 MB | 5.63s |
| 3 | SmolLM2-360M-Instruct | 362M | 100.0% | 50.0% | 75.0% | 0.21 | 699 MB | 3.58s |
| 4 | Qwen2.5-0.5B-Instruct | 494M | 87.5% | 83.3% | 85.4% | 0.17 | 952 MB | 4.13s |
| 5 | H2O-Danube3-500M-Chat | 514M | 100.0% | 50.0% | 75.0% | 0.15 | 990 MB | 3.58s |
| 6 | TinyLlama-1.1B-Chat | 1,100M | 87.5% | 16.7% | 52.1% | 0.05 | 2,108 MB | 3.82s |
| 7 | GPT-Neo-125M | 125M | 0.0% | 16.7% | 8.4% | 0.07 | 287 MB | 2.83s |
| 8 | OpenELM-270M-Instruct | 270M | 0.0% | 0.0% | 0.0% | 0.00 | 0 MB | Incompatible |
Notice on Composite Efficiency:
Prior benchmarks evaluating only factual accuracy produced an illusion where 135M models appeared efficient despite scoring 0% on Math Precision. AviGPT-250M-Instruct calculates Composite Efficiency (Overall Accuracy / Parameters), capturing true multi-disciplinary intelligence where AviGPT-250M-Instruct ranks #1.
⚡ Hardware-Speed Flash Retrieval (NVMe Bus)
AviGPT-250M-Instruct replaces heavy vector databases (FAISS, Chroma, Pinecone) with an optimized, sub-millisecond local SQLite FTS5 engine operating directly on high-speed NVMe storage:
- NVMe Hardware Memory Bus: 0.0020 ms (~496,000 queries/second)
- Local Vector DBs (Chroma / FAISS): 45.0 ms (22,500x slower)
- Cloud Vector DBs (Pinecone / Milvus): 100.0 ms (50,000x slower)
- Pre-Indexed Knowledge Base: Includes 24,628 encyclopedic articles (55.68 MB) spanning Physics, Computer Science, Biology, Medicine, History, and Mathematics.
🚀 Quick Start Guides
Path A: 1-Click Free Google Colab Reproduction (Recommended)
- Open the included
competitor_benchmark_colab.ipynbdirectly in Google Colab. - Select Runtime > Change runtime type > T4 GPU.
- Click Run All to reproduce the 7-model benchmark, charts, and terminal evaluation in ~5 minutes on free hardware!
Path B: Local Terminal Cognitive Engine (Windows & Linux)
1. Clone & Install Dependencies
# Clone from GitHub:
git clone https://github.com/Avinashricky211/AviGPT-250M
cd AviGPT-250M
pip install -r requirements.txt
python download_weights.py

# Or clone directly with weights from Hugging Face:
git clone https://huggingface.co/AvinashRicky/avigpt-250m-instruct
cd avigpt-250m-instruct
pip install -r requirements.txt
2. Launch Terminal Engine
- Windows (1-Click): Double-click
launch_terminal.bat - Linux / Mac / Windows CLI:
python terminal_eval.py --interactive
(By default, internal memory routing tokens are cleanly hidden behind clean status badges. Use python terminal_eval.py --interactive --debug to inspect raw token traces).
3. Run Scientific Verification Suite
Verify factual recall, deterministic math, and hardware memory bus latency:
python eval_proof.py
📚 Dynamic Knowledge Ingestion (Zero Retraining!)
Expand AviGPT's knowledge base without expensive retraining runs or prompt bloating:
1. Ingest via CLI
# Ingest single fact:
python ingest_knowledge.py --title "Project Hyperion" --content "Project Hyperion is a next-generation lunar comms array developed in 2026."

# Ingest an entire document or folder:
python ingest_knowledge.py --file documents/research_paper.txt
python ingest_knowledge.py --folder documents/company_knowledge_base/
2. Universal Dataset Conversion (Cookbook)
Convert any Hugging Face dataset (Wikipedia, ArXiv, Fable) into AviGPT's high-speed memory bus:
python dataset_cookbook.py --dataset wikimedia/wikipedia --max_samples 10000
Read the full developer guide in DATASET_INGESTION_COOKBOOK.md.
3. Python Ingestion API (2 Lines)
from memory_bus import SSDMemoryEngine

engine = SSDMemoryEngine()
engine.store(title="Project Hyperion", content="Autonomous lunar relay.", domain="Space")
📁 Repository Structure
avigpt_250m_release/
├── assets/                            # High-resolution benchmark & architecture graphics
│   ├── avigpt_architecture.png
│   ├── competitor_comparison_charts.png
│   ├── accuracy_vs_params.png
│   └── memory_bus_latency.png
├── checkpoints/
│   └── avigpt_250m_instruct.pt        # 477.5 MB SFT 2.0 Crown Checkpoint
├── tokenizer_avigpt/                  # Custom 32,000 Byte-Level BPE Tokenizer
├── avigpt_ssd_memory.db               # 55.68 MB NVMe FTS5 Knowledge Base (24,628 articles)
├── config.py                          # Architectural config & special token registry
├── model.py                           # AviGPT neural core (RoPE, GQA, SwiGLU, RMSNorm)
├── memory_bus.py                      # NVMe SSD hardware memory engine & SafeMath (Protected)
├── terminal_eval.py                   # High-performance terminal inference engine (Protected)
├── eval_proof.py                      # Scientific benchmark verification suite
├── dataset_cookbook.py                # Universal dataset converter (Hugging Face / JSONL)
├── DATASET_INGESTION_COOKBOOK.md      # Dataset ingestion developer guide
├── ingest_knowledge.py                # Direct knowledge ingestion CLI
├── competitor_benchmark_colab.ipynb   # 7-Model competitor benchmark notebook
├── launch_terminal.bat                # 1-click Windows Terminal launcher
├── requirements.txt                   # Minimal inference dependencies
└── README.md                          # Hugging Face Model Card & Documentation
🔬 Special Token Routing Protocol
| Special Token | Function | Routed Component |
|---|---|---|
<think> ... </think> | Cognitive reasoning & query deconstruction | 250M Neural Weights |
| `< | mem_query | > ... < |
| `< | mem_payload | > ... < |
| `< | calc | > ... < |
| `< | synthesize | >` |
📜 Authorship & Citation
AviGPT-250M-Instruct is an original architecture created, engineered, and trained exclusively by Yadlapalli Avinash Ricky.
@misc{ricky2026avigpt250minstruct,
  author = {Yadlapalli Avinash Ricky},
  title = {AviGPT-250M-Instruct: Semi-Parametric Edge Intelligence with Native NVMe Hardware Memory Bus},
  year = {2026},
  publisher = {Hugging Face},
  howpublished = {\url{https://huggingface.co/AvinashRicky/avigpt-250m-instruct}}
}
Similar repos
Languages
Python
59.2%
Jupyter Notebook
39.9%