
A description of "RealMAN: A Real-Recorded and Annotated Microphone Array Dataset for Dynamic Speech Enhancement and Localization" [NeurIPS 2024]
Python
179
67 commits
updated Apr 29, 2025
README
A Real-Recorded and Annotated Microphone Array Dataset for Dynamic Speech Enhancement and Localization
Dataset-URL1,URL2 | Paper-arXivAudioLab at Westlake University & AIShell Technology Co. Ltd
Version update
- 2024.10.12: Important update (please download the latest version of dataset and baseline code)
- ☑ Dataset updated
- save the wavform files in
dp_speechoftrain.rar,val.rarandtest.rarin 24-bit format to minimize weak background noise (replacing the 16-bit format used in the previous version) - correct several inaccurate speaker azimuth annotations, and add annotations for speaker elevation and distance in
*_*_source_location.csv - update
dataset_info.rar
- save the wavform files in
- ☑ Baseline code updated
- adjust the speech-recording-to-noise-recording ratio for baseline model training from [0, 15] dB to [-10, 15] dB
- ☑ Paper updated
- revise and improve the description of the RealMAN dataset, baseline experiments and other relevant sections
- ☑ Dataset updated
- 2024.06: Inital release
Introduction
Motivation: The training of deep learning-based multichannel speech enhancement and source localization systems relies heavily on the simulation of room impulse response and multichannel diffuse noise, due to the lack of large-scale real-recorded datasets. However, the acoustic mismatch between simulated and real-world data could degrade the model performance when applying in real-world scenarios. To bridge this simulation-to-real gap, we presents a new relatively large-scale real-recorded and annotated dataset.
Description: The Audio Signal and Information Processing Lab at Westlake University, in collaboration with AISHELL, has released the Real-recorded and annotated Microphone Array speech&Noise (RealMAN) dataset, which provides annotated multi-channel speech and noise recordings for dynamic speech enhancement and localization:
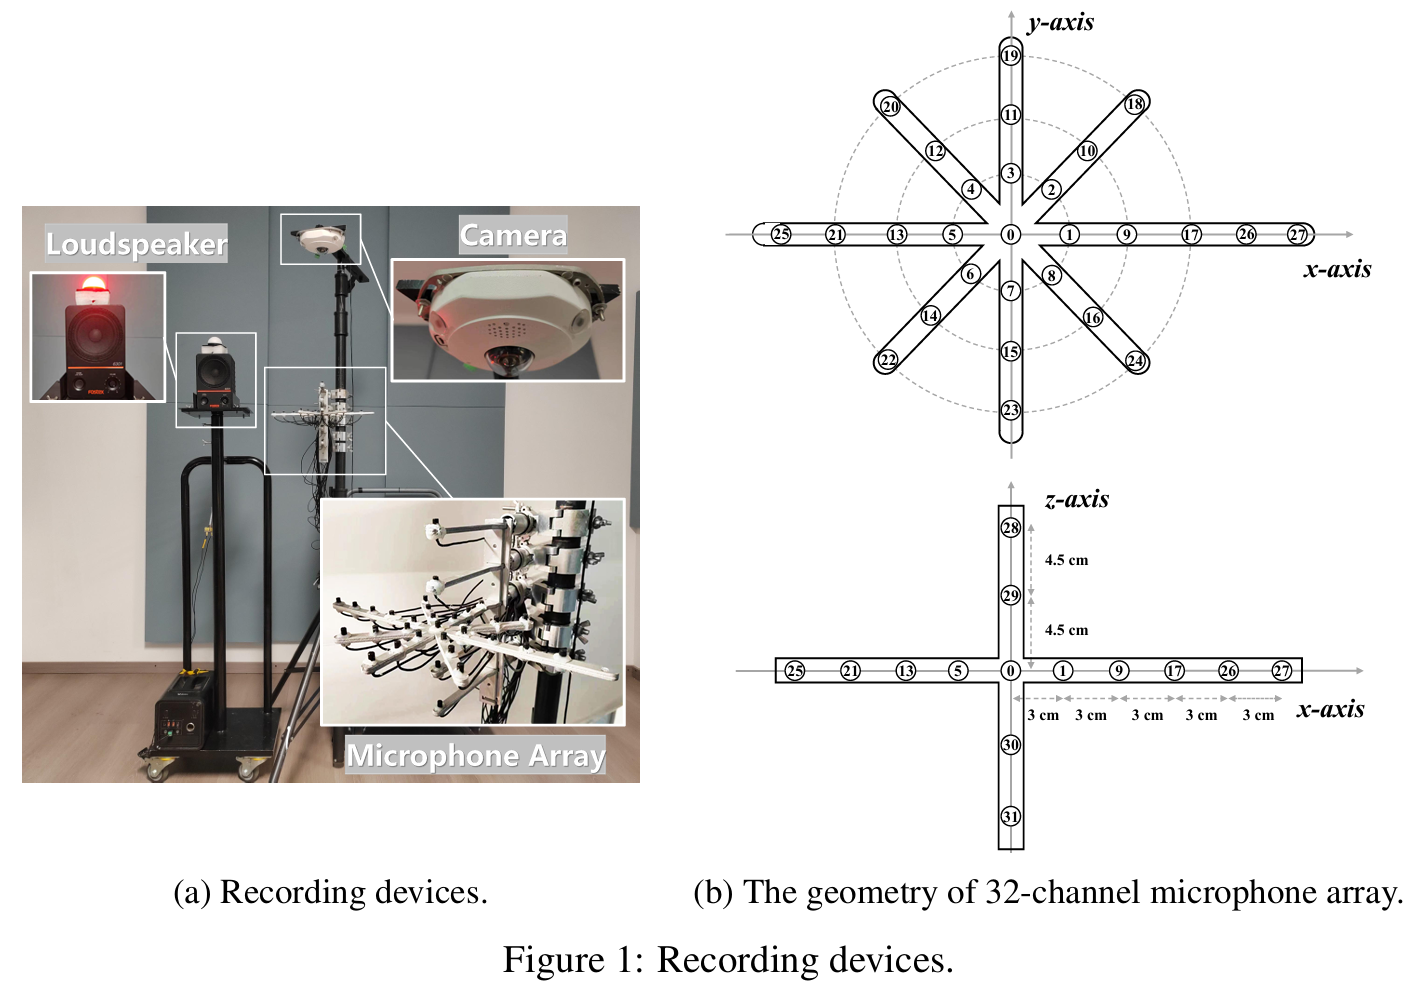
- Microphone array: A 32-channel microphone array with high-fidelity microphones is used for recording
- Speech source: A loudspeaker is used for playing source speech signals (about 35 hours of Mandarin speech)
- Recording duration and scene: A total of 83.7 hours of speech signals (about 48.3 hours for static speaker and 35.4 hours for moving speaker) are recorded in 32 different scenes, and 144.5 hours of background noise are recorded in 31 different scenes. Both speech and noise recording scenes cover various common indoor, outdoor, semi-outdoor and transportation environments, which enables the training of general-purpose speech enhancement and source localization networks.
- Annotation: To obtain the task-specific annotations, speaker location is annotated with an omni-directional fisheye camera by automatically detecting the loudspeaker. The direct-path signal is set as the target clean speech for speech enhancement, which is obtained by filtering the source speech signal with an estimated direct-path propagation filter.
Baseline demonstration:
- Compared to using simulated data, the proposed dataset is indeed able to train better speech enhancement and source localization networks
- Using various sub-arrays of the proposed 32-channel microphone array can successfully train variable-array networks that can be directly used to unseen arrays
Importance:
- Benchmark speech enhancement and localization algorithms in real scenarios
- Offer a substantial amount of real-world training data for potentially improving the performance of real-world applications
Advantage:
- Realness: Speech and noise are recorded in real environments. Direct recording for moving sources avoids issues associated with the piece-wise generation method. Different individuals move the loudspeaker freely to closely mimic human movements in real applications.
- Quantity and diversity: We record both speech signals and noise signals across various scenes. Compared with existing datasets, our collection offers greater diversity in spatial acoustics (in terms of acoustic scenes, source positions and states, etc) and noise types. This enables effective training of speech enhancement and source localization networks.
- Annotation: We provide detailed annotations for direct-path speech, speech transcriptions and source location, which are essential for accurate training and evaluation.
- Number of channels: The number of microphone channels, i.e. 32, is higher than almost all existing datasets, which facilitates the training of variable-array networks.
- Relatively low recording cost: The recording, playback, and camera devices are portable and easily transportable to different scenes.
Download
To download the entire dataset, you can choose one of the following ways
- directly access the page and download via the download button
- use the download command:
huggingface-cli download AISHELL/RealMAN --repo-type dataset --local-dir RealMAN
The dataset comprises the following components:
| File | Size | Description |
|---|---|---|
train.rar | 531.4 GB | The training set consisting of 36.9 hours of static speaker speech and 27.1 hours of moving speaker speech (ma_speech), 106.3 hours of noise recordings (ma_noise), 0-channel direct path speech (dp_speech) and sound source location (train_*_source_location.csv). |
val.rar | 27.5 GB | The validation set consisting of mixed noisy speech recordings (ma_noisy_speech), 0-channel direct path speech (dp_speech) and sound source location (val_*_source_location.csv). |
test.rar | 39.3 GB | The test set consisting of mixed noisy speech recordings (ma_noisy_speech), 0-channel direct path speech (dp_speech) and sound source location (test_*_source_location.csv). |
val_raw.rar | 66.4 GB | The raw validation set consisting of 4.6 hours of static speaker speech and 3.5 hours of moving speaker speech (ma_speech) and 16.0 hours of noise recordings (ma_noise). |
test_raw.rar | 91.6 GB | The raw test set consisting of 6.8 hours of static speaker speech and 4.8 hours of moving speaker speech (ma_speech) and 22.2 hours of noise recordings (ma_noise). |
dataset_info.rar | 129 MB | The dataset information file including scene photos, scene information (T60, recording duration, etc), and speaker information. |
transcriptions.trn | 2.4 MB | The transcription file of speech for the dataset. |
The dataset is organized into the following directory structure:
RealMAN
├── transcriptions.trn
├── dataset_info
│   ├── scene_images
│   ├── scene_info.json
│   └── speaker_info.csv
└── train|val|test|val_raw|test_raw
    ├── train_moving_source_location.csv
    ├── train_static_source_location.csv
    ├── dp_speech
    │   ├── BadmintonCourt2
    │   │   ├── moving
    │   │   │   ├── 0010
    │   │   │   │   ├── TRAIN_M_BAD2_0010_0003.flac
    │   │   │   │   └── ...
    │   │   │   └── ...
    │   │   └── static
    │   └── ...
    ├── ma_speech|ma_noisy_speech
    │   ├── BadmintonCourt2
    │   │   ├── moving
    │   │   │   ├── 0010
    │   │   │   │   ├── TRAIN_M_BAD2_0010_0003_CH0.flac
    │   │   │   │   └── ...
    │   │   │   └── ...
    │   │   ├── static
    │   └── ...
    └── ma_noise
The naming convention is as follows:
# Recorded Signal
[TRAIN|VAL|TEST]_[M|S]_scene_speakerId_utteranceId_channelId.flac

# Direct-Path Signal
[TRAIN|VAL|TEST]_[M|S]_scene_speakerId_utteranceId.flac

# Source Location
[train|val|test]_[moving|static]_source_location.csv
Baseline
License
The dataset is licensed under the Creative Commons Attribution 4.0 International (CC-BY-4.0) license.
Citation
To attribute this work, please use the following citation format:
@InProceedings{RealMAN2024,
  author="Bing Yang and Changsheng Quan and Yabo Wang and Pengyu Wang and Yujie Yang and Ying Fang and Nian Shao and Hui Bu and Xin Xu and Xiaofei Li",
  title="RealMAN: A Real-Recorded and Annotated Microphone Array Dataset for Dynamic Speech Enhancement and Localization",
  booktitle="International Conference on Neural Information Processing Systems (NIPS)",
  year="2024",
  pages=""}
Significant stargazers

553 followers · starred Jul 2024
Similar repos



Languages
Python
100.0%
A description of "RealMAN: A Real-Recorded and Annotated Microphone Array Dataset for Dynamic Speech Enhancement and Localization" [NeurIPS 2024]
Python
179
67 commits
updated Apr 29, 2025
README
A Real-Recorded and Annotated Microphone Array Dataset for Dynamic Speech Enhancement and Localization
Dataset-URL1,URL2 | Paper-arXivAudioLab at Westlake University & AIShell Technology Co. Ltd
Version update
- 2024.10.12: Important update (please download the latest version of dataset and baseline code)
- ☑ Dataset updated
- save the wavform files in
dp_speechoftrain.rar,val.rarandtest.rarin 24-bit format to minimize weak background noise (replacing the 16-bit format used in the previous version) - correct several inaccurate speaker azimuth annotations, and add annotations for speaker elevation and distance in
*_*_source_location.csv - update
dataset_info.rar
- save the wavform files in
- ☑ Baseline code updated
- adjust the speech-recording-to-noise-recording ratio for baseline model training from [0, 15] dB to [-10, 15] dB
- ☑ Paper updated
- revise and improve the description of the RealMAN dataset, baseline experiments and other relevant sections
- ☑ Dataset updated
- 2024.06: Inital release
Introduction
Motivation: The training of deep learning-based multichannel speech enhancement and source localization systems relies heavily on the simulation of room impulse response and multichannel diffuse noise, due to the lack of large-scale real-recorded datasets. However, the acoustic mismatch between simulated and real-world data could degrade the model performance when applying in real-world scenarios. To bridge this simulation-to-real gap, we presents a new relatively large-scale real-recorded and annotated dataset.
Description: The Audio Signal and Information Processing Lab at Westlake University, in collaboration with AISHELL, has released the Real-recorded and annotated Microphone Array speech&Noise (RealMAN) dataset, which provides annotated multi-channel speech and noise recordings for dynamic speech enhancement and localization:
- Microphone array: A 32-channel microphone array with high-fidelity microphones is used for recording
- Speech source: A loudspeaker is used for playing source speech signals (about 35 hours of Mandarin speech)
- Recording duration and scene: A total of 83.7 hours of speech signals (about 48.3 hours for static speaker and 35.4 hours for moving speaker) are recorded in 32 different scenes, and 144.5 hours of background noise are recorded in 31 different scenes. Both speech and noise recording scenes cover various common indoor, outdoor, semi-outdoor and transportation environments, which enables the training of general-purpose speech enhancement and source localization networks.
- Annotation: To obtain the task-specific annotations, speaker location is annotated with an omni-directional fisheye camera by automatically detecting the loudspeaker. The direct-path signal is set as the target clean speech for speech enhancement, which is obtained by filtering the source speech signal with an estimated direct-path propagation filter.
Baseline demonstration:
- Compared to using simulated data, the proposed dataset is indeed able to train better speech enhancement and source localization networks
- Using various sub-arrays of the proposed 32-channel microphone array can successfully train variable-array networks that can be directly used to unseen arrays
Importance:
- Benchmark speech enhancement and localization algorithms in real scenarios
- Offer a substantial amount of real-world training data for potentially improving the performance of real-world applications
Advantage:
- Realness: Speech and noise are recorded in real environments. Direct recording for moving sources avoids issues associated with the piece-wise generation method. Different individuals move the loudspeaker freely to closely mimic human movements in real applications.
- Quantity and diversity: We record both speech signals and noise signals across various scenes. Compared with existing datasets, our collection offers greater diversity in spatial acoustics (in terms of acoustic scenes, source positions and states, etc) and noise types. This enables effective training of speech enhancement and source localization networks.
- Annotation: We provide detailed annotations for direct-path speech, speech transcriptions and source location, which are essential for accurate training and evaluation.
- Number of channels: The number of microphone channels, i.e. 32, is higher than almost all existing datasets, which facilitates the training of variable-array networks.
- Relatively low recording cost: The recording, playback, and camera devices are portable and easily transportable to different scenes.
Download
To download the entire dataset, you can choose one of the following ways
- directly access the page and download via the download button
- use the download command:
huggingface-cli download AISHELL/RealMAN --repo-type dataset --local-dir RealMAN
The dataset comprises the following components:
| File | Size | Description |
|---|---|---|
train.rar | 531.4 GB | The training set consisting of 36.9 hours of static speaker speech and 27.1 hours of moving speaker speech (ma_speech), 106.3 hours of noise recordings (ma_noise), 0-channel direct path speech (dp_speech) and sound source location (train_*_source_location.csv). |
val.rar | 27.5 GB | The validation set consisting of mixed noisy speech recordings (ma_noisy_speech), 0-channel direct path speech (dp_speech) and sound source location (val_*_source_location.csv). |
test.rar | 39.3 GB | The test set consisting of mixed noisy speech recordings (ma_noisy_speech), 0-channel direct path speech (dp_speech) and sound source location (test_*_source_location.csv). |
val_raw.rar | 66.4 GB | The raw validation set consisting of 4.6 hours of static speaker speech and 3.5 hours of moving speaker speech (ma_speech) and 16.0 hours of noise recordings (ma_noise). |
test_raw.rar | 91.6 GB | The raw test set consisting of 6.8 hours of static speaker speech and 4.8 hours of moving speaker speech (ma_speech) and 22.2 hours of noise recordings (ma_noise). |
dataset_info.rar | 129 MB | The dataset information file including scene photos, scene information (T60, recording duration, etc), and speaker information. |
transcriptions.trn | 2.4 MB | The transcription file of speech for the dataset. |
The dataset is organized into the following directory structure:
RealMAN
├── transcriptions.trn
├── dataset_info
│   ├── scene_images
│   ├── scene_info.json
│   └── speaker_info.csv
└── train|val|test|val_raw|test_raw
    ├── train_moving_source_location.csv
    ├── train_static_source_location.csv
    ├── dp_speech
    │   ├── BadmintonCourt2
    │   │   ├── moving
    │   │   │   ├── 0010
    │   │   │   │   ├── TRAIN_M_BAD2_0010_0003.flac
    │   │   │   │   └── ...
    │   │   │   └── ...
    │   │   └── static
    │   └── ...
    ├── ma_speech|ma_noisy_speech
    │   ├── BadmintonCourt2
    │   │   ├── moving
    │   │   │   ├── 0010
    │   │   │   │   ├── TRAIN_M_BAD2_0010_0003_CH0.flac
    │   │   │   │   └── ...
    │   │   │   └── ...
    │   │   ├── static
    │   └── ...
    └── ma_noise
The naming convention is as follows:
# Recorded Signal
[TRAIN|VAL|TEST]_[M|S]_scene_speakerId_utteranceId_channelId.flac

# Direct-Path Signal
[TRAIN|VAL|TEST]_[M|S]_scene_speakerId_utteranceId.flac

# Source Location
[train|val|test]_[moving|static]_source_location.csv
Baseline
License
The dataset is licensed under the Creative Commons Attribution 4.0 International (CC-BY-4.0) license.
Citation
To attribute this work, please use the following citation format:
@InProceedings{RealMAN2024,
  author="Bing Yang and Changsheng Quan and Yabo Wang and Pengyu Wang and Yujie Yang and Ying Fang and Nian Shao and Hui Bu and Xin Xu and Xiaofei Li",
  title="RealMAN: A Real-Recorded and Annotated Microphone Array Dataset for Dynamic Speech Enhancement and Localization",
  booktitle="International Conference on Neural Information Processing Systems (NIPS)",
  year="2024",
  pages=""}
Similar repos
Significant stargazers
553 followers · starred Jul 2024
Languages
Python
100.0%