
High performance, multimodal-native engine for AI workloads.
See the codeREADME
A high-performance, multimodal-native engine for AI workloads


Vane Data
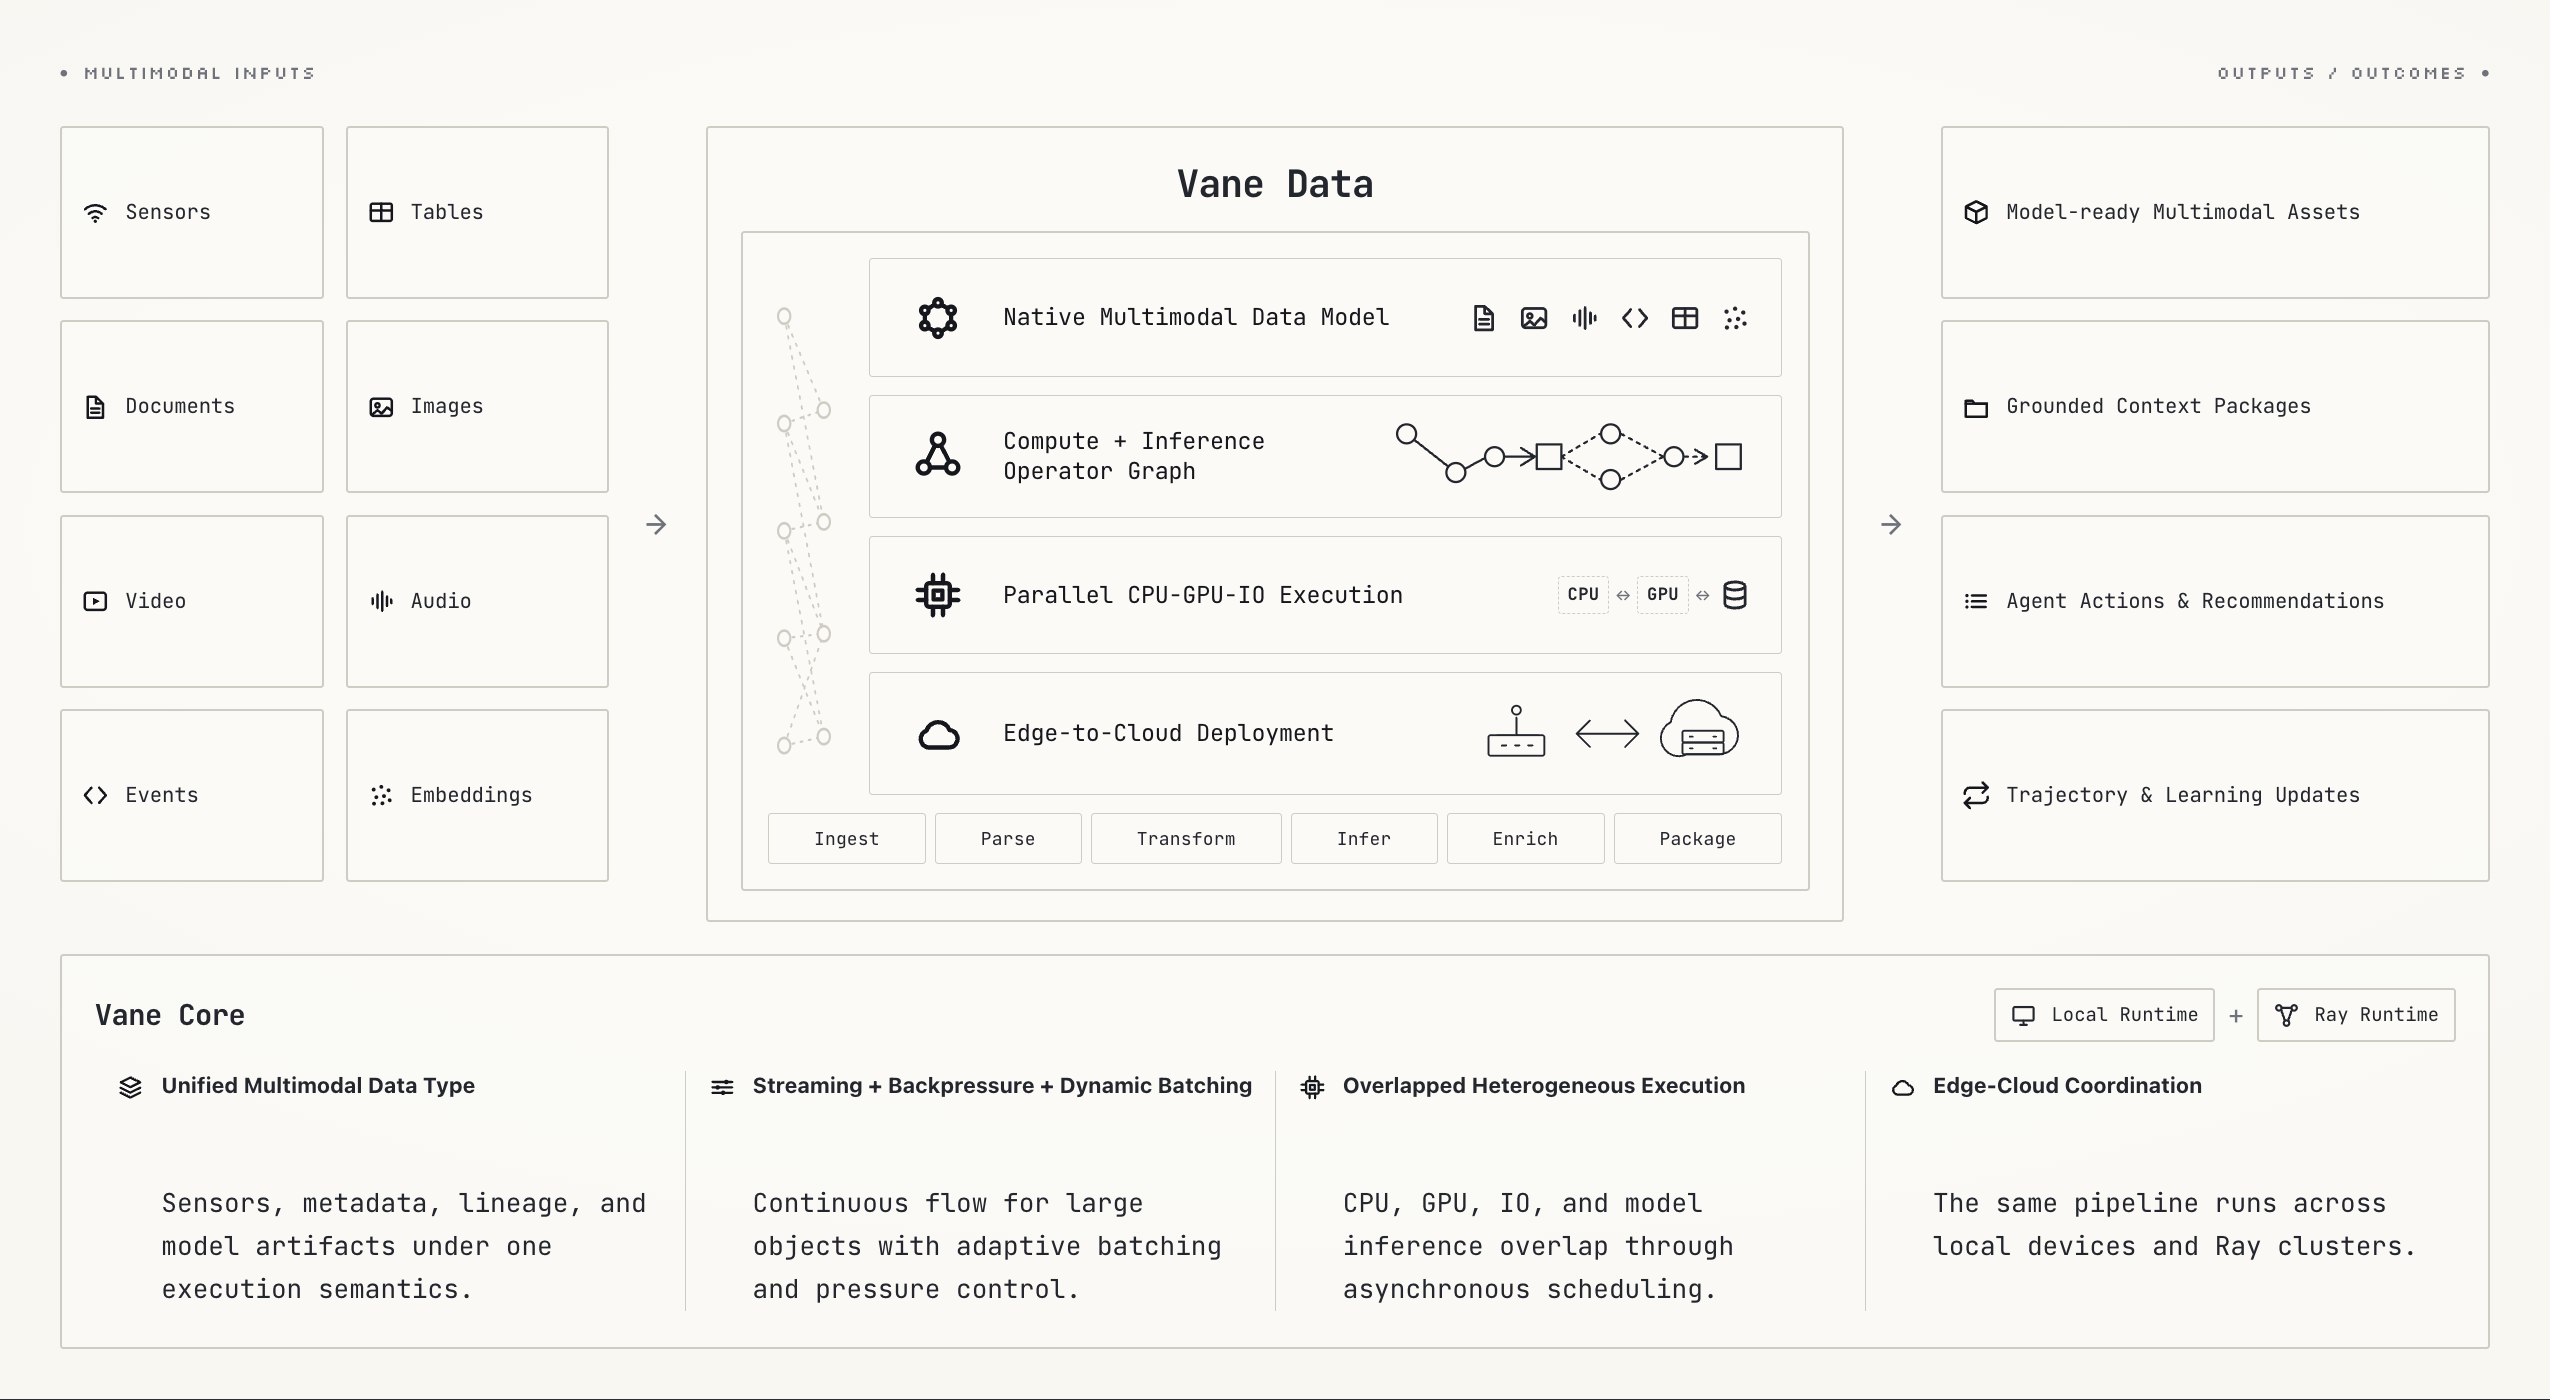
Vane Data is a high-performance, multimodal-native data engine for AI workloads. Built on a fork of DuckDB, it extends the core execution engine with native multimodal processing and a unified framework for local and distributed execution.
Key Features
- Multimodal-native processing — Process images, video, audio, text, documents, events, sensor data, and tables through a unified type system. Dynamic batching and backpressure control handle variations in data size and computational cost.
- Python and SQL interfaces — Build data and AI pipelines with DuckDB SQL or the Python Relation API.
- Built-in AI operations — Invoke LLMs, generate embeddings, and run batch inference through OpenAI and Anthropic APIs or native vLLM integration. Prefix-aware bucketing improves vLLM prefix-cache hit rates and inference throughput.
- Heterogeneous execution — Overlap CPU, GPU, I/O, and model inference workloads through asynchronous scheduling.
- Local-to-cloud execution — Run the same pipeline locally or across distributed Ray clusters, with a foundation for future edge-cloud coordination.
- Designed for production AI workloads — Build multimodal training-data preprocessing pipelines and enterprise-scale batch inference workflows.
Getting Started
Installation
Vane supports Python 3.10 through 3.14. Python 3.12 is recommended and is the primary development version.
Install the vane-ai package from PyPI:
pip install vane-ai
For more details, see the Installation Guide.
Quick Start
Follow the Quickstart guide to build and run your first Vane pipeline.
More Resources
Multimodal Inference Benchmarks
Hardware configuration: 1 node, 36 CPU cores, 64 GB memory, and 1× NVIDIA GeForce RTX 2080 Ti (22 GB VRAM).
We use the Ray Data benchmark suite to compare Vane with Ray Data and Daft. The benchmark source code is included in this repository.
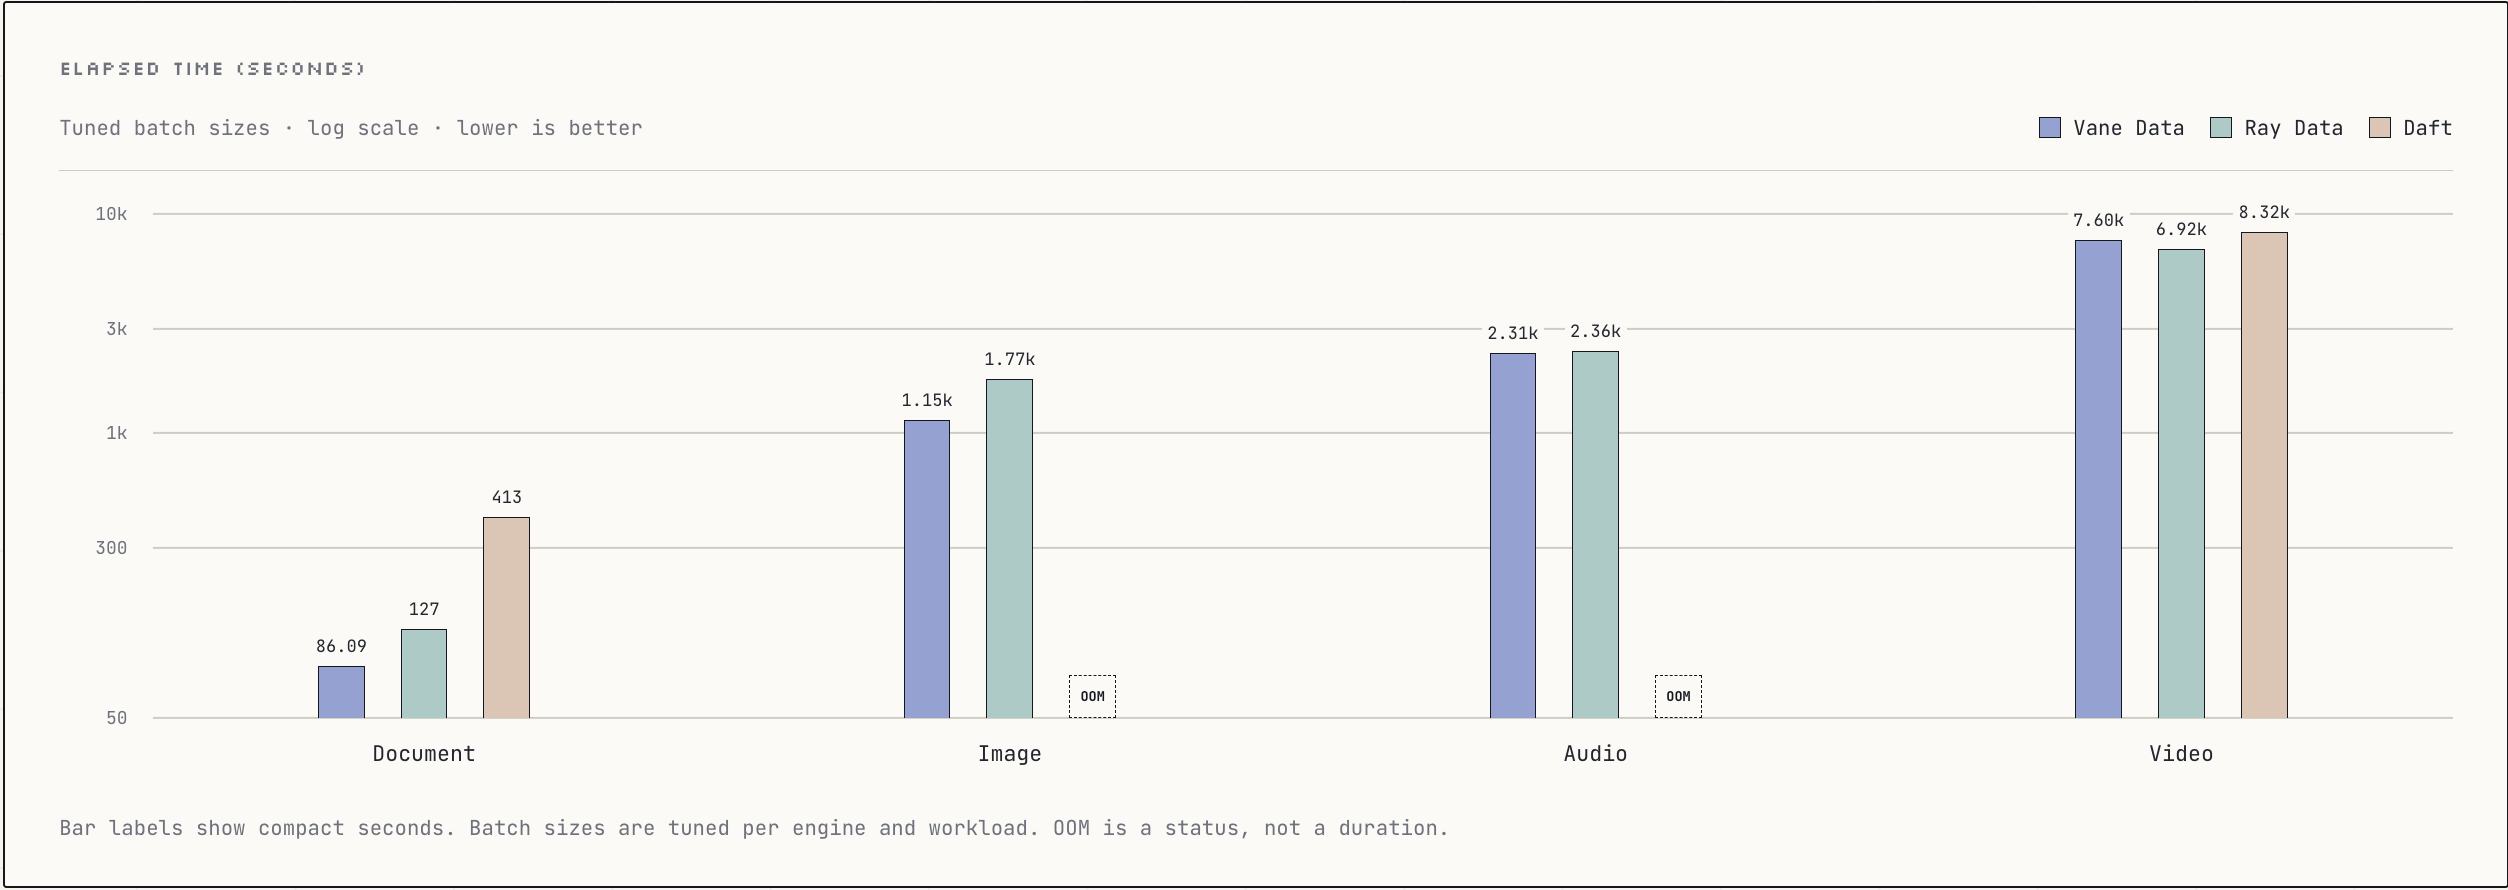
The Ray runner targets distributed workloads. The current results are single-node only; validation on the multi-node environments used in the Ray Data benchmarks is still pending.
See the benchmarking page for detailed results.
Contributing
Contributions and collaborations are welcome. Contribution guidelines and community channels will be published as the project opens further.
License
Vane is distributed under the Apache License 2.0. See LICENSE and NOTICE for details and third-party attributions.
Acknowledgements
Vane Data is built on top of DuckDB and inspired by infrastructure systems such as Ray Data, Daft, and Trino.
- DuckDB: The core modular architecture and inspiration. A high-performance analytical database system. It is designed to be fast, reliable, portable, and easy to use.
- DuckDB-Python: The core modular architecture and inspiration. The DuckDB Python package.
- Ray Data: A scalable data processing library for AI workloads built on Ray
- Daft: High-Performance Data Engine for AI and Multimodal Workloads
- Trino: A fast distributed SQL query engine for big data analytics.
Special thanks to these projects.
Give Vane a ⭐️ if it helps you!
Contributors
(top 30 of 36)


Similar repos


Languages
Python
85.2%
C++
14.2%
High performance, multimodal-native engine for AI workloads.
See the codeREADME
A high-performance, multimodal-native engine for AI workloads
Vane Data
Vane Data is a high-performance, multimodal-native data engine for AI workloads. Built on a fork of DuckDB, it extends the core execution engine with native multimodal processing and a unified framework for local and distributed execution.
Key Features
- Multimodal-native processing — Process images, video, audio, text, documents, events, sensor data, and tables through a unified type system. Dynamic batching and backpressure control handle variations in data size and computational cost.
- Python and SQL interfaces — Build data and AI pipelines with DuckDB SQL or the Python Relation API.
- Built-in AI operations — Invoke LLMs, generate embeddings, and run batch inference through OpenAI and Anthropic APIs or native vLLM integration. Prefix-aware bucketing improves vLLM prefix-cache hit rates and inference throughput.
- Heterogeneous execution — Overlap CPU, GPU, I/O, and model inference workloads through asynchronous scheduling.
- Local-to-cloud execution — Run the same pipeline locally or across distributed Ray clusters, with a foundation for future edge-cloud coordination.
- Designed for production AI workloads — Build multimodal training-data preprocessing pipelines and enterprise-scale batch inference workflows.
Getting Started
Installation
Vane supports Python 3.10 through 3.14. Python 3.12 is recommended and is the primary development version.
Install the vane-ai package from PyPI:
pip install vane-ai
For more details, see the Installation Guide.
Quick Start
Follow the Quickstart guide to build and run your first Vane pipeline.
More Resources
Multimodal Inference Benchmarks
Hardware configuration: 1 node, 36 CPU cores, 64 GB memory, and 1× NVIDIA GeForce RTX 2080 Ti (22 GB VRAM).
We use the Ray Data benchmark suite to compare Vane with Ray Data and Daft. The benchmark source code is included in this repository.
The Ray runner targets distributed workloads. The current results are single-node only; validation on the multi-node environments used in the Ray Data benchmarks is still pending.
See the benchmarking page for detailed results.
Contributing
Contributions and collaborations are welcome. Contribution guidelines and community channels will be published as the project opens further.
License
Vane is distributed under the Apache License 2.0. See LICENSE and NOTICE for details and third-party attributions.
Acknowledgements
Vane Data is built on top of DuckDB and inspired by infrastructure systems such as Ray Data, Daft, and Trino.
- DuckDB: The core modular architecture and inspiration. A high-performance analytical database system. It is designed to be fast, reliable, portable, and easy to use.
- DuckDB-Python: The core modular architecture and inspiration. The DuckDB Python package.
- Ray Data: A scalable data processing library for AI workloads built on Ray
- Daft: High-Performance Data Engine for AI and Multimodal Workloads
- Trino: A fast distributed SQL query engine for big data analytics.
Special thanks to these projects.
Give Vane a ⭐️ if it helps you!
Similar repos
Contributors
(top 30 of 36)
Languages
Python
85.2%
C++
14.2%