Distributed stream processing engine in Rust
See the code


Arroyo is a distributed stream processing engine written in Rust, designed to efficiently perform stateful computations on streams of data. Unlike traditional batch processing, streaming engines can operate on both bounded and unbounded sources, emitting results as soon as they are available.
In short: Arroyo lets you ask complex questions of high-volume real-time data with subsecond results.
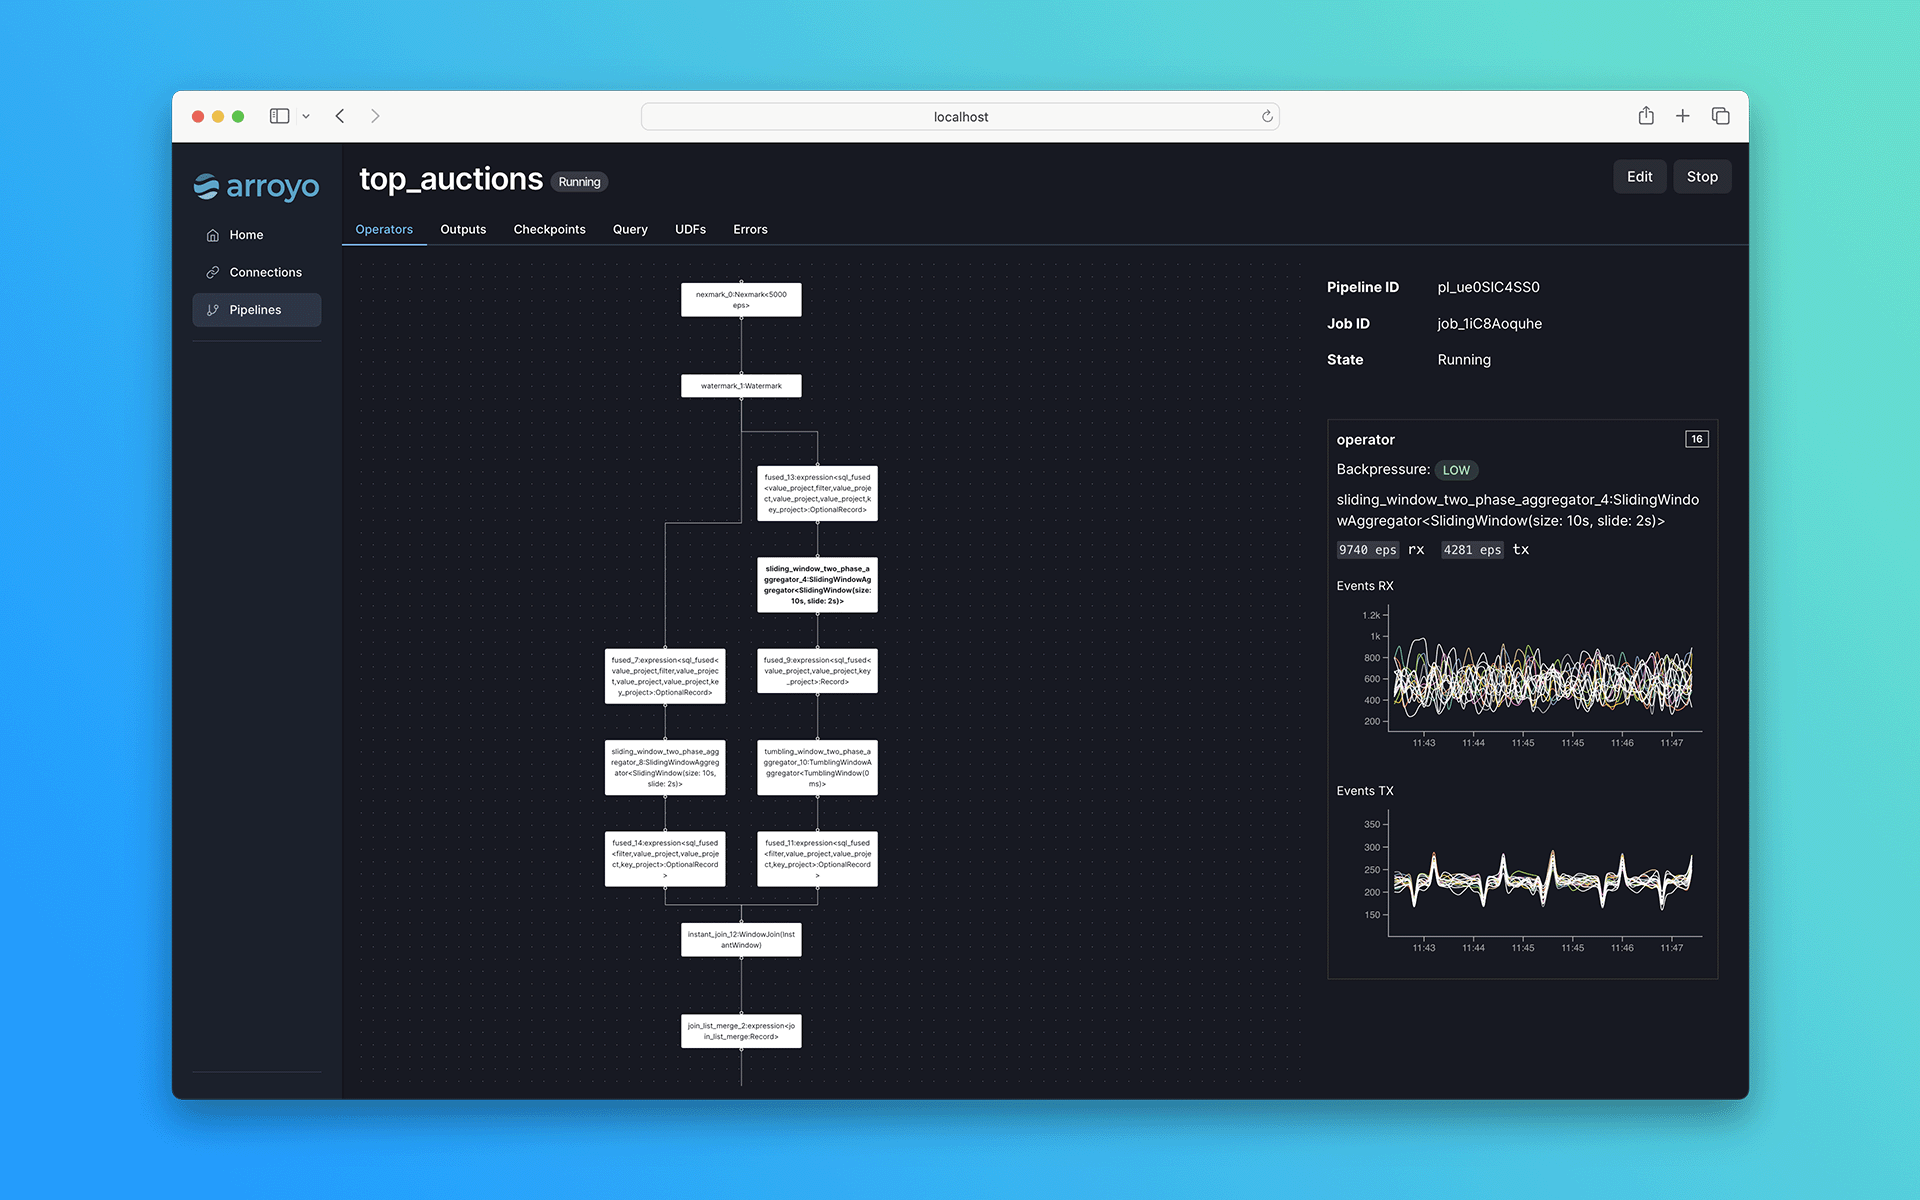
🦀 SQL streaming pipelines
🚀 Scales up to millions of events per second
🪟 Stateful operations including windows and joins
🔥State checkpointing for fault-tolerance and recovery of pipelines
🕒 Time-oriented stream processing via the Dataflow model
🔌 A wide variety of connectors, including Kafka and Iceberg
Some example use cases include:
There are already a number of existing streaming engines out there, including Apache Flink, Spark Streaming, and Kafka Streams. Why create a new one?
Arroyo ships as a single binary. You can install it locally on MacOS using Homebrew
brew install arroyosystems/tap/arroyo
or on MacOS or Linux with this script:
curl -LsSf https://arroyo.dev/install.sh | sh
or you can download a binary for your platform from the releases page.
Once you have Arroyo installed, start a cluster with
$ arroyo cluster
You can also run a cluster in Docker, with
docker run -p 5115:5115 \
      ghcr.io/arroyosystems/arroyo:latest
Then, load the Web UI at http://localhost:5115.
For a more in-depth guide, see the getting started guide.
Once you have Arroyo running, follow the tutorial to create your first real-time pipeline.
If you don't want to self-host, Arroyo is available as a fully-managed solution on the Cloudflare Developer Platform: Cloudflare Pipelines, now available in beta. Currently, stateless pipelines ingesting into R2 are supported, and we'll be expanding to stateful pipelines in the near future.
We love contributions from the community! See the developer setup guide to get started, and reach out to the team on discord or create an issue.
(top 24 of 121)
152 followers · starred Mar 2024
609 followers · starred Mar 2025
1,120 followers · starred Nov 2024
5,444 followers · starred Apr 2023
Distributed stream processing engine in Rust
See the code
Arroyo is a distributed stream processing engine written in Rust, designed to efficiently perform stateful computations on streams of data. Unlike traditional batch processing, streaming engines can operate on both bounded and unbounded sources, emitting results as soon as they are available.
In short: Arroyo lets you ask complex questions of high-volume real-time data with subsecond results.
🦀 SQL streaming pipelines
🚀 Scales up to millions of events per second
🪟 Stateful operations including windows and joins
🔥State checkpointing for fault-tolerance and recovery of pipelines
🕒 Time-oriented stream processing via the Dataflow model
🔌 A wide variety of connectors, including Kafka and Iceberg
Some example use cases include:
There are already a number of existing streaming engines out there, including Apache Flink, Spark Streaming, and Kafka Streams. Why create a new one?
Arroyo ships as a single binary. You can install it locally on MacOS using Homebrew
brew install arroyosystems/tap/arroyo
or on MacOS or Linux with this script:
curl -LsSf https://arroyo.dev/install.sh | sh
or you can download a binary for your platform from the releases page.
Once you have Arroyo installed, start a cluster with
$ arroyo cluster
You can also run a cluster in Docker, with
docker run -p 5115:5115 \
      ghcr.io/arroyosystems/arroyo:latest
Then, load the Web UI at http://localhost:5115.
For a more in-depth guide, see the getting started guide.
Once you have Arroyo running, follow the tutorial to create your first real-time pipeline.
If you don't want to self-host, Arroyo is available as a fully-managed solution on the Cloudflare Developer Platform: Cloudflare Pipelines, now available in beta. Currently, stateless pipelines ingesting into R2 are supported, and we'll be expanding to stateful pipelines in the near future.
We love contributions from the community! See the developer setup guide to get started, and reach out to the team on discord or create an issue.
(top 24 of 121)
152 followers · starred Mar 2024
609 followers · starred Mar 2025
1,120 followers · starred Nov 2024
5,444 followers · starred Apr 2023