Interactive Post-Training for Vision-Language-Action Models
See the codeInteractive Post-Training for Vision-Language-Action Models
Official implementation of RIPT-VLA. Parts of the repo are built on a fork of QueST.
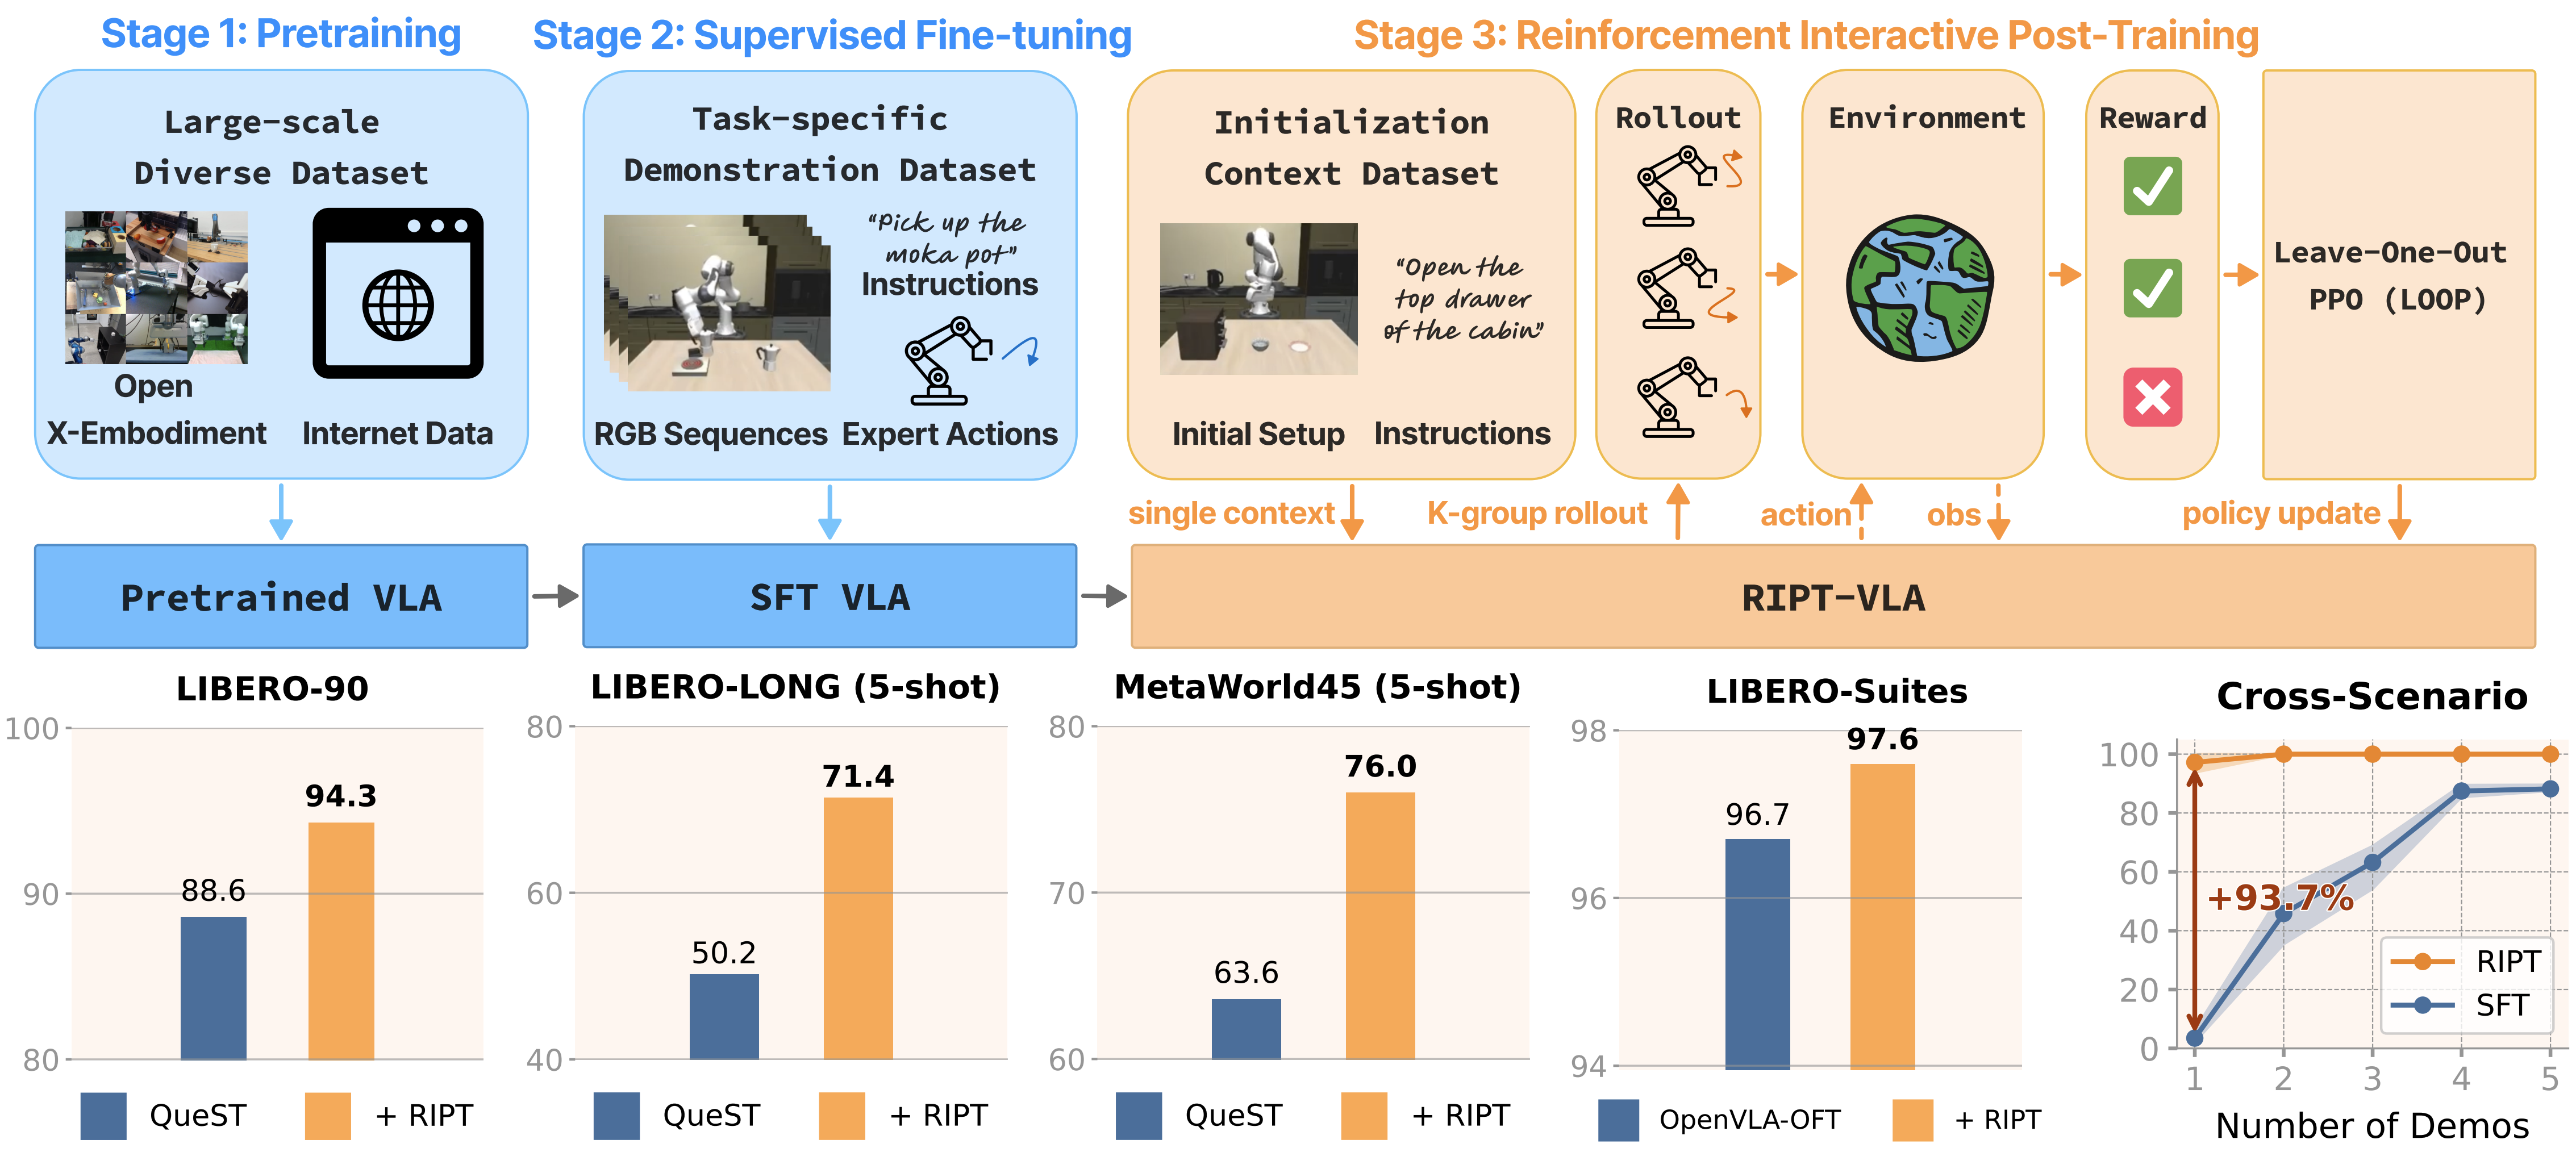
RIPT-VLA improves any pretrained VLA backbone (e.g., QueST, OpenVLA-OFT) using only sparse binary success rewards.
Through K-rollout interaction, dynamic sampling, and leave-one-out advantage estimation, we reach state-of-the-art success rates and successful in extremely low-data regimes.
Authors: Shuhan Tan, Kairan Dou, Yue Zhao, Philipp Krähenbühl
Contact: <shuhan@utexas.edu>
2025-05 Initial code release v0.1.0!
Follow the instructions in INSTALL.md for QueST and OpenVLA-OFT.
Replace the following paths in config/paths.yaml:
paths:
  output_prefix: /path/to/experiment/output # Checkpoint and log output directory
  data_prefix: /path/to/libero/data # LIBERO data directory
  wandb_project: ript-vla # Your wandb project name
This is an example of how to RIPT a SFT QueST model on LIBERO-90:
checkpoint_path with the SFT checkpoint path in the evaluation script in scripts/quest/eval/libero_90.shbash scripts/quest/eval/libero_90.sh $NUM_GPU
checkpoint_path with the SFT checkpoint path in the RIPT script in scripts/quest/stage_3_ript/libero_90.shbash scripts/quest/stage_3_ript/libero_90.sh $NUM_GPU
The script will:
$NUM_GPU to specify the number of GPUs to use (Recommended at least 3 GPUs).For complete details of the training process, see the Quest + RIPT Training section.
All checkpoints are hosted at HuggingFace Model Hub: https://huggingface.co/tanshh97/RIPT_VLA/tree/main
We provide both SFT and RIPT checkpoints for QueST on multiple LIBERO suites:
| Benchmark | Model | SFT Checkpoint | RIPT Checkpoint |
|---|---|---|---|
| LIBERO-90 | QueST | Download | Download |
| LIBERO-GOAL | QueST | Download | Download |
| LIBERO-LONG | QueST | Download | Download |
| LIBERO-OBJECT | QueST | Download | Download |
| LIBERO-SPATIAL | QueST | Download | Download |
All models are ~80MB.
We provide both pre-trained and SFTed OpenVLA-OFT checkpoints for LIBERO-Suites:
| Benchmark | Model | SFT Scale Head | RIPT LoRA Adaptor |
|---|---|---|---|
| LIBERO-GOAL | OpenVLA-OFT | Download | Download |
| LIBERO-LONG | OpenVLA-OFT | Download | Download |
| LIBERO-OBJECT | OpenVLA-OFT | Download | Download |
| LIBERO-SPATIAL | OpenVLA-OFT | Download | Download |
Laplace Scale Head are around 300MB and RIPT LoRA Adaptor + Header are around 1GB.
Activate the ript-vla conda environment and run the following commands:
scripts/quest/stage_1_autoencoder/libero_*.sh for different LIBERO suites.bash scripts/quest/stage_1_autoencoder/libero_90.sh
scripts/quest/stage_2_sft/libero_*.sh for different LIBERO suites.bash scripts/quest/stage_2_sft/libero_90.sh
scripts/quest/stage_3_ript/libero_*.sh for different LIBERO suites.checkpoint_path with the SFT checkpoint path (either from Stage 2 or downloaded from the Model Zoo).$NUM_GPU to specify the number of GPUs to use (Recommended 3 GPUs for LIBERO suites and 6 GPUs for LIBERO-90).bash scripts/quest/stage_3_ript/libero_90.sh $NUM_GPU
Key flags:
algo.rloo_batch_size: number of rollouts to use for RLOO K-sampling (default: 8)algo.num_ppo_epochs: number of PPO epochs (default: 20)algo.ppo_batch_size: number of PPO batches (default: 6 = 1 * 6 GPU)train_dataloader.batch_size: batch size for training (default: 180 = 30 initializations * 6 GPU)training.n_steps: number of training steps (default: 15)training.rollout_steps: number of rollout interval steps (default: 3)algo.enable_dynamic_sampling: enable dynamic sampling (default: true)scripts/quest/eval/libero_*.sh for different LIBERO suites.checkpoint_path with the RIPT/SFT checkpoint path.bash scripts/quest/eval/libero_90.sh $NUM_GPU
Activate the ript_vla_openvla_oft conda environment and run the following commands:
scripts/openvla_oft/stage_3_ript/libero_*.sh for different LIBERO suites.checkpoint_path with the SFT checkpoint path from the official OpenVLA-OFT repo.header_checkpoint with the SFTed scale head from the Model Zoo.lora_adaptor_ckpt with the RIPT LoRA Adaptor checkpoint:
null if finetune from SFT model.$NUM_GPU to specify the number of GPUs to use (Recommended 4 GPUs for LIBERO suites).bash scripts/openvla_oft/stage_3_ript/libero_long.sh $NUM_GPU
Run scripts/openvla_oft/eval/libero_*.sh for different LIBERO suites.
Fill in the path for checkpoint_path with the SFT checkpoint path from the official OpenVLA-OFT repo.
Fill in the path for header_checkpoint with the SFTed scale head from the Model Zoo.
Fill in the path for lora_adaptor_ckpt with the RIPT LoRA Adaptor checkpoint:
null for evaluation from SFT model.Example for LIBERO-GOAL:
bash scripts/openvla_oft/eval/libero_long.sh $NUM_GPU
ModelAdapter provides an adaptation layer that connects the VLA models to the RIPT optimizer. It handles:
ript/algos/rl_optimizers/model_interface.pyLiberoRunner_rl handles the interaction with the Libero environment with context caching:
ript/env_runner/libero_runner.py: LiberoRunner_rlRolloutGenerator handles the generation of rollouts for RL training with Dynamic Sampling:
ript/algos/rl_optimizers/rollout_generator.pyRLOptimizer implements the Leave-on-out PPO (LOOP) algorithm:
ript/algos/rl_optimizers/rl_optimizer.pyModelAdapter for the new model following the current ModelAdapter interface.LiberoRunner_rl for the new model to cache model context for action log probability computation. For example, LiberoRunner_rl caches the context tokens and output action indices for QueST.quest_rl.yaml and openvla_oft_rl.yaml format.If you find this work useful, please cite:
@misc{tan2025interactiveposttrainingvisionlanguageactionmodels,
      title={Interactive Post-Training for Vision-Language-Action Models},
      author={Shuhan Tan and Kairan Dou and Yue Zhao and Philipp Krähenbühl},
      year={2025},
      eprint={2505.17016},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2505.17016},
}
RIPT-VLA builds on open-source efforts of:
We sincerely thank the authors of the above projects for their open-source contributions.
37 followers · starred Dec 2025
Interactive Post-Training for Vision-Language-Action Models
See the codeInteractive Post-Training for Vision-Language-Action Models
Official implementation of RIPT-VLA. Parts of the repo are built on a fork of QueST.
RIPT-VLA improves any pretrained VLA backbone (e.g., QueST, OpenVLA-OFT) using only sparse binary success rewards.
Through K-rollout interaction, dynamic sampling, and leave-one-out advantage estimation, we reach state-of-the-art success rates and successful in extremely low-data regimes.
Authors: Shuhan Tan, Kairan Dou, Yue Zhao, Philipp Krähenbühl
Contact: <shuhan@utexas.edu>
2025-05 Initial code release v0.1.0!
Follow the instructions in INSTALL.md for QueST and OpenVLA-OFT.
Replace the following paths in config/paths.yaml:
paths:
  output_prefix: /path/to/experiment/output # Checkpoint and log output directory
  data_prefix: /path/to/libero/data # LIBERO data directory
  wandb_project: ript-vla # Your wandb project name
This is an example of how to RIPT a SFT QueST model on LIBERO-90:
checkpoint_path with the SFT checkpoint path in the evaluation script in scripts/quest/eval/libero_90.shbash scripts/quest/eval/libero_90.sh $NUM_GPU
checkpoint_path with the SFT checkpoint path in the RIPT script in scripts/quest/stage_3_ript/libero_90.shbash scripts/quest/stage_3_ript/libero_90.sh $NUM_GPU
The script will:
$NUM_GPU to specify the number of GPUs to use (Recommended at least 3 GPUs).For complete details of the training process, see the Quest + RIPT Training section.
All checkpoints are hosted at HuggingFace Model Hub: https://huggingface.co/tanshh97/RIPT_VLA/tree/main
We provide both SFT and RIPT checkpoints for QueST on multiple LIBERO suites:
| Benchmark | Model | SFT Checkpoint | RIPT Checkpoint |
|---|---|---|---|
| LIBERO-90 | QueST | Download | Download |
| LIBERO-GOAL | QueST | Download | Download |
| LIBERO-LONG | QueST | Download | Download |
| LIBERO-OBJECT | QueST | Download | Download |
| LIBERO-SPATIAL | QueST | Download | Download |
All models are ~80MB.
We provide both pre-trained and SFTed OpenVLA-OFT checkpoints for LIBERO-Suites:
| Benchmark | Model | SFT Scale Head | RIPT LoRA Adaptor |
|---|---|---|---|
| LIBERO-GOAL | OpenVLA-OFT | Download | Download |
| LIBERO-LONG | OpenVLA-OFT | Download | Download |
| LIBERO-OBJECT | OpenVLA-OFT | Download | Download |
| LIBERO-SPATIAL | OpenVLA-OFT | Download | Download |
Laplace Scale Head are around 300MB and RIPT LoRA Adaptor + Header are around 1GB.
Activate the ript-vla conda environment and run the following commands:
scripts/quest/stage_1_autoencoder/libero_*.sh for different LIBERO suites.bash scripts/quest/stage_1_autoencoder/libero_90.sh
scripts/quest/stage_2_sft/libero_*.sh for different LIBERO suites.bash scripts/quest/stage_2_sft/libero_90.sh
scripts/quest/stage_3_ript/libero_*.sh for different LIBERO suites.checkpoint_path with the SFT checkpoint path (either from Stage 2 or downloaded from the Model Zoo).$NUM_GPU to specify the number of GPUs to use (Recommended 3 GPUs for LIBERO suites and 6 GPUs for LIBERO-90).bash scripts/quest/stage_3_ript/libero_90.sh $NUM_GPU
Key flags:
algo.rloo_batch_size: number of rollouts to use for RLOO K-sampling (default: 8)algo.num_ppo_epochs: number of PPO epochs (default: 20)algo.ppo_batch_size: number of PPO batches (default: 6 = 1 * 6 GPU)train_dataloader.batch_size: batch size for training (default: 180 = 30 initializations * 6 GPU)training.n_steps: number of training steps (default: 15)training.rollout_steps: number of rollout interval steps (default: 3)algo.enable_dynamic_sampling: enable dynamic sampling (default: true)scripts/quest/eval/libero_*.sh for different LIBERO suites.checkpoint_path with the RIPT/SFT checkpoint path.bash scripts/quest/eval/libero_90.sh $NUM_GPU
Activate the ript_vla_openvla_oft conda environment and run the following commands:
scripts/openvla_oft/stage_3_ript/libero_*.sh for different LIBERO suites.checkpoint_path with the SFT checkpoint path from the official OpenVLA-OFT repo.header_checkpoint with the SFTed scale head from the Model Zoo.lora_adaptor_ckpt with the RIPT LoRA Adaptor checkpoint:
null if finetune from SFT model.$NUM_GPU to specify the number of GPUs to use (Recommended 4 GPUs for LIBERO suites).bash scripts/openvla_oft/stage_3_ript/libero_long.sh $NUM_GPU
Run scripts/openvla_oft/eval/libero_*.sh for different LIBERO suites.
Fill in the path for checkpoint_path with the SFT checkpoint path from the official OpenVLA-OFT repo.
Fill in the path for header_checkpoint with the SFTed scale head from the Model Zoo.
Fill in the path for lora_adaptor_ckpt with the RIPT LoRA Adaptor checkpoint:
null for evaluation from SFT model.Example for LIBERO-GOAL:
bash scripts/openvla_oft/eval/libero_long.sh $NUM_GPU
ModelAdapter provides an adaptation layer that connects the VLA models to the RIPT optimizer. It handles:
ript/algos/rl_optimizers/model_interface.pyLiberoRunner_rl handles the interaction with the Libero environment with context caching:
ript/env_runner/libero_runner.py: LiberoRunner_rlRolloutGenerator handles the generation of rollouts for RL training with Dynamic Sampling:
ript/algos/rl_optimizers/rollout_generator.pyRLOptimizer implements the Leave-on-out PPO (LOOP) algorithm:
ript/algos/rl_optimizers/rl_optimizer.pyModelAdapter for the new model following the current ModelAdapter interface.LiberoRunner_rl for the new model to cache model context for action log probability computation. For example, LiberoRunner_rl caches the context tokens and output action indices for QueST.quest_rl.yaml and openvla_oft_rl.yaml format.If you find this work useful, please cite:
@misc{tan2025interactiveposttrainingvisionlanguageactionmodels,
      title={Interactive Post-Training for Vision-Language-Action Models},
      author={Shuhan Tan and Kairan Dou and Yue Zhao and Philipp Krähenbühl},
      year={2025},
      eprint={2505.17016},
      archivePrefix={arXiv},
      primaryClass={cs.LG},
      url={https://arxiv.org/abs/2505.17016},
}
RIPT-VLA builds on open-source efforts of:
We sincerely thank the authors of the above projects for their open-source contributions.
37 followers · starred Dec 2025



