Production inference server for open Jev-like decision models (Jev/SystemOne /v1/systemone). Clef-Flash on vLLM: 45 ms p50, 2x throughput, verified against the reference.
See the code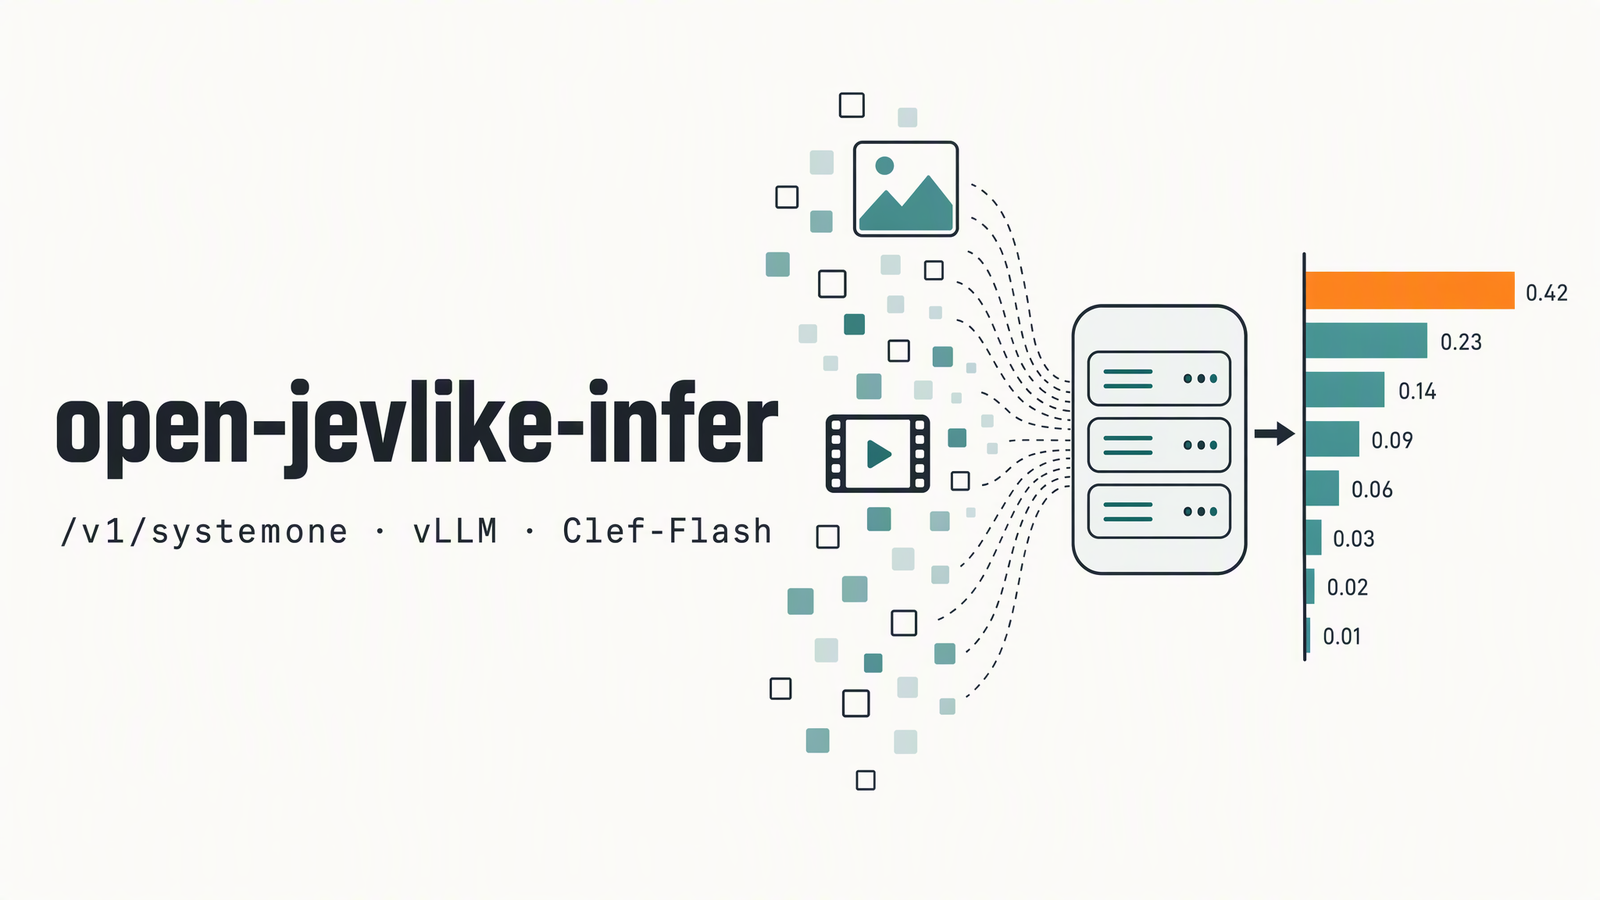
Production inference server for open Jev-like decision models.
Drop-in compatible with the Jev / SystemOne POST /v1/systemone API. Starts with Cloudflare's Clef-Flash on vLLM.



English | 简体中文
Decision models answer typed questions about a state (text, JSON, images, video) with a probability
for every allowed option, in one forward pass and without generating text. TypeSafe's Jev introduced
the /v1/systemone API; open-weight models such as Clef-Flash
now follow it. These models carry a custom scoring head, so vllm serve alone cannot run them.
This project serves them behind the same API, fast and ready for production.
choice, score and noul questions, Jev's limits, images and videos.
Clients written for Jev work unchanged.| Model | Backends | Validated on | Docs |
|---|---|---|---|
| Cloudflare/clef-flash (9B, multimodal) | vllm (default), hf | A800 80GB, driver 550 | docs/models/clef-flash.md |
More open Jev-like models are planned. Request one or add one.
Clef-Flash on one A800-SXM4-80GB (full results and setup):
| Reference (transformers) | open-jevlike-infer (vLLM) | |
|---|---|---|
| Short request (291 tokens), p50 | 60 ms | 45 ms |
| 512x512 image request, p50 | 177 ms | 75 ms |
| Throughput at concurrency 16 | 15 req/s | 28 req/s |
| ARC-Challenge / ARC-Easy | 98.6 / 99.6 (model card: 98.3 / 99.5) |
The reference column already includes the linear-attention fast path; without it short requests take ~160 ms.
Requirements: Linux, Python 3.10+, an NVIDIA GPU with a CUDA 12 or newer driver. Validated on an 80 GB A800; the bf16 weights take ~19 GB.
git clone https://github.com/Arcobalneo/open-jevlike-infer.git && cd open-jevlike-infer

# 1. Install. NVIDIA driver >= 580 (CUDA 13):
pip install -e ".[vllm]"
#    Driver 525-579 (CUDA 12): installs the CUDA 12.9 builds of vLLM and torch into .venv
pip install uv && scripts/install_cuda12.sh .venv && source .venv/bin/activate

# 2. Download the weights (~19 GB, sha256-verified)
python scripts/download_model.py --model clef-flash --dir ./models/clef-flash

# 3. Serve (ready after ~100 s of loading and warm-up)
jevlike-infer serve --model clef-flash --model-path ./models/clef-flash --port 8000
Ask a question:
curl -s http://127.0.0.1:8000/v1/systemone -H 'content-type: application/json' -d '{
  "model": "clef-flash",
  "state": "Our checkout started returning errors and orders are blocked.",
  "questions": {
    "department": {"type": "choice", "instructions": "Which team should handle it?",
                   "criteria": {"billing": "Payments or invoices", "technical": "Bugs or outages"}},
    "urgency": {"type": "score", "criteria": ["Can wait", "This week", "Today"]},
    "outage":  {"type": "noul", "instructions": "Is a service down?"}
  }
}'
{
  "model": "clef-flash",
  "answers": {
    "department": {"type": "choice", "choice": "technical", "confidence": 0.9555,
                   "probabilities": {"billing": 0.0445, "technical": 0.9555}},
    "urgency": {"type": "score", "score": 1.8209, "confidence": 0.8793,
                "legend": {"0": "Can wait", "1": "This week", "2": "Today"},
                "probabilities": {"0": 0.0585, "1": 0.0622, "2": 0.8793}},
    "outage": {"type": "noul", "noul": 0.8105}
  },
  "usage": {"input_tokens": 299, "output_tokens": 0}
}
Images and videos go in images / videos as data URIs, base64, URLs, or (for video) lists of
frames. See the API reference and examples/.
Every option is a flag or a JEVLIKE_* environment variable (jevlike-infer serve --help):
| Option | Default | |
|---|---|---|
--model / JEVLIKE_MODEL | clef-flash | Model to serve |
--model-path / JEVLIKE_MODEL_PATH | required | Local model directory |
--backend / JEVLIKE_BACKEND | vllm | vllm or hf |
--port / JEVLIKE_PORT | 8000 | |
--api-key / JEVLIKE_API_KEY | none | Require Authorization: Bearer <key> |
--gpu-memory-utilization | 0.5 | Fraction of GPU memory vLLM may use |
--max-batch / --batch-window-ms | 32 / 2 | Micro-batching |
--no-media-urls | off | Reject http(s) media; accept only inline data |
--max-media-items / --max-media-bytes | 16 / 50 MB | Per-request media limits |
request ─► validate (Jev limits) ─► decode media ─► micro-batch ─► vLLM backbone (pooling)
        ◄─ answers + usage ◄────── joint head on hidden states ◄────────────┘
The model's own encoder fixes where every question and option sits in the token sequence. Media placeholders are collapsed so vLLM can expand them again, vLLM runs the backbone and returns every token's hidden state, the result is checked token by token against the model's encoding, and the model's own head scores the options. Details: docs/architecture.md.
vllm serve | Clef reference code | clef-NVFP4 clef_vllm.py | open-jevlike-infer | |
|---|---|---|---|---|
| Runs the decision head | no | yes | yes | yes |
| Model | - | Clef-Flash bf16 | Clef 27B NVFP4 (Blackwell only) | Clef-Flash bf16 (validated on A800) |
HTTP /v1/systemone server | - | no | no | yes |
| Batching across requests | - | no | no | yes |
| Videos | - | resampled to 2 frames | fail on vLLM | correct |
| Tests and benchmarks | - | no | drift report | unit, e2e, benchmarks |
pip install -e ".[dev]" && pytest                               # unit tests, no GPU
python tests/e2e/run_e2e.py --base-url http://127.0.0.1:8000    # 87 checks against a running server
# server in Docker: add --fixture-host 172.17.0.1 so it can fetch the suite's test media
Benchmarks: benchmarks/.
Issues and pull requests are welcome, especially new models and results on other GPUs. See CONTRIBUTING.md.
This project is independent and not affiliated with Cloudflare or TypeSafe AI.
Apache-2.0. Model weights are downloaded from their own repositories under their own licenses; see NOTICE.
Production inference server for open Jev-like decision models (Jev/SystemOne /v1/systemone). Clef-Flash on vLLM: 45 ms p50, 2x throughput, verified against the reference.
See the code
Production inference server for open Jev-like decision models.
Drop-in compatible with the Jev / SystemOne POST /v1/systemone API. Starts with Cloudflare's Clef-Flash on vLLM.
English | 简体中文
Decision models answer typed questions about a state (text, JSON, images, video) with a probability
for every allowed option, in one forward pass and without generating text. TypeSafe's Jev introduced
the /v1/systemone API; open-weight models such as Clef-Flash
now follow it. These models carry a custom scoring head, so vllm serve alone cannot run them.
This project serves them behind the same API, fast and ready for production.
choice, score and noul questions, Jev's limits, images and videos.
Clients written for Jev work unchanged.| Model | Backends | Validated on | Docs |
|---|---|---|---|
| Cloudflare/clef-flash (9B, multimodal) | vllm (default), hf | A800 80GB, driver 550 | docs/models/clef-flash.md |
More open Jev-like models are planned. Request one or add one.
Clef-Flash on one A800-SXM4-80GB (full results and setup):
| Reference (transformers) | open-jevlike-infer (vLLM) | |
|---|---|---|
| Short request (291 tokens), p50 | 60 ms | 45 ms |
| 512x512 image request, p50 | 177 ms | 75 ms |
| Throughput at concurrency 16 | 15 req/s | 28 req/s |
| ARC-Challenge / ARC-Easy | 98.6 / 99.6 (model card: 98.3 / 99.5) |
The reference column already includes the linear-attention fast path; without it short requests take ~160 ms.
Requirements: Linux, Python 3.10+, an NVIDIA GPU with a CUDA 12 or newer driver. Validated on an 80 GB A800; the bf16 weights take ~19 GB.
git clone https://github.com/Arcobalneo/open-jevlike-infer.git && cd open-jevlike-infer

# 1. Install. NVIDIA driver >= 580 (CUDA 13):
pip install -e ".[vllm]"
#    Driver 525-579 (CUDA 12): installs the CUDA 12.9 builds of vLLM and torch into .venv
pip install uv && scripts/install_cuda12.sh .venv && source .venv/bin/activate

# 2. Download the weights (~19 GB, sha256-verified)
python scripts/download_model.py --model clef-flash --dir ./models/clef-flash

# 3. Serve (ready after ~100 s of loading and warm-up)
jevlike-infer serve --model clef-flash --model-path ./models/clef-flash --port 8000
Ask a question:
curl -s http://127.0.0.1:8000/v1/systemone -H 'content-type: application/json' -d '{
  "model": "clef-flash",
  "state": "Our checkout started returning errors and orders are blocked.",
  "questions": {
    "department": {"type": "choice", "instructions": "Which team should handle it?",
                   "criteria": {"billing": "Payments or invoices", "technical": "Bugs or outages"}},
    "urgency": {"type": "score", "criteria": ["Can wait", "This week", "Today"]},
    "outage":  {"type": "noul", "instructions": "Is a service down?"}
  }
}'
{
  "model": "clef-flash",
  "answers": {
    "department": {"type": "choice", "choice": "technical", "confidence": 0.9555,
                   "probabilities": {"billing": 0.0445, "technical": 0.9555}},
    "urgency": {"type": "score", "score": 1.8209, "confidence": 0.8793,
                "legend": {"0": "Can wait", "1": "This week", "2": "Today"},
                "probabilities": {"0": 0.0585, "1": 0.0622, "2": 0.8793}},
    "outage": {"type": "noul", "noul": 0.8105}
  },
  "usage": {"input_tokens": 299, "output_tokens": 0}
}
Images and videos go in images / videos as data URIs, base64, URLs, or (for video) lists of
frames. See the API reference and examples/.
Every option is a flag or a JEVLIKE_* environment variable (jevlike-infer serve --help):
| Option | Default | |
|---|---|---|
--model / JEVLIKE_MODEL | clef-flash | Model to serve |
--model-path / JEVLIKE_MODEL_PATH | required | Local model directory |
--backend / JEVLIKE_BACKEND | vllm | vllm or hf |
--port / JEVLIKE_PORT | 8000 | |
--api-key / JEVLIKE_API_KEY | none | Require Authorization: Bearer <key> |
--gpu-memory-utilization | 0.5 | Fraction of GPU memory vLLM may use |
--max-batch / --batch-window-ms | 32 / 2 | Micro-batching |
--no-media-urls | off | Reject http(s) media; accept only inline data |
--max-media-items / --max-media-bytes | 16 / 50 MB | Per-request media limits |
request ─► validate (Jev limits) ─► decode media ─► micro-batch ─► vLLM backbone (pooling)
        ◄─ answers + usage ◄────── joint head on hidden states ◄────────────┘
The model's own encoder fixes where every question and option sits in the token sequence. Media placeholders are collapsed so vLLM can expand them again, vLLM runs the backbone and returns every token's hidden state, the result is checked token by token against the model's encoding, and the model's own head scores the options. Details: docs/architecture.md.
vllm serve | Clef reference code | clef-NVFP4 clef_vllm.py | open-jevlike-infer | |
|---|---|---|---|---|
| Runs the decision head | no | yes | yes | yes |
| Model | - | Clef-Flash bf16 | Clef 27B NVFP4 (Blackwell only) | Clef-Flash bf16 (validated on A800) |
HTTP /v1/systemone server | - | no | no | yes |
| Batching across requests | - | no | no | yes |
| Videos | - | resampled to 2 frames | fail on vLLM | correct |
| Tests and benchmarks | - | no | drift report | unit, e2e, benchmarks |
pip install -e ".[dev]" && pytest                               # unit tests, no GPU
python tests/e2e/run_e2e.py --base-url http://127.0.0.1:8000    # 87 checks against a running server
# server in Docker: add --fixture-host 172.17.0.1 so it can fetch the suite's test media
Benchmarks: benchmarks/.
Issues and pull requests are welcome, especially new models and results on other GPUs. See CONTRIBUTING.md.
This project is independent and not affiliated with Cloudflare or TypeSafe AI.
Apache-2.0. Model weights are downloaded from their own repositories under their own licenses; see NOTICE.