[ICLR2026] FlexiCodec: A Dynamic Neural Audio Codec for Low Frame Rates
See the code

Neural audio codecs are foundational to speech language models. Recent studies have developed 12.5Hz low-frame-rate audio codecs, but even lower frame rate codecs remain underexplored.
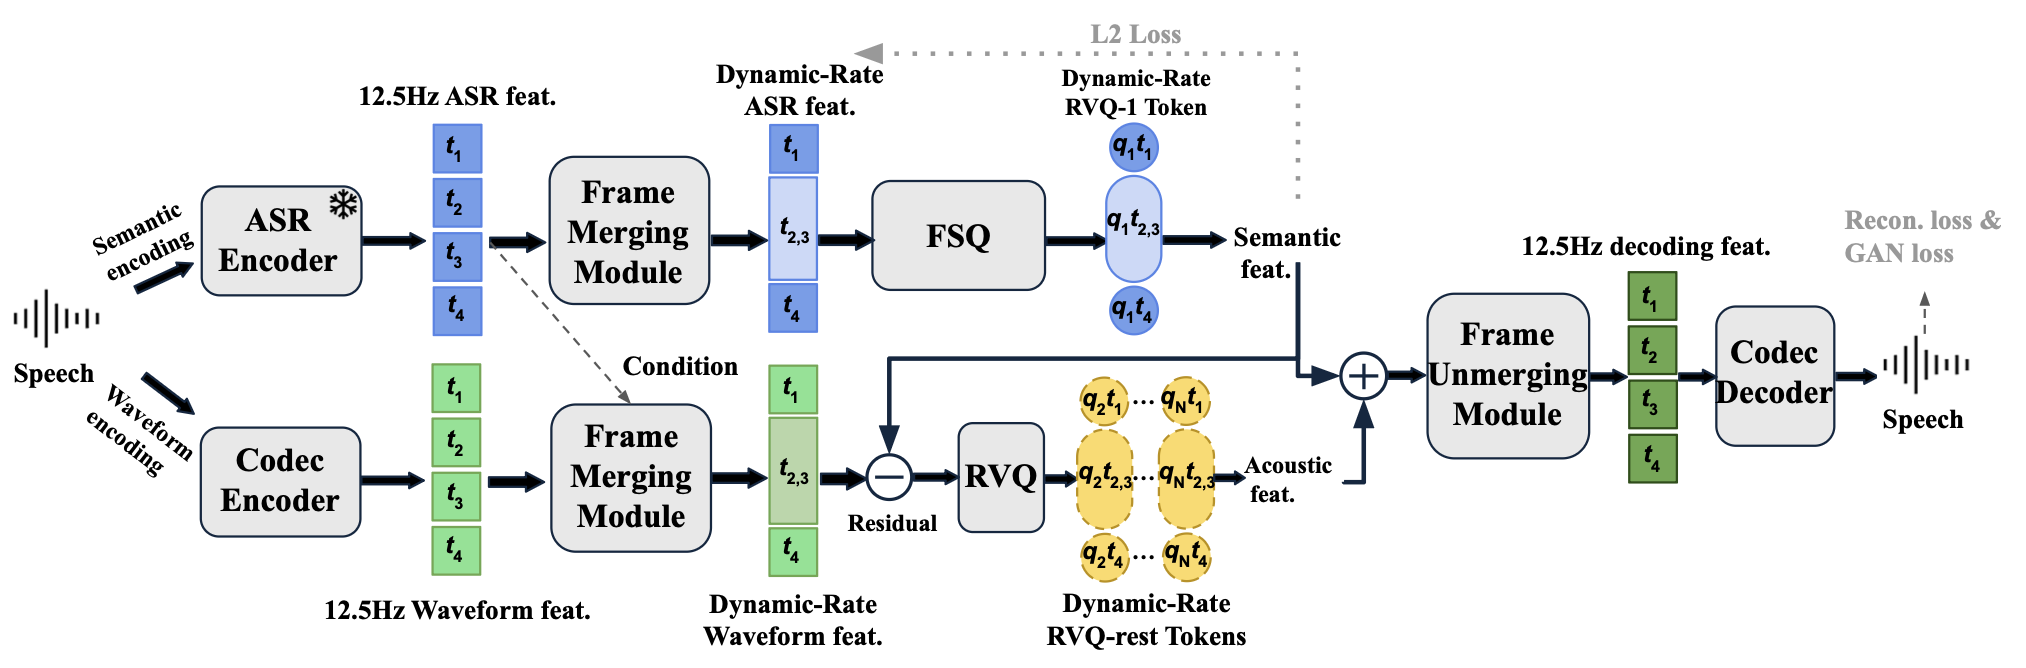
In this work, we develop FlexiCodec. FlexiCodec improves semantic preservation with a dynamic frame rate approach and introduces a novel architecture featuring an ASR feature-assisted dual stream encoding and Transformer bottlenecks. With dynamic frame rates, it uses less frames at information-sparse regions through adaptively merging semantically similar frames. A dynamic frame rate also allows FlexiCodec to support inference-time controllable frame rates between 3Hz and 12.5Hz.
To install FlexiCodec for inference, you need to properly install torch and torchaudio in your environment first, and then run:
pip install flexicodec
Alternatively, you can clone the repository and install locally:
git clone https://github.com/AmphionTeam/FlexiCodec.git
cd FlexiCodec
pip install -e .

 , applying FlexiCodec to a speech-in-speech-out spoken language model, enabling dynamic and controllable frame rate.
This code automatically downloads checkpoint from huggingface. If you prefer to download the checkpoint manually, there is another example below.
import torch
import torchaudio
import soundfile as sf
from flexicodec.infer import prepare_model, encode_flexicodec

model_dict = prepare_model()

# Load a real audio file
audio_path = "./audio_examples/audio1.wav" # or replace with your own audio file
audio_np, sample_rate = sf.read(audio_path, dtype="float32", always_2d=True)
audio = torch.from_numpy(audio_np.T)
# If this doesn't work, use `audio, sample_rate = torchaudio.load(audio_path)`

with torch.no_grad():
    encoded_output = encode_flexicodec(audio, model_dict, sample_rate, num_quantizers=8, merging_threshold=0.91)

    reconstructed_audio = model_dict['model'].decode_from_codes(
        semantic_codes=encoded_output['semantic_codes'],
        acoustic_codes=encoded_output['acoustic_codes'],
        token_lengths=encoded_output['token_lengths'],
    )

duration = audio.shape[-1] / sample_rate
output_path = 'decoded_audio.wav'
sf.write(output_path, reconstructed_audio.cpu().squeeze(1).T.numpy(), 16000)

print(f"Saved decoded audio to {output_path}")
print(f"This sample avg frame rate: {encoded_output['token_lengths'].shape[-1] / duration:.4f} frames/sec")
Notes:
You may tune the num_quantizers=xxx (min 1, max 24), merging_threshold=xxx (maximum 1.0) parameters. If you set merging_threshold=1.0, it will be a standard 12.5Hz neural audio codec. All of its token_lengths items will be 1.
Batched input is supported. You can directly pass audios shaped [B,T] to the script above, but the audio length information will be unavailable.
To resolve this, you can additionally pass an audio_lens parameter to encode_flexicodec, and you can crop the output for each audio in encoded_output[speech_token_len].
To extract continuous features from the semantic tokens, use:
feat = model_dict['model'].get_semantic_feature(encoded_output['semantic_codes'])
Troubleshooting:
export HF_ENDPOINT=https://hf-mirror.com in terminal, before running the code.Run the following commands to download the checkpoint manually:
hf download FunAudioLLM/SenseVoiceSmall --local-dir ./checkpoints/SenseVoiceSmall
hf download jiaqili3/flexicodec 12hz_v1_half.safetensors --local-dir ./checkpoints/flexicodec
hf download jiaqili3/flexicodec 12hz_v1_half_config.yaml --local-dir ./checkpoints/flexicodec
Then, you can use the following code to do inference:
import torch
import torchaudio
import soundfile as sf
from flexicodec.infer import prepare_model, encode_flexicodec

model_dict = prepare_model(sensevoice_small_path='./checkpoints/SenseVoiceSmall', ckpt_path='./checkpoints/flexicodec/12hz_v1_half.safetensors', config_path='./checkpoints/flexicodec/12hz_v1_half_config.yaml')

# Load a real audio file
audio_path = "./audio_examples/audio1.wav" # or replace with your own audio file
audio_np, sample_rate = sf.read(audio_path, dtype="float32", always_2d=True)
audio = torch.from_numpy(audio_np.T)
# If this doesn't work, use `audio, sample_rate = torchaudio.load(audio_path)`

with torch.no_grad():
    encoded_output = encode_flexicodec(audio, model_dict, sample_rate, num_quantizers=8, merging_threshold=0.91)

    reconstructed_audio = model_dict['model'].decode_from_codes(
        semantic_codes=encoded_output['semantic_codes'],
        acoustic_codes=encoded_output['acoustic_codes'],
        token_lengths=encoded_output['token_lengths'],
    )

duration = audio.shape[-1] / sample_rate
output_path = 'decoded_audio.wav'
sf.write(output_path, reconstructed_audio.cpu().squeeze(1).T.numpy(), 16000)

print(f"Saved decoded audio to {output_path}")
print(f"This sample avg frame rate: {encoded_output['token_lengths'].shape[-1] / duration:.4f} frames/sec")
First, install additional dependencies:
sudo apt install espeak-ng
pip install cached_path phonemizer openai-whisper
The AR+NAR TTS system generates speech tokens from text using an autoregressive transformer model, and then uses the Voicebox NAR system to decode the tokens into audio.
To perform complete text-to-speech with both AR generation and NAR decoding:
import torch
import torchaudio
from flexicodec.ar_tts.inference_tts import tts_synthesize
from flexicodec.ar_tts.modeling_artts import prepare_artts_model
from flexicodec.nar_tts.inference_voicebox import prepare_voicebox_model
from cached_path import cached_path

# Prepare both AR and NAR models
ar_checkpoint = cached_path('hf://jiaqili3/flexicodec/artts.safetensors')
nar_checkpoint = cached_path('hf://jiaqili3/flexicodec/nartts.safetensors')

ar_model_dict = prepare_artts_model(ar_checkpoint)
nar_model_dict = prepare_voicebox_model(nar_checkpoint)

# Full TTS synthesis
output_audio, output_sr, duration_classes = tts_synthesize(
    ar_model_dict=ar_model_dict,
    nar_model_dict=nar_model_dict,
    text="Hello, this is a complete text to speech example.",
    language="en",
    ref_audio_path="./audio_examples/1089-134686-0030.flac",  # Reference voice
    ref_text="be ware of making that mistake",  # Optional reference text
    merging_threshold=0.91,  # Frame rate control. Only two options supported: 0.91 or 0.86. If you set it to 0.91, the output is roughly 8Hz. The other option is about 6Hz.
    beam_size=1,
    top_k=25,
    temperature=1.0,
    predict_duration=True,
    duration_top_k=1,
    n_timesteps=15,  # NAR diffusion steps
    cfg=2.0,  # NAR classifier-free guidance
    rescale_cfg=0.75,  # NAR CFG rescaling
    use_nar=True,  # Set to False for AR-only decoding
)

# Save output
output_path = "output.wav"
torchaudio.save(output_path, output_audio.unsqueeze(0) if output_audio.dim() == 1 else output_audio, output_sr)

# Calculate and print frame rate
duration = output_audio.shape[-1] / output_sr
avg_frame_rate = duration_classes.shape[-1] / duration
print(f"Saved output to {output_path}")
print(f"This sample avg frame rate: {avg_frame_rate:.4f} frames/sec")
Troubleshooting:
ffmpeg installed (e.g., apt install ffmpeg), or (2) use soundfile package to load and save audio.Notes:
nartts_flexicodec_only.safetensors so that it can reuse this released Voicebox model and checkpoint.tts_synthesize performs the full pipeline: AR generation + NAR decoding to audio(output_audio, sample_rate, duration_classes)duration_classes contains the token durations which can be used to calculate the average frame rateref_audio_path) provides the voice/style characteristicsref_text) is optional and can help with prosody alignmentuse_nar=False in tts_synthesize to use AR-only decoding (faster but lower quality)merging_threshold controls the frame rate: 0.91 gives ~8.3Hz, 0.86 gives ~6.25HzThe VoiceBox NAR system can decode FlexiCodec's RVQ-1 tokens into speech. It is used as the second stage in FlexiCodec-TTS, but can also be used standalone. To run NAR TTS inference using FlexiCodec-Voicebox:
import torch
import torchaudio
from flexicodec.nar_tts.inference_voicebox import (
    prepare_voicebox_model,
    infer_voicebox_tts
)
from cached_path import cached_path

# Prepare VoiceBox model (loads model and vocoder)
checkpoint_path = cached_path('hf://jiaqili3/flexicodec/nartts.safetensors')
model_dict = prepare_voicebox_model(
    checkpoint_path,
    n_timesteps=15,          # Number of diffusion steps (default: 15)
    cfg=2.0,                 # Classifier-free guidance scale (default: 2.0)
    rescale_cfg=0.75,        # CFG rescaling factor (default: 0.75)
)

# Load ground truth audio (target content) and extract semantic tokens via FlexiCodec
from flexicodec.infer import prepare_model as prepare_flexicodec_model, encode_flexicodec

flexicodec_dict = prepare_flexicodec_model()
gt_audio_path = "audio_examples/1089-134686-0030.flac"  # Ground truth (target content)
gt_audio, gt_sr = torchaudio.load(gt_audio_path)

# Extract semantic tokens and length_ids from ground truth audio
with torch.no_grad():
    encoded_output = encode_flexicodec(gt_audio, flexicodec_dict, gt_sr, merging_threshold=0.9) # You can use any merging threshold value here.
    audio_tokens = encoded_output['semantic_codes'].squeeze()  # [T] semantic token indices
    length_ids = encoded_output['token_lengths'].squeeze()     # [T] duration classes

# Load prompt audio (reference voice/style)
prompt_audio_path = "audio_examples/1089-134686-0032.flac"  # Reference audio (voice/style)
prompt_audio, _ = torchaudio.load(prompt_audio_path)

# Run VoiceBox NAR inference
output_audio, output_sr = infer_voicebox_tts(
    model_dict=model_dict,
    audio_tokens=audio_tokens,     # [T] semantic token indices from FlexiCodec
    length_ids=length_ids,         # [T] duration classes from FlexiCodec
    prompt_audio=prompt_audio,     # [1, T_audio] prompt audio tensor
    prompt_audio_path=prompt_audio_path,  # Optional: for feature caching
    framerate=1.0                  # Frame rate control (default: 1.0, max: 1.0)
                                   # Lower values (e.g., 0.87, 0.91) enable dynamic merging
)

# Save output
output_path = "output_nar.wav"
torchaudio.save(output_path, output_audio.unsqueeze(0) if output_audio.dim() == 1 else output_audio, output_sr)

# Calculate and print frame rate
duration = output_audio.shape[-1] / output_sr
avg_frame_rate = length_ids.shape[-1] / duration
print(f"Saved output to {output_path}")
print(f"This sample avg frame rate: {avg_frame_rate:.4f} frames/sec")
Notes:
nartts_flexicodec_only.safetensors so that it can reuse this released Voicebox model.audio_tokens are semantic token indices extracted from ground truth audio via FlexiCodec encoding (as shown above) or generated by an AR modellength_ids are duration classes for each token extracted from FlexiCodec encoding (optional, defaults to 1 for each token)prompt_audio determines the voice/style characteristics of the outputmodel_dict for multiple inference calls to avoid reloading the modelframerate controls FlexiCodec's dynamic frame rate: lower values (e.g., 0.87, 0.91) enable merging for lower average frame rates, while 1.0 disables merging (standard 12.5Hz)flexicodec/ar_tts/modeling_artts.py and flexicodec/nar_tts/modeling_voicebox.py there are training_forward methods that receive audios and prepared sensevoice-small input "FBank" features. (dl_output dictionary containing x (the feature_extractor output), x_lens (length of each x before padding), audio (the 16khz audio tensor)).
Training can be replicated by passing the same data to the training_forward methods.If you need more code for training FlexiCodec-TTS, you can contact me or create an issue.
If you find our works useful, please consider citing as:
@article{li2025flexicodec,
  title={FlexiCodec: A Dynamic Neural Audio Codec for Low Frame Rates},
  author={Li, Jiaqi and Qian, Yao and Hu, Yuxuan and Zhang, Leying and Wang, Xiaofei and Lu, Heng and Thakker, Manthan and Li, Jinyu and Zhao, Sheng and Wu, Zhizheng},
  journal={arXiv preprint arXiv:2510.00981},
  year={2025}
}

@article{li2025dualcodec,
  title={Dualcodec: A low-frame-rate, semantically-enhanced neural audio codec for speech generation},
  author={Li, Jiaqi and Lin, Xiaolong and Li, Zhekai and Huang, Shixi and Wang, Yuancheng and Wang, Chaoren and Zhan, Zhenpeng and Wu, Zhizheng},
  journal={Interspeech 2025},
  year={2025}
}
286 followers · starred Dec 2025
522 followers · starred Nov 2025
210 followers · starred Oct 2025
170 followers · starred Nov 2025
[ICLR2026] FlexiCodec: A Dynamic Neural Audio Codec for Low Frame Rates
See the code
Neural audio codecs are foundational to speech language models. Recent studies have developed 12.5Hz low-frame-rate audio codecs, but even lower frame rate codecs remain underexplored.
In this work, we develop FlexiCodec. FlexiCodec improves semantic preservation with a dynamic frame rate approach and introduces a novel architecture featuring an ASR feature-assisted dual stream encoding and Transformer bottlenecks. With dynamic frame rates, it uses less frames at information-sparse regions through adaptively merging semantically similar frames. A dynamic frame rate also allows FlexiCodec to support inference-time controllable frame rates between 3Hz and 12.5Hz.
To install FlexiCodec for inference, you need to properly install torch and torchaudio in your environment first, and then run:
pip install flexicodec
Alternatively, you can clone the repository and install locally:
git clone https://github.com/AmphionTeam/FlexiCodec.git
cd FlexiCodec
pip install -e .
This code automatically downloads checkpoint from huggingface. If you prefer to download the checkpoint manually, there is another example below.
import torch
import torchaudio
import soundfile as sf
from flexicodec.infer import prepare_model, encode_flexicodec

model_dict = prepare_model()

# Load a real audio file
audio_path = "./audio_examples/audio1.wav" # or replace with your own audio file
audio_np, sample_rate = sf.read(audio_path, dtype="float32", always_2d=True)
audio = torch.from_numpy(audio_np.T)
# If this doesn't work, use `audio, sample_rate = torchaudio.load(audio_path)`

with torch.no_grad():
    encoded_output = encode_flexicodec(audio, model_dict, sample_rate, num_quantizers=8, merging_threshold=0.91)

    reconstructed_audio = model_dict['model'].decode_from_codes(
        semantic_codes=encoded_output['semantic_codes'],
        acoustic_codes=encoded_output['acoustic_codes'],
        token_lengths=encoded_output['token_lengths'],
    )

duration = audio.shape[-1] / sample_rate
output_path = 'decoded_audio.wav'
sf.write(output_path, reconstructed_audio.cpu().squeeze(1).T.numpy(), 16000)

print(f"Saved decoded audio to {output_path}")
print(f"This sample avg frame rate: {encoded_output['token_lengths'].shape[-1] / duration:.4f} frames/sec")
Notes:
You may tune the num_quantizers=xxx (min 1, max 24), merging_threshold=xxx (maximum 1.0) parameters. If you set merging_threshold=1.0, it will be a standard 12.5Hz neural audio codec. All of its token_lengths items will be 1.
Batched input is supported. You can directly pass audios shaped [B,T] to the script above, but the audio length information will be unavailable.
To resolve this, you can additionally pass an audio_lens parameter to encode_flexicodec, and you can crop the output for each audio in encoded_output[speech_token_len].
To extract continuous features from the semantic tokens, use:
feat = model_dict['model'].get_semantic_feature(encoded_output['semantic_codes'])
Troubleshooting:
export HF_ENDPOINT=https://hf-mirror.com in terminal, before running the code.Run the following commands to download the checkpoint manually:
hf download FunAudioLLM/SenseVoiceSmall --local-dir ./checkpoints/SenseVoiceSmall
hf download jiaqili3/flexicodec 12hz_v1_half.safetensors --local-dir ./checkpoints/flexicodec
hf download jiaqili3/flexicodec 12hz_v1_half_config.yaml --local-dir ./checkpoints/flexicodec
Then, you can use the following code to do inference:
import torch
import torchaudio
import soundfile as sf
from flexicodec.infer import prepare_model, encode_flexicodec

model_dict = prepare_model(sensevoice_small_path='./checkpoints/SenseVoiceSmall', ckpt_path='./checkpoints/flexicodec/12hz_v1_half.safetensors', config_path='./checkpoints/flexicodec/12hz_v1_half_config.yaml')

# Load a real audio file
audio_path = "./audio_examples/audio1.wav" # or replace with your own audio file
audio_np, sample_rate = sf.read(audio_path, dtype="float32", always_2d=True)
audio = torch.from_numpy(audio_np.T)
# If this doesn't work, use `audio, sample_rate = torchaudio.load(audio_path)`

with torch.no_grad():
    encoded_output = encode_flexicodec(audio, model_dict, sample_rate, num_quantizers=8, merging_threshold=0.91)

    reconstructed_audio = model_dict['model'].decode_from_codes(
        semantic_codes=encoded_output['semantic_codes'],
        acoustic_codes=encoded_output['acoustic_codes'],
        token_lengths=encoded_output['token_lengths'],
    )

duration = audio.shape[-1] / sample_rate
output_path = 'decoded_audio.wav'
sf.write(output_path, reconstructed_audio.cpu().squeeze(1).T.numpy(), 16000)

print(f"Saved decoded audio to {output_path}")
print(f"This sample avg frame rate: {encoded_output['token_lengths'].shape[-1] / duration:.4f} frames/sec")
First, install additional dependencies:
sudo apt install espeak-ng
pip install cached_path phonemizer openai-whisper
The AR+NAR TTS system generates speech tokens from text using an autoregressive transformer model, and then uses the Voicebox NAR system to decode the tokens into audio.
To perform complete text-to-speech with both AR generation and NAR decoding:
import torch
import torchaudio
from flexicodec.ar_tts.inference_tts import tts_synthesize
from flexicodec.ar_tts.modeling_artts import prepare_artts_model
from flexicodec.nar_tts.inference_voicebox import prepare_voicebox_model
from cached_path import cached_path

# Prepare both AR and NAR models
ar_checkpoint = cached_path('hf://jiaqili3/flexicodec/artts.safetensors')
nar_checkpoint = cached_path('hf://jiaqili3/flexicodec/nartts.safetensors')

ar_model_dict = prepare_artts_model(ar_checkpoint)
nar_model_dict = prepare_voicebox_model(nar_checkpoint)

# Full TTS synthesis
output_audio, output_sr, duration_classes = tts_synthesize(
    ar_model_dict=ar_model_dict,
    nar_model_dict=nar_model_dict,
    text="Hello, this is a complete text to speech example.",
    language="en",
    ref_audio_path="./audio_examples/1089-134686-0030.flac",  # Reference voice
    ref_text="be ware of making that mistake",  # Optional reference text
    merging_threshold=0.91,  # Frame rate control. Only two options supported: 0.91 or 0.86. If you set it to 0.91, the output is roughly 8Hz. The other option is about 6Hz.
    beam_size=1,
    top_k=25,
    temperature=1.0,
    predict_duration=True,
    duration_top_k=1,
    n_timesteps=15,  # NAR diffusion steps
    cfg=2.0,  # NAR classifier-free guidance
    rescale_cfg=0.75,  # NAR CFG rescaling
    use_nar=True,  # Set to False for AR-only decoding
)

# Save output
output_path = "output.wav"
torchaudio.save(output_path, output_audio.unsqueeze(0) if output_audio.dim() == 1 else output_audio, output_sr)

# Calculate and print frame rate
duration = output_audio.shape[-1] / output_sr
avg_frame_rate = duration_classes.shape[-1] / duration
print(f"Saved output to {output_path}")
print(f"This sample avg frame rate: {avg_frame_rate:.4f} frames/sec")
Troubleshooting:
ffmpeg installed (e.g., apt install ffmpeg), or (2) use soundfile package to load and save audio.Notes:
nartts_flexicodec_only.safetensors so that it can reuse this released Voicebox model and checkpoint.tts_synthesize performs the full pipeline: AR generation + NAR decoding to audio(output_audio, sample_rate, duration_classes)duration_classes contains the token durations which can be used to calculate the average frame rateref_audio_path) provides the voice/style characteristicsref_text) is optional and can help with prosody alignmentuse_nar=False in tts_synthesize to use AR-only decoding (faster but lower quality)merging_threshold controls the frame rate: 0.91 gives ~8.3Hz, 0.86 gives ~6.25HzThe VoiceBox NAR system can decode FlexiCodec's RVQ-1 tokens into speech. It is used as the second stage in FlexiCodec-TTS, but can also be used standalone. To run NAR TTS inference using FlexiCodec-Voicebox:
import torch
import torchaudio
from flexicodec.nar_tts.inference_voicebox import (
    prepare_voicebox_model,
    infer_voicebox_tts
)
from cached_path import cached_path

# Prepare VoiceBox model (loads model and vocoder)
checkpoint_path = cached_path('hf://jiaqili3/flexicodec/nartts.safetensors')
model_dict = prepare_voicebox_model(
    checkpoint_path,
    n_timesteps=15,          # Number of diffusion steps (default: 15)
    cfg=2.0,                 # Classifier-free guidance scale (default: 2.0)
    rescale_cfg=0.75,        # CFG rescaling factor (default: 0.75)
)

# Load ground truth audio (target content) and extract semantic tokens via FlexiCodec
from flexicodec.infer import prepare_model as prepare_flexicodec_model, encode_flexicodec

flexicodec_dict = prepare_flexicodec_model()
gt_audio_path = "audio_examples/1089-134686-0030.flac"  # Ground truth (target content)
gt_audio, gt_sr = torchaudio.load(gt_audio_path)

# Extract semantic tokens and length_ids from ground truth audio
with torch.no_grad():
    encoded_output = encode_flexicodec(gt_audio, flexicodec_dict, gt_sr, merging_threshold=0.9) # You can use any merging threshold value here.
    audio_tokens = encoded_output['semantic_codes'].squeeze()  # [T] semantic token indices
    length_ids = encoded_output['token_lengths'].squeeze()     # [T] duration classes

# Load prompt audio (reference voice/style)
prompt_audio_path = "audio_examples/1089-134686-0032.flac"  # Reference audio (voice/style)
prompt_audio, _ = torchaudio.load(prompt_audio_path)

# Run VoiceBox NAR inference
output_audio, output_sr = infer_voicebox_tts(
    model_dict=model_dict,
    audio_tokens=audio_tokens,     # [T] semantic token indices from FlexiCodec
    length_ids=length_ids,         # [T] duration classes from FlexiCodec
    prompt_audio=prompt_audio,     # [1, T_audio] prompt audio tensor
    prompt_audio_path=prompt_audio_path,  # Optional: for feature caching
    framerate=1.0                  # Frame rate control (default: 1.0, max: 1.0)
                                   # Lower values (e.g., 0.87, 0.91) enable dynamic merging
)

# Save output
output_path = "output_nar.wav"
torchaudio.save(output_path, output_audio.unsqueeze(0) if output_audio.dim() == 1 else output_audio, output_sr)

# Calculate and print frame rate
duration = output_audio.shape[-1] / output_sr
avg_frame_rate = length_ids.shape[-1] / duration
print(f"Saved output to {output_path}")
print(f"This sample avg frame rate: {avg_frame_rate:.4f} frames/sec")
Notes:
nartts_flexicodec_only.safetensors so that it can reuse this released Voicebox model.audio_tokens are semantic token indices extracted from ground truth audio via FlexiCodec encoding (as shown above) or generated by an AR modellength_ids are duration classes for each token extracted from FlexiCodec encoding (optional, defaults to 1 for each token)prompt_audio determines the voice/style characteristics of the outputmodel_dict for multiple inference calls to avoid reloading the modelframerate controls FlexiCodec's dynamic frame rate: lower values (e.g., 0.87, 0.91) enable merging for lower average frame rates, while 1.0 disables merging (standard 12.5Hz)flexicodec/ar_tts/modeling_artts.py and flexicodec/nar_tts/modeling_voicebox.py there are training_forward methods that receive audios and prepared sensevoice-small input "FBank" features. (dl_output dictionary containing x (the feature_extractor output), x_lens (length of each x before padding), audio (the 16khz audio tensor)).
Training can be replicated by passing the same data to the training_forward methods.If you need more code for training FlexiCodec-TTS, you can contact me or create an issue.
If you find our works useful, please consider citing as:
@article{li2025flexicodec,
  title={FlexiCodec: A Dynamic Neural Audio Codec for Low Frame Rates},
  author={Li, Jiaqi and Qian, Yao and Hu, Yuxuan and Zhang, Leying and Wang, Xiaofei and Lu, Heng and Thakker, Manthan and Li, Jinyu and Zhao, Sheng and Wu, Zhizheng},
  journal={arXiv preprint arXiv:2510.00981},
  year={2025}
}

@article{li2025dualcodec,
  title={Dualcodec: A low-frame-rate, semantically-enhanced neural audio codec for speech generation},
  author={Li, Jiaqi and Lin, Xiaolong and Li, Zhekai and Huang, Shixi and Wang, Yuancheng and Wang, Chaoren and Zhan, Zhenpeng and Wu, Zhizheng},
  journal={Interspeech 2025},
  year={2025}
}
286 followers · starred Dec 2025
522 followers · starred Nov 2025
210 followers · starred Oct 2025
170 followers · starred Nov 2025