
Official PyTorch Implementation of "The Hidden Attention of Mamba Models"
Python
237
37 commits
updated Oct 16, 2025
README
🐍 The Hidden Attention of Mamba Models 🐍 (ACL 2025)
Ameen Ali1 *,Itamar Zimerman1 * and Lior Wolf1
ameenali023@gmail.com, itamarzimm@gmail.com, liorwolf@gmail.com
1 Tel Aviv University
(*) equal contribution
Official PyTorch Implementation of "The Hidden Attention of Mamba Models"
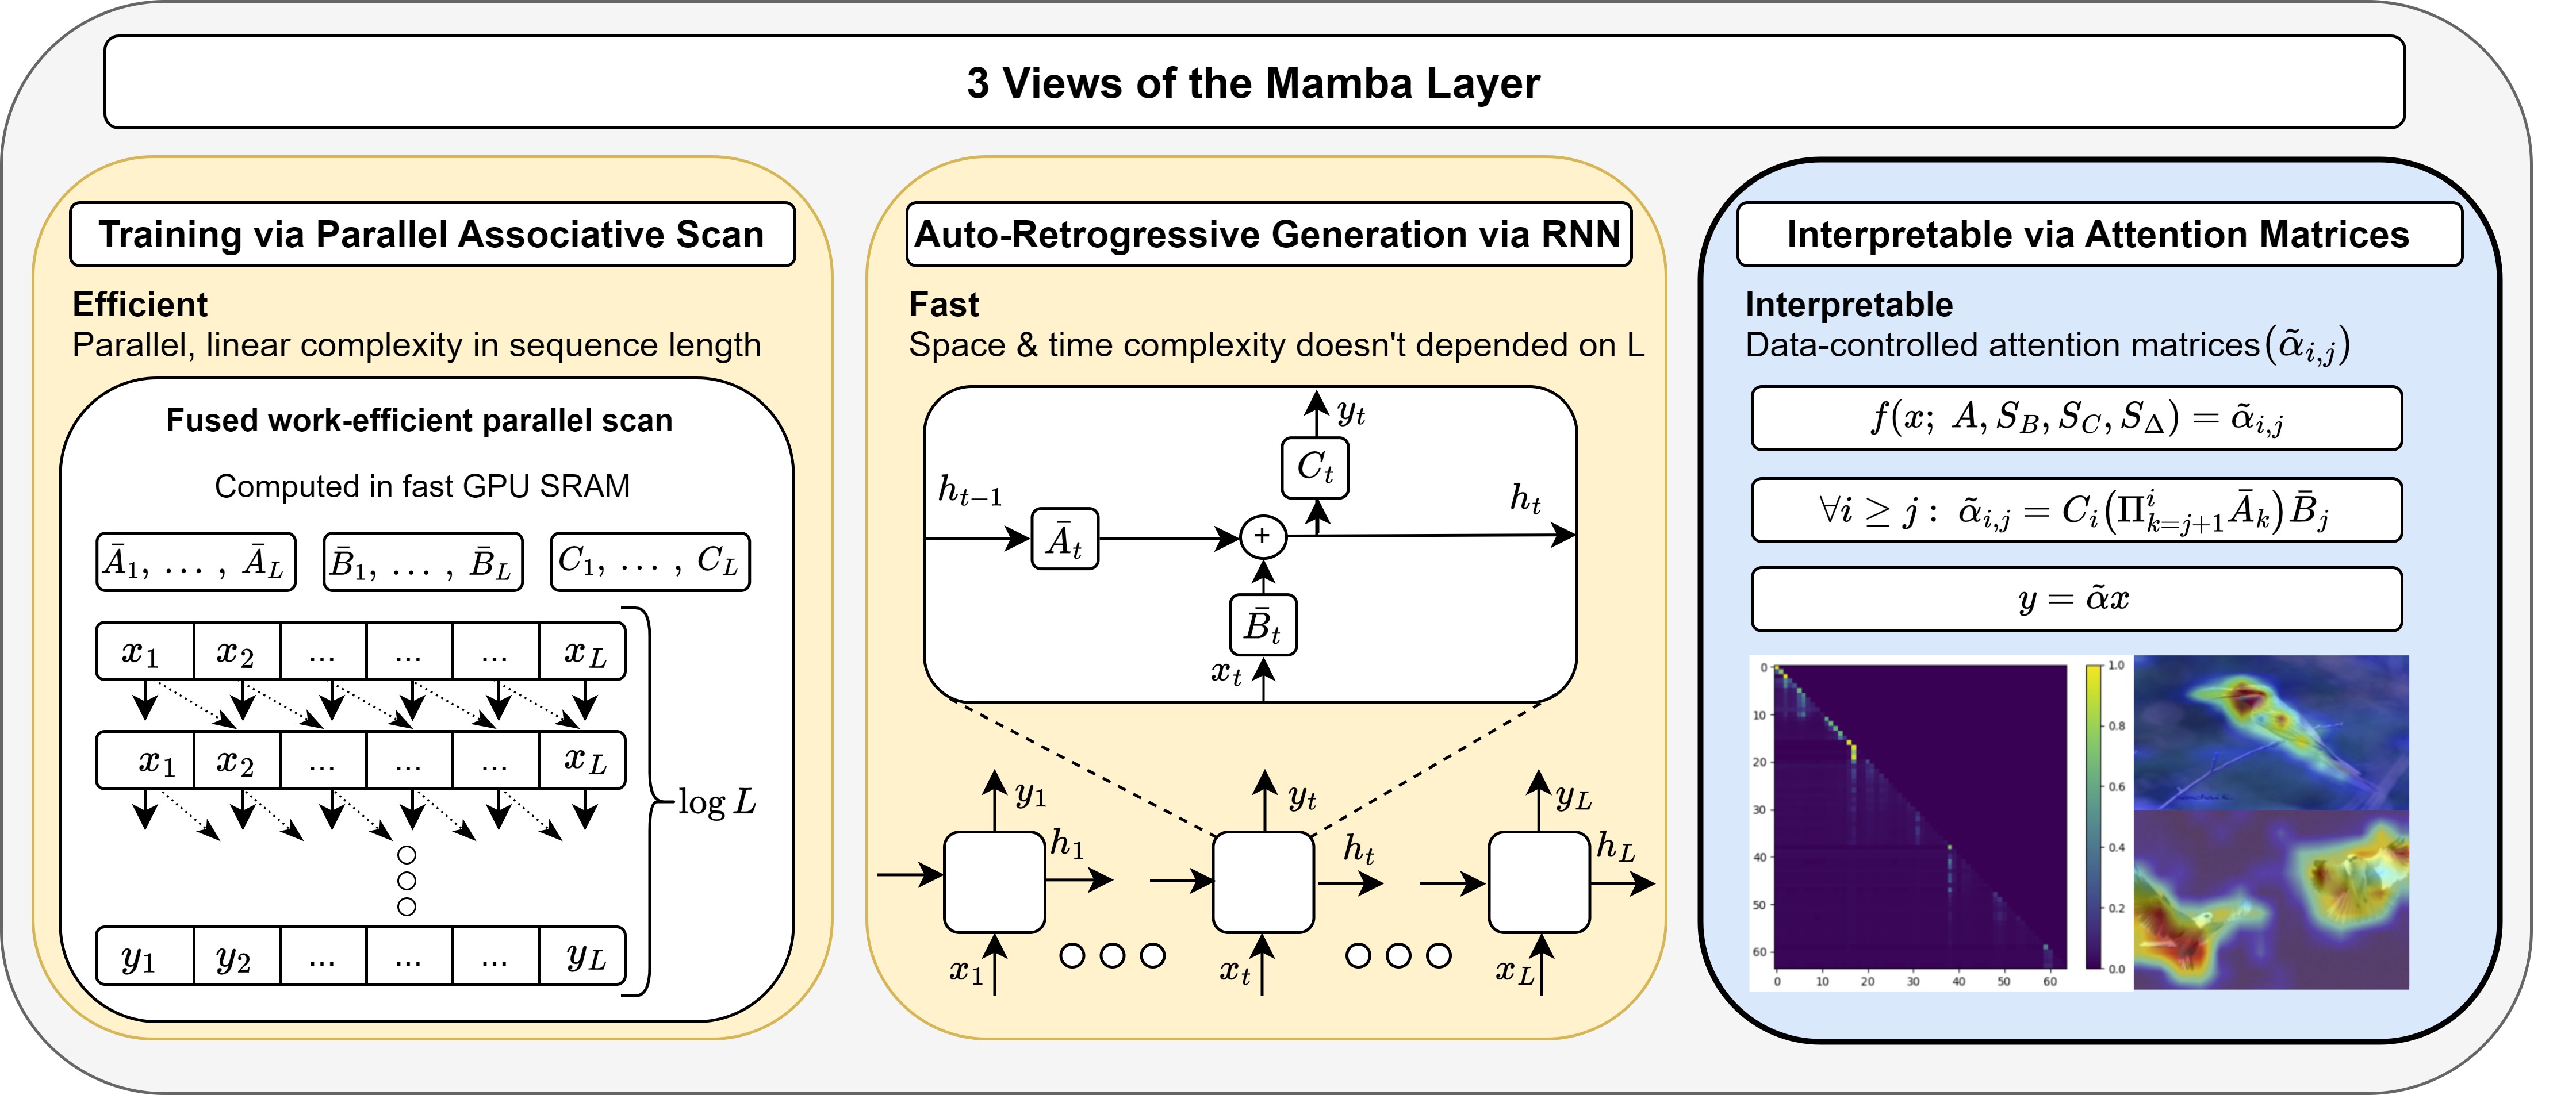
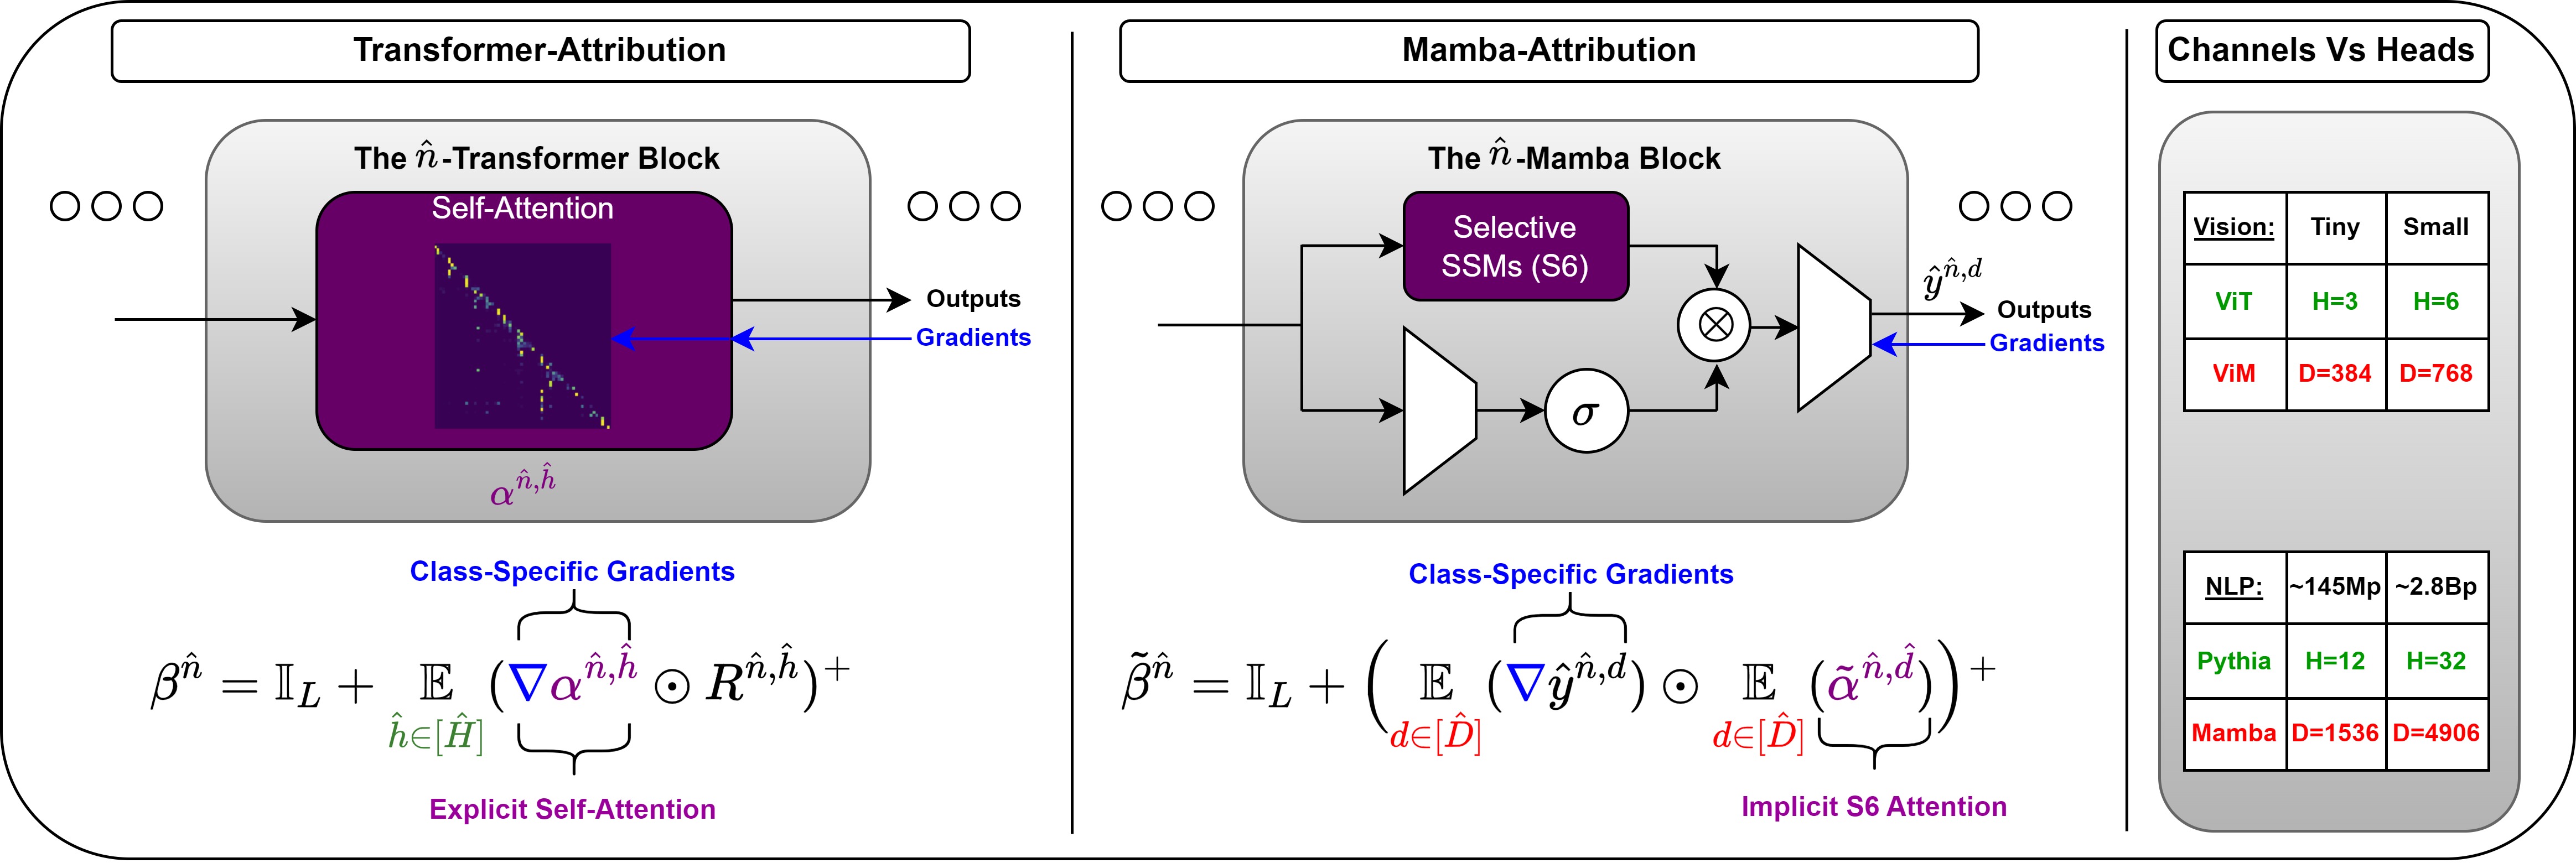
The Mamba layer offers an efficient state space model (SSM) that is highly effective in modeling multiple domains including long-range sequences and images. SSMs are viewed as dual models, in which one trains in parallel on the entire sequence using convolutions, and deploys in an autoregressive manner. We add a third view and show that such models can be viewed as attention-driven models. This new perspective enables us to compare the underlying mechanisms to that of the self-attention layers in transformers and allows us to peer inside the inner workings of the Mamba model with explainability methods.
You can access the paper through : The Hidden Attention of Mamba Models
Set Up Environment
-
Python 3.10.13
conda create -n your_env_name python=3.10.13
-
Activate Env
conda activate your_env_name
-
CUDA TOOLKIT 11.8
conda install nvidia/label/cuda-11.8.0::cuda-toolkit
-
torch 2.1.1 + cu118
pip install torch==2.1.1 torchvision==0.16.1 torchaudio==2.1.1 --index-url https://download.pytorch.org/whl/cu118
-
Requirements: vim_requirements.txt
pip install -r vim/vim_requirements.txt
-
Install jupyter
pip install jupyter
-
Install
causal_conv1dandmambafrom our sourcecd causal-conv1dpip install --editable .cd ..pip install --editable mamba-1p1p1
Pre-Trained Weights
We have used the official weights provided by Vim, which can be downloaded from here:
| Model | #param. | Top-1 Acc. | Top-5 Acc. | Hugginface Repo |
|---|---|---|---|---|
| Vim-tiny | 7M | 76.1 | 93.0 | https://huggingface.co/hustvl/Vim-tiny-midclstok |
| Vim-tiny+ | 7M | 78.3 | 94.2 | https://huggingface.co/hustvl/Vim-tiny-midclstok |
| Vim-small | 26M | 80.5 | 95.1 | https://huggingface.co/hustvl/Vim-small-midclstok |
| Vim-small+ | 26M | 81.6 | 95.4 | https://huggingface.co/hustvl/Vim-small-midclstok |
Notes:
- In all of our experiments, we have worked with Vim-small.
Vision-Mamba Explainability Notebook:
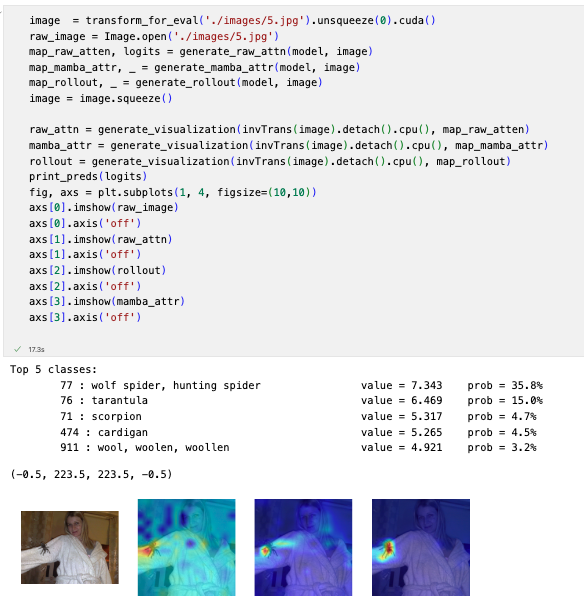
Follow the instructions in vim/vmamba_xai.ipynb notebook, in order to apply a single-image inference for the 3 introduced methods in the paper.
To-Do
For the segmentation experiment, please check out our follow-up work.
- XAI - Single Image Inference Notebook
- XAI - Segmentation Experimnts
Citation
if you find our work useful, please consider citing us:
@inproceedings{ali-etal-2025-hidden,
    title="The Hidden Attention of Mamba Models",
    author = "Ali, Ameen Ali  and
      Zimerman, Itamar  and
      Wolf, Lior",
    editor="Che, Wanxiang  and
      Nabende, Joyce  and
      Shutova, Ekaterina  and
      Pilehvar, Mohammad Taher",
    booktitle="Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month=jul,
    year="2025",
    address="Vienna, Austria",
    publisher="Association for Computational Linguistics",
    url="https://aclanthology.org/2025.acl-long.76/",
    doi="10.18653/v1/2025.acl-long.76",
    pages="1516--1534",
    ISBN="979-8-89176-251-0",
    abstract="The Mamba layer offers an efficient selective state-space model (SSM) that is highly effective in modeling multiple domains, includingNLP, long-range sequence processing, and computer vision. Selective SSMs are viewed as dual models, in which one trains in parallel on the entire sequence via an IO-aware parallel scan, and deploys in an autoregressive manner. We add a third view and show that such models can be viewed as attention-driven models. This new perspective enables us to empirically and theoretically compare the underlying mechanisms to that of the attention in transformers and allows us to peer inside the inner workings of the Mamba model with explainability methods. Our code is publicly available."
}
Acknowledgement
This repository is heavily based on Vim, Mamba and Transformer-Explainability. Thanks for their wonderful works.
Contributors


Similar repos


Languages
Python
59.1%
Cuda
26.7%
C++
9.9%
Jupyter Notebook
2.7%
C
1.1%
Official PyTorch Implementation of "The Hidden Attention of Mamba Models"
Python
237
37 commits
updated Oct 16, 2025
README
🐍 The Hidden Attention of Mamba Models 🐍 (ACL 2025)
Ameen Ali1 *,Itamar Zimerman1 * and Lior Wolf1
ameenali023@gmail.com, itamarzimm@gmail.com, liorwolf@gmail.com
1 Tel Aviv University
(*) equal contribution
Official PyTorch Implementation of "The Hidden Attention of Mamba Models"
The Mamba layer offers an efficient state space model (SSM) that is highly effective in modeling multiple domains including long-range sequences and images. SSMs are viewed as dual models, in which one trains in parallel on the entire sequence using convolutions, and deploys in an autoregressive manner. We add a third view and show that such models can be viewed as attention-driven models. This new perspective enables us to compare the underlying mechanisms to that of the self-attention layers in transformers and allows us to peer inside the inner workings of the Mamba model with explainability methods.
You can access the paper through : The Hidden Attention of Mamba Models
Set Up Environment
-
Python 3.10.13
conda create -n your_env_name python=3.10.13
-
Activate Env
conda activate your_env_name
-
CUDA TOOLKIT 11.8
conda install nvidia/label/cuda-11.8.0::cuda-toolkit
-
torch 2.1.1 + cu118
pip install torch==2.1.1 torchvision==0.16.1 torchaudio==2.1.1 --index-url https://download.pytorch.org/whl/cu118
-
Requirements: vim_requirements.txt
pip install -r vim/vim_requirements.txt
-
Install jupyter
pip install jupyter
-
Install
causal_conv1dandmambafrom our sourcecd causal-conv1dpip install --editable .cd ..pip install --editable mamba-1p1p1
Pre-Trained Weights
We have used the official weights provided by Vim, which can be downloaded from here:
| Model | #param. | Top-1 Acc. | Top-5 Acc. | Hugginface Repo |
|---|---|---|---|---|
| Vim-tiny | 7M | 76.1 | 93.0 | https://huggingface.co/hustvl/Vim-tiny-midclstok |
| Vim-tiny+ | 7M | 78.3 | 94.2 | https://huggingface.co/hustvl/Vim-tiny-midclstok |
| Vim-small | 26M | 80.5 | 95.1 | https://huggingface.co/hustvl/Vim-small-midclstok |
| Vim-small+ | 26M | 81.6 | 95.4 | https://huggingface.co/hustvl/Vim-small-midclstok |
Notes:
- In all of our experiments, we have worked with Vim-small.
Vision-Mamba Explainability Notebook:
Follow the instructions in vim/vmamba_xai.ipynb notebook, in order to apply a single-image inference for the 3 introduced methods in the paper.
To-Do
For the segmentation experiment, please check out our follow-up work.
- XAI - Single Image Inference Notebook
- XAI - Segmentation Experimnts
Citation
if you find our work useful, please consider citing us:
@inproceedings{ali-etal-2025-hidden,
    title="The Hidden Attention of Mamba Models",
    author = "Ali, Ameen Ali  and
      Zimerman, Itamar  and
      Wolf, Lior",
    editor="Che, Wanxiang  and
      Nabende, Joyce  and
      Shutova, Ekaterina  and
      Pilehvar, Mohammad Taher",
    booktitle="Proceedings of the 63rd Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers)",
    month=jul,
    year="2025",
    address="Vienna, Austria",
    publisher="Association for Computational Linguistics",
    url="https://aclanthology.org/2025.acl-long.76/",
    doi="10.18653/v1/2025.acl-long.76",
    pages="1516--1534",
    ISBN="979-8-89176-251-0",
    abstract="The Mamba layer offers an efficient selective state-space model (SSM) that is highly effective in modeling multiple domains, includingNLP, long-range sequence processing, and computer vision. Selective SSMs are viewed as dual models, in which one trains in parallel on the entire sequence via an IO-aware parallel scan, and deploys in an autoregressive manner. We add a third view and show that such models can be viewed as attention-driven models. This new perspective enables us to empirically and theoretically compare the underlying mechanisms to that of the attention in transformers and allows us to peer inside the inner workings of the Mamba model with explainability methods. Our code is publicly available."
}
Acknowledgement
This repository is heavily based on Vim, Mamba and Transformer-Explainability. Thanks for their wonderful works.
Similar repos
Contributors
Languages
Python
59.1%
Cuda
26.7%
C++
9.9%
Jupyter Notebook
2.7%
C
1.1%