
README
Awesome LLM Systems Papers
A curated list of Large Language Model systems related academic papers, articles, tutorials, slides and projects. Star this repository, and then you can keep abreast of the latest developments of this booming research field.
Trends at a Glance (2024 → 2026)
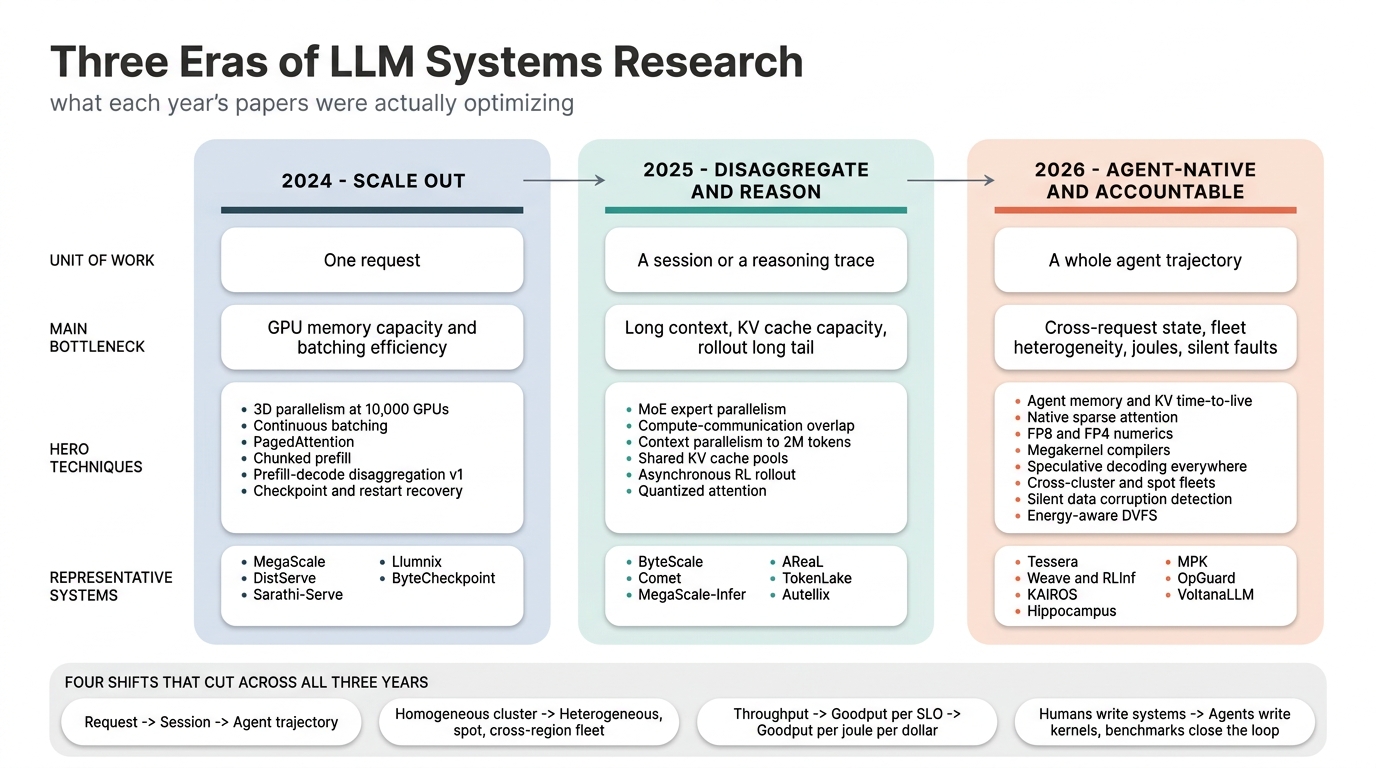
Three eras, one lens: what unit of work the system optimizes — a request (2024), a session or reasoning trace (2025), a whole agent trajectory (2026).
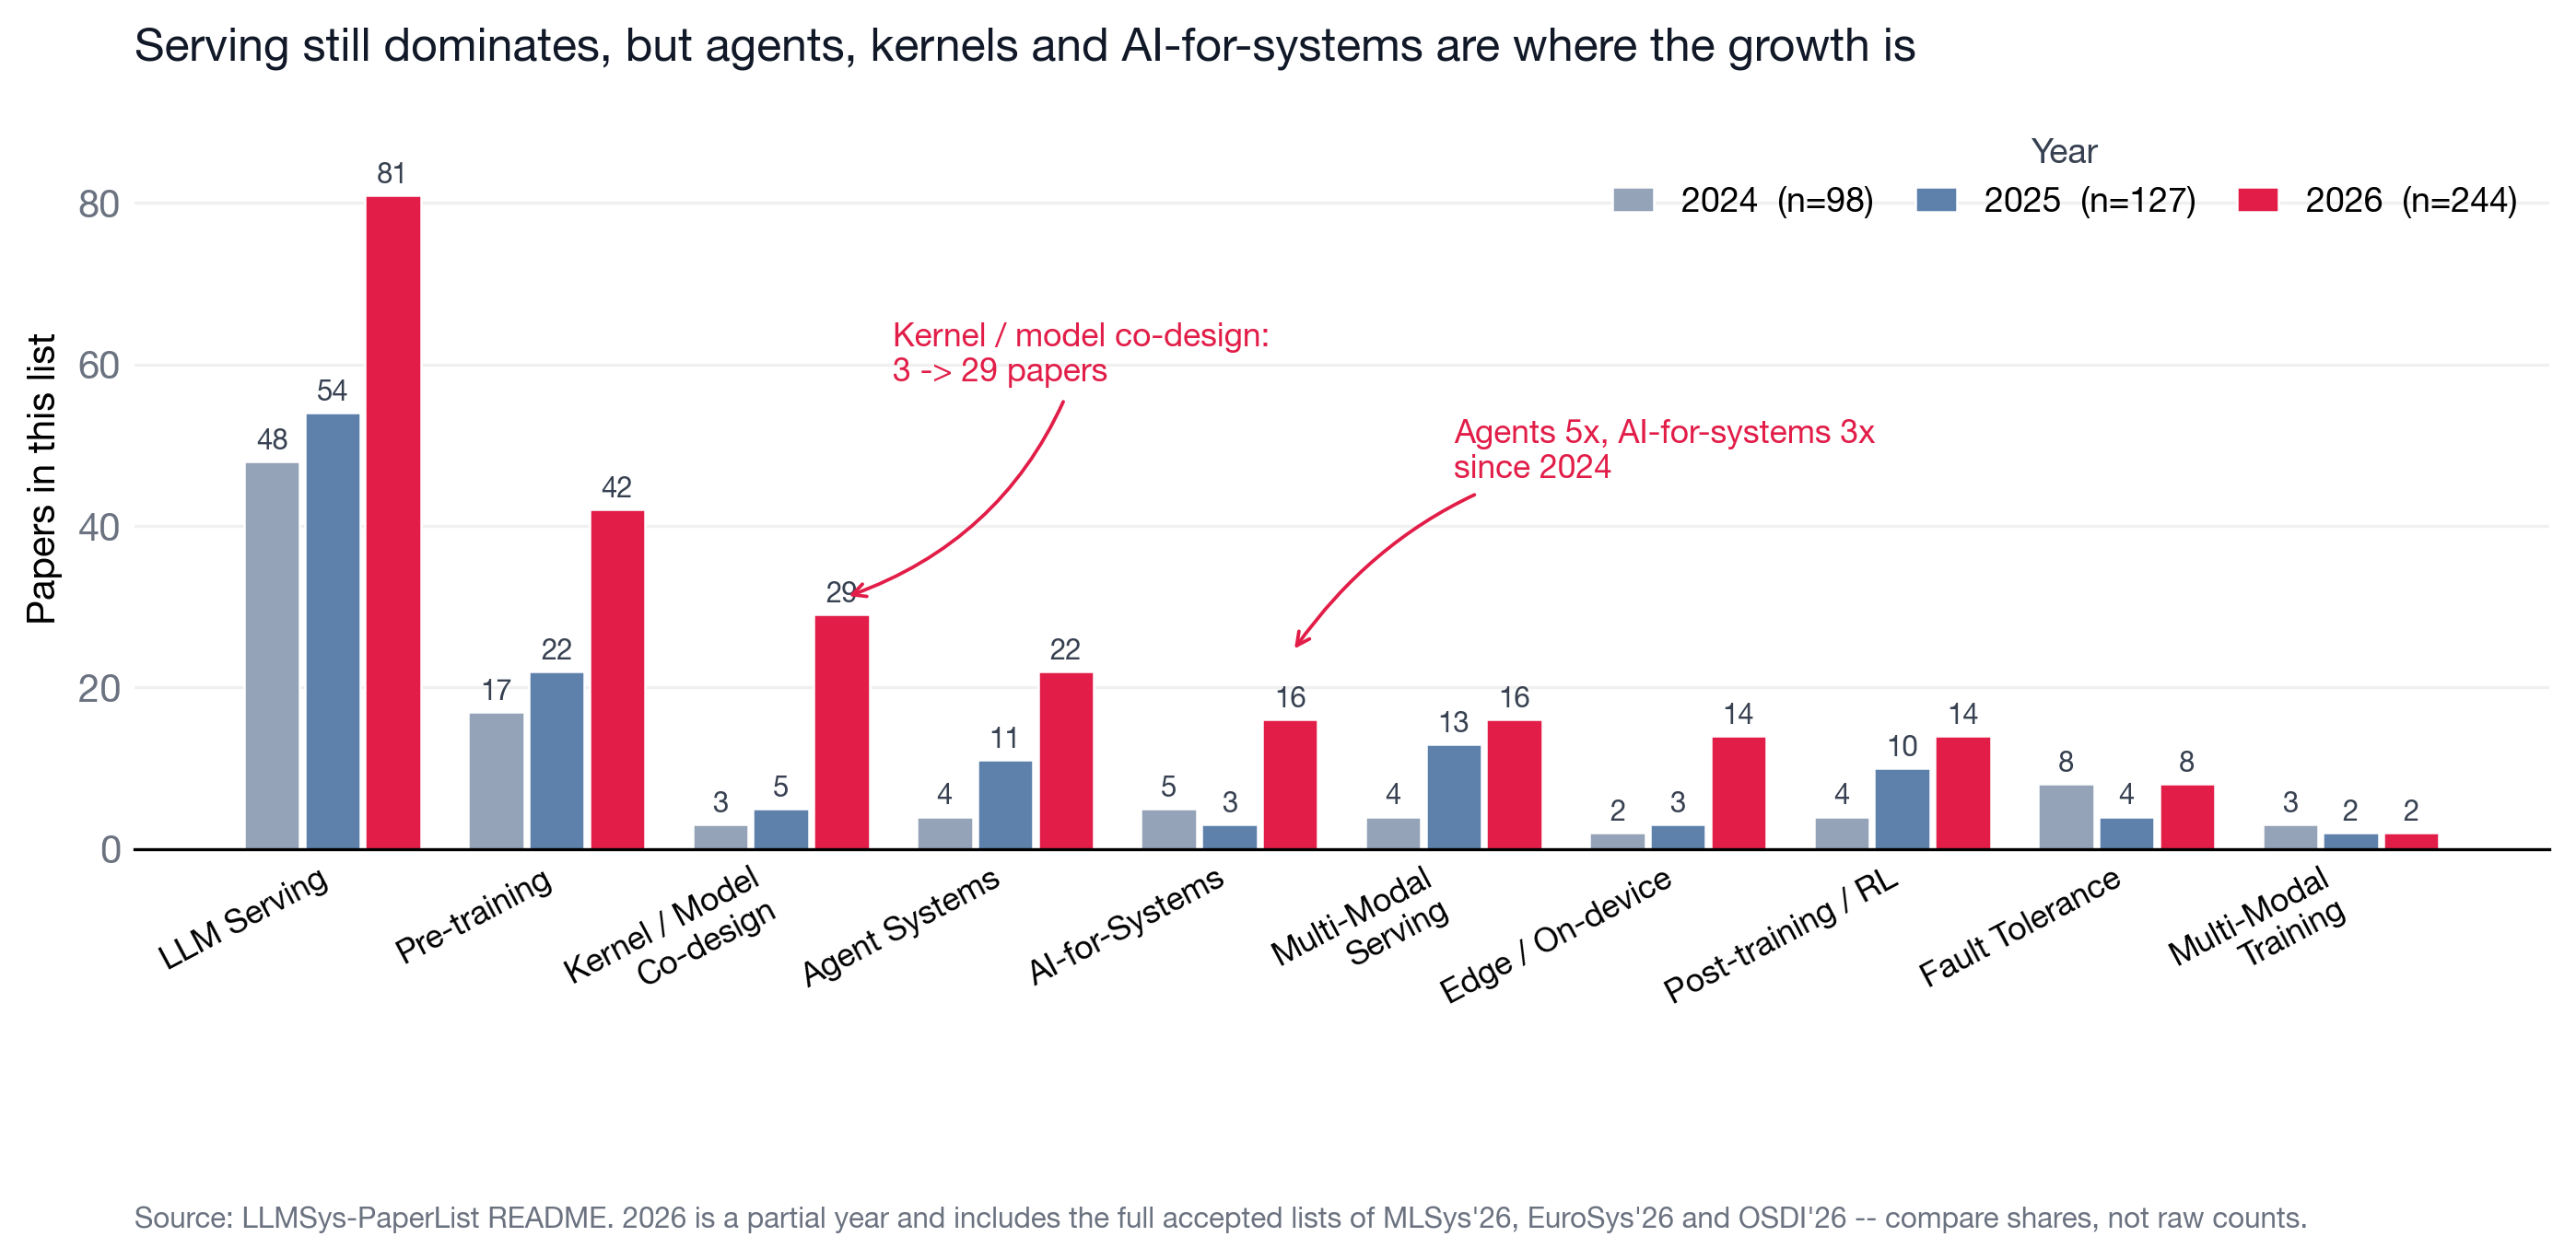
Serving is still the largest area in absolute terms, but its share of the list fell from 49% to 33% — the growth went to kernel/model co-design (3 → 29 papers), agentic systems (4 → 22), AI-for-systems (5 → 16) and edge (2 → 14).
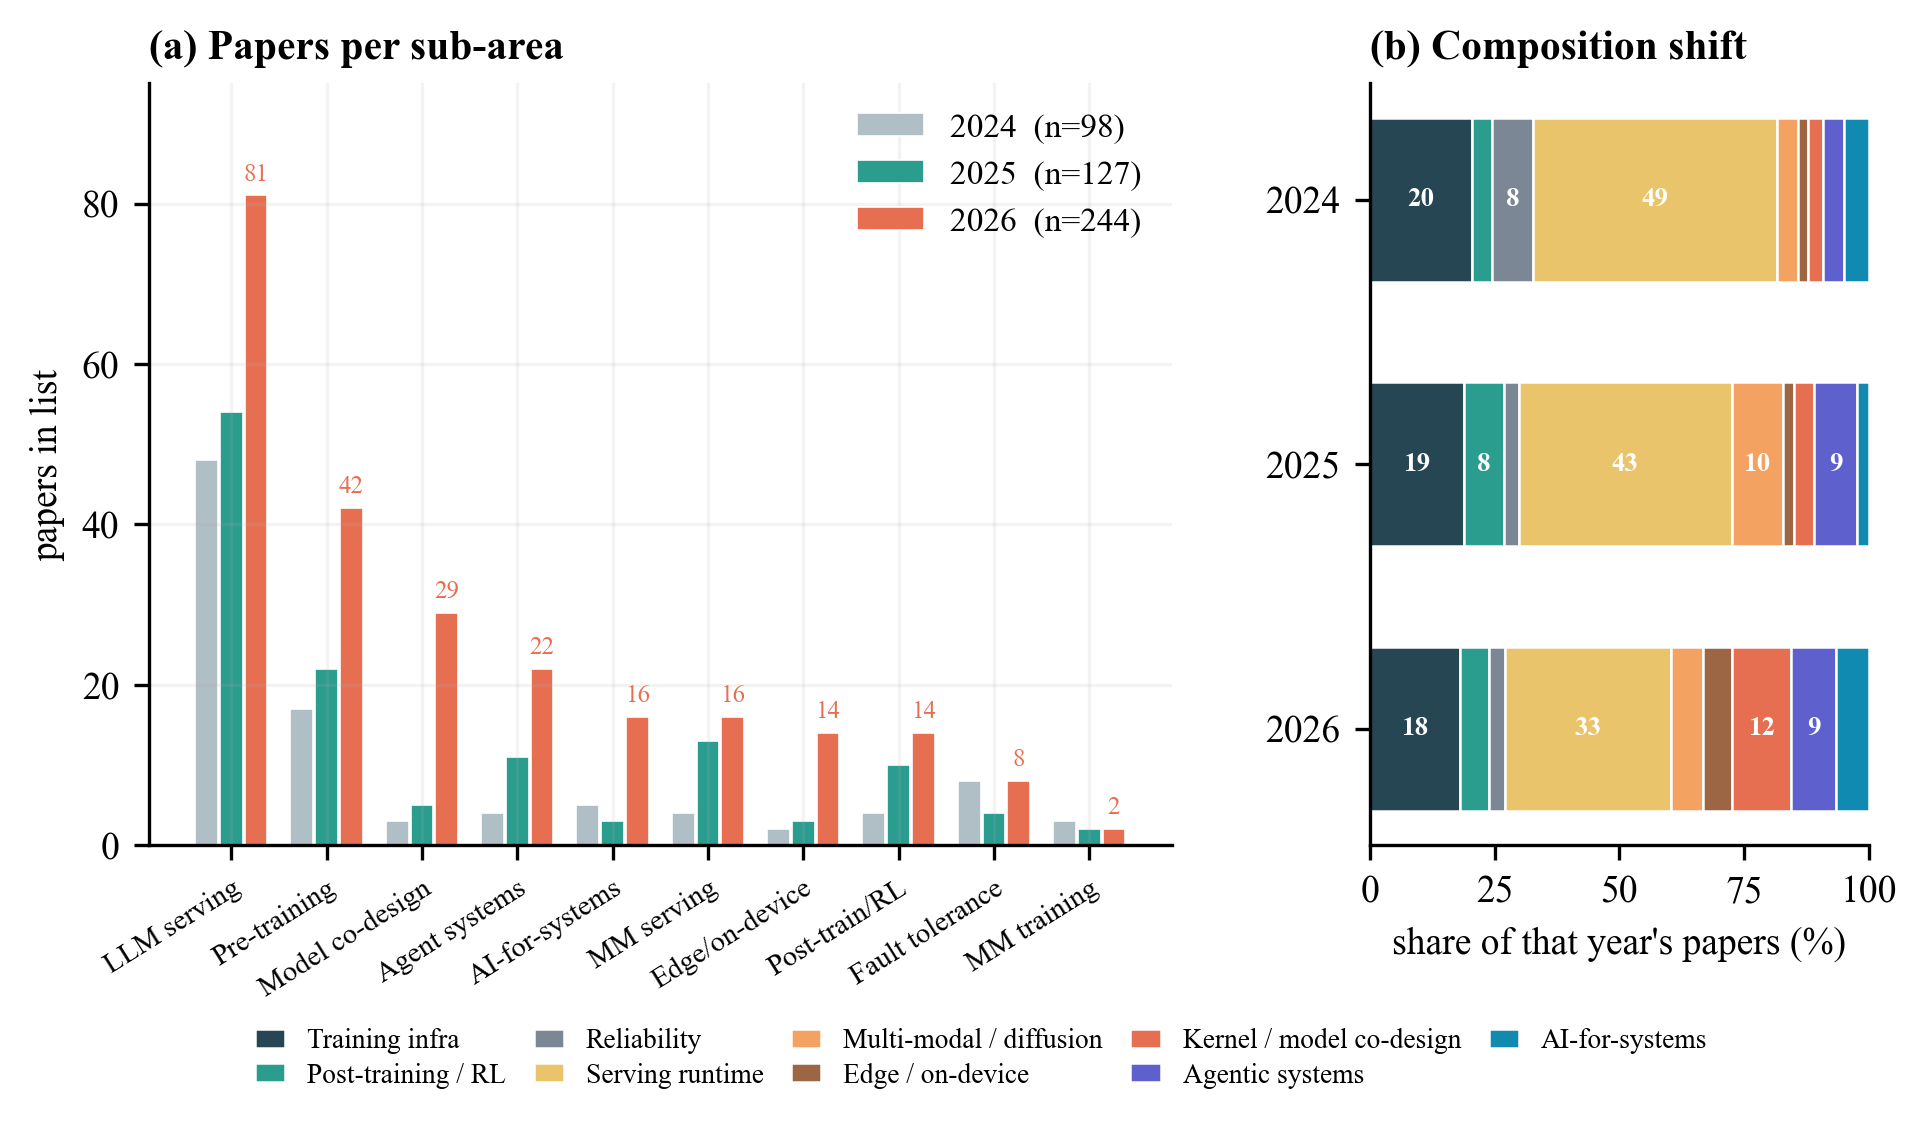
The fastest-rising techniques by share of the year's papers: agentic / multi-agent (1.0% → 13.1%), compiler / kernel / megakernel (0.0% → 10.2%), speculative decoding (1.0% → 5.7%), sparse attention (1.0% → 4.5%) and energy / power (1.0% → 3.3%).
→ Full analysis, per-technique numbers and reproduction scripts: trends/
Table of Contents
- Trends at a Glance
- LLM Systems
- LLM for Systems
- Industrial LLM Technical Report
- ML Conferences
- LLM Frameworks
- ML Systems
- Survey Paper
- LLM Benchmark / Leaderboard / Traces
- Related ML Readings
- MLSys Courses
- Other Reading
LLM Systems
Training
Pre-training
Before 2024
- Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism
- Efficient Large-Scale Language Model Training on GPU Clusters Using Megatron-LM
- Reducing Activation Recomputation in Large Transformer Models
- Optimized Network Architectures for Large Language Model Training with Billions of Parameters | MIT
- Carbon Emissions and Large Neural Network Training | Google, UCB
2024
- Perseus: Removing Energy Bloat from Large Model Training | SOSP' 24
- MegaScale: Scaling Large Language Model Training to More Than 10,000 GPUs | ByteDance
- DISTMM: Accelerating distributed multimodal model training | NSDI' 24
- Pipeline Parallelism with Controllable Memory | Sea AI Lab
- Boosting Large-scale Parallel Training Efficiency with C4: A Communication-Driven Approach
- Scaling Beyond the GPU Memory Limit for Large Mixture-of-Experts Model Training | ICML' 24
- Alibaba HPN: A Data Center Network for Large Language ModelTraining
- The Llama 3 Herd of Models (Section 3)
- Enabling Parallelism Hot Switching for Efficient Training of Large Language Models | SOSP' 24
- Revisiting Reliability in Large-Scale Machine Learning Research Clusters
- ScheMoE: An Extensible Mixture-of-Experts Distributed Training System with Tasks Scheduling | EuroSys '24
- DynaPipe : Optimizing Multi-task Training through Dynamic Pipelines | EuroSys '24
- HAP: SPMD DNN Training on Heterogeneous GPU Clusters with Automated Program Synthesis | EuroSys'24
- Demystifying Workload Imbalances in Large Transformer Model Training over Variable-length Sequences | PKU
- Improving training time and GPU utilization in geo-distributed language model training
- DeepSeek-V3 Technical Report
- Megalodon: Efficient LLM Pretraining and Inference with Unlimited Context Length
2025
- Comet: Fine-grained Computation-communication Overlapping for Mixture-of-Experts | ByteDance
- ByteScale : Efficient Scaling of LLM Training with a 2048K Context Length on More Than 12,000 GPUs | ByteDance
- SPPO:Efficient Long-sequence LLM Training via Adaptive Sequence Pipeline Parallel Offloading
- TileLink: Generating Efficient Compute-Communication Overlapping Kernels using Tile-Centric Primitives | MLSys' 25
- Every FLOP Counts: Scaling a 300B Mixture-of-Experts LING LLM without Premium GPUs| Ant Group
- FlexSP: Accelerating Large Language Model Training via Flexible Sequence Parallelism | ASPLOS '25
- WeiPipe: Weight Pipeline Parallelism for Communication-Effective Long-Context Large Model Training | PPoPP ’25
- WLB-LLM: Workload-Balanced 4D Parallelism for Large Language Model TraininG | OSDI' 25
- Mixtera: A Data Plane for Foundation Model Training | ETH
- Flex Attention: A Programming Model for Generating Optimized Attention Kernels | MLSys' 25
- Balancing Pipeline Parallelism with Vocabulary Parallelism | MLSys' 25
- SlimPipe: Memory-Thrifty and Efficient Pipeline Parallelism for Long-Context LLM Training | Kuaishou
- Scaling Llama 3 Training with Efficient Parallelism Strategies | ISCA' 25
- Lumos : Efficient Performance Modeling and Estimation for Large-scale LLM Training| MLSys' 25
- BurstEngine: an Efficient Distributed Framework for Training Transformers on Extremely Long Sequences of over 1M Tokens
- Robust LLM Training Infrastructure at ByteDance | SOSP' 25
- Sailor: Automating Distributed Training over Dynamic, Heterogeneous, and Geo-distributed Clusters | SOSP' 25
- Tempo: Compiled Dynamic Deep Learning with Symbolic Dependence Graphs | SOSP' 25
- Mycroft: Tracing Dependencies in Collective Communication Towards Reliable LLM Training | SOSP' 25
- DCP: Addressing Input Dynamism In Long-Context Training via Dynamic Context Parallelism | SOSP' 25
- TrainVerify: Equivalence-Based Verification for Distributed LLM Training | SOSP' 25
- Collective Communication for 100k+ GPUs: Large-scale collective communication optimization for massive GPU clusters
2026
- Arena: Efficiently Training Large Models via Dynamic Scheduling and Adaptive Parallelism Co-Design | EuroSys' 26
- Zeppelin: Balancing Variable-length Workloads in Data Parallel Large Model Training | EuroSys' 26
- RDMA Point-to-Point Communication for LLM Systems: RDMA-based point-to-point communication optimization for distributed LLM systems | MLSys' 26
- MoEBlaze: Breaking the Memory Wall for Efficient MoE Training on Modern GPUs | MLSys' 26
- Kareus: Joint Reduction of Dynamic and Static Energy in Large Model Training | OSDI' 26
- AXLearn: Modular Large Model Training on Heterogeneous Infrastructure | MLSys' 26
- MoSE: Mixture of Slimmable Experts for Efficient and Adaptive Language Models
- MegaScale-MoE: Large-Scale Communication-Efficient Training of Mixture-of-Experts Models in Production | EuroSys' 26
- MegaScale-Data: Scaling DataLoader for Multisource Large Foundation Model Training | EuroSys' 26
- HetAuto: Cross-Cluster Auto-Parallelism for Heterogeneous Distributed Training | EuroSys' 26
- HARP: Orchestrating Automated Parallel Training on Heterogeneous GPU Clusters | EuroSys' 26
- Crimson: Collaborative Parameter Updates for Efficient Pipeline Training of Large Language Models | EuroSys' 26
- Suika: Efficient and High-quality Re-scheduling of 3D-parallelized LLM Training Jobs in Shared Clusters | EuroSys' 26
- Efficient and Adaptable Overlapping for Computation and Communication via Signaling and Reordering | EuroSys' 26
- BOOST: BOttleneck-Optimized Scalable Training Framework for Low-Rank Large Language Models | MLSys' 26
- MTraining: Distributed Dynamic Sparse Attention for Efficient Ultra-Long Context Training | MLSys' 26
- ProTrain: Efficient LLM Training via Automatic Memory Management | MLSys' 26
- DreamDDP: Accelerating Data Parallel Distributed LLM Training with Layer-wise Scheduled Partial Synchronization | MLSys' 26
- Multipath Collective Communication Beyond Scale-up Networks in GPU Clouds | EuroSys' 26
- STAlloc: Enhancing Memory Efficiency in Large-Scale Model Training through Spatio-Temporal Allocation Planning | EuroSys' 26
- Maya: Optimizing Deep Learning Training Workloads using GPU Runtime Emulation | EuroSys' 26
- Bridging the GPU Utilization Gap: Predictive Multi-Dimensional Resource Scheduling for AI Workloads | EuroSys' 26
- Reducing the GPU Memory Bottleneck with Lossless Compression for ML | EuroSys' 26
- Efficient Long-Context LM Training by Core Attention Disaggregation | MLSys' 26
- Zorse: Optimizing LLM Training Efficiency on Heterogeneous GPU Clusters | MLSys' 26
- Unleashing Scalable Context Parallelism via Fully Connected Pipeline | MLSys' 26
- FlexTrain: Scalable Hybrid-Parallel Training for Long-Context LLMs | MLSys' 26
- veScale-FSDP: Flexible and High-Performance FSDP at Scale | MLSys' 26
- HexiScale: LLM Training over Heterogeneous Hardware | MLSys' 26
- FP8-Flow-MoE: Casting-Free FP8 Recipe for MoE without Double Quantization Error | MLSys' 26
- PithTrain: A Compact and Agent-Native MoE Training System with 4D Parallelism and FP8 | CMU
- Olmix: A Framework for Data Mixing Throughout LM Development | Stanford
- SuperOffload: Unleashing the Power of Large-Scale LLM Training on Superchips | ASPLOS' 26
- AutoSP: Unlocking Long-Context LLM Training via Compiler-Based Sequence Parallelism | ICLR' 26
- SYMI: Efficient Mixture-of-Experts Training via Model and Optimizer State Decoupling | NSDI' 26
- Tessera: A Holistic Pipeline Parallelism Framework for Trillion-Parameter Heterogeneous MoE Training | OSDI' 26
- Hetu v2: A General and Scalable Deep Learning System with Hierarchical and Heterogeneous SPMD Annotations | OSDI' 26
- Syncopate: Efficient Multi-GPU AI Kernels via Automatic Chunk-Centric Compute-Communication Overlap | OSDI' 26
- Teaching the Old Dog New Tricks: Building Efficient Data Pipelines for Large-Scale LLM Pre-Training | OSDI' 26
- Cocoon: A System Architecture for Differentially Private Training with Correlated Noises | OSDI' 26
- Heterogeneity at Hyperscale: Characterization and Scheduling of Large Production AI Clusters at Alibaba | OSDI' 26
- Quota Marketplace: Dynamic Pricing for Efficient Allocation of ML Training Resources | OSDI' 26
Systems for Post-training / RLHF
2024
- Ymir: A Scheduler for Foundation Model Fine-tuning Workloads in Datacenters | ICS' 24
- HybridFlow: A Flexible and Efficient RLHF Framework
- ReaLHF: Optimized RLHF Training for Large Language Models through Parameter Reallocation
- NeMo-Aligner: Scalable Toolkit for Efficient Model Alignment | Nvidia
2025
- RLHFuse: Efficient RLHF Training for Large Language Models with Inter- and Intra-Stage Fusion | NSDI'25
- Systems Opportunities for LLM Fine-Tuning using Reinforcement Learning
- AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning | Code | Ant
- StreamRL: Scalable, Heterogeneous, and Elastic RL for LLMs with Disaggregated Stream Generation
- RL-Factory: Train your Agent model via our easy and efficient framework
- PLoRA: Efficient LoRA Hyperparameter Tuning for Large Models
- History Rhymes: Accelerating LLM Reinforcement Learning with RhymeRL
- APRIL: Active Partial Rollouts in Reinforcement Learning to tame long-tail generation
- Seer: Online Context Learning for Fast Synchronous LLM Reinforcement Learning | OSDI' 26
- SkyRL-Agent: Efficient RL Training for Multi-turn LLM Agent
2026
- Laminar: A Scalable Asynchronous RL Post-Training Framework | EuroSys' 26
- LoRAFusion: Efficient LoRA Fine-Tuning for LLMs | EuroSys' 26
- HetRL: Efficient Reinforcement Learning for LLMs in Heterogeneous Environments | MLSys' 26
- ReSpec: Towards Optimizing Speculative Decoding in Reinforcement Learning Systems | MLSys' 26
- Beat the Long Tail: Distribution-Aware Speculative Decoding for Reinforcement Learning | MLSys' 26
- FLoRIST: Federated Low-Rank Adaptation with Random Subspaces for LLMs | MLSys' 26
- Taming the Long-Tail: Efficient Reasoning RL Training with an Adaptive Drafter | ASPLOS' 26
- Aurora: When RL Meets Adaptive Speculative Training — A Unified Training-Serving System
- AstraFlow: Dataflow-Oriented Reinforcement Learning for Agentic LLMs | CMU
- RLBoost: Harvesting Preemptible Cloud Resources for Cost-Efficient Reinforcement Learning on LLMs | NSDI' 26
- Weave: Efficient Co-Scheduling for Disaggregated RL Post-Training | OSDI' 26
- RLinf: Flexible and Efficient Large-Scale Reinforcement Learning via Macro-to-Micro Flow Transformation | OSDI' 26
- DynaRL: Flexible and Dynamic Scheduling of Large-Scale Reinforcement Learning Training | OSDI' 26
- RollArt: Disaggregated Multi-Task Agentic RL Training at Scale | OSDI' 26
Fault Tolerance / Straggler Mitigation
Before 2024
2024
- FALCON: Pinpointing and Mitigating Stragglers for Large-Scale Hybrid-Parallel Training
- Malleus: Straggler-Resilient Hybrid Parallel Training of Large-scale Models via Malleable Data and Model Parallelization
- Fire-Flyer AI-HPC: A Cost-Effective Software-Hardware Co-Design for Deep Learning | DeepSeek SC' 24
- Lazarus: Resilient and Elastic Training of Mixture-of-Experts Models with Adaptive Expert Placement
- ByteCheckpoint: A Unified Checkpointing System for LLM Development
- ReCycle: Resilient Training of Large DNNs using Pipeline Adaptation | SOSP' 24
- Minder: Faulty Machine Detection for Large-scale Distributed Model Training | THU
- TrainMover: An Interruption-Resilient Runtime for ML Training | Alibaba, OSDI' 26
2025
- The Streaming Batch Model for Efficient and Fault-Tolerant Heterogeneous Execution
- Characterizing GPU Resilience and Impact on AI/HPC Systems | UIUC
- Understanding Stragglers in Large Model Training Using What-if Analysis | OSDI' 25
- BitSnap: Checkpoint Sparsification and Quantization in LLM Training
2026
- GoCkpt: Gradient-Assisted Multi-Step Overlapped Checkpointing for Efficient LLM Training | PPoPP' 26
- Handling Network Faults in Distributed AI Training: Failover is Now an Option | EuroSys' 26
- GUARD: Scalable Straggler Detection and Mitigation in LLM Training | MLSys' 26
- Sparse Checkpointing for Fast and Reliable MoE Training (MoEvement): In-Memory Sparse Checkpointing and Localized Recovery | NSDI' 26
- SDCs in the Wild: Characterizing and Diagnosing SDC-Defective GPUs in Production LLM Training | OSDI' 26
- Safeguarding LLM Training at Scale: Online SDC Detection and Insights from 35 Million GPU Hours | OSDI' 26
- OpGuard: Bitwise Alignment for Precise and General Debugging of Production LLM Training | OSDI' 26
- RobustRL: Role-Based Fault Tolerance System for RL Post-Training | OSDI' 26
Serving
LLM serving
Before 2024
- Orca: A Distributed Serving System for Transformer-Based Generative Models | OSDI'22
- Response Length Perception and Sequence Scheduling: An LLM-Empowered LLM Inference Pipeline | NUS
- Efficiently Scaling Transformer Inference | MLSys' 23
- Flover: A Temporal Fusion Framework for Efficient Autoregressive Model Parallel Inference
- FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
- DeepSpeed Inference : Enabling Efficient Inference of Transformer Models at Unprecedented Scale.
- TurboTransformers: An Efficient GPU Serving System For Transformer Models
- FlexGen: High-throughput Generative Inference of Large Language Models with a Single GPU | ICML' 23
- MPCFormer : fast, performant, and private transformer inference with MPC | ICLR'23
- POLCA: Power Oversubscription in LLM Cloud Providers | Microsoft
- SARATHI: Efficient LLM Inference by Piggybacking Decodes with Chunked Prefills | Microsoft
- AttMemo: Accelerating Self-Attention with Memoization on Big Memory Systems
- vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | SOSP' 23
- Tabi: An Efficient Multi-Level Inference System for Large Language Models | EuroSys' 23
- AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation | Microsoft
- FlashDecoding++: Faster Large Language Model Inference on GPUs | Tsinghua
- DeepSpeed-MII: Model Implementations for Inference (MII) | Microsoft
- SuperServe: Fine-Grained Inference Serving for Unpredictable Workloads
2024
- FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision
- Flash-LLM: Enabling Cost-Effective and Highly-Efficient Large Generative Model Inference with Unstructured Sparsity | VLDB' 24
- Punica: Multi-Tenant LoRA Serving | MLSys' 24
- S-LoRA: Serving Thousands of Concurrent LoRA Adapters | MLSys' 24
- SpotServe: Serving Generative Large Language Models on Preemptible Instances | CMU
- Fairness in Serving Large Language Models | OSDI' 24
- Infinite-LLM: Efficient LLM Service for Long Context with DistAttention and Distributed KVCache
- CaraServe: CPU-Assisted and Rank-Aware LoRA Serving for Generative LLM Inference
- DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving| OSDI' 24
- Inference without Interference: Disaggregate LLM Inference for Mixed Downstream Workloads
- APIServe: Efficient API Support for Large-Language Model Inferencing
- FlexLLM: A System for Co-Serving Large Language Model Inference and Parameter-Efficient Finetuning
- DéjàVu: KV-cache Streaming for Fast, Fault-tolerant Generative LLM Serving
- Optimizing LLM Queries in Relational Workloads | UCB
- AttentionStore: Cost-effective Attention Reuse across Multi-turn Conversations in Large Language Model Serving | NUS
- MuxServe: Flexible Multiplexing for Efficient Multiple LLM Serving
- LoongServe: Efficiently Serving Long-context Large Language Models with Elastic Sequence Parallelism | SOSP' 24
- RAGCache: Efficient Knowledge Caching for Retrieval-Augmented Generation | PKU
- Andes: Defining and Enhancing Quality-of-Experience in LLM-Based Text Streaming Services | Umich
- BlockLLM: Multi-tenant Finer-grained Serving for Large Language Models
- vAttention: Dynamic Memory Management for Serving LLMs without PagedAttention
- Helix: Distributed Serving of Large Language Models via Max-Flow on Heterogeneous GPUs | CMU
- Eloquent: A More Robust Transmission Scheme for LLM Token Streaming | NAIC' 24
- Optimizing Speculative Decoding for Serving Large Language Models Using Goodput | UCB
- Enabling Elastic Model Serving with MultiWorld | Cisco Research
- Prepacking: A Simple Method for Fast Prefilling and Increased Throughput in Large Language Models
- NanoFlow: Towards Optimal Large Language Model Serving Throughput
- Responsive ML inference in multi-tenanted environments using AQUA
- One Queue Is All You Need: Resolving Head-of-Line Blocking in Large Language Model Serving
- MemServe: Context Caching for Disaggregated LLM Serving with Elastic Memory Pool
- dLoRA: Dynamically Orchestrating Requests and Adapters for LoRA LLM Serving | OSDI' 24
- Llumnix: Dynamic Scheduling for Large Language Model Serving | OSDI' 24
- Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve | OSDI' 24
- InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management
- ServerlessLLM: Low-Latency Serverless Inference for Large Language Models | OSDI' 24
- CacheGen: KV Cache Compression and Streaming for Fast Large Language Model Serving | SIGCOMM' 24
- Preble: Efficient Distributed Prompt Scheduling for LLM Serving
- Mnemosyne: Parallelization Strategies for Efficiently Serving Multi-Million Context Length LLM Inference Requests Without Approximations
- ConServe: Harvesting GPUs for Low-Latency and High-Throughput Large Language Model Serving
- BlockLLM: Multi-tenant Finer-grained Serving for Large Language Models
- Context Parallelism for Scalable Million-Token Inference
- Pie: Pooling CPU Memory for LLM Inference
- NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference
- FastSwitch: Optimizing Context Switching Efficiency in Fairness-aware Large Language Model Serving
- Flash Communication: Reducing Tensor Parallelization Bottleneck for Fast Large Language Model Inference
- Fast Inference for Augmented Large Language Models
- A System for Microserving of LLMs | CMU
- TokenFlow: Responsive LLM Text Streaming Serving under Request Burst via Preemptive Scheduling | Plagiarism
2025
- SageAttention: Accurate 8-Bit Attention for Plug-and-play Inference Acceleration | ICLR 2025
- SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization | ICML 2025
- SageAttention3: SageAttention3: Microscaling FP4 Attention for Inference and An Exploration of 8-Bit Training | NeurIPS 2025 spotlight
- SageAttention2++: SageAttention2++: A More Efficient Implementation of SageAttention2 | ICML ES-FoMo Workshop 2025
- FlashInfer: Efficient and Customizable Attention Engine for LLM Inference Serving
- iServe : An Intent-based Serving System for LLMs| UT Austin
- Locality-aware Fair Scheduling in LLM Serving | UCB
- Towards Efficient Large Multimodal Model Serving | MSFT
- DeltaZip: Efficient Serving of Multiple Full-Model-Tuned LLMs
- PIM Is All You Need: A CXL-Enabled GPU-Free System for Large Language Model Inference | ASPLOS' 25
- λScale: Enabling Fast Scaling for Serverless Large Language Model Inference
- AIBrix: Towards Scalable and Cost-Effective LLM Inference Infrastructure | vLLM
- Serving Models, Fast and Slow:Optimizing Heterogeneous LLM Inferencing Workloads at Scale
- Make LLM Inference Affordable to Everyone: Augmenting GPU Memory with NDP-DIMM
- Jenga: Effective Memory Management for Serving LLM with Heterogeneity
- AQUA : Network-Accelerated Memory Offloading for LLMs in Scale-Up GPU Domains | ASPLOS 2025
- MegaScale-Infer: Serving Mixture-of-Experts at Scale with Disaggregated Expert Parallelism | Bytedance
- Towards End-to-End Optimization of LLM-based Applications with Ayo | ASPLOS '25
- CacheBlend : Fast Large Language Model Serving for RAG with Cached Knowledge Fusion | EuroSys' 25 (Best Paper)
- ThunderServe: High-performance and Cost-efficient LLM Serving in Cloud Environments | MLSys' 25
- SLOs-Serve: Optimized Serving of Multi-SLO LLMs
- Tempo: Application-aware LLM Serving with Mixed SLO Requirements
- Hogwild! Inference: Parallel LLM Generation via Concurrent Attention
- Prism: Cost-Efficient Multi-LLM Serving via GPU Memory Ballooning | UCLA, OSDI' 26
- RetroInfer: A Vector-Storage Approach for Scalable Long-Context LLM Inference
- Efficient Serving of LLM Applications with Probabilistic Demand Modeling
- eLLM : Elastic Memory Management Framework for Efficient LLM Serving
- DiSCo: Device-Server Collaborative LLM-Based Text Streaming Services
- DynaServe: Unified and Elastic Execution for Dynamic Disaggregated LLM Serving
- HyGen: Efficient LLM Serving via Elastic Online-Offline Request Co-location
- WaferLLM: A Wafer‑Scale LLM Inference System | OSDI 25
- BlitzScale: Fast and Live Large Model Autoscaling with O(1) Host Caching | OSDI 25
- Nexus: Taming Throughput-Latency Tradeoff in LLM Serving via Efficient GPU Sharing
- Taming the Chaos: Coordinated Autoscaling for Heterogeneous and Disaggregated LLM Inference | Seed
- TokenLake: A Unified Segment-level Prefix Cache Pool for Fine-grained Elastic Long-Context LLM Serving
- Expert-as-a-Service: Towards Efficient, Scalable, and Robust Large-scale MoE Serving
- Shift Parallelism: Low-Latency, High-Throughput LLM Inference for Dynamic Workloads
- Defeating Nondeterminism in LLM Inference
- Deterministic Inference across Tensor Parallel Sizes That Eliminates Training-Inference Mismatch: Ensuring deterministic inference across different tensor parallelism configurations
- The Cost of Dynamic Reasoning: Demystifying AI Agents and Test-Time Scaling from an AI Infrastructure Perspective
- Barbarians at the Gate: How AI is Upending Systems Research
- Mercury: Unlocking Multi-GPU Operator Optimization for LLMs via Remote Memory Scheduling | SOSP' 25
- DiffKV: Differentiated Memory Management for Large Language Models with Parallel KV Compaction | SOSP' 25
- Pie: A Programmable Serving System for Emerging LLM Applications | SOSP' 25
- Aegaeon: Effective GPU Pooling for Concurrent LLM Serving on the Market | SOSP' 25
- Jenga: Effective Memory Management for Serving LLM with Heterogeneity | SOSP' 25
- IC-Cache: Efficient Large Language Model Serving via In-context Caching | SOSP' 25
- PrefillOnly: An Inference Engine for Prefill-only Workloads in Large Language Model Applications | SOSP' 25
- KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models | SOSP' 25
- The ML.ENERGY Benchmark: Toward Automated Inference Energy Measurement and Optimization | NeurIPS' 25
- Serve Programs, Not Prompts: Efficient LLM serving system for structured program execution
- Continuum: Efficient and Robust Multi-Turn LLM Agent Scheduling with KV Cache Time-to-Live
- BestServe: Serving Strategies with Optimal Goodput in Collocation and Disaggregation Architectures
- Online Scheduling for LLM Inference with KV Cache Constraints: Optimal Batching and Scheduling for KV Cache-Constrained Inference
2026
- TokenWeave: Efficient Compute-Communication Overlap for Distributed LLM Inference | Code | MLSys' 26
- AIConfigurator: Lightning-Fast Configuration Optimization for Multi-Framework LLM Serving
- SuperInfer: SLO-Aware Rotary Scheduling and Memory Management for LLM Inference on Superchips | MLSys' 26
- Scaling Up Efficient Small Language Models Serving: Serving and Deployment for Semantic Job Search | MLSys' 26
- OptiKIT: Meeting SLOs, Slashing Hours - Automated Enterprise LLM Optimization | MLSys' 26
- BlendServe: Optimizing Offline Inference for Auto-regressive Large Models with Resource-aware Batching | ASPLOS' 26
- SwiftSpec: Ultra-Low Latency LLM Decoding by Scaling Asynchronous Speculative Decoding with Disaggregated Pipeline and Fused Kernels | ASPLOS' 26
- MuxWise: Towards High-Goodput LLM Serving with Prefill-decode Multiplexing | ASPLOS' 26
- MoEless: Efficient MoE LLM Serving via Serverless Computing
- BiScale: Energy-Efficient Disaggregated LLM Serving via Phase-Aware Placement and DVFS
- Harvest: Opportunistic Peer-to-Peer GPU Caching for LLM Inference
- MineDraft: A Framework for Batch Parallel Speculative Decoding — overlaps drafting and verification across two batches, hiding draft latency. Up to +75% throughput, -39% latency. Integrated into vLLM. | NUS & MIT
- Foundry: Template-Based CUDA Graph Context Materialization for Fast LLM Serving Cold Start
- AdaServe: Accelerating Multi-SLO LLM Serving with SLO-Customized Speculative Decoding | EuroSys' 26
- FlexPipe: Adapting Dynamic LLM Serving Through Inflight Pipeline Refactoring in Fragmented Serverless Clusters | EuroSys' 26
- Taming Latency-Memory Trade-Off in MoE-Based LLM Serving via Fine-Grained Expert Offloading | EuroSys' 26
- KunServe: Parameter-centric Memory Management for Efficient Memory Overloading Handling in LLM Serving | EuroSys' 26
- AdaGen: Workload-Adaptive Cluster Scheduler for Latency-Optimal LLM Inference Serving | EuroSys' 26
- SkyWalker: A Locality-Aware Cross-Region Load Balancer for LLM Inference | EuroSys' 26
- High Throughput and Low Latency LLM Serving via Adaptive KV Caching | EuroSys' 26
- PARD: Enhancing Goodput for Inference Pipeline via Proactive Request Dropping | EuroSys' 26
- PiLLM: Resource-Efficient LLM Inference Using Workload Prediction | EuroSys' 26
- Automated End-to-End Model Serving with Cooperative Compilation and Scheduling | EuroSys' 26
- MFS: An Efficient Model Family Serving System for LLMs | EuroSys' 26
- CRAFT: Cost-aware Expert Replica Allocation with Fine-Grained Layerwise Estimations for Efficient MoE Serving | MLSys' 26
- MorphServe: Efficient and Workload-Aware LLM Serving via Runtime Quantized Layer Swapping and KV Cache Resizing | MLSys' 26
- FlexiCache: Leveraging Temporal Stability of Attention Heads for Efficient KV Cache Management | MLSys' 26
- Kitty: Accurate and Efficient 2-bit KV Cache Quantization with Dynamic Channel-wise Precision Boost | MLSys' 26
- SkipKV: Selective Skipping of KV Generation and Storage for Efficient Inference with Large Reasoning Models | MLSys' 26
- BOute: Cost-Efficient LLM Serving with Heterogeneous LLMs and GPUs via Multi-Objective Bayesian Optimization | MLSys' 26
- From Tokens to Layers: Redefining Stall-Free Scheduling for LLM Serving with Layered Prefill | MLSys' 26
- HELIOS: Adaptive Model And Early-Exit Selection for Efficient LLM Inference Serving | MLSys' 26
- BatchLLM: Optimizing Large Batched LLM Inference with Global Prefix Sharing and Throughput-oriented Token Batching | MLSys' 26
- GhostServe: A Lightweight Checkpointing System in the Shadow for Fault-Tolerant LLM Serving | MLSys' 26
- PRISM: Parametrically Refactoring Inference for Speculative Decoding Draft Models | MLSys' 26
- FarSkip-Collective: Unhobbling Blocking Communication in Mixture of Experts Models | MLSys' 26
- Efficient Data Passing for Serverless Inference Workflows: A GPU-Centric Approach | EuroSys' 26
- TrustWeave: Integrity Measurement and Attestation for Multi-Cloud LLMs | EuroSys' 26
- Stream2LLM: Overlapping Context Streaming and Prefill for Low-Latency LLM Serving | MLSys' 26
- Locality-Aware Beam Scheduling for Efficient Test-Time Compute | MLSys' 26
- Optimizing Deployment Configurations for LLM Inference | MLSys' 26
- ContextPilot: Fast Long-Context Inference via Context Reuse | MLSys' 26
- Speculative Decoding: Performance or Illusion? | MLSys' 26
- SHIP: SRAM-Based Huge Inference Pipelines for Fast LLM Serving | MLSys' 26
- BEAM: Joint Resource-Power Optimization for LLM Inference | MLSys' 26
- Beyond the Buzz: A Pragmatic Take on Inference Disaggregation | MLSys' 26
- PLA-Serve: Prefill-Length-Aware LLM Serving System | MLSys' 26
- Accelerating Reasoning Model Inference with Sparse Self-Speculative Decoding | MLSys' 26
- FaaScale: Unlocking Fast LLM Scaling for Serverless Inference | MLSys' 26
- Breaking the Ice: Analyzing Cold Start Latency in vLLM | MLSys' 26
- Demystifying the Mixture of Experts Serving Tax | MLSys' 26
- RaidServe: High-Performance Resilient LLM Serving | MLSys' 26
- Toward Principled LLM Safety Testing: Solving the Jailbreak Oracle Problem | MLSys' 26
- ZeRO-Prefill: Zero Redundancy Overheads in MoE Prefill Serving
- SkyNomad: On Using Multi-Region Spot Instances to Minimize AI Batch Job Cost | UCB
- Qrita: High-performance Top-k and Top-p Algorithm for GPUs using Pivot-based Truncation and Selection | UCB
- The Time is Here for Just-in-Time Systems: Challenges and Opportunities for Adaptive AI/ML Serving | UCB
- Event Tensor: A Unified Abstraction for Compiling Dynamic Megakernels for Low-Latency Serving | MLSys' 26
- XGrammar-2: Efficient Dynamic Structured Generation Engine for Agentic LLMs | CMU
- Prism (Superoptimizer): Symbolic Superoptimization of Tensor Programs | CMU
- Coral: Cost-Efficient Multi-LLM Serving over Heterogeneous Cloud GPUs | CMU
- LAPS: A Length-Aware-Prefill LLM Serving System | CMU/MBZUAI
- Where Do the Joules Go?: Diagnosing Inference Energy Consumption | UMich
- SYMPHONY: Enabling Compute-Memory Disaggregation in LLM Serving Systems | NSDI' 26
- OpenTela: Unifying Decentralized Computing Resources for Heterogeneous LLM Serving | OSDI' 26
- Speculative Speculative Decoding: Parallelizing the Speculate-then-Verify Dependency | ICLR' 26
- WWW.Serve: Interconnecting Global LLM Services through Decentralization | CMU
- Not All Prefills Are Equal: PPD Disaggregation for Multi-turn LLM Serving | UChicago
- Hexcute: A Compiler Framework for Automating Layout Synthesis in GPU Programs | CGO' 26
- AutoScout: Structured Optimization for Automating ML System Configuration | UT Austin
- VoltanaLLM: Energy-Efficient and SLO-Aware Disaggregated LLM Serving | ISC' 26
- Regulating Branch Parallelism in LLM Serving: Balancing Intra-Request Branch Admission against Co-batched Latency | Stanford
- Strata: Hierarchical Context Caching for Long-Context LLM Serving | OSDI' 26
- ECHO: Efficient KV Cache Offloading with Lossless Prefetching for Serving Native Sparse Attention LLMs | OSDI' 26
- No Buffer, No Bottleneck: Efficient Zero-Copy KV Cache Offloading for Long-Context LLMs | OSDI' 26
- Simple Is Better: Multiplication May Be All You Need for LLM Request Scheduling | OSDI' 26
- BatchGen: An Architecture for Scalable and Efficient Batch Inference | OSDI' 26
- Efficient LLM Serving on Commodity GPU Clusters: Data-Reduced Cross-Instance Orchestration for LLM Serving | OSDI' 26
- Revisiting Pipeline Parallelism for LLM Serving: Revisiting pipeline parallelism as an alternative to tensor parallelism for online LLM serving | OSDI' 26
- Kairox: Adaptive GPU-CPU Hybrid LLM Inference via Online Neuron Balancing | OSDI' 26
- StriaTrace: Efficient Tracing and Diagnosis for Online LLM Inference | OSDI' 26
Agent Systems
2024
- ALTO: An Efficient Network Orchestrator for Compound AI Systems | Stanford & UCB
- Parrot: Efficient Serving of LLM-based Applications with Semantic Variable | OSDI' 24
- Efficiently Serving LLM Reasoning Programs with Certaindex | UCSD
- DroidSpeak: KV Cache Sharing for Cross-LLM Communication and Multi-LLM Serving
2025
- Supporting Our AI Overlords: Redesigning Data Systems to be Agent-First | UCB
- Autellix: An Efficient Serving Engine for LLM Agents as General Programs | UCB
- RAGO: Systematic Performance Optimization for Retrieval-Augmented Generation Serving | ISCA'25
- Circinus: Efficient Query Planner for Compound ML Serving | UIUC
- Patchwork: A Unified Framework for RAG Serving
- DS SERVE: A Framework for Efficient and Scalable Neural Retrieval | UCB
- KVFlow: Efficient Prefix Caching for Accelerating LLM-Based Multi-Agent Workflows
- Murakkab: Resource-Efficient Agentic Workflow Orchestration in Cloud Platforms | OSDI' 26
- HedraRAG: Co-Optimizing Generation and Retrieval for Heterogeneous RAG Workflows | SOSP' 25
- METIS: Fast Quality-Aware RAG Systems with Configuration Adaptation | SOSP' 25
- Aragog: Just-in-Time Model Routing for Scalable Serving of Agentic Workflows
2026
- DualPath: Breaking the Storage Bandwidth Bottleneck in Agentic LLM Inference | DeepSeek
- AIMS: Cost-Efficient LLM-Based Agent Deployment in Hybrid Cloud-Edge Environments | EuroSys' 26
- From Imperative to Declarative: Towards LLM-friendly OS Interfaces for Boosted Computer-Use Agents | EuroSys' 26
- Hippocampus: An Efficient and Scalable Memory Module for Agentic AI | MLSys' 26
- PROMPTS: Performance Optimization via Multi-Agent Planning for Test-time Compute Scaling | MLSys' 26
- TeleRAG: Efficient Retrieval-Augmented Generation Inference with Lookahead Retrieval | MLSys' 26
- OpenHands Software Agent SDK | MLSys' 26
- FlashAgents: Accelerating Multi-Agent LLM Systems via Streaming Prefill Overlap | MLSys' 26
- AgenticCache: Cache-Driven Asynchronous Planning for Agentic LLM Systems | MLSys' 26
- Matrix: Peer-to-Peer Multi-Agent Synthetic Data Generation | MLSys' 26
- Ontology-Guided Long-Term Agent Memory for Conversational RAG | MLSys' 26
- OSWorld-Human: Benchmarking Efficiency of Computer-Use Agents | MLSys' 26
- KAIROS: Stateful, Context-Aware, Power-Efficient Agentic Inference Serving | UMich
- ThunderAgent: A Simple, Fast and Program-Aware Agentic Inference System | CMU
- Vortex: Efficient and Programmable Sparse Attention Serving for AI Agents | CMU
- Nalar: An Agent Serving Framework Separating Workflow Specification from Execution | UT Austin
- Concurrency without Model Changes: Future-based Asynchronous Function Calling for LLMs | UCB
- Agent JIT Compilation: Latency-Optimizing Web Agent Planning and Scheduling | ICML' 26
- SemWeave: Semantic Common Expressions for LLM-powered Query Processing | SIGMOD' 26
- Breaking the Reward Barrier: Accelerating Tree-of-Thought Reasoning via Speculative Exploration | OSDI' 26
- Disentangling Graph Dependencies for Efficient Billion-Scale GPU Vector Search | OSDI' 26
- Helmsman: The Clustering Strikes Back — Building Cost-Effective and High-Performance ANNS at Scale | OSDI' 26
Serving at the edge
Before 2024
- STI: Turbocharge NLP Inference at the Edge via Elastic Pipelining | ASPLOS 23
- LLM in a flash: Efficient Large Language Model Inference with Limited Memory | Apple
2024
- PowerInfer: Fast Large Language Model Serving with a Consumer-grade GPU | SOSP' 24
- MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
2025
- InfiniteHiP: Extending Language Model Context Up to 3 Million Tokens on a Single GPU
- prima.cpp: PRIMA.CPP: Speeding Up 70B-Scale LLM Inference on Low-Resource Everyday Home Clusters
- Characterizing Mobile SoC for Accelerating Heterogeneous LLM Inference | SOSP' 25
2026
- TZ-LLM: Protecting On-Device Large Language Models with Arm TrustZone | EuroSys' 26
- TailorLLM: Collaborative End-Cloud Inference of Large and Small Language Models Based on Low-Rank Adaptation | EuroSys' 26
- Federated Fine-Tuning of Sparsely-Activated Large Language Models on Resource-Constrained Devices | EuroSys' 26
- Scaling LLM Test-Time Compute with Mobile NPU on Smartphones | EuroSys' 26
- On-device Semantic Selection Made Low Latency and Memory Efficient with Monolithic Forwarding | EuroSys' 26
- SwiftFL: Enabling Speculative Training for On-Device Federated Deep Learning | EuroSys' 26
- viNPU: Optimizing Vision Transformer Inference on Mobile NPUs | EuroSys' 26
- Efficient, VRAM-Constrained Cross-Lingual Model Inference on Client Devices | MLSys' 26
- Rethinking DVFS for Mobile LLMs: CORE for Energy-Efficient On-Device Inference | MLSys' 26
- IntAttention: Fully Integer Attention Pipeline for Edge LLM Inference | MLSys' 26
- OpenJarvis: Personal AI, On Personal Devices via LLM-Guided Spec Search and Local-Cloud Collaboration | Stanford
- Sereno: Taming Memory Bandwidth Contention in Mobile LLM Inference | OSDI' 26
- Achieving Cloud-Grade SLOs for Local Mixture-of-Experts Inference through CPU–GPU Hybrid Design | OSDI' 26
- Unleash All Cores: Asymmetry-Aware Scalable DNN Inference on Mobile CPUs | OSDI' 26
System Efficiency Optimization - Model Co-design
Before 2024
- Fast Distributed Inference Serving for Large Language Models | PKU
- FrugalGPT: How to Use Large Language Models While Reducing Cost and Improving Performance | Stanford
- H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models | ICML ES-FoMo Workshop 2023
- Inference with Reference: Lossless Acceleration of Large Language Models
- SkipDecode: Autoregressive Skip Decoding with Batching and Caching for Efficient LLM Inferencex
- Scissorhands: Exploiting the Persistence of Importance Hypothesis for LLM KV Cache Compression at Test Time
- Knowledge-preserving Pruning for Pre-trained Language Models without Retraining | SNU
- Accelerating LLM Inference with Staged Speculative Decoding | ICML' 23
- SpecInfer: Accelerating Generative LLM Serving with Speculative Inference and Token Tree Verification | CMU
- Deja Vu: Contextual Sparsity for Efficient LLMs at Inference Time | ICML' 23
- S3: Increasing GPU Utilization during Generative Inference for Higher Throughput | Havard
- LLMCad: Fast and Scalable On-device Large Language Model Inference
- Skeleton-of-Thought: Large Language Models Can Do Parallel Decoding | THU
- LoRAShear: Efficient Large Language Model Structured Pruning and Knowledge Recovery | Microsoft
- Ring Attention with Blockwise Transformers for Near-Infinite Context | UCB
- Training Transformers with 4-bit Integers | NeurIPS' 23
2024
- Learned Best-Effort LLM Serving | UCB
- Star Attention : Efficient LLM Inference over Long Sequences| NVIDIA
- Jetfire: Efficient and Accurate Transformer Pretraining with INT8 Data Flow and Per-Block Quantization | ICML' 24
2025
- Sparse-Linear Attention: SLA: Beyond Sparsity in Diffusion Transformers via Fine-Tunable Sparse–Linear Attention | Tsinghua
- FFN Fusion: Rethinking Sequential Computation in Large Language Models
- SpargeAttention: SpargeAttention: Accurate and Training-free Sparse Attention Accelerating Any Model Inference | ICML' 25
- COAT: Compressing Optimizer states and Activation for Memory-Efficient FP8 Training | ICLR'25
- Efficient Mixed-Precision Large Language Model Inference with TurboMind | Shanghai AI Lab
2026
- Reducing GPU Memory Fragmentation via Spatio-Temporal Allocation Planning | EuroSys' 26
- SAS: Sparse Attention Synthesizer for Efficient Language Model Inference | EuroSys' 26
- LLMFolder: Revisiting Constant Folding in Large Language Models | EuroSys' 26
- FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for Asymmetric Hardware Scaling (Blackwell) | MLSys' 26
- BLASST: Dynamic Blocked Attention Sparsity for Scalable Transformer Inference | MLSys' 26
- Attribution-based Sparse Activation in Large Language Models | MLSys' 26
- MixLLM: LLM Quantization with Global Mixed-Precision between Output and Embeddings | MLSys' 26
- MAC-Attention: Match-Amend-Complete Attention for Efficient Long-Context Inference | MLSys' 26
- Flashlight: PyTorch Compiler Extensions for Attention Variants | MLSys' 26
- CAGE: Curvature-Aware Gradient Estimation for Quantization-Aware Training | MLSys' 26
- OPKV: Recallable Sparsity in Paged KV Cache for Efficient LLM Inference | MLSys' 26
- Using Span Queries to Optimize Cache and Attention Locality | MLSys' 26
- SLA2: Sparse-Linear Attention with Learnable Routing and QAT | UCB
- SageBwd: A Trainable Low-bit Attention for Efficient Training | UCB
- Inference Time Context Sparsity: Illusion or Opportunity? | UCB
- Tilus: A Tile-Level GPGPU Programming Language for Low-Precision Computation | ASPLOS' 26
- PuzzleMoE: Efficient Compression of Large MoE Models via Sparse Expert Merging and Bit-packed Inference | ICML' 26
- Sieve: Dynamic Expert-Aware PIM Acceleration for Evolving Mixture-of-Experts Models | Stanford
- Streaming Tensor Programs: A Streaming Abstraction for Dynamic Parallelism on Dataflow Accelerators | ASPLOS' 26
- FuseFlow: A Fusion-Centric Compilation Framework for Sparse Deep Learning on Streaming Dataflow | ASPLOS' 26
- Optimal Software Pipelining and Warp Specialization for Tensor Core GPUs | OSDI' 26
- TileLoom: Automatic Dataflow Planning for Tile-Based Languages on Spatial Dataflow Accelerators | OSDI' 26
- MPK: A Compiler and Runtime for Mega-Kernelizing Tensor Programs into a Single High-Performance Multi-GPU Kernel | OSDI' 26
- GraCE: Unlocking CUDA Graphs with Compiler Support for ML Workloads | OSDI' 26
- VTC: DNN Compilation with Virtual Tensors for Data Movement Elimination | OSDI' 26
- ADAngel: Accelerating Arbitrary-Precision Quantized LLMs with Adaptive Computing Mapping | OSDI' 26
- UEP: Portable Expert-Parallel Communication for MoE Serving | OSDI' 26
- UCCL-Tran: An Extensible Software Transport Layer for GPU Networking | OSDI' 26
- CoPilotIO: CPU as a Co-Pilot for GPU I/O to Free GPU Compute | OSDI' 26
Multi-Modal Training Systems
- DISTMM: Accelerating distributed multimodal model training | NSDI' 24
- Optimus: Accelerating Large-Scale Multi-Modal LLM Training by Bubble Exploitation
- Addressing Model and Data Heterogeneity in Multimodal Large Language Model Training | PKU
- Cornstarch: Distributed Multimodal Training Must Be Multimodality-Aware | UMich
- PipeWeaver: Addressing Data Dynamicity in Large Multimodal Model Training with Dynamic Interleaved Pipeline | SJTU
- MegaScale-Omni: A Hyper-Scale, Workload-Resilient System for MultiModal LLM Training in Production | EuroSys' 26
- Entrain: Addressing Variable Heterogeneity in Distributed Multimodal Training | UMich
Multi-Modal Serving Systems
- xDiT: an Inference Engine for Diffusion Transformers (DiTs) with Massive Parallelism
- MOSEL: Inference Serving Using Dynamic Modality Selection
- Approximate Caching for Efficiently Serving Diffusion Models | Adobe Research
- Generative AI Beyond LLMs: System Implications of Multi-Modal Generation | Meta
- Characterizing and Efficiently Accelerating Multimodal Generation Model Inference | Meta
- DistriFusion: Distributed Parallel Inference for High-Resolution Diffusion Models | MIT
- LongVILA: Scaling Long-Context Visual Language Models for Long Videos | NVIDIA
- FlexCache: Flexible Approximate Cache System for Video Diffusion | University of Waterloo
- DDiT: Dynamic Resource Allocation for Diffusion Transformer Model Serving
- PATCHEDSERVE: A Patch Management Framework for SLO-Optimized Hybrid Resolution Diffusion Serving
- ElasticMM: Efficient Multimodal LLMs Serving with Elastic Multimodal Parallelism
- TetriServe: Efficient DiT Serving for Heterogeneous Image Generation
- dInfer: An Efficient Inference Framework for Diffusion Language Models
- Fast-dLLM v2: Efficient Block-Diffusion LLM
- Argus: Quality-Aware High-Throughput Text-to-Image Inference Serving System
- Cornserve: Efficiently Serving Any-to-Any Multimodal Models
- HydraInfer: Hybrid Disaggregated Scheduling for Multimodal Large Language Model Serving
- Enabling Disaggregated Multi-Stage MLLM Inference via GPU-Internal Scheduling and Resource Sharing
- VoxServe: Streaming-Centric Serving System for Speech Language Models
- dLLM-Serve: Taming the Memory Footprint Crisis for Efficient Diffusion LLM Serving
- HADIS: Hybrid Adaptive Diffusion Model Serving for Efficient Text-to-Image Generation
- Efficient Multimodal Serving via Module Multiplexing | EuroSys' 26
- FlashPS: Efficient Generative Image Editing with Mask-aware Caching and Scheduling | EuroSys' 26
- StreamDiffusionV2: A Streaming System for Dynamic and Interactive Video Generation | MLSys' 26
- SpecDiff-2: Scaling Diffusion Drafter Alignment For Faster Speculative Decoding | MLSys' 26
- Million-Scale Text-to-Video Retrieval with Hyperdimensional Computing | EuroSys' 26
- TriInfer: Hybrid Encode-Prefill-Decode Disaggregation for Multimodal LLM Inference | MLSys' 26
- CDLM: Consistency Diffusion Language Models for Faster Text Generation Sampling | MLSys' 26
- db-SP: Accelerating Sparse Attention for Visual Generative Models | MLSys' 26
- TiDAR: Think in Diffusion, Talk in Autoregression for Multimodal Generation | MLSys' 26
- SlackServe: Adaptive Resource Management and Quality Control for Streaming Video Generation | Peking University, Purdue
- Quant VideoGen: Auto-Regressive Long Video Generation via 2-Bit KV-Cache Quantization | UCB
- MonarchRT: Efficient Attention for Real-Time Video Generation | CMU
- SwiftFusion: Scalable Sequence Parallelism for Distributed Inference of Diffusion Transformers on GPUs | Univ. of Toronto
- d3LLM: Ultra-Fast Diffusion LLM using Pseudo-Trajectory Distillation | UCSD
- VLA-Perf: Demystifying VLA Inference Performance | Stanford
LLM for Systems
- Large Language Models for Compiler Optimization
- The Hitchhiker's Guide to Program Analysis: A Journey with Large Language Models
- LLM-Assisted Code Cleaning For Training Accurate Code Generators | UCB
- Efficient Multi-Task Large Model Training via Data Heterogeneity-aware Model Management
- If At First You Don't Succeed, Try, Try, Again...? | SOSP' 24
- Aceso: Efficient Parallel DNN Training through Iterative Bottleneck Alleviation | EuroSys '24
- GMorph: Accelerating Multi-DNN Inference via Model Fusion | EuroSys '24
- Automatic Root Cause Analysis via Large Language Models for Cloud Incidents | EuroSys '24
- KNighter: Transforming Static Analysis with LLM-Synthesized Checkers | SOSP' 25
- Barbarians at the Gate: How AI is Upending Systems Research
- Let the Barbarians In: How AI Can Accelerate Systems Performance Research
- AI Research Engineering Skills Library: A collection of AI research engineering skills and best practices
- K-Search: LLM Kernel Generation via Co-Evolving Intrinsic World Model
- AI-Driven Research for Databases: Automated database optimization via co-evolving evaluators and AI-generated solutions
- No More Translation at Runtime: LLM-Empowered Static Binary Translation | EuroSys' 26
- Unified LLM Model for PPA Prediction from Hardware Code | MLSys' 26
- Optimizing PyTorch Inference with LLM-Based Multi-Agent Systems | MLSys' 26
- AccelOpt: Self-Improving LLM Agentic System for Kernel Optimization | MLSys' 26
- VeriMoA: Mixture-of-Agents for Spec-to-HDL Verification and Generation | MLSys' 26
- AVO: Agentic Variation Operators for Autonomous Evolutionary Search of GPU Attention Kernels | CMU/UW
- FlashInfer-Bench: Building the Virtuous Cycle for AI-driven LLM Systems | UW
- VibeTensor: System Software for Deep Learning, Fully Generated by AI Agents | UW
- SOL-ExecBench: Speed-of-Light Benchmarking for Real-World GPU Kernels Against Hardware Limits | UW
- FastKernels: Benchmarking GPU Kernel Generation in Production | CMU
- CUCo: An Agentic Framework for Compute and Communication Co-design | UT Austin
- ARGUS: Agentic GPU Optimization Guided by Data-Flow Invariants | Stanford
- ECO: An AI-Driven Code Efficiency Optimizer for Warehouse Scale Computers | OSDI' 26
- SMARTTalk: Teaching SMART Logs to Talk to LLMs | OSDI' 26
Industrial LLM Technical Report
Before 2024
- PaLM: Scaling Language Modeling with Pathways – Google / DeepMind (Apr 2022)
- GLM-130B: An Open Bilingual Pre-trained Model – Zhipu AI (Oct 2022)
- BLOOM: A 176B-Parameter Open-Access Multilingual Language Model – BigScience (Nov 2022)
- LLaMA: Open and Efficient Foundation Language Models – Meta (Feb 2023)
- GPT-4 Technical Report – OpenAI (Mar 2023)
- BloombergGPT: A Large Language Model for Finance – Bloomberg (Mar 2023)
- PaLM 2 Technical Report – Google / DeepMind (May 2023)
- StarCoder: may the source be with you! – BigCode (May 2023)
- Llama 2: Open Foundation and Fine-Tuned Chat Models – Meta (Jul 2023)
- Code Llama: Open Foundation Models for Code – Meta (Aug 2023)
- Qwen Technical Report – Alibaba (Sep 2023)
- Baichuan 2: Open Large-scale Language Models – Baichuan (Sep 2023)
- Mistral 7B – Mistral AI (Oct 2023)
- Skywork: A More Open Bilingual Foundation Model – Skywork (Oct 2023)
- The Falcon Series of Open Language Models – TII (Nov 2023)
- Gemini: A Family of Highly Capable Multimodal Models – Google / DeepMind (Dec 2023)
2024
- Mixtral of Experts – Mistral AI (Jan 2024)
- DeepSeek LLM: Scaling Open-Source Language Models with Longtermism – DeepSeek (Jan 2024)
- DeepSeek-Coder: When the Large Language Model Meets Programming -- The Rise of Code Intelligence – DeepSeek (Jan 2024)
- Gemini 1.5: Unlocking Multimodal Understanding Across Millions of Tokens of Context – Google / DeepMind (Feb 2024)
- DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models – DeepSeek (Feb 2024)
- OLMo: Accelerating the Science of Language Models – AI2 (Feb 2024)
- StarCoder 2 and The Stack v2: The Next Generation – BigCode (Feb 2024)
- Claude 3 Model Card – Anthropic (Mar 2024)
- Gemma: Open Models Based on Gemini Research and Technology – Google / DeepMind (Mar 2024)
- MM1: Methods, Analysis & Insights from Multimodal LLM Pre-training – Apple (Mar 2024)
- Grok-1 Model Release – xAI (Mar 2024)
- DeepSeek-VL: Towards Real-World Vision-Language Understanding – DeepSeek (Mar 2024)
- Yi: Open Foundation Models by 01.AI – 01.AI (Mar 2024)
- InternLM2 Technical Report – InternLM (Shanghai AI Lab) (Mar 2024)
- Jamba: A Hybrid Transformer-Mamba Language Model – AI21 Labs (Mar 2024)
- Introducing DBRX: A New State-of-the-Art Open LLM – Databricks (Mar 2024)
- Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone – Microsoft (Apr 2024)
- Command R+ Technical Overview – Cohere (Apr 2024)
- Reka Core, Flash, and Edge: A Series of Powerful Multimodal Language Models – Reka (Apr 2024)
- Snowflake Arctic: The Best LLM for Enterprise AI – Snowflake (Apr 2024)
- MiniCPM: Unveiling the Potential of Small Language Models with Scalable Training Strategies – MiniCPM (Apr 2024)
- DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model – DeepSeek (May 2024)
- Aya 23: Open Weight Releases to Further Multilingual Progress – Cohere (May 2024)
- Granite Code Models: A Family of Open Foundation Models for Code Intelligence – IBM (May 2024)
- Nemotron-4 340B Technical Report – NVIDIA (Jun 2024)
- Claude 3.5 Sonnet Model Card Addendum – Anthropic (Jun 2024)
- CodeGemma: Open Code Models Based on Gemma – Google / DeepMind (Jun 2024)
- ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools – Zhipu AI (Jun 2024)
- Skywork-MoE: A Deep Dive into Training Techniques for Mixture-of-Experts Language Models – Skywork (Jun 2024)
- The Llama 3 Herd of Models – Meta (Jul 2024)
- Gemma 2: Improving Open Language Models at a Practical Size – Google / DeepMind (Jul 2024)
- Apple Intelligence Foundation Language Models – Apple (Jul 2024)
- Qwen2 Technical Report – Alibaba (Jul 2024)
- Jamba-1.5: Hybrid Transformer-Mamba Models at Scale – AI21 Labs (Aug 2024)
- Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution – Alibaba (Sep 2024)
- Qwen2.5-Coder Technical Report – Alibaba (Sep 2024)
- OLMoE: Open Mixture-of-Experts Language Models – AI2 (Sep 2024)
- GPT-4o System Card – OpenAI (Oct 2024)
- Hunyuan-Large: An Open-Source MoE Model with 52 Billion Activated Parameters by Tencent – Tencent (Nov 2024)
- Tülu 3: Pushing Frontiers in Open Language Model Post-Training – AI2 (Nov 2024)
- OpenAI o1 System Card – OpenAI (Dec 2024)
- Phi-4 Technical Report – Microsoft (Dec 2024)
- DeepSeek-V3 Technical Report – DeepSeek (Dec 2024)
- Qwen2.5 Technical Report – Alibaba (Dec 2024)
- Yi-Lightning Technical Report – 01.AI (Dec 2024)
- 2 OLMo 2 Furious – AI2 (Dec 2024)
2025
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning – DeepSeek (Jan 2025)
- Kimi k1.5: Scaling Reinforcement Learning with LLMs – Moonshot AI (Jan 2025)
- MiniMax-01: Scaling Foundation Models with Lightning Attention – MiniMax (Jan 2025)
- Qwen2.5-VL Technical Report – Alibaba (Feb 2025)
- Gemma 3 Technical Report – Google / DeepMind (Mar 2025)
- Phi-4-reasoning Technical Report – Microsoft (Apr 2025)
- Kimi-VL Technical Report – Moonshot AI (Apr 2025)
- The Llama 4 Herd: The Beginning of a New Era of Natively Multimodal AI – Meta (Apr 2025)
- Claude 4 System Card – Anthropic (May 2025)
- Llama-Nemotron: Efficient Reasoning Models – NVIDIA (May 2025)
- Qwen3 Technical Report – Alibaba (May 2025)
- Pangu Ultra: Pushing the Limits of Dense Large Language Models on Ascend NPUs – Huawei (May 2025)
- Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next-Generation Agentic Capabilities – Google / DeepMind (Jun 2025)
- MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning Attention – MiniMax (Jun 2025)
- Kimi K2: Open Agentic Intelligence – Moonshot AI (Jul 2025)
- GPT-oss-120b & GPT-oss-20b Model Card – OpenAI (Aug 2025)
- GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models – Zhipu AI (Aug 2025)
2026
- Falcon-H1R: Pushing the Reasoning Frontiers with a Hybrid Model for Efficient Test-Time Scaling – TII (Jan 2026)
- Qwen3-VL-Embedding and Qwen3-VL-Reranker: A Unified Framework for State-of-the-Art Multimodal Retrieval and Ranking – Alibaba (Jan 2026)
- Ministral 3 – Mistral AI (Jan 2026)
- TranslateGemma Technical Report – Google / DeepMind (Jan 2026)
- Qwen3-ASR Technical Report – Alibaba (Jan 2026)
- GLM-5: from Vibe Coding to Agentic Engineering – Zhipu AI (Feb 2026)
- Qwen3-Coder-Next Technical Report – Alibaba (Feb 2026)
- Qwen3.5-Omni Technical Report – Alibaba (Apr 2026)
- Nemotron 3 Nano Omni: Efficient and Open Multimodal Intelligence – NVIDIA (Apr 2026)
- Granite Embedding Multilingual R2 Models – IBM (May 2026)
ML Conferences
NeurIPS 2025
A curated collection of NeurIPS 2025 papers focused on efficient systems for generative AI models. The collection includes papers on:
- Architecture & Efficient Mechanisms - Efficient attention, KV-cache systems, speculative decoding
- Model Compression & Quantization - Quantization, pruning, KV cache compression
- Inference & Serving - LLM serving, scheduling, distributed inference
- Multi-Modal & Diffusion - VLM efficiency, diffusion optimization
- Reinforcement Learning - RL training infrastructure, policy optimization
- Training Systems - Distributed training, memory efficiency
See the full NeurIPS 2025 collection for detailed categorization and paper summaries.
LLM Frameworks
Training
-
DeepSpeed: a deep learning optimization library that makes distributed training and inference easy, efficient, and effective | Microsoft
-
Accelerate | Hugging Face
-
Megatron | Nvidia
-
NeMo | Nvidia
-
torchtitan | PyTorch
-
torchtune: PyTorch-native fine-tuning library for LLMs with minimal dependencies | PyTorch
-
veScale | ByteDance
-
VeOmni: Scaling any Modality Model Training
-
Cornstarch: Distributed Multimodal Training Must Be Multimodality-Aware | UMich
-
GPT-NeoX: Model-parallel autoregressive LLM training combining Megatron and DeepSpeed | EleutherAI
-
nanotron: Minimalistic 3D-parallel (tensor/pipeline/data) LLM training framework | Hugging Face
-
litgpt: 20+ LLM implementations with pre-training and fine-tuning recipes | Lightning AI
-
LLaMA-Factory: Unified efficient fine-tuning of 100+ LLMs and VLMs via LoRA, full fine-tuning, and RL methods | ACL' 24
-
Unsloth: 2-5x faster LLM fine-tuning with ~80% less memory via custom Triton/CUDA kernels
-
Post-Training
- PEFT: Parameter-efficient fine-tuning library (LoRA, QLoRA, Prompt Tuning, IA3, etc.) | Hugging Face
- TRL: Transformers Reinforcement Learning
- OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework based on Ray
- VeRL: Volcano Engine Reinforcement Learning for LLMs
- rLLM: Reinforcement Learning for Language Agents
- SkyRL: A Modular Full-stack RL Library for LLMs
- AReal: Distributed RL System for LLM Reasoning
- ROLL: Reinforcement Learning Optimization for Large-Scale Learning
- slime: a LLM post-training framework aiming for RL Scaling
- RAGEN: Training Agents by Reinforcing Reasoning
- Agent Lightning: Train ANY AI Agents with Reinforcement Learning
- LMFlow: Extensible toolkit for fine-tuning and inference of large foundation models
- NeMo-Aligner: Scalable alignment toolkit for SFT, PPO, DPO, and SteerLM on NeMo | Nvidia
Serving
- llama.cpp: LLM inference in C/C++ with GGUF quantization; supports CPU, Metal, CUDA, and wide hardware
- Ollama: Local LLM serving with model management and OpenAI-compatible API
- TensorRT-LLM | Nvidia
- Triton Inference Server: Production multi-framework model serving platform with dynamic batching | Nvidia
- Ray-LLM | Ray
- TGI | Hugging Face
- vLLM | UCB
- SGLang | UCB
- LMDeploy: LLM compression, deployment, and serving toolkit with TurboMind persistent batching engine | InternLM
- LightLLM: Lightweight Python LLM serving with tri-process architecture decoupling prefill and decode
- DeepSpeed-MII: Low-latency, high-throughput LLM inference powered by DeepSpeed | Microsoft
- CTranslate2: Fast C++/Python inference engine for Transformer models with int8/int16 quantization | OpenNMT
- Petals: Distributed LLM inference and fine-tuning across volunteer GPUs in a BitTorrent-like fashion | ACL' 23
- KV Transformers
- Dynamo: A Datacenter Scale Distributed Inference Serving Framework | Nvidia
- LMCache: Supercharge Your LLM with the Fastest KV Cache Layer
- aibrix: Cost-efficient pluggable infrastructure for GenAI inference (KV cache routing, autoscaling, disaggregated prefill) | vLLM Project
ML Systems
Survey Paper
- Efficient Large Language Models: A Survey
- Challenges and Applications of Large Language Models
- Beyond Efficiency: A Systematic Survey of Resource-Efficient Large Language Models
- Towards Efficient Generative Large Language Model Serving: A Survey from Algorithms to Systems
LLM Benchmark / Leaderboard ? Traces
- LLM Energy Leaderboard | Umich
- LLM-Perf Leaderboard | HuggingFace
- Aviary Explorer | Anyscale
- Open LLM Leaderboard | HuggingFace
- HELM | Stanford
- LMSYS | UCB
- Towards Efficient and Reliable LLM Serving: A Real-World Workload Study
- FlashInfer-Bench / LLMInfer-Bench: Benchmarking LLM Inference Kernels and Systems | MLSys' 26
- DriftBench: Measuring and Predicting Infrastructure Drift in LLM Serving Systems | MLSys' 26
- Charon: A Unified Simulator for LLM Training and Inference | MLSys' 26
- ProfInfer: eBPF-based Fine-Grained LLM Inference Profiler | MLSys' 26
Related ML Readings
- Large Transformer Model Inference Optimization
- Transformer Inference Arithmetic
- The Transformer Family Version 2.0
- Full Stack Optimization of Transformer Inference: a Survey | UCB
- The Smol Training Playbook: The Secrets to Building World-Class LLMs | Hugging Face
- The Ultra-Scale Playbook: Training LLMs on GPU Clusters | Hugging Face
MLSys Courses
- Systems for Machine Learning | (Stanford)[https://cs229s.stanford.edu/fall2023/]
- Systems for Generative AI | (Umich)[https://github.com/mosharaf/eecs598/tree/w24-genai]
- Systems for AI - LLMs | (GT)[https://cs8803-sp24.anand-iyer.com/]
Other Reading
- A curated list of Large Language Model
- AI systems paper list
- A baseline repository of Auto-Parallelism in Training Neural Networks
- Numbers every LLM Developer should know
- 100,000 H100 Clusters: Power, Network Topology, Ethernet vs InfiniBand, Reliability, Failures, Checkpointing
- OpenAI Keynote on Building Scalable AI Infrastructure
- Awesome ML SYS Tutorial
Contributors


Similar repos


Languages
Python
100.0%
README
Awesome LLM Systems Papers
A curated list of Large Language Model systems related academic papers, articles, tutorials, slides and projects. Star this repository, and then you can keep abreast of the latest developments of this booming research field.
Trends at a Glance (2024 → 2026)
Three eras, one lens: what unit of work the system optimizes — a request (2024), a session or reasoning trace (2025), a whole agent trajectory (2026).
Serving is still the largest area in absolute terms, but its share of the list fell from 49% to 33% — the growth went to kernel/model co-design (3 → 29 papers), agentic systems (4 → 22), AI-for-systems (5 → 16) and edge (2 → 14).
The fastest-rising techniques by share of the year's papers: agentic / multi-agent (1.0% → 13.1%), compiler / kernel / megakernel (0.0% → 10.2%), speculative decoding (1.0% → 5.7%), sparse attention (1.0% → 4.5%) and energy / power (1.0% → 3.3%).
→ Full analysis, per-technique numbers and reproduction scripts: trends/
Table of Contents
- Trends at a Glance
- LLM Systems
- LLM for Systems
- Industrial LLM Technical Report
- ML Conferences
- LLM Frameworks
- ML Systems
- Survey Paper
- LLM Benchmark / Leaderboard / Traces
- Related ML Readings
- MLSys Courses
- Other Reading
LLM Systems
Training
Pre-training
Before 2024
- Megatron-LM: Training Multi-Billion Parameter Language Models Using Model Parallelism
- Efficient Large-Scale Language Model Training on GPU Clusters Using Megatron-LM
- Reducing Activation Recomputation in Large Transformer Models
- Optimized Network Architectures for Large Language Model Training with Billions of Parameters | MIT
- Carbon Emissions and Large Neural Network Training | Google, UCB
2024
- Perseus: Removing Energy Bloat from Large Model Training | SOSP' 24
- MegaScale: Scaling Large Language Model Training to More Than 10,000 GPUs | ByteDance
- DISTMM: Accelerating distributed multimodal model training | NSDI' 24
- Pipeline Parallelism with Controllable Memory | Sea AI Lab
- Boosting Large-scale Parallel Training Efficiency with C4: A Communication-Driven Approach
- Scaling Beyond the GPU Memory Limit for Large Mixture-of-Experts Model Training | ICML' 24
- Alibaba HPN: A Data Center Network for Large Language ModelTraining
- The Llama 3 Herd of Models (Section 3)
- Enabling Parallelism Hot Switching for Efficient Training of Large Language Models | SOSP' 24
- Revisiting Reliability in Large-Scale Machine Learning Research Clusters
- ScheMoE: An Extensible Mixture-of-Experts Distributed Training System with Tasks Scheduling | EuroSys '24
- DynaPipe : Optimizing Multi-task Training through Dynamic Pipelines | EuroSys '24
- HAP: SPMD DNN Training on Heterogeneous GPU Clusters with Automated Program Synthesis | EuroSys'24
- Demystifying Workload Imbalances in Large Transformer Model Training over Variable-length Sequences | PKU
- Improving training time and GPU utilization in geo-distributed language model training
- DeepSeek-V3 Technical Report
- Megalodon: Efficient LLM Pretraining and Inference with Unlimited Context Length
2025
- Comet: Fine-grained Computation-communication Overlapping for Mixture-of-Experts | ByteDance
- ByteScale : Efficient Scaling of LLM Training with a 2048K Context Length on More Than 12,000 GPUs | ByteDance
- SPPO:Efficient Long-sequence LLM Training via Adaptive Sequence Pipeline Parallel Offloading
- TileLink: Generating Efficient Compute-Communication Overlapping Kernels using Tile-Centric Primitives | MLSys' 25
- Every FLOP Counts: Scaling a 300B Mixture-of-Experts LING LLM without Premium GPUs| Ant Group
- FlexSP: Accelerating Large Language Model Training via Flexible Sequence Parallelism | ASPLOS '25
- WeiPipe: Weight Pipeline Parallelism for Communication-Effective Long-Context Large Model Training | PPoPP ’25
- WLB-LLM: Workload-Balanced 4D Parallelism for Large Language Model TraininG | OSDI' 25
- Mixtera: A Data Plane for Foundation Model Training | ETH
- Flex Attention: A Programming Model for Generating Optimized Attention Kernels | MLSys' 25
- Balancing Pipeline Parallelism with Vocabulary Parallelism | MLSys' 25
- SlimPipe: Memory-Thrifty and Efficient Pipeline Parallelism for Long-Context LLM Training | Kuaishou
- Scaling Llama 3 Training with Efficient Parallelism Strategies | ISCA' 25
- Lumos : Efficient Performance Modeling and Estimation for Large-scale LLM Training| MLSys' 25
- BurstEngine: an Efficient Distributed Framework for Training Transformers on Extremely Long Sequences of over 1M Tokens
- Robust LLM Training Infrastructure at ByteDance | SOSP' 25
- Sailor: Automating Distributed Training over Dynamic, Heterogeneous, and Geo-distributed Clusters | SOSP' 25
- Tempo: Compiled Dynamic Deep Learning with Symbolic Dependence Graphs | SOSP' 25
- Mycroft: Tracing Dependencies in Collective Communication Towards Reliable LLM Training | SOSP' 25
- DCP: Addressing Input Dynamism In Long-Context Training via Dynamic Context Parallelism | SOSP' 25
- TrainVerify: Equivalence-Based Verification for Distributed LLM Training | SOSP' 25
- Collective Communication for 100k+ GPUs: Large-scale collective communication optimization for massive GPU clusters
2026
- Arena: Efficiently Training Large Models via Dynamic Scheduling and Adaptive Parallelism Co-Design | EuroSys' 26
- Zeppelin: Balancing Variable-length Workloads in Data Parallel Large Model Training | EuroSys' 26
- RDMA Point-to-Point Communication for LLM Systems: RDMA-based point-to-point communication optimization for distributed LLM systems | MLSys' 26
- MoEBlaze: Breaking the Memory Wall for Efficient MoE Training on Modern GPUs | MLSys' 26
- Kareus: Joint Reduction of Dynamic and Static Energy in Large Model Training | OSDI' 26
- AXLearn: Modular Large Model Training on Heterogeneous Infrastructure | MLSys' 26
- MoSE: Mixture of Slimmable Experts for Efficient and Adaptive Language Models
- MegaScale-MoE: Large-Scale Communication-Efficient Training of Mixture-of-Experts Models in Production | EuroSys' 26
- MegaScale-Data: Scaling DataLoader for Multisource Large Foundation Model Training | EuroSys' 26
- HetAuto: Cross-Cluster Auto-Parallelism for Heterogeneous Distributed Training | EuroSys' 26
- HARP: Orchestrating Automated Parallel Training on Heterogeneous GPU Clusters | EuroSys' 26
- Crimson: Collaborative Parameter Updates for Efficient Pipeline Training of Large Language Models | EuroSys' 26
- Suika: Efficient and High-quality Re-scheduling of 3D-parallelized LLM Training Jobs in Shared Clusters | EuroSys' 26
- Efficient and Adaptable Overlapping for Computation and Communication via Signaling and Reordering | EuroSys' 26
- BOOST: BOttleneck-Optimized Scalable Training Framework for Low-Rank Large Language Models | MLSys' 26
- MTraining: Distributed Dynamic Sparse Attention for Efficient Ultra-Long Context Training | MLSys' 26
- ProTrain: Efficient LLM Training via Automatic Memory Management | MLSys' 26
- DreamDDP: Accelerating Data Parallel Distributed LLM Training with Layer-wise Scheduled Partial Synchronization | MLSys' 26
- Multipath Collective Communication Beyond Scale-up Networks in GPU Clouds | EuroSys' 26
- STAlloc: Enhancing Memory Efficiency in Large-Scale Model Training through Spatio-Temporal Allocation Planning | EuroSys' 26
- Maya: Optimizing Deep Learning Training Workloads using GPU Runtime Emulation | EuroSys' 26
- Bridging the GPU Utilization Gap: Predictive Multi-Dimensional Resource Scheduling for AI Workloads | EuroSys' 26
- Reducing the GPU Memory Bottleneck with Lossless Compression for ML | EuroSys' 26
- Efficient Long-Context LM Training by Core Attention Disaggregation | MLSys' 26
- Zorse: Optimizing LLM Training Efficiency on Heterogeneous GPU Clusters | MLSys' 26
- Unleashing Scalable Context Parallelism via Fully Connected Pipeline | MLSys' 26
- FlexTrain: Scalable Hybrid-Parallel Training for Long-Context LLMs | MLSys' 26
- veScale-FSDP: Flexible and High-Performance FSDP at Scale | MLSys' 26
- HexiScale: LLM Training over Heterogeneous Hardware | MLSys' 26
- FP8-Flow-MoE: Casting-Free FP8 Recipe for MoE without Double Quantization Error | MLSys' 26
- PithTrain: A Compact and Agent-Native MoE Training System with 4D Parallelism and FP8 | CMU
- Olmix: A Framework for Data Mixing Throughout LM Development | Stanford
- SuperOffload: Unleashing the Power of Large-Scale LLM Training on Superchips | ASPLOS' 26
- AutoSP: Unlocking Long-Context LLM Training via Compiler-Based Sequence Parallelism | ICLR' 26
- SYMI: Efficient Mixture-of-Experts Training via Model and Optimizer State Decoupling | NSDI' 26
- Tessera: A Holistic Pipeline Parallelism Framework for Trillion-Parameter Heterogeneous MoE Training | OSDI' 26
- Hetu v2: A General and Scalable Deep Learning System with Hierarchical and Heterogeneous SPMD Annotations | OSDI' 26
- Syncopate: Efficient Multi-GPU AI Kernels via Automatic Chunk-Centric Compute-Communication Overlap | OSDI' 26
- Teaching the Old Dog New Tricks: Building Efficient Data Pipelines for Large-Scale LLM Pre-Training | OSDI' 26
- Cocoon: A System Architecture for Differentially Private Training with Correlated Noises | OSDI' 26
- Heterogeneity at Hyperscale: Characterization and Scheduling of Large Production AI Clusters at Alibaba | OSDI' 26
- Quota Marketplace: Dynamic Pricing for Efficient Allocation of ML Training Resources | OSDI' 26
Systems for Post-training / RLHF
2024
- Ymir: A Scheduler for Foundation Model Fine-tuning Workloads in Datacenters | ICS' 24
- HybridFlow: A Flexible and Efficient RLHF Framework
- ReaLHF: Optimized RLHF Training for Large Language Models through Parameter Reallocation
- NeMo-Aligner: Scalable Toolkit for Efficient Model Alignment | Nvidia
2025
- RLHFuse: Efficient RLHF Training for Large Language Models with Inter- and Intra-Stage Fusion | NSDI'25
- Systems Opportunities for LLM Fine-Tuning using Reinforcement Learning
- AReaL: A Large-Scale Asynchronous Reinforcement Learning System for Language Reasoning | Code | Ant
- StreamRL: Scalable, Heterogeneous, and Elastic RL for LLMs with Disaggregated Stream Generation
- RL-Factory: Train your Agent model via our easy and efficient framework
- PLoRA: Efficient LoRA Hyperparameter Tuning for Large Models
- History Rhymes: Accelerating LLM Reinforcement Learning with RhymeRL
- APRIL: Active Partial Rollouts in Reinforcement Learning to tame long-tail generation
- Seer: Online Context Learning for Fast Synchronous LLM Reinforcement Learning | OSDI' 26
- SkyRL-Agent: Efficient RL Training for Multi-turn LLM Agent
2026
- Laminar: A Scalable Asynchronous RL Post-Training Framework | EuroSys' 26
- LoRAFusion: Efficient LoRA Fine-Tuning for LLMs | EuroSys' 26
- HetRL: Efficient Reinforcement Learning for LLMs in Heterogeneous Environments | MLSys' 26
- ReSpec: Towards Optimizing Speculative Decoding in Reinforcement Learning Systems | MLSys' 26
- Beat the Long Tail: Distribution-Aware Speculative Decoding for Reinforcement Learning | MLSys' 26
- FLoRIST: Federated Low-Rank Adaptation with Random Subspaces for LLMs | MLSys' 26
- Taming the Long-Tail: Efficient Reasoning RL Training with an Adaptive Drafter | ASPLOS' 26
- Aurora: When RL Meets Adaptive Speculative Training — A Unified Training-Serving System
- AstraFlow: Dataflow-Oriented Reinforcement Learning for Agentic LLMs | CMU
- RLBoost: Harvesting Preemptible Cloud Resources for Cost-Efficient Reinforcement Learning on LLMs | NSDI' 26
- Weave: Efficient Co-Scheduling for Disaggregated RL Post-Training | OSDI' 26
- RLinf: Flexible and Efficient Large-Scale Reinforcement Learning via Macro-to-Micro Flow Transformation | OSDI' 26
- DynaRL: Flexible and Dynamic Scheduling of Large-Scale Reinforcement Learning Training | OSDI' 26
- RollArt: Disaggregated Multi-Task Agentic RL Training at Scale | OSDI' 26
Fault Tolerance / Straggler Mitigation
Before 2024
2024
- FALCON: Pinpointing and Mitigating Stragglers for Large-Scale Hybrid-Parallel Training
- Malleus: Straggler-Resilient Hybrid Parallel Training of Large-scale Models via Malleable Data and Model Parallelization
- Fire-Flyer AI-HPC: A Cost-Effective Software-Hardware Co-Design for Deep Learning | DeepSeek SC' 24
- Lazarus: Resilient and Elastic Training of Mixture-of-Experts Models with Adaptive Expert Placement
- ByteCheckpoint: A Unified Checkpointing System for LLM Development
- ReCycle: Resilient Training of Large DNNs using Pipeline Adaptation | SOSP' 24
- Minder: Faulty Machine Detection for Large-scale Distributed Model Training | THU
- TrainMover: An Interruption-Resilient Runtime for ML Training | Alibaba, OSDI' 26
2025
- The Streaming Batch Model for Efficient and Fault-Tolerant Heterogeneous Execution
- Characterizing GPU Resilience and Impact on AI/HPC Systems | UIUC
- Understanding Stragglers in Large Model Training Using What-if Analysis | OSDI' 25
- BitSnap: Checkpoint Sparsification and Quantization in LLM Training
2026
- GoCkpt: Gradient-Assisted Multi-Step Overlapped Checkpointing for Efficient LLM Training | PPoPP' 26
- Handling Network Faults in Distributed AI Training: Failover is Now an Option | EuroSys' 26
- GUARD: Scalable Straggler Detection and Mitigation in LLM Training | MLSys' 26
- Sparse Checkpointing for Fast and Reliable MoE Training (MoEvement): In-Memory Sparse Checkpointing and Localized Recovery | NSDI' 26
- SDCs in the Wild: Characterizing and Diagnosing SDC-Defective GPUs in Production LLM Training | OSDI' 26
- Safeguarding LLM Training at Scale: Online SDC Detection and Insights from 35 Million GPU Hours | OSDI' 26
- OpGuard: Bitwise Alignment for Precise and General Debugging of Production LLM Training | OSDI' 26
- RobustRL: Role-Based Fault Tolerance System for RL Post-Training | OSDI' 26
Serving
LLM serving
Before 2024
- Orca: A Distributed Serving System for Transformer-Based Generative Models | OSDI'22
- Response Length Perception and Sequence Scheduling: An LLM-Empowered LLM Inference Pipeline | NUS
- Efficiently Scaling Transformer Inference | MLSys' 23
- Flover: A Temporal Fusion Framework for Efficient Autoregressive Model Parallel Inference
- FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
- DeepSpeed Inference : Enabling Efficient Inference of Transformer Models at Unprecedented Scale.
- TurboTransformers: An Efficient GPU Serving System For Transformer Models
- FlexGen: High-throughput Generative Inference of Large Language Models with a Single GPU | ICML' 23
- MPCFormer : fast, performant, and private transformer inference with MPC | ICLR'23
- POLCA: Power Oversubscription in LLM Cloud Providers | Microsoft
- SARATHI: Efficient LLM Inference by Piggybacking Decodes with Chunked Prefills | Microsoft
- AttMemo: Accelerating Self-Attention with Memoization on Big Memory Systems
- vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | SOSP' 23
- Tabi: An Efficient Multi-Level Inference System for Large Language Models | EuroSys' 23
- AutoGen: Enabling Next-Gen LLM Applications via Multi-Agent Conversation | Microsoft
- FlashDecoding++: Faster Large Language Model Inference on GPUs | Tsinghua
- DeepSpeed-MII: Model Implementations for Inference (MII) | Microsoft
- SuperServe: Fine-Grained Inference Serving for Unpredictable Workloads
2024
- FlashAttention-3: Fast and Accurate Attention with Asynchrony and Low-precision
- Flash-LLM: Enabling Cost-Effective and Highly-Efficient Large Generative Model Inference with Unstructured Sparsity | VLDB' 24
- Punica: Multi-Tenant LoRA Serving | MLSys' 24
- S-LoRA: Serving Thousands of Concurrent LoRA Adapters | MLSys' 24
- SpotServe: Serving Generative Large Language Models on Preemptible Instances | CMU
- Fairness in Serving Large Language Models | OSDI' 24
- Infinite-LLM: Efficient LLM Service for Long Context with DistAttention and Distributed KVCache
- CaraServe: CPU-Assisted and Rank-Aware LoRA Serving for Generative LLM Inference
- DistServe: Disaggregating Prefill and Decoding for Goodput-optimized Large Language Model Serving| OSDI' 24
- Inference without Interference: Disaggregate LLM Inference for Mixed Downstream Workloads
- APIServe: Efficient API Support for Large-Language Model Inferencing
- FlexLLM: A System for Co-Serving Large Language Model Inference and Parameter-Efficient Finetuning
- DéjàVu: KV-cache Streaming for Fast, Fault-tolerant Generative LLM Serving
- Optimizing LLM Queries in Relational Workloads | UCB
- AttentionStore: Cost-effective Attention Reuse across Multi-turn Conversations in Large Language Model Serving | NUS
- MuxServe: Flexible Multiplexing for Efficient Multiple LLM Serving
- LoongServe: Efficiently Serving Long-context Large Language Models with Elastic Sequence Parallelism | SOSP' 24
- RAGCache: Efficient Knowledge Caching for Retrieval-Augmented Generation | PKU
- Andes: Defining and Enhancing Quality-of-Experience in LLM-Based Text Streaming Services | Umich
- BlockLLM: Multi-tenant Finer-grained Serving for Large Language Models
- vAttention: Dynamic Memory Management for Serving LLMs without PagedAttention
- Helix: Distributed Serving of Large Language Models via Max-Flow on Heterogeneous GPUs | CMU
- Eloquent: A More Robust Transmission Scheme for LLM Token Streaming | NAIC' 24
- Optimizing Speculative Decoding for Serving Large Language Models Using Goodput | UCB
- Enabling Elastic Model Serving with MultiWorld | Cisco Research
- Prepacking: A Simple Method for Fast Prefilling and Increased Throughput in Large Language Models
- NanoFlow: Towards Optimal Large Language Model Serving Throughput
- Responsive ML inference in multi-tenanted environments using AQUA
- One Queue Is All You Need: Resolving Head-of-Line Blocking in Large Language Model Serving
- MemServe: Context Caching for Disaggregated LLM Serving with Elastic Memory Pool
- dLoRA: Dynamically Orchestrating Requests and Adapters for LoRA LLM Serving | OSDI' 24
- Llumnix: Dynamic Scheduling for Large Language Model Serving | OSDI' 24
- Taming Throughput-Latency Tradeoff in LLM Inference with Sarathi-Serve | OSDI' 24
- InfiniGen: Efficient Generative Inference of Large Language Models with Dynamic KV Cache Management
- ServerlessLLM: Low-Latency Serverless Inference for Large Language Models | OSDI' 24
- CacheGen: KV Cache Compression and Streaming for Fast Large Language Model Serving | SIGCOMM' 24
- Preble: Efficient Distributed Prompt Scheduling for LLM Serving
- Mnemosyne: Parallelization Strategies for Efficiently Serving Multi-Million Context Length LLM Inference Requests Without Approximations
- ConServe: Harvesting GPUs for Low-Latency and High-Throughput Large Language Model Serving
- BlockLLM: Multi-tenant Finer-grained Serving for Large Language Models
- Context Parallelism for Scalable Million-Token Inference
- Pie: Pooling CPU Memory for LLM Inference
- NEO: Saving GPU Memory Crisis with CPU Offloading for Online LLM Inference
- FastSwitch: Optimizing Context Switching Efficiency in Fairness-aware Large Language Model Serving
- Flash Communication: Reducing Tensor Parallelization Bottleneck for Fast Large Language Model Inference
- Fast Inference for Augmented Large Language Models
- A System for Microserving of LLMs | CMU
- TokenFlow: Responsive LLM Text Streaming Serving under Request Burst via Preemptive Scheduling | Plagiarism
2025
- SageAttention: Accurate 8-Bit Attention for Plug-and-play Inference Acceleration | ICLR 2025
- SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization | ICML 2025
- SageAttention3: SageAttention3: Microscaling FP4 Attention for Inference and An Exploration of 8-Bit Training | NeurIPS 2025 spotlight
- SageAttention2++: SageAttention2++: A More Efficient Implementation of SageAttention2 | ICML ES-FoMo Workshop 2025
- FlashInfer: Efficient and Customizable Attention Engine for LLM Inference Serving
- iServe : An Intent-based Serving System for LLMs| UT Austin
- Locality-aware Fair Scheduling in LLM Serving | UCB
- Towards Efficient Large Multimodal Model Serving | MSFT
- DeltaZip: Efficient Serving of Multiple Full-Model-Tuned LLMs
- PIM Is All You Need: A CXL-Enabled GPU-Free System for Large Language Model Inference | ASPLOS' 25
- λScale: Enabling Fast Scaling for Serverless Large Language Model Inference
- AIBrix: Towards Scalable and Cost-Effective LLM Inference Infrastructure | vLLM
- Serving Models, Fast and Slow:Optimizing Heterogeneous LLM Inferencing Workloads at Scale
- Make LLM Inference Affordable to Everyone: Augmenting GPU Memory with NDP-DIMM
- Jenga: Effective Memory Management for Serving LLM with Heterogeneity
- AQUA : Network-Accelerated Memory Offloading for LLMs in Scale-Up GPU Domains | ASPLOS 2025
- MegaScale-Infer: Serving Mixture-of-Experts at Scale with Disaggregated Expert Parallelism | Bytedance
- Towards End-to-End Optimization of LLM-based Applications with Ayo | ASPLOS '25
- CacheBlend : Fast Large Language Model Serving for RAG with Cached Knowledge Fusion | EuroSys' 25 (Best Paper)
- ThunderServe: High-performance and Cost-efficient LLM Serving in Cloud Environments | MLSys' 25
- SLOs-Serve: Optimized Serving of Multi-SLO LLMs
- Tempo: Application-aware LLM Serving with Mixed SLO Requirements
- Hogwild! Inference: Parallel LLM Generation via Concurrent Attention
- Prism: Cost-Efficient Multi-LLM Serving via GPU Memory Ballooning | UCLA, OSDI' 26
- RetroInfer: A Vector-Storage Approach for Scalable Long-Context LLM Inference
- Efficient Serving of LLM Applications with Probabilistic Demand Modeling
- eLLM : Elastic Memory Management Framework for Efficient LLM Serving
- DiSCo: Device-Server Collaborative LLM-Based Text Streaming Services
- DynaServe: Unified and Elastic Execution for Dynamic Disaggregated LLM Serving
- HyGen: Efficient LLM Serving via Elastic Online-Offline Request Co-location
- WaferLLM: A Wafer‑Scale LLM Inference System | OSDI 25
- BlitzScale: Fast and Live Large Model Autoscaling with O(1) Host Caching | OSDI 25
- Nexus: Taming Throughput-Latency Tradeoff in LLM Serving via Efficient GPU Sharing
- Taming the Chaos: Coordinated Autoscaling for Heterogeneous and Disaggregated LLM Inference | Seed
- TokenLake: A Unified Segment-level Prefix Cache Pool for Fine-grained Elastic Long-Context LLM Serving
- Expert-as-a-Service: Towards Efficient, Scalable, and Robust Large-scale MoE Serving
- Shift Parallelism: Low-Latency, High-Throughput LLM Inference for Dynamic Workloads
- Defeating Nondeterminism in LLM Inference
- Deterministic Inference across Tensor Parallel Sizes That Eliminates Training-Inference Mismatch: Ensuring deterministic inference across different tensor parallelism configurations
- The Cost of Dynamic Reasoning: Demystifying AI Agents and Test-Time Scaling from an AI Infrastructure Perspective
- Barbarians at the Gate: How AI is Upending Systems Research
- Mercury: Unlocking Multi-GPU Operator Optimization for LLMs via Remote Memory Scheduling | SOSP' 25
- DiffKV: Differentiated Memory Management for Large Language Models with Parallel KV Compaction | SOSP' 25
- Pie: A Programmable Serving System for Emerging LLM Applications | SOSP' 25
- Aegaeon: Effective GPU Pooling for Concurrent LLM Serving on the Market | SOSP' 25
- Jenga: Effective Memory Management for Serving LLM with Heterogeneity | SOSP' 25
- IC-Cache: Efficient Large Language Model Serving via In-context Caching | SOSP' 25
- PrefillOnly: An Inference Engine for Prefill-only Workloads in Large Language Model Applications | SOSP' 25
- KTransformers: Unleashing the Full Potential of CPU/GPU Hybrid Inference for MoE Models | SOSP' 25
- The ML.ENERGY Benchmark: Toward Automated Inference Energy Measurement and Optimization | NeurIPS' 25
- Serve Programs, Not Prompts: Efficient LLM serving system for structured program execution
- Continuum: Efficient and Robust Multi-Turn LLM Agent Scheduling with KV Cache Time-to-Live
- BestServe: Serving Strategies with Optimal Goodput in Collocation and Disaggregation Architectures
- Online Scheduling for LLM Inference with KV Cache Constraints: Optimal Batching and Scheduling for KV Cache-Constrained Inference
2026
- TokenWeave: Efficient Compute-Communication Overlap for Distributed LLM Inference | Code | MLSys' 26
- AIConfigurator: Lightning-Fast Configuration Optimization for Multi-Framework LLM Serving
- SuperInfer: SLO-Aware Rotary Scheduling and Memory Management for LLM Inference on Superchips | MLSys' 26
- Scaling Up Efficient Small Language Models Serving: Serving and Deployment for Semantic Job Search | MLSys' 26
- OptiKIT: Meeting SLOs, Slashing Hours - Automated Enterprise LLM Optimization | MLSys' 26
- BlendServe: Optimizing Offline Inference for Auto-regressive Large Models with Resource-aware Batching | ASPLOS' 26
- SwiftSpec: Ultra-Low Latency LLM Decoding by Scaling Asynchronous Speculative Decoding with Disaggregated Pipeline and Fused Kernels | ASPLOS' 26
- MuxWise: Towards High-Goodput LLM Serving with Prefill-decode Multiplexing | ASPLOS' 26
- MoEless: Efficient MoE LLM Serving via Serverless Computing
- BiScale: Energy-Efficient Disaggregated LLM Serving via Phase-Aware Placement and DVFS
- Harvest: Opportunistic Peer-to-Peer GPU Caching for LLM Inference
- MineDraft: A Framework for Batch Parallel Speculative Decoding — overlaps drafting and verification across two batches, hiding draft latency. Up to +75% throughput, -39% latency. Integrated into vLLM. | NUS & MIT
- Foundry: Template-Based CUDA Graph Context Materialization for Fast LLM Serving Cold Start
- AdaServe: Accelerating Multi-SLO LLM Serving with SLO-Customized Speculative Decoding | EuroSys' 26
- FlexPipe: Adapting Dynamic LLM Serving Through Inflight Pipeline Refactoring in Fragmented Serverless Clusters | EuroSys' 26
- Taming Latency-Memory Trade-Off in MoE-Based LLM Serving via Fine-Grained Expert Offloading | EuroSys' 26
- KunServe: Parameter-centric Memory Management for Efficient Memory Overloading Handling in LLM Serving | EuroSys' 26
- AdaGen: Workload-Adaptive Cluster Scheduler for Latency-Optimal LLM Inference Serving | EuroSys' 26
- SkyWalker: A Locality-Aware Cross-Region Load Balancer for LLM Inference | EuroSys' 26
- High Throughput and Low Latency LLM Serving via Adaptive KV Caching | EuroSys' 26
- PARD: Enhancing Goodput for Inference Pipeline via Proactive Request Dropping | EuroSys' 26
- PiLLM: Resource-Efficient LLM Inference Using Workload Prediction | EuroSys' 26
- Automated End-to-End Model Serving with Cooperative Compilation and Scheduling | EuroSys' 26
- MFS: An Efficient Model Family Serving System for LLMs | EuroSys' 26
- CRAFT: Cost-aware Expert Replica Allocation with Fine-Grained Layerwise Estimations for Efficient MoE Serving | MLSys' 26
- MorphServe: Efficient and Workload-Aware LLM Serving via Runtime Quantized Layer Swapping and KV Cache Resizing | MLSys' 26
- FlexiCache: Leveraging Temporal Stability of Attention Heads for Efficient KV Cache Management | MLSys' 26
- Kitty: Accurate and Efficient 2-bit KV Cache Quantization with Dynamic Channel-wise Precision Boost | MLSys' 26
- SkipKV: Selective Skipping of KV Generation and Storage for Efficient Inference with Large Reasoning Models | MLSys' 26
- BOute: Cost-Efficient LLM Serving with Heterogeneous LLMs and GPUs via Multi-Objective Bayesian Optimization | MLSys' 26
- From Tokens to Layers: Redefining Stall-Free Scheduling for LLM Serving with Layered Prefill | MLSys' 26
- HELIOS: Adaptive Model And Early-Exit Selection for Efficient LLM Inference Serving | MLSys' 26
- BatchLLM: Optimizing Large Batched LLM Inference with Global Prefix Sharing and Throughput-oriented Token Batching | MLSys' 26
- GhostServe: A Lightweight Checkpointing System in the Shadow for Fault-Tolerant LLM Serving | MLSys' 26
- PRISM: Parametrically Refactoring Inference for Speculative Decoding Draft Models | MLSys' 26
- FarSkip-Collective: Unhobbling Blocking Communication in Mixture of Experts Models | MLSys' 26
- Efficient Data Passing for Serverless Inference Workflows: A GPU-Centric Approach | EuroSys' 26
- TrustWeave: Integrity Measurement and Attestation for Multi-Cloud LLMs | EuroSys' 26
- Stream2LLM: Overlapping Context Streaming and Prefill for Low-Latency LLM Serving | MLSys' 26
- Locality-Aware Beam Scheduling for Efficient Test-Time Compute | MLSys' 26
- Optimizing Deployment Configurations for LLM Inference | MLSys' 26
- ContextPilot: Fast Long-Context Inference via Context Reuse | MLSys' 26
- Speculative Decoding: Performance or Illusion? | MLSys' 26
- SHIP: SRAM-Based Huge Inference Pipelines for Fast LLM Serving | MLSys' 26
- BEAM: Joint Resource-Power Optimization for LLM Inference | MLSys' 26
- Beyond the Buzz: A Pragmatic Take on Inference Disaggregation | MLSys' 26
- PLA-Serve: Prefill-Length-Aware LLM Serving System | MLSys' 26
- Accelerating Reasoning Model Inference with Sparse Self-Speculative Decoding | MLSys' 26
- FaaScale: Unlocking Fast LLM Scaling for Serverless Inference | MLSys' 26
- Breaking the Ice: Analyzing Cold Start Latency in vLLM | MLSys' 26
- Demystifying the Mixture of Experts Serving Tax | MLSys' 26
- RaidServe: High-Performance Resilient LLM Serving | MLSys' 26
- Toward Principled LLM Safety Testing: Solving the Jailbreak Oracle Problem | MLSys' 26
- ZeRO-Prefill: Zero Redundancy Overheads in MoE Prefill Serving
- SkyNomad: On Using Multi-Region Spot Instances to Minimize AI Batch Job Cost | UCB
- Qrita: High-performance Top-k and Top-p Algorithm for GPUs using Pivot-based Truncation and Selection | UCB
- The Time is Here for Just-in-Time Systems: Challenges and Opportunities for Adaptive AI/ML Serving | UCB
- Event Tensor: A Unified Abstraction for Compiling Dynamic Megakernels for Low-Latency Serving | MLSys' 26
- XGrammar-2: Efficient Dynamic Structured Generation Engine for Agentic LLMs | CMU
- Prism (Superoptimizer): Symbolic Superoptimization of Tensor Programs | CMU
- Coral: Cost-Efficient Multi-LLM Serving over Heterogeneous Cloud GPUs | CMU
- LAPS: A Length-Aware-Prefill LLM Serving System | CMU/MBZUAI
- Where Do the Joules Go?: Diagnosing Inference Energy Consumption | UMich
- SYMPHONY: Enabling Compute-Memory Disaggregation in LLM Serving Systems | NSDI' 26
- OpenTela: Unifying Decentralized Computing Resources for Heterogeneous LLM Serving | OSDI' 26
- Speculative Speculative Decoding: Parallelizing the Speculate-then-Verify Dependency | ICLR' 26
- WWW.Serve: Interconnecting Global LLM Services through Decentralization | CMU
- Not All Prefills Are Equal: PPD Disaggregation for Multi-turn LLM Serving | UChicago
- Hexcute: A Compiler Framework for Automating Layout Synthesis in GPU Programs | CGO' 26
- AutoScout: Structured Optimization for Automating ML System Configuration | UT Austin
- VoltanaLLM: Energy-Efficient and SLO-Aware Disaggregated LLM Serving | ISC' 26
- Regulating Branch Parallelism in LLM Serving: Balancing Intra-Request Branch Admission against Co-batched Latency | Stanford
- Strata: Hierarchical Context Caching for Long-Context LLM Serving | OSDI' 26
- ECHO: Efficient KV Cache Offloading with Lossless Prefetching for Serving Native Sparse Attention LLMs | OSDI' 26
- No Buffer, No Bottleneck: Efficient Zero-Copy KV Cache Offloading for Long-Context LLMs | OSDI' 26
- Simple Is Better: Multiplication May Be All You Need for LLM Request Scheduling | OSDI' 26
- BatchGen: An Architecture for Scalable and Efficient Batch Inference | OSDI' 26
- Efficient LLM Serving on Commodity GPU Clusters: Data-Reduced Cross-Instance Orchestration for LLM Serving | OSDI' 26
- Revisiting Pipeline Parallelism for LLM Serving: Revisiting pipeline parallelism as an alternative to tensor parallelism for online LLM serving | OSDI' 26
- Kairox: Adaptive GPU-CPU Hybrid LLM Inference via Online Neuron Balancing | OSDI' 26
- StriaTrace: Efficient Tracing and Diagnosis for Online LLM Inference | OSDI' 26
Agent Systems
2024
- ALTO: An Efficient Network Orchestrator for Compound AI Systems | Stanford & UCB
- Parrot: Efficient Serving of LLM-based Applications with Semantic Variable | OSDI' 24
- Efficiently Serving LLM Reasoning Programs with Certaindex | UCSD
- DroidSpeak: KV Cache Sharing for Cross-LLM Communication and Multi-LLM Serving
2025
- Supporting Our AI Overlords: Redesigning Data Systems to be Agent-First | UCB
- Autellix: An Efficient Serving Engine for LLM Agents as General Programs | UCB
- RAGO: Systematic Performance Optimization for Retrieval-Augmented Generation Serving | ISCA'25
- Circinus: Efficient Query Planner for Compound ML Serving | UIUC
- Patchwork: A Unified Framework for RAG Serving
- DS SERVE: A Framework for Efficient and Scalable Neural Retrieval | UCB
- KVFlow: Efficient Prefix Caching for Accelerating LLM-Based Multi-Agent Workflows
- Murakkab: Resource-Efficient Agentic Workflow Orchestration in Cloud Platforms | OSDI' 26
- HedraRAG: Co-Optimizing Generation and Retrieval for Heterogeneous RAG Workflows | SOSP' 25
- METIS: Fast Quality-Aware RAG Systems with Configuration Adaptation | SOSP' 25
- Aragog: Just-in-Time Model Routing for Scalable Serving of Agentic Workflows
2026
- DualPath: Breaking the Storage Bandwidth Bottleneck in Agentic LLM Inference | DeepSeek
- AIMS: Cost-Efficient LLM-Based Agent Deployment in Hybrid Cloud-Edge Environments | EuroSys' 26
- From Imperative to Declarative: Towards LLM-friendly OS Interfaces for Boosted Computer-Use Agents | EuroSys' 26
- Hippocampus: An Efficient and Scalable Memory Module for Agentic AI | MLSys' 26
- PROMPTS: Performance Optimization via Multi-Agent Planning for Test-time Compute Scaling | MLSys' 26
- TeleRAG: Efficient Retrieval-Augmented Generation Inference with Lookahead Retrieval | MLSys' 26
- OpenHands Software Agent SDK | MLSys' 26
- FlashAgents: Accelerating Multi-Agent LLM Systems via Streaming Prefill Overlap | MLSys' 26
- AgenticCache: Cache-Driven Asynchronous Planning for Agentic LLM Systems | MLSys' 26
- Matrix: Peer-to-Peer Multi-Agent Synthetic Data Generation | MLSys' 26
- Ontology-Guided Long-Term Agent Memory for Conversational RAG | MLSys' 26
- OSWorld-Human: Benchmarking Efficiency of Computer-Use Agents | MLSys' 26
- KAIROS: Stateful, Context-Aware, Power-Efficient Agentic Inference Serving | UMich
- ThunderAgent: A Simple, Fast and Program-Aware Agentic Inference System | CMU
- Vortex: Efficient and Programmable Sparse Attention Serving for AI Agents | CMU
- Nalar: An Agent Serving Framework Separating Workflow Specification from Execution | UT Austin
- Concurrency without Model Changes: Future-based Asynchronous Function Calling for LLMs | UCB
- Agent JIT Compilation: Latency-Optimizing Web Agent Planning and Scheduling | ICML' 26
- SemWeave: Semantic Common Expressions for LLM-powered Query Processing | SIGMOD' 26
- Breaking the Reward Barrier: Accelerating Tree-of-Thought Reasoning via Speculative Exploration | OSDI' 26
- Disentangling Graph Dependencies for Efficient Billion-Scale GPU Vector Search | OSDI' 26
- Helmsman: The Clustering Strikes Back — Building Cost-Effective and High-Performance ANNS at Scale | OSDI' 26
Serving at the edge
Before 2024
- STI: Turbocharge NLP Inference at the Edge via Elastic Pipelining | ASPLOS 23
- LLM in a flash: Efficient Large Language Model Inference with Limited Memory | Apple
2024
- PowerInfer: Fast Large Language Model Serving with a Consumer-grade GPU | SOSP' 24
- MoE-Lightning: High-Throughput MoE Inference on Memory-constrained GPUs
2025
- InfiniteHiP: Extending Language Model Context Up to 3 Million Tokens on a Single GPU
- prima.cpp: PRIMA.CPP: Speeding Up 70B-Scale LLM Inference on Low-Resource Everyday Home Clusters
- Characterizing Mobile SoC for Accelerating Heterogeneous LLM Inference | SOSP' 25
2026
- TZ-LLM: Protecting On-Device Large Language Models with Arm TrustZone | EuroSys' 26
- TailorLLM: Collaborative End-Cloud Inference of Large and Small Language Models Based on Low-Rank Adaptation | EuroSys' 26
- Federated Fine-Tuning of Sparsely-Activated Large Language Models on Resource-Constrained Devices | EuroSys' 26
- Scaling LLM Test-Time Compute with Mobile NPU on Smartphones | EuroSys' 26
- On-device Semantic Selection Made Low Latency and Memory Efficient with Monolithic Forwarding | EuroSys' 26
- SwiftFL: Enabling Speculative Training for On-Device Federated Deep Learning | EuroSys' 26
- viNPU: Optimizing Vision Transformer Inference on Mobile NPUs | EuroSys' 26
- Efficient, VRAM-Constrained Cross-Lingual Model Inference on Client Devices | MLSys' 26
- Rethinking DVFS for Mobile LLMs: CORE for Energy-Efficient On-Device Inference | MLSys' 26
- IntAttention: Fully Integer Attention Pipeline for Edge LLM Inference | MLSys' 26
- OpenJarvis: Personal AI, On Personal Devices via LLM-Guided Spec Search and Local-Cloud Collaboration | Stanford
- Sereno: Taming Memory Bandwidth Contention in Mobile LLM Inference | OSDI' 26
- Achieving Cloud-Grade SLOs for Local Mixture-of-Experts Inference through CPU–GPU Hybrid Design | OSDI' 26
- Unleash All Cores: Asymmetry-Aware Scalable DNN Inference on Mobile CPUs | OSDI' 26
System Efficiency Optimization - Model Co-design
Before 2024
- Fast Distributed Inference Serving for Large Language Models | PKU
- FrugalGPT: How to Use Large Language Models While Reducing Cost and Improving Performance | Stanford
- H2O: Heavy-Hitter Oracle for Efficient Generative Inference of Large Language Models | ICML ES-FoMo Workshop 2023
- Inference with Reference: Lossless Acceleration of Large Language Models
- SkipDecode: Autoregressive Skip Decoding with Batching and Caching for Efficient LLM Inferencex
- Scissorhands: Exploiting the Persistence of Importance Hypothesis for LLM KV Cache Compression at Test Time
- Knowledge-preserving Pruning for Pre-trained Language Models without Retraining | SNU
- Accelerating LLM Inference with Staged Speculative Decoding | ICML' 23
- SpecInfer: Accelerating Generative LLM Serving with Speculative Inference and Token Tree Verification | CMU
- Deja Vu: Contextual Sparsity for Efficient LLMs at Inference Time | ICML' 23
- S3: Increasing GPU Utilization during Generative Inference for Higher Throughput | Havard
- LLMCad: Fast and Scalable On-device Large Language Model Inference
- Skeleton-of-Thought: Large Language Models Can Do Parallel Decoding | THU
- LoRAShear: Efficient Large Language Model Structured Pruning and Knowledge Recovery | Microsoft
- Ring Attention with Blockwise Transformers for Near-Infinite Context | UCB
- Training Transformers with 4-bit Integers | NeurIPS' 23
2024
- Learned Best-Effort LLM Serving | UCB
- Star Attention : Efficient LLM Inference over Long Sequences| NVIDIA
- Jetfire: Efficient and Accurate Transformer Pretraining with INT8 Data Flow and Per-Block Quantization | ICML' 24
2025
- Sparse-Linear Attention: SLA: Beyond Sparsity in Diffusion Transformers via Fine-Tunable Sparse–Linear Attention | Tsinghua
- FFN Fusion: Rethinking Sequential Computation in Large Language Models
- SpargeAttention: SpargeAttention: Accurate and Training-free Sparse Attention Accelerating Any Model Inference | ICML' 25
- COAT: Compressing Optimizer states and Activation for Memory-Efficient FP8 Training | ICLR'25
- Efficient Mixed-Precision Large Language Model Inference with TurboMind | Shanghai AI Lab
2026
- Reducing GPU Memory Fragmentation via Spatio-Temporal Allocation Planning | EuroSys' 26
- SAS: Sparse Attention Synthesizer for Efficient Language Model Inference | EuroSys' 26
- LLMFolder: Revisiting Constant Folding in Large Language Models | EuroSys' 26
- FlashAttention-4: Algorithm and Kernel Pipelining Co-Design for Asymmetric Hardware Scaling (Blackwell) | MLSys' 26
- BLASST: Dynamic Blocked Attention Sparsity for Scalable Transformer Inference | MLSys' 26
- Attribution-based Sparse Activation in Large Language Models | MLSys' 26
- MixLLM: LLM Quantization with Global Mixed-Precision between Output and Embeddings | MLSys' 26
- MAC-Attention: Match-Amend-Complete Attention for Efficient Long-Context Inference | MLSys' 26
- Flashlight: PyTorch Compiler Extensions for Attention Variants | MLSys' 26
- CAGE: Curvature-Aware Gradient Estimation for Quantization-Aware Training | MLSys' 26
- OPKV: Recallable Sparsity in Paged KV Cache for Efficient LLM Inference | MLSys' 26
- Using Span Queries to Optimize Cache and Attention Locality | MLSys' 26
- SLA2: Sparse-Linear Attention with Learnable Routing and QAT | UCB
- SageBwd: A Trainable Low-bit Attention for Efficient Training | UCB
- Inference Time Context Sparsity: Illusion or Opportunity? | UCB
- Tilus: A Tile-Level GPGPU Programming Language for Low-Precision Computation | ASPLOS' 26
- PuzzleMoE: Efficient Compression of Large MoE Models via Sparse Expert Merging and Bit-packed Inference | ICML' 26
- Sieve: Dynamic Expert-Aware PIM Acceleration for Evolving Mixture-of-Experts Models | Stanford
- Streaming Tensor Programs: A Streaming Abstraction for Dynamic Parallelism on Dataflow Accelerators | ASPLOS' 26
- FuseFlow: A Fusion-Centric Compilation Framework for Sparse Deep Learning on Streaming Dataflow | ASPLOS' 26
- Optimal Software Pipelining and Warp Specialization for Tensor Core GPUs | OSDI' 26
- TileLoom: Automatic Dataflow Planning for Tile-Based Languages on Spatial Dataflow Accelerators | OSDI' 26
- MPK: A Compiler and Runtime for Mega-Kernelizing Tensor Programs into a Single High-Performance Multi-GPU Kernel | OSDI' 26
- GraCE: Unlocking CUDA Graphs with Compiler Support for ML Workloads | OSDI' 26
- VTC: DNN Compilation with Virtual Tensors for Data Movement Elimination | OSDI' 26
- ADAngel: Accelerating Arbitrary-Precision Quantized LLMs with Adaptive Computing Mapping | OSDI' 26
- UEP: Portable Expert-Parallel Communication for MoE Serving | OSDI' 26
- UCCL-Tran: An Extensible Software Transport Layer for GPU Networking | OSDI' 26
- CoPilotIO: CPU as a Co-Pilot for GPU I/O to Free GPU Compute | OSDI' 26
Multi-Modal Training Systems
- DISTMM: Accelerating distributed multimodal model training | NSDI' 24
- Optimus: Accelerating Large-Scale Multi-Modal LLM Training by Bubble Exploitation
- Addressing Model and Data Heterogeneity in Multimodal Large Language Model Training | PKU
- Cornstarch: Distributed Multimodal Training Must Be Multimodality-Aware | UMich
- PipeWeaver: Addressing Data Dynamicity in Large Multimodal Model Training with Dynamic Interleaved Pipeline | SJTU
- MegaScale-Omni: A Hyper-Scale, Workload-Resilient System for MultiModal LLM Training in Production | EuroSys' 26
- Entrain: Addressing Variable Heterogeneity in Distributed Multimodal Training | UMich
Multi-Modal Serving Systems
- xDiT: an Inference Engine for Diffusion Transformers (DiTs) with Massive Parallelism
- MOSEL: Inference Serving Using Dynamic Modality Selection
- Approximate Caching for Efficiently Serving Diffusion Models | Adobe Research
- Generative AI Beyond LLMs: System Implications of Multi-Modal Generation | Meta
- Characterizing and Efficiently Accelerating Multimodal Generation Model Inference | Meta
- DistriFusion: Distributed Parallel Inference for High-Resolution Diffusion Models | MIT
- LongVILA: Scaling Long-Context Visual Language Models for Long Videos | NVIDIA
- FlexCache: Flexible Approximate Cache System for Video Diffusion | University of Waterloo
- DDiT: Dynamic Resource Allocation for Diffusion Transformer Model Serving
- PATCHEDSERVE: A Patch Management Framework for SLO-Optimized Hybrid Resolution Diffusion Serving
- ElasticMM: Efficient Multimodal LLMs Serving with Elastic Multimodal Parallelism
- TetriServe: Efficient DiT Serving for Heterogeneous Image Generation
- dInfer: An Efficient Inference Framework for Diffusion Language Models
- Fast-dLLM v2: Efficient Block-Diffusion LLM
- Argus: Quality-Aware High-Throughput Text-to-Image Inference Serving System
- Cornserve: Efficiently Serving Any-to-Any Multimodal Models
- HydraInfer: Hybrid Disaggregated Scheduling for Multimodal Large Language Model Serving
- Enabling Disaggregated Multi-Stage MLLM Inference via GPU-Internal Scheduling and Resource Sharing
- VoxServe: Streaming-Centric Serving System for Speech Language Models
- dLLM-Serve: Taming the Memory Footprint Crisis for Efficient Diffusion LLM Serving
- HADIS: Hybrid Adaptive Diffusion Model Serving for Efficient Text-to-Image Generation
- Efficient Multimodal Serving via Module Multiplexing | EuroSys' 26
- FlashPS: Efficient Generative Image Editing with Mask-aware Caching and Scheduling | EuroSys' 26
- StreamDiffusionV2: A Streaming System for Dynamic and Interactive Video Generation | MLSys' 26
- SpecDiff-2: Scaling Diffusion Drafter Alignment For Faster Speculative Decoding | MLSys' 26
- Million-Scale Text-to-Video Retrieval with Hyperdimensional Computing | EuroSys' 26
- TriInfer: Hybrid Encode-Prefill-Decode Disaggregation for Multimodal LLM Inference | MLSys' 26
- CDLM: Consistency Diffusion Language Models for Faster Text Generation Sampling | MLSys' 26
- db-SP: Accelerating Sparse Attention for Visual Generative Models | MLSys' 26
- TiDAR: Think in Diffusion, Talk in Autoregression for Multimodal Generation | MLSys' 26
- SlackServe: Adaptive Resource Management and Quality Control for Streaming Video Generation | Peking University, Purdue
- Quant VideoGen: Auto-Regressive Long Video Generation via 2-Bit KV-Cache Quantization | UCB
- MonarchRT: Efficient Attention for Real-Time Video Generation | CMU
- SwiftFusion: Scalable Sequence Parallelism for Distributed Inference of Diffusion Transformers on GPUs | Univ. of Toronto
- d3LLM: Ultra-Fast Diffusion LLM using Pseudo-Trajectory Distillation | UCSD
- VLA-Perf: Demystifying VLA Inference Performance | Stanford
LLM for Systems
- Large Language Models for Compiler Optimization
- The Hitchhiker's Guide to Program Analysis: A Journey with Large Language Models
- LLM-Assisted Code Cleaning For Training Accurate Code Generators | UCB
- Efficient Multi-Task Large Model Training via Data Heterogeneity-aware Model Management
- If At First You Don't Succeed, Try, Try, Again...? | SOSP' 24
- Aceso: Efficient Parallel DNN Training through Iterative Bottleneck Alleviation | EuroSys '24
- GMorph: Accelerating Multi-DNN Inference via Model Fusion | EuroSys '24
- Automatic Root Cause Analysis via Large Language Models for Cloud Incidents | EuroSys '24
- KNighter: Transforming Static Analysis with LLM-Synthesized Checkers | SOSP' 25
- Barbarians at the Gate: How AI is Upending Systems Research
- Let the Barbarians In: How AI Can Accelerate Systems Performance Research
- AI Research Engineering Skills Library: A collection of AI research engineering skills and best practices
- K-Search: LLM Kernel Generation via Co-Evolving Intrinsic World Model
- AI-Driven Research for Databases: Automated database optimization via co-evolving evaluators and AI-generated solutions
- No More Translation at Runtime: LLM-Empowered Static Binary Translation | EuroSys' 26
- Unified LLM Model for PPA Prediction from Hardware Code | MLSys' 26
- Optimizing PyTorch Inference with LLM-Based Multi-Agent Systems | MLSys' 26
- AccelOpt: Self-Improving LLM Agentic System for Kernel Optimization | MLSys' 26
- VeriMoA: Mixture-of-Agents for Spec-to-HDL Verification and Generation | MLSys' 26
- AVO: Agentic Variation Operators for Autonomous Evolutionary Search of GPU Attention Kernels | CMU/UW
- FlashInfer-Bench: Building the Virtuous Cycle for AI-driven LLM Systems | UW
- VibeTensor: System Software for Deep Learning, Fully Generated by AI Agents | UW
- SOL-ExecBench: Speed-of-Light Benchmarking for Real-World GPU Kernels Against Hardware Limits | UW
- FastKernels: Benchmarking GPU Kernel Generation in Production | CMU
- CUCo: An Agentic Framework for Compute and Communication Co-design | UT Austin
- ARGUS: Agentic GPU Optimization Guided by Data-Flow Invariants | Stanford
- ECO: An AI-Driven Code Efficiency Optimizer for Warehouse Scale Computers | OSDI' 26
- SMARTTalk: Teaching SMART Logs to Talk to LLMs | OSDI' 26
Industrial LLM Technical Report
Before 2024
- PaLM: Scaling Language Modeling with Pathways – Google / DeepMind (Apr 2022)
- GLM-130B: An Open Bilingual Pre-trained Model – Zhipu AI (Oct 2022)
- BLOOM: A 176B-Parameter Open-Access Multilingual Language Model – BigScience (Nov 2022)
- LLaMA: Open and Efficient Foundation Language Models – Meta (Feb 2023)
- GPT-4 Technical Report – OpenAI (Mar 2023)
- BloombergGPT: A Large Language Model for Finance – Bloomberg (Mar 2023)
- PaLM 2 Technical Report – Google / DeepMind (May 2023)
- StarCoder: may the source be with you! – BigCode (May 2023)
- Llama 2: Open Foundation and Fine-Tuned Chat Models – Meta (Jul 2023)
- Code Llama: Open Foundation Models for Code – Meta (Aug 2023)
- Qwen Technical Report – Alibaba (Sep 2023)
- Baichuan 2: Open Large-scale Language Models – Baichuan (Sep 2023)
- Mistral 7B – Mistral AI (Oct 2023)
- Skywork: A More Open Bilingual Foundation Model – Skywork (Oct 2023)
- The Falcon Series of Open Language Models – TII (Nov 2023)
- Gemini: A Family of Highly Capable Multimodal Models – Google / DeepMind (Dec 2023)
2024
- Mixtral of Experts – Mistral AI (Jan 2024)
- DeepSeek LLM: Scaling Open-Source Language Models with Longtermism – DeepSeek (Jan 2024)
- DeepSeek-Coder: When the Large Language Model Meets Programming -- The Rise of Code Intelligence – DeepSeek (Jan 2024)
- Gemini 1.5: Unlocking Multimodal Understanding Across Millions of Tokens of Context – Google / DeepMind (Feb 2024)
- DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models – DeepSeek (Feb 2024)
- OLMo: Accelerating the Science of Language Models – AI2 (Feb 2024)
- StarCoder 2 and The Stack v2: The Next Generation – BigCode (Feb 2024)
- Claude 3 Model Card – Anthropic (Mar 2024)
- Gemma: Open Models Based on Gemini Research and Technology – Google / DeepMind (Mar 2024)
- MM1: Methods, Analysis & Insights from Multimodal LLM Pre-training – Apple (Mar 2024)
- Grok-1 Model Release – xAI (Mar 2024)
- DeepSeek-VL: Towards Real-World Vision-Language Understanding – DeepSeek (Mar 2024)
- Yi: Open Foundation Models by 01.AI – 01.AI (Mar 2024)
- InternLM2 Technical Report – InternLM (Shanghai AI Lab) (Mar 2024)
- Jamba: A Hybrid Transformer-Mamba Language Model – AI21 Labs (Mar 2024)
- Introducing DBRX: A New State-of-the-Art Open LLM – Databricks (Mar 2024)
- Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone – Microsoft (Apr 2024)
- Command R+ Technical Overview – Cohere (Apr 2024)
- Reka Core, Flash, and Edge: A Series of Powerful Multimodal Language Models – Reka (Apr 2024)
- Snowflake Arctic: The Best LLM for Enterprise AI – Snowflake (Apr 2024)
- MiniCPM: Unveiling the Potential of Small Language Models with Scalable Training Strategies – MiniCPM (Apr 2024)
- DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model – DeepSeek (May 2024)
- Aya 23: Open Weight Releases to Further Multilingual Progress – Cohere (May 2024)
- Granite Code Models: A Family of Open Foundation Models for Code Intelligence – IBM (May 2024)
- Nemotron-4 340B Technical Report – NVIDIA (Jun 2024)
- Claude 3.5 Sonnet Model Card Addendum – Anthropic (Jun 2024)
- CodeGemma: Open Code Models Based on Gemma – Google / DeepMind (Jun 2024)
- ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools – Zhipu AI (Jun 2024)
- Skywork-MoE: A Deep Dive into Training Techniques for Mixture-of-Experts Language Models – Skywork (Jun 2024)
- The Llama 3 Herd of Models – Meta (Jul 2024)
- Gemma 2: Improving Open Language Models at a Practical Size – Google / DeepMind (Jul 2024)
- Apple Intelligence Foundation Language Models – Apple (Jul 2024)
- Qwen2 Technical Report – Alibaba (Jul 2024)
- Jamba-1.5: Hybrid Transformer-Mamba Models at Scale – AI21 Labs (Aug 2024)
- Qwen2-VL: Enhancing Vision-Language Model's Perception of the World at Any Resolution – Alibaba (Sep 2024)
- Qwen2.5-Coder Technical Report – Alibaba (Sep 2024)
- OLMoE: Open Mixture-of-Experts Language Models – AI2 (Sep 2024)
- GPT-4o System Card – OpenAI (Oct 2024)
- Hunyuan-Large: An Open-Source MoE Model with 52 Billion Activated Parameters by Tencent – Tencent (Nov 2024)
- Tülu 3: Pushing Frontiers in Open Language Model Post-Training – AI2 (Nov 2024)
- OpenAI o1 System Card – OpenAI (Dec 2024)
- Phi-4 Technical Report – Microsoft (Dec 2024)
- DeepSeek-V3 Technical Report – DeepSeek (Dec 2024)
- Qwen2.5 Technical Report – Alibaba (Dec 2024)
- Yi-Lightning Technical Report – 01.AI (Dec 2024)
- 2 OLMo 2 Furious – AI2 (Dec 2024)
2025
- DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning – DeepSeek (Jan 2025)
- Kimi k1.5: Scaling Reinforcement Learning with LLMs – Moonshot AI (Jan 2025)
- MiniMax-01: Scaling Foundation Models with Lightning Attention – MiniMax (Jan 2025)
- Qwen2.5-VL Technical Report – Alibaba (Feb 2025)
- Gemma 3 Technical Report – Google / DeepMind (Mar 2025)
- Phi-4-reasoning Technical Report – Microsoft (Apr 2025)
- Kimi-VL Technical Report – Moonshot AI (Apr 2025)
- The Llama 4 Herd: The Beginning of a New Era of Natively Multimodal AI – Meta (Apr 2025)
- Claude 4 System Card – Anthropic (May 2025)
- Llama-Nemotron: Efficient Reasoning Models – NVIDIA (May 2025)
- Qwen3 Technical Report – Alibaba (May 2025)
- Pangu Ultra: Pushing the Limits of Dense Large Language Models on Ascend NPUs – Huawei (May 2025)
- Gemini 2.5: Pushing the Frontier with Advanced Reasoning, Multimodality, Long Context, and Next-Generation Agentic Capabilities – Google / DeepMind (Jun 2025)
- MiniMax-M1: Scaling Test-Time Compute Efficiently with Lightning Attention – MiniMax (Jun 2025)
- Kimi K2: Open Agentic Intelligence – Moonshot AI (Jul 2025)
- GPT-oss-120b & GPT-oss-20b Model Card – OpenAI (Aug 2025)
- GLM-4.5: Agentic, Reasoning, and Coding (ARC) Foundation Models – Zhipu AI (Aug 2025)
2026
- Falcon-H1R: Pushing the Reasoning Frontiers with a Hybrid Model for Efficient Test-Time Scaling – TII (Jan 2026)
- Qwen3-VL-Embedding and Qwen3-VL-Reranker: A Unified Framework for State-of-the-Art Multimodal Retrieval and Ranking – Alibaba (Jan 2026)
- Ministral 3 – Mistral AI (Jan 2026)
- TranslateGemma Technical Report – Google / DeepMind (Jan 2026)
- Qwen3-ASR Technical Report – Alibaba (Jan 2026)
- GLM-5: from Vibe Coding to Agentic Engineering – Zhipu AI (Feb 2026)
- Qwen3-Coder-Next Technical Report – Alibaba (Feb 2026)
- Qwen3.5-Omni Technical Report – Alibaba (Apr 2026)
- Nemotron 3 Nano Omni: Efficient and Open Multimodal Intelligence – NVIDIA (Apr 2026)
- Granite Embedding Multilingual R2 Models – IBM (May 2026)
ML Conferences
NeurIPS 2025
A curated collection of NeurIPS 2025 papers focused on efficient systems for generative AI models. The collection includes papers on:
- Architecture & Efficient Mechanisms - Efficient attention, KV-cache systems, speculative decoding
- Model Compression & Quantization - Quantization, pruning, KV cache compression
- Inference & Serving - LLM serving, scheduling, distributed inference
- Multi-Modal & Diffusion - VLM efficiency, diffusion optimization
- Reinforcement Learning - RL training infrastructure, policy optimization
- Training Systems - Distributed training, memory efficiency
See the full NeurIPS 2025 collection for detailed categorization and paper summaries.
LLM Frameworks
Training
-
DeepSpeed: a deep learning optimization library that makes distributed training and inference easy, efficient, and effective | Microsoft
-
Accelerate | Hugging Face
-
Megatron | Nvidia
-
NeMo | Nvidia
-
torchtitan | PyTorch
-
torchtune: PyTorch-native fine-tuning library for LLMs with minimal dependencies | PyTorch
-
veScale | ByteDance
-
VeOmni: Scaling any Modality Model Training
-
Cornstarch: Distributed Multimodal Training Must Be Multimodality-Aware | UMich
-
GPT-NeoX: Model-parallel autoregressive LLM training combining Megatron and DeepSpeed | EleutherAI
-
nanotron: Minimalistic 3D-parallel (tensor/pipeline/data) LLM training framework | Hugging Face
-
litgpt: 20+ LLM implementations with pre-training and fine-tuning recipes | Lightning AI
-
LLaMA-Factory: Unified efficient fine-tuning of 100+ LLMs and VLMs via LoRA, full fine-tuning, and RL methods | ACL' 24
-
Unsloth: 2-5x faster LLM fine-tuning with ~80% less memory via custom Triton/CUDA kernels
-
Post-Training
- PEFT: Parameter-efficient fine-tuning library (LoRA, QLoRA, Prompt Tuning, IA3, etc.) | Hugging Face
- TRL: Transformers Reinforcement Learning
- OpenRLHF: An Easy-to-use, Scalable and High-performance RLHF Framework based on Ray
- VeRL: Volcano Engine Reinforcement Learning for LLMs
- rLLM: Reinforcement Learning for Language Agents
- SkyRL: A Modular Full-stack RL Library for LLMs
- AReal: Distributed RL System for LLM Reasoning
- ROLL: Reinforcement Learning Optimization for Large-Scale Learning
- slime: a LLM post-training framework aiming for RL Scaling
- RAGEN: Training Agents by Reinforcing Reasoning
- Agent Lightning: Train ANY AI Agents with Reinforcement Learning
- LMFlow: Extensible toolkit for fine-tuning and inference of large foundation models
- NeMo-Aligner: Scalable alignment toolkit for SFT, PPO, DPO, and SteerLM on NeMo | Nvidia
Serving
- llama.cpp: LLM inference in C/C++ with GGUF quantization; supports CPU, Metal, CUDA, and wide hardware
- Ollama: Local LLM serving with model management and OpenAI-compatible API
- TensorRT-LLM | Nvidia
- Triton Inference Server: Production multi-framework model serving platform with dynamic batching | Nvidia
- Ray-LLM | Ray
- TGI | Hugging Face
- vLLM | UCB
- SGLang | UCB
- LMDeploy: LLM compression, deployment, and serving toolkit with TurboMind persistent batching engine | InternLM
- LightLLM: Lightweight Python LLM serving with tri-process architecture decoupling prefill and decode
- DeepSpeed-MII: Low-latency, high-throughput LLM inference powered by DeepSpeed | Microsoft
- CTranslate2: Fast C++/Python inference engine for Transformer models with int8/int16 quantization | OpenNMT
- Petals: Distributed LLM inference and fine-tuning across volunteer GPUs in a BitTorrent-like fashion | ACL' 23
- KV Transformers
- Dynamo: A Datacenter Scale Distributed Inference Serving Framework | Nvidia
- LMCache: Supercharge Your LLM with the Fastest KV Cache Layer
- aibrix: Cost-efficient pluggable infrastructure for GenAI inference (KV cache routing, autoscaling, disaggregated prefill) | vLLM Project
ML Systems
Survey Paper
- Efficient Large Language Models: A Survey
- Challenges and Applications of Large Language Models
- Beyond Efficiency: A Systematic Survey of Resource-Efficient Large Language Models
- Towards Efficient Generative Large Language Model Serving: A Survey from Algorithms to Systems
LLM Benchmark / Leaderboard ? Traces
- LLM Energy Leaderboard | Umich
- LLM-Perf Leaderboard | HuggingFace
- Aviary Explorer | Anyscale
- Open LLM Leaderboard | HuggingFace
- HELM | Stanford
- LMSYS | UCB
- Towards Efficient and Reliable LLM Serving: A Real-World Workload Study
- FlashInfer-Bench / LLMInfer-Bench: Benchmarking LLM Inference Kernels and Systems | MLSys' 26
- DriftBench: Measuring and Predicting Infrastructure Drift in LLM Serving Systems | MLSys' 26
- Charon: A Unified Simulator for LLM Training and Inference | MLSys' 26
- ProfInfer: eBPF-based Fine-Grained LLM Inference Profiler | MLSys' 26
Related ML Readings
- Large Transformer Model Inference Optimization
- Transformer Inference Arithmetic
- The Transformer Family Version 2.0
- Full Stack Optimization of Transformer Inference: a Survey | UCB
- The Smol Training Playbook: The Secrets to Building World-Class LLMs | Hugging Face
- The Ultra-Scale Playbook: Training LLMs on GPU Clusters | Hugging Face
MLSys Courses
- Systems for Machine Learning | (Stanford)[https://cs229s.stanford.edu/fall2023/]
- Systems for Generative AI | (Umich)[https://github.com/mosharaf/eecs598/tree/w24-genai]
- Systems for AI - LLMs | (GT)[https://cs8803-sp24.anand-iyer.com/]
Other Reading
- A curated list of Large Language Model
- AI systems paper list
- A baseline repository of Auto-Parallelism in Training Neural Networks
- Numbers every LLM Developer should know
- 100,000 H100 Clusters: Power, Network Topology, Ethernet vs InfiniBand, Reliability, Failures, Checkpointing
- OpenAI Keynote on Building Scalable AI Infrastructure
- Awesome ML SYS Tutorial
Similar repos
Contributors
Languages
Python
100.0%