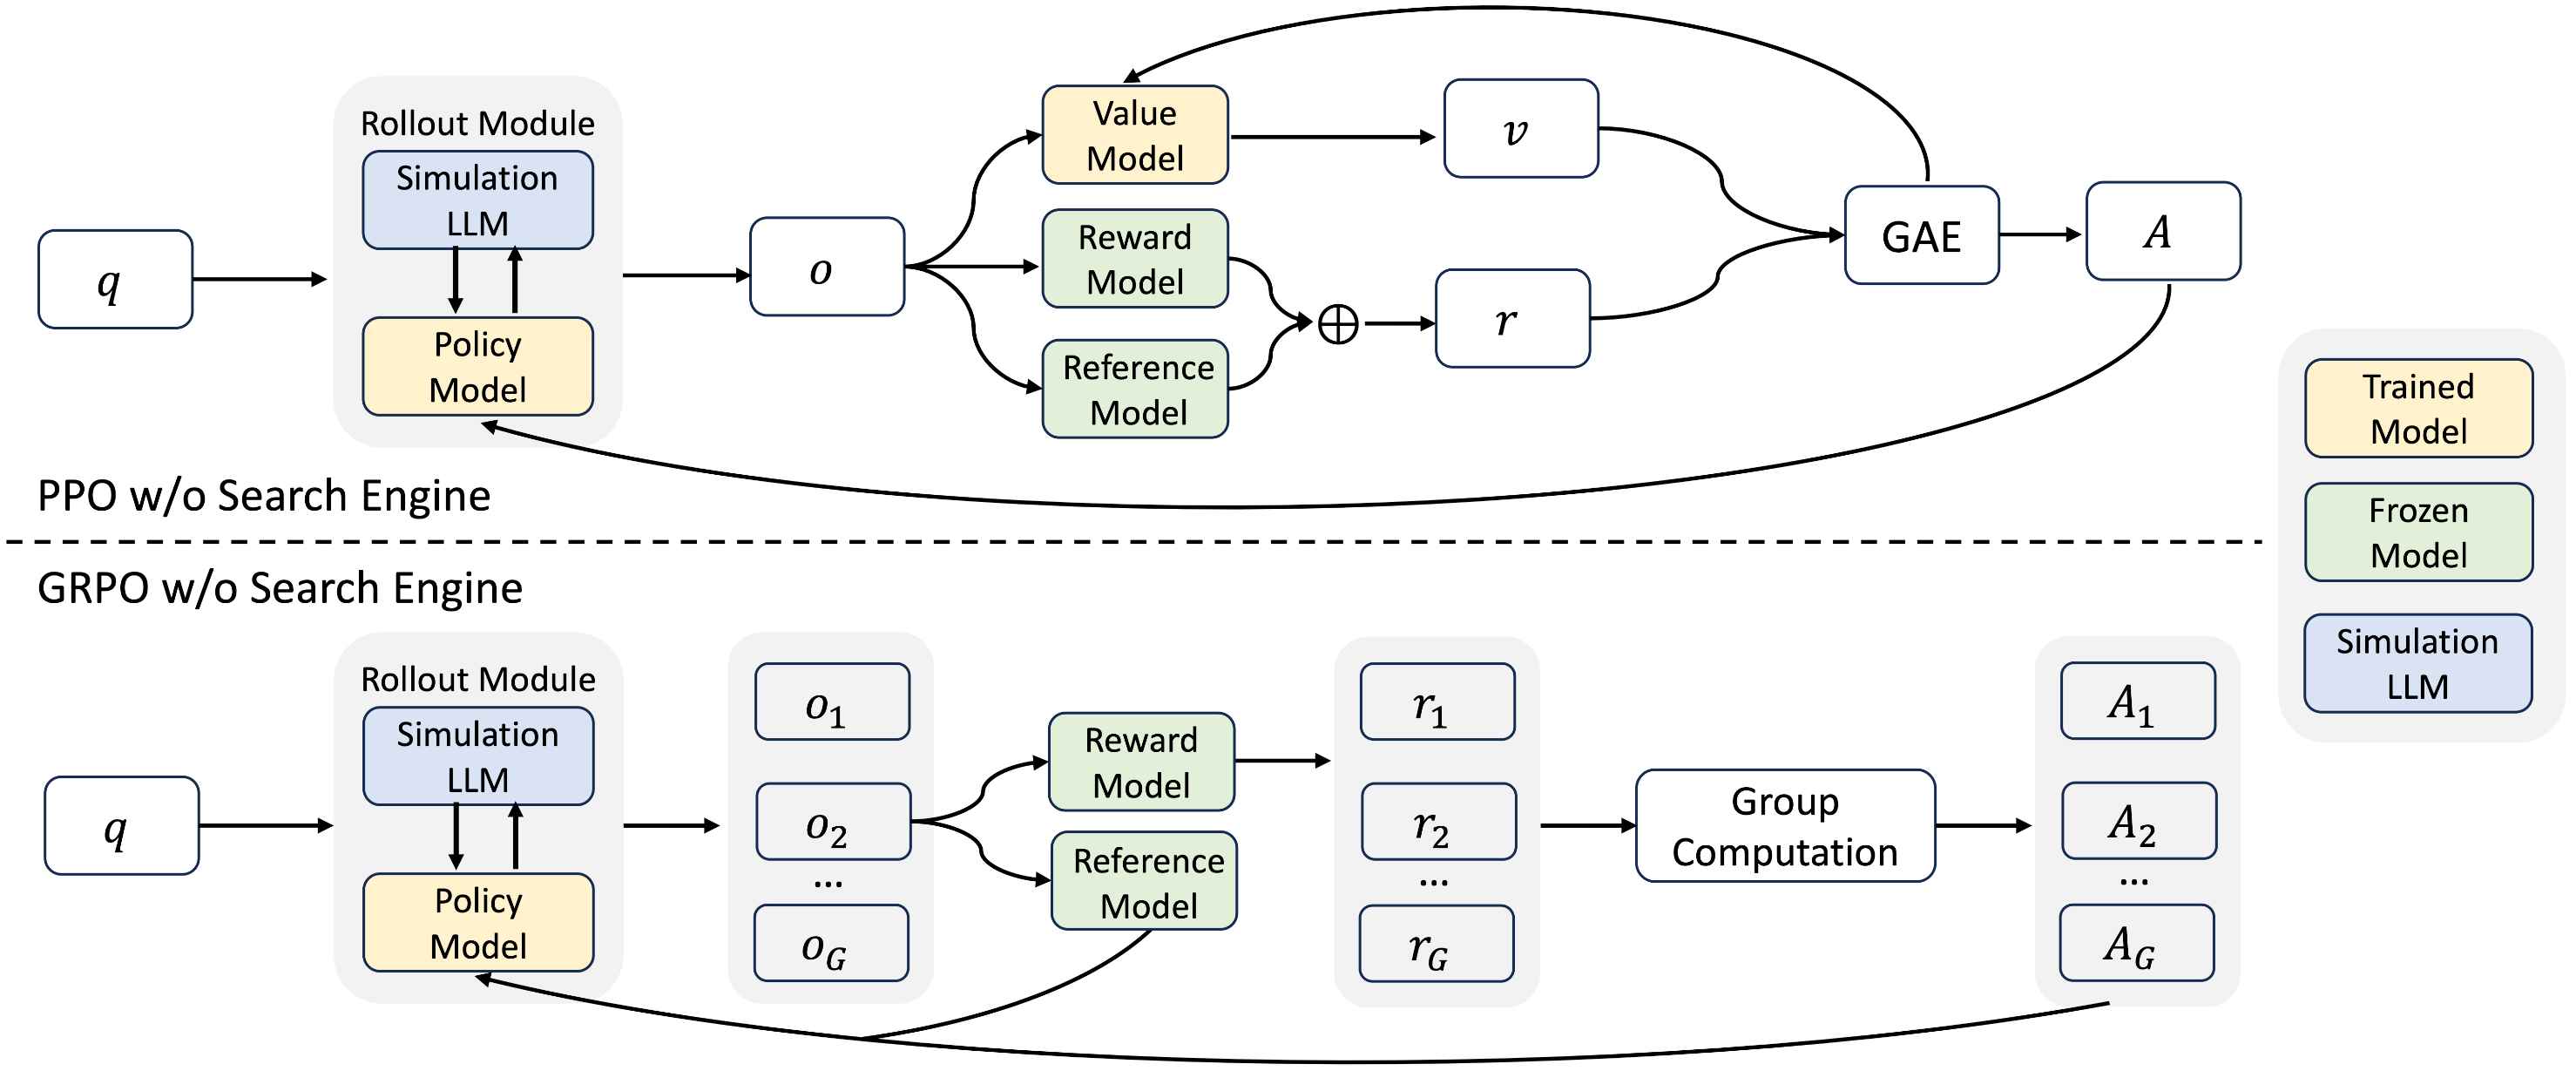
ZeroSearch: Incentivize the Search Capability of LLMs without Searching
See the code


Hao Sun, Zile Qiao, Jiayan Guo, Xuanbo Fan, Yingyan Hou
Yong Jiang, Pengjun Xie, Yan Zhang, Fei Huang, Jingren Zhou
Tongyi Lab  , Alibaba Group
conda create -n zerosearch python=3.9
conda activate zerosearch
pip install torch==2.4.0 --index-url https://download.pytorch.org/whl/cu121
pip install vllm==0.6.3
pip install wandb
pip install serpapi

# verl
pip install -e .

# flash attention 2
pip3 install flash-attn --no-build-isolation

# sglang
# If you encounter package conflicts when trying to install sglang in the current environment, we recommend creating a new environment and installing sglang there.
pip install sglang[all]
(1) Download the training dataset.
huggingface-cli download --repo-type dataset --resume-download sunhaonlp/ZeroSearch_dataset --local-dir ZeroSearch_dataset

# (Optional) Download the Simulation Tuning dataset, required only if you want to train your own simulation LLMs
huggingface-cli download --repo-type dataset --resume-download sunhaonlp/SimulationTuning_dataset --local-dir SimulationTuning_dataset
(2) Download the simulation LLMs.
# Simulation LLMs are available in different parameter sizes. Choose the one that best suits your needs.
# The 14B version is recommended for its stable and reliable simulation performance.
huggingface-cli download --resume-download sunhaonlp/Simulation_LLM_google_3B_V2 --local-dir Simulation_LLM_google_3B

huggingface-cli download --resume-download sunhaonlp/Simulation_LLM_google_7B_V2 --local-dir Simulation_LLM_google_7B

huggingface-cli download --resume-download sunhaonlp/Simulation_LLM_google_14B_V2 --local-dir Simulation_LLM_google_14B
(3) Launch a local simulation server.
# Prompt-based simulation
python -m sglang.launch_server --model-path Qwen2.5-14B-Instruct --host 0.0.0.0 --tp 2 --dp 2 --port 6001

# Fine-tuning-based simulation
python -m sglang.launch_server --model-path Simulation_LLM_google_14B --host 0.0.0.0 --tp 2 --dp 2 --port 6001
(4) Conduct RL training with Qwen2.5-3B-Instruct.
# Activate the conda environment
conda activate zerosearch

# Set your Google Search API key
export SER_API_KEY=your_api_key

# You can run REINFORCE, GRPO or PPO training using the scripts below.
# The START_THRESHOLD and END_THRESHOLD parameters define the initial and final difficulty levels of the training tasks. Adjusting these values can help optimize model performance.

## Prompt-based simulation
bash train_reinforce.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_prompt SIMULATION_LLM Qwen2.5-14B-Instruct START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_grpo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_prompt SIMULATION_LLM Qwen2.5-14B-Instruct START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_ppo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_prompt SIMULATION_LLM Qwen2.5-14B-Instruct START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5

## Fine-tuning-based simulation
bash train_reinforce.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_sft SIMULATION_LLM Simulation_LLM_google_14B START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_grpo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_sft SIMULATION_LLM Simulation_LLM_google_14B START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_ppo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_sft SIMULATION_LLM Simulation_LLM_google_14B START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
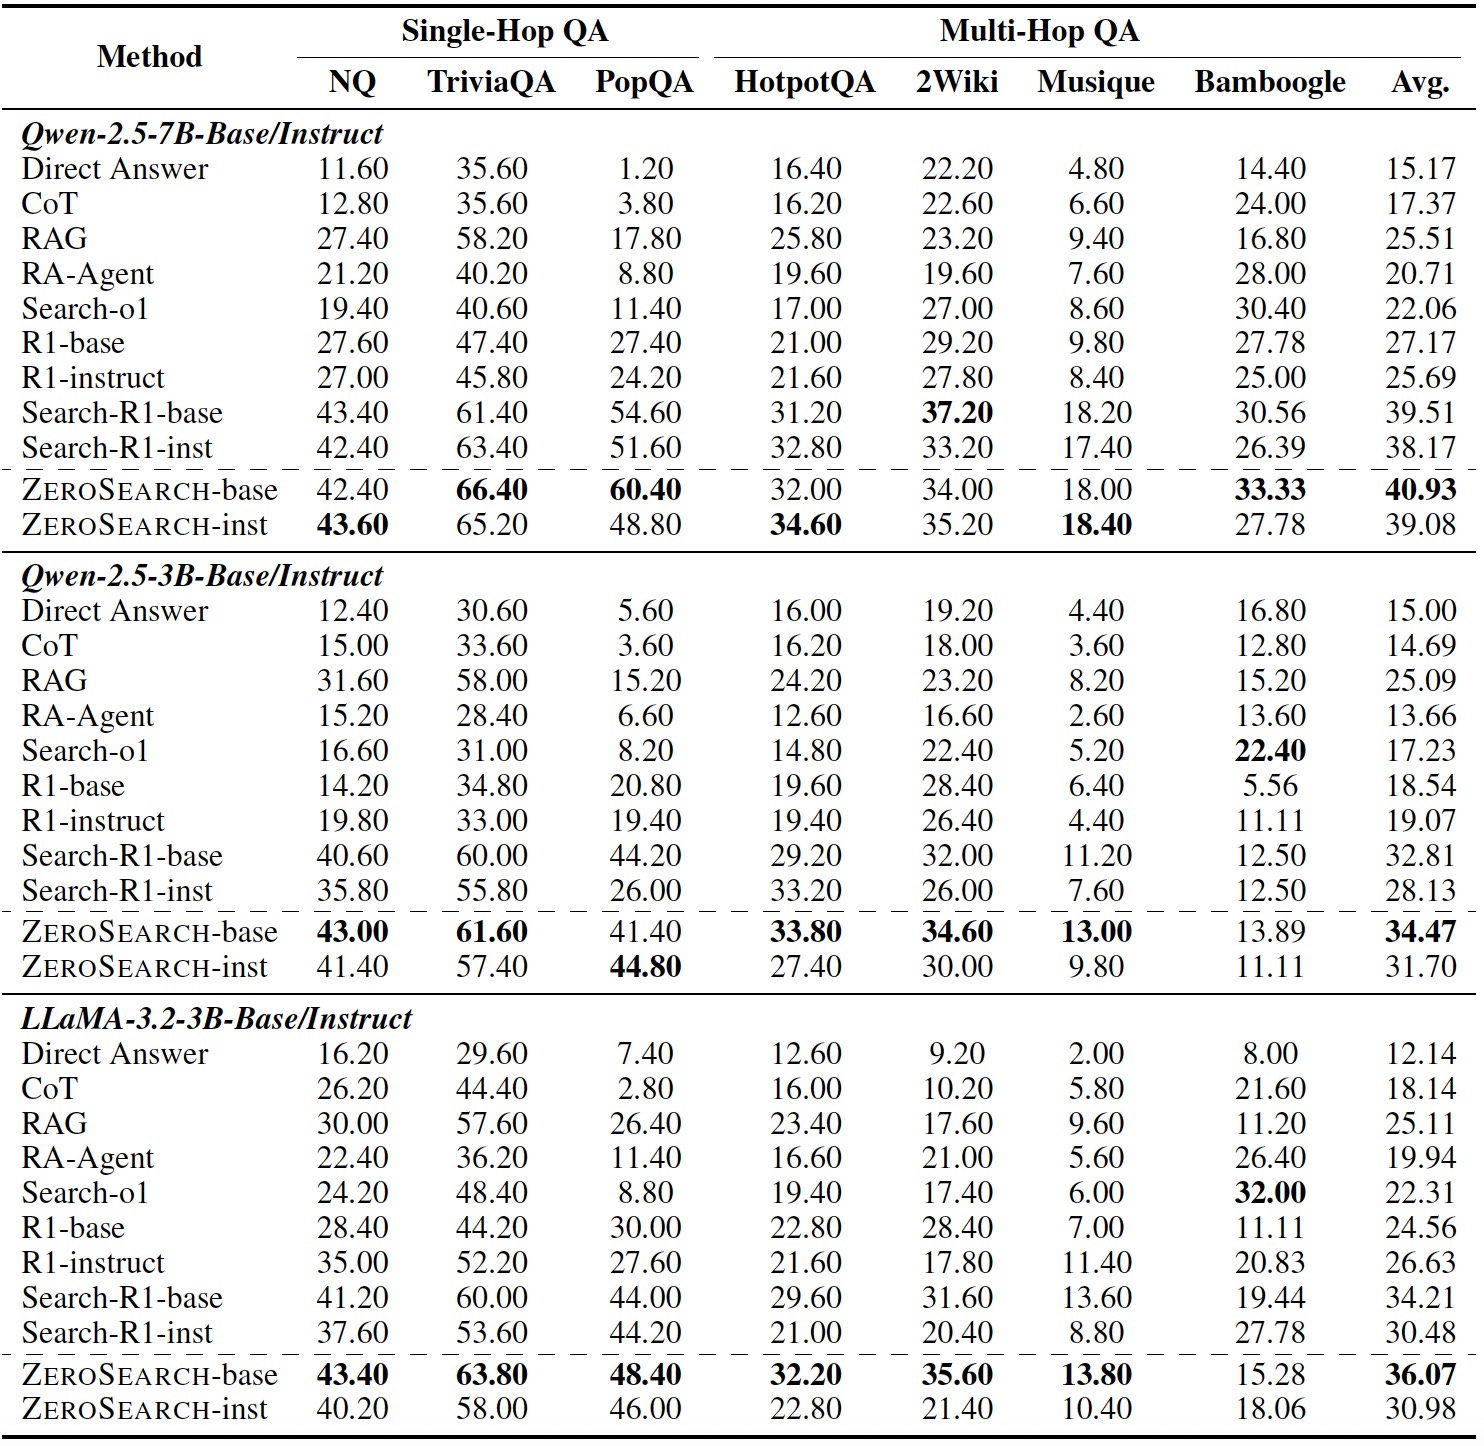
This work is implemented based on Search-R1, veRL, and RAGEN. We sincerely thank the authors of these projects for their valuable contributions to the open-source community.

If you have any questions, feel free to reach out to me via email: [email protected]
If this work is helpful, please kindly cite as:
@article{sun2025zerosearch,
  title={ZeroSearch: Incentivize the Search Capability of LLMs without Searching},
  author={Sun, Hao and Qiao, Zile and Guo, Jiayan and Fan, Xuanbo and Hou, Yingyan and Jiang, Yong and Xie, Pengjun and Huang, Fei and Zhang, Yan},
  journal={arXiv preprint arXiv:2505.04588},
  year={2025}
}
2,396 followers · starred Aug 2025
214 followers · starred Nov 2025
835 followers · starred May 2025
1,018 followers · starred May 2025
ZeroSearch: Incentivize the Search Capability of LLMs without Searching
See the code
Hao Sun, Zile Qiao, Jiayan Guo, Xuanbo Fan, Yingyan Hou
Yong Jiang, Pengjun Xie, Yan Zhang, Fei Huang, Jingren Zhou
Tongyi Lab , Alibaba Group
conda create -n zerosearch python=3.9
conda activate zerosearch
pip install torch==2.4.0 --index-url https://download.pytorch.org/whl/cu121
pip install vllm==0.6.3
pip install wandb
pip install serpapi

# verl
pip install -e .

# flash attention 2
pip3 install flash-attn --no-build-isolation

# sglang
# If you encounter package conflicts when trying to install sglang in the current environment, we recommend creating a new environment and installing sglang there.
pip install sglang[all]
(1) Download the training dataset.
huggingface-cli download --repo-type dataset --resume-download sunhaonlp/ZeroSearch_dataset --local-dir ZeroSearch_dataset

# (Optional) Download the Simulation Tuning dataset, required only if you want to train your own simulation LLMs
huggingface-cli download --repo-type dataset --resume-download sunhaonlp/SimulationTuning_dataset --local-dir SimulationTuning_dataset
(2) Download the simulation LLMs.
# Simulation LLMs are available in different parameter sizes. Choose the one that best suits your needs.
# The 14B version is recommended for its stable and reliable simulation performance.
huggingface-cli download --resume-download sunhaonlp/Simulation_LLM_google_3B_V2 --local-dir Simulation_LLM_google_3B

huggingface-cli download --resume-download sunhaonlp/Simulation_LLM_google_7B_V2 --local-dir Simulation_LLM_google_7B

huggingface-cli download --resume-download sunhaonlp/Simulation_LLM_google_14B_V2 --local-dir Simulation_LLM_google_14B
(3) Launch a local simulation server.
# Prompt-based simulation
python -m sglang.launch_server --model-path Qwen2.5-14B-Instruct --host 0.0.0.0 --tp 2 --dp 2 --port 6001

# Fine-tuning-based simulation
python -m sglang.launch_server --model-path Simulation_LLM_google_14B --host 0.0.0.0 --tp 2 --dp 2 --port 6001
(4) Conduct RL training with Qwen2.5-3B-Instruct.
# Activate the conda environment
conda activate zerosearch

# Set your Google Search API key
export SER_API_KEY=your_api_key

# You can run REINFORCE, GRPO or PPO training using the scripts below.
# The START_THRESHOLD and END_THRESHOLD parameters define the initial and final difficulty levels of the training tasks. Adjusting these values can help optimize model performance.

## Prompt-based simulation
bash train_reinforce.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_prompt SIMULATION_LLM Qwen2.5-14B-Instruct START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_grpo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_prompt SIMULATION_LLM Qwen2.5-14B-Instruct START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_ppo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_prompt SIMULATION_LLM Qwen2.5-14B-Instruct START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5

## Fine-tuning-based simulation
bash train_reinforce.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_sft SIMULATION_LLM Simulation_LLM_google_14B START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_grpo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_sft SIMULATION_LLM Simulation_LLM_google_14B START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
bash train_ppo.sh NUM_GPUS_PER_NODE 4 MODEL_PATH Qwen2.5-3B-Instruct DATA_PATH ZeroSearch_dataset TOTAL_STEPS 203 IP localhost SEARCH_MODE simulate_sft SIMULATION_LLM Simulation_LLM_google_14B START_THRESHOLD 0 END_THRESHOLD 0.5 SEARCH_ENGINE google MAX_TURNS 5 TOPK 5
This work is implemented based on Search-R1, veRL, and RAGEN. We sincerely thank the authors of these projects for their valuable contributions to the open-source community.
If you have any questions, feel free to reach out to me via email: [email protected]
If this work is helpful, please kindly cite as:
@article{sun2025zerosearch,
  title={ZeroSearch: Incentivize the Search Capability of LLMs without Searching},
  author={Sun, Hao and Qiao, Zile and Guo, Jiayan and Fan, Xuanbo and Hou, Yingyan and Jiang, Yong and Xie, Pengjun and Huang, Fei and Zhang, Yan},
  journal={arXiv preprint arXiv:2505.04588},
  year={2025}
}
2,396 followers · starred Aug 2025
214 followers · starred Nov 2025
835 followers · starred May 2025
1,018 followers · starred May 2025