A light-weight deep reinforcement learning framework for portfolio management. This project explores the possibility of applying deep reinforcement learning algorithms to stock trading in a highly modular and scalable framework.
Jupyter Notebook
690
173 commits
updated Nov 6, 2024
This project intends to leverage deep reinforcement learning in portfolio management. The framework structure is inspired by Q-Trader. The reward for agents is the net unrealized (meaning the stocks are still in portfolio and not cashed out yet) profit evaluated at each action step. For inaction at each step, a negtive penalty is added to the portfolio as the missed opportunity to invest in "risk-free" Treasury bonds. A lot of new features and improvements are made in the training and evaluation pipelines. All evaluation metrics and visualizations are built from scratch.
Key assumptions and limitations of the current framework:
Key challenges of the current framework:
Currently, the state is defined as the normalized adjacent daily stock price differences for n days plus [stock_price, balance, num_holding].
In the future, we plan to add other state-of-the-art deep reinforcement learning algorithms, such as Proximal Policy Optimization (PPO), to the framework and increase the complexity to the state in each algorithm by constructing more complex price tensors etc. with a wider range of deep learning approaches, such as convolutional neural networks or attention mechanism. In addition, we plan to integrate better pipelines for high quality data source, e.g. from vendors like Quandl; and backtesting, e.g. zipline.
To install all libraries/dependencies used in this project, run
pip3 install -r requirements.txt
To train a DDPG agent or a DQN agent, e.g. over S&P 500 from 2010 to 2015, run
python3 train.py --model_name=model_name --stock_name=stock_name
model_name is the model to use: either DQN or DDPG; default is DQNstock_name is the stock used to train the model; default is ^GSPC_2010-2015, which is S&P 500 from 1/1/2010 to 12/31/2015window_size is the span (days) of observation; default is 10num_episode is the number of episodes used for training; default is 10initial_balance is the initial balance of the portfolio; default is 50000To evaluate a DDPG or DQN agent, run
python3 evaluate.py --model_to_load=model_to_load --stock_name=stock_name
model_to_load is the model to load; default is DQN_ep10; alternative is DDPG_ep10 etc.stock_name is the stock used to evaluate the model; default is ^GSPC_2018, which is S&P 500 from 1/1/2018 to 12/31/2018initial_balance is the initial balance of the portfolio; default is 50000window_size is the span (days) of observation; default is 10where stock_name can be referred in data directory and model_to_laod can be referred in saved_models directory.
To visualize training loss and portfolio value fluctuations history, run:
tensorboard --logdir=logs/model_events
where model_events can be found in logs directory.
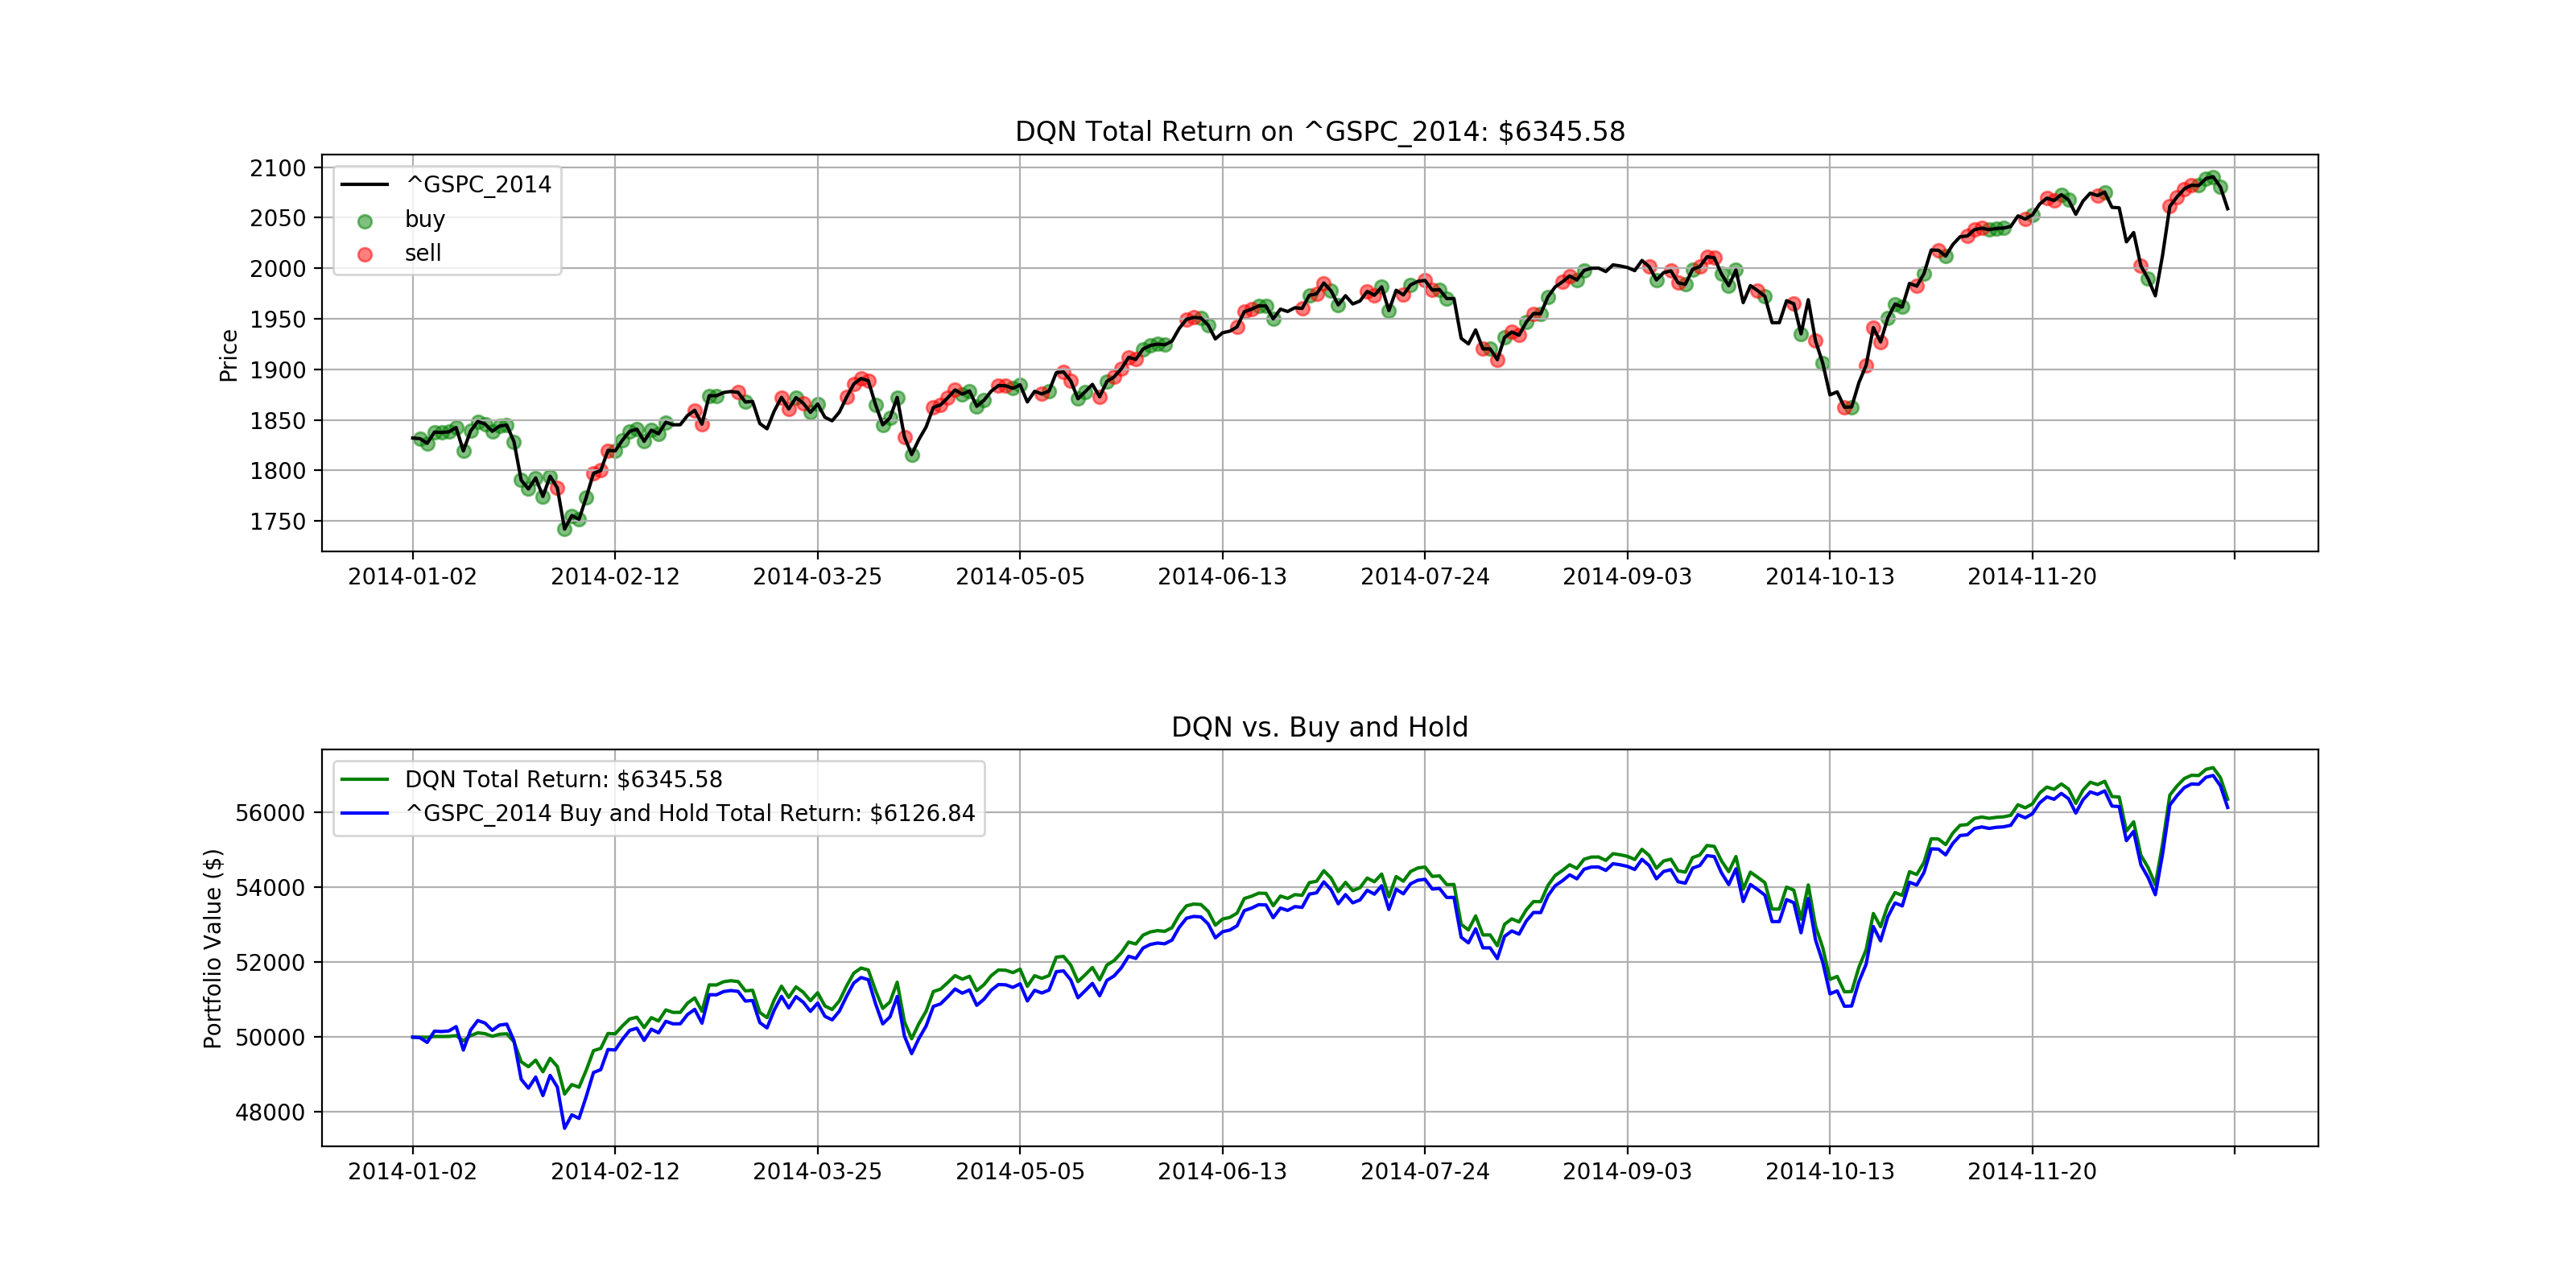
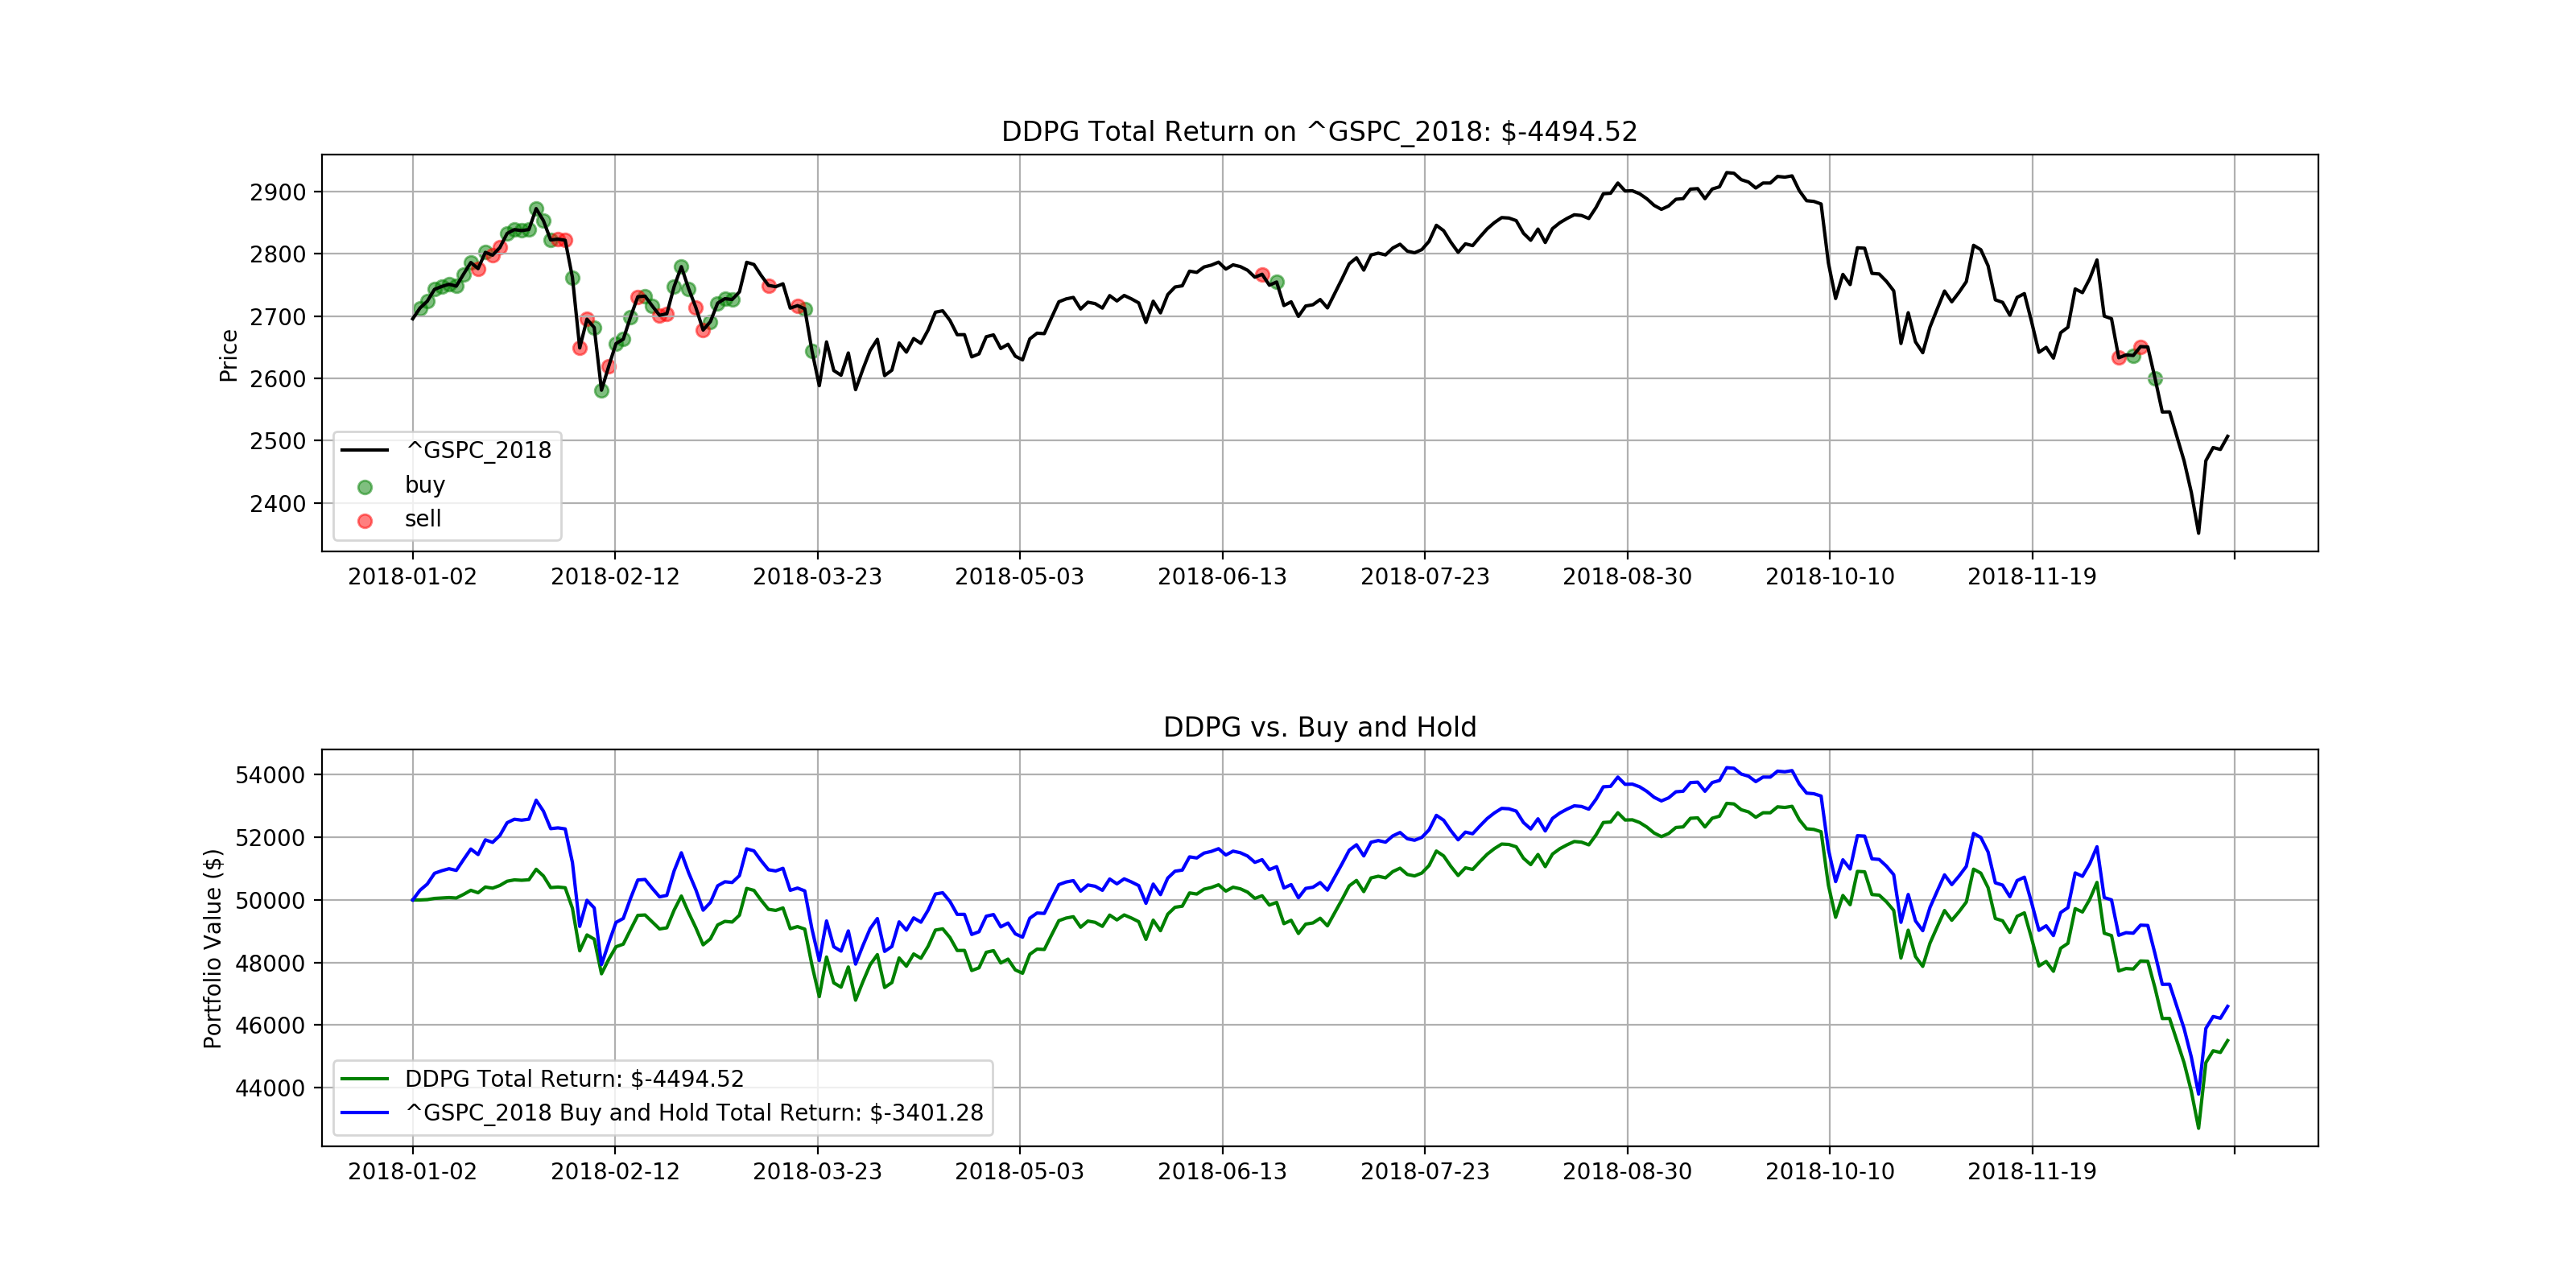
Note that the following results were obtained with 10 epochs of training only.
175 followers · starred Apr 2023
174 followers · starred Oct 2020
40 followers · starred Jun 2025
26 followers · starred Sep 2025
A light-weight deep reinforcement learning framework for portfolio management. This project explores the possibility of applying deep reinforcement learning algorithms to stock trading in a highly modular and scalable framework.
Jupyter Notebook
690
173 commits
updated Nov 6, 2024
This project intends to leverage deep reinforcement learning in portfolio management. The framework structure is inspired by Q-Trader. The reward for agents is the net unrealized (meaning the stocks are still in portfolio and not cashed out yet) profit evaluated at each action step. For inaction at each step, a negtive penalty is added to the portfolio as the missed opportunity to invest in "risk-free" Treasury bonds. A lot of new features and improvements are made in the training and evaluation pipelines. All evaluation metrics and visualizations are built from scratch.
Key assumptions and limitations of the current framework:
Key challenges of the current framework:
Currently, the state is defined as the normalized adjacent daily stock price differences for n days plus [stock_price, balance, num_holding].
In the future, we plan to add other state-of-the-art deep reinforcement learning algorithms, such as Proximal Policy Optimization (PPO), to the framework and increase the complexity to the state in each algorithm by constructing more complex price tensors etc. with a wider range of deep learning approaches, such as convolutional neural networks or attention mechanism. In addition, we plan to integrate better pipelines for high quality data source, e.g. from vendors like Quandl; and backtesting, e.g. zipline.
To install all libraries/dependencies used in this project, run
pip3 install -r requirements.txt
To train a DDPG agent or a DQN agent, e.g. over S&P 500 from 2010 to 2015, run
python3 train.py --model_name=model_name --stock_name=stock_name
model_name is the model to use: either DQN or DDPG; default is DQNstock_name is the stock used to train the model; default is ^GSPC_2010-2015, which is S&P 500 from 1/1/2010 to 12/31/2015window_size is the span (days) of observation; default is 10num_episode is the number of episodes used for training; default is 10initial_balance is the initial balance of the portfolio; default is 50000To evaluate a DDPG or DQN agent, run
python3 evaluate.py --model_to_load=model_to_load --stock_name=stock_name
model_to_load is the model to load; default is DQN_ep10; alternative is DDPG_ep10 etc.stock_name is the stock used to evaluate the model; default is ^GSPC_2018, which is S&P 500 from 1/1/2018 to 12/31/2018initial_balance is the initial balance of the portfolio; default is 50000window_size is the span (days) of observation; default is 10where stock_name can be referred in data directory and model_to_laod can be referred in saved_models directory.
To visualize training loss and portfolio value fluctuations history, run:
tensorboard --logdir=logs/model_events
where model_events can be found in logs directory.
Note that the following results were obtained with 10 epochs of training only.
175 followers · starred Apr 2023
174 followers · starred Oct 2020
40 followers · starred Jun 2025
26 followers · starred Sep 2025