
LLM-based code analysis tool for detecting suspicious or inconsistent code regions written in Rust 🦀
Rust
7
32 commits
updated Jan 4, 2026
README
Ouakha
LLM-based code analysis tool for detecting suspicious or inconsistent code regions.
Why "Ouakha"?
Ouakha (واخا) means "agree" or "okay" in Moroccan Darija (dialect). The name captures the core concept: this tool finds places where the LLM model doesn't agree with your code; highlighting tokens that seem surprising, inconsistent, or potentially buggy.
When the model "ouakha" (agrees) with your code, everything looks fine. When it doesn't? That's where you should look closer.
Ouakha uses local LLMs to evaluate next-token predictions and find locations where the model "disagrees" with the actual code; indicating potentially surprising, inconsistent, or suspicious code.
Code Visualization
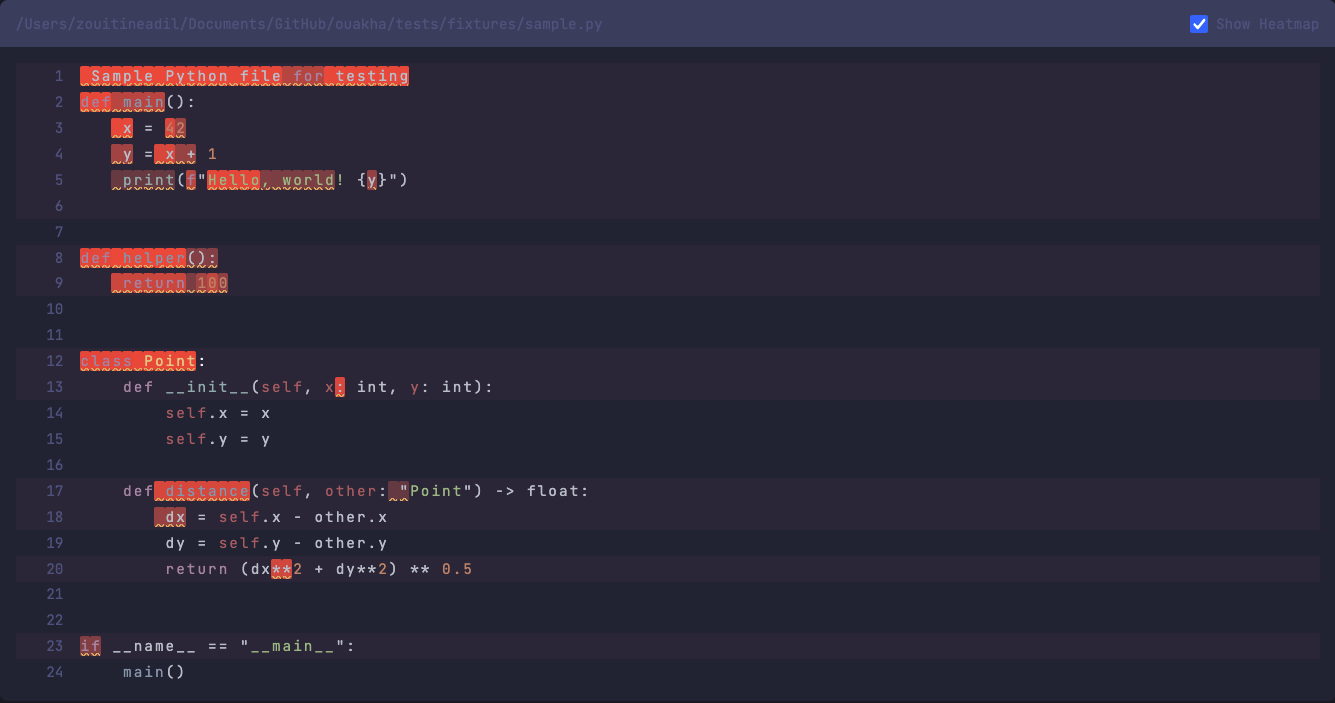
Heatmap visualization showing model confidence — red highlights indicate low confidence (potential issues)
Features
- TUI Interface: Vim-style navigation (hjkl, gg/G, /search, ]d/[d for diagnostics)
- Web UI: Browser-based interface with HTMX
- Vim/Neovim Integration: Quickfix format output and Lua plugin
- Git-Aware: Analyze changed files in your repository
- Pluggable Backends: Support for multiple LLM backends:
- vLLM (default): HTTP backend for high-performance GPU inference
- Candle: Local inference with StarCoder models
- Confidence Visualization: Color gradient based on model confidence
Prerequisites
Ouakha uses vLLM as the default backend for inference. Install it before running:
pip install vllm
Installation
Download Pre-built Binaries
Download the latest release for your platform from GitHub Releases:
- Linux (x86_64):
ouakha-linux-x86_64.tar.gz - macOS (Intel):
ouakha-macos-x86_64.tar.gz - macOS (Apple Silicon):
ouakha-macos-aarch64.tar.gz
# Example for macOS Apple Silicon
tar -xzf ouakha-macos-aarch64.tar.gz
sudo mv ouakha /usr/local/bin/
Build from Source
# Clone the repository
git clone https://github.com/yourusername/ouakha.git
cd ouakha

# Build (requires Rust 1.83+)
cargo build --release

# With Metal support (macOS)
cargo build --release --features metal

# With CUDA support (Linux)
cargo build --release --features cuda
Usage
Single File Analysis
# 1. Start vLLM server (vLLM is the default backend)
vllm serve bigcode/starcoder2-3b --port 8000

# 2. Analyze with TUI (default)
ouakha analyze src/main.rs

# Output to stdout
ouakha analyze src/main.rs --disable-tui --format=quickfix

# Use a different model
ouakha analyze src/main.rs --model codellama/CodeLlama-7b-hf
Using Candle Backend
For local inference without a separate server (useful for quick tests):
# Use Candle backend for local inference
ouakha analyze src/main.rs --backend candle

# Force CPU inference
ouakha analyze src/main.rs --backend candle --cpu
Project Analysis
# Analyze all supported files in a project
ouakha project ./my-project --extensions=rs,py,js
Git Integration
Ouakha can analyze only files with uncommitted changes and filter results to show only issues in changed lines:
# Analyze unstaged changes in working directory
ouakha git working

# Analyze staged changes only
ouakha git staged

# Analyze all changes (staged + unstaged)
ouakha git all

# Compare against a branch
ouakha git branch --base=main
The git integration:
- Detects added, modified, and renamed files
- Computes which specific lines were changed
- Filters flagged regions to only show issues on changed lines
- Supports working tree, staged changes, and branch comparisons
Web UI
# Start web server
ouakha web --addr=127.0.0.1:8080

# With pre-loaded results
ouakha web --results=analysis.json
Interactive TUI
ouakha tui src/main.rs
TUI Keybindings
| Key | Action |
|---|---|
h/j/k/l | Move cursor left/down/up/right |
gg | Jump to top of file |
G | Jump to bottom of file |
w/b | Word forward/backward |
Ctrl-d/u | Half-page down/up |
/pattern | Search forward |
n/N | Next/previous search match |
]d | Next flagged region (low confidence) |
[d | Previous flagged region |
t | Toggle confidence threshold |
q | Quit |
Vim/Neovim Integration
Quickfix Output
# Generate quickfix-compatible output
ouakha --file-path src/main.rs --disable-tui --format=quickfix > /tmp/ouakha.qf

# In Vim/Neovim
:cfile /tmp/ouakha.qf
:copen
Neovim Lua Plugin
Add to your Neovim config:
-- ~/.config/nvim/lua/plugins/ouakha.lua
return {
  dir = "/path/to/ouakha/nvim",
  config = function()
    require("ouakha").setup({
      threshold = 0.5,
      auto_analyze = false,
      signs = true,
    })
  end,
}
Commands:
:OuakhaAnalyze- Analyze current buffer:OuakhaNext/:OuakhaPrev- Navigate flagged regions:OuakhaQuickfix- Send results to quickfix list:OuakhaClear- Clear analysis results
Output Formats
summary- Human-readable summary (default)quickfix- Vim quickfix formatjson- Structured JSON outputlocationlist- Vim location list format
Environment Variables
HUGGINGFACE_TOKEN- HuggingFace API token (required for model download)
Configuration
CLI Options
--backend <BACKEND>    Backend to use: vllm, candle [default: vllm]
--backend-url <URL>    URL for HTTP backends [default: http://localhost:8000]
--model <MODEL>        Model to use [default: depends on backend]
--threshold <FLOAT>    Confidence threshold for flagging [default: 0.5]
--cpu                  Force CPU inference (Candle only)
--disable-cache        Disable result caching
--save-cache           Save analysis results to cache
--cache-dir <PATH>     Custom cache directory
--clear-cache          Clear all cached results
Caching
Ouakha uses a versioned cache system (v2) to store analysis results:
- Cache keys are computed from file path, backend, model, and file content
- Old cache entries from previous versions are automatically invalidated
- Cache files are stored as versioned JSON in
~/.cache/ouakha/
Note: After upgrading Ouakha, old cache entries will be ignored due to version changes. This is intentional to ensure consistency.
Supported Models
vLLM Backend (default, HTTP server):
bigcode/starcoder2-3b(default)- Any model supported by vLLM
Candle Backend (local inference):
bigcode/starcoderbase-1b(default, ~2GB)bigcode/starcoderbase-3b(~6GB)bigcode/starcoderbase-7b(~14GB)
Development
# Run tests
cargo test

# Run with debug output
RUST_LOG=debug cargo run -- --file-path test.rs

# Format code
cargo fmt

# Lint
cargo clippy
Architecture
src/
├── analysis/       # Core analysis logic
│   ├── code_agreement.rs  # Token/char level probability data
│   ├── chunker.rs         # Large file chunking with overlap merging
│   └── project.rs         # Multi-file project analysis
├── backend/        # LLM backend implementations
│   ├── mod.rs      # Backend trait
│   ├── candle.rs   # Candle/StarCoder (local)
│   └── vllm.rs     # vLLM HTTP backend
├── cache.rs        # Versioned cache system (v2)
├── model/          # Neural network models
│   └── big_coder.rs
├── tui/            # Terminal UI
│   ├── input.rs    # Input state machine
│   ├── search.rs   # Search functionality
│   └── view.rs     # Rendering
├── web/            # Web UI
│   ├── handlers.rs    # HTTP request handlers
│   ├── templates.rs   # HTML templates
│   └── code_renderer.rs  # Syntax-highlighted heatmap rendering
├── git/            # Git integration
│   ├── scanner.rs  # Working/staged/branch change detection
│   └── diff.rs     # Unified diff parsing
├── output/         # Output formatters
│   ├── quickfix.rs
│   └── json.rs
└── main.rs         # CLI entry point
Chunking for Large Files
For files exceeding the model's context window, Ouakha:
- Splits code at semantic boundaries (function definitions, empty lines)
- Creates overlapping chunks for continuity
- Merges results by averaging probabilities in overlapping regions
- Returns character-level probabilities (token proposals are not available in chunked mode)
License
MIT
Contributors

32 commits
Similar repos


Languages
Rust
96.9%
Lua
3.1%
LLM-based code analysis tool for detecting suspicious or inconsistent code regions written in Rust 🦀
Rust
7
32 commits
updated Jan 4, 2026
README
Ouakha
LLM-based code analysis tool for detecting suspicious or inconsistent code regions.
Why "Ouakha"?
Ouakha (واخا) means "agree" or "okay" in Moroccan Darija (dialect). The name captures the core concept: this tool finds places where the LLM model doesn't agree with your code; highlighting tokens that seem surprising, inconsistent, or potentially buggy.
When the model "ouakha" (agrees) with your code, everything looks fine. When it doesn't? That's where you should look closer.
Ouakha uses local LLMs to evaluate next-token predictions and find locations where the model "disagrees" with the actual code; indicating potentially surprising, inconsistent, or suspicious code.
Code Visualization
Heatmap visualization showing model confidence — red highlights indicate low confidence (potential issues)
Features
- TUI Interface: Vim-style navigation (hjkl, gg/G, /search, ]d/[d for diagnostics)
- Web UI: Browser-based interface with HTMX
- Vim/Neovim Integration: Quickfix format output and Lua plugin
- Git-Aware: Analyze changed files in your repository
- Pluggable Backends: Support for multiple LLM backends:
- vLLM (default): HTTP backend for high-performance GPU inference
- Candle: Local inference with StarCoder models
- Confidence Visualization: Color gradient based on model confidence
Prerequisites
Ouakha uses vLLM as the default backend for inference. Install it before running:
pip install vllm
Installation
Download Pre-built Binaries
Download the latest release for your platform from GitHub Releases:
- Linux (x86_64):
ouakha-linux-x86_64.tar.gz - macOS (Intel):
ouakha-macos-x86_64.tar.gz - macOS (Apple Silicon):
ouakha-macos-aarch64.tar.gz
# Example for macOS Apple Silicon
tar -xzf ouakha-macos-aarch64.tar.gz
sudo mv ouakha /usr/local/bin/
Build from Source
# Clone the repository
git clone https://github.com/yourusername/ouakha.git
cd ouakha

# Build (requires Rust 1.83+)
cargo build --release

# With Metal support (macOS)
cargo build --release --features metal

# With CUDA support (Linux)
cargo build --release --features cuda
Usage
Single File Analysis
# 1. Start vLLM server (vLLM is the default backend)
vllm serve bigcode/starcoder2-3b --port 8000

# 2. Analyze with TUI (default)
ouakha analyze src/main.rs

# Output to stdout
ouakha analyze src/main.rs --disable-tui --format=quickfix

# Use a different model
ouakha analyze src/main.rs --model codellama/CodeLlama-7b-hf
Using Candle Backend
For local inference without a separate server (useful for quick tests):
# Use Candle backend for local inference
ouakha analyze src/main.rs --backend candle

# Force CPU inference
ouakha analyze src/main.rs --backend candle --cpu
Project Analysis
# Analyze all supported files in a project
ouakha project ./my-project --extensions=rs,py,js
Git Integration
Ouakha can analyze only files with uncommitted changes and filter results to show only issues in changed lines:
# Analyze unstaged changes in working directory
ouakha git working

# Analyze staged changes only
ouakha git staged

# Analyze all changes (staged + unstaged)
ouakha git all

# Compare against a branch
ouakha git branch --base=main
The git integration:
- Detects added, modified, and renamed files
- Computes which specific lines were changed
- Filters flagged regions to only show issues on changed lines
- Supports working tree, staged changes, and branch comparisons
Web UI
# Start web server
ouakha web --addr=127.0.0.1:8080

# With pre-loaded results
ouakha web --results=analysis.json
Interactive TUI
ouakha tui src/main.rs
TUI Keybindings
| Key | Action |
|---|---|
h/j/k/l | Move cursor left/down/up/right |
gg | Jump to top of file |
G | Jump to bottom of file |
w/b | Word forward/backward |
Ctrl-d/u | Half-page down/up |
/pattern | Search forward |
n/N | Next/previous search match |
]d | Next flagged region (low confidence) |
[d | Previous flagged region |
t | Toggle confidence threshold |
q | Quit |
Vim/Neovim Integration
Quickfix Output
# Generate quickfix-compatible output
ouakha --file-path src/main.rs --disable-tui --format=quickfix > /tmp/ouakha.qf

# In Vim/Neovim
:cfile /tmp/ouakha.qf
:copen
Neovim Lua Plugin
Add to your Neovim config:
-- ~/.config/nvim/lua/plugins/ouakha.lua
return {
  dir = "/path/to/ouakha/nvim",
  config = function()
    require("ouakha").setup({
      threshold = 0.5,
      auto_analyze = false,
      signs = true,
    })
  end,
}
Commands:
:OuakhaAnalyze- Analyze current buffer:OuakhaNext/:OuakhaPrev- Navigate flagged regions:OuakhaQuickfix- Send results to quickfix list:OuakhaClear- Clear analysis results
Output Formats
summary- Human-readable summary (default)quickfix- Vim quickfix formatjson- Structured JSON outputlocationlist- Vim location list format
Environment Variables
HUGGINGFACE_TOKEN- HuggingFace API token (required for model download)
Configuration
CLI Options
--backend <BACKEND>    Backend to use: vllm, candle [default: vllm]
--backend-url <URL>    URL for HTTP backends [default: http://localhost:8000]
--model <MODEL>        Model to use [default: depends on backend]
--threshold <FLOAT>    Confidence threshold for flagging [default: 0.5]
--cpu                  Force CPU inference (Candle only)
--disable-cache        Disable result caching
--save-cache           Save analysis results to cache
--cache-dir <PATH>     Custom cache directory
--clear-cache          Clear all cached results
Caching
Ouakha uses a versioned cache system (v2) to store analysis results:
- Cache keys are computed from file path, backend, model, and file content
- Old cache entries from previous versions are automatically invalidated
- Cache files are stored as versioned JSON in
~/.cache/ouakha/
Note: After upgrading Ouakha, old cache entries will be ignored due to version changes. This is intentional to ensure consistency.
Supported Models
vLLM Backend (default, HTTP server):
bigcode/starcoder2-3b(default)- Any model supported by vLLM
Candle Backend (local inference):
bigcode/starcoderbase-1b(default, ~2GB)bigcode/starcoderbase-3b(~6GB)bigcode/starcoderbase-7b(~14GB)
Development
# Run tests
cargo test

# Run with debug output
RUST_LOG=debug cargo run -- --file-path test.rs

# Format code
cargo fmt

# Lint
cargo clippy
Architecture
src/
├── analysis/       # Core analysis logic
│   ├── code_agreement.rs  # Token/char level probability data
│   ├── chunker.rs         # Large file chunking with overlap merging
│   └── project.rs         # Multi-file project analysis
├── backend/        # LLM backend implementations
│   ├── mod.rs      # Backend trait
│   ├── candle.rs   # Candle/StarCoder (local)
│   └── vllm.rs     # vLLM HTTP backend
├── cache.rs        # Versioned cache system (v2)
├── model/          # Neural network models
│   └── big_coder.rs
├── tui/            # Terminal UI
│   ├── input.rs    # Input state machine
│   ├── search.rs   # Search functionality
│   └── view.rs     # Rendering
├── web/            # Web UI
│   ├── handlers.rs    # HTTP request handlers
│   ├── templates.rs   # HTML templates
│   └── code_renderer.rs  # Syntax-highlighted heatmap rendering
├── git/            # Git integration
│   ├── scanner.rs  # Working/staged/branch change detection
│   └── diff.rs     # Unified diff parsing
├── output/         # Output formatters
│   ├── quickfix.rs
│   └── json.rs
└── main.rs         # CLI entry point
Chunking for Large Files
For files exceeding the model's context window, Ouakha:
- Splits code at semantic boundaries (function definitions, empty lines)
- Creates overlapping chunks for continuity
- Merges results by averaging probabilities in overlapping regions
- Returns character-level probabilities (token proposals are not available in chunked mode)
License
MIT
Similar repos
Contributors
32 commits
Languages
Rust
96.9%
Lua
3.1%