
A Large-scale Wu Dialect Speech Corpus with Multi-dimensional Annotations
Python
184
87 commits
updated Feb 6, 2026
README
📢:Good news! 21,800 hours of multi-label Cantonese speech data are also available at ⭐WenetSpeech-Yue⭐.
📢:Good news! 10,000 hours of multi-label Chuan-Yu speech data are also available at ⭐WenetSpeech-Chuan⭐.
WenetSpeech-Wu: Datasets, Benchmarks, and Models for a Unified Chinese Wu Dialect Speech Processing Ecosystem
Chengyou Wang1*, Mingchen Shao1*, Jingbin Hu1*, Zeyu Zhu1*, Hongfei Xue1, Bingshen Mu1, Xin Xu2, Xingyi Duan6, Binbin Zhang3, Pengcheng Zhu3, Chuang Ding4, Xiaojun Zhang5, Hui Bu2, Lei Xie1†
1 Audio, Speech and Language Processing Group (ASLP@NPU), Northwestern Polytechnical University
2 Beijing AISHELL Technology Co., Ltd.
3 WeNet Open Source Community
4 Moonstep AI
5 Xi'an Jiaotong-Liverpool University
6 YK Pao School
📑 Paper |
🐙 GitHub |
🤗 HuggingFace
🎤 Demo Page |
💬 Contact Us
This repository contains the official WenetSpeech-Wu dataset, the WenetSpeech-Wu benchmark, and related models.
Demo Video
Download
- The WenetSpeech-Wu dataset are available at WenetSpeech-Wu.
- The WenetSpeech-Wu benchmark are available at WenetSpeech-Wu-Bench.
- The ASR and understanding models are available at WSWu-Understanding.
- The TTS and instruct TTS models are available at WSWu-Generation.
Dataset
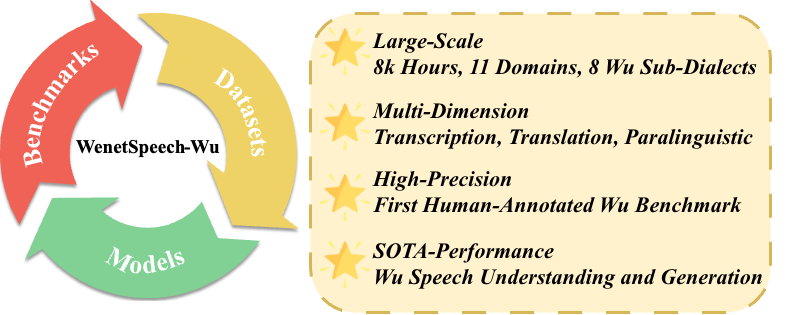
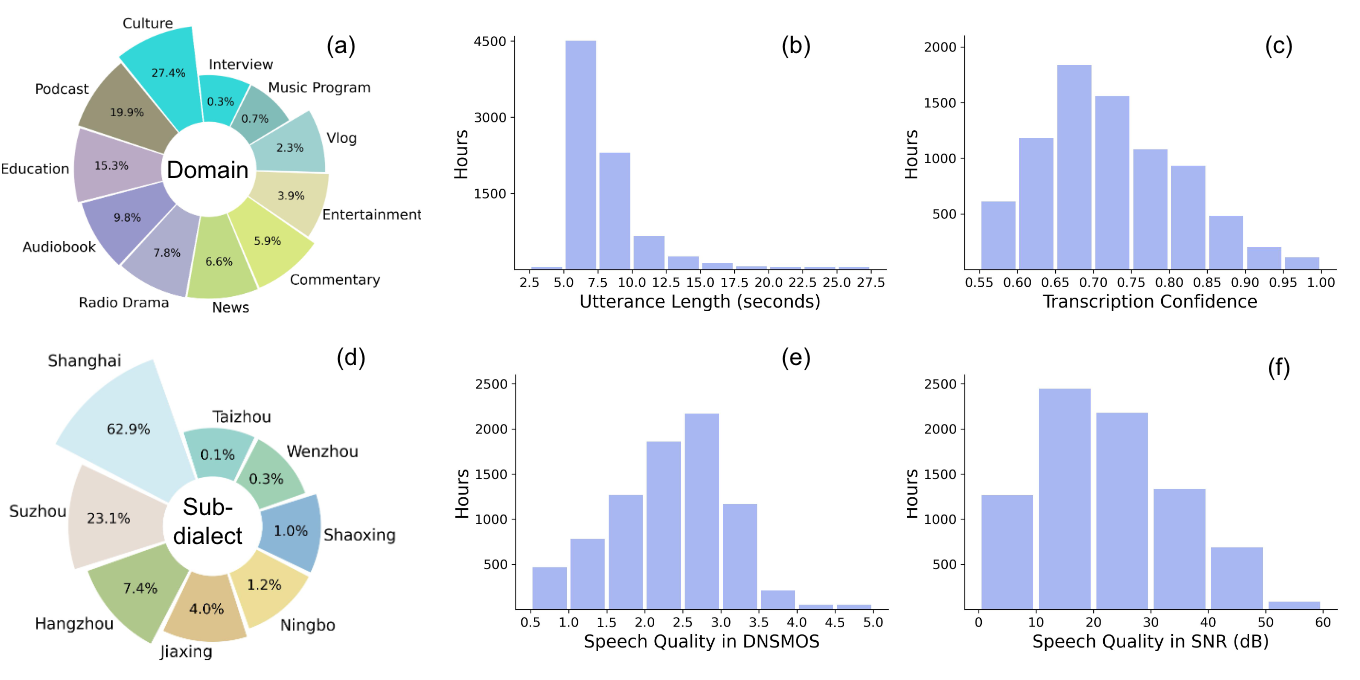
WenetSpeech-Wu is the first large-scale Wu dialect speech corpus with multi-dimensional annotations. It contains rich metadata and annotations, including transcriptions with confidence scores, Wu-to-Mandarin translations, domain and sub-dialect labels, speaker attributes, emotion annotations, and audio quality measures. The dataset comprises approximately 8,000 hours of speech collected from diverse domains and covers eight Wu sub-dialects. To support a wide range of speech processing tasks with heterogeneous quality requirements, we further adopt a task-specific data quality grading strategy.
WenetSpeech-Wu-Bench
We introduce WenetSpeech-Wu-Bench, the first publicly available, manually curated benchmark for Wu dialect speech processing, covering ASR, Wu-to-Mandarin AST, speaker attributes, emotion recognition, TTS, and instruct TTS, and providing a unified platform for fair evaluation.
- ASR: Wu dialect ASR (9.75 hour, including Shanghainese, Suzhounese, and Mandarin code-mixed speech). Evaluated by CER.
- Wu→Mandarin AST: Speech translation from Wu dialects to Mandarin (3k utterances, 4.4h). Evaluated by BLEU.
- Speaker Attributes & Emotion: Speaker gender/age prediction and emotion recognition on Wu dialect. Evaluated by classification accuracy.
- TTS: Wu dialect TTS with speaker prompting (242 sentences, 12 speakers). Evaluated by speaker similarity, CER, and MOS.
- Instruct TTS: Instruction-following TTS with prosodic and emotional control. Evaluated by automatic accuracy and subjective MOS.
Data Construction Pipeline for WenetSpeech-Wu
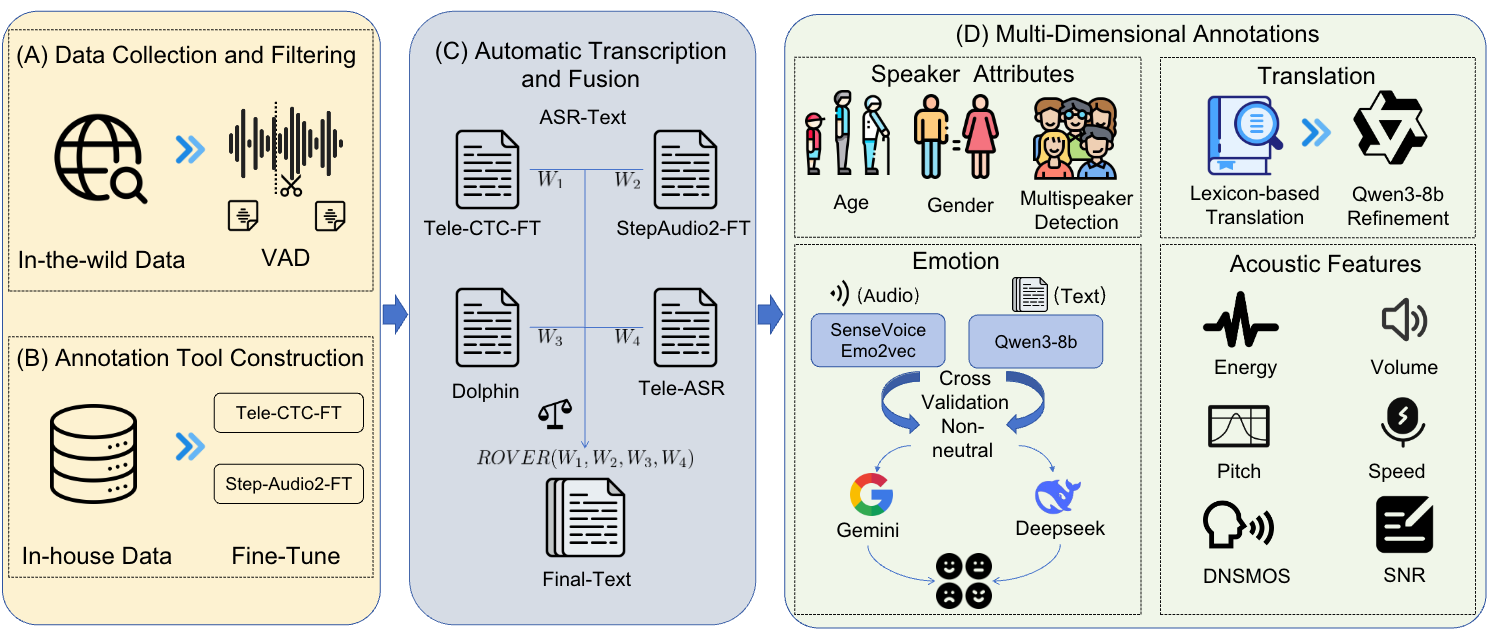
We propose an automatic and scalable pipeline for constructing a large-scale Wu dialect speech dataset with multi-dimensional annotations, as illustrated in the figure below. The pipeline is designed to enable efficient data collection, robust automatic transcription, and diverse downstream annotations.
ASR & Understanding Leaderboard
Bold and underlined values denote the best and second-best results.
ASR results (CER%) on various test sets
| Model | In-House | WS-Wu-Bench | |
|---|---|---|---|
| Dialogue | Reading | ASR | |
| ASR Models | |||
| Paraformer | 63.13 | 66.85 | 64.92 |
| SenseVoice-small | 29.20 | 31.00 | 46.85 |
| Whisper-medium | 79.31 | 83.94 | 78.24 |
| FireRedASR-AED-L | 51.34 | 59.92 | 56.69 |
| Step-Audio2-mini | 24.27 | 24.01 | 26.72 |
| Qwen3-ASR | 23.96 | 24.13 | 29.31 |
| Tencent-Cloud-ASR | 23.25 | 25.26 | 29.48 |
| Gemini-2.5-pro | 85.50 | 84.67 | 89.99 |
| Conformer-U2pp-Wu ⭐ | 15.20 | 12.24 | 15.14 |
| Whisper-medium-Wu ⭐ | 14.19 | 11.09 | 14.33 |
| Step-Audio2-Wu-ASR ⭐ | 8.68 | 7.86 | 12.85 |
| Annotation Models | |||
| Dolphin-small | 24.78 | 27.29 | 26.93 |
| TeleASR | 29.07 | 21.18 | 30.81 |
| Step-Audio2-FT | 8.02 | 6.14 | 15.64 |
| Tele-CTC-FT | 11.90 | 7.23 | 23.85 |
Speech understanding performance on WenetSpeech-Wu-Bench
| Model | ASR | AST | Gender | Age | Emotion |
|---|---|---|---|---|---|
| Qwen3-Omni | 44.27 | 33.31 | 0.977 | 0.541 | 0.667 |
| Step-Audio2-mini | 26.72 | 37.81 | 0.855 | 0.370 | 0.460 |
| Step-Audio2-Wu-Und⭐ | 13.23 | 53.13 | 0.956 | 0.729 | 0.712 |
TTS and Instruct TTS Leaderboard
Bold and underlined values denote the best and second-best results.
TTS results on WenetSpeech-Wu-Bench.
| Model | CER (%)↓ | SIM ↑ | IMOS ↑ | SMOS ↑ | AMOS ↑ | CER (%)↓ | SIM ↑ | IMOS ↑ | SMOS ↑ | AMOS ↑ |
|---|---|---|---|---|---|---|---|---|---|---|
| Qwen3-TTS† | 5.95 | -- | 4.35 | -- | 4.19 | 16.45 | -- | 4.03 | -- | 3.91 |
| DiaMoE-TTS | 57.05 | 0.702 | 3.11 | 3.43 | 3.52 | 82.52 | 0.587 | 2.83 | 3.14 | 3.22 |
| CosyVoice2 | 10.33 | 0.713 | 3.83 | 3.71 | 3.84 | 82.49 | 0.618 | 3.24 | 3.42 | 3.37 |
| CosyVoice2-Wu-CPT⭐ | 6.35 | 0.727 | 4.01 | 3.84 | 3.92 | 32.97 | 0.620 | 3.72 | 3.55 | 3.63 |
| CosyVoice2-Wu-SFT⭐ | 6.19 | 0.726 | 4.32 | 3.78 | 4.11 | 25.00 | 0.601 | 3.96 | 3.48 | 3.76 |
| CosyVoice2-Wu-SS⭐ | 5.42 | -- | 4.37 | -- | 4.21 | 15.45 | -- | 4.04 | -- | 3.88 |
Performance of instruct TTS model.
| Type | Metric | CosyVoice2-Wu-SFT⭐ | CosyVoice2-Wu-instruct⭐ |
|---|---|---|---|
| Emotion | Happy ↑ | 0.87 | 0.94 |
| Angry ↑ | 0.83 | 0.87 | |
| Sad ↑ | 0.84 | 0.88 | |
| Surprised ↑ | 0.67 | 0.73 | |
| EMOS ↑ | 3.66 | 3.83 | |
| Prosody | Pitch ↑ | 0.24 | 0.74 |
| Speech Rate ↑ | 0.26 | 0.82 | |
| PMOS ↑ | 2.13 | 3.68 |
ASR & Speech Understanding Inference
This section describes the inference procedures for different speech models used in our experiments, including Conformer-U2pp-Wu, Whisper-Medium-Wu, Step-Audio2-Wu-ASR and Step-Audio2-Wu-Und. Different models are trained and inferred under different frameworks, with corresponding data formats.
For more details, please refer to Understanding
Conformer-U2pp-Wu
dir=exp
data_type=raw
decode_checkpoint=$dir/u2++.pt
decode_modes="attention attention_rescoring ctc_prefix_beam_search ctc_greedy_search"
decode_batch=4
test_result_dir=./results
ctc_weight=0.0
reverse_weight=0.0
decoding_chunk_size=-1

python wenet/bin/recognize.py --gpu 0 \
  --modes ${decode_modes} \
  --config $dir/train.yaml \
  --data_type $data_type \
  --test_data $test_dir/$test_set/data.jsonl \
  --checkpoint $decode_checkpoint \
  --beam_size 10 \
  --batch_size ${decode_batch} \
  --blank_penalty 0.0 \
  --ctc_weight $ctc_weight \
  --reverse_weight $reverse_weight \
  --result_dir $test_result_dir \
  ${decoding_chunk_size:+--decoding_chunk_size $decoding_chunk_size}
This setup supports multiple decoding strategies, including attention-based and CTC-based decoding.
Whisper-Medium-Wu
dir=exp
data_type=raw
decode_checkpoint=$dir/whisper.pt
decode_modes="attention attention_rescoring ctc_prefix_beam_search ctc_greedy_search"
decode_batch=4
test_result_dir=./results
ctc_weight=0.0
reverse_weight=0.0
decoding_chunk_size=-1

python wenet/bin/recognize.py --gpu 0 \
  --modes ${decode_modes} \
  --config $dir/train.yaml \
  --data_type $data_type \
  --test_data $test_dir/$test_set/data.jsonl \
  --checkpoint $decode_checkpoint \
  --beam_size 10 \
  --batch_size ${decode_batch} \
  --blank_penalty 0.0 \
  --ctc_weight $ctc_weight \
  --reverse_weight $reverse_weight \
  --result_dir $test_result_dir \
  ${decoding_chunk_size:+--decoding_chunk_size $decoding_chunk_size}
Step-Audio2-Wu-ASR & Step-Audio2-Wu-Und
Please download the origin model:Step-Audio 2 mini
model_dir=Step-Audio-2-mini
adapter_dir=./checkpoints

CUDA_VISIBLE_DEVICES=0 \
swift infer \
  --model $model_dir \
  --adapters $adapter_dir \
  --val_dataset data.jsonl \
  --max_new_tokens 512 \
  --torch_dtype bfloat16 \
  --result_path results.jsonl
TTS Inference
Install
Clone and install
- Clone the repo
git clone https://github.com/ASLP-lab/WenetSpeech-Wu-Repo.git
cd WenetSpeech-Wu-Repo/Generation
- Create Conda env:
conda create -n cosyvoice python=3.10
conda activate cosyvoice
pip install -r requirements.txt -i https://mirrors.aliyun.com/pypi/simple/ --trusted-host=mirrors.aliyun.com
Model download
from huggingface_hub import snapshot_download
snapshot_download('ASLP-lab/WenetSpeech-Wu-Speech-Generation', local_dir='pretrained_models')
Usage
CosyVoice2-Wu-SFT
Prepare Model
ln -s ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2/* ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT/
mv ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT/SFT.pt ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT/llm.pt
Inference
import sys
sys.path.append('third_party/Matcha-TTS')
from cosyvoice.cli.cosyvoice import CosyVoice, CosyVoice2
from cosyvoice.utils.file_utils import load_wav
import torchaudio

cosyvoice_base = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)

cosyvoice_sft = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)


prompt_speech_16k = load_wav('figs/A0002_S0003_0_G0003_G0004_33.wav', 16000)
prompt_text = "最少辰光阿拉是做撒呃喃,有钞票就是到银行里保本保息。"
text = "<|wuyu|>"+"阿拉屋里向养了一只小猫,伊老欢喜晒太阳的,每日下半天总归蹲辣窗口。"

for i, j in enumerate(cosyvoice_base.inference_instruct2(text, '用上海话说这句话', prompt_speech_16k, stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)

for i, j in enumerate(cosyvoice_sft.inference_zero_shot(text, prompt_text, prompt_speech_16k , stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)
CosyVoice2-Wu-instruct
Prepare Model
ln -s ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2/* ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion/
mv ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion/instruct_Emo.pt ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion/llm.pt


ln -s ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2/* ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody/
mv ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody/instruct_Pro.pt ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody/llm.pt
Inference
import sys
sys.path.append('third_party/Matcha-TTS')
from cosyvoice.cli.cosyvoice import CosyVoice, CosyVoice2
from cosyvoice.utils.file_utils import load_wav
import torchaudio

cosyvoice_emo = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)

cosyvoice_pro = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)


prompt_speech_16k = load_wav('figs/A0002_S0003_0_G0003_G0004_33.wav', 16000)
prompt_text = "最少辰光阿拉是做撒呃喃,有钞票就是到银行里保本保息。"
text = "阿拉屋里向养了一只小猫,伊老欢喜晒太阳的,每日下半天总归蹲辣窗口。"

emo_text = "<|开心|><|wuyu|>"+text
for i, j in enumerate(cosyvoice_emo.inference_instruct2(emo_text, '用开心的情感说', prompt_speech_16k, stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)

pro_text = "<|男性|><|语速快|><|基频高|><|wuyu|>"+text
for i, j in enumerate(cosyvoice_pro.inference_instruct2(pro_text, '这是一位男性,音调很高语速很快地说',prompt_speech_16k, stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)
Contributors
 |  |  |  |  |
|---|
Citation
Please cite our paper if you find this work useful:
@misc{wang2026wenetspeechwudatasetsbenchmarksmodels,
      title={WenetSpeech-Wu: Datasets, Benchmarks, and Models for a Unified Chinese Wu Dialect Speech Processing Ecosystem},
      author={Chengyou Wang and Mingchen Shao and Jingbin Hu and Zeyu Zhu and Hongfei Xue and Bingshen Mu and Xin Xu and Xingyi Duan and Binbin Zhang and Pengcheng Zhu and Chuang Ding and Xiaojun Zhang and Hui Bu and Lei Xie},
      year={2026},
      eprint={2601.11027},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2601.11027},
}
Contact
If you are interested in leaving a message to our research team, feel free to email asd6404112a@mail.nwpu.edu.cn or mcshao@mail.nwpu.edu.cn .
You’re welcome to join our WeChat group for technical discussions, updates.
Contributors


Similar repos


Languages
Python
85.9%
Shell
13.2%
A Large-scale Wu Dialect Speech Corpus with Multi-dimensional Annotations
Python
184
87 commits
updated Feb 6, 2026
README
📢:Good news! 21,800 hours of multi-label Cantonese speech data are also available at ⭐WenetSpeech-Yue⭐.
📢:Good news! 10,000 hours of multi-label Chuan-Yu speech data are also available at ⭐WenetSpeech-Chuan⭐.
WenetSpeech-Wu: Datasets, Benchmarks, and Models for a Unified Chinese Wu Dialect Speech Processing Ecosystem
Chengyou Wang1*, Mingchen Shao1*, Jingbin Hu1*, Zeyu Zhu1*, Hongfei Xue1, Bingshen Mu1, Xin Xu2, Xingyi Duan6, Binbin Zhang3, Pengcheng Zhu3, Chuang Ding4, Xiaojun Zhang5, Hui Bu2, Lei Xie1†
1 Audio, Speech and Language Processing Group (ASLP@NPU), Northwestern Polytechnical University
2 Beijing AISHELL Technology Co., Ltd.
3 WeNet Open Source Community
4 Moonstep AI
5 Xi'an Jiaotong-Liverpool University
6 YK Pao School
📑 Paper |
🐙 GitHub |
🤗 HuggingFace
🎤 Demo Page |
💬 Contact Us
This repository contains the official WenetSpeech-Wu dataset, the WenetSpeech-Wu benchmark, and related models.
Demo Video
Download
- The WenetSpeech-Wu dataset are available at WenetSpeech-Wu.
- The WenetSpeech-Wu benchmark are available at WenetSpeech-Wu-Bench.
- The ASR and understanding models are available at WSWu-Understanding.
- The TTS and instruct TTS models are available at WSWu-Generation.
Dataset
WenetSpeech-Wu is the first large-scale Wu dialect speech corpus with multi-dimensional annotations. It contains rich metadata and annotations, including transcriptions with confidence scores, Wu-to-Mandarin translations, domain and sub-dialect labels, speaker attributes, emotion annotations, and audio quality measures. The dataset comprises approximately 8,000 hours of speech collected from diverse domains and covers eight Wu sub-dialects. To support a wide range of speech processing tasks with heterogeneous quality requirements, we further adopt a task-specific data quality grading strategy.
WenetSpeech-Wu-Bench
We introduce WenetSpeech-Wu-Bench, the first publicly available, manually curated benchmark for Wu dialect speech processing, covering ASR, Wu-to-Mandarin AST, speaker attributes, emotion recognition, TTS, and instruct TTS, and providing a unified platform for fair evaluation.
- ASR: Wu dialect ASR (9.75 hour, including Shanghainese, Suzhounese, and Mandarin code-mixed speech). Evaluated by CER.
- Wu→Mandarin AST: Speech translation from Wu dialects to Mandarin (3k utterances, 4.4h). Evaluated by BLEU.
- Speaker Attributes & Emotion: Speaker gender/age prediction and emotion recognition on Wu dialect. Evaluated by classification accuracy.
- TTS: Wu dialect TTS with speaker prompting (242 sentences, 12 speakers). Evaluated by speaker similarity, CER, and MOS.
- Instruct TTS: Instruction-following TTS with prosodic and emotional control. Evaluated by automatic accuracy and subjective MOS.
Data Construction Pipeline for WenetSpeech-Wu
We propose an automatic and scalable pipeline for constructing a large-scale Wu dialect speech dataset with multi-dimensional annotations, as illustrated in the figure below. The pipeline is designed to enable efficient data collection, robust automatic transcription, and diverse downstream annotations.
ASR & Understanding Leaderboard
Bold and underlined values denote the best and second-best results.
ASR results (CER%) on various test sets
| Model | In-House | WS-Wu-Bench | |
|---|---|---|---|
| Dialogue | Reading | ASR | |
| ASR Models | |||
| Paraformer | 63.13 | 66.85 | 64.92 |
| SenseVoice-small | 29.20 | 31.00 | 46.85 |
| Whisper-medium | 79.31 | 83.94 | 78.24 |
| FireRedASR-AED-L | 51.34 | 59.92 | 56.69 |
| Step-Audio2-mini | 24.27 | 24.01 | 26.72 |
| Qwen3-ASR | 23.96 | 24.13 | 29.31 |
| Tencent-Cloud-ASR | 23.25 | 25.26 | 29.48 |
| Gemini-2.5-pro | 85.50 | 84.67 | 89.99 |
| Conformer-U2pp-Wu ⭐ | 15.20 | 12.24 | 15.14 |
| Whisper-medium-Wu ⭐ | 14.19 | 11.09 | 14.33 |
| Step-Audio2-Wu-ASR ⭐ | 8.68 | 7.86 | 12.85 |
| Annotation Models | |||
| Dolphin-small | 24.78 | 27.29 | 26.93 |
| TeleASR | 29.07 | 21.18 | 30.81 |
| Step-Audio2-FT | 8.02 | 6.14 | 15.64 |
| Tele-CTC-FT | 11.90 | 7.23 | 23.85 |
Speech understanding performance on WenetSpeech-Wu-Bench
| Model | ASR | AST | Gender | Age | Emotion |
|---|---|---|---|---|---|
| Qwen3-Omni | 44.27 | 33.31 | 0.977 | 0.541 | 0.667 |
| Step-Audio2-mini | 26.72 | 37.81 | 0.855 | 0.370 | 0.460 |
| Step-Audio2-Wu-Und⭐ | 13.23 | 53.13 | 0.956 | 0.729 | 0.712 |
TTS and Instruct TTS Leaderboard
Bold and underlined values denote the best and second-best results.
TTS results on WenetSpeech-Wu-Bench.
| Model | CER (%)↓ | SIM ↑ | IMOS ↑ | SMOS ↑ | AMOS ↑ | CER (%)↓ | SIM ↑ | IMOS ↑ | SMOS ↑ | AMOS ↑ |
|---|---|---|---|---|---|---|---|---|---|---|
| Qwen3-TTS† | 5.95 | -- | 4.35 | -- | 4.19 | 16.45 | -- | 4.03 | -- | 3.91 |
| DiaMoE-TTS | 57.05 | 0.702 | 3.11 | 3.43 | 3.52 | 82.52 | 0.587 | 2.83 | 3.14 | 3.22 |
| CosyVoice2 | 10.33 | 0.713 | 3.83 | 3.71 | 3.84 | 82.49 | 0.618 | 3.24 | 3.42 | 3.37 |
| CosyVoice2-Wu-CPT⭐ | 6.35 | 0.727 | 4.01 | 3.84 | 3.92 | 32.97 | 0.620 | 3.72 | 3.55 | 3.63 |
| CosyVoice2-Wu-SFT⭐ | 6.19 | 0.726 | 4.32 | 3.78 | 4.11 | 25.00 | 0.601 | 3.96 | 3.48 | 3.76 |
| CosyVoice2-Wu-SS⭐ | 5.42 | -- | 4.37 | -- | 4.21 | 15.45 | -- | 4.04 | -- | 3.88 |
Performance of instruct TTS model.
| Type | Metric | CosyVoice2-Wu-SFT⭐ | CosyVoice2-Wu-instruct⭐ |
|---|---|---|---|
| Emotion | Happy ↑ | 0.87 | 0.94 |
| Angry ↑ | 0.83 | 0.87 | |
| Sad ↑ | 0.84 | 0.88 | |
| Surprised ↑ | 0.67 | 0.73 | |
| EMOS ↑ | 3.66 | 3.83 | |
| Prosody | Pitch ↑ | 0.24 | 0.74 |
| Speech Rate ↑ | 0.26 | 0.82 | |
| PMOS ↑ | 2.13 | 3.68 |
ASR & Speech Understanding Inference
This section describes the inference procedures for different speech models used in our experiments, including Conformer-U2pp-Wu, Whisper-Medium-Wu, Step-Audio2-Wu-ASR and Step-Audio2-Wu-Und. Different models are trained and inferred under different frameworks, with corresponding data formats.
For more details, please refer to Understanding
Conformer-U2pp-Wu
dir=exp
data_type=raw
decode_checkpoint=$dir/u2++.pt
decode_modes="attention attention_rescoring ctc_prefix_beam_search ctc_greedy_search"
decode_batch=4
test_result_dir=./results
ctc_weight=0.0
reverse_weight=0.0
decoding_chunk_size=-1

python wenet/bin/recognize.py --gpu 0 \
  --modes ${decode_modes} \
  --config $dir/train.yaml \
  --data_type $data_type \
  --test_data $test_dir/$test_set/data.jsonl \
  --checkpoint $decode_checkpoint \
  --beam_size 10 \
  --batch_size ${decode_batch} \
  --blank_penalty 0.0 \
  --ctc_weight $ctc_weight \
  --reverse_weight $reverse_weight \
  --result_dir $test_result_dir \
  ${decoding_chunk_size:+--decoding_chunk_size $decoding_chunk_size}
This setup supports multiple decoding strategies, including attention-based and CTC-based decoding.
Whisper-Medium-Wu
dir=exp
data_type=raw
decode_checkpoint=$dir/whisper.pt
decode_modes="attention attention_rescoring ctc_prefix_beam_search ctc_greedy_search"
decode_batch=4
test_result_dir=./results
ctc_weight=0.0
reverse_weight=0.0
decoding_chunk_size=-1

python wenet/bin/recognize.py --gpu 0 \
  --modes ${decode_modes} \
  --config $dir/train.yaml \
  --data_type $data_type \
  --test_data $test_dir/$test_set/data.jsonl \
  --checkpoint $decode_checkpoint \
  --beam_size 10 \
  --batch_size ${decode_batch} \
  --blank_penalty 0.0 \
  --ctc_weight $ctc_weight \
  --reverse_weight $reverse_weight \
  --result_dir $test_result_dir \
  ${decoding_chunk_size:+--decoding_chunk_size $decoding_chunk_size}
Step-Audio2-Wu-ASR & Step-Audio2-Wu-Und
Please download the origin model:Step-Audio 2 mini
model_dir=Step-Audio-2-mini
adapter_dir=./checkpoints

CUDA_VISIBLE_DEVICES=0 \
swift infer \
  --model $model_dir \
  --adapters $adapter_dir \
  --val_dataset data.jsonl \
  --max_new_tokens 512 \
  --torch_dtype bfloat16 \
  --result_path results.jsonl
TTS Inference
Install
Clone and install
- Clone the repo
git clone https://github.com/ASLP-lab/WenetSpeech-Wu-Repo.git
cd WenetSpeech-Wu-Repo/Generation
- Create Conda env:
conda create -n cosyvoice python=3.10
conda activate cosyvoice
pip install -r requirements.txt -i https://mirrors.aliyun.com/pypi/simple/ --trusted-host=mirrors.aliyun.com
Model download
from huggingface_hub import snapshot_download
snapshot_download('ASLP-lab/WenetSpeech-Wu-Speech-Generation', local_dir='pretrained_models')
Usage
CosyVoice2-Wu-SFT
Prepare Model
ln -s ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2/* ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT/
mv ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT/SFT.pt ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT/llm.pt
Inference
import sys
sys.path.append('third_party/Matcha-TTS')
from cosyvoice.cli.cosyvoice import CosyVoice, CosyVoice2
from cosyvoice.utils.file_utils import load_wav
import torchaudio

cosyvoice_base = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)

cosyvoice_sft = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-SFT',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)


prompt_speech_16k = load_wav('figs/A0002_S0003_0_G0003_G0004_33.wav', 16000)
prompt_text = "最少辰光阿拉是做撒呃喃,有钞票就是到银行里保本保息。"
text = "<|wuyu|>"+"阿拉屋里向养了一只小猫,伊老欢喜晒太阳的,每日下半天总归蹲辣窗口。"

for i, j in enumerate(cosyvoice_base.inference_instruct2(text, '用上海话说这句话', prompt_speech_16k, stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)

for i, j in enumerate(cosyvoice_sft.inference_zero_shot(text, prompt_text, prompt_speech_16k , stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)
CosyVoice2-Wu-instruct
Prepare Model
ln -s ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2/* ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion/
mv ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion/instruct_Emo.pt ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion/llm.pt


ln -s ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2/* ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody/
mv ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody/instruct_Pro.pt ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody/llm.pt
Inference
import sys
sys.path.append('third_party/Matcha-TTS')
from cosyvoice.cli.cosyvoice import CosyVoice, CosyVoice2
from cosyvoice.utils.file_utils import load_wav
import torchaudio

cosyvoice_emo = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-emotion',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)

cosyvoice_pro = CosyVoice2(
    'ASLP-lab/WenetSpeech-Wu-Speech-Generation/CosyVoice2-Wu-instruct-prosody',
    load_jit=False, load_trt=False, load_vllm=False, fp16=False
)


prompt_speech_16k = load_wav('figs/A0002_S0003_0_G0003_G0004_33.wav', 16000)
prompt_text = "最少辰光阿拉是做撒呃喃,有钞票就是到银行里保本保息。"
text = "阿拉屋里向养了一只小猫,伊老欢喜晒太阳的,每日下半天总归蹲辣窗口。"

emo_text = "<|开心|><|wuyu|>"+text
for i, j in enumerate(cosyvoice_emo.inference_instruct2(emo_text, '用开心的情感说', prompt_speech_16k, stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)

pro_text = "<|男性|><|语速快|><|基频高|><|wuyu|>"+text
for i, j in enumerate(cosyvoice_pro.inference_instruct2(pro_text, '这是一位男性,音调很高语速很快地说',prompt_speech_16k, stream=False)):
    torchaudio.save('A0002_S0003_0_G0003_G0004_33_{}.wav'.format(i), j['tts_speech'], cosyvoice.sample_rate)
Contributors
| | | | |
|---|
Citation
Please cite our paper if you find this work useful:
@misc{wang2026wenetspeechwudatasetsbenchmarksmodels,
      title={WenetSpeech-Wu: Datasets, Benchmarks, and Models for a Unified Chinese Wu Dialect Speech Processing Ecosystem},
      author={Chengyou Wang and Mingchen Shao and Jingbin Hu and Zeyu Zhu and Hongfei Xue and Bingshen Mu and Xin Xu and Xingyi Duan and Binbin Zhang and Pengcheng Zhu and Chuang Ding and Xiaojun Zhang and Hui Bu and Lei Xie},
      year={2026},
      eprint={2601.11027},
      archivePrefix={arXiv},
      primaryClass={cs.SD},
      url={https://arxiv.org/abs/2601.11027},
}
Contact
If you are interested in leaving a message to our research team, feel free to email asd6404112a@mail.nwpu.edu.cn or mcshao@mail.nwpu.edu.cn .
You’re welcome to join our WeChat group for technical discussions, updates.
Similar repos
Contributors
Languages
Python
85.9%
Shell
13.2%