
BioMedArena: a state-of-the-art biomedical harness for evaluating AI agents at scale - 100+ benchmarks, 70+ tools
Python
26
14 commits
updated Jun 25, 2026
README
BioMedArena
BioMedArena: An Open-source Toolkit for Building and Evaluating Biomedical Deep Research Agents
If you find BioMedArena useful, please give us a star on GitHub for the latest updates.

Reproducing and comparing deep research agents today is hard: the same backbone evaluated on the same benchmark can report different accuracies across papers because the harness and tool registry differ, and integrating a new model into a comparable evaluation surface costs weeks of model-specific engineering. These are symptoms of a broader reproducibility problem in deep research agent research. We release BioMedArena, an open-source toolkit that addresses this reproducibility gap and provides an arena for comparing biomedical deep research agents under a shared evaluation environment.
BioMedArena decouples six layers of biomedical agent evaluation: benchmark loading, tool exposure, tool selection, harness mode, context management, and scoring. The current public code exposes 166 registered benchmark entries (155 canonical benchmarks plus 11 deprecated compatibility aliases), 76 tools across 9 biomedical functional families, 4 modes, and 9 registered model backbone IDs. Adding a new model, benchmark, or tool reduces to registering a small provider adapter, loader, or schema/handler pair.
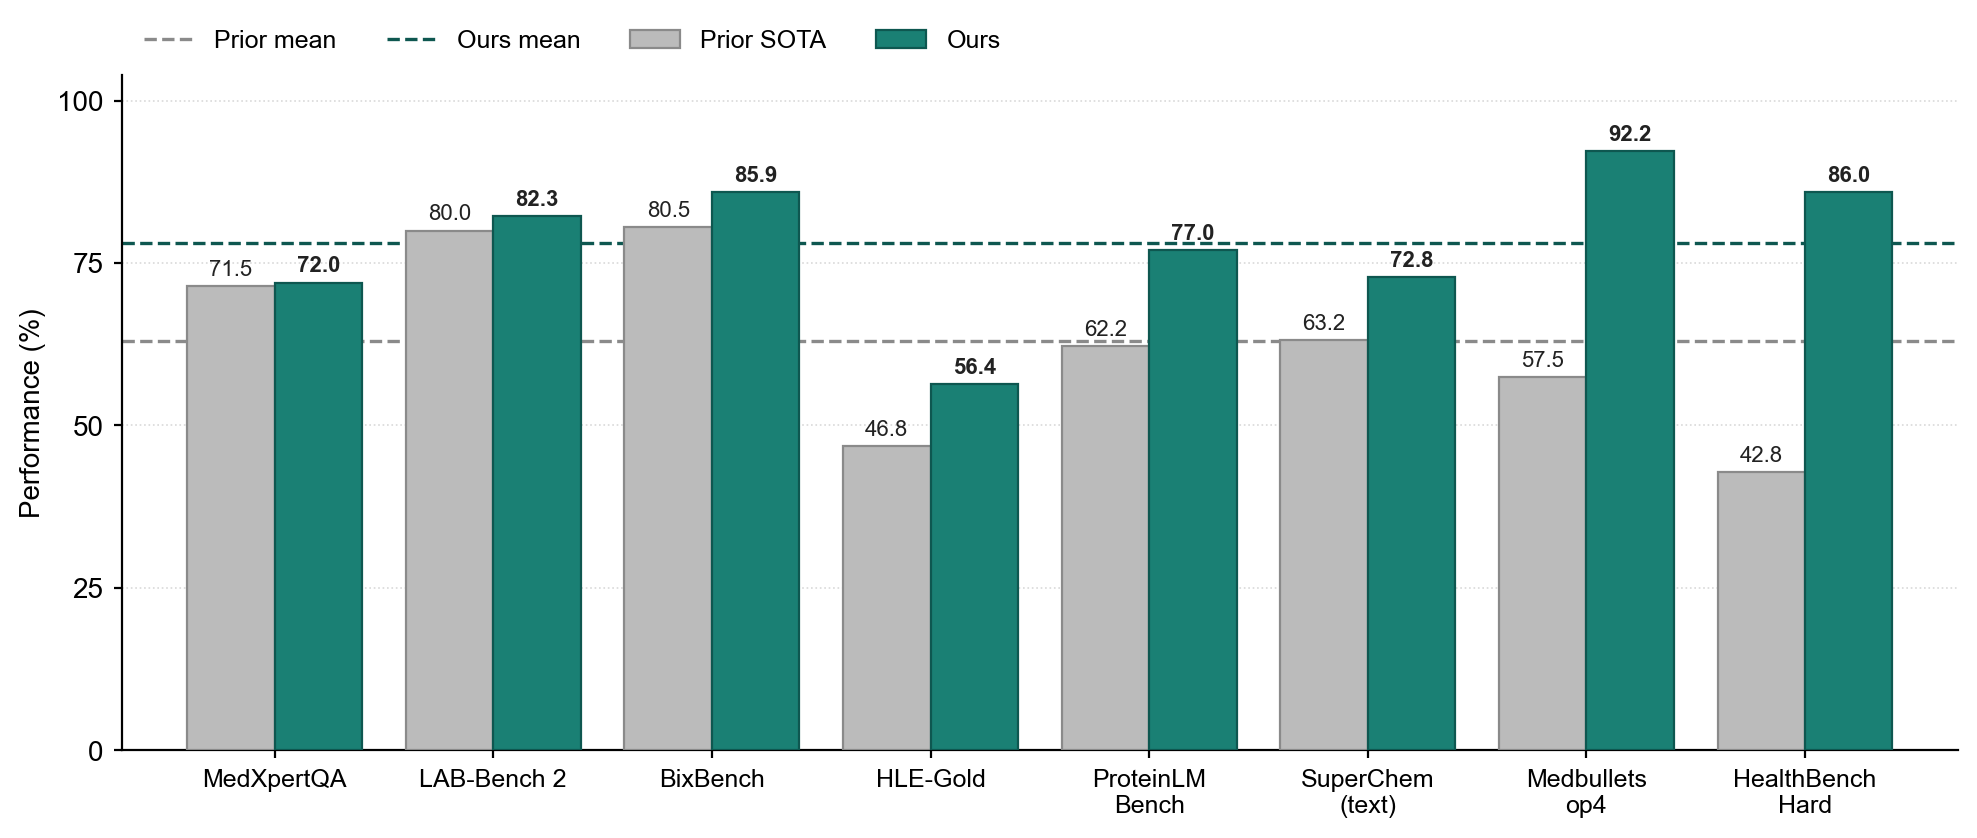
Overall Performance
Scroll horizontally to view all benchmark columns.
| Type | Model | Setting | HealthBench Hard (1000) | MedXpertQA (2450) | ProteinLMBench (944) | Medbullets (308) | SuperChem (500) | BixBench (205) | HLE-Gold (149) | LAB-Bench 2 (821) | ||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Text | Image | Total | Bio | Chem | Total | |||||||||
| SOTA | - | 42.8 | 71.5 | 62.2 | 57.5 | 63.2 | - | 38.5 | 80.5 | 44.2 | 53.2 | 46.8 | 80.0 | |
| Public LLMs | Trinity-Large-Thinking | Baseline | 41.9 | 33.3 | 39.0 | 77.3 | 23.8 | - | - | 5.4 | 15.0 | 7.1 | 12.8 | 43.5 |
| Trinity-Large-Thinking | Ours | 47.7 | 44.2 | 69.5 | 82.1 | 30.6 | - | - | 26.3 | 19.6 | 19.0 | 19.5 | 61.0 | |
| NVIDIA Nemotron-3 Super 120B | Baseline | 58.7 | 37.8 | 50.5 | 79.2 | 32.5 | - | - | 13.2 | 13.1 | 4.8 | 10.7 | 43.6 | |
| NVIDIA Nemotron-3 Super 120B | Ours | 65.4 | 45.9 | 63.1 | 82.5 | 39.6 | - | - | 10.7 | 28.0 | 33.3 | 29.5 | 62.6 | |
| INTELLECT-3.1 | Baseline | 41.1 | 36.2 | 43.5 | 72.7 | 27.9 | - | - | 5.4 | 20.6 | 9.5 | 17.4 | 43.5 | |
| INTELLECT-3.1 | Ours | 48.2 | 37.5 | 65.6 | 75.0 | 29.4 | - | - | 20.0 | 26.2 | 19.0 | 24.2 | 57.9 | |
| GLM-4.5 | Baseline | 42.0 | 35.3 | 59.2 | 79.2 | 21.1 | - | - | 23.9 | 16.8 | 2.4 | 12.8 | 44.8 | |
| GLM-4.5 | Ours | 45.3 | 36.5 | 63.1 | 81.2 | 28.3 | - | - | 30.2 | 28.0 | 28.6 | 28.2 | 61.5 | |
| Qwen3-235B-A22B | Baseline | 27.9 | 40.5 | 54.0 | 79.5 | 23.4 | - | - | 22.4 | 15.0 | 14.3 | 14.8 | 42.5 | |
| Qwen3-235B-A22B | Ours | 32.4 | 40.8 | 62.2 | 83.1 | 37.7 | - | - | 35.1 | 28.0 | 14.3 | 24.2 | 57.9 | |
| Commercial LLMs | GPT-5.4 | Baseline | 61.3 | 44.7 | 67.6 | 84.8 | 57.7 | 22.6 | 41.2 | 40.0 | 43.0 | 33.3 | 40.3 | 48.5 |
| GPT-5.4 | Ours | 77.2 | 57.3 | 70.0 | 91.8 | 66.8 | 58.3 | 62.8 | 49.8 | 48.6 | 54.8 | 50.3 | 72.1 | |
| Gemini 3 Flash | Baseline | 59.7 | 52.9 | 65.7 | 64.9 | 49.1 | 10.2 | 30.8 | 38.5 | 39.3 | 28.6 | 36.2 | 51.9 | |
| Gemini 3 Flash | Ours | 80.7 | 63.6 | 72.1 | 85.4 | 54.0 | 34.5 | 44.8 | 69.3 | 51.4 | 47.6 | 50.3 | 59.8 | |
| Gemini 3.1 Pro | Baseline | 72.0 | 58.9 | 70.3 | 70.1 | 54.3 | 19.2 | 37.8 | 42.4 | 41.1 | 47.6 | 43.0 | 52.1 | |
| Gemini 3.1 Pro | Ours | 80.8 | 72.0 | 77.0 | 91.6 | 57.4 | 62.6 | 59.8 | 85.9 | 49.5 | 50.0 | 49.7 | 70.9 | |
| Claude Sonnet 4.5 | Baseline | 67.9 | 45.9 | 58.7 | 88.3 | 29.1 | 17.4 | 23.6 | 17.1 | 22.4 | 16.7 | 20.8 | 48.1 | |
| Claude Sonnet 4.5 | Ours | 75.3 | 60.1 | 72.8 | 91.2 | 39.6 | 31.9 | 35.4 | 42.4 | 42.1 | 40.5 | 41.6 | 71.5 | |
| Claude Sonnet 4.6 | Baseline | 69.3 | 51.0 | 60.3 | 86.0 | 40.4 | 24.7 | 33.0 | 40.5 | 24.3 | 21.4 | 23.5 | 49.3 | |
| Claude Sonnet 4.6 | Ours | 86.0 | 62.4 | 64.7 | 89.0 | 66.0 | 53.6 | 58.6 | 48.3 | 42.1 | 50.0 | 44.3 | 74.3 | |
| Claude Opus 4.5 | Baseline | 72.5 | 49.4 | 63.8 | 87.3 | 48.3 | 24.3 | 37.0 | 41.0 | 30.8 | 31.0 | 30.9 | 49.8 | |
| Claude Opus 4.5 | Ours | 78.9 | 62.0 | 69.8 | 90.3 | 59.2 | 41.3 | 50.8 | 50.2 | 49.5 | 50.0 | 49.7 | 73.8 | |
| Claude Opus 4.6 | Baseline | 76.2 | 55.8 | 64.4 | 89.9 | 62.3 | 30.2 | 47.2 | 42.0 | 36.4 | 42.9 | 38.3 | 51.2 | |
| Claude Opus 4.6 | Ours | 80.2 | 66.0 | 71.8 | 92.2 | 72.8 | 57.9 | 65.8 | 53.7 | 55.1 | 59.5 | 56.4 | 82.3 | |
Documentation
The root README stays short on purpose. Detailed release information
lives in docs/:
Quick Check
After installing dependencies, run the offline smoke suite:
python3 scripts/run_quick_suite.py
Expected healthy output:
- 166 registered benchmarks
- 76 registered tools
- 4 registered modes
- 20/20 scorer checks passed
For the stricter offline release gate:
python3 scripts/release_gate.py --strict
Prepare the full BixBench agent setting only when you need the official
capsule-backed protocol. This downloads the large CapsuleFolder-{uuid}.zip
files explicitly instead of during normal benchmark loading:
biomedarena prepare-bixbench --revision main --extract
docker build -t biomedarena/bixbench-sandbox:latest docker/bixbench
biomedarena run --benchmark bixbench --bixbench-form open --bixbench-capsules \
  --backbone gemini-3-flash-preview --tools biomed --reasoning-mode heavy
If you are running fully offline from a cache you prepared yourself, add
--bixbench-offline-metadata to the run command. The open-form path is
official-compatible: it uses the public BixBench rows, mounted data capsules,
and eval_mode-specific scoring, while the external FutureHouse evaluator is
not vendored in this repository.
Installation
git clone https://github.com/AI-in-Health/BioMedArena.git
cd BioMedArena

python3.11 -m venv .venv
source .venv/bin/activate

python -m pip install -e ".[dev,eval,provider-gemini]"

cp .env.example .env
Fill at least one model provider key in .env:
OPENAI_API_KEY=<your-openai-api-key>
ANTHROPIC_API_KEY=<your-anthropic-api-key>
GEMINI_API_KEY=<your-gemini-api-key>
HF_TOKEN=<your-huggingface-token-for-gated-benchmarks>
Gated HuggingFace datasets also require accepting the dataset terms in
the browser before HF_TOKEN can load them. See .env.example for
optional domain-specific keys such as NCBI, OMIM, Serper, and Jina.
Basic Usage
List available resources:
biomedarena list-benchmarks
biomedarena list-backbones
biomedarena list-modes
The package name and command-line entry point are both biomedarena.
Environment variables use the BIOMEDARENA_ prefix.
Run one benchmark cell:
biomedarena run \
  --benchmark medcalc \
  --backbone gemini-2.5-flash \
  --tools biomed --reasoning-mode light \
  --limit 5 \
  --output result.json
Run a small matrix cell:
python3 scripts/run_matrix.py \
  --config configs/matrix_default.yaml \
  --only medcalc,gemini,simple_llm \
  --limit-override 1
For the 7-setting quick-start experiment suite used to compare thinking,
domain tools, web search, and combined tool use, see quick_run.sh.
Check official source accessibility before spending model budget:
python3 scripts/verify_benchmark_sources.py --benchmarks all
Execution Modes
The public CLI exposes four modes:
| Mode | Purpose |
|---|---|
simple_llm | Pure model baseline, no tools. |
deep_think | Native model reasoning/thinking path where supported. |
light | Single-turn function/tool calling. |
heavy | Multi-turn ReAct loop with tool retrieval. |
A unified CLI interface is also available via --tools / --reasoning-mode /
--enable-thinking flags, which map to the modes above:
--tools | --reasoning-mode | Internal mode | Thinking |
|---|---|---|---|
off | (n/a) | deep_think | ON (default) |
off + --enable-thinking 0 | (n/a) | simple_llm | OFF |
biomed / search / all | light | light | OFF |
biomed / search / all | heavy | heavy | ON |
The legacy --mode / --web-tools flags remain supported for backward
compatibility. Add --self-consistency to wrap any mode with majority voting.
Security
python_exec can execute model-supplied Python with timeout and basic
denylist checks. Treat this as a convenience guard, not a hardened
sandbox. Run untrusted workloads in an isolated container or VM, keep
secrets out of the working directory, and disable code-execution or
web-search tools for private data unless you have reviewed the policy.
External tools may call third-party APIs and public databases. Review the benchmark and tool inventories before running sensitive workloads.
Testing
python3 scripts/run_quick_suite.py
python3 scripts/release_gate.py --strict
python3 -m pytest tests/unit -q
HF_HOME=/tmp/biomedarena_hf_empty \
HF_DATASETS_CACHE=/tmp/biomedarena_hf_datasets_empty \
HF_TOKEN= HUGGING_FACE_HUB_TOKEN= HUGGINGFACE_HUB_TOKEN= \
python3 -m pytest tests/smoke -q -m "not slow"
Citation
@article{wu2026biomedarena,
  title={BioMedArena: An Open-source Toolkit for Building and Evaluating Biomedical Deep Research Agents},
  author={Wu, J and Zhou, H and Zeng, M and Zhu, J and Wu, J and Pan, J and Noori, A and Wu, S and Wu, H and Liu, F and Clifton, D A},
  journal={arXiv preprint arXiv:2605.06177},
  year={2026}
}
License
See LICENSE. Ported life-science skill attribution is tracked in harness/tools/openai_ported/NOTICE.md.


Similar repos


Languages
Python
99.2%
BioMedArena: a state-of-the-art biomedical harness for evaluating AI agents at scale - 100+ benchmarks, 70+ tools
Python
26
14 commits
updated Jun 25, 2026
README
BioMedArena
BioMedArena: An Open-source Toolkit for Building and Evaluating Biomedical Deep Research Agents
If you find BioMedArena useful, please give us a star on GitHub for the latest updates.
Reproducing and comparing deep research agents today is hard: the same backbone evaluated on the same benchmark can report different accuracies across papers because the harness and tool registry differ, and integrating a new model into a comparable evaluation surface costs weeks of model-specific engineering. These are symptoms of a broader reproducibility problem in deep research agent research. We release BioMedArena, an open-source toolkit that addresses this reproducibility gap and provides an arena for comparing biomedical deep research agents under a shared evaluation environment.
BioMedArena decouples six layers of biomedical agent evaluation: benchmark loading, tool exposure, tool selection, harness mode, context management, and scoring. The current public code exposes 166 registered benchmark entries (155 canonical benchmarks plus 11 deprecated compatibility aliases), 76 tools across 9 biomedical functional families, 4 modes, and 9 registered model backbone IDs. Adding a new model, benchmark, or tool reduces to registering a small provider adapter, loader, or schema/handler pair.
Overall Performance
Scroll horizontally to view all benchmark columns.
| Type | Model | Setting | HealthBench Hard (1000) | MedXpertQA (2450) | ProteinLMBench (944) | Medbullets (308) | SuperChem (500) | BixBench (205) | HLE-Gold (149) | LAB-Bench 2 (821) | ||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Text | Image | Total | Bio | Chem | Total | |||||||||
| SOTA | - | 42.8 | 71.5 | 62.2 | 57.5 | 63.2 | - | 38.5 | 80.5 | 44.2 | 53.2 | 46.8 | 80.0 | |
| Public LLMs | Trinity-Large-Thinking | Baseline | 41.9 | 33.3 | 39.0 | 77.3 | 23.8 | - | - | 5.4 | 15.0 | 7.1 | 12.8 | 43.5 |
| Trinity-Large-Thinking | Ours | 47.7 | 44.2 | 69.5 | 82.1 | 30.6 | - | - | 26.3 | 19.6 | 19.0 | 19.5 | 61.0 | |
| NVIDIA Nemotron-3 Super 120B | Baseline | 58.7 | 37.8 | 50.5 | 79.2 | 32.5 | - | - | 13.2 | 13.1 | 4.8 | 10.7 | 43.6 | |
| NVIDIA Nemotron-3 Super 120B | Ours | 65.4 | 45.9 | 63.1 | 82.5 | 39.6 | - | - | 10.7 | 28.0 | 33.3 | 29.5 | 62.6 | |
| INTELLECT-3.1 | Baseline | 41.1 | 36.2 | 43.5 | 72.7 | 27.9 | - | - | 5.4 | 20.6 | 9.5 | 17.4 | 43.5 | |
| INTELLECT-3.1 | Ours | 48.2 | 37.5 | 65.6 | 75.0 | 29.4 | - | - | 20.0 | 26.2 | 19.0 | 24.2 | 57.9 | |
| GLM-4.5 | Baseline | 42.0 | 35.3 | 59.2 | 79.2 | 21.1 | - | - | 23.9 | 16.8 | 2.4 | 12.8 | 44.8 | |
| GLM-4.5 | Ours | 45.3 | 36.5 | 63.1 | 81.2 | 28.3 | - | - | 30.2 | 28.0 | 28.6 | 28.2 | 61.5 | |
| Qwen3-235B-A22B | Baseline | 27.9 | 40.5 | 54.0 | 79.5 | 23.4 | - | - | 22.4 | 15.0 | 14.3 | 14.8 | 42.5 | |
| Qwen3-235B-A22B | Ours | 32.4 | 40.8 | 62.2 | 83.1 | 37.7 | - | - | 35.1 | 28.0 | 14.3 | 24.2 | 57.9 | |
| Commercial LLMs | GPT-5.4 | Baseline | 61.3 | 44.7 | 67.6 | 84.8 | 57.7 | 22.6 | 41.2 | 40.0 | 43.0 | 33.3 | 40.3 | 48.5 |
| GPT-5.4 | Ours | 77.2 | 57.3 | 70.0 | 91.8 | 66.8 | 58.3 | 62.8 | 49.8 | 48.6 | 54.8 | 50.3 | 72.1 | |
| Gemini 3 Flash | Baseline | 59.7 | 52.9 | 65.7 | 64.9 | 49.1 | 10.2 | 30.8 | 38.5 | 39.3 | 28.6 | 36.2 | 51.9 | |
| Gemini 3 Flash | Ours | 80.7 | 63.6 | 72.1 | 85.4 | 54.0 | 34.5 | 44.8 | 69.3 | 51.4 | 47.6 | 50.3 | 59.8 | |
| Gemini 3.1 Pro | Baseline | 72.0 | 58.9 | 70.3 | 70.1 | 54.3 | 19.2 | 37.8 | 42.4 | 41.1 | 47.6 | 43.0 | 52.1 | |
| Gemini 3.1 Pro | Ours | 80.8 | 72.0 | 77.0 | 91.6 | 57.4 | 62.6 | 59.8 | 85.9 | 49.5 | 50.0 | 49.7 | 70.9 | |
| Claude Sonnet 4.5 | Baseline | 67.9 | 45.9 | 58.7 | 88.3 | 29.1 | 17.4 | 23.6 | 17.1 | 22.4 | 16.7 | 20.8 | 48.1 | |
| Claude Sonnet 4.5 | Ours | 75.3 | 60.1 | 72.8 | 91.2 | 39.6 | 31.9 | 35.4 | 42.4 | 42.1 | 40.5 | 41.6 | 71.5 | |
| Claude Sonnet 4.6 | Baseline | 69.3 | 51.0 | 60.3 | 86.0 | 40.4 | 24.7 | 33.0 | 40.5 | 24.3 | 21.4 | 23.5 | 49.3 | |
| Claude Sonnet 4.6 | Ours | 86.0 | 62.4 | 64.7 | 89.0 | 66.0 | 53.6 | 58.6 | 48.3 | 42.1 | 50.0 | 44.3 | 74.3 | |
| Claude Opus 4.5 | Baseline | 72.5 | 49.4 | 63.8 | 87.3 | 48.3 | 24.3 | 37.0 | 41.0 | 30.8 | 31.0 | 30.9 | 49.8 | |
| Claude Opus 4.5 | Ours | 78.9 | 62.0 | 69.8 | 90.3 | 59.2 | 41.3 | 50.8 | 50.2 | 49.5 | 50.0 | 49.7 | 73.8 | |
| Claude Opus 4.6 | Baseline | 76.2 | 55.8 | 64.4 | 89.9 | 62.3 | 30.2 | 47.2 | 42.0 | 36.4 | 42.9 | 38.3 | 51.2 | |
| Claude Opus 4.6 | Ours | 80.2 | 66.0 | 71.8 | 92.2 | 72.8 | 57.9 | 65.8 | 53.7 | 55.1 | 59.5 | 56.4 | 82.3 | |
Documentation
The root README stays short on purpose. Detailed release information
lives in docs/:
Quick Check
After installing dependencies, run the offline smoke suite:
python3 scripts/run_quick_suite.py
Expected healthy output:
- 166 registered benchmarks
- 76 registered tools
- 4 registered modes
- 20/20 scorer checks passed
For the stricter offline release gate:
python3 scripts/release_gate.py --strict
Prepare the full BixBench agent setting only when you need the official
capsule-backed protocol. This downloads the large CapsuleFolder-{uuid}.zip
files explicitly instead of during normal benchmark loading:
biomedarena prepare-bixbench --revision main --extract
docker build -t biomedarena/bixbench-sandbox:latest docker/bixbench
biomedarena run --benchmark bixbench --bixbench-form open --bixbench-capsules \
  --backbone gemini-3-flash-preview --tools biomed --reasoning-mode heavy
If you are running fully offline from a cache you prepared yourself, add
--bixbench-offline-metadata to the run command. The open-form path is
official-compatible: it uses the public BixBench rows, mounted data capsules,
and eval_mode-specific scoring, while the external FutureHouse evaluator is
not vendored in this repository.
Installation
git clone https://github.com/AI-in-Health/BioMedArena.git
cd BioMedArena

python3.11 -m venv .venv
source .venv/bin/activate

python -m pip install -e ".[dev,eval,provider-gemini]"

cp .env.example .env
Fill at least one model provider key in .env:
OPENAI_API_KEY=<your-openai-api-key>
ANTHROPIC_API_KEY=<your-anthropic-api-key>
GEMINI_API_KEY=<your-gemini-api-key>
HF_TOKEN=<your-huggingface-token-for-gated-benchmarks>
Gated HuggingFace datasets also require accepting the dataset terms in
the browser before HF_TOKEN can load them. See .env.example for
optional domain-specific keys such as NCBI, OMIM, Serper, and Jina.
Basic Usage
List available resources:
biomedarena list-benchmarks
biomedarena list-backbones
biomedarena list-modes
The package name and command-line entry point are both biomedarena.
Environment variables use the BIOMEDARENA_ prefix.
Run one benchmark cell:
biomedarena run \
  --benchmark medcalc \
  --backbone gemini-2.5-flash \
  --tools biomed --reasoning-mode light \
  --limit 5 \
  --output result.json
Run a small matrix cell:
python3 scripts/run_matrix.py \
  --config configs/matrix_default.yaml \
  --only medcalc,gemini,simple_llm \
  --limit-override 1
For the 7-setting quick-start experiment suite used to compare thinking,
domain tools, web search, and combined tool use, see quick_run.sh.
Check official source accessibility before spending model budget:
python3 scripts/verify_benchmark_sources.py --benchmarks all
Execution Modes
The public CLI exposes four modes:
| Mode | Purpose |
|---|---|
simple_llm | Pure model baseline, no tools. |
deep_think | Native model reasoning/thinking path where supported. |
light | Single-turn function/tool calling. |
heavy | Multi-turn ReAct loop with tool retrieval. |
A unified CLI interface is also available via --tools / --reasoning-mode /
--enable-thinking flags, which map to the modes above:
--tools | --reasoning-mode | Internal mode | Thinking |
|---|---|---|---|
off | (n/a) | deep_think | ON (default) |
off + --enable-thinking 0 | (n/a) | simple_llm | OFF |
biomed / search / all | light | light | OFF |
biomed / search / all | heavy | heavy | ON |
The legacy --mode / --web-tools flags remain supported for backward
compatibility. Add --self-consistency to wrap any mode with majority voting.
Security
python_exec can execute model-supplied Python with timeout and basic
denylist checks. Treat this as a convenience guard, not a hardened
sandbox. Run untrusted workloads in an isolated container or VM, keep
secrets out of the working directory, and disable code-execution or
web-search tools for private data unless you have reviewed the policy.
External tools may call third-party APIs and public databases. Review the benchmark and tool inventories before running sensitive workloads.
Testing
python3 scripts/run_quick_suite.py
python3 scripts/release_gate.py --strict
python3 -m pytest tests/unit -q
HF_HOME=/tmp/biomedarena_hf_empty \
HF_DATASETS_CACHE=/tmp/biomedarena_hf_datasets_empty \
HF_TOKEN= HUGGING_FACE_HUB_TOKEN= HUGGINGFACE_HUB_TOKEN= \
python3 -m pytest tests/smoke -q -m "not slow"
Citation
@article{wu2026biomedarena,
  title={BioMedArena: An Open-source Toolkit for Building and Evaluating Biomedical Deep Research Agents},
  author={Wu, J and Zhou, H and Zeng, M and Zhu, J and Wu, J and Pan, J and Noori, A and Wu, S and Wu, H and Liu, F and Clifton, D A},
  journal={arXiv preprint arXiv:2605.06177},
  year={2026}
}
License
See LICENSE. Ported life-science skill attribution is tracked in harness/tools/openai_ported/NOTICE.md.
Similar repos
Languages
Python
99.2%