
README
OIBench
OIBench. is a high-quality, private, and challenging olympiad-level informatics benchmark consisting of 250 carefully curated original problems.
This repository contains the evaluation environment for our OIBench paper. You can access data on HuggingFace.
The scoring system is implemented in scorer.py and can be used to evaluate model performance.
Leaderboard
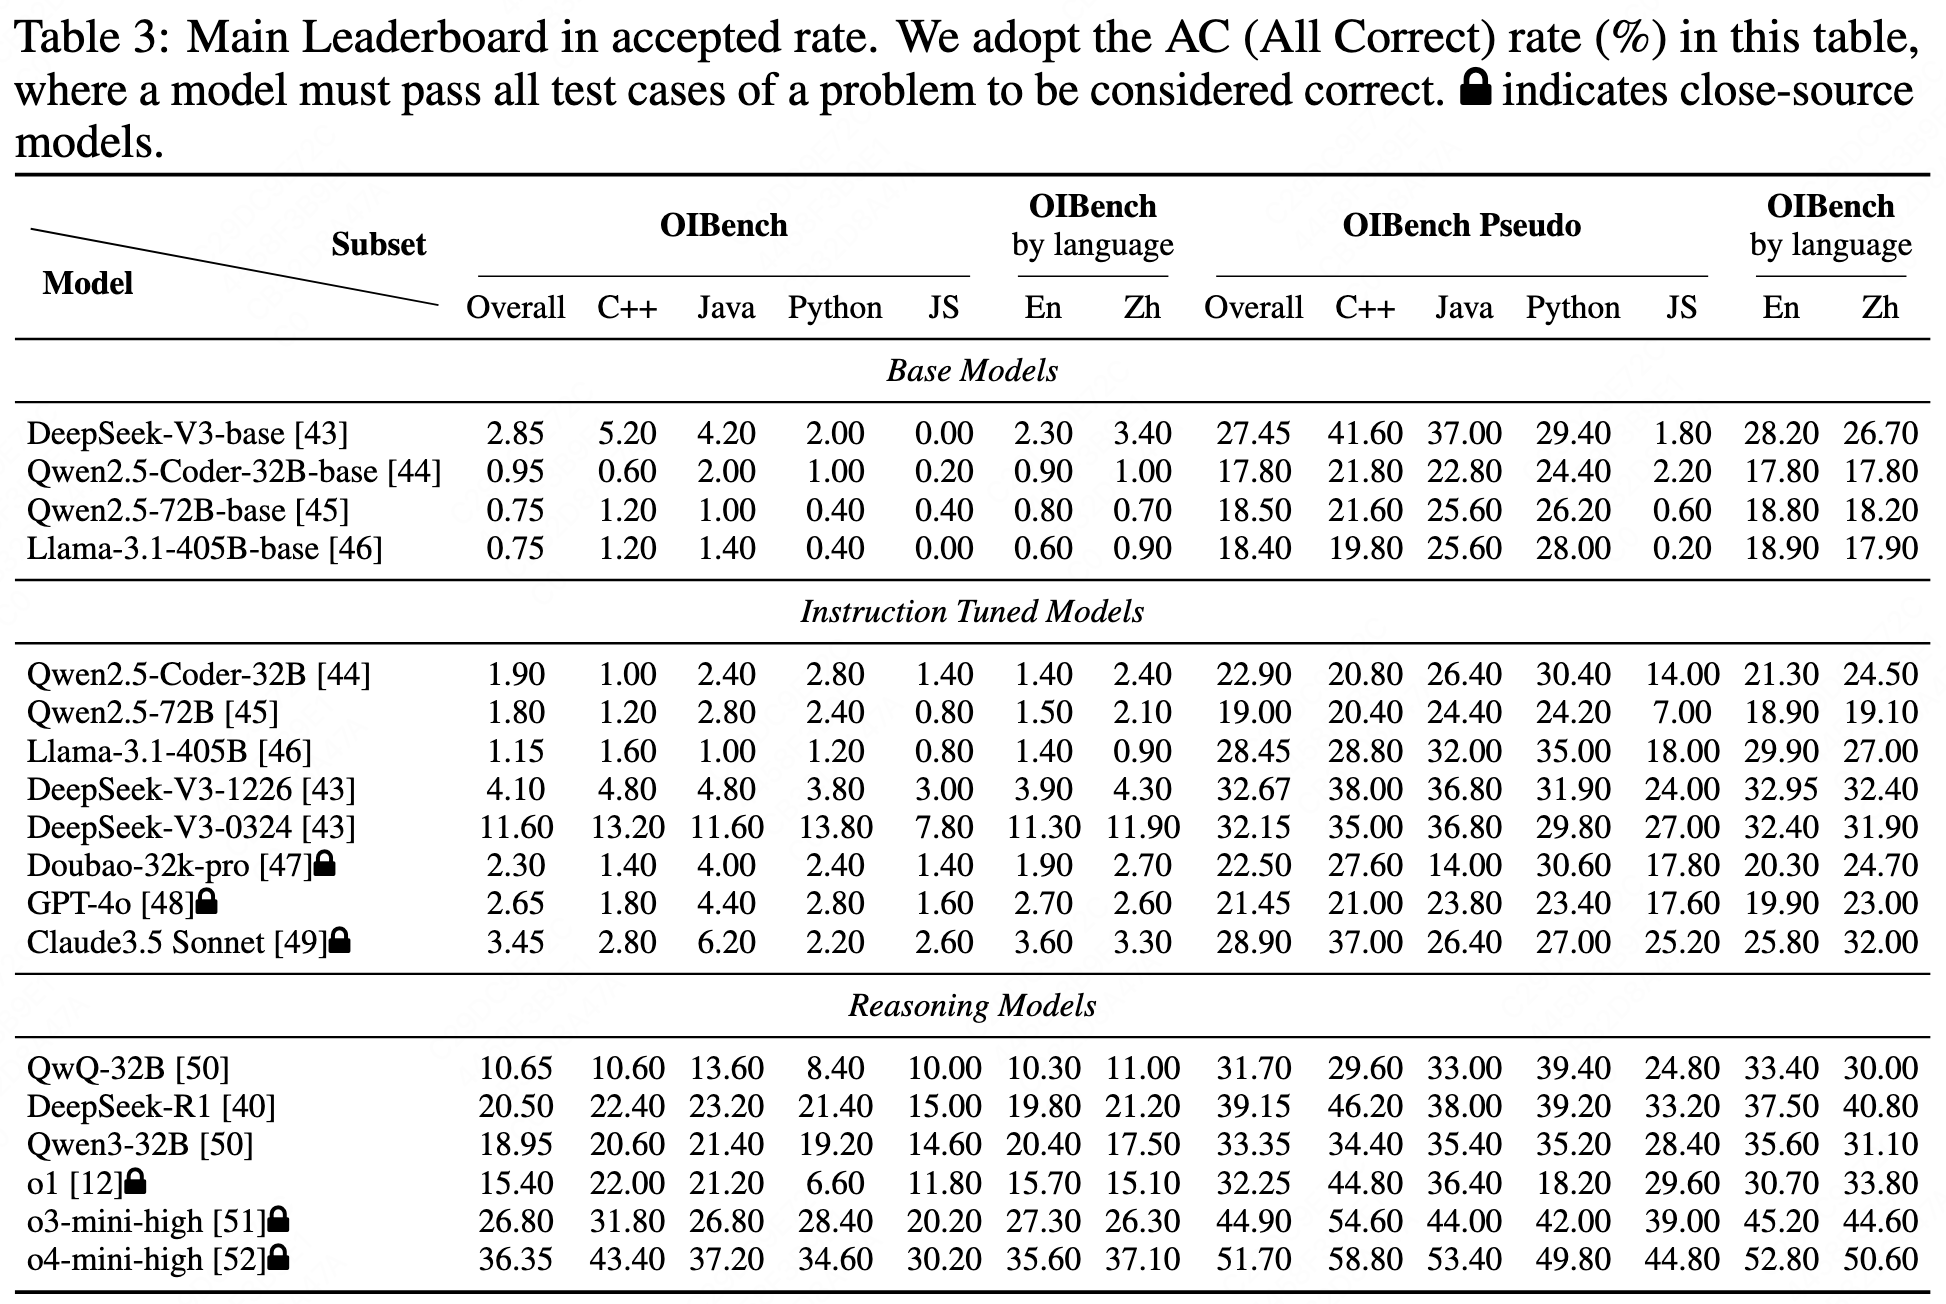
- We will continue to update the evaluation results of new models and host them on the AGI-Eval community.
Prerequisites
Before running the scorer, you need to set up the required language environments. We recommend to run the scorer under Linux-based systems.
For Ubuntu-based Systems:
Install C++
sudo apt update && sudo apt install -y libssl-dev libcrypto++-dev
Install Python
sudo apt update && sudo apt install -y python3 python3-pip
Install Java (OpenJDK 11)
sudo apt update && sudo apt install -y openjdk-11-jdk
Install Node.js
sudo apt update && sudo apt install -y curl
curl -fsSL https://deb.nodesource.com/setup_lts.x | sudo -E bash -
sudo apt install -y nodejs
For CentOS :
Install C++
sudo yum group install -y "Development Tools"
sudo yum install -y openssl-devel
Install Python 3
sudo yum install -y epel-release
sudo yum install -y python3 python3-pip
Install Java (OpenJDK 11)
sudo yum install -y java-11-openjdk-devel
Install Node.js
curl -fsSL https://rpm.nodesource.com/setup_lts.x | sudo bash -
sudo yum install -y nodejs
Setup
Install the required Python packages:
pip install -r requirements.txt
Usage
Run the scorer:
python scorer.py
The evaluation results will be:
- Printed to stdout for model scores
- Saved to
cases.jsonfor detailed case-by-case results
Please note that the provided scorer.py uses the C++ language and problem's canonical_solution as a demonstration. In actual execution, please replace it with your model's response (raw code). We provide a function extractor in the code_utils file for your convenience. In the code comments, we have included an example method for obtaining the model's solution using the OpenAI API.
Citation
@misc{zhu2025oibenchbenchmarkingstrongreasoning,
      title={OIBench: Benchmarking Strong Reasoning Models with Olympiad in Informatics},
      author={Yaoming Zhu and Junxin Wang and Yiyang Li and Lin Qiu and ZongYu Wang and Jun Xu and Xuezhi Cao and Yuhuai Wei and Mingshi Wang and Xunliang Cai and Rong Ma},
      year={2025},
      eprint={2506.10481},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.10481},
}
Acknowledgement
Our scorer logic is adapted from the implementation of OctoPack: Instruction Tuning Code Large Language Models.
Similar repos


Languages
Python
100.0%
README
OIBench
OIBench. is a high-quality, private, and challenging olympiad-level informatics benchmark consisting of 250 carefully curated original problems.
This repository contains the evaluation environment for our OIBench paper. You can access data on HuggingFace.
The scoring system is implemented in scorer.py and can be used to evaluate model performance.
Leaderboard
- We will continue to update the evaluation results of new models and host them on the AGI-Eval community.
Prerequisites
Before running the scorer, you need to set up the required language environments. We recommend to run the scorer under Linux-based systems.
For Ubuntu-based Systems:
Install C++
sudo apt update && sudo apt install -y libssl-dev libcrypto++-dev
Install Python
sudo apt update && sudo apt install -y python3 python3-pip
Install Java (OpenJDK 11)
sudo apt update && sudo apt install -y openjdk-11-jdk
Install Node.js
sudo apt update && sudo apt install -y curl
curl -fsSL https://deb.nodesource.com/setup_lts.x | sudo -E bash -
sudo apt install -y nodejs
For CentOS :
Install C++
sudo yum group install -y "Development Tools"
sudo yum install -y openssl-devel
Install Python 3
sudo yum install -y epel-release
sudo yum install -y python3 python3-pip
Install Java (OpenJDK 11)
sudo yum install -y java-11-openjdk-devel
Install Node.js
curl -fsSL https://rpm.nodesource.com/setup_lts.x | sudo bash -
sudo yum install -y nodejs
Setup
Install the required Python packages:
pip install -r requirements.txt
Usage
Run the scorer:
python scorer.py
The evaluation results will be:
- Printed to stdout for model scores
- Saved to
cases.jsonfor detailed case-by-case results
Please note that the provided scorer.py uses the C++ language and problem's canonical_solution as a demonstration. In actual execution, please replace it with your model's response (raw code). We provide a function extractor in the code_utils file for your convenience. In the code comments, we have included an example method for obtaining the model's solution using the OpenAI API.
Citation
@misc{zhu2025oibenchbenchmarkingstrongreasoning,
      title={OIBench: Benchmarking Strong Reasoning Models with Olympiad in Informatics},
      author={Yaoming Zhu and Junxin Wang and Yiyang Li and Lin Qiu and ZongYu Wang and Jun Xu and Xuezhi Cao and Yuhuai Wei and Mingshi Wang and Xunliang Cai and Rong Ma},
      year={2025},
      eprint={2506.10481},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2506.10481},
}
Acknowledgement
Our scorer logic is adapted from the implementation of OctoPack: Instruction Tuning Code Large Language Models.
Similar repos
Languages
Python
100.0%